docs(docker): maintain Docker Hub overview in-repo + auto-sync on main (#410)
The hub.docker.com/r/palashdeb/omnivoice-studio overview was managed by
hand and had gone stale (stuck at the sha-f86beb0 era, missing the tag
table, audiobook/long-form, Supertonic-3, server-mode networking notes).

Add deploy/dockerhub-overview.md as the source of truth and a
peter-evans/dockerhub-description step in docker.yml that pushes it to
Docker Hub on main pushes. Gated identically to the image push: only when
DOCKERHUB_TOKEN is set, so forks / GHCR-only runs are unaffected.

Overview adds the :latest=preview / :stable=release tag semantics (matching
docs/install/docker.md), the current feature set, server-mode + LAN
networking notes, and shields badges. Short description is 98/100 chars.

Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
This commit is contained in:
 Palash Debnath
co-authored by
Claude Opus 4.8
Claude Opus 4.8
parent
7af5143fac
commit
bd62659b9f
@@ -0,0 +1,129 @@
|
||||
# OmniVoice Studio
|
||||
|
||||
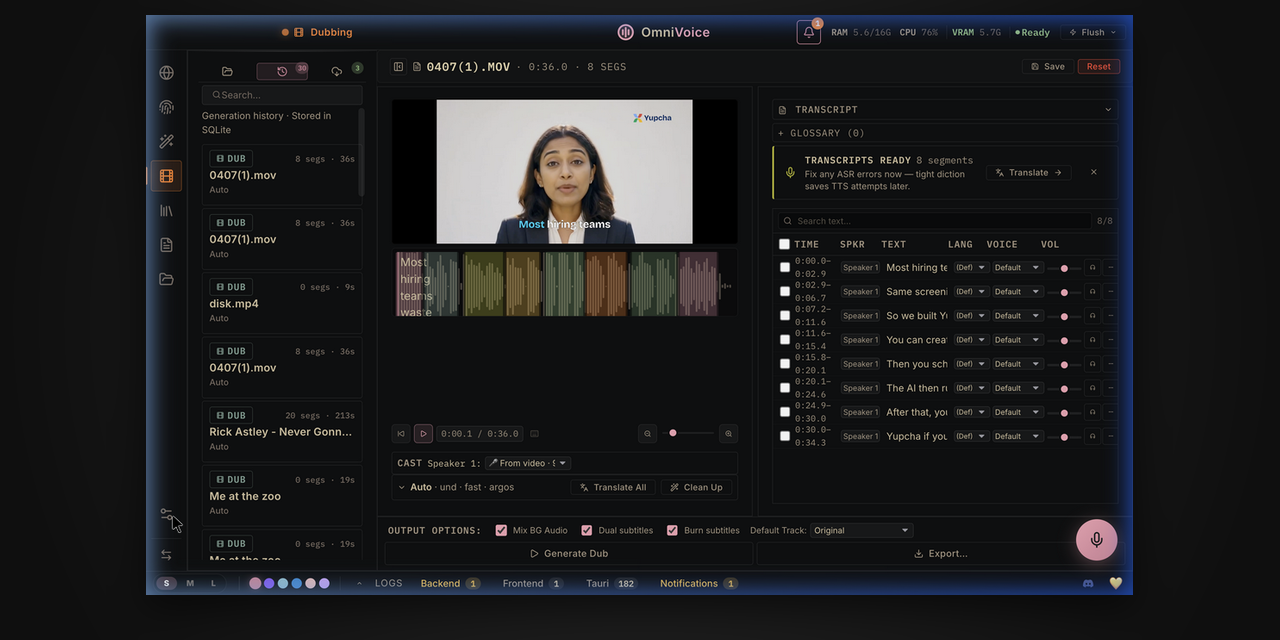
**The open-source ElevenLabs alternative.** Real-time dictation, zero-shot voice
|
||||
cloning, and cinematic video dubbing — fully local, no API keys, no accounts.
|
||||
**646 languages.**
|
||||
|
||||
[](https://hub.docker.com/r/palashdeb/omnivoice-studio)
|
||||
[](https://hub.docker.com/r/palashdeb/omnivoice-studio/tags)
|
||||
[](https://github.com/debpalash/OmniVoice-Studio)
|
||||
[](https://github.com/debpalash/OmniVoice-Studio/blob/main/LICENSE)
|
||||
[](https://discord.gg/bzQavDfVV9)
|
||||
|
||||
|
||||
|
||||
OmniVoice runs entirely on your own hardware (CUDA / MPS / ROCm / CPU
|
||||
auto-detect) — nothing is sent to the cloud. This image is the **headless
|
||||
web-server build**: a FastAPI backend serving a pre-built React UI over HTTP, so
|
||||
you can run it on a homelab box, a GPU server, or anywhere Docker runs and open
|
||||
the UI in a browser.
|
||||
|
||||
> The Tauri desktop app's auto-updater and update-channel toggle are
|
||||
> **desktop-only** and do not apply to this image — to update, pull a newer tag
|
||||
> and recreate the container.
|
||||
|
||||
---
|
||||
|
||||
## Quick start (CPU)
|
||||
|
||||
```bash
|
||||
docker run -d --name omnivoice \
|
||||
-p 127.0.0.1:3900:3900 \
|
||||
-v omnivoice-data:/app/omnivoice_data \
|
||||
-v ~/.cache/huggingface:/root/.cache/huggingface \
|
||||
palashdeb/omnivoice-studio:latest
|
||||
```
|
||||
|
||||
Open <http://localhost:3900>. The first run downloads a few GB of model weights —
|
||||
follow `docker logs -f omnivoice` to watch progress.
|
||||
|
||||
## Quick start (NVIDIA GPU)
|
||||
|
||||
```bash
|
||||
docker run -d --name omnivoice --gpus all \
|
||||
-p 127.0.0.1:3900:3900 \
|
||||
-v omnivoice-data:/app/omnivoice_data \
|
||||
-v ~/.cache/huggingface:/root/.cache/huggingface \
|
||||
palashdeb/omnivoice-studio:latest
|
||||
```
|
||||
|
||||
GPU mode needs the
|
||||
[NVIDIA Container Toolkit](https://docs.nvidia.com/datacenter/cloud-native/container-toolkit/latest/install-guide.html)
|
||||
on the host. There's also a Compose file in the repo with `cpu` / `gpu` profiles
|
||||
— see the [Docker install guide](https://github.com/debpalash/OmniVoice-Studio/blob/main/docs/install/docker.md).
|
||||
|
||||
---
|
||||
|
||||
## Image tags
|
||||
|
||||
| Tag | What you get |
|
||||
|-----|--------------|
|
||||
| `:latest` | **Rolling preview** — latest commit on `main` (always one patch ahead of the last release). This is the preview channel; pin `:stable` for production. |
|
||||
| `:stable` | Most recent versioned release (updated on every `v*` git tag) |
|
||||
| `:0.3.6` | Exact release version |
|
||||
| `:0.3` | Latest patch within the `0.3` minor |
|
||||
| `:main` | Alias of the same rolling `main` build as `:latest` |
|
||||
| `:sha-xxxxxxx` | A specific commit (produced by manual workflow dispatch) |
|
||||
|
||||
`main` always carries *last release + 1 patch*, so `:latest` (preview)
|
||||
version-sorts above `:stable` — upgrades flow naturally. The same images and tags
|
||||
are mirrored on GHCR at
|
||||
[`ghcr.io/debpalash/omnivoice-studio`](https://github.com/debpalash/OmniVoice-Studio/pkgs/container/omnivoice-studio).
|
||||
|
||||
---
|
||||
|
||||
## What's inside
|
||||
|
||||
- **🎙️ Voice Cloning** — a 3-second clip mirrors any voice, zero-shot, in 646 languages.
|
||||
- **🎨 Voice Design** — dial in gender, age, accent, pitch, speed, emotion, and dialect.
|
||||
- **🎬 Video Dubbing** — YouTube URL or file → transcribe → translate → re-voice → MP4.
|
||||
- **📖 Audiobook & long-form** — script → plan → loudness-normalized M4B with chapters, metadata, and cover art.
|
||||
- **🔊 Vocal Isolation** — Demucs splits speech from music and keeps the background.
|
||||
- **👥 Speaker Diarization** — Pyannote + WhisperX auto-identify who said what.
|
||||
- **📦 Batch Queue** — drop 50 videos and walk away; per-job progress.
|
||||
- **🤖 MCP Server** — drive OmniVoice from Claude, Cursor, or any MCP client.
|
||||
- **🛡️ AI Watermark** — invisible AudioSeal (Meta) marking that survives compression.
|
||||
- **⚡ GPU Auto-Detect** — CUDA · MPS · ROCm · CPU, with auto-offload on ≤8 GB cards.
|
||||
- **🧩 Extensible** — subclass `TTSBackend` to add any engine in ~50 lines.
|
||||
|
||||
Multiple TTS engines ship out of the box (IndexTTS, CosyVoice, Supertonic-3, and
|
||||
more), auto-detected and selectable in Settings.
|
||||
|
||||
---
|
||||
|
||||
## Volumes worth persisting
|
||||
|
||||
| Mount | Purpose |
|
||||
|-------|---------|
|
||||
| `omnivoice-data:/app/omnivoice_data` | Project DB, user voices, settings, encrypted HF token — survives upgrades |
|
||||
| `~/.cache/huggingface:/root/.cache/huggingface` | HF model cache — reuse the host cache to skip multi-GB re-downloads |
|
||||
|
||||
---
|
||||
|
||||
## Configuration & networking
|
||||
|
||||
- The container binds uvicorn to `0.0.0.0` internally; the host-side
|
||||
`127.0.0.1:3900:3900` mapping is what keeps it loopback-only. Change the
|
||||
mapping to `0.0.0.0:3900:3900` for LAN access.
|
||||
- Behind a reverse proxy on a different origin, set
|
||||
`-e OMNIVOICE_PUBLIC_API_BASE=https://api.your-host.example` so the UI targets
|
||||
the right API base (works on the prebuilt image; no rebuild needed).
|
||||
- The image ships with `OMNIVOICE_SERVER_MODE=1`, which relaxes the desktop-only
|
||||
loopback-origin gate so the admin UI works through Docker's NAT. Set it to `0`
|
||||
if you front the container with your own loopback auth proxy.
|
||||
|
||||
> **Security:** OmniVoice ships **no authentication**. Anything that can reach the
|
||||
> URL can use the app. Before exposing it beyond localhost, put it behind a
|
||||
> reverse proxy with auth (Caddy `basic_auth`, nginx + htpasswd) or a private
|
||||
> overlay (Tailscale, ZeroTier).
|
||||
|
||||
---
|
||||
|
||||
## Links
|
||||
|
||||
- **Source & full install docs:** <https://github.com/debpalash/OmniVoice-Studio>
|
||||
- **Docker guide:** <https://github.com/debpalash/OmniVoice-Studio/blob/main/docs/install/docker.md>
|
||||
- **Troubleshooting:** <https://github.com/debpalash/OmniVoice-Studio/blob/main/docs/install/troubleshooting.md>
|
||||
- **Community / support:** [Discord](https://discord.gg/bzQavDfVV9)
|
||||
|
||||
OmniVoice Studio is in active beta and licensed under AGPL-3.0.
|
||||
Reference in New Issue
Block a user