Compare commits
158
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 debpalash |
772e3e82b4 | ||
|
debpalash
|
228019c9a8 | ||
|
Palash Debnath
|
e38b5f5741 | ||
|
debpalash
|
f60f5f1f59 | ||
|
Palash Debnath
|
7640f42dce | ||
|
Palash Debnath
|
3eeed0cfe9 | ||
|
Muhammad Ahmad Ali
|
b946fded12 | ||
|
Palash Debnath
|
7718a7a10b | ||
|
Palash Debnath
|
0687e13b57 | ||
|
Palash Debnath
|
89d585a36e | ||
|
Paolo Antinori
|
3f5114923b | ||
|
Palash Debnath
|
43f1d46fe6 | ||
|
Paolo Antinorianddebpalash
|
3223a20f88 | ||
|
Palash Debnath
|
2d37627ab2 | ||
|
Palash Debnath
|
54a88f694b | ||
|
Palash Debnath
|
3441201be0 | ||
|
Palash Debnath
|
de5d848189 | ||
|
debpalash
|
aa7c2f5801 | ||
|
debpalash
|
b7f14ce4ad | ||
|
debpalash
|
7a928da1a0 | ||
|
debpalash
|
0961a5e512 | ||
|
debpalash
|
0619df8dff | ||
|
debpalash
|
a91b27b518 | ||
|
debpalash
|
605236566c | ||
|
debpalash
|
918c400f29 | ||
|
debpalash
|
76d16ac1bd | ||
|
debpalash
|
f22606f3ad | ||
|
debpalash
|
f8492dd676 | ||
|
debpalash
|
f6afa43d07 | ||
|
debpalash
|
835a889326 | ||
|
debpalash
|
2f3888549b | ||
|
debpalash
|
e9e4d95d06 | ||
|
debpalash
|
2048d2793a | ||
|
debpalash
|
52ce462396 | ||
|
debpalash
|
e300739d78 | ||
|
debpalash
|
7efae54cf8 | ||
|
debpalash
|
0257bfcfec | ||
|
debpalash
|
933c1a2cf1 | ||
|
debpalash
|
c59a787a10 | ||
|
debpalash
|
ed6d7a9652 | ||
|
debpalash
|
3a1013527f | ||
|
debpalash
|
243220fc3a | ||
|
debpalash
|
d57b4babc5 | ||
|
debpalash
|
c198a8349a | ||
|
debpalash
|
c4f3ca457d | ||
|
debpalash
|
e1e3a477a7 | ||
|
debpalash
|
e20add344c | ||
|
debpalash
|
0a07202634 | ||
|
debpalash
|
3cf1007f28 | ||
|
debpalash
|
1044483edf | ||
|
debpalash
|
a04c972b71 | ||
|
debpalash
|
8c1afe6d9d | ||
|
debpalash
|
809314a459 | ||
|
debpalash
|
2dcfd0bb55 | ||
|
debpalash
|
93616a9c2a | ||
|
debpalash
|
4072ec3db4 | ||
|
debpalash
|
0548386cb3 | ||
|
debpalash
|
45ec840ead | ||
|
debpalash
|
fcc6e4a843 | ||
|
debpalash
|
99a98eaefe | ||
|
debpalash
|
f72439d6cf | ||
|
debpalash
|
a355ad4ab6 | ||
|
debpalash
|
daefad8769 | ||
|
debpalash
|
afe013a6bc | ||
|
debpalash
|
f0764532e2 | ||
|
debpalash
|
d11d608c2d | ||
|
debpalash
|
109199e024 | ||
|
debpalash
|
9d133870e5 | ||
|
debpalash
|
0d9a392e8d | ||
|
debpalash
|
e6284a5d5f | ||
|
debpalash
|
69567e2e56 | ||
|
debpalash
|
8e98e7a1be | ||
|
debpalash
|
b0785c4e6d | ||
|
debpalash
|
5baf82bfb9 | ||
|
debpalash
|
f5d33aad8c | ||
|
debpalash
|
539309ea84 | ||
|
debpalash
|
e450a37d4b | ||
|
debpalash
|
77b66abd94 | ||
|
debpalash
|
1a39061849 | ||
|
debpalash
|
dd1aa3654d | ||
|
debpalash
|
8430f9843c | ||
|
debpalash
|
3299d5986b | ||
|
debpalash
|
a53ddc35a8 | ||
|
debpalash
|
62eddfad41 | ||
|
debpalash
|
5462eeacaa | ||
|
debpalash
|
9aa01d4e72 | ||
|
debpalash
|
17d181e427 | ||
|
debpalash
|
1762c57355 | ||
|
Palash Debnath
|
e3eda1af2c | ||
|
debpalash
|
40b3c4f460 | ||
|
debpalash
|
eed841a8ca | ||
|
debpalash
|
49ab178db7 | ||
|
debpalash
|
3482399197 | ||
|
debpalash
|
28f69d37aa | ||
|
debpalash
|
df4d016a7d | ||
|
debpalash
|
128b07c923 | ||
|
Palash Debnath
|
ca7fb9c68d | ||
|
debpalash
|
3dfe9664cf | ||
|
debpalash
|
fd6d21401b | ||
|
debpalash
|
c9adcb2647 | ||
|
debpalash
|
e6d3103ba8 | ||
|
debpalash
|
1e6de9155b | ||
|
debpalash
|
a41dc8bcac | ||
|
debpalash
|
a8c5ce5c31 | ||
|
debpalash
|
cc9c7cfa18 | ||
|
debpalash
|
51163cf260 | ||
|
Palash Debnath
|
4ce4f05c06 | ||
|
debpalash
|
e77feae817 | ||
|
debpalash
|
e0e19f3dc9 | ||
|
debpalash
|
b73f31b237 | ||
|
debpalash
|
6bcd3429ac | ||
|
debpalash
|
81b6bbc4d3 | ||
|
debpalash
|
fdc02b398e | ||
|
Palash Debnath
|
6e1bb44e0d | ||
|
debpalash
|
def15b8423 | ||
|
debpalash
|
4df7d4e97e | ||
|
debpalash
|
42b63488e9 | ||
|
Palash Debnath
|
4dc90a7f4f | ||
|
debpalash
|
ee3e87c0a7 | ||
|
debpalash
|
3b64d317ae | ||
|
debpalash
|
b8f1d7f19d | ||
|
debpalash
|
ee7202b1eb | ||
|
Paolo Antinori
|
871d68a6ff | ||
|
Palash Debnath
|
b37466b2e5 | ||
|
victordonat0
|
155b9345b9 | ||
|
Paolo Antinori
|
37c5df6f3a | ||
|
Paolo Antinori
|
3be001f3fd | ||
|
Paolo Antinori
|
28c7bacefb | ||
|
Paolo Antinori
|
fbb258d2e2 | ||
|
Paolo Antinori
|
6837ba25ac | ||
|
Paolo Antinori
|
366b55d9d1 | ||
|
Palash DebnathandClaude Fable 5
|
2d5f2e800e | ||
|
Palash DebnathandClaude Fable 5
|
4db02d0c97 | ||
|
Paolo Antinori
|
be007e9d77 | ||
|
velixio
|
ee35d2389e | ||
|
velixio
|
1fda5bdf96 | ||
|
Paolo Antinori
|
030bc47515 | ||
|
Palash Debnath
|
2477dde688 | ||
|
Paolo Antinori
|
31d4db65e8 | ||
|
Paolo Antinori
|
fd30a6c4ad | ||
|
Paolo Antinori
|
dcaed7cbf4 | ||
|
Paolo Antinori
|
9615cd5294 | ||
|
Palash DebnathandClaude Fable 5
|
48c9a3b1f8 | ||
|
Palash DebnathandClaude Fable 5
|
030d5ea01f | ||
|
Palash DebnathandClaude Fable 5
|
b79ba9bd3b | ||
|
Palash DebnathandClaude Fable 5
|
3d0c9605df | ||
|
Palash DebnathandClaude Fable 5
|
bb813ff676 | ||
|
Palash DebnathandClaude Fable 5
|
bc6acec5a3 | ||
|
Palash DebnathandClaude Fable 5
|
94ba362ef2 | ||
|
Palash DebnathandClaude Fable 5
|
aabe5783f3 | ||
|
Palash DebnathandGius
|
854b4852ed | ||
|
Eman-Yousaf
|
579f2e0a2e | ||
|
Paolo Antinori
|
e4c1ef0de6 | ||
|
Paolo Antinori
|
5229a9504c | ||
|
Paolo Antinori
|
214a859344 | ||
|
Paolo Antinori
|
b72436a4e5 | ||
|
Paolo Antinori
|
c2955dbe92 | ||
|
Paolo Antinori
|
a6f008ec38 |
@@ -0,0 +1,60 @@
|
||||
---
|
||||
name: fastapi-python
|
||||
description: Expert in FastAPI Python development with best practices for APIs and async operations
|
||||
---
|
||||
|
||||
# FastAPI Python
|
||||
|
||||
You are an expert in FastAPI and Python backend development.
|
||||
|
||||
## Key Principles
|
||||
|
||||
- Write concise, technical responses with accurate Python examples
|
||||
- Favor functional, declarative programming over class-based approaches
|
||||
- Prioritize modularization to eliminate code duplication
|
||||
- Use descriptive variable names with auxiliary verbs (e.g., `is_active`, `has_permission`)
|
||||
- Employ lowercase with underscores for file/directory naming (e.g., `routers/user_routes.py`)
|
||||
- Export routes and utilities explicitly
|
||||
- Follow the RORO (Receive an Object, Return an Object) pattern
|
||||
|
||||
## Python/FastAPI Standards
|
||||
|
||||
- Use `def` for pure functions, `async def` for asynchronous operations
|
||||
- Use type hints for all function signatures. Prefer Pydantic models over raw dictionaries
|
||||
- Structure: exported router, sub-routes, utilities, static content, types (models, schemas)
|
||||
- Use ordinary Python control flow; prefer readability over compressed one-line conditionals
|
||||
|
||||
## Error Handling
|
||||
|
||||
- Handle edge cases at function entry points
|
||||
- Employ early returns for error conditions
|
||||
- Place happy path logic last
|
||||
- Avoid unnecessary else statements; use if-return patterns
|
||||
- Implement guard clauses for preconditions
|
||||
- Provide proper error logging and user-friendly messaging
|
||||
|
||||
## FastAPI-Specific Guidelines
|
||||
|
||||
- Use functional components (plain functions) and Pydantic models for input validation
|
||||
- Declare routes with clear return type annotations
|
||||
- Prefer lifespan context managers for managing startup and shutdown events
|
||||
- Leverage middleware for logging, error monitoring, and optimization
|
||||
- Use HTTPException for expected errors and model them as specific HTTP responses
|
||||
- Apply Pydantic's BaseModel consistently for validation
|
||||
|
||||
## Performance Optimization
|
||||
|
||||
- Minimize blocking I/O. In `async def` handlers, use awaitable database/API clients; put synchronous SQLite or other blocking work in synchronous routes or explicitly offload it
|
||||
- Implement caching with Redis or in-memory stores
|
||||
- Optimize Pydantic serialization/deserialization
|
||||
- Use lazy loading for large datasets
|
||||
|
||||
## Key Conventions
|
||||
|
||||
1. Rely on FastAPI's dependency injection system
|
||||
2. Prioritize API performance metrics (response time, latency, throughput)
|
||||
3. Structure routes and dependencies for readability and maintainability
|
||||
|
||||
## Dependencies
|
||||
|
||||
FastAPI, Pydantic v2, asyncpg/aiomysql, SQLAlchemy 2.0
|
||||
@@ -0,0 +1,357 @@
|
||||
---
|
||||
name: vite
|
||||
description: Expert guidance for Vite development with modern build tooling, HMR, framework integrations, and performance optimization
|
||||
---
|
||||
|
||||
# Vite Development
|
||||
|
||||
You are an expert in Vite, modern JavaScript/TypeScript build tooling, and frontend development.
|
||||
|
||||
## Key Principles
|
||||
|
||||
- Leverage native ES modules for fast development
|
||||
- Use Vite's opinionated defaults when possible
|
||||
- Configure only what needs customization
|
||||
- Understand the dev/build differences
|
||||
- Optimize for both development speed and production performance
|
||||
|
||||
## Project Setup
|
||||
|
||||
### Basic Configuration
|
||||
```typescript
|
||||
// vite.config.ts
|
||||
import { defineConfig } from 'vite';
|
||||
import react from '@vitejs/plugin-react';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [react()],
|
||||
server: {
|
||||
port: 3000,
|
||||
open: true,
|
||||
},
|
||||
build: {
|
||||
outDir: 'dist',
|
||||
sourcemap: true,
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
### Path Aliases
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
|
||||
export default defineConfig({
|
||||
resolve: {
|
||||
alias: {
|
||||
'@': new URL('./src', import.meta.url).pathname,
|
||||
'@components': new URL('./src/components', import.meta.url).pathname,
|
||||
'@utils': new URL('./src/utils', import.meta.url).pathname,
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
### Usage
|
||||
```typescript
|
||||
// .env
|
||||
VITE_API_URL=https://api.example.com
|
||||
VITE_APP_TITLE=My App
|
||||
|
||||
// In code
|
||||
const apiUrl = import.meta.env.VITE_API_URL;
|
||||
const isDev = import.meta.env.DEV;
|
||||
const isProd = import.meta.env.PROD;
|
||||
const mode = import.meta.env.MODE;
|
||||
```
|
||||
|
||||
### Type Definitions
|
||||
```typescript
|
||||
// src/vite-env.d.ts
|
||||
/// <reference types="vite/client" />
|
||||
|
||||
interface ImportMetaEnv {
|
||||
readonly VITE_API_URL: string;
|
||||
readonly VITE_APP_TITLE: string;
|
||||
}
|
||||
|
||||
interface ImportMeta {
|
||||
readonly env: ImportMetaEnv;
|
||||
}
|
||||
```
|
||||
|
||||
## Hot Module Replacement
|
||||
|
||||
### Manual HMR
|
||||
```typescript
|
||||
// For libraries without HMR support
|
||||
if (import.meta.hot) {
|
||||
import.meta.hot.accept('./module.ts', (newModule) => {
|
||||
// Handle the updated module
|
||||
console.log('Module updated:', newModule);
|
||||
});
|
||||
|
||||
import.meta.hot.dispose(() => {
|
||||
// Cleanup before module is replaced
|
||||
});
|
||||
}
|
||||
```
|
||||
|
||||
## Asset Handling
|
||||
|
||||
### Static Assets
|
||||
```typescript
|
||||
// Import as URL
|
||||
import imageUrl from './image.png';
|
||||
// <img src={imageUrl} />
|
||||
|
||||
// Import as string (raw)
|
||||
import shaderCode from './shader.glsl?raw';
|
||||
|
||||
// Import as worker
|
||||
import Worker from './worker.ts?worker';
|
||||
const worker = new Worker();
|
||||
```
|
||||
|
||||
### Public Directory
|
||||
```
|
||||
public/
|
||||
├── favicon.ico # Served at /favicon.ico
|
||||
├── robots.txt # Served at /robots.txt
|
||||
└── images/ # Served at /images/
|
||||
```
|
||||
|
||||
## Framework Integrations
|
||||
|
||||
### React
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
import react from '@vitejs/plugin-react';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [
|
||||
react({
|
||||
// Babel plugins
|
||||
babel: {
|
||||
plugins: ['@emotion/babel-plugin'],
|
||||
},
|
||||
}),
|
||||
],
|
||||
});
|
||||
```
|
||||
|
||||
### Vue
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
import vue from '@vitejs/plugin-vue';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [vue()],
|
||||
});
|
||||
```
|
||||
|
||||
### Svelte
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
import { svelte } from '@sveltejs/vite-plugin-svelte';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [svelte()],
|
||||
});
|
||||
```
|
||||
|
||||
## Build Optimization
|
||||
|
||||
### Code Splitting
|
||||
```typescript
|
||||
// Dynamic imports create separate chunks
|
||||
const AdminPanel = lazy(() => import('./AdminPanel'));
|
||||
|
||||
// Manual chunks
|
||||
export default defineConfig({
|
||||
build: {
|
||||
rollupOptions: {
|
||||
output: {
|
||||
manualChunks: {
|
||||
vendor: ['react', 'react-dom'],
|
||||
utils: ['lodash', 'date-fns'],
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
### Chunk Size Optimization
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
build: {
|
||||
chunkSizeWarningLimit: 500,
|
||||
rollupOptions: {
|
||||
output: {
|
||||
manualChunks(id) {
|
||||
if (id.includes('node_modules')) {
|
||||
return id.split('node_modules/')[1].split('/')[0];
|
||||
}
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## CSS Handling
|
||||
|
||||
### CSS Modules
|
||||
```typescript
|
||||
// styles.module.css is auto-detected
|
||||
import styles from './styles.module.css';
|
||||
|
||||
// <div className={styles.container}>
|
||||
```
|
||||
|
||||
### PostCSS
|
||||
```javascript
|
||||
// postcss.config.js
|
||||
export default {
|
||||
plugins: {
|
||||
tailwindcss: {},
|
||||
autoprefixer: {},
|
||||
},
|
||||
};
|
||||
```
|
||||
|
||||
### Preprocessors
|
||||
```typescript
|
||||
// Automatically handled with package installed
|
||||
// npm install -D sass
|
||||
import './styles.scss';
|
||||
```
|
||||
|
||||
## Proxy Configuration
|
||||
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
server: {
|
||||
proxy: {
|
||||
'/api': {
|
||||
target: 'http://localhost:4000',
|
||||
changeOrigin: true,
|
||||
rewrite: (path) => path.replace(/^\/api/, ''),
|
||||
},
|
||||
'/socket.io': {
|
||||
target: 'ws://localhost:4000',
|
||||
ws: true,
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Plugin Development
|
||||
|
||||
```typescript
|
||||
// my-vite-plugin.ts
|
||||
import type { Plugin } from 'vite';
|
||||
|
||||
export function myPlugin(): Plugin {
|
||||
return {
|
||||
name: 'my-plugin',
|
||||
|
||||
// Hook: modify config
|
||||
config(config, { mode }) {
|
||||
return {
|
||||
define: {
|
||||
__BUILD_TIME__: JSON.stringify(new Date().toISOString()),
|
||||
},
|
||||
};
|
||||
},
|
||||
|
||||
// Hook: transform code
|
||||
transform(code, id) {
|
||||
if (id.endsWith('.md')) {
|
||||
return {
|
||||
code: `export default ${JSON.stringify(code)}`,
|
||||
map: null,
|
||||
};
|
||||
}
|
||||
},
|
||||
|
||||
// Hook: configure dev server
|
||||
configureServer(server) {
|
||||
server.middlewares.use((req, res, next) => {
|
||||
// Custom middleware
|
||||
next();
|
||||
});
|
||||
},
|
||||
};
|
||||
}
|
||||
```
|
||||
|
||||
## Testing with Vitest
|
||||
|
||||
```typescript
|
||||
// vitest.config.ts
|
||||
import { defineConfig } from 'vitest/config';
|
||||
|
||||
export default defineConfig({
|
||||
test: {
|
||||
globals: true,
|
||||
environment: 'jsdom',
|
||||
setupFiles: './src/test/setup.ts',
|
||||
coverage: {
|
||||
provider: 'v8',
|
||||
reporter: ['text', 'json', 'html'],
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## SSR Configuration
|
||||
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
build: {
|
||||
ssr: true,
|
||||
rollupOptions: {
|
||||
input: './src/entry-server.ts',
|
||||
},
|
||||
},
|
||||
ssr: {
|
||||
external: ['express'],
|
||||
noExternal: ['my-ui-library'],
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Library Mode
|
||||
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
build: {
|
||||
lib: {
|
||||
entry: './src/index.ts',
|
||||
name: 'MyLib',
|
||||
fileName: (format) => `my-lib.${format}.js`,
|
||||
},
|
||||
rollupOptions: {
|
||||
external: ['react', 'react-dom'],
|
||||
output: {
|
||||
globals: {
|
||||
react: 'React',
|
||||
'react-dom': 'ReactDOM',
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
- Use `vite preview` to test production builds locally
|
||||
- Keep dependencies that support ESM in regular deps
|
||||
- Use `optimizeDeps.include` for CommonJS dependencies
|
||||
- Enable `build.sourcemap` for debugging production
|
||||
- Use `server.warmup` for faster dev server starts
|
||||
@@ -271,6 +271,17 @@ jobs:
|
||||
working-directory: frontend/src-tauri
|
||||
run: cargo test --lib --target ${{ matrix.rust_target }} --message-format=short
|
||||
|
||||
# Backend-lifecycle fault-injection harness: real child processes die
|
||||
# scripted deaths through the OMNIVOICE_BACKEND_CMD seam, and each
|
||||
# scenario asserts the user-visible diagnosis names the actual cause
|
||||
# (port conflict / traceback root cause / spawn failure / timeout /
|
||||
# crash-loop exhaustion / signal 9 / deliberate replace / deferred-
|
||||
# startup step). Serial: the scenarios share process-global state
|
||||
# (env vars, crash store, kill-intended flag) by design.
|
||||
- name: Cargo test (backend lifecycle harness)
|
||||
working-directory: frontend/src-tauri
|
||||
run: cargo test --test backend_lifecycle --target ${{ matrix.rust_target }} --message-format=short -- --test-threads=1
|
||||
|
||||
# ── Cross-platform Python runtime smoke (Phase 0 GATE-02) ───────────────
|
||||
# Loads the frozen tests/fixtures/omnivoice_data/ fixture and boots the
|
||||
# FastAPI app in-process via TestClient on macOS/Windows/Linux. Catches
|
||||
|
||||
@@ -0,0 +1,127 @@
|
||||
# Installer smoke — runs scripts/install.sh / scripts/install.ps1 end-to-end
|
||||
# on all three desktop platforms so the one-liner installers can't rot.
|
||||
#
|
||||
# Gated by `paths` because a cold run downloads multi-GB wheels (torch) and
|
||||
# takes ~15-30 min per OS; it only needs to fire when an installer or this
|
||||
# workflow changes. The heavy Tauri bundles stay in release.yml (tag push).
|
||||
|
||||
name: Install smoke
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
paths:
|
||||
- "scripts/install.sh"
|
||||
- "scripts/install.ps1"
|
||||
- ".github/workflows/install-smoke.yml"
|
||||
push:
|
||||
branches: [main]
|
||||
paths:
|
||||
- "scripts/install.sh"
|
||||
- "scripts/install.ps1"
|
||||
- ".github/workflows/install-smoke.yml"
|
||||
workflow_dispatch:
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
env:
|
||||
FORCE_JAVASCRIPT_ACTIONS_TO_NODE24: true
|
||||
|
||||
jobs:
|
||||
install:
|
||||
name: Install (${{ matrix.os }})
|
||||
runs-on: ${{ matrix.os }}
|
||||
timeout-minutes: 60
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
os: [ubuntu-22.04, macos-latest, windows-latest]
|
||||
steps:
|
||||
- uses: actions/checkout@v4
|
||||
|
||||
# Running `sh scripts/install.sh` from the repo root exercises the
|
||||
# repo-root resolution (script dir is scripts/, project root one level
|
||||
# up) — the exact bug that made a local run clone a duplicate repo.
|
||||
# Binary mode is the default: prebuilt release asset, checksum verified.
|
||||
- name: Run installer — binary (macOS/Linux)
|
||||
if: runner.os != 'Windows'
|
||||
run: sh scripts/install.sh
|
||||
|
||||
- name: Verify install — binary (macOS/Linux)
|
||||
if: runner.os != 'Windows'
|
||||
run: |
|
||||
if [ "$(uname)" = "Darwin" ]; then
|
||||
test -d "/Applications/VoiceStudio.app" || { echo "::error::VoiceStudio.app missing from /Applications"; exit 1; }
|
||||
echo "✓ VoiceStudio.app installed in /Applications"
|
||||
else
|
||||
test -x "$HOME/.local/bin/VoiceStudio" || { echo "::error::AppImage missing from ~/.local/bin"; exit 1; }
|
||||
"$HOME/.local/bin/VoiceStudio" --appimage-help >/dev/null 2>&1 || true
|
||||
echo "✓ AppImage installed and executable"
|
||||
fi
|
||||
|
||||
# Source mode stays covered end-to-end behind --source.
|
||||
- name: Run installer — source (macOS/Linux)
|
||||
if: runner.os != 'Windows'
|
||||
run: sh scripts/install.sh --source
|
||||
|
||||
- name: Verify install — source (macOS/Linux)
|
||||
if: runner.os != 'Windows'
|
||||
working-directory: ${{ github.workspace }}
|
||||
run: |
|
||||
test -d .venv || { echo "::error::.venv missing"; exit 1; }
|
||||
test -f frontend/dist/index.html || { echo "::error::frontend build missing"; exit 1; }
|
||||
echo "✓ venv + frontend bundle present"
|
||||
|
||||
# Binary mode is the default; CI runs msiexec silently.
|
||||
- name: Run installer — binary (Windows)
|
||||
if: runner.os == 'Windows'
|
||||
env:
|
||||
CI: true
|
||||
shell: pwsh
|
||||
run: '& { $ErrorActionPreference = "Stop"; & "${{ github.workspace }}\scripts\install.ps1" }'
|
||||
|
||||
- name: Verify install — binary (Windows)
|
||||
if: runner.os == 'Windows'
|
||||
shell: pwsh
|
||||
run: |
|
||||
$paths = @(
|
||||
"HKLM:\Software\Microsoft\Windows\CurrentVersion\Uninstall\*",
|
||||
"HKLM:\Software\WOW6432Node\Microsoft\Windows\CurrentVersion\Uninstall\*",
|
||||
"HKCU:\Software\Microsoft\Windows\CurrentVersion\Uninstall\*"
|
||||
)
|
||||
$key = Get-ItemProperty $paths -ErrorAction SilentlyContinue |
|
||||
Where-Object { $_.DisplayName -match "VoiceStudio|OmniVoice" } |
|
||||
Select-Object -First 1
|
||||
if (-not $key) {
|
||||
Get-ItemProperty $paths -ErrorAction SilentlyContinue |
|
||||
Where-Object DisplayName | ForEach-Object { Write-Host " installed: $($_.DisplayName)" }
|
||||
Write-Host "::error::MSI product not registered"; exit 1
|
||||
}
|
||||
Write-Host "✓ MSI product registered: $($key.DisplayName)"
|
||||
|
||||
# Source mode stays covered end-to-end behind -Source.
|
||||
- name: Run installer — source (Windows)
|
||||
if: runner.os == 'Windows'
|
||||
env:
|
||||
VOICESTUDIO_INSTALL_MODE: source
|
||||
shell: pwsh
|
||||
run: '& { $ErrorActionPreference = "Stop"; & "${{ github.workspace }}\scripts\install.ps1" }'
|
||||
|
||||
- name: Verify install — source (Windows)
|
||||
if: runner.os == 'Windows'
|
||||
shell: pwsh
|
||||
run: |
|
||||
if (-not (Test-Path .venv)) { Write-Host "::error::.venv missing"; exit 1 }
|
||||
if (-not (Test-Path frontend\dist\index.html)) { Write-Host "::error::frontend build missing"; exit 1 }
|
||||
Write-Host "✓ venv + frontend bundle present"
|
||||
|
||||
- name: Upload install log on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v4
|
||||
with:
|
||||
name: install-log-${{ matrix.os }}
|
||||
path: |
|
||||
/Users/runner/Library/Application Support/OmniVoice/*.log
|
||||
/home/runner/.local/share/VoiceStudio/*.log
|
||||
${{ runner.temp }}/VoiceStudio/**/*.log
|
||||
if-no-files-found: ignore
|
||||
@@ -25,4 +25,6 @@ regexes = [
|
||||
'''^hf_QWERTYUIOPasdfghjklZXCVBNM0123456789xyzAB$''',
|
||||
# NLLB generation length argument, not the value of a credential.
|
||||
'''^max_length=400$''',
|
||||
# cryptography's Ed25519 private-key type name, not key material.
|
||||
'''^Ed25519PrivateKey$''',
|
||||
]
|
||||
|
||||
@@ -35,6 +35,10 @@ Binding for every AI agent (Claude, Codex, Cursor, review bots, …). CLAUDE.md
|
||||
|
||||
## Agent skills
|
||||
|
||||
Project development skills are pinned in `skills-lock.json` and installed under
|
||||
`.agents/skills/`: Vite and FastAPI.
|
||||
Repository rules and tracker mappings override generic skill guidance.
|
||||
|
||||
### Issue tracker
|
||||
|
||||
GitHub Issues on `debpalash/VoiceStudio`, via the `gh` CLI. See `docs/agents/issue-tracker.md`.
|
||||
|
||||
@@ -6,6 +6,79 @@ The format is loosely based on [Keep a Changelog](https://keepachangelog.com/).
|
||||
`frontend/package.json` is the app-version source of truth; Cargo, Python, and
|
||||
the frozen-backend fallback mirror it for their toolchains.
|
||||
|
||||
## [Unreleased]
|
||||
|
||||
**Highlights**
|
||||
|
||||
- Dictation now stays bound to the app where it started and recovers locally from silent recognizer output (#1175)
|
||||
- The backend now answers within a second of launch and narrates its startup step by step (#1550)
|
||||
- Reporting a bug from an outdated build now offers the latest release first (#1547)
|
||||
- The backend is only announced ready once it can actually serve, and crash-loop restarts now pace themselves (#1548)
|
||||
- Invisible watermarking no longer stalls — or silently skips — the first take of a session (#1615)
|
||||
- Dub subtitles can be retimed, inserted, and merged in either direction from the segment table (#1612) — thanks @invio-a11y!
|
||||
|
||||
### Changed
|
||||
- Dictation now carries one native output session from shortcut-down through final delivery, restores text, HTML, image, or file-list clipboards only when untouched, keeps Wayland copy-safe unless current-focus insertion is explicitly enabled, and retries silent Sherpa speech only through an already-installed local ASR model (#1175)
|
||||
- The backend binds its port immediately and reports startup progress live — `/health` answers 503-with-step and a new `/startup/progress` endpoint lists every step while PyTorch, API routes, and database migrations load in the background, so "starting at step X" is never mistakable for "dead"; the desktop splash narrates each step (#1550)
|
||||
|
||||
### Added
|
||||
- One-command install on every desktop OS: `curl -fsSL https://voicestudio.sh/install | sh` (macOS/Linux/WSL) or `irm https://voicestudio.sh/install | iex` (Windows) — the URL serves the right script per platform, and Windows gains a source installer (`scripts/install.ps1`) with a 3-OS CI smoke (#1626)
|
||||
- Per-line subtitle management in the dub table: a line's end time is editable alongside its start (typing a time and dragging its timeline edge now take the same path), lines merge with the previous row as well as the next (`Ctrl/Cmd+Shift+M`), and a new line can be inserted into the gap after any row (#1612) — thanks @invio-a11y!
|
||||
- CI now enforces performance regression budgets on the hot paths — operation-count tests pin streaming TTS to one synthesis per sentence and cached dub re-mixes to zero re-synthesis; fast-path guards cover zero re-decoding and ⌈N/W⌉ native batch calls when enabled (#1594)
|
||||
- Default-engine dubbing now synthesizes several segments per forward pass instead of one call per line — the width follows the host's device headroom (1 on CPU and low-VRAM cards, up to 8), `OMNIVOICE_DUB_BATCH_WIDTH` overrides it, and engines without native batching keep the single-segment path (#1594)
|
||||
- `/ws/tts` now reports real time-to-first-audio, and its RTF measures synthesis alone so a slow client can't inflate it (#1594)
|
||||
- The locally cached AudioSeal watermark generator warms on a background thread ~35s after boot (`OMNIVOICE_PRELOAD_WATERMARK=0` opts out; explicitly setting `=1` may download it), so the first synthesis no longer serializes the audioseal import + model load inline — measured at ~42s on a cold filesystem, 3s short of a 90s client timeout (#1576) — thanks @paoloantinori!
|
||||
- Voices you've cloned stay "warm" across restarts — encoded references now persist to disk (~10 KB each), so the first generation of a session skips the re-encode and any transcription pass; `OMNIVOICE_PROMPT_DISK_CACHE=0` opts out (#1565)
|
||||
- Optional FlashInfer acceleration for the default engine on CUDA (`OMNIVOICE_FLASHINFER=1`, ~2.2x measured) — needs the optional `flashinfer-python` package; missing package or kernel failure logs why and falls back to the standard path (#1565)
|
||||
- The bug reporter notices when you're on an outdated build and offers the latest release before filing — with a "File anyway" escape hatch — and stamps a `Build status` line into every report so up-to-date reports are tellable from stale ones (#1547)
|
||||
- Settings → Performance & Device gains a compute-device override (Auto / CUDA / ROCm / XPU / MPS / CPU, or `OMNIVOICE_DEVICE`) — pin the device when auto-detect picks wrong; only devices your machine actually has are offered (#1557)
|
||||
- Opt-in 24-layer PocketTTS checkpoints via `OMNIVOICE_POCKETTTS_24L` — better prosody for it/de/es/pt at roughly 2x render time (still faster than real-time); the fast 6-layer model stays the default (#1613) — thanks @paoloantinori!
|
||||
|
||||
### Docs
|
||||
- The Docker Hub overview now shows the current engine-switching demo, Model Catalogue, and gallery voice workflow (#1593)
|
||||
- The Docker Hub overview and install guide now show the v0.5 tags and the built-in API-key/share-PIN security model instead of obsolete v0.4 and no-authentication guidance (#1592)
|
||||
- The READMEs now lead with download buttons and a three-step first-clone walkthrough, and a new benchmarks page anchors measured per-engine/per-device numbers on the in-repo harness (#1555)
|
||||
- Every engine now has its own guide — 21 new pages under docs/engines plus an index covering all 16 TTS and 11 ASR engines, linked from both READMEs (#1556)
|
||||
- The OmniVoice guide now covers combining style attributes with a reference clip (consistent instruct stabilizes cloning; the reference wins conflicts), inline pronunciation control (pinyin / CMU phonemes), and corrects the claim that the default engine can't do voice design — it can, from attributes (#1565)
|
||||
|
||||
### Fixed
|
||||
- Moving words across a speaker boundary in a dub — merging two lines and splitting them again — no longer dubs the second half in the first speaker's voice; each half now keeps the speaker, voice, direction, gain, and language of whoever actually says it (#1612) — thanks @invio-a11y!
|
||||
- Dictation on a WebView that refuses a 16 kHz audio context (WKWebView) now low-passes before downsampling, so frequencies above 8 kHz stop folding into the speech the recognizer is fed (#1610)
|
||||
- A microphone context that cannot be resumed now reports a mic error instead of leaving the dictation pill on "Listening" while capturing nothing (#1610)
|
||||
- Dictation no longer retains a whole session's audio for silent-model recovery — an open mic grew that buffer by ~115 MB an hour; the recent two minutes are kept instead (#1610)
|
||||
- The clipboard-delivery status is now translated in all 21 languages, so Wayland users — where clipboard delivery is the default — no longer see an English string (#1610)
|
||||
- A native sherpa-onnx load failure of any exception type now degrades to "engine unavailable" instead of taking the dictation WebSocket down (#1610)
|
||||
- Dictation now ships Whisper Tiny as its one cross-platform default, avoiding Parakeet's measured empty decoding on Windows while keeping Parakeet selectable behind runtime fallback (#1175)
|
||||
- Re-mixing a dub no longer decodes, rewrites, and re-reads every cached segment — same-rate cached audio is reused directly (and rejected if truncated), switching timing modes can't reuse slot-truncated audio as natural-rate, and RVC respects natural-rate modes (#1594)
|
||||
- PocketTTS French works again — pocket-tts only ships a 24-layer French model and rejected the name the sidecar asked for, so every French request failed at model load; French now always loads `french_24l` (#1613) — thanks @paoloantinori!
|
||||
- Installing IndexTTS 2.5 no longer fails claiming an interrupted download — the weights repo ships `config.yaml` and VoiceStudio demanded a `config_v2_5.yaml` that exists in no upstream release; both names are accepted, so a hand-renamed checkout keeps working (#1611) — thanks @zuiaiyutu!
|
||||
- IndexTTS 2.5 no longer has long-text generation killed at 60 seconds — the sidecar now proves it is alive every 5 seconds while `infer()` runs, and its deadline rises to 900s (`OMNIVOICE_INDEXTTS_RECV_TIMEOUT_S`) (#1611) — thanks @zuiaiyutu!
|
||||
- The OpenAI-compatible `/v1/audio/speech` route now reuses the shared cached engine for explicit `model` ids instead of constructing a fresh engine — and its sidecar/model load, a ~28s floor per call for subprocess engines — on every request, with the same single-engine-resident discipline `/generate` applies (#1614) — thanks @paoloantinori!
|
||||
- The setup wizard's RAM check no longer blocks 8 GB machines whose OS reports ~7.8 GB usable — the thresholds now tolerate reserved memory, and `OMNIVOICE_RAM_PREFLIGHT=0` turns a genuine block into a warning for those who accept the OOM risk (#1618)
|
||||
- Invisible watermarking now runs eagerly instead of through `torch.compile` — AudioSeal's lazy compile sent the first embed of every session into Inductor's C++ codegen, which failed outright on macOS hosts whose toolchain couldn't serve it and shipped the audio unmarked after a 30-40s wait; first embed drops from 9.70s to 0.26s (#1615) — thanks @paoloantinori!
|
||||
- The macOS Accessibility blocker now rechecks while visible and closes as soon as the grant is enabled instead of keeping a stale permission prompt on screen (#1609)
|
||||
- The dubbing editor's video and transcript columns can now be resized by pointer or keyboard, and the chosen split persists across launches (#1571) — thanks @invio-a11y!
|
||||
- CPU-only synthesis now gets a bounded ten-minute execution budget, and a render that exhausts it is reported as a compute timeout instead of misleading "generation capacity is busy" queue pressure (#1588) — thanks @ChienNguyen1111!
|
||||
- Rapid Launchpad ↔ Dub navigation now replaces the workspace DOM owner cleanly, so late media/waveform cleanup cannot trigger React's `insertBefore` crash (#1590) — thanks @nicolas-jacques!
|
||||
- Watermark embedding failures now log the full traceback instead of just the exception message, so a silently-unmarked-audio incident (audio passes through unmarked by design) is diagnosable from the log alone (#1576) — thanks @paoloantinori!
|
||||
- Dubbing now recovers rapid two-speaker exchanges when diarization collapses them, defaults new projects to lip sync without overwriting saved timing choices, and keeps the editor usable on narrow screens (#1584) — thanks @victordonat0!
|
||||
- `OMNIVOICE_ASR_BACKEND=omnivoice` now selects the PyTorch-native Whisper path, so the documented ROCm escape hatch no longer fails as an unknown engine (#1582) — thanks @patmansk!
|
||||
- Network Sharing from Windows MSI/portable installs now serves the bundled web interface to LAN devices instead of redirecting them to their own `localhost` (#1589) — thanks @TWIISTED-STUDIOS!
|
||||
- Exported dubbed videos now mark the dubbed language as the default audio stream while keeping Original available as an explicit choice (#1575) — thanks @invio-a11y!
|
||||
- Cloning references can no longer exhaust system memory: transcript-free clips up to 75 seconds are searched in five bounded passages, longer clips ask to be trimmed, and supplied transcripts remain capped at 20 seconds to preserve alignment (#1578) — thanks @ACKAPOB!
|
||||
- Stored artifact subpaths now resolve after moving a data directory between Windows, macOS, Linux, and Docker, while traversal and symlink escapes remain blocked (#1559) — thanks @Eman-Yousaf!
|
||||
- A remote browser hitting an API-key-configured server's admin 403 now gets the API-key login form instead of endless console 403s, while desktop and PIN-only/no-key servers keep the plain loopback error so guests are never offered a login no key can satisfy (#1568) — thanks @paoloantinori!
|
||||
- The crash-isolated ASR sidecar and its download preflight now agree on which model to load — setting the shared faster-whisper model variable applies to both variants instead of the sidecar quietly using a different one (#1556)
|
||||
- "Ready" now requires the deep health probe (a working database-backed route), not just the identity probe — a backend whose install broke underneath can no longer be announced up while every real request fails (#1548)
|
||||
- Supervisor restarts after repeat crashes now back off (immediate, then 5s, then 15s) instead of respawning back-to-back, so a tight crash loop can't burn the whole restart budget in seconds (#1548)
|
||||
- The Linux desktop cleanup regression test now isolates build artifacts, so an existing developer build can no longer change its result (#1566)
|
||||
|
||||
- Renaming, deleting, or revoking consent on a voice (and starring/clearing history, recording exports) now live-updates every open tab again — the sync routes' WebSocket events were silently dropped, which could look like "all my voices are gone" (#1561) — thanks @paoloantinori!
|
||||
|
||||
### CI
|
||||
- Project agents now share pinned Vite and FastAPI skills from skills.sh (#1594)
|
||||
- Weekly full-history secret scans no longer mistake the Ed25519 private-key type name for committed key material (#1591)
|
||||
|
||||
## [0.5.0] — 2026-08-13
|
||||
|
||||
**Highlights**
|
||||
@@ -31,6 +104,7 @@ the frozen-backend fallback mirror it for their toolchains.
|
||||
### Changed
|
||||
|
||||
- Gallery personas now preview through the local backend, retain their complete voice-design recipe, and open directly in Voice, Stories, or Audiobook. (#1542)
|
||||
- Typing and large workspace edits no longer serialize and rewrite persisted documents on every input; writes are coalesced off the interaction path — thanks @bultodepapas! (#1541)
|
||||
- Support amount choices now use every theme's shared card, accent and focus tokens. (#1530)
|
||||
- Sponsoring, commercial licensing and getting in touch are one page now. They answered the same question between them and each used to live somewhere else, so they are three sections on a single scroll — the footer heart, the commercial-licence links and Contact all land on it, at the section you asked for. (#1522)
|
||||
- Model Catalogue switches panes with tabs instead of a two-state toggle, and the Engine Compatibility Matrix's TTS / ASR / LLM switcher is now tabs too — arrow-key navigable, and each tab still shows the engine it would use. (#1522)
|
||||
|
||||
@@ -66,7 +66,10 @@ Architecture not yet mapped. Follow existing patterns found in the codebase.
|
||||
<!-- GSD:skills-start source:skills/ -->
|
||||
## Project Skills
|
||||
|
||||
No project skills found. Add skills to any of: `.claude/skills/`, `.agents/skills/`, `.cursor/skills/`, `.github/skills/`, or `.codex/skills/` with a `SKILL.md` index file.
|
||||
- `vite` — Vite configuration, assets, HMR, builds, and Vitest guidance.
|
||||
- `fastapi-python` — FastAPI and Pydantic implementation patterns.
|
||||
|
||||
Canonical copies live under `.agents/skills/`; `skills-lock.json` pins their sources and hashes. Claude should follow these paths directly, avoiding cross-platform symlinks.
|
||||
<!-- GSD:skills-end -->
|
||||
|
||||
<!-- GSD:workflow-start source:GSD defaults -->
|
||||
|
||||
@@ -1,551 +1,385 @@
|
||||
<div align="center">
|
||||
<img src="docs/logo.png" alt="VoiceStudio Logo" width="120" height="120" />
|
||||
<img src="docs/logo.png" alt="VoiceStudio logo" width="120" height="120" />
|
||||
<h1>VoiceStudio</h1>
|
||||
<p><sub><em>previously OmniVoice-Studio</em></sub></p>
|
||||
<h3>Make voices. Tell stories. Keep the files. ♡</h3>
|
||||
<p>Clone, design, dub, dictate, and build audiobooks in one open-source desktop studio.<br/><b>Local-first by default.</b> No subscription or usage meter. Optional online services stay opt-in.</p>
|
||||
<p><sub>Previously OmniVoice-Studio</sub></p>
|
||||
<h3>Local voice cloning, dubbing, dictation, and long-form audio.</h3>
|
||||
<p>16 TTS engines · 11 ASR engines · 646-language catalogue · macOS, Windows, and Linux</p>
|
||||
<p><strong>Local-first.</strong> No account, API key, subscription, or usage meter for the core workflow.</p>
|
||||
|
||||
<p>
|
||||
<a href="#quickstart">Quickstart</a> ·
|
||||
<a href="#install">Install</a> ·
|
||||
<a href="#features">Features</a> ·
|
||||
<a href="#why-voicestudio">Why VoiceStudio</a> ·
|
||||
<a href="#tts-engines">Engines</a> ·
|
||||
<a href="#openai-api">API</a> ·
|
||||
<a href="#sponsor--donate">Donate</a> ·
|
||||
<a href="#contributing">Contributing</a> ·
|
||||
<a href="https://voicestudio.sh">Website</a> ·
|
||||
<a href="https://voicestudio.sh/docs">Docs</a> ·
|
||||
<a href="https://status.voicestudio.sh">Status</a> ·
|
||||
<a href="https://discord.gg/bzQavDfVV9">Discord</a> ·
|
||||
<a href="https://x.com/idebpalash">X</a> ·
|
||||
<a href="#comparison">Compare</a> ·
|
||||
<a href="#requirements">Requirements</a> ·
|
||||
<a href="#engines">Engines</a> ·
|
||||
<a href="#architecture">Architecture</a> ·
|
||||
<a href="#api">API</a> ·
|
||||
<a href="#documentation">Docs</a> ·
|
||||
<a href="README_CN.md"><strong>简体中文</strong></a>
|
||||
</p>
|
||||
|
||||
<p>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/stargazers"><img src="https://img.shields.io/github/stars/debpalash/VoiceStudio?style=flat-square&color=f59e0b" alt="Stars" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/stargazers"><img src="https://img.shields.io/github/stars/debpalash/VoiceStudio?style=flat-square&color=f59e0b" alt="GitHub stars" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases"><img src="https://img.shields.io/github/downloads/debpalash/VoiceStudio/total?style=flat-square&color=8b5cf6&label=downloads" alt="Total downloads" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/github/v/release/debpalash/VoiceStudio?style=flat-square&color=10b981" alt="Release" /></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/license-AGPL--3.0-blue?style=flat-square" alt="License" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/issues"><img src="https://img.shields.io/github/issues/debpalash/VoiceStudio?style=flat-square&color=ef4444" alt="Issues" /></a>
|
||||
<a href="https://discord.gg/bzQavDfVV9"><img src="https://img.shields.io/badge/Discord-Join_Community-5865F2?style=flat-square&logo=discord&logoColor=white" alt="Discord" /></a>
|
||||
<a href="https://x.com/idebpalash"><img src="https://img.shields.io/badge/X-Follow_for_updates-000000?style=flat-square&logo=x&logoColor=white" alt="Follow on X" /></a>
|
||||
<a href="https://ko-fi.com/debpalash"><img src="https://img.shields.io/badge/Ko--fi-Support_Us-FF5E5B?style=flat-square&logo=ko-fi&logoColor=white" alt="Ko-fi" /></a>
|
||||
<a href="https://paypal.me/palashCoder"><img src="https://img.shields.io/badge/PayPal-Donate-00457C?style=flat-square&logo=paypal&logoColor=white" alt="PayPal" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/github/v/release/debpalash/VoiceStudio?style=flat-square&color=10b981" alt="Latest release" /></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/license-AGPL--3.0-blue?style=flat-square" alt="AGPL-3.0 license" /></a>
|
||||
<a href="https://discord.gg/bzQavDfVV9"><img src="https://img.shields.io/badge/Discord-Community-5865F2?style=flat-square&logo=discord&logoColor=white" alt="Discord community" /></a>
|
||||
</p>
|
||||
|
||||
<p>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/⬇_Download-macOS_·_Windows_·_Linux-10b981?style=for-the-badge" alt="Download the latest release" /></a>
|
||||
</p>
|
||||
|
||||
<p>
|
||||
<a href="https://trendshift.io/repositories/28176?utm_source=trendshift-badge&utm_medium=badge&utm_campaign=badge-trendshift-28176" target="_blank" rel="noopener noreferrer"><img src="https://trendshift.io/api/badge/trendshift/repositories/28176/daily?language=Python" alt="debpalash%2FVoiceStudio | Trendshift" width="250" height="55"/></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Download-macOS_·_Windows_·_Linux-10b981?style=for-the-badge" alt="Download VoiceStudio" /></a>
|
||||
</p>
|
||||
</div>
|
||||
|
||||
<br/>
|
||||
|
||||
<div align="center">
|
||||
<img src="docs/screenshot-launchpad.png" alt="VoiceStudio — Launchpad" width="100%"/>
|
||||
<img src="docs/media/0.5.0/quick-switch.gif" alt="Switching TTS engines from the VoiceStudio status bar" width="100%" />
|
||||
</div>
|
||||
|
||||
> **Your voice is personal. Your studio should feel personal too.** VoiceStudio keeps its core workflow on your hardware: clone, design, dub, dictate, and publish in 646 languages without a subscription or usage meter. Network-backed engines and services are optional, visible choices—not hidden requirements.
|
||||
|
||||
> [!WARNING]
|
||||
> **Active beta.** Things may break between releases — for the newest fixes, run from source. Bug reports and PRs are very welcome: [open an issue](https://github.com/debpalash/VoiceStudio/issues) or [join Discord](https://discord.gg/bzQavDfVV9).
|
||||
> **Active beta.** Use the [latest release](https://github.com/debpalash/VoiceStudio/releases/latest) for stable work or `main` for current fixes. Report problems through [GitHub Issues](https://github.com/debpalash/VoiceStudio/issues).
|
||||
|
||||
<a id="whats-new"></a>
|
||||
## At a glance
|
||||
|
||||
## 🆕 What's new in 0.5.0
|
||||
| | VoiceStudio |
|
||||
|---|---|
|
||||
| **Workflows** | Voice cloning and design, video dubbing, dictation, stories, audiobooks, batch generation |
|
||||
| **Language catalogue** | 646 TTS languages; actual coverage and quality depend on the selected engine |
|
||||
| **Engines** | 16 TTS · 11 ASR · switch in Model Catalogue or with <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd> |
|
||||
| **Platforms** | macOS 13.3+ on Apple Silicon · Windows 10/11 x64 · Linux x86_64 with glibc 2.39+ |
|
||||
| **Compute** | CUDA · Apple Silicon MPS/MLX · ROCm on Linux · CPU · optional remote workers |
|
||||
| **Interfaces** | Desktop app · local REST/SSE/WebSocket API · OpenAI-compatible audio API · MCP Server |
|
||||
| **Storage** | Voices, projects, settings, and outputs stay on the machine by default |
|
||||
| **License** | AGPL-3.0; optional engines keep their own model licenses |
|
||||
|
||||
The rename release — full notes: [v0.5.0 release](https://github.com/debpalash/VoiceStudio/releases/tag/v0.5.0) · [CHANGELOG](CHANGELOG.md).
|
||||
<a id="install"></a>
|
||||
|
||||
- 🏷️ **A new name** — VoiceStudio (previously OmniVoice-Studio): one waveform-and-spark identity across app, docs, and installers. Your data folder, settings, and Docker image paths stay put.
|
||||
- 📚 **Model Catalogue** — engines and models in one workspace: every TTS, ASR, and LLM engine with its device routing and install state; pick defaults, install or remove weights.
|
||||
- ⚡ **Engine quick-switch** — change TTS/ASR/LLM engines from the status bar or anywhere with <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd> — ready-only choices, memory status, environment-pin protection.
|
||||
- 🖧 **Remote GPU workers** — lend another machine's GPU with a join code and a QR scan; a **Compute** control picks where jobs run, and several people can share one GPU box over revocable, certificate-pinned connections.
|
||||
- 🔐 **Hardened server mode** — admin actions require an API key, exchanged for short-lived scoped sessions that never sit in browser storage or WebSocket URLs.
|
||||
- 💾 **Gallery voices → local profiles** — save any gallery voice as a profile of your own and use it in every picker.
|
||||
- 🎤 **Dictation on Wayland** — the portal shortcut actually fires now, and the recording pill is back on every desktop.
|
||||
## Install
|
||||
|
||||
<div align="center">
|
||||
<img src="docs/media/0.5.0/quick-switch.gif" alt="Switching engines from the status bar" width="640"/>
|
||||
<br/><sub>Engine quick-switch from the status bar — <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd> from any workspace</sub>
|
||||
</div>
|
||||
| Platform | Package | Guide |
|
||||
|---|---|---|
|
||||
| macOS 13.3+ | DMG, Apple Silicon | [Install on macOS](docs/install/macos.md) |
|
||||
| Windows 10/11 | MSI, x64 | [Install on Windows](docs/install/windows.md) |
|
||||
| Linux | AppImage, x86_64 with glibc 2.39+ | [Install on Linux](docs/install/linux.md) |
|
||||
| Docker | CUDA, ROCm, or CPU | [Run with Docker](docs/install/docker.md) |
|
||||
|
||||
<br/>
|
||||
Download packages from the [latest release](https://github.com/debpalash/VoiceStudio/releases/latest). First launch creates a managed Python environment and downloads the default model. Later launches reuse both.
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td width="50%"><img src="docs/media/0.5.0/catalogue.png" alt="Model Catalogue — engines pane" width="100%"/></td>
|
||||
<td width="50%"><img src="docs/media/0.5.0/gallery-save.png" alt="Saving a gallery voice as a profile" width="100%"/></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><sub><b>Model Catalogue</b> — every engine, its routing and install state</sub></td>
|
||||
<td align="center"><sub><b>Gallery → profile</b> — keep a gallery voice as your own</sub></td>
|
||||
</tr>
|
||||
</table>
|
||||
> [!NOTE]
|
||||
> On macOS, first launch needs a one-time right-click → **Open** approval. Intel Macs cannot run the local Python backend; use a [remote backend](docs/install/macos.md) instead.
|
||||
|
||||
### First voice
|
||||
|
||||
1. Launch VoiceStudio and open **Voice Cloning**.
|
||||
2. Add a clean voice sample. Three seconds works; 5–15 seconds usually gives a better prompt.
|
||||
3. Enter text, choose a language, then select **Generate**.
|
||||
|
||||
### Run from source
|
||||
|
||||
Install the [development prerequisites](.github/CONTRIBUTING.md#development-setup), then:
|
||||
|
||||
```bash
|
||||
git clone https://github.com/debpalash/VoiceStudio.git
|
||||
cd VoiceStudio
|
||||
bun install
|
||||
bun run desktop
|
||||
```
|
||||
|
||||
Use `bun run dev` for the browser UI. See [Contributing](.github/CONTRIBUTING.md) for services, tests, and platform packages.
|
||||
|
||||
### If setup fails
|
||||
|
||||
- Run **Settings → About → Run self-check** or `uv run python backend/main.py --diagnose --deep`.
|
||||
- Check [install troubleshooting](docs/install/troubleshooting.md).
|
||||
- Save a scrubbed diagnostic bundle from the app when opening an issue.
|
||||
- For slow generation, compare [measured benchmarks](docs/benchmarks.md) and [performance settings](docs/performance.md).
|
||||
|
||||
<a id="features"></a>
|
||||
|
||||
## ✨ Features
|
||||
## Features
|
||||
|
||||
Three flagships, five more headliners, and a dozen under the fold.
|
||||
| Area | Included |
|
||||
|---|---|
|
||||
| **Voice Cloning** | Zero-shot synthesis from a short reference clip |
|
||||
| **Voice Design** | Create a voice from age, accent, pitch, style, and delivery instructions |
|
||||
| **Video Dubbing** | Transcribe, translate, preserve speakers, synthesize, and export video |
|
||||
| **Stories and audiobooks** | Multi-voice scripts · EPUB/PDF import · chapter rendering · `.m4b` export |
|
||||
| **[Dictation Widget](docs/features/dictation.md)** | System-wide shortcut, live transcription, optional local-LLM cleanup |
|
||||
| **Vocal Isolation** | Demucs speech/background separation |
|
||||
| **Speaker Diarization** | Pyannote and WhisperX speaker assignment |
|
||||
| **Batch Queue** | Queue large sets of audio and video jobs with per-job progress |
|
||||
| **Model Catalogue** | Install, remove, select, and route TTS, ASR, and LLM models |
|
||||
| **Remote Model Downloads** | Install models on enrolled remote workers with live progress |
|
||||
| **GPU Auto-Detect** | CUDA, MPS, ROCm, and CPU routing with per-engine checks |
|
||||
| **AI Watermark** | AudioSeal embedding and detection |
|
||||
| **MCP Server** | Synthesis and transcription tools for MCP clients |
|
||||
| **Diagnostics** | Self-checks, error journal, logs, and scrubbed support bundles |
|
||||
| **Local-first** | Core creation stays local; network-backed features are explicit opt-ins |
|
||||
| **Extensible** | Registry-based TTS, ASR, and plugin interfaces |
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td width="33%"><img src="docs/features/clone.png" alt="Voice Cloning" width="100%"/></td>
|
||||
<td width="33%"><img src="docs/features/design.png" alt="Voice Design" width="100%"/></td>
|
||||
<td width="33%"><img src="docs/features/dub.png" alt="Video Dubbing" width="100%"/></td>
|
||||
<td width="50%"><img src="docs/media/0.5.0/catalogue.png" alt="VoiceStudio Model Catalogue" width="100%" /></td>
|
||||
<td width="50%"><img src="docs/media/0.5.0/gallery-save.png" alt="Saving a gallery voice as a local profile" width="100%" /></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center">🎙️ <b>Voice Cloning</b><br/><sub>3-sec clip → any voice · 646 languages · zero-shot</sub></td>
|
||||
<td align="center">🎨 <b>Voice Design</b><br/><sub>Describe it — gender, age, accent, emotion</sub></td>
|
||||
<td align="center">🎬 <b>Video Dubbing</b><br/><sub>Transcribe → translate → re-voice → MP4</sub></td>
|
||||
<td align="center"><sub>Model Catalogue: engine, device, and install state</sub></td>
|
||||
<td align="center"><sub>Gallery: save a shared voice as a local profile</sub></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td align="center" width="20%">📖<br/><b>Audiobook</b><br/><sub>EPUB/PDF → .m4b, multi-voice cast</sub></td>
|
||||
<td align="center" width="20%">🎭<br/><b>Stories</b><br/><sub>Multi-voice script editor</sub></td>
|
||||
<td align="center" width="20%">⌨️<br/><b>Dictation Widget</b><br/><sub><kbd>⌘⇧Space</kbd> in any app</sub></td>
|
||||
<td align="center" width="20%">🔐<br/><b>Local-first</b><br/><sub>Core creation stays on your machine</sub></td>
|
||||
<td align="center" width="20%">🤖<br/><b>MCP Server</b><br/><sub>Use from Claude, Cursor, …</sub></td>
|
||||
</tr>
|
||||
</table>
|
||||
<a id="comparison"></a>
|
||||
|
||||
<details>
|
||||
<summary><b>…and 12 more</b> — catalogue, remote GPUs, isolation, diarization, batch, watermarking, and friends</summary>
|
||||
## Comparison
|
||||
|
||||
<br/>
|
||||
VoiceStudio trades managed cloud compute for local control. This is the practical difference:
|
||||
|
||||
- 📚 **Model Catalogue** — one workspace for every TTS/ASR/LLM engine and model: defaults, device routing, install or remove weights — and quick-switch engines from anywhere with <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd>.
|
||||
- 🖧 **Remote GPU workers** — send jobs to GPUs on your other machines: join code + QR enrolment, Remote Model Downloads with per-worker live progress, chapter-by-chapter audiobook rendering with local fallback. Off by default; see [docs/remote-workers.md](docs/remote-workers.md).
|
||||
- 🔊 **Vocal Isolation** — Demucs-powered: splits speech from music and keeps the background bed.
|
||||
- 👥 **Speaker Diarization** — Pyannote + WhisperX auto-identify who said what.
|
||||
- 📦 **Batch Queue** — drop 50 videos, walk away; per-job progress bars.
|
||||
- 🛡️ **AI Watermark** — AudioSeal (Meta): invisible, survives compression.
|
||||
- 🔬 **Diagnostics** — self-check suite, error journal, scrubbed diagnostic bundles.
|
||||
- ⚡ **GPU Auto-Detect & Routing** — CUDA · MPS · ROCm (Linux, opt-in) · CPU; ≤8 GB VRAM auto-offloads; per-engine GPU preflight, no silent CPU fallback.
|
||||
- 🧩 **Extensible** — subclass `TTSBackend`, add any engine in ~50 lines.
|
||||
- 🎒 **Portable personas** — export voices as `.ovsvoice` bundles: identity + watermark.
|
||||
- ♾️ **Unlimited TTS** — sentence-chunked generation, no length cap, streaming via WebSocket.
|
||||
- 🧠 **Dictation + LLM** — local-LLM cleanup of transcripts, optional echo cancellation.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="quickstart"></a>
|
||||
|
||||
## ⚡ Quickstart
|
||||
|
||||
<div align="center">
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/macOS-DMG_(Apple_Silicon)-000?style=for-the-badge&logo=apple&logoColor=white" alt="Download macOS DMG" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Windows-MSI_(x64)-0078D4?style=for-the-badge&logo=windows&logoColor=white" alt="Download Windows MSI" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Linux-AppImage_(x64)-FCC624?style=for-the-badge&logo=linux&logoColor=black" alt="Download Linux AppImage" /></a>
|
||||
<br/>
|
||||
<sub><b>macOS:</b> first launch needs a one-time approval — right-click → <b>Open</b> (or System Settings → Privacy & Security → <b>"Open Anyway"</b> on macOS 15). No Terminal needed. <a href="docs/install/macos.md#gatekeeper-quarantine">Why?</a> · <b>Intel Macs:</b> local backend unsupported (<a href="https://github.com/debpalash/VoiceStudio/issues/889">#889</a>) — <a href="docs/install/macos.md">details</a>.</sub>
|
||||
</div>
|
||||
|
||||
**Install guide:** [🍎 macOS](docs/install/macos.md) · [🪟 Windows](docs/install/windows.md) · [🐧 Linux](docs/install/linux.md) · [🐳 Docker](docs/install/docker.md)
|
||||
|
||||
<details>
|
||||
<summary><b>🧰 Troubleshooting · slow generation · HF tokens · restricted networks</b></summary>
|
||||
|
||||
<br/>
|
||||
|
||||
- **Something broke?** Run the self-check — **Settings → About → "Run self-check"** (or `uv run python backend/main.py --diagnose --deep`) — then the [top 10 install errors](docs/install/troubleshooting.md). **"Save diagnostic bundle"** packages scrubbed logs for a bug report.
|
||||
- **Feels slow?** [docs/performance.md](docs/performance.md) — where the time goes and how to tune it.
|
||||
- **Want breaths, laughter, emotion?** [docs/expressive-speech.md](docs/expressive-speech.md) — what each engine can do today.
|
||||
- **HF tokens · diarization · download speed / mirrors:** [tokens](docs/setup/huggingface-token.md) · [diarization](docs/features/diarization.md) · [downloads](docs/downloading-models.md).
|
||||
- **Coming from [Real-Time-Voice-Cloning](https://github.com/CorentinJ/Real-Time-Voice-Cloning)?** [Migration guide](docs/migration/real-time-voice-cloning.md).
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="why-voicestudio"></a>
|
||||
|
||||
## ⚖️ Why VoiceStudio
|
||||
|
||||
Cloud voice tools are convenient, but they put your workflow behind an account, a meter, and somebody else's infrastructure. VoiceStudio gives you a capable studio that runs on your hardware, with optional integrations when you choose them.
|
||||
|
||||
| | **ElevenLabs** | **VoiceStudio** |
|
||||
| | **VoiceStudio** | **Typical hosted voice service** |
|
||||
|---|---|---|
|
||||
| **Pricing** | Subscription and usage limits | Free & open-source (AGPL-3.0) · [Commercial license](#license) for proprietary use |
|
||||
| **Voice Cloning** | ✅ 3s clip | ✅ 3s clip, zero-shot |
|
||||
| **Voice Design** | ✅ Gender, age | ✅ Gender, age, accent, pitch, style, dialect |
|
||||
| **Audiobook / Stories** | ❌ | ✅ Full audiobook editor + multi-voice stories (EPUB/PDF import, .m4b export) |
|
||||
| **Languages** | Plan/model dependent | **646** |
|
||||
| **Video Dubbing** | ✅ Cloud-only | ✅ Fully local |
|
||||
| **Data Privacy** | Audio is processed remotely | Core workflow runs locally; online services are explicit opt-ins |
|
||||
| **API Keys** | Account required | Not needed for the local workflow |
|
||||
| **GPU Support** | N/A (cloud) | CUDA · Apple Silicon · ROCm (Linux) · CPU — plus your other machines' GPUs as [remote workers](docs/remote-workers.md) |
|
||||
| **Desktop App** | ❌ | ✅ macOS · Windows · Linux |
|
||||
| **TTS Engines** | 1 | **16** — [full matrix](#tts-engines) |
|
||||
| **ASR Engines** | 1 | **11** — [full lineup](#asr-engines) |
|
||||
| **MCP Server** | ❌ | ✅ Use from Claude, Cursor, any MCP client |
|
||||
| **Self-check** | ❌ | ✅ Diagnostics suite, error journal, scrubbed debug bundles |
|
||||
| **Customizable** | ❌ Closed | ✅ Fork it, extend it, ship it |
|
||||
| **Best fit** | Private, offline, self-hosted, or high-volume work | Fast setup without local model management |
|
||||
| **Data path** | Local by default; remote features are opt-in | Audio and text are processed by the provider |
|
||||
| **Cost model** | Free software; you supply the hardware | Subscription, credits, or metered API use |
|
||||
| **Setup** | Install the app and model weights | Create an account and use the web app or API |
|
||||
| **Performance** | Depends on your engine and hardware | Provider manages compute and scaling |
|
||||
| **Offline use** | Yes, after required models are installed | Usually requires a network connection |
|
||||
| **Customization** | Source, engines, models, API, and routing are open | Limited to provider options |
|
||||
| **Maintenance** | You manage updates, disk, and compute | Provider manages infrastructure |
|
||||
|
||||
Professional-grade voice AI, minus the subscription and the cloud. Convinced? [Come build with us.](https://discord.gg/bzQavDfVV9)
|
||||
<a id="requirements"></a>
|
||||
|
||||
---
|
||||
## Requirements
|
||||
|
||||
## 🖥️ System Requirements
|
||||
Requirements vary by engine. These values cover the default local workflow.
|
||||
|
||||
| | **Minimum** | **Recommended** |
|
||||
|---|---|---|
|
||||
| **OS** | Windows 10, macOS 13.3+ (Apple Silicon), Ubuntu 24.04+ (glibc 2.39+) | Any modern 64-bit OS |
|
||||
| **OS** | Windows 10 x64 · macOS 13.3 Apple Silicon · Linux x86_64 with glibc 2.39+ | Current supported OS release |
|
||||
| **RAM** | 8 GB | 16 GB+ |
|
||||
| **VRAM (GPU)** | 4 GB (auto-offloads TTS to CPU) | 8 GB+ (NVIDIA RTX 3060+) |
|
||||
| **Disk** | 10 GB free (models + cache) | 20 GB+ SSD |
|
||||
| **Python** | 3.10+ (managed by `uv`) | 3.11–3.12 |
|
||||
| **GPU** | Optional — CPU works | NVIDIA CUDA · Apple Silicon MPS · AMD ROCm (Linux only) |
|
||||
| **Disk** | 10 GB free | 20 GB+ SSD |
|
||||
| **GPU** | Optional; CPU mode is supported | NVIDIA CUDA or Apple Silicon |
|
||||
| **VRAM** | 4 GB when using a GPU | 8 GB+; large optional engines need more |
|
||||
| **Python from source** | 3.11+ | 3.11–3.12 |
|
||||
|
||||
> [!NOTE]
|
||||
> **A GPU is optional** — the whole pipeline runs on CPU (just slower), and on ≤8 GB VRAM, TTS auto-offloads to CPU. Caveats: **AMD ROCm** is Linux-only + opt-in ([Linux](docs/install/linux.md#amd-gpu-rocm)) — Windows AMD/Ryzen AI is CPU-only ([Windows](docs/install/windows.md#gpu-support)); **macOS Intel** can't run the local backend, so point it at a remote one ([#889](https://github.com/debpalash/VoiceStudio/issues/889) · [macOS](docs/install/macos.md)).
|
||||
ROCm is Linux-only and opt-in. Windows AMD/Ryzen AI uses CPU. Systems with limited VRAM offload work to CPU when required. See [performance](docs/performance.md), [benchmarks](docs/benchmarks.md), and [engine disk usage](docs/engines/disk-usage.md).
|
||||
|
||||
<a id="engines"></a>
|
||||
|
||||
## Engines
|
||||
|
||||
Engine support is capability-specific. Check cloning, language, platform, memory, and license before choosing one. Full setup guides: [docs/engines](docs/engines/README.md).
|
||||
|
||||
<a id="tts-engines"></a>
|
||||
|
||||
### 🗣️ TTS Engines
|
||||
|
||||
**16 engines, one picker.** VoiceStudio (default, 600+ languages) is always available; seven more are opt-in and auto-detected (CosyVoice 3, GPT-SoVITS, VoxCPM2, MOSS-TTS-Nano, KittenTTS, MLX-Audio, Sherpa-ONNX), plus eight lazy-installed opt-ins (IndexTTS 2.5, OmniVoice GGUF, OmniVoice subprocess, PocketTTS, Supertonic 3, MOSS-TTS-v1.5, dots.tts, Confucius4-TTS). Switch in **Model Catalogue → Engines** — or from anywhere with <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd>; the choice applies everywhere synthesis happens.
|
||||
|
||||
<details>
|
||||
<summary><b>📊 The full matrix</b> — 16 engines × platform × clone/instruct × license</summary>
|
||||
|
||||
<br/>
|
||||
### Text to speech
|
||||
|
||||
| Engine | Languages | Clone | Instruct | Linux | macOS ARM | Windows | License |
|
||||
|--------|:---------:|:-----:|:--------:|:-----:|:---------:|:-------:|:-------:|
|
||||
| **VoiceStudio** (default, powered by k2-fsa/OmniVoice) | 600+ | ✅ | ✅ | ✅ CUDA/CPU | ✅ MPS | ✅ CUDA/CPU | Built-in |
|
||||
| **CosyVoice 3** | 9 + 18 dialects | ✅ | ✅ | ✅ CUDA/CPU | ✅ MPS | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **GPT-SoVITS** | 5 | ✅ | — | ✅ CUDA/CPU | — | ✅ CUDA/CPU | MIT |
|
||||
| **VoxCPM2** | 30 | ✅ | ✅ | ✅ CUDA/CPU | ✅ MPS | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **MOSS-TTS-Nano** | 20 | ✅ | — | ✅ CUDA/CPU | ✅ CPU | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **KittenTTS** | English | — | — | ✅ CPU | ✅ CPU | ✅ CPU | MIT |
|
||||
| **MLX-Audio** (Kokoro, Qwen3-TTS, CSM, Dia, …) | Multi | Varies | Varies | ❌ | ✅ Native | ❌ | Varies |
|
||||
| **Sherpa-ONNX** | 20+ | — | — | ✅ CUDA/CPU | ✅ CPU | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **IndexTTS 2.5** ⚡ | ZH · EN · JA · ES · AR | ✅ | — | ✅ CUDA | — | ✅ CUDA | Bilibili model license¹ |
|
||||
| **OmniVoice GGUF** ⚡ | 600+ | ✅ | ✅ | ✅ CPU | ✅ CPU | ✅ CPU | Built-in |
|
||||
| **OmniVoice (subprocess)** ⚡² | 600+ | ✅ | ✅ | ✅ CUDA/CPU | ✅ MPS | ✅ CUDA/CPU | Built-in |
|
||||
| **PocketTTS** ⚡ (Kyutai) | EN · FR · DE · PT · IT · ES | ✅ | — | ✅ CPU | ✅ CPU | ✅ CPU | CC-BY-4.0 (gated)³ |
|
||||
| **Supertonic 3** ⚡ | 31 | — | — | ✅ CPU | ✅ CPU | ✅ CPU | OpenRAIL-M |
|
||||
| **MOSS-TTS-v1.5** ⚡ (8B) | 31 | ✅ | — | ✅ CUDA/CPU | ✅ CPU | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **dots.tts** ⚡ (2B) | 24 | ✅ | — | ✅ CUDA/CPU | ✅ CPU | ❌ | Apache-2.0 |
|
||||
| **Confucius4-TTS** ⚡ | 14 | ✅ | — | ✅ CUDA/CPU | ✅ CPU | ✅ CUDA/CPU | Apache-2.0 |
|
||||
|---|:---:|:---:|:---:|:---:|:---:|:---:|---|
|
||||
| **VoiceStudio** (default, powered by k2-fsa/OmniVoice) | 600+ | Yes | Yes | CUDA/CPU | MPS | CUDA/CPU | [AGPL-3.0](LICENSE) app · [Apache-2.0](LICENSE-NOTICE.md) model |
|
||||
| **CosyVoice 3** | 9 + 18 dialects | Yes | Yes | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
| **GPT-SoVITS** | 5 | Yes | — | CUDA/CPU | — | CUDA/CPU | MIT |
|
||||
| **VoxCPM2** | 30 | Yes | Yes | CUDA/CPU | MPS | CUDA/CPU | Apache-2.0 |
|
||||
| **MOSS-TTS-Nano** | 20 | Yes | — | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
| **KittenTTS** | English | — | — | CPU | CPU | CPU | MIT |
|
||||
| **MLX-Audio** | Model-dependent | Varies | Varies | — | MLX | — | Varies |
|
||||
| **Sherpa-ONNX** | 20+ | — | — | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
| **IndexTTS 2.5** ⚡ | ZH · EN · JA · ES · AR | Yes | — | CUDA/CPU | CPU | CUDA/CPU | Bilibili model license¹ |
|
||||
| **OmniVoice GGUF** ⚡ | 600+ | Yes | Yes | CUDA/CPU | MPS/CPU | CUDA/CPU | [AGPL-3.0](LICENSE) app · [Apache-2.0](LICENSE-NOTICE.md) model |
|
||||
| **OmniVoice (subprocess)** ⚡ | 600+ | Yes | Yes | CUDA/CPU | MPS | CUDA/CPU | [AGPL-3.0](LICENSE) app · [Apache-2.0](LICENSE-NOTICE.md) model |
|
||||
| **PocketTTS** ⚡ | EN · FR · DE · PT · IT · ES | Yes | — | CPU | CPU | CPU | CC-BY-4.0, gated² |
|
||||
| **Supertonic 3** ⚡ | 31 | — | — | CPU | CPU | CPU | OpenRAIL-M |
|
||||
| **MOSS-TTS-v1.5** ⚡ | 31 | Yes | — | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
| **dots.tts** ⚡ | 24 | Yes | — | CUDA/CPU | CPU | — | Apache-2.0 |
|
||||
| **Confucius4-TTS** ⚡ | 14 | Yes | — | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
|
||||
¹ IndexTTS 2.5 requires a separate written Bilibili license above 100 million
|
||||
monthly active users or RMB 1 billion in annual revenue. Review its
|
||||
[model license](https://huggingface.co/IndexTeam/IndexTTS-2.5/blob/main/LICENSE)
|
||||
before enabling the optional sidecar.
|
||||
⚡ Installed or registered on demand.
|
||||
|
||||
² **OmniVoice (subprocess)** is the same resident model as the default engine, run
|
||||
in a crash-isolated child process: a wedged generation can be hard-killed and its
|
||||
VRAM reclaimed. Opt-in for unattended synthesis and VRAM-tight MPS hosts —
|
||||
[docs/engines/omnivoice-subprocess.md](docs/engines/omnivoice-subprocess.md).
|
||||
¹ IndexTTS 2.5 requires a separate written Bilibili license above 100 million monthly active users or RMB 1 billion annual revenue. Review the [model license](https://huggingface.co/IndexTeam/IndexTTS-2.5/blob/main/LICENSE).
|
||||
|
||||
³ **PocketTTS** (Kyutai) is a fast, low-latency CPU engine with zero-shot cloning;
|
||||
its gated model access and CC-BY-4.0 conditions are shown for review in-app before
|
||||
first use.
|
||||
² PocketTTS shows its gated-access and CC-BY-4.0 terms before first use.
|
||||
|
||||
GPT-SoVITS connects to `http://127.0.0.1:9880` by default. To use a server on
|
||||
another machine, set `OMNIVOICE_GPTSOVITS_URL` to its credential-free
|
||||
`http://` or `https://` origin and add that machine's CIDR to
|
||||
`OMNIVOICE_TRUSTED_NETWORKS`; redirects and untrusted destinations are rejected.
|
||||
|
||||
> **CUDA** = GPU-accelerated · **MPS** = Apple Silicon Metal · **CPU** = runs everywhere, slower for large models · KittenTTS, MOSS-TTS-Nano, and PocketTTS run realtime on CPU · MLX-Audio is Apple Silicon only · ⚡ = lazy-registered (installed on first use)
|
||||
>
|
||||
> **Clone** matters beyond single-clip generation: Video Dubbing (and any Batch job with a pinned voice) needs reference-audio cloning to preserve speaker identity, so picking a Clone-less engine (KittenTTS, Sherpa-ONNX, Supertonic 3) as the active engine fails those jobs up front with an actionable message instead of silently falling back to VoiceStudio.
|
||||
>
|
||||
> **MOSS-TTS-v1.5** (8B, ~16 GB), **dots.tts** (2B, ~9 GB), and **Confucius4-TTS** are heavyweight opt-ins that run in their own isolated venv from a local clone. None claims Apple-Silicon MPS (CPU on Macs); dots.tts has no Windows path; Confucius4 wants CUDA (CPU works, ~17× realtime). Details: [MOSS-TTS-v1.5](docs/engines/moss-tts-v15.md) · [dots.tts](docs/engines/dots-tts.md) · [Confucius4-TTS](docs/engines/confucius4-tts.md).
|
||||
|
||||
</details>
|
||||
Clone-less engines cannot preserve a reference speaker in dubbing or pinned-voice batch jobs. VoiceStudio rejects those jobs instead of silently changing engines. Heavy engines have separate memory and platform limits; check their engine guide first.
|
||||
|
||||
<a id="asr-engines"></a>
|
||||
|
||||
### 🎧 ASR Engines
|
||||
### Speech to text
|
||||
|
||||
**11 engines** — they power dictation, video dubbing, and subtitles. **WhisperX** is the cross-platform default (~100 languages, word-level timing); the rest are opt-in and auto-detected. Switch in **Model Catalogue → Engines**. Ten run fully on-device; the eleventh (OpenAI-compatible) is an optional remote client for Qwen3-ASR or any compatible server.
|
||||
| Engine | ID | Languages | Best fit |
|
||||
|---|---|:---:|---|
|
||||
| **WhisperX** (default) | `whisperx` | ~100 | Dubbing, subtitles, word-level timing |
|
||||
| **Faster-Whisper** | `faster-whisper` | ~100 | General cross-platform transcription |
|
||||
| **Faster-Whisper (isolated)** | `faster-whisper-isolated` | ~100 | Crash-isolated batch transcription |
|
||||
| **MLX Whisper** | `mlx-whisper` | ~100 | Apple Silicon |
|
||||
| **PyTorch Whisper** | `pytorch-whisper` | ~100 | CUDA, MPS, and CPU fallback |
|
||||
| **Parakeet TDT** | `nemo-parakeet` | English + 25 EU | Fast CPU/CUDA transcription |
|
||||
| **Parakeet TDT v3 (MLX)** | `parakeet-mlx` | 25 EU | Apple Silicon dictation and word timestamps |
|
||||
| **Moonshine** | `moonshine` | English | Low-power, low-latency ONNX |
|
||||
| **FunASR** | `funasr` | 50+ | VAD and inline diarization |
|
||||
| **sherpa-onnx** (live dictation) | `sherpa-onnx-asr` | Model-dependent | Streaming CPU dictation |
|
||||
| **OpenAI-compatible** ⚠️ remote | `openai-compat-asr` | Server-dependent | Qwen3-ASR or another compatible endpoint; audio leaves the machine |
|
||||
|
||||
<details>
|
||||
<summary><b>📊 The full lineup</b> — 11 engines, what each is best at, and compute-type notes</summary>
|
||||
WhisperX and Faster-Whisper retry with `int8` when efficient `float16` is unavailable. Pin `ASR_COMPUTE_TYPE=int8` or `float32` only if automatic selection still fails.
|
||||
|
||||
<br/>
|
||||
<a id="architecture"></a>
|
||||
|
||||
| Engine | `OMNIVOICE_ASR_BACKEND` | Languages | Best for |
|
||||
|--------|-------------------------|:---------:|----------|
|
||||
| **WhisperX** (default) | `whisperx` | ~100 | Dubbing & subtitles — word-level timing via wav2vec2 forced alignment |
|
||||
| **Faster-Whisper** | `faster-whisper` | ~100 | Fast transcription on Linux / macOS / Windows (CTranslate2) |
|
||||
| **Faster-Whisper (isolated)** | `faster-whisper-isolated` | ~100 | Same as Faster-Whisper but crash-isolated in a subprocess — an ASR crash won't take down the app |
|
||||
| **MLX Whisper** | `mlx-whisper` | ~100 | Native Apple Silicon speed (Apple MLX / Metal) |
|
||||
| **PyTorch Whisper** | `pytorch-whisper` | ~100 | CUDA / CPU fallback via 🤗 Transformers (no cuDNN 8 needed) |
|
||||
| **Parakeet TDT** | `nemo-parakeet` | English + 25 EU | SOTA accuracy at ~10× realtime even on CPU, auto language detection (NVIDIA NeMo, CUDA/CPU) |
|
||||
| **Parakeet TDT v3 (MLX)** | `parakeet-mlx` | 25 EU | The Parakeet tier for Apple Silicon — word timestamps, ~2 GB unified memory, dictation-grade speed via MLX. Dictation prefers it automatically for its 25 European languages; other languages keep multilingual Whisper. |
|
||||
| **Moonshine** | `moonshine` | English | Edge / low-latency, ONNX |
|
||||
| **FunASR** | `funasr` | 50+ | All-in-one multilingual — built-in VAD + inline speaker diarization (SenseVoice) |
|
||||
| **sherpa-onnx** (live dictation) | `sherpa-onnx-asr` | 25 EU + 90+ | Live, faster-than-real-time dictation — small streaming/offline ONNX models, CPU, identical on macOS / Windows / Linux. Picked per-model in **Settings → Voice**. |
|
||||
| **OpenAI-compatible** ⚠️ remote | `openai-compat-asr` | Server-dependent | A path to **Qwen3-ASR** today (self-hosted server), any OpenAI-compatible transcription endpoint, or OpenAI's own API — configure + test in **Model Catalogue → Engines** (ASR tab). Audio leaves your machine to whatever server you point it at; see [docs/engines/openai-compatible-asr.md](docs/engines/openai-compatible-asr.md). |
|
||||
## Architecture
|
||||
|
||||
> If Dubbing needs an ASR model that is not installed yet, it offers the recommended download in place, shows its progress, and retries transcription on the same job when the model is ready.
|
||||
>
|
||||
> **GPU without efficient float16?** On older NVIDIA GPUs (Maxwell/Pascal, GTX 16xx) or after a CTranslate2/cuDNN mismatch, the CTranslate2 ASR engines (WhisperX, Faster-Whisper) can't run `float16` and VoiceStudio automatically retries on `int8` — no config needed. If transcription still fails, pin the compute type with `ASR_COMPUTE_TYPE=int8` (or `float32` for CPU) and restart the backend.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 🏗️ Architecture
|
||||
|
||||
A **Tauri v2** desktop shell (Rust) wraps a **React** UI and a bundled **Python/FastAPI** backend that runs as a local sidecar on `localhost:3900`. Every layer runs on your machine by default; the only network paths are the ones you opt into (remote GPU workers, a remote backend, or an OpenAI-compatible ASR endpoint).
|
||||
|
||||
```
|
||||
┌────────────────────────────────────────────────────────────────────┐
|
||||
│ Tauri v2 shell — Rust │
|
||||
│ window state · global dictation hotkey · system tray · │
|
||||
│ signed auto-updater (stable/preview) · single-instance · │
|
||||
│ first-run bootstrap (installs uv + Python venv) · blank guard │
|
||||
├────────────────────────────────────────────────────────────────────┤
|
||||
│ Frontend — React + Vite │
|
||||
│ Studio · Dub · Stories · Audiobook · Gallery · Catalogue · │
|
||||
│ Dictation · Batch · Diagnostics — Zustand store · WS bus │
|
||||
│ ▲ IPC / HTTP + WS │
|
||||
├──────────────────────────┼─────────────────────────────────────────┤
|
||||
│ Backend — FastAPI sidecar @ localhost:3900 │
|
||||
│ 100+ REST endpoints · SSE + WebSocket streaming · │
|
||||
│ SQLite + Alembic (omnivoice_data/) · OpenAI-compatible API │
|
||||
├───────────┬───────────┬───────────┬───────────┬────────────────────┤
|
||||
│ TTS ×16 │ ASR ×11 │ Demucs │ Pyannote │ AudioSeal │
|
||||
│ clone / │ WhisperX │ vocal │ speaker │ watermark │
|
||||
│ design │ +10 more │ isolation│ diariz. │ embed / detect │
|
||||
├───────────┴───────────┴───────────┴───────────┴────────────────────┤
|
||||
│ Engine routing — per-engine GPU preflight, no silent CPU fallback │
|
||||
│ Hardware: CUDA · MPS · ROCm (Linux) · CPU (auto-detected) │
|
||||
│ + optional remote GPU workers on your other machines │
|
||||
└────────────────────────────────────────────────────────────────────┘
|
||||
```text
|
||||
Tauri v2 desktop shell (Rust)
|
||||
│ IPC
|
||||
React + Vite UI
|
||||
│ HTTP · SSE · WebSocket on localhost:3900
|
||||
FastAPI backend
|
||||
├── TTS / ASR engine registries
|
||||
├── dubbing / audio / long-form pipelines
|
||||
├── OpenAI-compatible API and MCP server
|
||||
└── SQLite + Alembic → omnivoice_data/
|
||||
```
|
||||
|
||||
<a id="openai-api"></a>
|
||||
| Layer | Path | Responsibility |
|
||||
|---|---|---|
|
||||
| Desktop shell | `frontend/src-tauri/` | Window lifecycle, tray, shortcuts, updater, sidecar bootstrap |
|
||||
| Frontend | `frontend/src/` | React UI, Zustand state, API and event clients, i18n |
|
||||
| API | `backend/api/` | REST routes, schemas, auth boundaries, streaming |
|
||||
| Core services | `backend/services/` | Generation, dubbing, audio processing, persistence |
|
||||
| Engines | `backend/engines/` | Isolated and optional engine adapters |
|
||||
| Worker system | `backend/worker/` | Authenticated remote compute and job transport |
|
||||
| Data | `omnivoice_data/` | Projects, voices, settings, logs, and SQLite state |
|
||||
| Delivery | `scripts/`, `deploy/`, `.github/workflows/` | Development, packaging, containers, releases, CI |
|
||||
|
||||
## 🔌 OpenAI-compatible API
|
||||
### Network boundary
|
||||
|
||||
<div align="center">
|
||||
- The desktop talks to a loopback-only backend on `localhost:3900`.
|
||||
- Loopback API calls need no server key. Remote access requires a share PIN or API key.
|
||||
- Remote workers and OpenAI-compatible ASR are opt-in. The UI identifies when audio leaves the machine.
|
||||
- Analytics is off until consent. If enabled, it sends allowlisted, content-free usage metadata—not text, audio, file names, or projects.
|
||||
|
||||
**Drop-in replacement for OpenAI / ElevenLabs audio.** One line — no key, no code changes:
|
||||
<a id="api"></a>
|
||||
|
||||
## OpenAI-compatible API
|
||||
|
||||
Point an OpenAI-compatible audio client at the local backend:
|
||||
|
||||
```diff
|
||||
- base_url="https://api.openai.com/v1"
|
||||
+ base_url="http://localhost:3900/v1"
|
||||
```
|
||||
|
||||
</div>
|
||||
|
||||
Your existing scripts, agents, and OpenAI/ElevenLabs SDK calls now run **locally** on whatever engine you have active. What the cloud can't do: `voice` takes **your own cloned-voice profile IDs**, and `model` can pin a **specific engine** per request.
|
||||
|
||||
| Endpoint | What it does |
|
||||
| Endpoint | Purpose |
|
||||
|---|---|
|
||||
| `POST /v1/audio/speech` | TTS — text in; `mp3` / `opus` / `aac` / `flac` / `wav` / `pcm` out. `model`: `tts-1`/`tts-1-hd` (active engine) or a specific one (`voxcpm2`, `cosyvoice`, …). `voice`: a cloned profile ID, `default`, or an OpenAI name (`alloy`, …). `speed` supported. |
|
||||
| `POST /v1/audio/transcriptions` | STT — audio file in; `json` / `text` / `verbose_json` / `srt` / `vtt` out (`verbose_json` adds word-level timings). `whisper-1` maps to your active ASR engine. |
|
||||
| `GET /v1/audio/voices` | VoiceStudio extension — lists every voice profile and engine, so clients can discover your clones. |
|
||||
|
||||
**Speak with your own cloned voice:**
|
||||
| `POST /v1/audio/speech` | TTS to `mp3`, `opus`, `aac`, `flac`, `wav`, or `pcm`; select a profile with `voice` and an engine with `model` |
|
||||
| `POST /v1/audio/transcriptions` | STT to `json`, `text`, `verbose_json`, `srt`, or `vtt` |
|
||||
| `GET /v1/audio/voices` | List local voice profiles and engines |
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
client = OpenAI(base_url="http://localhost:3900/v1", api_key="none") # any string — nothing checks it
|
||||
|
||||
# Find your cloned voices: GET /v1/audio/voices lists profile IDs
|
||||
client = OpenAI(base_url="http://localhost:3900/v1", api_key="local")
|
||||
|
||||
with client.audio.speech.with_streaming_response.create(
|
||||
model="tts-1", voice="<profile-id>", input="Made on my own hardware.") as r:
|
||||
r.stream_to_file("speech.wav")
|
||||
|
||||
# STT
|
||||
print(client.audio.transcriptions.create(model="whisper-1", file=open("clip.wav", "rb")).text)
|
||||
model="tts-1",
|
||||
voice="<profile-id>",
|
||||
input="Made on my own hardware.",
|
||||
response_format="wav",
|
||||
) as response:
|
||||
response.stream_to_file("speech.wav")
|
||||
```
|
||||
|
||||
Want the whole surface (100+ endpoints)? The full REST API reference is embedded in the app — **Settings → OpenAPI Reference** (Scalar-powered), or the `{}` button in the footer.
|
||||
The full API reference is in **Settings → OpenAPI Reference**. For LAN, Tailscale, or proxy access, read [API authentication](docs/api-auth.md) before exposing the backend.
|
||||
|
||||
Calling the backend from **another machine** (LAN, Tailscale, behind a proxy)? It's loopback-only and unauthenticated by default; to reach it remotely you set a share PIN or an API key, and admin actions require the key — exchanged for short-lived scoped sessions. [docs/api-auth.md](docs/api-auth.md) covers the exact headers, query params, `401`/`403`/`429` meanings, and the `OMNIVOICE_TRUSTED_NETWORKS` exemption.
|
||||
### Agent skills
|
||||
|
||||
### 📓 Run on Google Colab
|
||||
Install the VoiceStudio skills for Claude Code, Codex, Cursor, and other [skills.sh](https://skills.sh)-compatible agents:
|
||||
|
||||
[](https://colab.research.google.com/github/debpalash/VoiceStudio/blob/main/notebooks/OmniVoice_Studio_Colab.ipynb)
|
||||
|
||||
No local GPU? The [official notebook](notebooks/OmniVoice_Studio_Colab.ipynb) boots the full app — web UI included — on a free Colab T4, then walks the whole feature surface as a guided tour with inline playback. No tunnels, no API keys.
|
||||
|
||||
### 🤝 Agent Skills
|
||||
|
||||
Teach your coding agent to speak and listen through your local VoiceStudio — one command, works with **Claude Code, Codex, Cursor, Grok, Kimi, opencode**, and any [skills.sh](https://skills.sh)-compatible agent:
|
||||
|
||||
```sh
|
||||
```bash
|
||||
npx skills add debpalash/omnivoice-studio
|
||||
```
|
||||
|
||||
Ships two skills: **`omnivoice`** — generate speech (including your cloned voices) and transcribe audio from any agent, free and fully offline — and **`oss-maintainer`** — the maintainer methodology this project is run with.
|
||||
- `omnivoice`: synthesize speech and transcribe audio through local VoiceStudio.
|
||||
- `oss-maintainer`: the repository's open-source maintenance workflow.
|
||||
|
||||
---
|
||||
### Google Colab
|
||||
|
||||
<a id="roadmap"></a>
|
||||
[](https://colab.research.google.com/github/debpalash/VoiceStudio/blob/main/notebooks/OmniVoice_Studio_Colab.ipynb)
|
||||
|
||||
## 🗺️ Roadmap
|
||||
The [notebook](notebooks/OmniVoice_Studio_Colab.ipynb) runs the app and web UI on a Colab GPU. Colab is remote compute, so uploaded audio and project data do not remain local to your machine.
|
||||
|
||||
What's up next (lip-sync v2, hosted demo, plugin marketplace, real-time voice changer) and the full history of everything shipped so far live in **[docs/ROADMAP.md](docs/ROADMAP.md)**.
|
||||
<a id="documentation"></a>
|
||||
|
||||
---
|
||||
## Documentation
|
||||
|
||||
<a id="sponsor--donate"></a>
|
||||
| Need | Read |
|
||||
|---|---|
|
||||
| Install | [macOS](docs/install/macos.md) · [Windows](docs/install/windows.md) · [Linux](docs/install/linux.md) · [Docker](docs/install/docker.md) |
|
||||
| Fix setup | [Troubleshooting](docs/install/troubleshooting.md) · [model downloads](docs/downloading-models.md) · [Hugging Face token](docs/setup/huggingface-token.md) |
|
||||
| Choose an engine | [Engine guides](docs/engines/README.md) · [benchmarks](docs/benchmarks.md) · [expressive speech](docs/expressive-speech.md) |
|
||||
| Tune hardware | [Performance](docs/performance.md) · [remote workers](docs/remote-workers.md) |
|
||||
| Build integrations | [API auth](docs/api-auth.md) · [MCP](docs/mcp.md) · [examples](examples/README.md) |
|
||||
| Build VoiceStudio | [Contributing](.github/CONTRIBUTING.md) · [engine acceptance](docs/engine-acceptance.md) |
|
||||
| Track changes | [Changelog](CHANGELOG.md) · [roadmap](docs/ROADMAP.md) · [latest release](https://github.com/debpalash/VoiceStudio/releases/latest) |
|
||||
| Remove everything | [Uninstall guide](docs/install/uninstall.md) |
|
||||
|
||||
## 💜 Sponsor / Donate
|
||||
## FAQ
|
||||
|
||||
One developer, real AI-agent bills. If VoiceStudio is useful to you, chipping in keeps development full-time — every dollar goes straight to the bills.
|
||||
<details>
|
||||
<summary><strong>Does it work on Apple Silicon and Intel Macs?</strong></summary>
|
||||
|
||||
Apple Silicon is supported with MPS and MLX options. Intel Macs cannot run the local backend because current PyTorch wheels are unavailable; they can connect to a remote backend. See [macOS installation](docs/install/macos.md).
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>How much VRAM do I need?</strong></summary>
|
||||
|
||||
A GPU is optional. Use 4 GB VRAM as the minimum for accelerated work and 8 GB+ for the default multi-stage workflow. Large optional engines can require 12–16 GB or more. Check the [benchmarks](docs/benchmarks.md) and engine guide.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>Why does a longer reference clip not always improve the clone?</strong></summary>
|
||||
|
||||
Cloning is zero-shot: the clip is a prompt, not training data. Use 5–15 seconds of one speaker, close to the microphone, without music, noise, or reverb. Match the tone and pace you want in the output. For training, see [data preparation](docs/data_preparation.md) and [training](docs/training.md).
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>Can I use generated audio commercially?</strong></summary>
|
||||
|
||||
Yes under VoiceStudio's AGPL-3.0 terms. Optional engines and model weights may use different licenses; review the selected engine's license before commercial use.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>Does VoiceStudio collect data?</strong></summary>
|
||||
|
||||
Not unless you opt in. Analytics is off by default and skipping consent keeps it off. When enabled, the app sends allowlisted, content-free usage metadata. Text, audio, file names, voices, and projects are excluded. Change this at **Settings → Privacy**.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>How do I remove VoiceStudio and its data?</strong></summary>
|
||||
|
||||
Use `scripts/uninstall.sh` on macOS/Linux or `scripts\uninstall.ps1` on Windows. Both show a dry run before deletion. See the [uninstall guide](docs/install/uninstall.md) for every path.
|
||||
</details>
|
||||
|
||||
## Community and contributing
|
||||
|
||||
- [GitHub Issues](https://github.com/debpalash/VoiceStudio/issues) for reproducible bugs and feature requests.
|
||||
- [Discord](https://discord.gg/bzQavDfVV9) for setup help and project discussion.
|
||||
- [Good first issues](https://github.com/debpalash/VoiceStudio/labels/good%20first%20issue) for a scoped starting point.
|
||||
- [Contributing guide](.github/CONTRIBUTING.md) for setup, tests, and pull requests.
|
||||
|
||||
## Support development
|
||||
|
||||
VoiceStudio is free and has no paid tier. Donations fund development and infrastructure.
|
||||
|
||||
[Ko-fi](https://ko-fi.com/debpalash) · [PayPal](https://paypal.me/palashCoder) · [Sponsorship details](SPONSORS.md)
|
||||
|
||||
## License
|
||||
|
||||
VoiceStudio is licensed under [AGPL-3.0](LICENSE). You may run it, modify it, use it internally, and sell generated audio. If you modify VoiceStudio and provide that modified version as a network service, AGPL requires you to offer the corresponding source under the same license. A commercial license is available for proprietary embedding; contact **VoiceStudio@palash.dev**. See [LICENSE-NOTICE.md](LICENSE-NOTICE.md) for the plain-language scope.
|
||||
|
||||
Optional engines and downloaded models retain their own licenses. The bundled `omnivoice/` model remains Apache-2.0 upstream.
|
||||
|
||||
## Acknowledgments
|
||||
|
||||
VoiceStudio builds on [OmniVoice](https://github.com/k2-fsa/OmniVoice), [WhisperX](https://github.com/m-bain/whisperX), [Demucs](https://github.com/facebookresearch/demucs), [Pyannote](https://github.com/pyannote/pyannote-audio), [CTranslate2](https://github.com/OpenNMT/CTranslate2), [AudioSeal](https://github.com/facebookresearch/audioseal), [Tauri](https://tauri.app), [Supertonic](https://huggingface.co/Supertone/supertonic-3), [Sherpa-ONNX](https://github.com/k2-fsa/sherpa-onnx), [GPT-SoVITS](https://github.com/RVC-Boss/GPT-SoVITS), and [PocketTTS](https://kyutai.org).
|
||||
|
||||
<div align="center">
|
||||
|
||||
<img src="https://img.shields.io/badge/raised_%2410_of_%24200-5%25-EAB308?style=for-the-badge" alt="This month's agent-bill fund: $10 / $200" />
|
||||
|
||||
<br/><br/>
|
||||
|
||||
<a href="https://ko-fi.com/debpalash"><img src="https://img.shields.io/badge/Ko--fi-Support_❤️-FF5E5B?style=for-the-badge&logo=ko-fi&logoColor=white" alt="Ko-fi" /></a>
|
||||
|
||||
<a href="https://paypal.me/palashCoder"><img src="https://img.shields.io/badge/PayPal-Donate-00457C?style=for-the-badge&logo=paypal&logoColor=white" alt="PayPal" /></a>
|
||||
|
||||
</div>
|
||||
|
||||
<a id="sponsors"></a>
|
||||
|
||||
### 🌟 Sponsors
|
||||
|
||||
VoiceStudio is **free** and **AGPL-3.0** — no paid tier, no SaaS revenue. Sponsors keep development going, and in return get a logo slot here, in the app, and (for top tiers) on the project website. It's a thank-you, never a paywall. **[See tiers & become a sponsor →](SPONSORS.md)**
|
||||
|
||||
<div align="center">
|
||||
|
||||
<!-- SPONSORS:START — logo slots are filled here as sponsors come aboard; see SPONSORS.md -->
|
||||
|
||||
**Your logo here** — [become a sponsor](SPONSORS.md)
|
||||
|
||||
<!-- SPONSORS:END -->
|
||||
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
## 💬 Community
|
||||
|
||||
<div align="center">
|
||||
<a href="https://discord.gg/bzQavDfVV9"><img src="https://img.shields.io/badge/💬_Discord-Join_Community-5865F2?style=for-the-badge&logo=discord&logoColor=white" alt="Join Discord" /></a>
|
||||
<a href="https://x.com/idebpalash"><img src="https://img.shields.io/badge/𝕏_Follow-for_updates-000000?style=for-the-badge&logo=x&logoColor=white" alt="Follow on X" /></a>
|
||||
<br/>
|
||||
<sub>Release news, setup help, GPU troubleshooting, feature votes, and showing off your dubs. We respond to setup questions within hours, not days.</sub>
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
<a id="contributing"></a>
|
||||
|
||||
## 🤝 Contributing
|
||||
|
||||
Yes please — bug fixes, new TTS engine adapters, UI improvements, docs, translations. All of it. Start with the **[Contributing Guide](.github/CONTRIBUTING.md)** (setup, code style, PR workflow), browse [good first issues](https://github.com/debpalash/VoiceStudio/labels/good%20first%20issue), or ask in [Discord](https://discord.gg/bzQavDfVV9).
|
||||
|
||||
---
|
||||
|
||||
## ❓ FAQ
|
||||
|
||||
<details>
|
||||
<summary><b>Does it work on Apple Silicon (M1/M2/M3/M4)?</b></summary>
|
||||
<br/>
|
||||
Yes. MPS acceleration is auto-detected. MLX-optimized Whisper models are available for faster transcription on Apple hardware. <b>Intel Macs are not supported</b>: the app UI installs, but the local Python backend cannot run because PyTorch no longer ships Intel-Mac wheels (<a href="https://github.com/debpalash/VoiceStudio/issues/889">#889</a>) — an Intel Mac can only be used with a remote backend.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>How much VRAM do I need?</b></summary>
|
||||
<br/>
|
||||
<b>4 GB minimum.</b> With ≤8 GB, the TTS model is automatically offloaded to CPU during transcription. With 8+ GB, everything runs on GPU simultaneously. No GPU at all? CPU mode works — just slower (~3× for TTS). You can also lend a GPU from another machine you own via <a href="docs/remote-workers.md">remote workers</a>.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>What languages are supported?</b></summary>
|
||||
<br/>
|
||||
646 languages for TTS via the VoiceStudio model. Transcription (WhisperX) supports 99 languages. Translation coverage depends on the target language pair.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Why doesn't a longer reference clip sound more like me?</b></summary>
|
||||
<br/>
|
||||
Because VoiceStudio's cloning is <b>zero-shot</b>: your clip is a <i>prompt</i> the model conditions on — it is never trained on, and past a short window extra audio is simply unused (the dubbing pipeline targets ~8 s and hard-caps at 15 s). <b>What moves clone quality is the clip, not its length</b>: record 5–15 seconds of continuous natural speech, close to the mic, in a quiet room with no reverb or music, one speaker, delivered in the tone and pace you want — the clone copies your delivery, not just your timbre. Want trained-on-your-voice fidelity? That's offline fine-tuning, not an in-app button: <a href="docs/data_preparation.md">docs/data_preparation.md</a> + <a href="docs/training.md">docs/training.md</a>.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Can I use this commercially?</b></summary>
|
||||
<br/>
|
||||
<b>Yes — commercial use is free</b> under the <a href="https://www.gnu.org/licenses/agpl-3.0.html">AGPL-3.0</a>: run it, sell the audio you make, dub client videos, deploy it across your team. One obligation: if you <b>modify</b> VoiceStudio and offer the modified version to others over a network, you must share that modified source under the same terms. Embedding it in a closed-source product instead? A commercial license is available — see <a href="#license">License</a>.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Can I add my own TTS engine?</b></summary>
|
||||
<br/>
|
||||
Yes. Subclass <code>TTSBackend</code> in <code>backend/services/tts_backend.py</code> and add it to the <code>_REGISTRY</code> dictionary — ~50 lines. The sixteen built-in engines all work this way; see <a href="#tts-engines">TTS Engines</a> and <a href="docs/engine-acceptance.md">docs/engine-acceptance.md</a>.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Does VoiceStudio collect any data about me?</b></summary>
|
||||
<br/>
|
||||
<b>Not unless you explicitly say yes.</b> On first run the app <i>asks</i> — one screen, two equal-weight buttons, no pre-ticked box — and until you answer yes, VoiceStudio sends nothing: no analytics, no telemetry, no accounts, no phone-home. Skipping the question means no. Your text, audio, voices, and projects never leave your machine either way.
|
||||
|
||||
If you do opt in (also togglable anytime under <b>Settings → Privacy → "Help improve VoiceStudio"</b>), what's sent is anonymous, content-free usage stats: generations (engine, language, generation time, character <i>count</i>, error <i>type</i>), plus app lifecycle — an install ping, updates (version-to-version), crashes (error class and a <i>bucketed</i> uptime, never logs), error <i>types</i> (capped, deduplicated), and a single uninstall ping if you remove it. Never your text, audio, file names, or anything identifying — enforced in code by a property allowlist (<code>backend/core/analytics.py</code>), not just a promise. Every build — installer, Docker, or built from source — asks the same first-run question and stays off unless you say yes. Your own numbers live in <b>Settings → Usage</b>, computed locally, sent nowhere.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>How do I uninstall it / remove all its data?</b></summary>
|
||||
<br/>
|
||||
VoiceStudio is fully local — uninstalling is just deleting the app plus the folders it wrote (model cache, Python env, your voices/projects, config). Run <code>scripts/uninstall.sh</code> (macOS/Linux) or <code>scripts\uninstall.ps1</code> (Windows) — it prints every folder with its size as a dry-run first, then deletes on <code>--yes</code>. The full per-platform path list and app-removal steps are in <a href="docs/install/uninstall.md"><b>docs/install/uninstall.md</b></a>.
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="license"></a>
|
||||
|
||||
## 📜 License
|
||||
|
||||
VoiceStudio is free and open-source software under the [**GNU Affero General Public License v3.0 (AGPL-3.0)**](https://www.gnu.org/licenses/agpl-3.0.html).
|
||||
|
||||
**Free for any use — including commercial and internal business use.** Run it, sell the audio you produce with it, dub your own or clients' videos, roll it out across your team — all free, no license needed. As a **network copyleft** license, AGPL adds one obligation: if you **modify** VoiceStudio and offer that modified version to others over a network, you must make the complete corresponding source of your modified version available to them under the same AGPL-3.0 terms.
|
||||
|
||||
A **commercial license** is available for organizations that want to embed VoiceStudio in a **closed-source or proprietary** product or service without the AGPL-3.0 copyleft obligations. **Pricing tiers coming soon.** Inquiries: **VoiceStudio@palash.dev**.
|
||||
|
||||
The bundled `omnivoice/` TTS model by Han Zhu remains Apache-2.0 upstream. See [`LICENSE`](LICENSE) for the full, binding terms, and [`LICENSE-NOTICE.md`](LICENSE-NOTICE.md) for the plain-language summary and scope.
|
||||
|
||||
---
|
||||
|
||||
## 🙏 Acknowledgments
|
||||
|
||||
VoiceStudio stands on exceptional open-source work: [OmniVoice (k2-fsa)](https://github.com/k2-fsa/OmniVoice) — the core zero-shot TTS model · [WhisperX](https://github.com/m-bain/whisperX) · [Demucs](https://github.com/facebookresearch/demucs) · [Pyannote](https://github.com/pyannote/pyannote-audio) · [CTranslate2](https://github.com/OpenNMT/CTranslate2) · [AudioSeal](https://github.com/facebookresearch/audioseal) · [Tauri](https://tauri.app) · [Supertonic](https://huggingface.co/Supertone/supertonic-3) · [Sherpa-ONNX](https://github.com/k2-fsa/sherpa-onnx) · [GPT-SoVITS](https://github.com/RVC-Boss/GPT-SoVITS) · [Kyutai PocketTTS](https://kyutai.org) — thank you.
|
||||
|
||||
<a id="more-from-the-maker"></a>
|
||||
|
||||
### 🧰 More local open-source from the maker
|
||||
|
||||
[**Opal** 💠](https://github.com/debpalash/Opal) — play everything: the media player for the AI era · [**memxt** 🧠](https://github.com/debpalash/memxt) — local long-term memory for coding agents. Same rule: **your data stays on your machine.**
|
||||
|
||||
---
|
||||
|
||||
<div align="center">
|
||||
|
||||
<br/>
|
||||
|
||||
If you read this far, you're our kind of person.<br/>
|
||||
**[⭐ Star this repo](https://github.com/debpalash/VoiceStudio)** so others can find it too.<br/>
|
||||
**[💬 Join the Discord](https://discord.gg/bzQavDfVV9)** to share what you build.<br/>
|
||||
**[❤️ Support development](https://ko-fi.com/debpalash)** — fund the AI agent bills that keep VoiceStudio shipping.
|
||||
|
||||
<br/>
|
||||
|
||||
<a href="https://star-history.com/#debpalash/VoiceStudio&Date">
|
||||
<picture>
|
||||
<source media="(prefers-color-scheme: dark)" srcset="https://api.star-history.com/svg?repos=debpalash/VoiceStudio&type=Date&theme=dark" />
|
||||
<source media="(prefers-color-scheme: light)" srcset="https://api.star-history.com/svg?repos=debpalash/VoiceStudio&type=Date" />
|
||||
<img alt="Star History" src="https://api.star-history.com/svg?repos=debpalash/VoiceStudio&type=Date&theme=dark" width="600" />
|
||||
</picture>
|
||||
</a>
|
||||
<strong><a href="https://github.com/debpalash/VoiceStudio/releases/latest">Download VoiceStudio</a></strong> ·
|
||||
<a href="https://github.com/debpalash/VoiceStudio">Star the project</a> ·
|
||||
<a href="https://discord.gg/bzQavDfVV9">Join Discord</a>
|
||||
</div>
|
||||
|
||||
+59
-52
@@ -37,7 +37,7 @@
|
||||
<br/>
|
||||
|
||||
<div align="center">
|
||||
<img src="docs/screenshot-launchpad.png" alt="VoiceStudio — 启动台" width="100%"/>
|
||||
<img src="docs/media/0.5.0/quick-switch.gif" alt="VoiceStudio — 从状态栏快速切换 TTS 引擎" width="100%"/>
|
||||
</div>
|
||||
|
||||
> **声音很私人,创作空间也应该真正属于你。** VoiceStudio 的核心流程运行在你的硬件上:克隆、设计、配音、听写,并以 646 种语言创作,不需要订阅,也没有用量计费。联网引擎和服务始终是清晰可见的可选项,而不是隐藏依赖。
|
||||
@@ -45,6 +45,56 @@
|
||||
> [!WARNING]
|
||||
> **活跃 Beta 阶段。** 各版本之间可能出现故障——如需最新修复,请从源码运行。非常欢迎 Bug 报告和 PR:[提交 Issue](https://github.com/debpalash/VoiceStudio/issues) 或 [加入 Discord](https://discord.gg/bzQavDfVV9)。
|
||||
|
||||
<a id="quickstart"></a>
|
||||
|
||||
## ⚡ 快速开始
|
||||
|
||||
<div align="center">
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/macOS-DMG_(Apple_Silicon)-000?style=for-the-badge&logo=apple&logoColor=white" alt="下载 macOS DMG" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Windows-MSI_(x64)-0078D4?style=for-the-badge&logo=windows&logoColor=white" alt="下载 Windows MSI" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Linux-AppImage_(x64)-FCC624?style=for-the-badge&logo=linux&logoColor=black" alt="下载 Linux AppImage" /></a>
|
||||
<br/>
|
||||
<sub>三个按钮都会打开最新发布页——在资源列表中下载对应你系统的安装包。</sub><br/>
|
||||
<sub><b>macOS:</b>首次启动需要一次性批准——右键点击 → <b>打开</b>(macOS 15 上为 系统设置 → 隐私与安全性 → <b>“仍要打开”</b>)。无需终端。<a href="docs/install/macos.md#gatekeeper-quarantine">为什么?</a> · <b>Intel Mac:</b>不支持本地后端(<a href="https://github.com/debpalash/VoiceStudio/issues/889">#889</a>)——<a href="docs/install/macos.md">详情</a>。</sub>
|
||||
</div>
|
||||
|
||||
选择你的操作系统,按指南从头到尾操作:
|
||||
|
||||
- 🍎 **macOS** — [docs/install/macos.md](docs/install/macos.md)
|
||||
- 🪟 **Windows** — [docs/install/windows.md](docs/install/windows.md)
|
||||
- 🐧 **Linux** — [docs/install/linux.md](docs/install/linux.md)
|
||||
- 🐳 **Docker** — [docs/install/docker.md](docs/install/docker.md) · [Docker Hub: `palashdeb/omnivoice-studio`](https://hub.docker.com/r/palashdeb/omnivoice-studio)
|
||||
|
||||
**三步克隆出你的第一个声音:**
|
||||
|
||||
1. **安装并启动。** 首次启动会自动搭建 Python 运行环境并下载模型权重——启动画面会逐步显示进度(仅首次,需要几分钟;之后即开即用)。
|
||||
2. 从启动台打开**语音克隆**,拖入任意声音的 **3 秒音频**。
|
||||
3. **输入一句话,点击生成。** 音频完全属于你——在你的设备上生成和保存,支持 646 种语言。
|
||||
|
||||
觉得慢?[docs/performance.md](docs/performance.md) 讲清了生成时间到底花在哪里、有哪些调优开关,以及“它变慢了”的三个经典原因。各引擎/设备的实测数据见 [docs/benchmarks.md](docs/benchmarks.md)。
|
||||
|
||||
> 正在从 **[CorentinJ/Real-Time-Voice-Cloning](https://github.com/CorentinJ/Real-Time-Voice-Cloning)**(现已归档)迁移过来?我们有专门的迁移指南:[docs/migration/real-time-voice-cloning.md](docs/migration/real-time-voice-cloning.md)。
|
||||
|
||||
<details>
|
||||
<summary><b>🧰 卡住了?自检、Token 与受限网络</b></summary>
|
||||
|
||||
<br/>
|
||||
|
||||
先运行内置自检——在应用中打开 **设置 → 关于 → “运行自检”**,或在源码检出目录中执行
|
||||
`uv run python backend/main.py --diagnose`(加 `--deep` 还会实际加载当前引擎进行测试)。然后查看
|
||||
[docs/install/troubleshooting.md](docs/install/troubleshooting.md) 中排名前
|
||||
10 的安装错误。运行时出错时,应用内的错误界面会直接深链到对应条目;**设置 → 关于 →
|
||||
“保存诊断包”** 会把脱敏日志与自检报告打包,方便附在 Bug 报告里。
|
||||
|
||||
Hugging Face Token 的配置见
|
||||
[docs/setup/huggingface-token.md](docs/setup/huggingface-token.md)。说话人分离相关的模型访问门槛见
|
||||
[docs/features/diarization.md](docs/features/diarization.md)。下载速度、⚡ 快速下载(Xet)状态,以及受限网络 / 镜像选项见
|
||||
[docs/downloading-models.md](docs/downloading-models.md)。
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="features"></a>
|
||||
|
||||
## ✨ 功能
|
||||
@@ -112,49 +162,6 @@
|
||||
|
||||
---
|
||||
|
||||
<a id="quickstart"></a>
|
||||
|
||||
## ⚡ 快速开始
|
||||
|
||||
<div align="center">
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/macOS-DMG_(Apple_Silicon)-000?style=for-the-badge&logo=apple&logoColor=white" alt="下载 macOS DMG" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Windows-MSI_(x64)-0078D4?style=for-the-badge&logo=windows&logoColor=white" alt="下载 Windows MSI" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Linux-AppImage_(x64)-FCC624?style=for-the-badge&logo=linux&logoColor=black" alt="下载 Linux AppImage" /></a>
|
||||
<br/>
|
||||
<sub><b>macOS:</b>首次启动需要一次性批准——右键点击 → <b>打开</b>(macOS 15 上为 系统设置 → 隐私与安全性 → <b>“仍要打开”</b>)。无需终端。<a href="docs/install/macos.md#gatekeeper-quarantine">为什么?</a> · <b>Intel Mac:</b>不支持本地后端(<a href="https://github.com/debpalash/VoiceStudio/issues/889">#889</a>)——<a href="docs/install/macos.md">详情</a>。</sub>
|
||||
</div>
|
||||
|
||||
选择你的操作系统,按指南从头到尾操作:
|
||||
|
||||
- 🍎 **macOS** — [docs/install/macos.md](docs/install/macos.md)
|
||||
- 🪟 **Windows** — [docs/install/windows.md](docs/install/windows.md)
|
||||
- 🐧 **Linux** — [docs/install/linux.md](docs/install/linux.md)
|
||||
- 🐳 **Docker** — [docs/install/docker.md](docs/install/docker.md) · [Docker Hub: `palashdeb/omnivoice-studio`](https://hub.docker.com/r/palashdeb/omnivoice-studio)
|
||||
|
||||
觉得慢?[docs/performance.md](docs/performance.md) 讲清了生成时间到底花在哪里、有哪些调优开关,以及“它变慢了”的三个经典原因。
|
||||
|
||||
> 正在从 **[CorentinJ/Real-Time-Voice-Cloning](https://github.com/CorentinJ/Real-Time-Voice-Cloning)**(现已归档)迁移过来?我们有专门的迁移指南:[docs/migration/real-time-voice-cloning.md](docs/migration/real-time-voice-cloning.md)。
|
||||
|
||||
<details>
|
||||
<summary><b>🧰 卡住了?自检、Token 与受限网络</b></summary>
|
||||
|
||||
<br/>
|
||||
|
||||
先运行内置自检——在应用中打开 **设置 → 关于 → “运行自检”**,或在源码检出目录中执行
|
||||
`uv run python backend/main.py --diagnose`(加 `--deep` 还会实际加载当前引擎进行测试)。然后查看
|
||||
[docs/install/troubleshooting.md](docs/install/troubleshooting.md) 中排名前
|
||||
10 的安装错误。运行时出错时,应用内的错误界面会直接深链到对应条目;**设置 → 关于 →
|
||||
“保存诊断包”** 会把脱敏日志与自检报告打包,方便附在 Bug 报告里。
|
||||
|
||||
Hugging Face Token 的配置见
|
||||
[docs/setup/huggingface-token.md](docs/setup/huggingface-token.md)。说话人分离相关的模型访问门槛见
|
||||
[docs/features/diarization.md](docs/features/diarization.md)。下载速度、⚡ 快速下载(Xet)状态,以及受限网络 / 镜像选项见
|
||||
[docs/downloading-models.md](docs/downloading-models.md)。
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="why-voicestudio"></a>
|
||||
|
||||
## 💡 为什么选择 VoiceStudio?
|
||||
@@ -173,8 +180,8 @@ Hugging Face Token 的配置见
|
||||
| **API 密钥** | 需要账号 | 本地流程不需要 |
|
||||
| **GPU 支持** | 不适用(云端) | CUDA · Apple Silicon · ROCm(Linux)· CPU |
|
||||
| **桌面应用** | ❌ | ✅ macOS · Windows · Linux |
|
||||
| **TTS 引擎** | 1 | **14** — [完整矩阵](#tts-engines) |
|
||||
| **ASR 引擎** | 1 | **10** — [完整阵容](#asr-engines) |
|
||||
| **TTS 引擎** | 1 | **16** — [完整矩阵](#tts-engines) |
|
||||
| **ASR 引擎** | 1 | **11** — [完整阵容](#asr-engines) |
|
||||
| **MCP 服务器** | ❌ | ✅ 可从 Claude、Cursor 及任何 MCP 客户端使用 |
|
||||
| **自检** | ❌ | ✅ 诊断套件、错误日志、脱敏调试包 |
|
||||
| **可定制** | ❌ 闭源 | ✅ 随你 Fork、扩展、发布 |
|
||||
@@ -214,10 +221,10 @@ Hugging Face Token 的配置见
|
||||
|
||||
### 🗣️ TTS 引擎
|
||||
|
||||
**14 个引擎,一个选择器。** VoiceStudio(默认,支持 600+ 语言)始终可用;另有七个引擎可选装并自动检测(CosyVoice 3、GPT-SoVITS、VoxCPM2、MOSS-TTS-Nano、KittenTTS、MLX-Audio、Sherpa-ONNX),外加六个按需延迟安装的重量级引擎(IndexTTS 2.5、OmniVoice GGUF、Supertonic 3、MOSS-TTS-v1.5、dots.tts、Confucius4-TTS)。在 **设置 → TTS 引擎** 中切换;所选引擎将应用于所有语音合成场景。
|
||||
**16 个引擎,一个选择器。** VoiceStudio(默认,支持 600+ 语言)始终可用;另有七个引擎可选装并自动检测(CosyVoice 3、GPT-SoVITS、VoxCPM2、MOSS-TTS-Nano、KittenTTS、MLX-Audio、Sherpa-ONNX),外加八个按需延迟安装的引擎(IndexTTS 2.5、OmniVoice GGUF、OmniVoice 子进程版、PocketTTS、Supertonic 3、MOSS-TTS-v1.5、dots.tts、Confucius4-TTS)。在 **设置 → TTS 引擎** 中切换;所选引擎将应用于所有语音合成场景。**每个引擎都有独立指南:[docs/engines](docs/engines/README.md)(英文)。**
|
||||
|
||||
<details>
|
||||
<summary><b>📊 完整矩阵</b>——14 个引擎 × 平台 × 克隆/指令 × 许可证</summary>
|
||||
<summary><b>📊 完整矩阵</b>——16 个引擎 × 平台 × 克隆/指令 × 许可证</summary>
|
||||
|
||||
<br/>
|
||||
|
||||
@@ -254,10 +261,10 @@ Hugging Face Token 的配置见
|
||||
|
||||
### 🎧 ASR 引擎
|
||||
|
||||
**10 个引擎**——它们驱动听写、视频配音和字幕。**WhisperX** 是跨平台的默认引擎(约 100 种语言,词级时间对齐);其余引擎均为可选装并自动检测。在 **设置 → 引擎** 中切换。九个完全在本地设备上运行;第十个(OpenAI 兼容)是可选的远程客户端,可用于 Qwen3-ASR 或任何兼容的服务器。
|
||||
**11 个引擎**——它们驱动听写、视频配音和字幕。**WhisperX** 是跨平台的默认引擎(约 100 种语言,词级时间对齐);其余引擎均为可选装并自动检测。在 **设置 → 引擎** 中切换。十个完全在本地设备上运行;第十一个(OpenAI 兼容)是可选的远程客户端,可用于 Qwen3-ASR 或任何兼容的服务器。
|
||||
|
||||
<details>
|
||||
<summary><b>📊 完整阵容</b>——10 个引擎、各自的强项与计算类型说明</summary>
|
||||
<summary><b>📊 完整阵容</b>——11 个引擎、各自的强项与计算类型说明</summary>
|
||||
|
||||
<br/>
|
||||
|
||||
@@ -274,7 +281,7 @@ Hugging Face Token 的配置见
|
||||
| **sherpa-onnx**(实时听写) | `sherpa-onnx-asr` | 25 种欧洲语言 + 90+ | 实时、快于实时的听写——小体积流式/离线 ONNX 模型(Parakeet TDT v3/v2、流式 Zipformer 与 Paraformer、Whisper Tiny),CPU 运行,macOS / Windows / Linux 表现完全一致。在 **设置 → 语音** 中按模型选择。 |
|
||||
| **OpenAI 兼容** ⚠️ 远程 | `openai-compat-asr` | 取决于服务器 | 当下通往 **Qwen3-ASR** 的路径(自托管服务器,无需等 transformers 支持)、任何 OpenAI 兼容的转录端点,或 OpenAI 官方 API——无需安装,在 **设置 → 引擎**(ASR 标签页)中配置并测试连接。音频会离开你的设备,发送到你指定的任何服务器;参见 [docs/engines/openai-compatible-asr.md](docs/engines/openai-compatible-asr.md)。 |
|
||||
|
||||
> Whisper 系列引擎覆盖约 100 种语言;**FunASR / SenseVoice** 额外提供一条多语言一体化路径,内置语音活动检测与行内说话人分离。**sherpa-onnx** 驱动实时听写的模型选择器——你边说,文字边出现。每个引擎都在本地设备上运行——无需 API 密钥,无需云端。
|
||||
> Whisper 系列引擎覆盖约 100 种语言;**FunASR / SenseVoice** 额外提供一条多语言一体化路径,内置语音活动检测与行内说话人分离。**sherpa-onnx** 驱动实时听写的模型选择器——你边说,文字边出现。除可选的 OpenAI 兼容远程客户端外,所有引擎都在本地设备上运行——无需 API 密钥,无需云端。
|
||||
|
||||
> **GPU 不支持高效 float16?** 在较老的 NVIDIA GPU(Maxwell/Pascal、GTX 16xx)上,或在 CTranslate2/cuDNN 版本不匹配之后,CTranslate2 系 ASR 引擎(WhisperX、Faster-Whisper)无法运行 `float16`,VoiceStudio 会自动改用 `int8` 重试——无需配置。如果转录仍然失败,可用 `ASR_COMPUTE_TYPE` 环境变量固定计算类型(逃生舱口):`ASR_COMPUTE_TYPE=int8`(CPU 用 `float32`)。将其设为 `int8` 并重启后端。
|
||||
|
||||
@@ -574,7 +581,7 @@ VoiceStudio 站在这些杰出开源工作的肩膀上:
|
||||
|
||||
## 🧰 来自同一作者的更多本地开源项目
|
||||
|
||||
喜欢这种本地优先的理念?它是一脉相承的——同一位作者,同一条准则:**你的数据只留在你的设备上。**
|
||||
喜欢这种本地优先的理念?它是一脉相承的——同一位作者,同一条准则:**你的数据只留在你的设备上。** 全部项目见 [palash.dev](https://palash.dev)。
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
|
||||
@@ -157,6 +157,31 @@ def require_loopback(request: Request) -> None:
|
||||
raise HTTPException(status_code=403, detail="loopback origin required")
|
||||
|
||||
|
||||
def _admin_gate_403() -> None:
|
||||
"""Raise the admin-gate 403 with a detail that states what would ACTUALLY
|
||||
satisfy the gate. The bundled UI routes any 403 whose detail mentions
|
||||
"admin api key" to the API-key login form (frontend ``client.ts``; the
|
||||
literal contract is locked by ``tests/test_auth_gate_detail_lockstep.py``),
|
||||
so the wording must not name a key where presenting one cannot help.
|
||||
|
||||
The detail names the key only when the gate would accept one: server mode
|
||||
WITH an API key configured. Every other rejection — desktop mode (the
|
||||
credential checks in the callers only run under server mode) and a
|
||||
server-mode deployment with only a share PIN or nothing configured — keeps
|
||||
the plain loopback detail, because only loopback can use admin there.
|
||||
Naming the key in those cases would trap a LAN-share guest in a login
|
||||
form that can never succeed (#1213, #1525; PR #1569 review).
|
||||
"""
|
||||
raise HTTPException(
|
||||
status_code=403,
|
||||
detail=(
|
||||
"loopback origin or admin API key required"
|
||||
if _server_mode() and remote_api_key()
|
||||
else "loopback origin required"
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
def require_admin(request: Request) -> None:
|
||||
"""Gate RCE/filesystem-capable admin routers.
|
||||
|
||||
@@ -180,7 +205,7 @@ def require_admin(request: Request) -> None:
|
||||
return
|
||||
if _request_presents_admin_credential(request):
|
||||
return
|
||||
raise HTTPException(status_code=403, detail="loopback origin or admin API key required")
|
||||
_admin_gate_403()
|
||||
|
||||
|
||||
def require_admin_action(request: Request) -> None:
|
||||
@@ -198,7 +223,7 @@ def require_admin_action(request: Request) -> None:
|
||||
side_effectful_get=True,
|
||||
):
|
||||
return
|
||||
raise HTTPException(status_code=403, detail="loopback origin or admin API key required")
|
||||
_admin_gate_403()
|
||||
|
||||
|
||||
def require_desktop(request: Request) -> None:
|
||||
|
||||
@@ -330,7 +330,7 @@ async def _render_archetype_wav(a: dict, out_path: Path) -> None:
|
||||
# GPU pool and brick the backend (#730 class). Budget comes from the shared
|
||||
# length-scaled helper (#1190) instead of the flat 300s default.
|
||||
from services.model_manager import generate_timeout_s
|
||||
_budget = generate_timeout_s(text)
|
||||
_budget = generate_timeout_s(text, engine=model)
|
||||
audio_tensor = await run_on_gpu_pool_guarded(
|
||||
lambda: _infer(_PREVIEW_SEED), what="Archetype preview generate",
|
||||
timeout=_budget)
|
||||
@@ -357,15 +357,11 @@ async def _render_archetype_wav(a: dict, out_path: Path) -> None:
|
||||
# Runs on the dedicated watermark pool (#1190): AudioSeal embedding is CPU
|
||||
# work that holds no VRAM, so it must not occupy a GPU worker ahead of the
|
||||
# next generate on 1-worker hosts.
|
||||
from services.watermark import mark_synthetic
|
||||
from services.model_manager import get_watermark_pool
|
||||
import functools
|
||||
audio_tensor = await run_on_gpu_pool_guarded(
|
||||
functools.partial(mark_synthetic, audio_tensor, model.sampling_rate,
|
||||
context="archetypes.render"),
|
||||
what="Archetype watermark",
|
||||
from services.watermark import mark_synthetic_async
|
||||
audio_tensor = await mark_synthetic_async(
|
||||
audio_tensor, model.sampling_rate,
|
||||
context="archetypes.render",
|
||||
timeout=generate_timeout_s(""),
|
||||
executor=get_watermark_pool(),
|
||||
)
|
||||
|
||||
out_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
|
||||
+188
-13
@@ -103,6 +103,75 @@ def _set_progress(job, stage, percent=0, **extra):
|
||||
job["progress"] = {"stage": stage, "percent": percent, **extra}
|
||||
|
||||
|
||||
#: Override for the native dub batch width. Set to 1 to disable batching.
|
||||
BATCH_WIDTH_ENV = "OMNIVOICE_DUB_BATCH_WIDTH"
|
||||
|
||||
#: Hard ceiling on the override — a batch this wide is already amortizing
|
||||
#: almost all of the per-call setup, and beyond it the failure mode is an OOM
|
||||
#: that costs more than the saving.
|
||||
_MAX_BATCH_WIDTH = 16
|
||||
|
||||
|
||||
def _native_batch_width(backend) -> int:
|
||||
"""How many segments to render in one native batch on THIS host.
|
||||
|
||||
A native batch widens the forward pass, so the width cannot be a constant.
|
||||
The default engine declares ``min_vram_gb = 6.0`` for a SINGLE job; an
|
||||
unconditional 8-wide batch would OOM the 4-8 GB CUDA cards and the MPS
|
||||
Macs where the per-segment path succeeds today — turning a throughput
|
||||
optimization into a regression on exactly the hardware that already
|
||||
struggles (#1616 is a 4 GB card reporting capacity failures). Default
|
||||
behaviour must not get riskier on a host, so the width is derived from
|
||||
measured headroom and falls back to 1 (no batching) when unknown.
|
||||
|
||||
CPU hosts get 1: batching there buys no kernel amortization and only
|
||||
multiplies peak RAM.
|
||||
"""
|
||||
override = os.environ.get(BATCH_WIDTH_ENV, "").strip()
|
||||
if override:
|
||||
try:
|
||||
return max(1, min(_MAX_BATCH_WIDTH, int(override)))
|
||||
except (TypeError, ValueError):
|
||||
logger.warning(
|
||||
"%s=%r is not an integer — deriving the batch width from the host instead.",
|
||||
BATCH_WIDTH_ENV, override,
|
||||
)
|
||||
try:
|
||||
from core.device_caps import detect_host_caps
|
||||
caps = detect_host_caps()
|
||||
except Exception: # noqa: BLE001 — an unprobeable host takes the safe path
|
||||
return 1
|
||||
if caps.family == "cpu" or not caps.vram_gb:
|
||||
return 1
|
||||
headroom = caps.vram_gb - float(getattr(backend, "min_vram_gb", 0.0) or 0.0)
|
||||
if headroom < 2.0:
|
||||
return 1
|
||||
if headroom < 6.0:
|
||||
return 2
|
||||
if headroom < 12.0:
|
||||
return 4
|
||||
return 8
|
||||
|
||||
|
||||
def _batch_timeout_s(texts: list[str], backend) -> float:
|
||||
"""Execution budget for one native batch.
|
||||
|
||||
Not the sum of the per-item budgets: ``generate_timeout_s`` returns a
|
||||
floor (300s GPU / 600s CPU) plus per-length overage, so summing it across
|
||||
eight items yields a ~2400s budget — and a wedged batch would hold a
|
||||
GPU-pool worker for forty minutes before the reset this file depends on
|
||||
(#730). One floor covers wedge detection for the whole call; only the
|
||||
length-driven overage is genuinely additive.
|
||||
"""
|
||||
from services.model_manager import generate_timeout_s
|
||||
|
||||
floor = generate_timeout_s("", engine=backend)
|
||||
overage = sum(
|
||||
max(0.0, generate_timeout_s(text, engine=backend) - floor) for text in texts
|
||||
)
|
||||
return floor + overage
|
||||
|
||||
|
||||
async def _run_batch_pipeline(job_id: str, job: dict):
|
||||
"""Full batch dub pipeline: extract → transcribe → translate → generate → mix → export."""
|
||||
import subprocess
|
||||
@@ -279,6 +348,111 @@ async def _run_batch_pipeline(job_id: str, job: dict):
|
||||
full_audio = torch.zeros(1, total_samples)
|
||||
total_segs = len(translated_segments)
|
||||
|
||||
# Native engines can amortize encoder/decoder setup across a small
|
||||
# batch. Keep the adapter seam optional: engines without a real batch
|
||||
# implementation inherit TTSBackend.generate_batch(), which preserves
|
||||
# the established one-segment behavior below.
|
||||
from services.tts_backend import TTSBackend
|
||||
batched_audio: dict[int, torch.Tensor] = {}
|
||||
has_native_batch = type(backend).generate_batch is not TTSBackend.generate_batch
|
||||
if has_native_batch:
|
||||
from services.text_normalization import normalize_for_tts
|
||||
|
||||
batch_ref_audio = None
|
||||
batch_ref_text = None
|
||||
if job.get("voice_id"):
|
||||
from core.db import db_conn
|
||||
from core.config import VOICES_DIR as _VD
|
||||
with db_conn() as conn:
|
||||
row = conn.execute(
|
||||
"SELECT * FROM voice_profiles WHERE id=?",
|
||||
(job["voice_id"],),
|
||||
).fetchone()
|
||||
if row:
|
||||
if row["is_locked"] and row["locked_audio_path"]:
|
||||
batch_ref_audio = os.path.join(_VD, row["locked_audio_path"])
|
||||
elif row["ref_audio_path"]:
|
||||
batch_ref_audio = os.path.join(_VD, row["ref_audio_path"])
|
||||
batch_ref_text = row["ref_text"]
|
||||
|
||||
batch_width = _native_batch_width(backend)
|
||||
|
||||
async def _prefetch_batch(first_index: int) -> None:
|
||||
"""Render the batch beginning at ``first_index`` into
|
||||
``batched_audio``.
|
||||
|
||||
Rendered on demand rather than prerendering the whole track:
|
||||
the tensors are popped as they are placed, so peak host memory
|
||||
is one batch instead of every segment of the language — and
|
||||
the progress bar tracks placement instead of running to the
|
||||
end and restarting at segment 1.
|
||||
"""
|
||||
if job["status"] == "cancelled":
|
||||
return
|
||||
batch_rows = []
|
||||
index = first_index
|
||||
while index < total_segs and len(batch_rows) < batch_width:
|
||||
seg = translated_segments[index]
|
||||
if (seg.get("end", 0) - seg.get("start", 0) > 0.05
|
||||
and seg.get("text", "").strip()):
|
||||
batch_rows.append((index, seg))
|
||||
index += 1
|
||||
if len(batch_rows) < 2:
|
||||
return # nothing to amortize — the per-segment path is equal
|
||||
batch_indices = [index for index, _ in batch_rows]
|
||||
batch_texts = [
|
||||
normalize_for_tts(row.get("text", "").strip(), target_lang)
|
||||
for _, row in batch_rows
|
||||
]
|
||||
batch_durations = [
|
||||
row.get("end", 0) - row.get("start", 0)
|
||||
for _, row in batch_rows
|
||||
]
|
||||
|
||||
def _render_native_batch():
|
||||
generated = backend.generate_batch(
|
||||
batch_texts,
|
||||
language=target_lang,
|
||||
ref_audio=batch_ref_audio,
|
||||
ref_text=batch_ref_text,
|
||||
duration=batch_durations,
|
||||
num_step=16,
|
||||
guidance_scale=2.0,
|
||||
speed=1.0,
|
||||
denoise=True,
|
||||
postprocess_output=True,
|
||||
)
|
||||
if len(generated) != len(batch_indices):
|
||||
raise RuntimeError(
|
||||
f"native batch returned {len(generated)} outputs for "
|
||||
f"{len(batch_indices)} segments"
|
||||
)
|
||||
rendered = []
|
||||
for audio_out in generated:
|
||||
if not getattr(backend, "applies_own_mastering", False):
|
||||
audio_out = apply_mastering(audio_out, sample_rate=sr)
|
||||
rendered.append(normalize_audio(audio_out, target_dBFS=-2.0))
|
||||
return rendered
|
||||
|
||||
try:
|
||||
rendered = await run_on_gpu_pool_guarded(
|
||||
_render_native_batch,
|
||||
what="Batch generate",
|
||||
timeout=_batch_timeout_s(batch_texts, backend),
|
||||
)
|
||||
batched_audio.update(zip(batch_indices, rendered))
|
||||
except TimeoutError:
|
||||
# Do not immediately queue the same expensive work again:
|
||||
# the timed-out pool task may still be holding the device.
|
||||
raise
|
||||
except Exception as e:
|
||||
logger.warning(
|
||||
"Native TTS batch failed for segments %s-%s; falling back per segment: %s",
|
||||
batch_indices[0] + 1,
|
||||
batch_indices[-1] + 1,
|
||||
e,
|
||||
)
|
||||
|
||||
for i, seg in enumerate(translated_segments):
|
||||
if job["status"] == "cancelled":
|
||||
return
|
||||
@@ -356,10 +530,15 @@ async def _run_batch_pipeline(job_id: str, job: dict):
|
||||
# Budget is the shared length-scaled one (#1190): a long segment
|
||||
# on CPU-class hardware no longer dies on the flat 300s.
|
||||
from services.model_manager import generate_timeout_s
|
||||
audio_tensor = await run_on_gpu_pool_guarded(
|
||||
_gen, what="Batch generate",
|
||||
timeout=generate_timeout_s(seg_text),
|
||||
)
|
||||
if has_native_batch and i not in batched_audio:
|
||||
await _prefetch_batch(i)
|
||||
if i in batched_audio:
|
||||
audio_tensor = batched_audio.pop(i)
|
||||
else:
|
||||
audio_tensor = await run_on_gpu_pool_guarded(
|
||||
_gen, what="Batch generate",
|
||||
timeout=generate_timeout_s(seg_text, engine=backend),
|
||||
)
|
||||
|
||||
# Fit to slot
|
||||
target_samples_seg = int(seg_duration * sr)
|
||||
@@ -413,19 +592,15 @@ async def _run_batch_pipeline(job_id: str, job: dict):
|
||||
# unmarked while the interactive dub pipeline marked every segment.
|
||||
# One whole-track embed (chunked internally, #1045) is equivalent to
|
||||
# dub_generate's per-segment marks: the 16-bit message repeats
|
||||
# throughout. Runs in the GPU pool like generate's finalize; never
|
||||
# raises (degrades to unmarked on failure, same as every producer).
|
||||
# throughout. Never raises (degrades to unmarked on failure, same as
|
||||
# every producer).
|
||||
# Dispatched to the dedicated watermark pool, not the GPU pool (#1190):
|
||||
# AudioSeal embedding is CPU work that holds no VRAM, and a whole-track
|
||||
# embed is long enough that occupying a GPU worker with it stalled the
|
||||
# next language's segments on 1-worker hosts.
|
||||
from services.watermark import mark_synthetic
|
||||
from services.model_manager import get_watermark_pool
|
||||
import functools
|
||||
full_audio = await loop.run_in_executor(
|
||||
get_watermark_pool(),
|
||||
functools.partial(mark_synthetic, full_audio, sr,
|
||||
context="batch.dub_track"),
|
||||
from services.watermark import mark_synthetic_async
|
||||
full_audio = await mark_synthetic_async(
|
||||
full_audio, sr, context="batch.dub_track",
|
||||
)
|
||||
|
||||
# Same assembly pattern as dub_generate.py:390 — `full_audio` is a
|
||||
|
||||
@@ -27,6 +27,10 @@ Protocol:
|
||||
"detail": "..."} — error ("detail"
|
||||
kept for legacy)
|
||||
|
||||
Sherpa ``final`` frames additionally carry
|
||||
``"final_kind": "utterance"|"summary"``. Utterances are mid-session
|
||||
commits; the summary is the authoritative whole-session result at EOF.
|
||||
|
||||
Every ``final`` text is normalised by services.text_polish (leading
|
||||
capital for Latin scripts, terminal punctuation, single-spaced) so the
|
||||
pasted result reads like typed text. Partials are raw.
|
||||
@@ -35,6 +39,7 @@ from __future__ import annotations
|
||||
|
||||
import asyncio
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import tempfile
|
||||
import time
|
||||
@@ -70,17 +75,46 @@ _AEC_NEAR = 0x00 # microphone frame (clean it, then buffer for ASR)
|
||||
_AEC_FAR = 0x01 # playback reference frame (feed the echo model only)
|
||||
|
||||
|
||||
def _requested_pcm_sample_rate(query_params) -> int | None:
|
||||
"""Return a bounded PCM rate for ``?pcm=1``/``?aec=1`` sessions."""
|
||||
raw_pcm = query_params.get("pcm") in ("1", "true", "on")
|
||||
aec = query_params.get("aec") in ("1", "true", "on")
|
||||
if not raw_pcm and not aec:
|
||||
return None
|
||||
# Client-supplied ``?sr=`` values outside the range real capture devices use
|
||||
# are replaced with 16 kHz. The rate sizes server-side state — RecoveryTail
|
||||
# multiplies it by RECOVERY_TAIL_SECONDS to compute its byte ceiling — so an
|
||||
# absurd rate must never be believed: it would re-open the unbounded-memory
|
||||
# path the recovery-tail cap closed.
|
||||
SR_MIN, SR_MAX = 8000, 96000
|
||||
|
||||
|
||||
def _bounded_sample_rate(query_params) -> int:
|
||||
try:
|
||||
sample_rate = int(query_params.get("sr", "16000"))
|
||||
except (TypeError, ValueError):
|
||||
return 16000
|
||||
return sample_rate if 8000 <= sample_rate <= 96000 else 16000
|
||||
return sample_rate if SR_MIN <= sample_rate <= SR_MAX else 16000
|
||||
|
||||
|
||||
def _requested_pcm_sample_rate(query_params) -> int | None:
|
||||
"""Return the bounded rate when the client transport is raw PCM.
|
||||
|
||||
Sherpa clients omit ``pcm=1`` because the selected model already defines
|
||||
that transport. If the model is demoted or its runtime is unavailable, the
|
||||
legacy recognizer fallback must still decode those same bytes as PCM.
|
||||
"""
|
||||
raw_pcm = query_params.get("pcm") in ("1", "true", "on")
|
||||
aec = query_params.get("aec") in ("1", "true", "on")
|
||||
sherpa_pcm = False
|
||||
requested_model = query_params.get("model")
|
||||
if requested_model:
|
||||
try:
|
||||
from services.sherpa_dictation import is_sherpa_model
|
||||
sherpa_pcm = is_sherpa_model(requested_model)
|
||||
except Exception: # noqa: BLE001
|
||||
# A broken sherpa install must not decide the framing question —
|
||||
# sherpa_pcm stays False and the session negotiates the
|
||||
# MediaRecorder path; availability is re-probed (and reported)
|
||||
# when the model is actually selected.
|
||||
sherpa_pcm = False
|
||||
if not raw_pcm and not aec and not sherpa_pcm:
|
||||
return None
|
||||
return _bounded_sample_rate(query_params)
|
||||
|
||||
|
||||
def _demux_aec_frame(data: bytes) -> tuple[str, bytes]:
|
||||
@@ -137,16 +171,27 @@ def _select_sherpa_spec(websocket: WebSocket):
|
||||
from services import sherpa_dictation as sd
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
def _usable_spec(model_id):
|
||||
spec = sd.get_spec(model_id)
|
||||
if spec is not None and sd.is_demoted(spec.id):
|
||||
logger.warning(
|
||||
"dictation model %s is demoted — using the capture ASR fallback",
|
||||
spec.id,
|
||||
)
|
||||
return None
|
||||
return spec
|
||||
|
||||
requested = websocket.query_params.get("model")
|
||||
if requested:
|
||||
return sd.get_spec(requested) # explicit selection (may be None if bad)
|
||||
return _usable_spec(requested) # explicit selection (may be unavailable)
|
||||
# Fall back to the persisted dictation pref.
|
||||
try:
|
||||
from services.asr_backend import dictation_model_id
|
||||
mid = dictation_model_id()
|
||||
except Exception:
|
||||
mid = None
|
||||
return sd.get_spec(mid) if mid else None
|
||||
return _usable_spec(mid) if mid else None
|
||||
|
||||
|
||||
@router.websocket("/ws/transcribe")
|
||||
@@ -422,6 +467,64 @@ SHERPA_OFFLINE_SILENCE_S = float(os.environ.get("OMNIVOICE_SHERPA_OFFLINE_SILENC
|
||||
SHERPA_OFFLINE_RMS_FLOOR = float(os.environ.get("OMNIVOICE_SHERPA_OFFLINE_RMS", "0.01"))
|
||||
|
||||
|
||||
#: Seconds of audio retained for silent-model recovery. Recovery only needs
|
||||
#: enough speech to prove the model is broken and to re-transcribe what was
|
||||
#: said; retaining the whole session grew ~115 MB/hour at 16 kHz on an open
|
||||
#: mic, unbounded, and only ever got read when the fallback fired.
|
||||
RECOVERY_TAIL_DEFAULT_SECONDS = 120.0
|
||||
RECOVERY_TAIL_MAX_SECONDS = 300.0
|
||||
|
||||
|
||||
def _bounded_recovery_tail_seconds(value: str | None) -> float:
|
||||
"""Parse the recovery tail override without allowing unbounded buffers."""
|
||||
try:
|
||||
seconds = float(value) if value is not None else RECOVERY_TAIL_DEFAULT_SECONDS
|
||||
except (TypeError, ValueError):
|
||||
return RECOVERY_TAIL_DEFAULT_SECONDS
|
||||
if not math.isfinite(seconds) or seconds <= 0:
|
||||
return RECOVERY_TAIL_DEFAULT_SECONDS
|
||||
return min(seconds, RECOVERY_TAIL_MAX_SECONDS)
|
||||
|
||||
|
||||
RECOVERY_TAIL_SECONDS = _bounded_recovery_tail_seconds(
|
||||
os.environ.get("OMNIVOICE_DICTATION_RECOVERY_TAIL_S")
|
||||
)
|
||||
|
||||
|
||||
class RecoveryTail:
|
||||
"""The most recent ``RECOVERY_TAIL_SECONDS`` of session audio.
|
||||
|
||||
Keeps the *tail* rather than the head: a long dictation's useful speech is
|
||||
what the user just said, and the silent-model check cares about how much
|
||||
audio the session carried overall — which ``total_bytes`` still reports
|
||||
truthfully after trimming.
|
||||
"""
|
||||
|
||||
__slots__ = ("_buf", "_max", "total_bytes")
|
||||
|
||||
def __init__(self, sample_rate: int, seconds: float = RECOVERY_TAIL_SECONDS):
|
||||
# int16 mono → 2 bytes/sample. Floor of one frame so a nonsense rate
|
||||
# or seconds value can't produce a zero-length buffer.
|
||||
self._max = max(2, int(seconds * max(1, sample_rate)) * 2)
|
||||
self._buf = bytearray()
|
||||
self.total_bytes = 0
|
||||
|
||||
def extend(self, pcm: bytes) -> None:
|
||||
self._buf.extend(pcm)
|
||||
self.total_bytes += len(pcm)
|
||||
excess = len(self._buf) - self._max
|
||||
if excess > 0:
|
||||
# int16 mono: trim whole samples only. A split frame can carry an
|
||||
# odd byte count, and an odd trim would leave the tail starting
|
||||
# mid-sample — every later sample byte-shifted, and the recovery
|
||||
# transcription fed noise.
|
||||
excess += excess % 2
|
||||
del self._buf[:excess]
|
||||
|
||||
def tail(self) -> bytes:
|
||||
return bytes(self._buf)
|
||||
|
||||
|
||||
def is_model_silent(text: str, heard_speech: bool, pcm_bytes: int) -> bool:
|
||||
"""True when the dictation model produced NO text despite real speech.
|
||||
|
||||
@@ -448,19 +551,74 @@ def _pcm16_to_f32(pcm: bytes):
|
||||
return np.frombuffer(pcm, dtype=np.int16).astype(np.float32) / 32768.0
|
||||
|
||||
|
||||
async def _sherpa_session(websocket: WebSocket):
|
||||
"""Shared WS receive setup for the sherpa handlers.
|
||||
def _pcm16_rms(pcm: bytes) -> float:
|
||||
samples = _pcm16_to_f32(pcm)
|
||||
if not len(samples):
|
||||
return 0.0
|
||||
return float((samples * samples).mean() ** 0.5)
|
||||
|
||||
Returns ``(get_frame, state)`` where ``get_frame`` is an async callable
|
||||
that yields the next near-end (mic) PCM bytes, ``b""`` for a keepalive/ref
|
||||
frame, or ``None`` on EOF/disconnect. ``state`` carries sample rate, AEC,
|
||||
and the disconnect flag for the caller's finaliser.
|
||||
"""
|
||||
pcm_sr = 16000
|
||||
|
||||
async def _recover_silent_sherpa(
|
||||
spec, pcm: bytes, pcm_sr: int,
|
||||
) -> tuple[str, list[dict]]:
|
||||
"""Retry a token-silent Sherpa session through an installed local ASR."""
|
||||
logger.warning(
|
||||
"dictation model %s decoded NOTHING from %.1fs of speech-level audio "
|
||||
"— falling back to the capture ASR engine for this session",
|
||||
spec.id, len(pcm) / float(max(1, pcm_sr) * 2),
|
||||
)
|
||||
try:
|
||||
pcm_sr = int(websocket.query_params.get("sr", "16000"))
|
||||
except (TypeError, ValueError):
|
||||
pcm_sr = 16000
|
||||
from services.asr_backend import asr_model_missing_error
|
||||
fallback_missing = await asyncio.to_thread(
|
||||
asr_model_missing_error,
|
||||
purpose="dictation",
|
||||
skip_sherpa=True,
|
||||
require_installed=True,
|
||||
)
|
||||
if fallback_missing is not None:
|
||||
logger.warning(
|
||||
"dictation silent-model fallback is not installed (%s); "
|
||||
"skipping recovery to avoid an automatic download",
|
||||
fallback_missing.get("missing_repo_id", "unknown"),
|
||||
)
|
||||
return "", []
|
||||
|
||||
result = await _transcribe_buffer_full(
|
||||
[pcm], pcm_sr=pcm_sr, skip_sherpa=True,
|
||||
)
|
||||
text = polish_text(_result_text(result))
|
||||
if not text:
|
||||
return "", []
|
||||
# The RMS gate can fire on fan/keyboard noise. Only another recognizer
|
||||
# producing words proves the audio held speech and makes persistent
|
||||
# demotion safe.
|
||||
try:
|
||||
from services.sherpa_dictation import demote_model
|
||||
if await asyncio.to_thread(demote_model, spec.id):
|
||||
logger.error(
|
||||
"dictation model %s demoted on this machine — it will no longer be "
|
||||
"auto-selected. Pick it again in Settings to give it another chance.",
|
||||
spec.id,
|
||||
)
|
||||
except Exception:
|
||||
logger.exception("silent-model demotion failed")
|
||||
segments = (result or {}).get("segments") or [
|
||||
{"start": 0.0, "end": None, "text": text}
|
||||
]
|
||||
return text, segments
|
||||
except Exception:
|
||||
logger.exception("dictation silent-model fallback failed")
|
||||
return "", []
|
||||
|
||||
|
||||
async def _sherpa_session(websocket: WebSocket):
|
||||
"""Shared WS setup for the sherpa handlers.
|
||||
|
||||
Returns ``(pcm_sr, aec)``: the bounded PCM sample rate for the session
|
||||
and the echo canceller when ``?aec=1`` requested one (``None`` otherwise
|
||||
or when AEC setup fails).
|
||||
"""
|
||||
pcm_sr = _bounded_sample_rate(websocket.query_params)
|
||||
aec = None
|
||||
if websocket.query_params.get("aec") in ("1", "true", "on"):
|
||||
try:
|
||||
@@ -569,6 +727,8 @@ async def _run_sherpa_streaming(websocket: WebSocket, spec):
|
||||
|
||||
last_partial = ""
|
||||
committed: list[str] = [] # finalized utterances this session
|
||||
session_pcm = RecoveryTail(pcm_sr) # bounded audio for silent-model recovery
|
||||
heard_speech = False
|
||||
client_disconnected = False
|
||||
|
||||
async def _send(payload) -> bool:
|
||||
@@ -610,6 +770,9 @@ async def _run_sherpa_streaming(websocket: WebSocket, spec):
|
||||
break
|
||||
if kind == "skip":
|
||||
continue
|
||||
session_pcm.extend(pcm)
|
||||
if not heard_speech and _pcm16_rms(pcm) >= SHERPA_OFFLINE_RMS_FLOOR:
|
||||
heard_speech = True
|
||||
text, endpoint = await asyncio.to_thread(_decode_after_feed, pcm)
|
||||
if endpoint:
|
||||
# Commit this utterance (polished — it gets pasted); reset
|
||||
@@ -618,6 +781,7 @@ async def _run_sherpa_streaming(websocket: WebSocket, spec):
|
||||
if text:
|
||||
committed.append(text)
|
||||
await _send({"type": "final", "text": text,
|
||||
"final_kind": "utterance",
|
||||
"segments": [{"start": 0.0, "end": None, "text": text}],
|
||||
"language": "auto", "engine": backend.id})
|
||||
rec.reset(stream)
|
||||
@@ -644,7 +808,28 @@ async def _run_sherpa_streaming(websocket: WebSocket, spec):
|
||||
# Pieces are already polished; the join is too (polish is idempotent).
|
||||
full = " ".join(t for t in committed if t).strip()
|
||||
segments = [{"start": 0.0, "end": None, "text": t} for t in committed if t]
|
||||
|
||||
model_silent = is_model_silent(full, heard_speech, session_pcm.total_bytes)
|
||||
if model_silent:
|
||||
recovered, recovered_segments = await _recover_silent_sherpa(
|
||||
spec, session_pcm.tail(), pcm_sr,
|
||||
)
|
||||
if recovered:
|
||||
full = recovered
|
||||
segments = recovered_segments
|
||||
|
||||
if not client_disconnected:
|
||||
payload = {"type": "final", "text": full, "final_kind": "summary",
|
||||
"segments": segments,
|
||||
"language": "auto", "engine": backend.id}
|
||||
if model_silent:
|
||||
payload["engine"] = "capture-asr-fallback" if full else backend.id
|
||||
payload["model_silent"] = spec.id
|
||||
payload["warning"] = (
|
||||
f"The selected dictation model ({spec.id}) produced no text from your "
|
||||
"speech. Switched to the fallback engine for this session — pick a "
|
||||
"different model in Settings → Dictation."
|
||||
)
|
||||
if full:
|
||||
# Hard-bounded refinement (~4s): never delays this summary `final`
|
||||
# beyond OMNIVOICE_REFINE_TIMEOUT_S even with a dead LLM endpoint.
|
||||
@@ -653,14 +838,9 @@ async def _run_sherpa_streaming(websocket: WebSocket, spec):
|
||||
refined = await maybe_refine_async(full)
|
||||
except Exception:
|
||||
refined = None
|
||||
payload = {"type": "final", "text": full, "segments": segments,
|
||||
"language": "auto", "engine": backend.id}
|
||||
if refined and refined != full:
|
||||
payload["refined_text"] = refined
|
||||
await _send(payload)
|
||||
else:
|
||||
await _send({"type": "final", "text": "", "segments": [],
|
||||
"language": "auto", "engine": backend.id})
|
||||
await _send(payload)
|
||||
try:
|
||||
await websocket.close()
|
||||
except Exception:
|
||||
@@ -697,7 +877,7 @@ async def _run_sherpa_offline(websocket: WebSocket, spec):
|
||||
# whisper/zipformer transcribe the same bytes). Keep the whole session's
|
||||
# audio and whether any of it was speech-level, so the finaliser can tell
|
||||
# "user said nothing" (fine) from "model produced nothing" (broken).
|
||||
session_pcm = bytearray()
|
||||
session_pcm = RecoveryTail(pcm_sr)
|
||||
heard_speech = False
|
||||
running = True
|
||||
client_disconnected = False
|
||||
@@ -716,12 +896,6 @@ async def _run_sherpa_offline(websocket: WebSocket, spec):
|
||||
client_disconnected = True
|
||||
return False
|
||||
|
||||
def _rms(pcm: bytes) -> float:
|
||||
samples = _pcm16_to_f32(pcm)
|
||||
if not len(samples):
|
||||
return 0.0
|
||||
return float((samples * samples).mean() ** 0.5)
|
||||
|
||||
def _decode_window(pcm: bytes) -> str:
|
||||
samples = _pcm16_to_f32(pcm)
|
||||
if not len(samples):
|
||||
@@ -740,7 +914,7 @@ async def _run_sherpa_offline(websocket: WebSocket, spec):
|
||||
continue
|
||||
buf.extend(pcm)
|
||||
session_pcm.extend(pcm)
|
||||
if not heard_speech and _rms(pcm) >= SHERPA_OFFLINE_RMS_FLOOR:
|
||||
if not heard_speech and _pcm16_rms(pcm) >= SHERPA_OFFLINE_RMS_FLOOR:
|
||||
heard_speech = True
|
||||
last_audio = time.monotonic()
|
||||
except WebSocketDisconnect:
|
||||
@@ -766,6 +940,7 @@ async def _run_sherpa_offline(websocket: WebSocket, spec):
|
||||
if text:
|
||||
committed.append(text)
|
||||
await _send({"type": "final", "text": text,
|
||||
"final_kind": "utterance",
|
||||
"segments": [{"start": 0.0, "end": None, "text": text}],
|
||||
"language": "auto", "engine": backend.id})
|
||||
|
||||
@@ -777,8 +952,8 @@ async def _run_sherpa_offline(websocket: WebSocket, spec):
|
||||
continue
|
||||
snapshot = bytes(buf)
|
||||
if len(snapshot) > sil_bytes and \
|
||||
_rms(snapshot[-sil_bytes:]) < SHERPA_OFFLINE_RMS_FLOOR:
|
||||
if _rms(snapshot[:-sil_bytes]) >= SHERPA_OFFLINE_RMS_FLOOR:
|
||||
_pcm16_rms(snapshot[-sil_bytes:]) < SHERPA_OFFLINE_RMS_FLOOR:
|
||||
if _pcm16_rms(snapshot[:-sil_bytes]) >= SHERPA_OFFLINE_RMS_FLOOR:
|
||||
await _commit(snapshot)
|
||||
else:
|
||||
# Pure silence — drop it (keep the gate window for
|
||||
@@ -824,39 +999,18 @@ async def _run_sherpa_offline(websocket: WebSocket, spec):
|
||||
# quiet user — hand the session to the capture ASR backend so the user
|
||||
# still gets their words, and say which model let them down. Bounded to
|
||||
# this session; the pref is left alone so the user stays in control.
|
||||
model_silent = is_model_silent(full, heard_speech, len(session_pcm))
|
||||
model_silent = is_model_silent(full, heard_speech, session_pcm.total_bytes)
|
||||
if model_silent:
|
||||
logger.warning(
|
||||
"dictation model %s decoded NOTHING from %.1fs of speech-level audio "
|
||||
"— falling back to the capture ASR engine for this session",
|
||||
spec.id, len(session_pcm) / float(max(1, pcm_sr) * 2),
|
||||
recovered, recovered_segments = await _recover_silent_sherpa(
|
||||
spec, session_pcm.tail(), pcm_sr,
|
||||
)
|
||||
# Demote it so the NEXT session doesn't repeat this round trip. The
|
||||
# curated default can be broken on a platform we never tested (the
|
||||
# NeMo-TDT decoder is, on Windows), and observing it beats guessing.
|
||||
try:
|
||||
from services.sherpa_dictation import demote_model
|
||||
if demote_model(spec.id):
|
||||
logger.error(
|
||||
"dictation model %s demoted on this machine — it will no longer be "
|
||||
"auto-selected. Pick it again in Settings to give it another chance.",
|
||||
spec.id,
|
||||
)
|
||||
except Exception:
|
||||
logger.exception("silent-model demotion failed")
|
||||
try:
|
||||
result = await _transcribe_buffer_full([bytes(session_pcm)], pcm_sr=pcm_sr)
|
||||
fb_text = polish_text((result or {}).get("text", "") or "")
|
||||
if fb_text:
|
||||
full = fb_text
|
||||
segments = (result or {}).get("segments") or [
|
||||
{"start": 0.0, "end": None, "text": fb_text}
|
||||
]
|
||||
except Exception:
|
||||
logger.exception("dictation silent-model fallback failed")
|
||||
if recovered:
|
||||
full = recovered
|
||||
segments = recovered_segments
|
||||
|
||||
if not client_disconnected:
|
||||
payload = {"type": "final", "text": full, "segments": segments,
|
||||
payload = {"type": "final", "text": full, "final_kind": "summary",
|
||||
"segments": segments,
|
||||
"language": "auto", "engine": backend.id}
|
||||
if model_silent:
|
||||
# The client surfaces this so a silently-broken model can't look
|
||||
@@ -884,6 +1038,35 @@ async def _run_sherpa_offline(websocket: WebSocket, spec):
|
||||
pass
|
||||
|
||||
|
||||
def _result_text(result: dict | None) -> str:
|
||||
"""Normalize text from every ASR backend result shape.
|
||||
|
||||
Some backends return a top-level ``text`` value, while WhisperX, Faster
|
||||
Whisper, Moonshine, and OpenAI-compatible ASR expose only ``segments`` and
|
||||
``chunks``. Dictation partials and finals must interpret both contracts the
|
||||
same way.
|
||||
"""
|
||||
if not isinstance(result, dict):
|
||||
return ""
|
||||
|
||||
text = result.get("text")
|
||||
if isinstance(text, str) and text.strip():
|
||||
return text.strip()
|
||||
|
||||
for key in ("segments", "chunks"):
|
||||
items = result.get(key)
|
||||
if not isinstance(items, (list, tuple)):
|
||||
continue
|
||||
text = " ".join(
|
||||
str(item.get("text", "")).strip()
|
||||
for item in items
|
||||
if isinstance(item, dict) and item.get("text")
|
||||
).strip()
|
||||
if text:
|
||||
return text
|
||||
return ""
|
||||
|
||||
|
||||
async def _transcribe_buffer(chunks: list[bytes], *, pcm_sr: int | None = None) -> str:
|
||||
"""Quick partial transcription of the current audio buffer."""
|
||||
|
||||
@@ -898,7 +1081,7 @@ async def _transcribe_buffer(chunks: list[bytes], *, pcm_sr: int | None = None)
|
||||
def _run():
|
||||
backend = get_capture_asr_backend()
|
||||
result = backend.transcribe(tmp, word_timestamps=False)
|
||||
return result.get("text", "")
|
||||
return _result_text(result)
|
||||
|
||||
# Bound dictation transcribes (#730): a wedged whisperx/CTranslate2 call
|
||||
# must not hold its GPU-pool worker forever and starve TTS / other ASR
|
||||
@@ -912,7 +1095,9 @@ async def _transcribe_buffer(chunks: list[bytes], *, pcm_sr: int | None = None)
|
||||
pass
|
||||
|
||||
|
||||
async def _transcribe_buffer_full(chunks: list[bytes], *, pcm_sr: int | None = None) -> dict:
|
||||
async def _transcribe_buffer_full(
|
||||
chunks: list[bytes], *, pcm_sr: int | None = None, skip_sherpa: bool = False,
|
||||
) -> dict:
|
||||
"""Full transcription with timing info for the final result."""
|
||||
tmp = _pcm16_to_wav(b"".join(chunks), pcm_sr) if pcm_sr else _chunks_to_wav(chunks)
|
||||
if tmp is None:
|
||||
@@ -924,15 +1109,13 @@ async def _transcribe_buffer_full(chunks: list[bytes], *, pcm_sr: int | None = N
|
||||
from services.asr_backend import get_capture_asr_backend, run_transcribe_guarded
|
||||
|
||||
def _run():
|
||||
backend = get_capture_asr_backend()
|
||||
backend = get_capture_asr_backend(skip_sherpa=skip_sherpa)
|
||||
t0 = time.perf_counter()
|
||||
result = backend.transcribe(tmp, word_timestamps=False)
|
||||
elapsed = round(time.perf_counter() - t0, 2)
|
||||
|
||||
segments = result.get("segments", [])
|
||||
full_text = result.get("text", "")
|
||||
if not full_text and segments:
|
||||
full_text = " ".join(s.get("text", "") for s in segments).strip()
|
||||
full_text = _result_text(result)
|
||||
|
||||
# Wave 1.1: strip Whisper hallucination loops from the final
|
||||
# text (the string that gets auto-pasted). Segments keep the
|
||||
|
||||
@@ -577,6 +577,118 @@ def _clamp_num_speakers(value) -> Optional[int]:
|
||||
return value if 1 <= value <= 20 else None
|
||||
|
||||
|
||||
def _recover_from_phrase_embeddings(
|
||||
diar_pipe,
|
||||
diarized_segments: list[dict],
|
||||
*,
|
||||
phrases: list[dict],
|
||||
requested_speakers: int | None,
|
||||
audio_target: str,
|
||||
segments: list[dict],
|
||||
words: list,
|
||||
):
|
||||
"""Recover rapid turns when pyannote collapses a two-speaker exchange.
|
||||
|
||||
Uses ASR phrase boundaries and the embedding/audio components already
|
||||
loaded by speaker-diarization-3.1. Weak or imbalanced clusters are rejected
|
||||
so ordinary single-speaker recordings remain untouched. Returns
|
||||
``(segments, separation)`` or ``None``.
|
||||
"""
|
||||
present = {
|
||||
str(seg.get("speaker_id")) for seg in diarized_segments
|
||||
if seg.get("speaker_id")
|
||||
}
|
||||
if len(present) > 1:
|
||||
return None
|
||||
usable_phrases = [
|
||||
phrase for phrase in phrases
|
||||
if phrase.get("text")
|
||||
and float(phrase.get("end", 0.0)) - float(phrase.get("start", 0.0)) >= 0.75
|
||||
]
|
||||
if len(usable_phrases) < 4:
|
||||
return None
|
||||
requested = int(requested_speakers) if requested_speakers else 2
|
||||
if requested != 2:
|
||||
return None
|
||||
embedding = getattr(diar_pipe, "_embedding", None)
|
||||
audio = getattr(diar_pipe, "_audio", None)
|
||||
if embedding is None or audio is None:
|
||||
return None
|
||||
try:
|
||||
import numpy as np
|
||||
from pyannote.core import Segment as _PyannoteSegment
|
||||
from sklearn.cluster import AgglomerativeClustering
|
||||
|
||||
vectors = []
|
||||
durations = []
|
||||
for phrase in usable_phrases:
|
||||
start, end = float(phrase["start"]), float(phrase["end"])
|
||||
duration = end - start
|
||||
waveform, _ = audio.crop(
|
||||
audio_target, _PyannoteSegment(start, end),
|
||||
duration=duration, mode="pad",
|
||||
)
|
||||
vector = np.asarray(embedding(waveform[None])).reshape(-1)
|
||||
if not np.isfinite(vector).all():
|
||||
return None
|
||||
vectors.append(vector)
|
||||
durations.append(duration)
|
||||
matrix = np.vstack(vectors)
|
||||
labels = np.asarray(AgglomerativeClustering(
|
||||
n_clusters=2, metric="cosine", linkage="average",
|
||||
).fit_predict(matrix))
|
||||
if len(set(labels.tolist())) != 2:
|
||||
return None
|
||||
|
||||
counts = [int(np.sum(labels == cluster)) for cluster in (0, 1)]
|
||||
cluster_durations = [
|
||||
float(sum(duration for duration, label in zip(durations, labels) if label == cluster))
|
||||
for cluster in (0, 1)
|
||||
]
|
||||
if min(counts) < 2 or min(cluster_durations) < 1.5:
|
||||
return None
|
||||
|
||||
normalized = matrix / np.maximum(np.linalg.norm(matrix, axis=1, keepdims=True), 1e-8)
|
||||
similarities = normalized @ normalized.T
|
||||
within, cross = [], []
|
||||
for left in range(len(labels)):
|
||||
for right in range(left + 1, len(labels)):
|
||||
target = within if labels[left] == labels[right] else cross
|
||||
target.append(float(similarities[left, right]))
|
||||
if not within or not cross:
|
||||
return None
|
||||
separation = float(np.mean(within) - np.mean(cross))
|
||||
min_separation = 0.12 if requested_speakers == 2 else 0.18
|
||||
if separation < min_separation:
|
||||
logger.info(
|
||||
"phrase-embedding speaker recovery rejected (separation=%.3f < %.3f)",
|
||||
separation, min_separation,
|
||||
)
|
||||
return None
|
||||
|
||||
speaker_map = {}
|
||||
turns = []
|
||||
for phrase, label in zip(usable_phrases, labels.tolist()):
|
||||
if label not in speaker_map:
|
||||
speaker_map[label] = f"Speaker {len(speaker_map) + 1}"
|
||||
turns.append({
|
||||
"start": float(phrase["start"]),
|
||||
"end": float(phrase["end"]),
|
||||
"speaker": speaker_map[label],
|
||||
})
|
||||
# Assignment mutates segment dictionaries. Work on copies so a recovery
|
||||
# rejected by the final two-speaker check cannot leak partial labels
|
||||
# into the ordinary pyannote result.
|
||||
assigned = assign_speakers_from_turns([dict(item) for item in segments], turns)
|
||||
recovered = resplit_segments_by_turns(assigned, words, turns)
|
||||
if len({item.get("speaker_id") for item in recovered if item.get("speaker_id")}) < 2:
|
||||
return None
|
||||
return recovered, separation
|
||||
except Exception:
|
||||
logger.exception("phrase-embedding speaker recovery failed")
|
||||
return None
|
||||
|
||||
|
||||
@router.get("/dub/transcribe-stream/{job_id}")
|
||||
async def dub_transcribe_stream(
|
||||
job_id: str,
|
||||
@@ -912,6 +1024,12 @@ async def dub_transcribe_stream(
|
||||
# Words (global-timeline) retained so diarization can re-split a segment
|
||||
# that spans two speakers' turns at the word boundary (#486).
|
||||
all_words: list = []
|
||||
# Preserve the ASR backend's natural phrase boundaries before
|
||||
# segment_transcript merges short neighboring phrases. Pyannote 3.1
|
||||
# occasionally collapses rapid exchanges into one dominant speaker; in
|
||||
# that narrow case these phrase spans give its own WeSpeaker embedding
|
||||
# model clean candidate utterances for a conservative recovery pass.
|
||||
asr_phrase_segments: list[dict] = []
|
||||
detected_lang = None
|
||||
next_seg_id = 0
|
||||
chunk_errors: list[str] = []
|
||||
@@ -1048,6 +1166,17 @@ async def dub_transcribe_stream(
|
||||
if detected_lang is None and part.get("language"):
|
||||
detected_lang = part["language"]
|
||||
asr_speaker_turns.extend(part.get("speaker_turns") or [])
|
||||
for _phrase in part.get("chunks", []) or []:
|
||||
_pts = _phrase.get("timestamp") or (None, None)
|
||||
_ptext = (_phrase.get("text") or "").strip()
|
||||
try:
|
||||
_ps, _pe = float(_pts[0]), float(_pts[1])
|
||||
except (TypeError, ValueError, IndexError):
|
||||
continue
|
||||
if _ptext and _pe > _ps:
|
||||
asr_phrase_segments.append({
|
||||
"start": _ps, "end": _pe, "text": _ptext,
|
||||
})
|
||||
chunk_segs = segment_transcript(part, duration=t1, scene_cuts=scene_cuts)
|
||||
# Same word source segment_transcript used (already global-timeline),
|
||||
# kept for the post-diarization speaker re-split (#486).
|
||||
@@ -1313,7 +1442,25 @@ async def dub_transcribe_stream(
|
||||
assigned = assign_speakers_from_diarization(all_segments, diar)
|
||||
# #486: split any segment that spans two speakers' turns at the
|
||||
# word boundary (single-speaker segments pass through unchanged).
|
||||
return resplit_segments_by_diarization(assigned, all_words, diar), None, "pyannote"
|
||||
resplit = resplit_segments_by_diarization(assigned, all_words, diar)
|
||||
recovered = _recover_from_phrase_embeddings(
|
||||
diar_pipe,
|
||||
resplit,
|
||||
phrases=asr_phrase_segments,
|
||||
requested_speakers=num_speakers,
|
||||
audio_target=asr_audio_target,
|
||||
segments=all_segments,
|
||||
words=all_words,
|
||||
)
|
||||
if recovered is not None:
|
||||
recovered_segments, separation = recovered
|
||||
logger.info(
|
||||
"Recovered rapid two-speaker exchange from ASR phrase embeddings "
|
||||
"(phrases=%d, separation=%.3f).",
|
||||
len(asr_phrase_segments), separation,
|
||||
)
|
||||
return recovered_segments, None, "phrase_embeddings"
|
||||
return resplit, None, "pyannote"
|
||||
except Exception as e:
|
||||
logger.exception("Diarization failed")
|
||||
# Inline ASR turns beat the silence-gap heuristic as a crash
|
||||
|
||||
@@ -572,7 +572,7 @@ def _build_audio_export_cmd(
|
||||
async def dub_download(
|
||||
job_id: str,
|
||||
preserve_bg: bool = Query(True, description="Mix background noise into dubbed tracks"),
|
||||
default_track: str = Query("original"),
|
||||
default_track: str = Query("", description="Default audio track; omitted selects the first dubbed track"),
|
||||
include_tracks: str = Query("", description="Comma-separated list of tracks to include (e.g. 'original,de,es'). Empty = include all."),
|
||||
save_authorization: str = Header("", alias="X-VoiceStudio-Path-Authorization"),
|
||||
burn_subs: bool = Query(False, description="Burn subtitles into the video stream (forces re-encode). Uses dual-subtitle layout when dual=1."),
|
||||
@@ -607,6 +607,18 @@ async def dub_download(
|
||||
for key, value in filtered_tracks.items()
|
||||
}
|
||||
|
||||
# A dub export should play the dub without requiring player-specific track
|
||||
# selection. Keep ``original`` as an explicit opt-in, but when callers omit
|
||||
# the preference choose the first generated dub consistently (#1575).
|
||||
if (
|
||||
filtered_tracks
|
||||
and not (default_track == "original" and include_original)
|
||||
and default_track not in filtered_tracks
|
||||
):
|
||||
default_track = next(iter(filtered_tracks))
|
||||
elif not filtered_tracks and include_original:
|
||||
default_track = "original"
|
||||
|
||||
if not filtered_tracks and not include_original:
|
||||
raise HTTPException(status_code=400, detail="No tracks selected for export")
|
||||
|
||||
@@ -631,12 +643,17 @@ async def dub_download(
|
||||
fmt = (out_format or "m4a").lower()
|
||||
if fmt not in _AUDIO_FORMAT_CODECS:
|
||||
fmt = "m4a"
|
||||
# lang_code is already constrained to an existing track key, but
|
||||
# allowlist-sanitize it before it reaches the output path so a path
|
||||
# component can never carry separators/traversal (same pattern as
|
||||
# safe_name below).
|
||||
safe_lang = "".join(c for c in lang_code if c.isalnum() or c in "-_") or "track"
|
||||
out_path = os.path.join(exports_dir, f"dubbed_audio_{safe_lang}_{stamp}.{fmt}")
|
||||
# Keep route/job data out of the filesystem and logging trust boundary.
|
||||
# The selected format reaches the path only through literal branches.
|
||||
if fmt == "wav":
|
||||
output_name = f"dubbed_audio_{stamp}.wav"
|
||||
elif fmt == "mp3":
|
||||
output_name = f"dubbed_audio_{stamp}.mp3"
|
||||
elif fmt == "flac":
|
||||
output_name = f"dubbed_audio_{stamp}.flac"
|
||||
else:
|
||||
output_name = f"dubbed_audio_{stamp}.m4a"
|
||||
out_path = os.path.join(exports_dir, output_name)
|
||||
bg = _optional_dub_artifact(job.get("no_vocals_path"), job_id) if preserve_bg else None
|
||||
cmd = _build_audio_export_cmd(ffmpeg, track_info["path"], bg, out_path, fmt)
|
||||
try:
|
||||
@@ -654,15 +671,28 @@ async def dub_download(
|
||||
)
|
||||
if not os.path.exists(out_path) or os.path.getsize(out_path) == 0:
|
||||
raise HTTPException(status_code=500, detail="ffmpeg audio export produced no output file")
|
||||
logger.info("Dub audio export wrote %s (%d bytes)", out_path, os.path.getsize(out_path))
|
||||
logger.info("Dub audio export completed (%d bytes)", os.path.getsize(out_path))
|
||||
|
||||
base_name = os.path.splitext(job.get("filename", "output"))[0]
|
||||
safe_name = "".join(c for c in base_name if c.isalnum() or c in "-_ ").strip() or "output"
|
||||
dl_name = f"dubbed_{safe_name}_{safe_lang}_{stamp}.{fmt}"
|
||||
# Response metadata must not become a second path-like sink for job or
|
||||
# request data. Keep the user-selected format through explicit literal
|
||||
# branches; source names and language keys never enter the label.
|
||||
if fmt == "wav":
|
||||
dl_name = f"dubbed_audio_{stamp}.wav"
|
||||
elif fmt == "mp3":
|
||||
dl_name = f"dubbed_audio_{stamp}.mp3"
|
||||
elif fmt == "flac":
|
||||
dl_name = f"dubbed_audio_{stamp}.flac"
|
||||
else:
|
||||
dl_name = f"dubbed_audio_{stamp}.m4a"
|
||||
media_type = _MEDIA_TYPES.get(f".{fmt}", "audio/mp4")
|
||||
save_path = _consume_native_save(save_authorization)
|
||||
if save_path:
|
||||
return _native_save(out_path, save_path, dl_name, media_type=media_type)
|
||||
# Keep the request-derived download label out of the filesystem
|
||||
# trust boundary. It is response metadata, not a source or
|
||||
# destination path (CodeQL, #1575).
|
||||
result = _native_save(out_path, save_path, "dubbed_audio", media_type=media_type)
|
||||
result["display_name"] = dl_name
|
||||
return result
|
||||
return FileResponse(
|
||||
out_path, media_type=media_type,
|
||||
headers={"Content-Disposition": content_disposition(dl_name)},
|
||||
@@ -887,7 +917,10 @@ async def dub_download(
|
||||
if default_track == "original" and include_original:
|
||||
cmd += ["-disposition:a:0", "default"]
|
||||
else:
|
||||
target_idx = 0
|
||||
# A stale/missing language preference still means "play a dub", not
|
||||
# "silently fall back to the source". The first processed dub is the
|
||||
# deterministic fallback; ``original`` above remains explicit.
|
||||
target_idx = tracks_to_process[0]["stream_idx"] if tracks_to_process else 0
|
||||
for t in tracks_to_process:
|
||||
if t['lang_code'] == default_track:
|
||||
target_idx = t["stream_idx"]
|
||||
|
||||
@@ -1,6 +1,7 @@
|
||||
import os
|
||||
import re
|
||||
import json
|
||||
import struct
|
||||
import logging
|
||||
import time
|
||||
import asyncio
|
||||
@@ -80,6 +81,62 @@ def _prepare_oom_retry(error: Exception, *, execution_target: str) -> bool:
|
||||
return True
|
||||
|
||||
|
||||
def _cached_payload_intact(path: str, info) -> bool:
|
||||
"""Cheap truth check on a cached WAV whose header we are about to trust.
|
||||
|
||||
The natural-rate fast path hands the mixer a PATH instead of decoded
|
||||
audio, so a cache whose header reads fine but whose payload is truncated
|
||||
would only fail later, during assembly — after the timing plan (Smart Fit,
|
||||
video stretch) had been computed from the header's frame count. The plan
|
||||
would then describe audio that no longer exists and the segment would be
|
||||
replaced by slot-length silence, leaving the persisted video plan and the
|
||||
rendered track disagreeing.
|
||||
|
||||
Comparing the declared frame count against the physical ``data`` chunk
|
||||
catches that without decoding: a truncated file cannot hold the samples
|
||||
its header claims. Anything failing here falls through to the decoding path, which
|
||||
already degrades to a warning plus silence. Formats with no fixed
|
||||
bits-per-sample (compressed caches) are left to the decoder as before.
|
||||
"""
|
||||
try:
|
||||
bits = int(getattr(info, "bits_per_sample", 0) or 0)
|
||||
frames = int(getattr(info, "num_frames", 0) or 0)
|
||||
channels = int(getattr(info, "num_channels", 0) or 0)
|
||||
if bits <= 0 or frames <= 0 or channels <= 0:
|
||||
# Undecidable metadata fails CLOSED (review on #1620): these caches
|
||||
# are PCM WAVs this module wrote itself, so anything else is
|
||||
# unexpected — and the decode path this falls through to handles
|
||||
# every format the fast path would have.
|
||||
return False
|
||||
payload = frames * channels * (bits // 8)
|
||||
if payload <= 0:
|
||||
return False
|
||||
|
||||
# A WAV may carry JUNK/LIST metadata before data, so its header is not
|
||||
# necessarily 44 bytes. Locate the data chunk instead of counting
|
||||
# metadata as audio; otherwise an extended header can mask truncation.
|
||||
file_size = os.path.getsize(path)
|
||||
with open(path, "rb") as wav:
|
||||
header = wav.read(12)
|
||||
if len(header) != 12 or header[:4] != b"RIFF" or header[8:12] != b"WAVE":
|
||||
return False
|
||||
offset = 12
|
||||
while offset + 8 <= file_size:
|
||||
wav.seek(offset)
|
||||
chunk_id = wav.read(4)
|
||||
chunk_size_raw = wav.read(4)
|
||||
if len(chunk_id) != 4 or len(chunk_size_raw) != 4:
|
||||
return False
|
||||
chunk_size = struct.unpack("<I", chunk_size_raw)[0]
|
||||
data_offset = offset + 8
|
||||
if chunk_id == b"data":
|
||||
return chunk_size >= payload and file_size >= data_offset + payload
|
||||
offset = data_offset + chunk_size + (chunk_size % 2)
|
||||
return False
|
||||
except Exception: # noqa: BLE001 — an unstattable cache is the decoder's problem
|
||||
return False
|
||||
|
||||
|
||||
def _underrun_min_rate() -> float:
|
||||
"""Floor for the underrun fill (audio slowed toward its slot, never below
|
||||
this rate). Default 0.85 stays natural-sounding; OMNIVOICE_UNDERRUN_MIN_RATE=1.0
|
||||
@@ -593,11 +650,11 @@ async def dub_generate(job_id: str, req: DubRequest):
|
||||
voice_match = (req.voice_match or "per_line").lower()
|
||||
_consistent_ref_memo: dict = {}
|
||||
remote_audio: dict[int, str] = {}
|
||||
# Strategy-transition guard: smart_fit re-mixes the *natural-rate*
|
||||
# per-segment WAVs from disk. If the previous run used strict_slot,
|
||||
# the on-disk WAVs are slot-squeezed ("slotted") — reusing them would
|
||||
# double-compress. Force one full regen; afterwards seg_wav_kind is
|
||||
# "natural" and partial regen / fit-only re-mix (regen_only=[]) work.
|
||||
# Strategy-transition guard: concise, stretch_video and smart_fit all
|
||||
# re-mix *natural-rate* per-segment WAVs. If the previous run used
|
||||
# strict_slot, the on-disk WAVs are slot-squeezed ("slotted") — the
|
||||
# missing tails cannot be recovered by a re-mix. Force one full regen;
|
||||
# afterwards partial regen / fit-only re-mix (regen_only=[]) is safe.
|
||||
# Jobs predating this field have unknown kind → also regen once.
|
||||
# P1.3: the kind is per-track now (each language renders under its own
|
||||
# strategy); the flat job["seg_wav_kind"] is only consulted for jobs
|
||||
@@ -608,7 +665,7 @@ async def dub_generate(job_id: str, req: DubRequest):
|
||||
_wav_kind = (
|
||||
_kind_map.get(lang_code) if isinstance(_kind_map, dict) else job.get("seg_wav_kind")
|
||||
)
|
||||
if strategy == "smart_fit" and regen_only is not None and _wav_kind != "natural":
|
||||
if strategy != "strict_slot" and regen_only is not None and _wav_kind != "natural":
|
||||
regen_only = None
|
||||
# Manifest: stable segment id per current index. Per-segment WAVs are
|
||||
# named by stable id (dub_seg_path) so regen reuses the right audio after
|
||||
@@ -759,15 +816,38 @@ async def dub_generate(job_id: str, req: DubRequest):
|
||||
if os.path.exists(seg_wav_path):
|
||||
try:
|
||||
_t_cache_0 = time.perf_counter()
|
||||
# Natural-rate caches are already the exact assembly
|
||||
# input. Keep the durable path in the manifest so the
|
||||
# mixer decodes it once; the old path decoded here,
|
||||
# wrote an identical mix_<id> scratch WAV, then decoded
|
||||
# that copy again. Header-only inspection preserves
|
||||
# the resample fallback for caches made by an engine
|
||||
# with a different sample rate.
|
||||
if strategy != "strict_slot":
|
||||
try:
|
||||
cached_info = torchaudio.info(seg_wav_path)
|
||||
except Exception:
|
||||
cached_info = None
|
||||
if (
|
||||
cached_info is not None
|
||||
and int(cached_info.sample_rate) == int(backend.sample_rate)
|
||||
and _cached_payload_intact(seg_wav_path, cached_info)
|
||||
):
|
||||
all_segment_wavs.append(
|
||||
(seg.start, seg.end, seg_wav_path, backend.sample_rate)
|
||||
)
|
||||
sync_scores.append(getattr(seg, 'sync_ratio', None) or 1.0)
|
||||
_t_cache += time.perf_counter() - _t_cache_0
|
||||
continue
|
||||
|
||||
cached_wav, cached_sr = torchaudio.load(seg_wav_path)
|
||||
if cached_sr != backend.sample_rate:
|
||||
import torchaudio.functional as AF
|
||||
cached_wav = AF.resample(cached_wav, cached_sr, backend.sample_rate)
|
||||
# Pad/trim to slot — except smart_fit, whose mix
|
||||
# loop needs the natural-rate length to compute the
|
||||
# audio/video split (the seg_wav_kind guard above
|
||||
# guarantees these cached WAVs are natural-rate).
|
||||
if strategy != "smart_fit":
|
||||
# strict_slot persists slot-sized buffers. Every other
|
||||
# strategy consumes natural-rate audio and lets the mix
|
||||
# loop fit it to the current timeline.
|
||||
if strategy == "strict_slot":
|
||||
target_samples = int(seg_duration * backend.sample_rate)
|
||||
current_samples = cached_wav.shape[-1]
|
||||
if target_samples > current_samples:
|
||||
@@ -1091,7 +1171,7 @@ async def dub_generate(job_id: str, req: DubRequest):
|
||||
_num_step, req.guidance_scale, seg_speed, seg_profile, seg_effect_preset,
|
||||
),
|
||||
what="Dub generate",
|
||||
timeout=generate_timeout_s(seg.text),
|
||||
timeout=generate_timeout_s(seg.text, engine=backend),
|
||||
)
|
||||
_t_tts += time.perf_counter() - _t_tts_0
|
||||
|
||||
@@ -1164,12 +1244,15 @@ async def dub_generate(job_id: str, req: DubRequest):
|
||||
if rvc_sr == backend.sample_rate:
|
||||
audio_tensor = rvc_wav
|
||||
|
||||
target_samples = int(seg_duration * backend.sample_rate)
|
||||
current_samples = audio_tensor.shape[-1]
|
||||
if target_samples > current_samples:
|
||||
audio_tensor = torch.nn.functional.pad(audio_tensor, (0, target_samples - current_samples))
|
||||
elif current_samples > target_samples:
|
||||
audio_tensor = audio_tensor[..., :target_samples]
|
||||
if strategy == "strict_slot":
|
||||
target_samples = int(seg_duration * backend.sample_rate)
|
||||
current_samples = audio_tensor.shape[-1]
|
||||
if target_samples > current_samples:
|
||||
audio_tensor = torch.nn.functional.pad(
|
||||
audio_tensor, (0, target_samples - current_samples)
|
||||
)
|
||||
elif current_samples > target_samples:
|
||||
audio_tensor = audio_tensor[..., :target_samples]
|
||||
except Exception as e:
|
||||
yield f"data: {json.dumps({'type': 'warning', 'segment': i, 'message': f'RVC skipped: {str(e)[:120]}'})}\n\n"
|
||||
|
||||
@@ -1356,7 +1439,21 @@ async def dub_generate(job_id: str, req: DubRequest):
|
||||
seg_gain = getattr(seg_ref, "gain", None) if seg_ref is not None else None
|
||||
seg_gain = seg_gain if seg_gain is not None else 1.0
|
||||
seg_gain = max(0.0, min(2.0, seg_gain))
|
||||
wav = _load_entry_wav((start, end, wav_path, sr), sr)
|
||||
try:
|
||||
wav = _load_entry_wav((start, end, wav_path, sr), sr)
|
||||
except Exception as e:
|
||||
# A WAV header can be readable while its payload is
|
||||
# truncated. Direct cache reuse deliberately defers the
|
||||
# decode to assembly, so preserve the old recovery contract
|
||||
# here: warn and fill this slot with silence instead of
|
||||
# aborting the entire dub.
|
||||
warning = {
|
||||
"type": "warning",
|
||||
"segment": i,
|
||||
"message": f"cached seg lost, padding silence: {str(e)[:120]}",
|
||||
}
|
||||
yield f"data: {json.dumps(warning)}\n\n"
|
||||
wav = torch.zeros(1, max(0, int((end - start) * sr)))
|
||||
adjusted = wav * seg_gain
|
||||
if adjusted.ndim == 2 and adjusted.shape[0] > 1:
|
||||
adjusted = adjusted.mean(dim=0, keepdim=True)
|
||||
@@ -1798,7 +1895,7 @@ async def preview_segment(job_id: str, req: SegmentPreviewRequest):
|
||||
from services.model_manager import generate_timeout_s
|
||||
audio_tensor = await run_on_gpu_pool_guarded(
|
||||
_gen, what="Dub preview generate",
|
||||
timeout=generate_timeout_s(req.text),
|
||||
timeout=generate_timeout_s(req.text, engine=backend),
|
||||
)
|
||||
|
||||
sr = backend.sample_rate
|
||||
|
||||
@@ -596,7 +596,7 @@ def _oom_friendly_reraise(e):
|
||||
) from e
|
||||
|
||||
|
||||
def _generate_timeout_s(text: str) -> float:
|
||||
def _generate_timeout_s(text: str, *, execution_device=None) -> float:
|
||||
"""Wall-clock budget for one generate, scaled to the request.
|
||||
|
||||
Thin alias for the canonical helper, which moved to
|
||||
@@ -605,7 +605,7 @@ def _generate_timeout_s(text: str) -> float:
|
||||
as they did, silently keeping the flat 300s).
|
||||
"""
|
||||
from services.model_manager import generate_timeout_s
|
||||
return generate_timeout_s(text)
|
||||
return generate_timeout_s(text, execution_device=execution_device)
|
||||
|
||||
|
||||
def _run_inference(
|
||||
@@ -870,7 +870,6 @@ async def _finalize_generation(
|
||||
Returns ``(watermarked_tensor, meta)`` where ``meta`` carries
|
||||
``id`` / ``filename`` / ``duration`` / ``gen_time``.
|
||||
"""
|
||||
loop = asyncio.get_running_loop()
|
||||
# Invisible AudioSeal provenance watermark on the final audio. Embedding
|
||||
# was previously only wired into the dub pipeline (dub_generate.py), so
|
||||
# plain TTS came out unmarked despite the setting being on — and the same
|
||||
@@ -882,12 +881,9 @@ async def _finalize_generation(
|
||||
# AudioSeal embedding is CPU work that holds no VRAM, so occupying a GPU
|
||||
# worker with it only delays the next generate on 1-worker hosts.
|
||||
if not already_marked:
|
||||
from services.watermark import mark_synthetic
|
||||
from services.model_manager import get_watermark_pool
|
||||
audio_tensor = await loop.run_in_executor(
|
||||
get_watermark_pool(),
|
||||
functools.partial(mark_synthetic, audio_tensor, sample_rate,
|
||||
context="generate.finalize"),
|
||||
from services.watermark import mark_synthetic_async
|
||||
audio_tensor = await mark_synthetic_async(
|
||||
audio_tensor, sample_rate, context="generate.finalize",
|
||||
)
|
||||
gen_time = round(time.time() - start_time, 2)
|
||||
|
||||
@@ -1198,6 +1194,10 @@ async def generate_speech(
|
||||
_backend = None
|
||||
_engine_min_vram_gb = getattr(backend_cls, "min_vram_gb", 0.0)
|
||||
_routing_notice = None
|
||||
# Remote renders deliberately skip this host's capability gate. Keep the
|
||||
# local fallback call's timeout device-neutral so the closure is valid
|
||||
# without pretending the control plane describes the remote worker.
|
||||
_routing = {"effective_device": None}
|
||||
|
||||
if not _remote:
|
||||
# Single-active-engine memory discipline: hand back any OTHER resident
|
||||
@@ -1406,7 +1406,7 @@ async def generate_speech(
|
||||
# Floor budget (#1190): a reference clip is seconds of audio,
|
||||
# so the length-scaled bonus never applies — but the timeout is
|
||||
# explicit here too, so no dispatch relies on a hidden default.
|
||||
timeout=_generate_timeout_s(""),
|
||||
timeout=_generate_timeout_s("", execution_device=_routing["effective_device"]),
|
||||
)
|
||||
# TimeoutError covers both the execution bound and pool saturation:
|
||||
# this path is best-effort either way.
|
||||
@@ -1523,7 +1523,7 @@ async def generate_speech(
|
||||
local=gpu_gateway.LocalCall(
|
||||
_remote_only_local_call(_target_label),
|
||||
what="TTS generate",
|
||||
timeout=_generate_timeout_s(text),
|
||||
timeout=_generate_timeout_s(text, execution_device=_routing["effective_device"]),
|
||||
min_vram_gb=_engine_min_vram_gb,
|
||||
),
|
||||
remote=_remote_call,
|
||||
@@ -1789,7 +1789,7 @@ async def generate_speech(
|
||||
),
|
||||
what="TTS generate",
|
||||
min_vram_gb=_engine_min_vram_gb,
|
||||
timeout=_generate_timeout_s(text),
|
||||
timeout=_generate_timeout_s(text, execution_device=_routing["effective_device"]),
|
||||
)
|
||||
sample_rate = _backend.sample_rate
|
||||
else:
|
||||
@@ -1805,7 +1805,7 @@ async def generate_speech(
|
||||
),
|
||||
what="TTS generate",
|
||||
min_vram_gb=_engine_min_vram_gb,
|
||||
timeout=_generate_timeout_s(text),
|
||||
timeout=_generate_timeout_s(text, execution_device=_routing["effective_device"]),
|
||||
)
|
||||
sample_rate = _model.sampling_rate
|
||||
yield _line({
|
||||
@@ -1822,12 +1822,10 @@ async def generate_speech(
|
||||
# (#1190): AudioSeal embedding is CPU work that owns no
|
||||
# VRAM, and on a 1-worker host it used to serialize
|
||||
# directly ahead of the next generate.
|
||||
from services.watermark import mark_synthetic
|
||||
from services.model_manager import get_watermark_pool
|
||||
_preview = await asyncio.get_running_loop().run_in_executor(
|
||||
get_watermark_pool(),
|
||||
functools.partial(mark_synthetic, audio_tensor, sample_rate,
|
||||
context="generate.stream_preview"),
|
||||
from services.watermark import mark_synthetic_async
|
||||
_preview = await mark_synthetic_async(
|
||||
audio_tensor, sample_rate,
|
||||
context="generate.stream_preview",
|
||||
)
|
||||
yield _line({"type": "chunk", "seq": 0, "pcm": _pcm16_b64(_preview)})
|
||||
else:
|
||||
@@ -1843,18 +1841,16 @@ async def generate_speech(
|
||||
# Budget scaled to THIS chunk (#1190) — the flat
|
||||
# 300s here is what made long streamed renders fail
|
||||
# even after the v0.3.22 scaled budget shipped.
|
||||
timeout=_generate_timeout_s(chunk_text),
|
||||
timeout=_generate_timeout_s(chunk_text, execution_device=_routing["effective_device"]),
|
||||
)
|
||||
parts.append(raw)
|
||||
# Provenance-mark the streamed copy off the GPU pool
|
||||
# (#1169 mark, #1190 placement): CPU-only AudioSeal
|
||||
# work must not occupy a GPU worker between chunks.
|
||||
from services.watermark import mark_synthetic
|
||||
from services.model_manager import get_watermark_pool
|
||||
preview = await asyncio.get_running_loop().run_in_executor(
|
||||
get_watermark_pool(),
|
||||
functools.partial(mark_synthetic, preview, sample_rate,
|
||||
context="generate.stream_preview"),
|
||||
from services.watermark import mark_synthetic_async
|
||||
preview = await mark_synthetic_async(
|
||||
preview, sample_rate,
|
||||
context="generate.stream_preview",
|
||||
)
|
||||
if i == 0:
|
||||
# After the first render so lazy-loading engines
|
||||
@@ -1869,7 +1865,7 @@ async def generate_speech(
|
||||
audio_tensor = await run_on_gpu_pool_guarded(
|
||||
functools.partial(_assemble_stream_chunks, parts, sample_rate),
|
||||
what="TTS assemble",
|
||||
timeout=_generate_timeout_s(text),
|
||||
timeout=_generate_timeout_s(text, execution_device=_routing["effective_device"]),
|
||||
)
|
||||
|
||||
_, meta = await _finalize_generation(
|
||||
@@ -1898,7 +1894,7 @@ async def generate_speech(
|
||||
# Client went away mid-stream — same semantics as aborting a
|
||||
# classic /generate mid-render: nothing is saved.
|
||||
raise
|
||||
except (GpuJobTimeoutError, GpuPoolBusyError) as e:
|
||||
except GpuPoolBusyError as e:
|
||||
# In-band error frame carries the machine-readable retryable
|
||||
# marker (#1190) — an NDJSON consumer can back off instead of
|
||||
# guessing from the prose.
|
||||
@@ -1907,6 +1903,14 @@ async def generate_speech(
|
||||
failure = stream_failure("generation_busy")
|
||||
failure["retry_after"] = getattr(e, "retry_after", 30)
|
||||
yield _line({"type": "error", **failure})
|
||||
except GpuJobTimeoutError:
|
||||
# The worker started and spent its full execution budget. That
|
||||
# is compute time, not queue pressure (#1588).
|
||||
logger.error("Streaming generation exceeded its compute budget")
|
||||
from core.public_errors import stream_failure
|
||||
failure = stream_failure("generation_timeout")
|
||||
failure["retry_after"] = 30
|
||||
yield _line({"type": "error", **failure})
|
||||
except ValueError:
|
||||
logger.error("Streaming generation request rejected")
|
||||
from core.public_errors import stream_failure
|
||||
@@ -1973,7 +1977,7 @@ async def generate_speech(
|
||||
_REMOTE_OP,
|
||||
local=gpu_gateway.LocalCall(
|
||||
_local_render, what="TTS generate",
|
||||
timeout=_generate_timeout_s(text),
|
||||
timeout=_generate_timeout_s(text, execution_device=_routing["effective_device"]),
|
||||
min_vram_gb=_engine_min_vram_gb,
|
||||
),
|
||||
decision=_decision,
|
||||
|
||||
@@ -160,7 +160,9 @@ _OPENAI_VOICE_ALIASES = {
|
||||
|
||||
def _resolve_engine(model_id: str):
|
||||
"""Map an OpenAI model name to a VoiceStudio backend."""
|
||||
from services.tts_backend import get_backend_class, get_active_tts_backend
|
||||
from services.tts_backend import (
|
||||
get_backend_class, get_active_tts_backend, get_engine_instance_for,
|
||||
)
|
||||
|
||||
# Accept OpenAI model names as pass-through to the active engine.
|
||||
if model_id in ("tts-1", "tts-1-hd"):
|
||||
@@ -177,8 +179,18 @@ def _resolve_engine(model_id: str):
|
||||
)
|
||||
from services.tts_backend import OmniVoiceBackend
|
||||
if cls is OmniVoiceBackend:
|
||||
# OmniVoice only ever runs as the shared active engine — the
|
||||
# explicit-omnivoice request is the active-engine request.
|
||||
return get_active_tts_backend()
|
||||
return cls()
|
||||
# Cached singleton, not a fresh cls(): SubprocessBackend engines would
|
||||
# spawn a sidecar process and reload their model on EVERY request, and
|
||||
# register a new atexit hook each time (get_engine_instance's contract).
|
||||
# No router-local cache on top of it: the shared cache is keyed by
|
||||
# CLASS precisely so id rebinds/evictions can't serve a stale instance,
|
||||
# and cross-engine memory discipline is create_speech's
|
||||
# evict_other_tts_engines call (the same seam /generate uses) — not a
|
||||
# bespoke unload here.
|
||||
return get_engine_instance_for(model_id)
|
||||
except ValueError:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
@@ -388,6 +400,15 @@ async def create_speech(req: SpeechRequest):
|
||||
# VRAM eviction runs in get_model()'s warm-return path now, covering every
|
||||
# native TTS generate (this route, WS TTS, dub, batch, audiobook).
|
||||
|
||||
# Single-active-engine memory discipline (MM2-01), the same call /generate
|
||||
# makes before its load: hand back every OTHER resident TTS engine's model
|
||||
# before this one warms up, so switching `model` ids across requests —
|
||||
# explicit id → explicit id, or explicit id → the tts-1/omnivoice aliases —
|
||||
# can't stack multi-GB engines/sidecars. No-op when nothing else is
|
||||
# resident; opt out with OMNIVOICE_SINGLE_ENGINE_RESIDENT=0.
|
||||
from services.engine_memory import evict_other_tts_engines
|
||||
await evict_other_tts_engines(backend.id)
|
||||
|
||||
# ── #1033/#1037/#1014: warm the engine under the LOAD budget before the
|
||||
# generate clock starts. The T4 verification (#1014) measured a fresh
|
||||
# install's first /v1/audio/speech burning its whole 300s generate budget
|
||||
@@ -454,7 +475,7 @@ async def create_speech(req: SpeechRequest):
|
||||
from services.model_manager import generate_timeout_s
|
||||
wav, sr = await run_on_gpu_pool_guarded(
|
||||
lambda: _run_tts(backend, text, kw), what="OpenAI TTS generate",
|
||||
timeout=generate_timeout_s(text))
|
||||
timeout=generate_timeout_s(text, engine=backend))
|
||||
except Exception as e:
|
||||
# #1172/#1173: typed failures get their real status + actionable
|
||||
# message (400 bad input / 503 broken engine binary) instead of a
|
||||
|
||||
@@ -133,6 +133,83 @@ def set_torch_compile_disabled(body: _TorchCompileBody):
|
||||
return _torch_compile_state()
|
||||
|
||||
|
||||
# ── Compute-device override (Settings → Performance) ──────────────────────
|
||||
|
||||
|
||||
class _ComputeDeviceBody(BaseModel):
|
||||
value: str = Field(..., description="auto | cuda | rocm | xpu | mps | cpu")
|
||||
|
||||
|
||||
def _compute_device_state() -> dict:
|
||||
"""Everything the Performance panel needs to render the device control:
|
||||
the resolved pick (env > prefs > auto), what this process actually applied
|
||||
at probe time (differs after a change until restart — caps are immutable
|
||||
per process), what auto would pick, and which families exist here."""
|
||||
from core import device_caps
|
||||
|
||||
caps = device_caps.detect_host_caps()
|
||||
env_pin = (os.environ.get("OMNIVOICE_DEVICE") or "").strip().lower()
|
||||
auto_family = next(
|
||||
(f for f in ("cuda", "rocm", "xpu", "mps") if f in caps.available_families),
|
||||
"cpu",
|
||||
)
|
||||
value = device_caps.requested_device_override()
|
||||
return {
|
||||
"value": value,
|
||||
"applied": caps.requested_family,
|
||||
"restart_required": value != caps.requested_family,
|
||||
# The running process asked for a family it doesn't have (env pin on
|
||||
# the wrong machine, hardware removed): auto is in effect, and a
|
||||
# restart would not change that — the panel says so instead of
|
||||
# pretending the pick took.
|
||||
"override_ignored": (
|
||||
caps.requested_family not in ("auto", caps.family)
|
||||
),
|
||||
"effective_family": caps.family,
|
||||
"auto_family": auto_family,
|
||||
"available_families": list(caps.available_families),
|
||||
"env_pinned": env_pin in device_caps.DEVICE_OVERRIDE_CHOICES and env_pin != "",
|
||||
"choices": list(device_caps.DEVICE_OVERRIDE_CHOICES),
|
||||
}
|
||||
|
||||
|
||||
@router.get("/compute-device")
|
||||
def get_compute_device():
|
||||
"""Current compute-device override state (Settings → Performance)."""
|
||||
return _compute_device_state()
|
||||
|
||||
|
||||
@router.put("/compute-device")
|
||||
def set_compute_device(body: _ComputeDeviceBody):
|
||||
"""Persist the compute-device pick. Applied by the capability probe at
|
||||
the next backend start (host caps are immutable per process — same
|
||||
restart contract as the rest of the Performance tab). ``OMNIVOICE_DEVICE``
|
||||
always wins over this pick; the UI shows the pin instead of pretending."""
|
||||
from core import device_caps, prefs
|
||||
|
||||
value = (body.value or "").strip().lower()
|
||||
if value not in device_caps.DEVICE_OVERRIDE_CHOICES:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail=f"Unknown device '{value}'. Valid: {', '.join(device_caps.DEVICE_OVERRIDE_CHOICES)}",
|
||||
)
|
||||
caps = device_caps.detect_host_caps()
|
||||
if value not in ("auto", "cpu") and value not in caps.available_families:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail=(
|
||||
f"'{value}' is not available on this host "
|
||||
f"(have: {', '.join(caps.available_families)})"
|
||||
),
|
||||
)
|
||||
try:
|
||||
prefs.set_("compute_device", value)
|
||||
except Exception:
|
||||
logger.exception("set_compute_device failed")
|
||||
raise HTTPException(status_code=500, detail="Failed to persist setting")
|
||||
return _compute_device_state()
|
||||
|
||||
|
||||
# ── Generation-history retention (Studio takes rail) ──────────────────────
|
||||
|
||||
|
||||
|
||||
@@ -62,6 +62,11 @@ def setup_status():
|
||||
_MIN_NVIDIA_DRIVER = 555
|
||||
_RAM_FAIL_GB = 8
|
||||
_RAM_WARN_GB = 12
|
||||
# Installed DIMMs never fully reach the OS: firmware, integrated graphics and
|
||||
# kernel reservations shave off up to ~7% (an "8 GB" Windows laptop reports
|
||||
# ~7.8 GB usable). Thresholds are compared with this allowance applied so the
|
||||
# machines a threshold is meant to admit aren't blocked by that gap (#1618).
|
||||
_RAM_RESERVED_ALLOWANCE = 0.93
|
||||
|
||||
|
||||
def _run_cmd(args: list[str], timeout: float = 2.0) -> tuple[int, str]:
|
||||
@@ -352,17 +357,28 @@ def preflight():
|
||||
|
||||
# ── RAM
|
||||
ram = _ram_gb()
|
||||
# Escape hatch (#1618): a preflight should inform, not brick setup —
|
||||
# OMNIVOICE_RAM_PREFLIGHT=0 downgrades the hard block to a warning for
|
||||
# users who accept the OOM risk. Same opt-out shape as
|
||||
# OMNIVOICE_ASR_VRAM_PREFLIGHT.
|
||||
ram_gate = os.environ.get(
|
||||
"OMNIVOICE_RAM_PREFLIGHT", "1"
|
||||
).strip().lower() not in ("0", "false", "no")
|
||||
if ram == 0:
|
||||
ram_status, ram_detail, ram_fix = (
|
||||
"warn", "Could not detect system RAM.",
|
||||
"Install psutil in the backend environment or ignore this warning.",
|
||||
)
|
||||
elif ram < _RAM_FAIL_GB:
|
||||
elif ram < _RAM_FAIL_GB * _RAM_RESERVED_ALLOWANCE:
|
||||
ram_status, ram_detail, ram_fix = (
|
||||
"fail", f"{ram:.1f} GB total (need ≥ {_RAM_FAIL_GB} GB)",
|
||||
"The app will OOM on first dub. Close other apps or upgrade RAM.",
|
||||
"fail" if ram_gate else "warn",
|
||||
f"{ram:.1f} GB total (need ≥ {_RAM_FAIL_GB} GB)",
|
||||
"The app will OOM on first dub. Close other apps or upgrade RAM."
|
||||
if ram_gate else
|
||||
"RAM check disabled via OMNIVOICE_RAM_PREFLIGHT=0 — dubbing may "
|
||||
"OOM on this machine.",
|
||||
)
|
||||
elif ram < _RAM_WARN_GB:
|
||||
elif ram < _RAM_WARN_GB * _RAM_RESERVED_ALLOWANCE:
|
||||
ram_status, ram_detail, ram_fix = (
|
||||
"warn", f"{ram:.1f} GB total ({_RAM_WARN_GB}+ GB recommended)",
|
||||
"Long videos may hit swap. Keep other apps closed during dubbing.",
|
||||
|
||||
@@ -10,7 +10,8 @@ as they're generated. This unlocks:
|
||||
Protocol:
|
||||
→ Client sends JSON: {"text": "...", "voice": "profile_id", ...}
|
||||
← Server sends binary audio chunks (PCM16 @ 24kHz mono) as generated
|
||||
← Server sends JSON: {"type": "done", "duration_s": 4.2, "gen_time_s": 1.1}
|
||||
← Server sends JSON: {"type": "done", "duration_s": 4.2,
|
||||
"gen_time_s": 1.1, "ttfa_ms": 180.0, "rtf": 0.262}
|
||||
← Server sends JSON: {"type": "error", "detail": "..."}
|
||||
|
||||
The chunked delivery targets <100ms time-to-first-audio (TTFA) on warm models.
|
||||
@@ -33,6 +34,10 @@ logger = logging.getLogger("omnivoice.tts_stream")
|
||||
# Smaller chunks = lower latency but more WebSocket overhead.
|
||||
CHUNK_SAMPLES = int(os.environ.get("OMNIVOICE_STREAM_CHUNK", "4800"))
|
||||
|
||||
# Module seam for deterministic latency-contract tests. Keep every timing
|
||||
# sample on the same monotonic clock.
|
||||
_perf_counter = time.perf_counter
|
||||
|
||||
|
||||
class StreamTTSRequest(BaseModel):
|
||||
"""Client request for streaming TTS."""
|
||||
@@ -85,7 +90,7 @@ async def ws_tts(websocket: WebSocket):
|
||||
})
|
||||
continue
|
||||
|
||||
t0 = time.perf_counter()
|
||||
t0 = _perf_counter()
|
||||
text = data["text"]
|
||||
|
||||
# Remote GPU: this socket stays on this machine, and says so.
|
||||
@@ -258,6 +263,11 @@ async def ws_tts(websocket: WebSocket):
|
||||
from services.model_manager import run_on_gpu_pool_guarded
|
||||
|
||||
def _generate(sentence_text):
|
||||
# Timed INSIDE the pool worker: the guarded dispatch below
|
||||
# can queue behind other jobs, and queue wait is not
|
||||
# synthesis (review on #1620) — under contention it would
|
||||
# inflate rtf without the engine slowing at all.
|
||||
_synth_t0 = _perf_counter()
|
||||
from services.audio_dsp import apply_mastering, normalize_audio
|
||||
from services.watermark import mark_synthetic
|
||||
wav = backend.generate(sentence_text, **kw)
|
||||
@@ -279,12 +289,19 @@ async def ws_tts(websocket: WebSocket):
|
||||
# watermark._iter_chunks), which is inherent to marking
|
||||
# ultra-short clips, not a coverage gap.
|
||||
wav = mark_synthetic(wav, sr_actual, context="tts_stream.sentence")
|
||||
return wav, sr_actual
|
||||
return wav, sr_actual, _perf_counter() - _synth_t0
|
||||
|
||||
import torch
|
||||
total_samples = 0
|
||||
sr = backend.sample_rate
|
||||
started = False
|
||||
first_audio_at: float | None = None
|
||||
# Synthesis time only. The wall clock below also carries socket
|
||||
# delivery and the per-chunk event-loop yields, so deriving RTF
|
||||
# from it reports "how slow was the client" as if it were engine
|
||||
# throughput — on a slow consumer that inflates RTF without the
|
||||
# engine having changed at all.
|
||||
synth_time = 0.0
|
||||
|
||||
for sentence in sentences:
|
||||
# Bounded + pool-reset on hang so a wedged generate can't
|
||||
@@ -294,11 +311,12 @@ async def ws_tts(websocket: WebSocket):
|
||||
# Length-scaled budget per sentence (#1190) — the flat 300s
|
||||
# default is gone from every dispatch.
|
||||
from services.model_manager import generate_timeout_s
|
||||
wav_tensor, sr = await run_on_gpu_pool_guarded(
|
||||
wav_tensor, sr, sentence_synth_s = await run_on_gpu_pool_guarded(
|
||||
functools.partial(_generate, sentence),
|
||||
what="TTS generate",
|
||||
timeout=generate_timeout_s(sentence),
|
||||
timeout=generate_timeout_s(sentence, engine=backend),
|
||||
)
|
||||
synth_time += sentence_synth_s
|
||||
|
||||
if not started:
|
||||
# Send metadata after the first generation so
|
||||
@@ -325,25 +343,49 @@ async def ws_tts(websocket: WebSocket):
|
||||
end = min(sent_samples + CHUNK_SAMPLES, n_samples)
|
||||
chunk = pcm_bytes[sent_samples * 2: end * 2]
|
||||
await websocket.send_bytes(chunk)
|
||||
if first_audio_at is None:
|
||||
# TTFA ends when the first audio bytes have been
|
||||
# handed to the socket. The previous log used the
|
||||
# whole-render duration and called it TTFA.
|
||||
first_audio_at = _perf_counter()
|
||||
sent_samples = end
|
||||
# Yield to event loop between chunks for responsiveness
|
||||
await asyncio.sleep(0)
|
||||
total_samples += n_samples
|
||||
|
||||
gen_time = round(time.perf_counter() - t0, 3)
|
||||
finished_at = _perf_counter()
|
||||
wall_time_raw = max(0.0, finished_at - t0)
|
||||
synth_time_raw = max(0.0, synth_time)
|
||||
gen_time = round(wall_time_raw, 3)
|
||||
duration = round(total_samples / sr, 3)
|
||||
ttfa_ms = (
|
||||
round(max(0.0, first_audio_at - t0) * 1000.0, 1)
|
||||
if first_audio_at is not None
|
||||
else None
|
||||
)
|
||||
# RTF is a render metric: synthesis seconds per audio second.
|
||||
rtf = (
|
||||
round(synth_time_raw / (total_samples / sr), 3)
|
||||
if total_samples > 0
|
||||
else None
|
||||
)
|
||||
|
||||
await websocket.send_json({
|
||||
"type": "done",
|
||||
"duration_s": duration,
|
||||
"gen_time_s": gen_time,
|
||||
"ttfa_ms": ttfa_ms,
|
||||
"rtf": rtf,
|
||||
"samples": total_samples,
|
||||
"sample_rate": sr,
|
||||
"engine": backend.id,
|
||||
})
|
||||
logger.info(
|
||||
"TTS stream: %.1fs audio in %.1fs (TTFA=%.0fms)",
|
||||
duration, gen_time, gen_time * 1000,
|
||||
"TTS stream: %.1fs audio in %.1fs (TTFA=%s, RTF=%s)",
|
||||
duration,
|
||||
gen_time,
|
||||
f"{ttfa_ms:.0f}ms" if ttfa_ms is not None else "n/a",
|
||||
f"{rtf:.3f}" if rtf is not None else "n/a",
|
||||
)
|
||||
|
||||
except Exception as e:
|
||||
|
||||
+10
-10
@@ -159,17 +159,16 @@ models:
|
||||
- repo_id: "csukuangfj/sherpa-onnx-nemo-parakeet-tdt-0.6b-v3-int8"
|
||||
label: "Parakeet TDT v3 (sherpa-onnx — dictation, 25 EU langs)"
|
||||
role: ASR
|
||||
size_gb: 0.18
|
||||
size_gb: 0.67
|
||||
engine: sherpa-onnx
|
||||
dictation_id: sherpa-parakeet-tdt-v3
|
||||
tag: offline
|
||||
curated_on: [all]
|
||||
note: "Recommended live-dictation default. CPU, int8 ONNX. Requires sherpa-onnx."
|
||||
note: "Multilingual European-language dictation. CPU, int8 ONNX. Requires sherpa-onnx."
|
||||
|
||||
- repo_id: "csukuangfj/sherpa-onnx-nemo-parakeet-tdt-0.6b-v2-int8"
|
||||
label: "Parakeet TDT v2 (sherpa-onnx — dictation, English)"
|
||||
role: ASR
|
||||
size_gb: 0.17
|
||||
size_gb: 0.66
|
||||
engine: sherpa-onnx
|
||||
dictation_id: sherpa-parakeet-tdt-v2
|
||||
tag: offline
|
||||
@@ -178,7 +177,7 @@ models:
|
||||
- repo_id: "csukuangfj/sherpa-onnx-streaming-zipformer-bilingual-zh-en-2023-02-20"
|
||||
label: "Zipformer Bilingual (sherpa-onnx — streaming, zh+en)"
|
||||
role: ASR
|
||||
size_gb: 0.13
|
||||
size_gb: 0.2
|
||||
engine: sherpa-onnx
|
||||
dictation_id: sherpa-zipformer-bilingual-zh-en
|
||||
tag: streaming
|
||||
@@ -187,7 +186,7 @@ models:
|
||||
- repo_id: "csukuangfj/sherpa-onnx-streaming-paraformer-bilingual-zh-en"
|
||||
label: "Paraformer Bilingual (sherpa-onnx — streaming, zh+en)"
|
||||
role: ASR
|
||||
size_gb: 0.115
|
||||
size_gb: 0.24
|
||||
engine: sherpa-onnx
|
||||
dictation_id: sherpa-paraformer-bilingual-zh-en
|
||||
tag: streaming
|
||||
@@ -196,7 +195,7 @@ models:
|
||||
- repo_id: "csukuangfj/sherpa-onnx-streaming-zipformer-en-20M-2023-02-17"
|
||||
label: "Zipformer Streaming EN 20M (sherpa-onnx — streaming, English)"
|
||||
role: ASR
|
||||
size_gb: 0.128
|
||||
size_gb: 0.044
|
||||
engine: sherpa-onnx
|
||||
dictation_id: sherpa-zipformer-en-20m
|
||||
tag: streaming
|
||||
@@ -205,7 +204,7 @@ models:
|
||||
- repo_id: "csukuangfj/sherpa-onnx-streaming-zipformer-zh-14M-2023-02-23"
|
||||
label: "Zipformer Streaming ZH 14M (sherpa-onnx — streaming, Chinese)"
|
||||
role: ASR
|
||||
size_gb: 0.074
|
||||
size_gb: 0.025
|
||||
engine: sherpa-onnx
|
||||
dictation_id: sherpa-zipformer-zh-14m
|
||||
tag: streaming
|
||||
@@ -214,11 +213,12 @@ models:
|
||||
- repo_id: "csukuangfj/sherpa-onnx-whisper-tiny"
|
||||
label: "Whisper Tiny (sherpa-onnx — dictation, 90+ langs)"
|
||||
role: ASR
|
||||
size_gb: 0.116
|
||||
size_gb: 0.104
|
||||
engine: sherpa-onnx
|
||||
dictation_id: sherpa-whisper-tiny
|
||||
tag: offline
|
||||
note: "Multilingual offline dictation (auto-detect). CPU, int8 ONNX. Requires sherpa-onnx."
|
||||
curated_on: [all]
|
||||
note: "Recommended cross-platform dictation default (auto-detect). CPU, int8 ONNX. Requires sherpa-onnx."
|
||||
|
||||
# ── Diarisation ───────────────────────────────────────────────────────
|
||||
|
||||
|
||||
@@ -374,6 +374,33 @@ class HostCaps:
|
||||
probe_ok: bool = True
|
||||
"""``False`` only when torch could not be imported (degraded CPU-only)."""
|
||||
|
||||
requested_family: str = "auto"
|
||||
"""The user's compute-device override as requested — ``"auto"`` when none.
|
||||
``family`` reflects what was actually honored: an override that names a
|
||||
family this host doesn't have is noted and ignored, never obeyed blindly."""
|
||||
|
||||
|
||||
#: Every value the compute-device override accepts. "auto" = today's
|
||||
#: priority pick; "cpu" is always honorable (invariant: cpu is always
|
||||
#: available); accelerator names are honored only when detected.
|
||||
DEVICE_OVERRIDE_CHOICES: tuple[str, ...] = ("auto", "cuda", "rocm", "xpu", "mps", "cpu")
|
||||
|
||||
|
||||
def requested_device_override() -> str:
|
||||
"""The user's compute-device pick: ``OMNIVOICE_DEVICE`` env > the Settings
|
||||
choice (``compute_device`` in prefs.json) > ``"auto"``. Env wins so
|
||||
power-users can pin a device without the UI silently undoing it (same
|
||||
resolution order as engine selection, #981). Unknown values normalize to
|
||||
``"auto"`` — the probe must never raise."""
|
||||
try:
|
||||
from core import prefs
|
||||
|
||||
raw = prefs.resolve("compute_device", env="OMNIVOICE_DEVICE", default="auto")
|
||||
except Exception:
|
||||
raw = os.environ.get("OMNIVOICE_DEVICE", "auto")
|
||||
val = str(raw or "auto").strip().lower()
|
||||
return val if val in DEVICE_OVERRIDE_CHOICES else "auto"
|
||||
|
||||
|
||||
def _probe() -> HostCaps:
|
||||
"""Run the probe once. Enumerates every failure branch from the spec's
|
||||
@@ -386,6 +413,7 @@ def _probe() -> HostCaps:
|
||||
available_families=("cpu",),
|
||||
notes=("torch not importable; treating host as CPU-only",),
|
||||
probe_ok=False,
|
||||
requested_family=requested_device_override(),
|
||||
)
|
||||
|
||||
notes: list[str] = []
|
||||
@@ -507,6 +535,26 @@ def _probe() -> HostCaps:
|
||||
# available_families: every detected accelerator + cpu, deduped, cpu last.
|
||||
available: tuple[DeviceFamily, ...] = tuple(dict.fromkeys([*detected, "cpu"]))
|
||||
|
||||
# User override (Settings → Performance, or OMNIVOICE_DEVICE): honored
|
||||
# only when the named family actually exists on this host — an override
|
||||
# can steer, it cannot invent hardware. Applied here, at the single
|
||||
# choke point, so routing, model loads (get_best_device delegates its
|
||||
# family decision here), and every badge inherit it for free.
|
||||
requested = requested_device_override()
|
||||
if requested != "auto":
|
||||
if requested in available:
|
||||
if requested != family:
|
||||
notes.append(
|
||||
f"compute device pinned to '{requested}' by user override "
|
||||
f"(auto would pick '{family}')"
|
||||
)
|
||||
family = requested # type: ignore[assignment]
|
||||
else:
|
||||
notes.append(
|
||||
f"requested compute device '{requested}' is not available on "
|
||||
f"this host (have: {', '.join(available)}) — using '{family}'"
|
||||
)
|
||||
|
||||
return HostCaps(
|
||||
family=family,
|
||||
available_families=available,
|
||||
@@ -515,6 +563,7 @@ def _probe() -> HostCaps:
|
||||
driver=driver,
|
||||
notes=tuple(notes),
|
||||
probe_ok=True,
|
||||
requested_family=requested,
|
||||
)
|
||||
|
||||
|
||||
|
||||
@@ -23,9 +23,17 @@ logger = logging.getLogger("omnivoice.events")
|
||||
_listeners: list[asyncio.Queue] = []
|
||||
_lock = asyncio.Lock()
|
||||
|
||||
# The loop that serves /ws/events, captured on first use. Sync FastAPI
|
||||
# endpoints (rename/delete profile, revoke consent) run in threadpool workers
|
||||
# where `asyncio.get_running_loop()` raises, which used to silently drop their
|
||||
# events — the UI then never refetched the voice list (#1158 class).
|
||||
_serving_loop: asyncio.AbstractEventLoop | None = None
|
||||
|
||||
|
||||
async def subscribe() -> asyncio.Queue:
|
||||
"""Register a new listener. Returns a Queue that receives event dicts."""
|
||||
global _serving_loop
|
||||
_serving_loop = asyncio.get_running_loop()
|
||||
q: asyncio.Queue = asyncio.Queue(maxsize=64)
|
||||
async with _lock:
|
||||
_listeners.append(q)
|
||||
@@ -57,11 +65,29 @@ def emit(kind: str, payload: dict[str, Any] | None = None) -> None:
|
||||
}
|
||||
event_str = json.dumps(event)
|
||||
try:
|
||||
loop = asyncio.get_running_loop()
|
||||
loop.create_task(_broadcast(event_str))
|
||||
caller_loop = asyncio.get_running_loop()
|
||||
except RuntimeError:
|
||||
# No event loop running (unlikely in FastAPI context but safe)
|
||||
caller_loop = None
|
||||
target_loop = _serving_loop or caller_loop
|
||||
if target_loop is None:
|
||||
# No serving loop yet — nobody to notify; dropping is correct.
|
||||
logger.debug("No event loop — event dropped: %s", kind)
|
||||
return
|
||||
try:
|
||||
if caller_loop is target_loop:
|
||||
target_loop.create_task(_broadcast(event_str))
|
||||
else:
|
||||
# Sync endpoints and async producers on a foreign loop must both
|
||||
# hand off: the lock and listener queues belong to serving_loop.
|
||||
target_loop.call_soon_threadsafe(_schedule_broadcast, event_str)
|
||||
except RuntimeError:
|
||||
# The serving loop closed between capture and use (app shutdown).
|
||||
logger.debug("Event loop closed — event dropped: %s", kind)
|
||||
|
||||
|
||||
def _schedule_broadcast(event_str: str) -> None:
|
||||
"""Run `_broadcast` on the serving loop; called via call_soon_threadsafe."""
|
||||
asyncio.get_running_loop().create_task(_broadcast(event_str))
|
||||
|
||||
|
||||
async def _broadcast(event_str: str) -> None:
|
||||
@@ -73,11 +99,11 @@ async def _broadcast(event_str: str) -> None:
|
||||
q.put_nowait(event_str)
|
||||
except asyncio.QueueFull:
|
||||
# Slow consumer — drop oldest, then push. Not a race (#1163):
|
||||
# every queue op runs on the single event loop, and there is
|
||||
# no await between the QueueFull and this get_nowait/put_nowait
|
||||
# pair — no consumer can interleave, so get_nowait cannot raise
|
||||
# QueueEmpty here. emit() from a foreign thread drops the event
|
||||
# before ever touching a queue (see the RuntimeError branch).
|
||||
# every queue op runs on the single event loop (a foreign
|
||||
# thread's emit() hands off via call_soon_threadsafe first),
|
||||
# and there is no await between the QueueFull and this
|
||||
# get_nowait/put_nowait pair — no consumer can interleave, so
|
||||
# get_nowait cannot raise QueueEmpty here.
|
||||
try:
|
||||
q.get_nowait()
|
||||
q.put_nowait(event_str)
|
||||
|
||||
@@ -17,6 +17,13 @@ _WINDOWS_RESERVED_NAMES = frozenset({"CON", "PRN", "AUX", "NUL"}) | frozenset(
|
||||
f"{prefix}{number}" for prefix in ("COM", "LPT") for number in range(1, 10)
|
||||
)
|
||||
|
||||
# Both separator families, so a stored sub-path splits into the same components
|
||||
# on every host. Windows accepts ``/`` as a real separator, so splitting on
|
||||
# ``os.sep`` alone left ``"job/out.mp4"`` as a single component there while the
|
||||
# identical value split cleanly on POSIX. POSIX input never reaches this with a
|
||||
# backslash — it is rejected as a foreign separator before the split.
|
||||
_PATH_SEPARATORS = re.compile(r"[\\/]")
|
||||
|
||||
|
||||
class UnsafePath(ValueError):
|
||||
"""Raised when a path crosses its allowed filesystem boundary."""
|
||||
@@ -52,11 +59,10 @@ def resolve_within(root: os.PathLike[str] | str, value: os.PathLike[str] | str)
|
||||
raw = os.fspath(value) if value is not None else ""
|
||||
if not isinstance(raw, str) or not raw:
|
||||
raise UnsafePath("path is empty")
|
||||
# Treat both separator families as structural on every host. Otherwise a
|
||||
# Windows traversal string is an innocent-looking filename when validated
|
||||
# on Linux (and can become dangerous after persisted data is moved).
|
||||
if os.sep != "\\" and ("\\" in raw or bool(ntpath.splitdrive(raw)[0])):
|
||||
raise UnsafePath("path uses a foreign separator or drive")
|
||||
# Treat both separator families as structural on every host while still
|
||||
# rejecting Windows drive paths before rebuilding relative components.
|
||||
if os.sep != "\\" and bool(ntpath.splitdrive(raw)[0]):
|
||||
raise UnsafePath("path uses a drive")
|
||||
root_path = Path(root).expanduser().resolve(strict=False)
|
||||
root_text = str(root_path)
|
||||
if os.path.isabs(raw):
|
||||
@@ -69,7 +75,7 @@ def resolve_within(root: os.PathLike[str] | str, value: os.PathLike[str] | str)
|
||||
# containment proof explicit to static analysis, this rejects empty,
|
||||
# dot, parent, drive, and separator-bearing components before Path sees
|
||||
# any persisted/request-derived string.
|
||||
parts = raw.split(os.sep)
|
||||
parts = _PATH_SEPARATORS.split(raw)
|
||||
clean_parts: list[str] = []
|
||||
for part in parts:
|
||||
clean = os.path.basename(part)
|
||||
|
||||
@@ -28,6 +28,15 @@ def stream_failure(code: str) -> dict[str, object]:
|
||||
"detail": "Generation capacity is busy. Try again shortly.",
|
||||
"retryable": True,
|
||||
},
|
||||
"generation_timeout": {
|
||||
"code": "generation_timeout",
|
||||
"detail": (
|
||||
"Generation exceeded the compute-time limit. The backend is "
|
||||
"still running; try a shorter passage or raise the generation "
|
||||
"timeout."
|
||||
),
|
||||
"retryable": True,
|
||||
},
|
||||
"invalid_request": {
|
||||
"code": "invalid_request",
|
||||
"detail": "The generation request could not be processed.",
|
||||
|
||||
@@ -0,0 +1,125 @@
|
||||
"""Startup progress ledger — what the backend is doing before it can serve.
|
||||
|
||||
Why this exists: the project's #1 lifetime failure class is "can't reach the
|
||||
local backend", and a large slice of it was never a dead backend at all —
|
||||
just one that couldn't say "I'm starting, currently loading PyTorch" because
|
||||
nothing listened until every heavy import and migration finished. main.py now
|
||||
binds the socket early and defers the heavy work; this module is the shared
|
||||
state the early `/health` + `/startup/progress` endpoints report from while
|
||||
that work runs.
|
||||
|
||||
Thread-safety: the deferred init runs Phase A in an executor thread while the
|
||||
event loop serves probes, so every mutation and snapshot takes the lock.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import threading
|
||||
import time
|
||||
|
||||
# Execution order matters only for display; the ledger records whatever order
|
||||
# steps actually begin in. Keep ids stable — the desktop shell field-sniffs
|
||||
# them and tests pin them.
|
||||
STEPS: "dict[str, str]" = {
|
||||
"env_prefs": "Restoring settings…",
|
||||
"native_preload": "Preparing GPU libraries…",
|
||||
"ml_imports": "Loading ML runtime (PyTorch)…",
|
||||
"api_routes": "Loading API routes…",
|
||||
"db_migrate": "Preparing database…",
|
||||
"services_start": "Starting background services…",
|
||||
}
|
||||
|
||||
_lock = threading.Lock()
|
||||
_t0 = time.monotonic()
|
||||
_current: "str | None" = None
|
||||
_done: "list[tuple[str, float]]" = [] # (step_id, seconds it took)
|
||||
_started_at: float = 0.0
|
||||
_ready = False
|
||||
_error: "dict | None" = None
|
||||
|
||||
|
||||
def begin_step(step_id: str) -> None:
|
||||
global _current, _started_at
|
||||
with _lock:
|
||||
_finish_current_locked()
|
||||
_current = step_id
|
||||
_started_at = time.monotonic()
|
||||
|
||||
|
||||
def _finish_current_locked() -> None:
|
||||
global _current
|
||||
if _current is not None:
|
||||
_done.append((_current, round(time.monotonic() - _started_at, 2)))
|
||||
_current = None
|
||||
|
||||
|
||||
def mark_ready() -> None:
|
||||
global _ready
|
||||
with _lock:
|
||||
_finish_current_locked()
|
||||
_ready = True
|
||||
|
||||
|
||||
def fail(message: str) -> None:
|
||||
"""Record a startup failure against the step that was running."""
|
||||
global _error
|
||||
with _lock:
|
||||
_error = {"step": _current, "message": str(message)[:500]}
|
||||
|
||||
|
||||
def is_ready() -> bool:
|
||||
with _lock:
|
||||
return _ready
|
||||
|
||||
|
||||
def current_step() -> "tuple[str | None, str | None]":
|
||||
"""(step_id, human label) of the active step, or (None, None)."""
|
||||
with _lock:
|
||||
if _current is None:
|
||||
return None, None
|
||||
return _current, STEPS.get(_current, _current)
|
||||
|
||||
|
||||
def snapshot() -> dict:
|
||||
"""The `/startup/progress` body. Always safe to call, never raises."""
|
||||
with _lock:
|
||||
if _error is not None:
|
||||
status = "failed"
|
||||
elif _ready:
|
||||
status = "ready"
|
||||
else:
|
||||
status = "starting"
|
||||
states = {sid: "pending" for sid in STEPS}
|
||||
for sid, _t in _done:
|
||||
states[sid] = "done"
|
||||
if _current is not None:
|
||||
states[_current] = "active"
|
||||
if _error is not None and _error.get("step"):
|
||||
states[_error["step"]] = "failed"
|
||||
durations = dict(_done)
|
||||
return {
|
||||
"status": status,
|
||||
"step": _current,
|
||||
"label": STEPS.get(_current, _current) if _current else None,
|
||||
"steps": [
|
||||
{
|
||||
"id": sid,
|
||||
"label": label,
|
||||
"state": states.get(sid, "pending"),
|
||||
**({"t": durations[sid]} if sid in durations else {}),
|
||||
}
|
||||
for sid, label in STEPS.items()
|
||||
],
|
||||
"elapsed_s": round(time.monotonic() - _t0, 2),
|
||||
"error": _error,
|
||||
}
|
||||
|
||||
|
||||
def _reset_for_tests() -> None:
|
||||
global _current, _ready, _error, _started_at
|
||||
with _lock:
|
||||
_current = None
|
||||
_done.clear()
|
||||
_ready = False
|
||||
_error = None
|
||||
_started_at = 0.0
|
||||
@@ -85,11 +85,27 @@ def _get_model():
|
||||
global _model
|
||||
if _model is None:
|
||||
from faster_whisper import WhisperModel
|
||||
name = os.environ.get("ASR_MODEL_FW", "large-v3")
|
||||
# Same weights as in-process faster-whisper: ASR_MODEL_FASTER selects
|
||||
# for BOTH variants, ASR_MODEL_FW stays as a sidecar-only override.
|
||||
# Before this, the sidecar read only ASR_MODEL_FW while the download
|
||||
# preflight read ASR_MODEL_FASTER — set one and the other variant (or
|
||||
# the preflight) quietly used a different model.
|
||||
name = (
|
||||
os.environ.get("ASR_MODEL_FW")
|
||||
or os.environ.get("ASR_MODEL_FASTER")
|
||||
or "large-v3"
|
||||
)
|
||||
try:
|
||||
import torch
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
# The probe honors the user compute-device override and the
|
||||
# ROCm/CT2 incompatibility (#1529) — the child must agree with
|
||||
# the parent's device decision, not re-derive its own.
|
||||
from core.device_caps import detect_host_caps
|
||||
device = "cuda" if detect_host_caps().family == "cuda" else "cpu"
|
||||
except Exception:
|
||||
# Fail SAFE: guessing "cuda" from torch here would bypass a cpu
|
||||
# override and hand CTranslate2 HIP-flavoured cuda on ROCm
|
||||
# (#1529). CPU always works; say why in the sidecar log.
|
||||
print("asr-sidecar: device probe failed — using cpu", file=sys.stderr, flush=True)
|
||||
device = "cpu"
|
||||
# Degrade fp16 → int8 rather than crash on GPUs without efficient fp16
|
||||
# (older Maxwell/Pascal, GTX 16xx, CTranslate2/cuDNN mismatch) (#551).
|
||||
|
||||
@@ -28,6 +28,7 @@ packages. The parent only ever spawns it as a subprocess.
|
||||
from __future__ import annotations
|
||||
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import re
|
||||
from typing import TYPE_CHECKING
|
||||
@@ -164,6 +165,23 @@ class IndexTTS2Backend(SubprocessBackend):
|
||||
from engines.indextts.bootstrap import resolve_indextts_venv
|
||||
return resolve_indextts_venv()
|
||||
|
||||
@property
|
||||
def recv_timeout_s(self) -> float:
|
||||
# IndexTTS was the only sidecar left on the 60s class default while
|
||||
# pockettts and omnivoice-subprocess both raised theirs. infer() is one
|
||||
# blocking upstream call, so a long passage legitimately outruns 60s and
|
||||
# the parent's watchdog killed a healthy synthesis (#1611). main.py also
|
||||
# heartbeats during infer(), which is what actually proves liveness —
|
||||
# this deadline is the ceiling for a sidecar that has gone genuinely
|
||||
# silent. OMNIVOICE_INDEXTTS_RECV_TIMEOUT_S tunes it.
|
||||
try:
|
||||
v = float(os.environ.get("OMNIVOICE_INDEXTTS_RECV_TIMEOUT_S", "900"))
|
||||
except (ValueError, TypeError):
|
||||
return 900.0
|
||||
if not math.isfinite(v): # reject inf/nan so the deadline can't be disabled
|
||||
return 900.0
|
||||
return max(30.0, v)
|
||||
|
||||
@classmethod
|
||||
def sidecar_script(cls):
|
||||
from engines.indextts.bootstrap import INDEXTTS_SIDECAR_SCRIPT
|
||||
|
||||
@@ -63,11 +63,13 @@ Restrictions:
|
||||
from __future__ import annotations
|
||||
|
||||
import base64
|
||||
import contextlib
|
||||
import json
|
||||
import os
|
||||
import struct
|
||||
import sys
|
||||
import tempfile
|
||||
import threading
|
||||
import traceback
|
||||
|
||||
|
||||
@@ -117,11 +119,59 @@ EMOTION_KWARGS_ALLOWLIST = frozenset({
|
||||
# ── wire protocol ─────────────────────────────────────────────────────────
|
||||
|
||||
|
||||
#: Seconds between keep-alive progress frames during a long blocking call.
|
||||
_HEARTBEAT_S = 5.0
|
||||
|
||||
#: Serializes _send across threads (the heartbeat below + the main loop) so
|
||||
#: concurrent length+body writes can't interleave and corrupt the framing.
|
||||
_send_lock = threading.Lock()
|
||||
|
||||
|
||||
def _send(stream, obj: dict) -> None:
|
||||
body = json.dumps(obj, separators=(",", ":")).encode("utf-8")
|
||||
stream.write(struct.pack("!I", len(body)))
|
||||
stream.write(body)
|
||||
stream.flush()
|
||||
with _send_lock:
|
||||
stream.write(struct.pack("!I", len(body)))
|
||||
stream.write(body)
|
||||
stream.flush()
|
||||
|
||||
|
||||
@contextlib.contextmanager
|
||||
def _heartbeat(stdout, stage: str):
|
||||
"""Emit a progress frame every ~5s for the duration of the block.
|
||||
|
||||
IndexTTS spends the whole of a cold load and the whole of ``infer()``
|
||||
inside one blocking upstream call, saying nothing on the wire. The parent
|
||||
reads that silence two ways, and BOTH kill a perfectly healthy synthesis
|
||||
of a long passage (#1611):
|
||||
|
||||
* ``SubprocessBackend.generate`` re-arms its recv watchdog on every
|
||||
frame, so with no frames it hard-kills the sidecar at recv_timeout_s;
|
||||
* each frame also reports activity to the GPU pool's execution clock
|
||||
(#1367), so with no frames the outer generate budget expires and
|
||||
blames the hardware.
|
||||
|
||||
Raising the deadline alone therefore does not fix long-text generation —
|
||||
the sidecar has to prove it is alive. Percent climbs 1..99 because the
|
||||
upstream call exposes no real progress; it is a liveness signal, not a
|
||||
measurement.
|
||||
"""
|
||||
stop = threading.Event()
|
||||
|
||||
def _beat() -> None:
|
||||
pct = 1
|
||||
while not stop.wait(_HEARTBEAT_S):
|
||||
pct = min(pct + 1, 99)
|
||||
try:
|
||||
_send(stdout, {"op": "progress", "stage": stage, "percent": pct})
|
||||
except Exception:
|
||||
return # pipe gone — the main loop will surface it
|
||||
hb = threading.Thread(target=_beat, name=f"indextts-{stage}-heartbeat", daemon=True)
|
||||
hb.start()
|
||||
try:
|
||||
yield
|
||||
finally:
|
||||
stop.set()
|
||||
hb.join(timeout=_HEARTBEAT_S + 1)
|
||||
|
||||
|
||||
def _recv(stream):
|
||||
@@ -160,14 +210,40 @@ def _torch_bf16_supported() -> bool:
|
||||
return False
|
||||
|
||||
|
||||
#: Model-config filenames to look for, most-preferred first, per version.
|
||||
#: IndexTeam/IndexTTS-2.5 ships ``config.yaml``; VoiceStudio used to demand
|
||||
#: ``config_v2_5.yaml``, a name that exists in no upstream revision, so the
|
||||
#: install failed until the user hand-renamed the file (#1611). Both names are
|
||||
#: accepted now — the hand-renamed installs must keep working untouched — and
|
||||
#: the renamed one wins, because a user who created it did so deliberately.
|
||||
_CFG_NAMES = {
|
||||
"2.5": ("config_v2_5.yaml", "config.yaml"),
|
||||
"2": ("config.yaml",),
|
||||
}
|
||||
|
||||
|
||||
def _resolve_cfg_path(model_dir: str, *, version: str) -> str:
|
||||
"""First accepted config that exists in ``model_dir``.
|
||||
|
||||
Falls back to the last candidate when none exist, so the failure surfaces
|
||||
as upstream's own "no such file" naming a real expected path rather than
|
||||
a name no upstream release has ever shipped.
|
||||
"""
|
||||
names = _CFG_NAMES.get(version, _CFG_NAMES["2"])
|
||||
for name in names:
|
||||
candidate = os.path.join(model_dir, name)
|
||||
if os.path.isfile(candidate):
|
||||
return candidate
|
||||
return os.path.join(model_dir, names[-1])
|
||||
|
||||
|
||||
def _model_init_kwargs(
|
||||
repo_dir: str, *, version: str, reduced_precision: bool,
|
||||
) -> dict:
|
||||
"""Build version-specific constructor arguments for IndexTTS 2.5 or 2."""
|
||||
model_dir = os.path.join(repo_dir, "checkpoints")
|
||||
cfg_name = "config_v2_5.yaml" if version == "2.5" else "config.yaml"
|
||||
kwargs = {
|
||||
"cfg_path": os.path.join(model_dir, cfg_name),
|
||||
"cfg_path": _resolve_cfg_path(model_dir, version=version),
|
||||
"model_dir": model_dir,
|
||||
"use_cuda_kernel": False,
|
||||
"use_deepspeed": False,
|
||||
@@ -216,7 +292,8 @@ def _load_model(stdout) -> object:
|
||||
model_kw = _model_init_kwargs(
|
||||
repo_dir, version=_model_version, reduced_precision=reduced_precision,
|
||||
)
|
||||
_model = IndexTTS2(**model_kw)
|
||||
with _heartbeat(stdout, "loading_model"):
|
||||
_model = IndexTTS2(**model_kw)
|
||||
|
||||
_send(stdout, {"op": "progress", "stage": "loading_model", "percent": 100})
|
||||
return _model
|
||||
@@ -276,7 +353,10 @@ def _handle_synthesize(msg: dict, stdout) -> None:
|
||||
tmp_path = tmp.name
|
||||
try:
|
||||
infer_kw["output_path"] = tmp_path
|
||||
model.infer(**infer_kw)
|
||||
# A long passage keeps infer() busy for minutes with nothing on the
|
||||
# wire; without this the parent kills the sidecar mid-synthesis (#1611).
|
||||
with _heartbeat(stdout, "synthesizing"):
|
||||
model.infer(**infer_kw)
|
||||
pcm_b64, sr, n_samples = _wav_to_pcm_b64(tmp_path)
|
||||
finally:
|
||||
try:
|
||||
|
||||
@@ -353,6 +353,9 @@ def _make_backend_class():
|
||||
display_name = "OmniVoice (GGUF, hardware-adaptive)"
|
||||
gpu_compat = ("cuda", "mps", "cpu")
|
||||
supports_voice_design = False
|
||||
# Every generate() spawns the external binary — allocations live in
|
||||
# that process, invisible to parent-side accelerator counters.
|
||||
runs_out_of_process = True
|
||||
|
||||
# 24 kHz mono Higgs Audio v2 — same as the in-process OmniVoice.
|
||||
_SAMPLE_RATE = 24_000
|
||||
|
||||
@@ -151,6 +151,40 @@ def _pocket_language(raw) -> str:
|
||||
)
|
||||
|
||||
|
||||
_TRUTHY = {"1", "true", "yes", "on"}
|
||||
|
||||
|
||||
def _has_24l_config(language: str) -> bool:
|
||||
"""Whether the installed pocket-tts ships a 24-layer checkpoint for
|
||||
``language`` (it/de/es/pt/fr in 2.1.0; english has none)."""
|
||||
try:
|
||||
from pocket_tts.models.tts_model import CONFIGS_DIR # type: ignore[import-not-found] # noqa: PLC0415
|
||||
except Exception as exc: # noqa: BLE001 — absence of the package is not fatal here
|
||||
# Log it, though: if a future pocket-tts moves CONFIGS_DIR, the 24L
|
||||
# opt-in would otherwise go silently inert.
|
||||
print(f"pockettts sidecar: 24l config probe failed: {exc!r}", file=sys.stderr)
|
||||
return False
|
||||
from pathlib import Path # noqa: PLC0415
|
||||
|
||||
return (Path(CONFIGS_DIR) / f"{language}_24l.yaml").is_file()
|
||||
|
||||
|
||||
def _model_config_name(language: str) -> str:
|
||||
"""Pocket-tts config name to load: the 6-layer default, or the 24-layer
|
||||
checkpoint when OMNIVOICE_POCKETTTS_24L is set and one exists for the
|
||||
language. Opt-in only — defaults keep the fast model; the 24-layer variant
|
||||
trades roughly 4x transformer compute for better prosody.
|
||||
|
||||
French is the exception: pocket-tts 2.1.0 only ships a 24-layer French
|
||||
model and load_model(language="french") raises, so French always maps to
|
||||
french_24l regardless of the env var."""
|
||||
if language == "french":
|
||||
return "french_24l"
|
||||
if os.environ.get("OMNIVOICE_POCKETTTS_24L", "").strip().lower() not in _TRUTHY:
|
||||
return language
|
||||
return f"{language}_24l" if _has_24l_config(language) else language
|
||||
|
||||
|
||||
def _load_model(stdout, language: str):
|
||||
"""Cold-construct the PocketTTS model for ``language`` (cached per language).
|
||||
Emits progress frames for the parent watchdog. Raises on failure (e.g.
|
||||
@@ -178,7 +212,7 @@ def _load_model(stdout, language: str):
|
||||
try:
|
||||
from pocket_tts import TTSModel # type: ignore[import-not-found] # noqa: PLC0415
|
||||
|
||||
model = TTSModel.load_model(language=language)
|
||||
model = TTSModel.load_model(language=_model_config_name(language))
|
||||
_MODELS[language] = model
|
||||
finally:
|
||||
stop.set()
|
||||
|
||||
+711
-417
File diff suppressed because it is too large
Load Diff
+116
-26
@@ -2325,7 +2325,7 @@ _INSTALL_HINTS: dict[str, str] = {
|
||||
"mac-ARM source installs since 0.3.22. Parakeet TDT v3 on the GPU via "
|
||||
"MLX: 25 European languages, word timestamps, ~2 GB unified memory.)"
|
||||
),
|
||||
"moonshine": "pip install useful-moonshine (edge/CPU-optimized ASR)",
|
||||
"moonshine": "uv pip install moonshine-onnx (or moonshine-voice; edge/CPU-optimized ASR)",
|
||||
"funasr": "pip install funasr (SenseVoiceSmall + FSMN-VAD; CUDA or CPU)",
|
||||
"sherpa-onnx-asr": "uv add sherpa-onnx (ONNX live dictation; CPU, cross-platform)",
|
||||
"openai-compat-asr": (
|
||||
@@ -2495,7 +2495,23 @@ def _ctranslate2_cuda_ok() -> bool:
|
||||
CUDA runtime version" — the #1529 report, an AMD RX 7900 XTX in the
|
||||
:rocm Docker image. Real CUDA only; ROCm hosts take the CPU path here
|
||||
(auto-detect prefers pytorch-whisper there, which does use HIP).
|
||||
|
||||
Also honors the user compute-device override (Settings → Performance /
|
||||
``OMNIVOICE_DEVICE``): a host pinned to cpu (or any non-cuda family)
|
||||
must not hand CTranslate2 a CUDA device — the probe applies the
|
||||
override, so gating on its family covers every CT2 loader at once.
|
||||
"""
|
||||
try:
|
||||
from core.device_caps import detect_host_caps
|
||||
|
||||
if detect_host_caps().family != "cuda":
|
||||
return False
|
||||
except Exception: # noqa: BLE001 — fail SAFE, not fast
|
||||
# Without a working probe we can't know whether an override or a
|
||||
# ROCm build is in play — guessing "cuda" from torch here is exactly
|
||||
# the #1529 crash. CPU always works.
|
||||
logger.warning("device probe failed — CTranslate2 taking the CPU path", exc_info=True)
|
||||
return False
|
||||
return _cuda_reported_available() and not _rocm_torch()
|
||||
|
||||
|
||||
@@ -2548,7 +2564,10 @@ def _auto_detect() -> str:
|
||||
def active_backend_id() -> str:
|
||||
explicit = os.environ.get("OMNIVOICE_ASR_BACKEND")
|
||||
if explicit:
|
||||
return explicit
|
||||
# #1582's public spelling predates the registry name. Keep it as a
|
||||
# compatibility alias for the PyTorch-native Whisper implementation
|
||||
# that can use ROCm/HIP; every ASR consumer resolves through here.
|
||||
return "pytorch-whisper" if explicit == "omnivoice" else explicit
|
||||
from core import prefs
|
||||
picked = prefs.get("asr_backend")
|
||||
if picked:
|
||||
@@ -2976,7 +2995,7 @@ def _capture_prefers_parakeet() -> bool:
|
||||
return _parakeet_mlx_installed()
|
||||
|
||||
|
||||
def get_capture_asr_backend() -> ASRBackend:
|
||||
def get_capture_asr_backend(*, skip_sherpa: bool = False) -> ASRBackend:
|
||||
"""Pick the fastest ASR engine for capture / dictation.
|
||||
|
||||
Selection order:
|
||||
@@ -3001,6 +3020,9 @@ def get_capture_asr_backend() -> ASRBackend:
|
||||
|
||||
Returns a cached singleton so the model stays warm between calls; the
|
||||
singleton is rebuilt if the selected sherpa model changes.
|
||||
|
||||
``skip_sherpa`` is used only to validate a token-silent Sherpa result with
|
||||
the installed capture fallback before persisting model demotion.
|
||||
"""
|
||||
global _capture_backend, _capture_backend_key
|
||||
|
||||
@@ -3009,7 +3031,7 @@ def get_capture_asr_backend() -> ASRBackend:
|
||||
# call get_sherpa_dictation_backend concurrently) can't both build a model.
|
||||
with _capture_backend_lock:
|
||||
# 0. Honor an explicit sherpa dictation model selection.
|
||||
sherpa_id = dictation_model_id()
|
||||
sherpa_id = None if skip_sherpa else dictation_model_id()
|
||||
if sherpa_id:
|
||||
ok, _ = SherpaDictationBackend.is_available()
|
||||
if ok:
|
||||
@@ -3120,10 +3142,18 @@ def _offline_asr_repo(backend_id: str | None = None) -> str | None:
|
||||
bid = backend_id or active_backend_id()
|
||||
if bid == "whisperx":
|
||||
return _fw_repo(os.environ.get("ASR_MODEL_WHISPERX", "large-v3"))
|
||||
if bid in ("faster-whisper", "faster-whisper-isolated"):
|
||||
# The crash-isolated sidecar loads the SAME CT2 weights as in-process
|
||||
# faster-whisper (it reuses the ASR_MODEL_FASTER selection).
|
||||
if bid == "faster-whisper":
|
||||
return _fw_repo(os.environ.get("ASR_MODEL_FASTER", _FASTER_WHISPER_DEFAULT))
|
||||
if bid == "faster-whisper-isolated":
|
||||
# Mirror the sidecar's own resolution (_asr_sidecar/main.py):
|
||||
# ASR_MODEL_FW is a sidecar-only override, otherwise the shared
|
||||
# ASR_MODEL_FASTER selection applies — so the preflight can never
|
||||
# download a different repo than the sidecar will load.
|
||||
return _fw_repo(
|
||||
os.environ.get("ASR_MODEL_FW")
|
||||
or os.environ.get("ASR_MODEL_FASTER")
|
||||
or _FASTER_WHISPER_DEFAULT
|
||||
)
|
||||
if bid == "mlx-whisper":
|
||||
return os.environ.get("ASR_MODEL", _MLX_MODEL_DEFAULT)
|
||||
if bid == "parakeet-mlx":
|
||||
@@ -3168,7 +3198,10 @@ def _capture_whisper_repo() -> str | None:
|
||||
return os.environ.get("OMNIVOICE_PYTORCH_ASR_MODEL", _PYTORCH_ASR_DEFAULT)
|
||||
|
||||
|
||||
def _recommended_asr_model(purpose: str, missing_repo: str | None) -> dict | None:
|
||||
def _recommended_asr_model(
|
||||
purpose: str, missing_repo: str | None, *, prefer_sherpa: bool = True,
|
||||
excluded_sherpa_model_id: str | None = None,
|
||||
) -> dict | None:
|
||||
"""The catalog entry to offer in the download CTA.
|
||||
|
||||
Offline: the missing repo itself when it's in the catalog (guarantees
|
||||
@@ -3188,20 +3221,38 @@ def _recommended_asr_model(purpose: str, missing_repo: str | None) -> dict | Non
|
||||
|
||||
by_id = {m["repo_id"]: m for m in KNOWN_MODELS}
|
||||
exact = by_id.get(missing_repo) if missing_repo else None
|
||||
want_sherpa = False
|
||||
if purpose == "dictation":
|
||||
if exact is not None and exact.get("engine") == "sherpa-onnx":
|
||||
|
||||
def _eligible(m: dict, *, sherpa: bool) -> bool:
|
||||
if (m.get("engine") == "sherpa-onnx") != sherpa:
|
||||
return False
|
||||
if sherpa and m.get("dictation_id") == excluded_sherpa_model_id:
|
||||
return False
|
||||
return _model_supported(m)
|
||||
|
||||
if purpose != "dictation":
|
||||
if exact is not None and _model_supported(exact):
|
||||
return _shape(exact)
|
||||
prefer_sherpa = False
|
||||
|
||||
if purpose == "dictation" and prefer_sherpa:
|
||||
ok, _ = SherpaDictationBackend.is_available()
|
||||
want_sherpa = ok
|
||||
if not want_sherpa and exact is not None and _model_supported(exact):
|
||||
if ok:
|
||||
if exact is not None and _eligible(exact, sherpa=True):
|
||||
return _shape(exact)
|
||||
for m in KNOWN_MODELS:
|
||||
if (m.get("role") == "ASR" and _eligible(m, sherpa=True)
|
||||
and _model_curated(m)):
|
||||
return _shape(m)
|
||||
|
||||
# No usable Sherpa recommendation remains (runtime unavailable, explicit
|
||||
# fallback probe, or the sole curated entry is the demoted model). Offer
|
||||
# the exact capture fallback so download → retry cannot loop.
|
||||
if exact is not None and _eligible(exact, sherpa=False):
|
||||
return _shape(exact)
|
||||
for m in KNOWN_MODELS:
|
||||
if m.get("role") != "ASR":
|
||||
continue
|
||||
if (m.get("engine") == "sherpa-onnx") != want_sherpa:
|
||||
continue
|
||||
if _model_curated(m) and _model_supported(m):
|
||||
if _eligible(m, sherpa=False) and _model_curated(m):
|
||||
return _shape(m)
|
||||
return None
|
||||
|
||||
@@ -3232,7 +3283,9 @@ def _repo_installed(repo: str) -> bool:
|
||||
|
||||
def asr_model_missing_error(*, purpose: str = "transcribe",
|
||||
sherpa_model_id: str | None = None,
|
||||
backend_id: str | None = None) -> dict | None:
|
||||
backend_id: str | None = None,
|
||||
skip_sherpa: bool = False,
|
||||
require_installed: bool = False) -> dict | None:
|
||||
"""None when the active ASR selection can transcribe without downloading
|
||||
anything; otherwise the typed ``{"error": "asr_model_missing", ...}``
|
||||
payload for a 409 / SSE / WS error with a download CTA.
|
||||
@@ -3244,6 +3297,11 @@ def asr_model_missing_error(*, purpose: str = "transcribe",
|
||||
``?model=`` override. Installed state comes from the same HF-cache helpers
|
||||
the model store uses (see :func:`_repo_installed`), so the answer matches
|
||||
the Model Catalogue → Models install badges.
|
||||
``skip_sherpa`` probes only the non-Sherpa capture fallback; silent-model
|
||||
recovery uses it before deciding whether persistent demotion is warranted.
|
||||
``require_installed`` makes unknown/custom selections fail closed for that
|
||||
recovery path so it can never turn the normal fail-open policy into an
|
||||
implicit model download.
|
||||
|
||||
FAIL-OPEN rule: a repo the model catalog doesn't know (a custom
|
||||
``ASR_MODEL_*`` pin, pytorch-whisper's default repo, an unrecognized
|
||||
@@ -3253,27 +3311,55 @@ def asr_model_missing_error(*, purpose: str = "transcribe",
|
||||
a broken preflight must degrade to the old behaviour, not block ASR.
|
||||
"""
|
||||
try:
|
||||
prefer_sherpa_recommendation = not skip_sherpa
|
||||
excluded_sherpa_model_id = None
|
||||
if purpose == "dictation":
|
||||
sid = sherpa_model_id or dictation_model_id()
|
||||
sid = None if skip_sherpa else (sherpa_model_id or dictation_model_id())
|
||||
if sid:
|
||||
ok, _ = SherpaDictationBackend.is_available()
|
||||
if ok:
|
||||
from services import sherpa_dictation as _sd
|
||||
spec = _sd.get_spec(sid)
|
||||
# A recognizer observed returning silence must follow the
|
||||
# same capture fallback as execution, even when the
|
||||
# frontend keeps sending its persisted `?model=` value.
|
||||
if spec is not None:
|
||||
if _sd.is_installed(spec):
|
||||
return None
|
||||
return {
|
||||
"error": ASR_MODEL_MISSING,
|
||||
"missing_repo_id": spec.repo_id,
|
||||
"recommended": _recommended_asr_model(purpose, spec.repo_id),
|
||||
}
|
||||
if _sd.is_demoted(spec.id):
|
||||
excluded_sherpa_model_id = spec.id
|
||||
else:
|
||||
if _sd.is_installed(spec):
|
||||
return None
|
||||
return {
|
||||
"error": ASR_MODEL_MISSING,
|
||||
"missing_repo_id": spec.repo_id,
|
||||
"recommended": _recommended_asr_model(
|
||||
purpose, spec.repo_id,
|
||||
),
|
||||
}
|
||||
repo = _capture_whisper_repo()
|
||||
else:
|
||||
repo = _offline_asr_repo(backend_id)
|
||||
if repo is None:
|
||||
if require_installed:
|
||||
return {
|
||||
"error": ASR_MODEL_MISSING,
|
||||
"missing_repo_id": "unresolved-capture-fallback",
|
||||
"recommended": None,
|
||||
}
|
||||
return None # explicit opt-in engine — can't (and shouldn't) preflight
|
||||
from api.routers.setup.models import get_model_catalog
|
||||
if require_installed:
|
||||
if _repo_installed(repo):
|
||||
return None
|
||||
return {
|
||||
"error": ASR_MODEL_MISSING,
|
||||
"missing_repo_id": repo,
|
||||
"recommended": _recommended_asr_model(
|
||||
purpose, repo,
|
||||
prefer_sherpa=prefer_sherpa_recommendation,
|
||||
excluded_sherpa_model_id=excluded_sherpa_model_id,
|
||||
),
|
||||
}
|
||||
if get_model_catalog().get(repo) is None:
|
||||
return None # not installable from the CTA — fail open (see docstring)
|
||||
if _repo_installed(repo):
|
||||
@@ -3281,7 +3367,11 @@ def asr_model_missing_error(*, purpose: str = "transcribe",
|
||||
return {
|
||||
"error": ASR_MODEL_MISSING,
|
||||
"missing_repo_id": repo,
|
||||
"recommended": _recommended_asr_model(purpose, repo),
|
||||
"recommended": _recommended_asr_model(
|
||||
purpose, repo,
|
||||
prefer_sherpa=prefer_sherpa_recommendation,
|
||||
excluded_sherpa_model_id=excluded_sherpa_model_id,
|
||||
),
|
||||
}
|
||||
except Exception: # noqa: BLE001 — preflight is best-effort, never a blocker
|
||||
logger.warning("ASR install preflight failed — proceeding without it",
|
||||
|
||||
@@ -57,6 +57,99 @@ def _force_compile_requested() -> bool:
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
|
||||
|
||||
# ── FlashInfer opt-in (upstream k2-fsa port) ────────────────────────────────
|
||||
# Explicit power-user opt-in, CUDA-only: OMNIVOICE_FLASHINFER=1 patches the
|
||||
# OmniVoice model with flashinfer packed attention (~2x per upstream's
|
||||
# benchmarks); =graph additionally captures CUDA graphs (best at batch=1).
|
||||
# Off by default — `flashinfer` is not a shipped dependency, and an
|
||||
# optimization must never be a point of failure. Session-sticky failure
|
||||
# latch mirrors torch.compile's (#278).
|
||||
_FLASHINFER_ENV = "OMNIVOICE_FLASHINFER"
|
||||
_flashinfer_runtime_failure: Optional[str] = None
|
||||
|
||||
|
||||
def flashinfer_mode() -> str:
|
||||
"""The user's ``OMNIVOICE_FLASHINFER`` request: 'off' | 'on' | 'graph'.
|
||||
|
||||
Unknown values normalize to 'off' with a log line naming the env var, so
|
||||
a typo degrades to the default path instead of half-applying.
|
||||
"""
|
||||
value = os.environ.get(_FLASHINFER_ENV, "").strip().lower()
|
||||
if value in {"", "0", "false", "no", "off"}:
|
||||
return "off"
|
||||
if value in {"1", "true", "yes", "on"}:
|
||||
return "on"
|
||||
if value == "graph":
|
||||
return "graph"
|
||||
logger.warning(
|
||||
"%s=%r not recognized (valid: 0, 1, graph) — FlashInfer stays off.",
|
||||
_FLASHINFER_ENV, value,
|
||||
)
|
||||
return "off"
|
||||
|
||||
|
||||
def should_flashinfer(device: str) -> str:
|
||||
"""Resolve the FlashInfer request against this host: 'off' | 'on' | 'graph'.
|
||||
|
||||
Requires all of: the ``OMNIVOICE_FLASHINFER`` opt-in, device == "cuda"
|
||||
(flashinfer is CUDA-only), the ``flashinfer`` package importable, and no
|
||||
earlier runtime failure this session. Every refusal is logged with the
|
||||
reason and the knob's name — the user asked for it, so silence would read
|
||||
as "the setting doesn't work".
|
||||
"""
|
||||
mode = flashinfer_mode()
|
||||
if mode == "off":
|
||||
return "off"
|
||||
if device != "cuda":
|
||||
logger.warning(
|
||||
"%s requested but the compute device is %r — FlashInfer is "
|
||||
"CUDA-only, continuing without it.", _FLASHINFER_ENV, device,
|
||||
)
|
||||
return "off"
|
||||
if importlib.util.find_spec("flashinfer") is None:
|
||||
logger.warning(
|
||||
"%s requested but the `flashinfer` package is not installed — "
|
||||
"continuing without it. Install with: uv pip install "
|
||||
"flashinfer-python flashinfer-jit-cache "
|
||||
"--extra-index-url https://flashinfer.ai/whl/cu128/ "
|
||||
"(pick the index matching your CUDA build).", _FLASHINFER_ENV,
|
||||
)
|
||||
return "off"
|
||||
if _flashinfer_runtime_failure is not None:
|
||||
logger.info(
|
||||
"FlashInfer skipped: failed earlier this session (%s) — using the "
|
||||
"standard path.", _flashinfer_runtime_failure,
|
||||
)
|
||||
return "off"
|
||||
return mode
|
||||
|
||||
|
||||
def mark_flashinfer_runtime_failure(reason: str) -> None:
|
||||
"""Latch a FlashInfer apply/runtime failure for the rest of the process,
|
||||
same contract as ``mark_compile_runtime_failure``."""
|
||||
global _flashinfer_runtime_failure
|
||||
try:
|
||||
# Import/kernel errors embed absolute paths (wheels under the user's
|
||||
# home) — redact before latching, since the reason is logged here and
|
||||
# re-logged on every later skip.
|
||||
from core.failure import sanitize
|
||||
|
||||
reason = sanitize(reason)
|
||||
except Exception:
|
||||
# Fail closed: if the redactor itself breaks, latching the raw text
|
||||
# would defeat the redaction. Keep only the exception class (the part
|
||||
# before ':' in our "Type: message" reasons) and drop the message.
|
||||
reason = (
|
||||
f"{(reason or '').split(':', 1)[0][:80]} "
|
||||
"(details redacted: sanitizer unavailable)"
|
||||
).strip()
|
||||
_flashinfer_runtime_failure = reason or "unknown FlashInfer runtime failure"
|
||||
logger.warning(
|
||||
"FlashInfer disabled for this session after a runtime failure: %s",
|
||||
_flashinfer_runtime_failure,
|
||||
)
|
||||
|
||||
|
||||
def _cuda_arch_supported_for_compile() -> "tuple[bool, str]":
|
||||
"""Check the GPU's architecture against this torch build's arch list.
|
||||
|
||||
|
||||
@@ -4,8 +4,9 @@ import sys
|
||||
import time
|
||||
import asyncio
|
||||
import logging
|
||||
import queue
|
||||
import threading
|
||||
from concurrent.futures import ThreadPoolExecutor, Executor
|
||||
from concurrent.futures import Executor, Future, ThreadPoolExecutor
|
||||
|
||||
from utils.containment import contain_system_exit
|
||||
|
||||
@@ -397,7 +398,13 @@ def __getattr__(name: str):
|
||||
# (generation.py, tts_stream.py) were the last unguarded dispatch — and the
|
||||
# residual on-main reports all fail on generate:start (audio). This is the same
|
||||
# guard generalised so every GPU dispatch shares one recovery path.
|
||||
_GENERATE_TIMEOUT_EXPLICIT = "OMNIVOICE_GENERATE_TIMEOUT_S" in os.environ
|
||||
GPU_JOB_TIMEOUT_S = float(os.environ.get("OMNIVOICE_GENERATE_TIMEOUT_S", "300.0"))
|
||||
_CONFIGURED_GPU_JOB_TIMEOUT_S = GPU_JOB_TIMEOUT_S
|
||||
# CPU synthesis is healthy but substantially slower than accelerated inference.
|
||||
# Keep a separate, bounded floor so a short render on CPU is not abandoned at
|
||||
# the GPU-oriented five-minute deadline (#1588).
|
||||
CPU_JOB_TIMEOUT_S = float(os.environ.get("OMNIVOICE_CPU_GENERATE_TIMEOUT_S", "600.0"))
|
||||
|
||||
# Queue-wait budget — a SEPARATE, deliberately generous clock (#1190/#1202).
|
||||
# The execution bound above must never be spent waiting in line: a job queued
|
||||
@@ -500,7 +507,9 @@ class GpuPoolBusyError(TimeoutError):
|
||||
self.retry_after = max(1, int(round(retry_after)))
|
||||
|
||||
|
||||
def generate_timeout_s(text: "str | None") -> float:
|
||||
def generate_timeout_s(
|
||||
text: "str | None", *, engine: object = None, execution_device: "str | None" = None,
|
||||
) -> float:
|
||||
"""THE wall-clock execution budget for one synthesis job, scaled to input.
|
||||
|
||||
Single source of truth for every TTS dispatch (#1190/#1202). The
|
||||
@@ -516,10 +525,33 @@ def generate_timeout_s(text: "str | None") -> float:
|
||||
CPU-class hardware, still bounded (a wedged job is caught in minutes, not
|
||||
hours).
|
||||
"""
|
||||
return max(
|
||||
GPU_JOB_TIMEOUT_S,
|
||||
GPU_JOB_TIMEOUT_S + (max(0, len(text or "") - 1200) / 40.0),
|
||||
)
|
||||
base = GPU_JOB_TIMEOUT_S
|
||||
try:
|
||||
from core.device_caps import detect_host_caps
|
||||
family = execution_device or detect_host_caps().family
|
||||
if execution_device is None and engine is not None:
|
||||
from services.engine_routing import resolve_routing
|
||||
compat = getattr(engine, "gpu_compat", None)
|
||||
if compat is None:
|
||||
compat = getattr(type(engine), "gpu_compat", (family, "cpu"))
|
||||
if tuple(compat) == ("cpu",):
|
||||
family = "cpu"
|
||||
else:
|
||||
family = resolve_routing(
|
||||
compat, detect_host_caps(),
|
||||
float(getattr(engine, "min_vram_gb", 0.0) or 0.0),
|
||||
)["effective_device"]
|
||||
universal_override = (
|
||||
_GENERATE_TIMEOUT_EXPLICIT
|
||||
or GPU_JOB_TIMEOUT_S != _CONFIGURED_GPU_JOB_TIMEOUT_S
|
||||
)
|
||||
if family == "cpu" and not universal_override:
|
||||
base = CPU_JOB_TIMEOUT_S
|
||||
except Exception:
|
||||
# Device probing is advisory here; the configured universal bound is
|
||||
# still safe when a platform probe is unavailable during startup.
|
||||
pass
|
||||
return base + (max(0, len(text or "") - 1200) / 40.0)
|
||||
|
||||
|
||||
def _retry_after_estimate(stats: dict) -> float:
|
||||
@@ -1057,21 +1089,166 @@ def _timeout_guidance(
|
||||
# doubling the effective queue depth of a streamed multi-chunk render.
|
||||
# Giving it its own tiny pool removes that head-of-line blocking with no VRAM
|
||||
# risk, because the work was never on the device to begin with.
|
||||
_watermark_pool_singleton: "ThreadPoolExecutor | None" = None
|
||||
_watermark_pool_lock = threading.Lock()
|
||||
_WATERMARK_STOP = object()
|
||||
|
||||
|
||||
def get_watermark_pool() -> ThreadPoolExecutor:
|
||||
"""Dedicated 1-worker pool for provenance marking. Built lazily so hosts
|
||||
with watermarking disabled never spawn the thread."""
|
||||
global _watermark_pool_singleton
|
||||
if _watermark_pool_singleton is None:
|
||||
with _watermark_pool_lock:
|
||||
if _watermark_pool_singleton is None:
|
||||
_watermark_pool_singleton = ThreadPoolExecutor(
|
||||
max_workers=1, thread_name_prefix="watermark",
|
||||
class _WatermarkExecutor(Executor):
|
||||
"""Single daemon worker with a bounded shutdown contract.
|
||||
|
||||
``ThreadPoolExecutor`` uses non-daemon workers that Python joins at exit,
|
||||
so ``wait=False`` still delays process exit while ``wait=True`` can hang
|
||||
lifespan teardown forever. AudioSeal loading is not cooperatively
|
||||
cancellable; a daemon worker plus a bounded join is the only thread-based
|
||||
contract that both preserves in-process model warm-up and guarantees exit.
|
||||
"""
|
||||
|
||||
def __init__(self) -> None:
|
||||
self._items: queue.Queue = queue.Queue()
|
||||
self._lock = threading.Lock()
|
||||
self._shutdown = False
|
||||
self._thread: threading.Thread | None = None
|
||||
|
||||
def submit(self, fn, /, *args, **kwargs) -> Future:
|
||||
future: Future = Future()
|
||||
with self._lock:
|
||||
if self._shutdown:
|
||||
raise RuntimeError("cannot schedule new futures after shutdown")
|
||||
if self._thread is None:
|
||||
self._thread = threading.Thread(
|
||||
target=self._run,
|
||||
name="watermark_0",
|
||||
daemon=True,
|
||||
)
|
||||
return _watermark_pool_singleton
|
||||
self._thread.start()
|
||||
self._items.put((future, fn, args, kwargs))
|
||||
return future
|
||||
|
||||
def _run(self) -> None:
|
||||
while True:
|
||||
item = self._items.get()
|
||||
if item is _WATERMARK_STOP:
|
||||
return
|
||||
future, fn, args, kwargs = item
|
||||
if not future.set_running_or_notify_cancel():
|
||||
continue
|
||||
try:
|
||||
future.set_result(fn(*args, **kwargs))
|
||||
except (Exception, SystemExit, KeyboardInterrupt) as exc:
|
||||
future.set_exception(exc)
|
||||
|
||||
def is_stopped(self) -> bool:
|
||||
"""Whether shutdown has completed and this executor can be replaced."""
|
||||
with self._lock:
|
||||
return self._shutdown and (
|
||||
self._thread is None or not self._thread.is_alive()
|
||||
)
|
||||
|
||||
def is_shutdown(self) -> bool:
|
||||
with self._lock:
|
||||
return self._shutdown
|
||||
|
||||
def shutdown(
|
||||
self,
|
||||
wait: bool = True,
|
||||
*,
|
||||
cancel_futures: bool = False,
|
||||
timeout: float | None = None,
|
||||
) -> bool:
|
||||
with self._lock:
|
||||
self._shutdown = True
|
||||
thread = self._thread
|
||||
if cancel_futures:
|
||||
while True:
|
||||
try:
|
||||
item = self._items.get_nowait()
|
||||
except queue.Empty:
|
||||
break
|
||||
if item is not _WATERMARK_STOP:
|
||||
item[0].cancel()
|
||||
self._items.put(_WATERMARK_STOP)
|
||||
if wait and thread is not None:
|
||||
thread.join(timeout=timeout)
|
||||
return thread is None or not thread.is_alive()
|
||||
|
||||
|
||||
_watermark_pool_singleton: "_WatermarkExecutor | None" = None
|
||||
_watermark_pool_lock = threading.Lock()
|
||||
_watermark_pool_accepting = True
|
||||
|
||||
|
||||
def begin_watermark_pool_lifecycle() -> None:
|
||||
"""Open watermark submissions for a newly-started app lifespan."""
|
||||
global _watermark_pool_accepting, _watermark_pool_singleton
|
||||
with _watermark_pool_lock:
|
||||
if (
|
||||
_watermark_pool_singleton is not None
|
||||
and _watermark_pool_singleton.is_stopped()
|
||||
):
|
||||
_watermark_pool_singleton = None
|
||||
_watermark_pool_accepting = (
|
||||
_watermark_pool_singleton is None
|
||||
or not _watermark_pool_singleton.is_shutdown()
|
||||
)
|
||||
|
||||
|
||||
def get_watermark_pool() -> _WatermarkExecutor:
|
||||
"""Dedicated 1-worker pool for provenance marking. Built lazily so hosts
|
||||
with watermarking disabled never spawn the thread.
|
||||
|
||||
The executor is captured and returned UNDER the lock: reading the global
|
||||
again after an unlocked null-check could race shutdown_watermark_pool's
|
||||
reset and hand out None (CodeRabbit, PR #1577)."""
|
||||
global _watermark_pool_accepting, _watermark_pool_singleton
|
||||
with _watermark_pool_lock:
|
||||
if not _watermark_pool_accepting:
|
||||
if (
|
||||
_watermark_pool_singleton is not None
|
||||
and _watermark_pool_singleton.is_stopped()
|
||||
):
|
||||
_watermark_pool_singleton = None
|
||||
_watermark_pool_accepting = True
|
||||
else:
|
||||
raise RuntimeError("watermark executor is shutting down")
|
||||
if (
|
||||
_watermark_pool_singleton is not None
|
||||
and _watermark_pool_singleton.is_stopped()
|
||||
):
|
||||
_watermark_pool_singleton = None
|
||||
if _watermark_pool_singleton is None:
|
||||
_watermark_pool_singleton = _WatermarkExecutor()
|
||||
return _watermark_pool_singleton
|
||||
|
||||
|
||||
def shutdown_watermark_pool(*, timeout: float = 20.0) -> None:
|
||||
"""Drain the watermark pool at app shutdown (PR #1577).
|
||||
|
||||
Refuse queued work and wait for the active operation: Python cannot kill
|
||||
a thread inside AudioSeal loading, so returning early would let model
|
||||
initialization continue during interpreter teardown. The draining pool
|
||||
remains published until its worker stops, preventing concurrent producers
|
||||
from creating a replacement that escapes this shutdown. A process that
|
||||
keeps running after lifespan shutdown (the test suite does exactly this)
|
||||
gets a fresh pool once the old worker has actually stopped."""
|
||||
global _watermark_pool_accepting, _watermark_pool_singleton
|
||||
with _watermark_pool_lock:
|
||||
_watermark_pool_accepting = False
|
||||
pool = _watermark_pool_singleton
|
||||
if pool is not None:
|
||||
stopped = pool.shutdown(
|
||||
wait=True,
|
||||
cancel_futures=True,
|
||||
timeout=max(0.0, float(timeout)),
|
||||
)
|
||||
if stopped:
|
||||
with _watermark_pool_lock:
|
||||
if _watermark_pool_singleton is pool:
|
||||
_watermark_pool_singleton = None
|
||||
else:
|
||||
logger.warning(
|
||||
"Watermark worker exceeded the %.1fs shutdown deadline; "
|
||||
"abandoning its daemon thread",
|
||||
timeout,
|
||||
)
|
||||
|
||||
|
||||
model = None # type: ignore
|
||||
@@ -1376,6 +1553,122 @@ def _install_compile_fallback(_model) -> None:
|
||||
_model.generate = _generate_with_compile_fallback
|
||||
|
||||
|
||||
# ── FlashInfer runtime fallback (upstream k2-fsa port) ──────────────────────
|
||||
|
||||
|
||||
def _is_flashinfer_runtime_failure(exc: BaseException) -> bool:
|
||||
"""True when an exception originates in the FlashInfer fast path (the
|
||||
flashinfer package, our omnivoice_flashinfer patch module, or CUDA-graph
|
||||
capture/replay) rather than in the model or the request itself. Same
|
||||
chain/traceback walk as ``_is_compile_runtime_failure``."""
|
||||
import traceback as _tb
|
||||
|
||||
tb_markers = ("/flashinfer/", "omnivoice_flashinfer")
|
||||
msg_markers = ("flashinfer", "cuda graph", "cudagraph")
|
||||
seen: set[int] = set()
|
||||
cur: BaseException | None = exc
|
||||
while cur is not None and id(cur) not in seen:
|
||||
seen.add(id(cur))
|
||||
mod = type(cur).__module__ or ""
|
||||
if mod.startswith("flashinfer"):
|
||||
return True
|
||||
msg = str(cur).lower()
|
||||
if any(marker in msg for marker in msg_markers):
|
||||
return True
|
||||
try:
|
||||
for frame in _tb.extract_tb(cur.__traceback__):
|
||||
filename = (frame.filename or "").replace("\\", "/")
|
||||
if any(marker in filename for marker in tb_markers):
|
||||
return True
|
||||
except Exception:
|
||||
pass
|
||||
if cur.__cause__ is not None:
|
||||
cur = cur.__cause__
|
||||
elif not cur.__suppress_context__:
|
||||
cur = cur.__context__
|
||||
else:
|
||||
cur = None
|
||||
return False
|
||||
|
||||
|
||||
def _unapply_flashinfer(_model) -> None:
|
||||
"""Restore the standard execution path on a FlashInfer-patched model.
|
||||
|
||||
``apply_flashinfer`` works entirely through *instance-level* state —
|
||||
MethodType-bound ``forward``/``_generate_iterative`` overrides and
|
||||
``_fi_*`` attributes — so deleting those attributes restores the class
|
||||
implementations exactly. The attention implementation is restored to the
|
||||
one captured before apply (``_fi_orig_attn_impl`` — could be
|
||||
flash_attention_2, not just sdpa), and use_cache is re-enabled."""
|
||||
llm = getattr(_model, "llm", None)
|
||||
orig_attn = getattr(_model, "_fi_orig_attn_impl", None) or "sdpa"
|
||||
if llm is not None:
|
||||
for module in llm.modules():
|
||||
if "forward" in vars(module):
|
||||
del module.forward
|
||||
for attr in ("_fi_w_qkv", "_fi_qkv_split", "_fi_rope_theta", "_fi_w_gate_up"):
|
||||
if attr in vars(module):
|
||||
delattr(module, attr)
|
||||
try:
|
||||
llm.set_attn_implementation(orig_attn)
|
||||
except Exception:
|
||||
logger.exception(
|
||||
"failed to restore %s attention after FlashInfer", orig_attn
|
||||
)
|
||||
llm.config.use_cache = True
|
||||
for attr in (
|
||||
"_fi_orig_attn_impl",
|
||||
"_generate_iterative",
|
||||
"_fi_runner",
|
||||
"_fi_graph_cache",
|
||||
"_fi_enable_cuda_graph",
|
||||
"_fi_graph_buckets",
|
||||
"_fi_overhead_budget",
|
||||
):
|
||||
if attr in vars(_model):
|
||||
delattr(_model, attr)
|
||||
|
||||
|
||||
def _install_flashinfer_fallback(_model) -> None:
|
||||
"""Wrap ``model.generate`` so a FlashInfer failure at inference time falls
|
||||
back to the standard path instead of failing the generation — the same
|
||||
contract as ``_install_compile_fallback`` (#278): an optimization must
|
||||
never turn a working generation into an error."""
|
||||
orig_generate = _model.generate
|
||||
|
||||
def _generate_with_flashinfer_fallback(*args, **kwargs):
|
||||
try:
|
||||
return orig_generate(*args, **kwargs)
|
||||
except Exception as exc:
|
||||
if not _is_flashinfer_runtime_failure(exc):
|
||||
raise
|
||||
logger.warning(
|
||||
"FlashInfer runtime failure during generation (%s: %s) — "
|
||||
"restoring the standard path and disabling FlashInfer for "
|
||||
"this session. Generation is being retried without it.",
|
||||
type(exc).__name__, exc,
|
||||
)
|
||||
from services import engine_env
|
||||
engine_env.mark_flashinfer_runtime_failure(
|
||||
f"{type(exc).__name__}: {exc}"
|
||||
)
|
||||
# Unapply BEFORE exposing the eager path: while the teardown
|
||||
# mutates modules, _model.generate still routes through the
|
||||
# thread-affinity wrapper, so a concurrent render queues behind
|
||||
# this call instead of racing the half-restored model (Greptile,
|
||||
# #1565 round 2). Only a fully restored model is published.
|
||||
_unapply_flashinfer(_model)
|
||||
_model.generate = orig_generate
|
||||
try:
|
||||
return orig_generate(*args, **kwargs)
|
||||
except Exception as plain_exc:
|
||||
# `from None`: a genuine standard-path failure must not be
|
||||
# chained to — and misread as — the FlashInfer error.
|
||||
raise plain_exc from None
|
||||
|
||||
_model.generate = _generate_with_flashinfer_fallback
|
||||
|
||||
|
||||
# ── #315: thread affinity for cudagraph-compiled models ─────────────────────
|
||||
# `torch.compile(mode="reduce-overhead")` captures CUDA graphs, and captured
|
||||
# graph state is **thread-local** (torch/_inductor/cudagraph_trees keys its
|
||||
@@ -2117,6 +2410,57 @@ def _load_model_sync():
|
||||
"to stop preloading it alongside TTS."
|
||||
) from asr_exc
|
||||
|
||||
# FlashInfer opt-in (upstream k2-fsa port): packed CFG attention +
|
||||
# fused kernels, ~2x on upstream's benchmarks. Applied INSTEAD of
|
||||
# torch.compile — both rewrite the llm's execution and they do not
|
||||
# compose. Best-effort: any apply failure latches the session off and
|
||||
# the standard path continues untouched.
|
||||
flashinfer_applied = False
|
||||
try:
|
||||
from services.engine_env import (
|
||||
mark_flashinfer_runtime_failure,
|
||||
should_flashinfer,
|
||||
)
|
||||
|
||||
fi_mode = should_flashinfer(device)
|
||||
if fi_mode != "off":
|
||||
_set_loading("compiling", "Applying FlashInfer kernels…")
|
||||
try:
|
||||
from omnivoice.models.omnivoice_flashinfer import apply_flashinfer
|
||||
|
||||
# Captured BEFORE apply so unapply (either the failure
|
||||
# branch below or the generate-time fallback) restores
|
||||
# the true prior implementation.
|
||||
_model._fi_orig_attn_impl = getattr(
|
||||
_model.llm.config, "_attn_implementation", "sdpa"
|
||||
)
|
||||
apply_flashinfer(_model, enable_cuda_graph=(fi_mode == "graph"))
|
||||
except Exception as fi_exc: # noqa: BLE001 — perf opt, never fatal
|
||||
mark_flashinfer_runtime_failure(
|
||||
f"{type(fi_exc).__name__}: {fi_exc}"
|
||||
)
|
||||
# apply_flashinfer mutates the model as it goes — a
|
||||
# failure partway leaves half-patched modules that would
|
||||
# crash the next render (Greptile, #1565). Restore fully.
|
||||
_unapply_flashinfer(_model)
|
||||
else:
|
||||
flashinfer_applied = True
|
||||
_install_flashinfer_fallback(_model)
|
||||
# BOTH modes pin inference to one thread. Graph mode for
|
||||
# the #315 reason (captured CUDA-graph state is
|
||||
# thread-local); eager mode because the FlashInfer
|
||||
# attention wrapper and packed position ids are planned
|
||||
# per generation in module state — two _gpu_pool workers
|
||||
# interleaving plan() and run() would corrupt each
|
||||
# other's layout (CodeRabbit/Greptile, #1565).
|
||||
_install_compile_thread_affinity(_model)
|
||||
logger.info(
|
||||
"FlashInfer applied (mode=%s) — torch.compile skipped "
|
||||
"for this load.", fi_mode,
|
||||
)
|
||||
except Exception:
|
||||
logger.exception("FlashInfer opt-in check failed; continuing without")
|
||||
|
||||
try:
|
||||
# plan-02 (#65): gate on Triton availability (+ user setting), not
|
||||
# just device==cuda. Triton has no Windows wheel, so the old
|
||||
@@ -2124,7 +2468,7 @@ def _load_model_sync():
|
||||
# falls back to eager there.
|
||||
from services.engine_env import should_torch_compile
|
||||
|
||||
if should_torch_compile(device):
|
||||
if not flashinfer_applied and should_torch_compile(device):
|
||||
_set_loading("compiling", "Compiling model (torch.compile)…")
|
||||
try:
|
||||
_model.llm = torch.compile(_model.llm, mode=_TORCH_COMPILE_MODE)
|
||||
|
||||
@@ -110,7 +110,7 @@ class SherpaModelSpec:
|
||||
# the same HF tree API on 2026-08-07 — not estimated. Every one of the seven
|
||||
# was wrong before, and in both directions, which is worse than uniformly
|
||||
# optimistic: the two Parakeets under-reported by ~3.8x (0.18 -> 0.67 GB),
|
||||
# so the recommended default quietly downloaded four times what the picker
|
||||
# so installing v3 quietly downloaded four times what the picker
|
||||
# promised on a metered or small-disk machine; but the two low-RAM
|
||||
# zipformers OVER-reported by ~3x (0.128 -> 0.044), making the fallback
|
||||
# models look bulkier than the heavyweights they exist to rescue users
|
||||
@@ -129,7 +129,6 @@ _MODELS: dict[str, SherpaModelSpec] = {
|
||||
kind="offline-transducer",
|
||||
size_gb=0.67,
|
||||
languages="25 European languages",
|
||||
recommended=True,
|
||||
heavy=True,
|
||||
model_type="nemo_transducer",
|
||||
files={
|
||||
@@ -223,6 +222,7 @@ _MODELS: dict[str, SherpaModelSpec] = {
|
||||
kind="offline-whisper",
|
||||
size_gb=0.104,
|
||||
languages="90+ languages (auto-detect)",
|
||||
recommended=True,
|
||||
files={
|
||||
"encoder": "tiny-encoder.int8.onnx",
|
||||
"decoder": "tiny-decoder.int8.onnx",
|
||||
@@ -231,7 +231,7 @@ _MODELS: dict[str, SherpaModelSpec] = {
|
||||
),
|
||||
}
|
||||
|
||||
DEFAULT_MODEL_ID = "sherpa-parakeet-tdt-v3"
|
||||
DEFAULT_MODEL_ID = "sherpa-whisper-tiny"
|
||||
|
||||
# repo_id → model id, so the model-store list (keyed by repo_id) can be
|
||||
# enriched with the dictation metadata, and so capture can map either key.
|
||||
@@ -261,6 +261,16 @@ def sherpa_available() -> tuple[bool, str]:
|
||||
return True, "ready"
|
||||
except ImportError as e:
|
||||
return False, f"sherpa-onnx not installed: {e}. Install with: uv add sherpa-onnx"
|
||||
except Exception as e: # noqa: BLE001 — an availability probe must fail closed
|
||||
# Native wheel failures surface as OSError/RuntimeError rather than
|
||||
# ImportError (missing DLL/dylib/so, loader or runtime init failure) —
|
||||
# but the set is open-ended: an extension module is free to raise
|
||||
# anything at init. This is an availability question, so ANY failure to
|
||||
# import means "not available", never an exception escaping to the
|
||||
# caller. SherpaDictationBackend.is_available() calls this directly and
|
||||
# capture_ws.ws_transcribe calls that without a guard, so an unexpected
|
||||
# type here took the WebSocket down instead of falling back (#1610).
|
||||
return False, f"sherpa-onnx unavailable ({type(e).__name__}): {e}"
|
||||
|
||||
|
||||
def _resolve_model_dir(spec: SherpaModelSpec, *, download: bool = True) -> str:
|
||||
@@ -397,13 +407,10 @@ def build_online_recognizer(spec: SherpaModelSpec, *, download: bool = True):
|
||||
# transcribe the same bytes. It is a defect inside sherpa-onnx that the app
|
||||
# cannot fix by configuration.
|
||||
#
|
||||
# The curated default therefore cannot be trusted to WORK just because it is
|
||||
# installed — and which platforms are affected is not knowable up front, so
|
||||
# hard-coding a different default per OS would only be a guess. Instead the app
|
||||
# learns from what it observes: when a session hears real speech and the model
|
||||
# returns nothing, that model is demoted on THIS machine and stops being
|
||||
# selected. Self-correcting wherever the breakage actually is, and a no-op
|
||||
# everywhere it isn't.
|
||||
# Installation alone therefore cannot prove that a recognizer works. When a
|
||||
# session hears real speech and the model returns nothing, that model is
|
||||
# demoted on this machine and stops being selected. This self-corrects wherever
|
||||
# the decoder defect appears and is a no-op everywhere it does not.
|
||||
|
||||
#: prefs key holding the list of model ids demoted on this machine.
|
||||
PREF_SILENT_MODELS = "dictation.silent_models"
|
||||
|
||||
@@ -108,7 +108,11 @@ class SidecarSpec:
|
||||
weights_repo_id: Optional[str] = None # HF repo downloaded into <checkout>/<weights_subdir>
|
||||
weights_revision: Optional[str] = None # reviewed HF commit
|
||||
weights_subdir: str = "checkpoints"
|
||||
weights_config_name: str = "config.yaml" # required model config inside weights_subdir
|
||||
# Model-config filenames accepted inside weights_subdir. A tuple, not a
|
||||
# single name: IndexTTS 2.5's weights repo ships config.yaml, but installs
|
||||
# predating #1611 were only usable after hand-renaming it to
|
||||
# config_v2_5.yaml, and those must keep working without a reinstall.
|
||||
weights_config_names: tuple[str, ...] = ("config.yaml",)
|
||||
docs_path: str = "docs/engines" # where the manual-install fallback lives
|
||||
required_bytes: int = 12 * _GIB # conservative source+venv+weights estimate for preflight
|
||||
# Called after a successful install/uninstall so the engine's memoised
|
||||
@@ -146,7 +150,7 @@ SPECS: dict[str, SidecarSpec] = {
|
||||
weights_repo_id="IndexTeam/IndexTTS-2.5",
|
||||
weights_revision="d0aa86e75bb6f3437f3831e95056fa72842d89ef",
|
||||
weights_subdir="checkpoints",
|
||||
weights_config_name="config_v2_5.yaml",
|
||||
weights_config_names=("config.yaml", "config_v2_5.yaml"),
|
||||
docs_path="docs/engines/indextts.md",
|
||||
# ~0.1 GB source + up to ~6 GB venv (torch + transformers<5) +
|
||||
# ~6 GB weights. Deliberately conservative; the preflight subtracts
|
||||
@@ -879,11 +883,11 @@ def _weights_present(spec: SidecarSpec) -> bool:
|
||||
actual = marker[:2] if len(marker) >= 2 else marker + [""]
|
||||
if actual != expected:
|
||||
return False
|
||||
return _weights_floor_ok(wdir, config_name=spec.weights_config_name)
|
||||
return _weights_floor_ok(wdir, config_names=spec.weights_config_names)
|
||||
|
||||
|
||||
def _weights_floor_ok(wdir: Path, *, config_name: str = "config.yaml") -> bool:
|
||||
if not (wdir / config_name).is_file():
|
||||
def _weights_floor_ok(wdir: Path, *, config_names: tuple[str, ...] = ("config.yaml",)) -> bool:
|
||||
if not any((wdir / name).is_file() for name in config_names):
|
||||
return False
|
||||
floor = 5 * 1024 * 1024
|
||||
try:
|
||||
@@ -969,7 +973,7 @@ def _step_fetch_weights(spec: SidecarSpec, job: dict) -> None:
|
||||
hf_progress.unregister_listener(listener_id)
|
||||
hf_progress.current_repo_id.reset(repo_token)
|
||||
|
||||
if not _weights_floor_ok(wdir, config_name=spec.weights_config_name):
|
||||
if not _weights_floor_ok(wdir, config_names=spec.weights_config_names):
|
||||
raise _StepError(
|
||||
"Weight download finished but no plausible weight files were found — "
|
||||
"the download was likely interrupted.",
|
||||
|
||||
@@ -363,6 +363,10 @@ class SubprocessBackend(TTSBackend):
|
||||
# A duck-typed marker survives that.
|
||||
_is_subprocess_isolated: bool = True
|
||||
|
||||
# Generation happens in the sidecar: parent-side accelerator counters
|
||||
# can't see its allocations (see TTSBackend.runs_out_of_process).
|
||||
runs_out_of_process: bool = True
|
||||
|
||||
# Default sample rate; subclasses override.
|
||||
_DEFAULT_SAMPLE_RATE = 24000
|
||||
|
||||
|
||||
+251
-14
@@ -300,6 +300,23 @@ class TTSBackend(ABC):
|
||||
#: 0 means "no meaningful floor" (CPU-class engines) and never warns.
|
||||
min_vram_gb: float = 0.0
|
||||
|
||||
#: True when generation allocates in ANOTHER process — a dedicated-venv
|
||||
#: sidecar (SubprocessBackend) or a spawned binary (omnivoice-gguf).
|
||||
#: Parent-process accelerator counters cannot see those allocations, so
|
||||
#: profilers/diagnostics must not attribute the parent's VRAM numbers to
|
||||
#: the engine. Duck-typed (attribute, not issubclass) for the same
|
||||
#: module-purge reason as `_is_subprocess_isolated`.
|
||||
runs_out_of_process: bool = False
|
||||
|
||||
def model_identity(self) -> Optional[str]:
|
||||
"""Which concrete model this backend would run, for adapter engines
|
||||
that host several very different models behind one backend id
|
||||
(mlx-audio, sherpa-onnx, cosyvoice). None means the engine id
|
||||
already names the model. Profilers and diagnostics use this to
|
||||
label results — without it, Kokoro-under-mlx and Dia-under-mlx
|
||||
rows are indistinguishable."""
|
||||
return None
|
||||
|
||||
@abstractmethod
|
||||
def generate(
|
||||
self,
|
||||
@@ -324,6 +341,44 @@ class TTSBackend(ABC):
|
||||
Engines that don't support this will ignore the parameter.
|
||||
"""
|
||||
|
||||
def generate_batch(
|
||||
self,
|
||||
texts: list[str],
|
||||
*,
|
||||
ref_audio=None,
|
||||
ref_text=None,
|
||||
instruct=None,
|
||||
language=None,
|
||||
duration=None,
|
||||
speed=1.0,
|
||||
**extras,
|
||||
) -> list[torch.Tensor]:
|
||||
"""Synthesize several utterances, preserving the single-item contract.
|
||||
|
||||
Engines with a native batch forward pass override this method. The
|
||||
default keeps every existing adapter correct while giving callers one
|
||||
stable seam and per-item keyword handling.
|
||||
"""
|
||||
if not texts:
|
||||
return []
|
||||
|
||||
def _item(value, index):
|
||||
return value[index] if isinstance(value, list) else value
|
||||
|
||||
return [
|
||||
self.generate(
|
||||
text,
|
||||
ref_audio=_item(ref_audio, index),
|
||||
ref_text=_item(ref_text, index),
|
||||
instruct=_item(instruct, index),
|
||||
language=_item(language, index),
|
||||
duration=_item(duration, index),
|
||||
speed=_item(speed, index),
|
||||
**extras,
|
||||
)
|
||||
for index, text in enumerate(texts)
|
||||
]
|
||||
|
||||
# ── Lifecycle (Phase 2 will enforce per-engine overrides) ──────────────
|
||||
#
|
||||
# Today every backend lazily loads its weights on first `generate()` and
|
||||
@@ -395,6 +450,95 @@ _PROMPT_CACHE_MAX = 8
|
||||
_prompt_cache: "OrderedDict[tuple, object]" = OrderedDict()
|
||||
_prompt_cache_lock = threading.Lock()
|
||||
|
||||
# Disk layer under the in-memory LRU (upstream k2-fsa VoiceClonePrompt.save/
|
||||
# load format). The in-memory cache dies with the process, so the first
|
||||
# generation of every session re-encodes each voice (~0.4 s + an ASR pass when
|
||||
# ref_text is missing). Encoded prompts are tiny (a (8, T) int token tensor +
|
||||
# transcript), so we persist them and reload across restarts. Keyed by the
|
||||
# same tuple as the memory cache — the ref file's mtime is inside the key, so
|
||||
# an edited reference never matches a stale file; stale files age out via the
|
||||
# mtime prune. Best-effort like the memory cache: any failure means "no disk
|
||||
# hit / no disk write", never a failed generation. OMNIVOICE_PROMPT_DISK_CACHE=0
|
||||
# disables the layer entirely.
|
||||
_PROMPT_DISK_CACHE_MAX = 32
|
||||
|
||||
|
||||
def _prompt_disk_dir():
|
||||
"""Return the prompt-cache directory (created on first use), or None when
|
||||
the layer is disabled or the directory can't be created."""
|
||||
if os.environ.get("OMNIVOICE_PROMPT_DISK_CACHE", "1") == "0":
|
||||
return None
|
||||
try:
|
||||
from core.config import DATA_DIR
|
||||
|
||||
path = os.path.join(str(DATA_DIR), "prompt_cache")
|
||||
os.makedirs(path, exist_ok=True)
|
||||
return path
|
||||
except Exception as e: # noqa: BLE001 — cache layer must never break synthesis
|
||||
logger.debug("prompt disk cache unavailable: %s", e)
|
||||
return None
|
||||
|
||||
|
||||
def _prompt_disk_path(cache_dir: str, key: tuple) -> str:
|
||||
import hashlib
|
||||
|
||||
digest = hashlib.sha256(repr(key).encode("utf-8")).hexdigest()[:32]
|
||||
return os.path.join(cache_dir, f"{digest}.pt")
|
||||
|
||||
|
||||
def _prompt_disk_load(key: tuple):
|
||||
"""Load a persisted prompt for ``key``, or None. Never raises."""
|
||||
cache_dir = _prompt_disk_dir()
|
||||
if cache_dir is None:
|
||||
return None
|
||||
path = _prompt_disk_path(cache_dir, key)
|
||||
if not os.path.exists(path):
|
||||
return None
|
||||
try:
|
||||
from omnivoice.models.omnivoice import VoiceClonePrompt
|
||||
|
||||
prompt = VoiceClonePrompt.load(path)
|
||||
# Freshen so the LRU prune (by mtime) keeps actively used voices.
|
||||
os.utime(path, None)
|
||||
return prompt
|
||||
except Exception as e: # noqa: BLE001
|
||||
logger.warning("failed to load cached voice prompt %s: %s", path, e)
|
||||
try:
|
||||
os.remove(path) # corrupt/incompatible file — don't retry it forever
|
||||
except OSError:
|
||||
pass
|
||||
return None
|
||||
|
||||
|
||||
def _prompt_disk_save(key: tuple, prompt) -> None:
|
||||
"""Persist ``prompt`` under ``key`` and prune old entries. Never raises."""
|
||||
cache_dir = _prompt_disk_dir()
|
||||
if cache_dir is None:
|
||||
return
|
||||
path = _prompt_disk_path(cache_dir, key)
|
||||
try:
|
||||
# Unique per write: two GPU-pool threads missing the same key must not
|
||||
# interleave writes into one tmp file (os.replace stays atomic).
|
||||
import uuid
|
||||
|
||||
tmp = f"{path}.tmp.{os.getpid()}.{uuid.uuid4().hex[:8]}"
|
||||
prompt.save(tmp)
|
||||
os.replace(tmp, path)
|
||||
except Exception as e: # noqa: BLE001
|
||||
logger.warning("failed to persist voice prompt to %s: %s", path, e)
|
||||
return
|
||||
try:
|
||||
entries = [
|
||||
os.path.join(cache_dir, f)
|
||||
for f in os.listdir(cache_dir)
|
||||
if f.endswith(".pt")
|
||||
]
|
||||
entries.sort(key=lambda p: os.path.getmtime(p), reverse=True)
|
||||
for old in entries[_PROMPT_DISK_CACHE_MAX:]:
|
||||
os.remove(old)
|
||||
except OSError as e:
|
||||
logger.debug("prompt disk cache prune skipped: %s", e)
|
||||
|
||||
|
||||
def _clone_prompt_key(ref_audio: str, ref_text, preprocess_prompt: bool = True):
|
||||
try:
|
||||
@@ -433,15 +577,24 @@ def _get_clone_prompt(
|
||||
if hit is not None:
|
||||
_prompt_cache.move_to_end(key)
|
||||
return hit
|
||||
try:
|
||||
# Encode outside the lock (slow). Mirrors exactly what generate() would
|
||||
# do inline for this ref (omnivoice.py:964-978), so output is identical.
|
||||
prompt = model.create_voice_clone_prompt(
|
||||
ref_audio, ref_text=ref_text, preprocess_prompt=preprocess_prompt
|
||||
)
|
||||
except Exception as e: # noqa: BLE001 — fall back, never break synthesis
|
||||
logger.warning("voice-clone prompt precompute failed; using inline ref: %s", e)
|
||||
return None
|
||||
# Memory miss → disk (survives restarts). A disk hit skips the encode AND
|
||||
# the ASR transcription pass a ref_text-less reference would trigger.
|
||||
prompt = _prompt_disk_load(key)
|
||||
if prompt is None:
|
||||
try:
|
||||
# Encode outside the lock (slow). Mirrors exactly what generate()
|
||||
# would do inline for this ref (omnivoice.py:964-978), so output is
|
||||
# identical.
|
||||
prompt = model.create_voice_clone_prompt(
|
||||
ref_audio, ref_text=ref_text, preprocess_prompt=preprocess_prompt
|
||||
)
|
||||
except Exception as e: # noqa: BLE001 — fall back, never break synthesis
|
||||
logger.warning(
|
||||
"voice-clone prompt precompute failed; using inline ref: %s", e
|
||||
)
|
||||
return None
|
||||
if store:
|
||||
_prompt_disk_save(key, prompt)
|
||||
if not store:
|
||||
return prompt
|
||||
with _prompt_cache_lock:
|
||||
@@ -602,6 +755,73 @@ class OmniVoiceBackend(TTSBackend):
|
||||
)
|
||||
return audios[0]
|
||||
|
||||
def generate_batch(self, texts: list[str], **kw) -> list[torch.Tensor]:
|
||||
"""Use OmniVoice's native variable-length batch generation.
|
||||
|
||||
Batch callers pass per-item language, duration, speed and reference
|
||||
lists. Reusable clone prompts are prepared once and handed to the
|
||||
model together; an incomplete prompt batch falls back to the proven
|
||||
single-item path instead of changing synthesis semantics.
|
||||
"""
|
||||
self._ensure_loaded()
|
||||
if not texts:
|
||||
return []
|
||||
|
||||
def _items(value):
|
||||
if isinstance(value, list):
|
||||
return value
|
||||
return [value] * len(texts)
|
||||
|
||||
def _item_kwargs(index):
|
||||
return {
|
||||
key: value[index] if isinstance(value, list) else value
|
||||
for key, value in kw.items()
|
||||
}
|
||||
|
||||
ref_audios = _items(kw.get("ref_audio"))
|
||||
ref_texts = _items(kw.get("ref_text"))
|
||||
cache_ref = bool(kw.get("cache_ref", True))
|
||||
preprocess_prompt = bool(kw.get("preprocess_prompt", True))
|
||||
prompts = []
|
||||
if any(ref_audios):
|
||||
for ref_audio, ref_text in zip(ref_audios, ref_texts):
|
||||
if not ref_audio:
|
||||
prompts = []
|
||||
break
|
||||
prompt = _get_clone_prompt(
|
||||
self._model,
|
||||
ref_audio,
|
||||
ref_text,
|
||||
preprocess_prompt,
|
||||
store=cache_ref,
|
||||
)
|
||||
if prompt is None:
|
||||
prompts = []
|
||||
break
|
||||
prompts.append(prompt)
|
||||
|
||||
if any(ref_audios) and len(prompts) != len(texts):
|
||||
return [self.generate(text, **_item_kwargs(i))
|
||||
for i, text in enumerate(texts)]
|
||||
|
||||
gen_kw = dict(
|
||||
language=kw.get("language"),
|
||||
instruct=kw.get("instruct"),
|
||||
duration=kw.get("duration"),
|
||||
speed=kw.get("speed", 1.0),
|
||||
denoise=kw.get("denoise", True),
|
||||
postprocess_output=kw.get("postprocess_output", True),
|
||||
num_step=kw.get("num_step", 16),
|
||||
guidance_scale=kw.get("guidance_scale", 2.0),
|
||||
preprocess_prompt=preprocess_prompt,
|
||||
)
|
||||
if prompts:
|
||||
gen_kw["voice_clone_prompt"] = prompts
|
||||
else:
|
||||
gen_kw["ref_audio"] = None
|
||||
gen_kw["ref_text"] = None
|
||||
return self._model.generate(text=texts, **gen_kw)
|
||||
|
||||
def unload(self) -> None:
|
||||
"""Release the OmniVoice model (MM2-02). OmniVoice shares the singleton
|
||||
owned by ``model_manager``, so dropping our local ref isn't enough — we
|
||||
@@ -1075,7 +1295,8 @@ class KittenTTSBackend(TTSBackend):
|
||||
- English only
|
||||
- Much faster + much smaller install
|
||||
|
||||
Preset voice is chosen via `extras["voice"]` (defaults to "Jasper"). Any
|
||||
Preset voice is chosen via `extras["voice"]` (defaults to DEFAULT_VOICE,
|
||||
"expr-voice-2-f"). Any
|
||||
`ref_audio` / `instruct` / `language` arg is ignored with a log line so
|
||||
the common call-site doesn't need to know which engine it's talking to.
|
||||
"""
|
||||
@@ -1384,6 +1605,9 @@ class MLXAudioBackend(TTSBackend):
|
||||
def sample_rate(self) -> int:
|
||||
return self._sr
|
||||
|
||||
def model_identity(self) -> Optional[str]:
|
||||
return self._model_id
|
||||
|
||||
@property
|
||||
def supported_languages(self) -> list[str]:
|
||||
# Per-model; Kokoro supports 8, Qwen3 ~4, Kugel 24. Return "multi"
|
||||
@@ -1571,6 +1795,18 @@ class CosyVoiceBackend(TTSBackend):
|
||||
def supported_languages(self) -> list[str]:
|
||||
return ["zh", "en", "ja", "ko", "yue", "de", "es", "fr", "it", "ru"]
|
||||
|
||||
@staticmethod
|
||||
def _resolved_model_dir() -> str:
|
||||
return os.environ.get(
|
||||
"OMNIVOICE_COSYVOICE_MODEL",
|
||||
"pretrained_models/Fun-CosyVoice3-0.5B",
|
||||
)
|
||||
|
||||
def model_identity(self) -> Optional[str]:
|
||||
# v1/v2/v3 all live behind the one "cosyvoice" id — the directory
|
||||
# basename is the only thing that tells the models apart.
|
||||
return os.path.basename(os.path.normpath(self._resolved_model_dir()))
|
||||
|
||||
def _ensure_loaded(self):
|
||||
if self._model is not None:
|
||||
return
|
||||
@@ -1578,10 +1814,7 @@ class CosyVoiceBackend(TTSBackend):
|
||||
if not ok:
|
||||
raise RuntimeError(f"CosyVoice unavailable: {msg}")
|
||||
from cosyvoice.cli.cosyvoice import AutoModel # type: ignore[import-not-found]
|
||||
model_dir = os.environ.get(
|
||||
"OMNIVOICE_COSYVOICE_MODEL",
|
||||
"pretrained_models/Fun-CosyVoice3-0.5B",
|
||||
)
|
||||
model_dir = self._resolved_model_dir()
|
||||
logger.info("Loading CosyVoice from %s", model_dir)
|
||||
self._model = AutoModel(model_dir=model_dir)
|
||||
|
||||
@@ -1814,6 +2047,10 @@ class SherpaOnnxBackend(TTSBackend):
|
||||
self._tts = None
|
||||
self._model_dir = os.environ.get("OMNIVOICE_SHERPA_MODEL", "")
|
||||
|
||||
def model_identity(self) -> Optional[str]:
|
||||
model_dir = (self._model_dir or "").strip()
|
||||
return os.path.basename(os.path.normpath(model_dir)) if model_dir else None
|
||||
|
||||
@classmethod
|
||||
def is_available(cls) -> tuple[bool, str]:
|
||||
try:
|
||||
|
||||
+266
-41
@@ -20,12 +20,17 @@ Usage:
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import contextlib
|
||||
import logging
|
||||
import math
|
||||
import os
|
||||
import threading
|
||||
import time
|
||||
import torch
|
||||
from pathlib import Path
|
||||
from typing import Optional
|
||||
|
||||
import torch
|
||||
|
||||
from core.prefs import resolve
|
||||
|
||||
logger = logging.getLogger("omnivoice.watermark")
|
||||
@@ -37,6 +42,20 @@ _detector = None
|
||||
_audioseal_available: Optional[bool] = None
|
||||
# Monotonic stamp of the last embed/detect, for the idle release below.
|
||||
_last_used = 0.0
|
||||
# Per-model locks for the lazy builds below: the startup prefetch thread
|
||||
# races the first embed, and both must share ONE build (a double load doubles
|
||||
# the cold-start cost the prefetch exists to hide). One lock PER MODEL — a
|
||||
# single shared lock made the ~42s generator prefetch block unrelated detector
|
||||
# loads and the idle reaper behind it. release_idle_models acquires both, in
|
||||
# this fixed order (nothing else nests them, so no cycle is possible).
|
||||
_generator_lock = threading.Lock()
|
||||
_detector_lock = threading.Lock()
|
||||
|
||||
# True when the generator exists ONLY because the startup prefetch built it
|
||||
# and no embed/detect has used it since. The idle reaper grants one extra
|
||||
# idle window before dropping such a model, so a first synthesis at minute
|
||||
# 20 still finds it warm (code-review finding 2 on the prefetch PR).
|
||||
_prefetched_unused = False
|
||||
|
||||
# 16-bit message: "OM" in ASCII = 0x4F 0x4D = 0100_1111 0100_1101
|
||||
# This is our signature — every VoiceStudio-generated audio carries it.
|
||||
@@ -50,6 +69,86 @@ OMNI_MESSAGE = [0, 1, 0, 0, 1, 1, 1, 1, 0, 1, 0, 0, 1, 1, 0, 1]
|
||||
_CHUNK_SECONDS = 30
|
||||
|
||||
|
||||
# AudioSeal vendors moshi's ``@torch_compile_lazy`` on SEANetEncoder.forward,
|
||||
# so the first EMBED — not the model load, which prefetch already warms —
|
||||
# calls torch.compile and drops into Inductor's C++ codegen. On hosts whose
|
||||
# C++ toolchain can't serve Inductor that compile raises CppCompileError, the
|
||||
# embed fail-opens, and audio ships unmarked: a macOS arm64 deployment lost
|
||||
# provenance marking on 10/10 takes while paying 30-40 s for the first failed
|
||||
# compile and 5-8 s for each later one (#1615).
|
||||
#
|
||||
# The compile is pure cost even where it succeeds. Measured on an M3 (5 s of
|
||||
# 24 kHz audio, three consecutive embeds): compiled 9.70 / 0.26 / 0.23 s vs
|
||||
# eager 0.30 / 0.28 / 0.27 s — a ~10 s first-embed tax to save ~0.03 s per
|
||||
# later embed, on CPU work that is already bounded by the 30 s chunk loop.
|
||||
# So watermarking runs eager on every platform.
|
||||
def _moshi_compile_module():
|
||||
"""AudioSeal's vendored moshi compile switch module, or None.
|
||||
|
||||
Resolved per call rather than at import: ``_check_available()`` is what
|
||||
guarantees audioseal is importable, and it runs later than this module.
|
||||
"""
|
||||
try:
|
||||
from audioseal.libs.moshi.utils import compile as moshi_compile
|
||||
except Exception: # noqa: BLE001 — any import shape change degrades, not crashes
|
||||
return None
|
||||
return moshi_compile
|
||||
|
||||
|
||||
_eager_lock = threading.Lock()
|
||||
#: Depth of nested/concurrent eager scopes, and the switch value to put back
|
||||
#: when the last one exits. One dict rather than two module scalars: the
|
||||
#: fields are only meaningful together, and only under _eager_lock.
|
||||
_eager_state: dict = {"depth": 0, "saved": None}
|
||||
_eager_guard_warned = False
|
||||
|
||||
|
||||
def _warn_missing_eager_guard() -> None:
|
||||
global _eager_guard_warned
|
||||
_eager_guard_warned = True
|
||||
logger.info(
|
||||
"audioseal's no_compile switch is unavailable — watermarking may run "
|
||||
"through torch.compile and pay (or fail) an Inductor C++ compile (#1615)."
|
||||
)
|
||||
|
||||
|
||||
@contextlib.contextmanager
|
||||
def _eager_audioseal():
|
||||
"""Run the AudioSeal model eagerly, restoring the switch on the way out.
|
||||
|
||||
Upstream's own ``no_compile()`` saves and restores ``_compile_disabled``
|
||||
per call, which is not safe when two watermark calls overlap: the first to
|
||||
exit restores False while the second is still mid-embed, handing it back
|
||||
the compile this whole fix exists to avoid. So the flag is reference
|
||||
counted here — it goes True on the outermost entry and only comes back on
|
||||
the outermost exit — rather than serializing embeds behind a lock, which
|
||||
would cost real throughput on concurrent generations.
|
||||
|
||||
Degrades to a plain call if a future audioseal drops the helper
|
||||
(``tests/test_watermark_no_torch_compile_1615.py`` fails loudly on that
|
||||
upgrade rather than letting the compile creep back in).
|
||||
"""
|
||||
moshi = _moshi_compile_module()
|
||||
if moshi is None:
|
||||
if not _eager_guard_warned:
|
||||
_warn_missing_eager_guard()
|
||||
yield
|
||||
return
|
||||
with _eager_lock:
|
||||
if _eager_state["depth"] == 0:
|
||||
_eager_state["saved"] = moshi._compile_disabled
|
||||
_eager_state["depth"] += 1
|
||||
moshi._compile_disabled = True
|
||||
try:
|
||||
yield
|
||||
finally:
|
||||
with _eager_lock:
|
||||
_eager_state["depth"] -= 1
|
||||
if _eager_state["depth"] == 0:
|
||||
moshi._compile_disabled = _eager_state["saved"]
|
||||
_eager_state["saved"] = None
|
||||
|
||||
|
||||
def _iter_chunks(audio: torch.Tensor, sample_rate: int):
|
||||
"""Yield ≤ ~_CHUNK_SECONDS slices of (batch, channels, samples) audio
|
||||
along the time axis. A sub-second tail is folded into the previous chunk
|
||||
@@ -77,28 +176,82 @@ def _check_available() -> bool:
|
||||
return _audioseal_available
|
||||
|
||||
|
||||
def _get_generator():
|
||||
"""Lazy-load the AudioSeal generator model."""
|
||||
global _generator, _last_used
|
||||
_last_used = time.monotonic()
|
||||
if _generator is None:
|
||||
from audioseal import AudioSeal
|
||||
_generator = AudioSeal.load_generator("audioseal_wm_16bits")
|
||||
_generator.eval()
|
||||
logger.info("AudioSeal generator loaded (16-bit message mode)")
|
||||
return _generator
|
||||
def _get_generator(mark_prefetched: bool = False):
|
||||
"""Lazy-load the AudioSeal generator model.
|
||||
|
||||
Owns the idle-reaper grace in ONE critical section: the startup prefetch
|
||||
claims it (``mark_prefetched=True``) only when THIS call builds the model,
|
||||
and every other call (a real embed) consumes it — no call-site blocks, no
|
||||
window between two lock scopes where the claim could land on an
|
||||
already-used model.
|
||||
"""
|
||||
global _generator, _last_used, _prefetched_unused
|
||||
with _generator_lock:
|
||||
_last_used = time.monotonic()
|
||||
if _generator is None:
|
||||
from audioseal import AudioSeal
|
||||
_generator = AudioSeal.load_generator("audioseal_wm_16bits")
|
||||
_generator.eval()
|
||||
logger.info("AudioSeal generator loaded (16-bit message mode)")
|
||||
_prefetched_unused = mark_prefetched
|
||||
elif not mark_prefetched:
|
||||
_prefetched_unused = False
|
||||
return _generator
|
||||
|
||||
|
||||
def _get_detector():
|
||||
"""Lazy-load the AudioSeal detector model."""
|
||||
global _detector, _last_used
|
||||
_last_used = time.monotonic()
|
||||
if _detector is None:
|
||||
from audioseal import AudioSeal
|
||||
_detector = AudioSeal.load_detector("audioseal_detector_16bits")
|
||||
_detector.eval()
|
||||
logger.info("AudioSeal detector loaded (16-bit message mode)")
|
||||
return _detector
|
||||
with _detector_lock:
|
||||
_last_used = time.monotonic()
|
||||
if _detector is None:
|
||||
from audioseal import AudioSeal
|
||||
_detector = AudioSeal.load_detector("audioseal_detector_16bits")
|
||||
_detector.eval()
|
||||
logger.info("AudioSeal detector loaded (16-bit message mode)")
|
||||
return _detector
|
||||
|
||||
|
||||
def _generator_checkpoint_cached() -> bool:
|
||||
"""Return whether AudioSeal can warm without contacting Hugging Face.
|
||||
|
||||
AudioSeal 0.2 stores the checkpoint in ``<cache>/audioseal`` even though
|
||||
it uses huggingface_hub to fetch it. Keep startup local-first: an ordinary
|
||||
boot may consume that file, but must never turn prefetch into a download.
|
||||
"""
|
||||
cache_root = os.environ.get("AUDIOSEAL_CACHE_DIR") or os.environ.get(
|
||||
"XDG_CACHE_HOME"
|
||||
)
|
||||
root = Path(cache_root).expanduser() if cache_root else Path.home() / ".cache"
|
||||
return (root / "audioseal" / "generator_base.pth").is_file()
|
||||
|
||||
|
||||
def prefetch_generator(*, allow_download: bool = False) -> None:
|
||||
"""Warm the AudioSeal generator eagerly (startup background thread).
|
||||
|
||||
The first ``mark_synthetic`` otherwise pays the audioseal import plus the
|
||||
generator load inline — measured at ~42 s on a cold filesystem (2026-08-17
|
||||
macOS deployment), serialized inside the first synthesis and 3 s short of
|
||||
a 90 s client timeout. Warming here overlaps that span with the TTS model
|
||||
load. No-op when watermarking is off or audioseal is absent; a failure
|
||||
logs and leaves the lazy path to retry on first embed. Default startup is
|
||||
also cache-only; a download is allowed only when the user explicitly set
|
||||
``OMNIVOICE_PRELOAD_WATERMARK=1``.
|
||||
"""
|
||||
try:
|
||||
if not will_mark():
|
||||
logger.debug("Watermark prefetch skipped (disabled or audioseal absent)")
|
||||
return
|
||||
if not allow_download and not _generator_checkpoint_cached():
|
||||
logger.info("Watermark prefetch skipped: AudioSeal checkpoint is not cached")
|
||||
return
|
||||
_get_generator(mark_prefetched=True)
|
||||
logger.info("AudioSeal generator prefetched in the background")
|
||||
except Exception:
|
||||
logger.warning(
|
||||
"Watermark prefetch failed; the first embed will retry inline",
|
||||
exc_info=True,
|
||||
)
|
||||
|
||||
|
||||
def release_idle_models(idle_seconds: float, *, now: Optional[float] = None) -> bool:
|
||||
@@ -114,14 +267,28 @@ def release_idle_models(idle_seconds: float, *, now: Optional[float] = None) ->
|
||||
Returns True if anything was released. Never raises: this runs from the
|
||||
idle reaper, which must survive it.
|
||||
"""
|
||||
global _generator, _detector
|
||||
if _generator is None and _detector is None:
|
||||
return False
|
||||
stamp = time.monotonic() if now is None else float(now)
|
||||
if stamp - _last_used < idle_seconds:
|
||||
return False
|
||||
_generator = None
|
||||
_detector = None
|
||||
global _generator, _detector, _prefetched_unused
|
||||
with _generator_lock, _detector_lock:
|
||||
if _generator is None and _detector is None:
|
||||
return False
|
||||
stamp = time.monotonic() if now is None else float(now)
|
||||
if stamp - _last_used < idle_seconds:
|
||||
return False
|
||||
if _prefetched_unused:
|
||||
# The startup prefetch built the generator and nothing has used
|
||||
# it yet. Drop the grace (one extra idle window only) instead of
|
||||
# the model, so a first synthesis shortly after boot still finds
|
||||
# it warm — the exact scenario the prefetch exists for.
|
||||
_prefetched_unused = False
|
||||
logger.info(
|
||||
"Idle watermark models are prefetch-warmed but unused; "
|
||||
"granting one more idle window before releasing."
|
||||
)
|
||||
return False
|
||||
# Under the locks so a release racing the prefetch or a first embed
|
||||
# can't wipe a model the lazy path just built.
|
||||
_generator = None
|
||||
_detector = None
|
||||
logger.info("Idle timeout reached. Released the AudioSeal watermark models.")
|
||||
return True
|
||||
|
||||
@@ -200,6 +367,62 @@ def mark_synthetic(
|
||||
return marked
|
||||
|
||||
|
||||
async def mark_synthetic_async(
|
||||
waveform: torch.Tensor,
|
||||
sample_rate: int,
|
||||
*,
|
||||
context: str,
|
||||
force: bool = False,
|
||||
timeout: float | None = None,
|
||||
) -> torch.Tensor:
|
||||
"""Dispatch marking without letting a draining pool lose finished audio."""
|
||||
import asyncio
|
||||
import functools
|
||||
|
||||
from services.model_manager import (
|
||||
GpuJobTimeoutError,
|
||||
GpuPoolBusyError,
|
||||
get_watermark_pool,
|
||||
run_on_gpu_pool_guarded,
|
||||
)
|
||||
|
||||
try:
|
||||
pool = get_watermark_pool()
|
||||
except RuntimeError:
|
||||
logger.warning("Watermark skipped while the prior worker is shutting down")
|
||||
return waveform
|
||||
|
||||
job = functools.partial(
|
||||
mark_synthetic, waveform, sample_rate, context=context, force=force
|
||||
)
|
||||
try:
|
||||
if timeout is not None:
|
||||
return await run_on_gpu_pool_guarded(
|
||||
job, what="Audio watermark", timeout=timeout, executor=pool
|
||||
)
|
||||
return await asyncio.get_running_loop().run_in_executor(pool, job)
|
||||
except (GpuJobTimeoutError, GpuPoolBusyError):
|
||||
# Watermarking is provenance best-effort: a typed execution overrun or
|
||||
# queue saturation must not discard synthesis that already completed.
|
||||
logger.warning("Watermark skipped after its bounded dispatch expired")
|
||||
return waveform
|
||||
except asyncio.CancelledError:
|
||||
# A queued future is cancelled during pool teardown. Caller-driven
|
||||
# cancellation while the pool is live must retain normal semantics.
|
||||
if not pool.is_shutdown():
|
||||
raise
|
||||
logger.warning("Watermark skipped while the pool is shutting down")
|
||||
return waveform
|
||||
except RuntimeError:
|
||||
# Shutdown may begin after admission but before Executor.submit().
|
||||
# Preserve unrelated worker failures; only lifecycle rejection is
|
||||
# fail-open because finished synthesis must not be lost to teardown.
|
||||
if not pool.is_shutdown():
|
||||
raise
|
||||
logger.warning("Watermark skipped while the pool is shutting down")
|
||||
return waveform
|
||||
|
||||
|
||||
@torch.no_grad()
|
||||
def embed_watermark(
|
||||
waveform: torch.Tensor,
|
||||
@@ -243,13 +466,14 @@ def embed_watermark(
|
||||
|
||||
# AudioSeal operates at 16kHz internally; it handles resampling, but
|
||||
# we need to inform it of the source rate for correct embedding.
|
||||
watermarked = torch.cat(
|
||||
[
|
||||
generator(seg, sample_rate=sample_rate, message=msg)
|
||||
for seg in _iter_chunks(audio, sample_rate)
|
||||
],
|
||||
dim=-1,
|
||||
)
|
||||
with _eager_audioseal():
|
||||
watermarked = torch.cat(
|
||||
[
|
||||
generator(seg, sample_rate=sample_rate, message=msg)
|
||||
for seg in _iter_chunks(audio, sample_rate)
|
||||
],
|
||||
dim=-1,
|
||||
)
|
||||
|
||||
# Restore original shape
|
||||
if len(original_shape) == 2:
|
||||
@@ -260,7 +484,7 @@ def embed_watermark(
|
||||
return watermarked
|
||||
|
||||
except Exception as e:
|
||||
logger.warning("Watermark embedding failed (passing through original): %s", e)
|
||||
logger.warning("Watermark embedding failed (passing through original): %s", e, exc_info=True)
|
||||
return waveform
|
||||
|
||||
|
||||
@@ -307,12 +531,13 @@ def detect_watermark(
|
||||
# embedding does, and a splice where only part of the file is
|
||||
# VoiceStudio audio still registers (a whole-file average would dilute it).
|
||||
best_conf, decoded_msg = -1.0, None
|
||||
for seg in _iter_chunks(audio, sample_rate):
|
||||
result = detector.detect_watermark(seg, sample_rate=sample_rate, message_threshold=0.5)
|
||||
seg_conf = float(result[0]) if isinstance(result, tuple) else 0.0
|
||||
if seg_conf > best_conf:
|
||||
best_conf = seg_conf
|
||||
decoded_msg = result[1] if isinstance(result, tuple) and len(result) > 1 else None
|
||||
with _eager_audioseal():
|
||||
for seg in _iter_chunks(audio, sample_rate):
|
||||
result = detector.detect_watermark(seg, sample_rate=sample_rate, message_threshold=0.5)
|
||||
seg_conf = float(result[0]) if isinstance(result, tuple) else 0.0
|
||||
if seg_conf > best_conf:
|
||||
best_conf = seg_conf
|
||||
decoded_msg = result[1] if isinstance(result, tuple) and len(result) > 1 else None
|
||||
confidence = max(best_conf, 0.0)
|
||||
|
||||
# Decode message bits
|
||||
@@ -337,7 +562,7 @@ def detect_watermark(
|
||||
}
|
||||
|
||||
except Exception as e:
|
||||
logger.warning("Watermark detection failed: %s", e)
|
||||
logger.warning("Watermark detection failed: %s", e, exc_info=True)
|
||||
return {
|
||||
"is_watermarked": False,
|
||||
"confidence": 0.0,
|
||||
|
||||
@@ -125,6 +125,16 @@ def test_faster_whisper_float16_unsupported_falls_back_to_int8(monkeypatch):
|
||||
)
|
||||
monkeypatch.setitem(sys.modules, "torch", fake_torch)
|
||||
|
||||
# The compute-device override gate consults the capability probe before
|
||||
# the torch mock above — pin it to a CUDA family so the fallback chain
|
||||
# under test is reachable on a cpu-only CI host.
|
||||
from core.device_caps import HostCaps
|
||||
|
||||
monkeypatch.setattr(
|
||||
"core.device_caps.detect_host_caps",
|
||||
lambda: HostCaps(family="cuda", available_families=("cuda", "cpu")),
|
||||
)
|
||||
|
||||
be = FasterWhisperBackend()
|
||||
be._ensure_model()
|
||||
|
||||
|
||||
@@ -1,16 +1,15 @@
|
||||
"""A dictation model that decodes nothing gets demoted, not re-selected forever.
|
||||
|
||||
`sherpa-parakeet-tdt-v3` is the curated default, and on Windows it installs
|
||||
cleanly, loads without error, and returns an empty token list for clear speech
|
||||
On Windows, `sherpa-parakeet-tdt-v3` installs cleanly, loads without error,
|
||||
and returns an empty token list for clear speech
|
||||
(both quantisations, both decoding methods, sherpa-onnx 1.13.3 and 1.13.4)
|
||||
while whisper and zipformer transcribe the same bytes. The defect is inside
|
||||
sherpa-onnx's NeMo-TDT decoder — unfixable from here by configuration.
|
||||
|
||||
Hard-coding a different default per OS would be a guess: we have evidence for
|
||||
one platform only. So the app observes instead. When a session hears real
|
||||
speech and the model returns nothing, that model is demoted ON THIS MACHINE and
|
||||
stops being auto-selected, which self-corrects wherever the breakage actually
|
||||
is and is a no-op everywhere it isn't.
|
||||
Whisper Tiny is now the cross-platform default, while Parakeet remains
|
||||
selectable. Runtime demotion still protects users who select a recognizer that
|
||||
loads successfully but decodes nothing: it is demoted on this machine and the
|
||||
next session follows the capture fallback.
|
||||
|
||||
These tests pin the demotion round trip and, critically, that the user can
|
||||
always take back control by re-picking the model.
|
||||
|
||||
@@ -1,13 +1,13 @@
|
||||
"""A dictation model that decodes NOTHING must fall back, not fail silently.
|
||||
|
||||
Found on Windows with the curated default `sherpa-parakeet-tdt-v3`: the model
|
||||
Found on Windows with `sherpa-parakeet-tdt-v3`: the model
|
||||
downloads, loads with zero errors, and is correctly detected as a TDT model
|
||||
(`num_durations: 5`) — then returns an empty token list for clear speech.
|
||||
Measured against the same 18.9s WAV, on the same machine, same sherpa-onnx:
|
||||
|
||||
sherpa-whisper-tiny -> "Alright, here we are. I hope that's all..."
|
||||
sherpa-zipformer-en-20m -> "ANTS BOTH IN WHAT DISGUISED THIS THAT..."
|
||||
parakeet-tdt-v3 (int8) -> '' <-- the curated default
|
||||
parakeet-tdt-v3 (int8) -> ''
|
||||
parakeet-tdt-v3 (fp32) -> ''
|
||||
parakeet-tdt-v2 (int8) -> ''
|
||||
|
||||
|
||||
@@ -0,0 +1,76 @@
|
||||
"""#1618 — RAM preflight must not hard-block the machines it means to admit.
|
||||
|
||||
An "8 GB" machine reports ~7.8 GB usable (firmware/iGPU/kernel reservations),
|
||||
so comparing reported RAM against the marketing-size threshold blocked exactly
|
||||
the boundary hardware the ≥8 GB rule intends to allow. The check now applies
|
||||
``_RAM_RESERVED_ALLOWANCE`` to both thresholds, and
|
||||
``OMNIVOICE_RAM_PREFLIGHT=0`` downgrades a genuine fail to a warning.
|
||||
"""
|
||||
|
||||
import pytest
|
||||
|
||||
from api.routers.setup import wizard
|
||||
|
||||
|
||||
def _ram_check(monkeypatch, ram_gb: float, env: str | None = None) -> dict:
|
||||
# Keep the preflight hermetic: stub the probes that hit the network or
|
||||
# auto-acquire media tools, so each RAM assertion stays fast and offline.
|
||||
monkeypatch.setattr(wizard, "_network_check", lambda: {
|
||||
"id": "network", "label": "Network", "status": "pass",
|
||||
"detail": "stubbed", "fix": None, "mirror_reachable": True,
|
||||
})
|
||||
import services.media_tools as media_tools
|
||||
monkeypatch.setattr(media_tools, "summary", lambda auto_acquire=True: None)
|
||||
monkeypatch.setattr(wizard, "_ram_gb", lambda: ram_gb)
|
||||
if env is None:
|
||||
monkeypatch.delenv("OMNIVOICE_RAM_PREFLIGHT", raising=False)
|
||||
else:
|
||||
monkeypatch.setenv("OMNIVOICE_RAM_PREFLIGHT", env)
|
||||
resp = wizard.preflight()
|
||||
checks = resp["checks"] if isinstance(resp, dict) else resp.checks
|
||||
for c in checks:
|
||||
c = c if isinstance(c, dict) else c.model_dump()
|
||||
if c["id"] == "ram":
|
||||
return c
|
||||
raise AssertionError("no ram check in preflight response")
|
||||
|
||||
|
||||
def test_8gb_installed_reporting_7_84_usable_is_not_blocked(monkeypatch):
|
||||
"""The #1618 report: 7.84 GB usable on an 8 GB laptop was a hard fail."""
|
||||
check = _ram_check(monkeypatch, 7.84)
|
||||
assert check["status"] != "fail"
|
||||
|
||||
|
||||
def test_boundary_at_allowance_passes_the_fail_gate(monkeypatch):
|
||||
check = _ram_check(
|
||||
monkeypatch, wizard._RAM_FAIL_GB * wizard._RAM_RESERVED_ALLOWANCE
|
||||
)
|
||||
assert check["status"] != "fail"
|
||||
|
||||
|
||||
def test_genuinely_low_ram_still_fails(monkeypatch):
|
||||
check = _ram_check(monkeypatch, 6.0)
|
||||
assert check["status"] == "fail"
|
||||
|
||||
|
||||
@pytest.mark.parametrize("env", ["0", "false", "no"])
|
||||
def test_escape_hatch_downgrades_fail_to_warn(monkeypatch, env):
|
||||
check = _ram_check(monkeypatch, 6.0, env=env)
|
||||
assert check["status"] == "warn"
|
||||
assert "OMNIVOICE_RAM_PREFLIGHT" in (check["fix"] or "")
|
||||
|
||||
|
||||
def test_escape_hatch_not_triggered_by_other_values(monkeypatch):
|
||||
check = _ram_check(monkeypatch, 6.0, env="1")
|
||||
assert check["status"] == "fail"
|
||||
|
||||
|
||||
def test_12gb_installed_reporting_11_8_usable_passes_clean(monkeypatch):
|
||||
"""Same reservation gap at the warn threshold: 12 GB installed ≈ 11.8."""
|
||||
check = _ram_check(monkeypatch, 11.8)
|
||||
assert check["status"] == "pass"
|
||||
|
||||
|
||||
def test_warn_band_between_thresholds(monkeypatch):
|
||||
check = _ram_check(monkeypatch, 9.0)
|
||||
assert check["status"] == "warn"
|
||||
@@ -76,6 +76,35 @@ class TestUnloadOnABC:
|
||||
)
|
||||
|
||||
|
||||
def test_omnivoice_native_batch_preserves_per_item_controls():
|
||||
"""The adapter forwards variable-length batch controls to OmniVoice."""
|
||||
import torch
|
||||
|
||||
tts = _load_tts_backend_module()
|
||||
calls = []
|
||||
|
||||
class _Model:
|
||||
sampling_rate = 24000
|
||||
|
||||
def generate(self, **kwargs):
|
||||
calls.append(kwargs)
|
||||
return [torch.zeros(1, 12000), torch.zeros(1, 24000)]
|
||||
|
||||
backend = tts.OmniVoiceBackend(model=_Model())
|
||||
outputs = backend.generate_batch(
|
||||
["short", "long"],
|
||||
language=["en", "es"],
|
||||
duration=[0.5, 1.0],
|
||||
speed=[1.0, 0.8],
|
||||
)
|
||||
|
||||
assert [output.shape[-1] for output in outputs] == [12000, 24000]
|
||||
assert calls[0]["text"] == ["short", "long"]
|
||||
assert calls[0]["language"] == ["en", "es"]
|
||||
assert calls[0]["duration"] == [0.5, 1.0]
|
||||
assert calls[0]["speed"] == [1.0, 0.8]
|
||||
|
||||
|
||||
class TestUnloadDefaultBehavior:
|
||||
"""The default no-op must actually be safe to call."""
|
||||
|
||||
@@ -154,4 +183,4 @@ class TestExistingSubclassesInherit:
|
||||
assert callable(getattr(cls, "unload", None)), (
|
||||
f"{cls.__name__} has no callable unload() — even via the "
|
||||
"ABC inheritance. Did someone shadow it?"
|
||||
)
|
||||
)
|
||||
|
||||
@@ -35,6 +35,9 @@ from typing import Optional
|
||||
# plane may run in a process that never loads torch). test_worker_deadlines.py
|
||||
# asserts the two agree, so a change there cannot silently drift from here.
|
||||
_GENERATE_TIMEOUT_S = float(os.environ.get("OMNIVOICE_GENERATE_TIMEOUT_S", "300.0"))
|
||||
_CPU_GENERATE_TIMEOUT_S = float(
|
||||
os.environ.get("OMNIVOICE_CPU_GENERATE_TIMEOUT_S", "600.0")
|
||||
)
|
||||
_MODEL_LOAD_EXTRA_S = float(os.environ.get("OMNIVOICE_MODEL_LOAD_TIMEOUT_S", "1800.0"))
|
||||
_HEARTBEAT_GRACE_S = float(os.environ.get("OMNIVOICE_MODEL_LOAD_HEARTBEAT_GRACE_S", "30.0"))
|
||||
|
||||
@@ -123,20 +126,40 @@ class Deadlines:
|
||||
}
|
||||
|
||||
|
||||
def _base_execution_seconds(text: Optional[str]) -> float:
|
||||
def _base_execution_seconds(
|
||||
text: Optional[str], *, execution_device: Optional[str] = None
|
||||
) -> float:
|
||||
"""Delegate to model_manager's budget; fall back to its formula.
|
||||
|
||||
The lazy import keeps this module usable in a process that has no torch —
|
||||
the control plane schedules work it never executes.
|
||||
"""
|
||||
target_device = str(execution_device or "cpu").lower()
|
||||
if target_device not in {"cpu", "cuda", "mps", "mlx", "directml", "rocm", "xpu"}:
|
||||
target_device = "cpu"
|
||||
try:
|
||||
from services import model_manager # noqa: PLC0415 — intentionally lazy
|
||||
|
||||
return float(model_manager.generate_timeout_s(text))
|
||||
return float(
|
||||
model_manager.generate_timeout_s(
|
||||
text, execution_device=target_device
|
||||
)
|
||||
)
|
||||
except Exception:
|
||||
base = _GENERATE_TIMEOUT_S
|
||||
try:
|
||||
if (
|
||||
target_device == "cpu"
|
||||
and "OMNIVOICE_GENERATE_TIMEOUT_S" not in os.environ
|
||||
):
|
||||
base = _CPU_GENERATE_TIMEOUT_S
|
||||
except Exception:
|
||||
# Capability detection is optional in the torch-free control
|
||||
# plane; retain the configured universal bounded fallback.
|
||||
pass
|
||||
return max(
|
||||
_GENERATE_TIMEOUT_S,
|
||||
_GENERATE_TIMEOUT_S + max(0, len(text or "") - _FREE_CHARS) / _CHARS_PER_SECOND,
|
||||
base,
|
||||
base + max(0, len(text or "") - _FREE_CHARS) / _CHARS_PER_SECOND,
|
||||
)
|
||||
|
||||
|
||||
@@ -147,6 +170,7 @@ def for_task(
|
||||
model_resident: bool = False,
|
||||
model_downloaded: bool = True,
|
||||
input_seconds: float = 0.0,
|
||||
execution_device: Optional[str] = None,
|
||||
) -> Deadlines:
|
||||
"""Compute the deadlines for one attempt.
|
||||
|
||||
@@ -158,7 +182,9 @@ def for_task(
|
||||
op = Operation.coerce(operation)
|
||||
multiplier, grace = _PROFILE[op]
|
||||
|
||||
execution = _base_execution_seconds(text) * multiplier
|
||||
execution = _base_execution_seconds(
|
||||
text, execution_device=execution_device
|
||||
) * multiplier
|
||||
# Media-length operations scale on duration, not characters.
|
||||
if input_seconds > 0:
|
||||
execution = max(execution, input_seconds * multiplier)
|
||||
|
||||
+40
-15
@@ -460,30 +460,55 @@ class TaskExecutor:
|
||||
|
||||
@staticmethod
|
||||
def _synthesize(backend, text: str, params: dict):
|
||||
"""Call the engine through the same serial GPU gate local jobs use.
|
||||
"""Render through the same seeded pipeline as local ``/generate``.
|
||||
|
||||
Held against the idle sweep for the duration: a long generation touches
|
||||
the instance cache once, at the start, so on elapsed time alone it is
|
||||
indistinguishable from a model nobody wants any more.
|
||||
|
||||
Do not reduce this to ``backend.generate()``. The control plane sends
|
||||
a complete render contract (pinned gallery seed, synthetic reference,
|
||||
quality controls, chunking, effects); calling the adapter directly
|
||||
silently turns a selected gallery voice into a fresh random take.
|
||||
"""
|
||||
from services import tts_backend # noqa: PLC0415
|
||||
from api.routers.generation import _run_backend_inference, _run_inference # noqa: PLC0415
|
||||
|
||||
kwargs = {
|
||||
key: params[key]
|
||||
for key in (
|
||||
"ref_audio",
|
||||
"ref_text",
|
||||
"instruct",
|
||||
"language",
|
||||
"duration",
|
||||
"description",
|
||||
"speed",
|
||||
)
|
||||
if params.get(key) is not None
|
||||
}
|
||||
language = params.get("language")
|
||||
ref_audio = params.get("ref_audio")
|
||||
ref_text = params.get("ref_text")
|
||||
instruct = params.get("instruct")
|
||||
duration = params.get("duration")
|
||||
num_step = params.get("num_step", 16)
|
||||
guidance_scale = params.get("guidance_scale", 2.0)
|
||||
speed = params.get("speed", 1.0)
|
||||
denoise = params.get("denoise", True)
|
||||
postprocess_output = params.get("postprocess_output", True)
|
||||
used_seed = params.get("seed")
|
||||
effect_preset = params.get("effect_preset", "broadcast")
|
||||
max_chunk_chars = params.get("max_chunk_chars")
|
||||
crossfade_ms = params.get("crossfade_ms")
|
||||
try:
|
||||
with tts_backend.engine_in_use(backend):
|
||||
return backend.generate(text, **kwargs)
|
||||
if isinstance(backend, tts_backend.OmniVoiceBackend):
|
||||
# The OSS default engine has an extended native surface;
|
||||
# preserving it is required for a gallery preview and a
|
||||
# GPU-worker take to share the same voice identity.
|
||||
return _run_inference(
|
||||
backend._model, text, language, ref_audio, ref_text,
|
||||
instruct, duration, num_step, guidance_scale, speed,
|
||||
params.get("t_shift"), denoise, postprocess_output,
|
||||
params.get("layer_penalty_factor"),
|
||||
params.get("position_temperature"),
|
||||
params.get("class_temperature"), used_seed,
|
||||
effect_preset, max_chunk_chars, crossfade_ms,
|
||||
)
|
||||
return _run_backend_inference(
|
||||
backend, text, language, ref_audio, ref_text, instruct,
|
||||
duration, num_step, guidance_scale, speed, denoise,
|
||||
postprocess_output, used_seed, effect_preset,
|
||||
max_chunk_chars, crossfade_ms,
|
||||
)
|
||||
except Exception as exc:
|
||||
from worker import errors as worker_errors # noqa: PLC0415
|
||||
|
||||
|
||||
@@ -33,6 +33,9 @@ _HEARTBEAT_MISS_SECONDS = 90.0
|
||||
# ping is a ~25-second view: current enough to notice a link degrading, long
|
||||
# enough that one slow answer cannot move it.
|
||||
_LATENCY_WINDOW = 5
|
||||
_KNOWN_EXECUTION_DEVICES = frozenset(
|
||||
{"cpu", "cuda", "mps", "mlx", "directml", "rocm", "xpu"}
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
@@ -100,6 +103,21 @@ class ConnectedWorker:
|
||||
return bool(cap.get("supported")) and bool(cap.get("installed", True))
|
||||
return False
|
||||
|
||||
def execution_device(self, engine: str, model_id: str, operation: str) -> str:
|
||||
"""Device used by the exact capability selected for this task."""
|
||||
for cap in self.record.capabilities:
|
||||
if cap.get("engine") != engine:
|
||||
continue
|
||||
if model_id and cap.get("model_id") not in (model_id, "", None):
|
||||
continue
|
||||
if operation and operation not in (cap.get("operations") or [operation]):
|
||||
continue
|
||||
if cap.get("cpu_fallback"):
|
||||
return "cpu"
|
||||
backend = str(cap.get("backend") or "").lower()
|
||||
return backend if backend in _KNOWN_EXECUTION_DEVICES else "cpu"
|
||||
return "cpu"
|
||||
|
||||
def is_warm(self, engine: str, model_id: str) -> bool:
|
||||
return self.capacity.is_resident(engine, model_id)
|
||||
|
||||
|
||||
@@ -2,7 +2,7 @@
|
||||
# Generated by the protocol buffer compiler. DO NOT EDIT!
|
||||
# NO CHECKED-IN PROTOBUF GENCODE
|
||||
# source: worker_v1.proto
|
||||
# Protobuf Python Version: 6.33.5
|
||||
# Protobuf Python Version: 7.35.1
|
||||
"""Generated protocol buffer code."""
|
||||
from google.protobuf import descriptor as _descriptor
|
||||
from google.protobuf import descriptor_pool as _descriptor_pool
|
||||
@@ -11,9 +11,9 @@ from google.protobuf import symbol_database as _symbol_database
|
||||
from google.protobuf.internal import builder as _builder
|
||||
_runtime_version.ValidateProtobufRuntimeVersion(
|
||||
_runtime_version.Domain.PUBLIC,
|
||||
6,
|
||||
33,
|
||||
5,
|
||||
7,
|
||||
35,
|
||||
1,
|
||||
'',
|
||||
'worker_v1.proto'
|
||||
)
|
||||
|
||||
@@ -5,7 +5,7 @@ import warnings
|
||||
|
||||
from . import worker_v1_pb2 as worker__v1__pb2
|
||||
|
||||
GRPC_GENERATED_VERSION = '1.81.1'
|
||||
GRPC_GENERATED_VERSION = '1.83.0'
|
||||
GRPC_VERSION = grpc.__version__
|
||||
_version_not_supported = False
|
||||
|
||||
|
||||
@@ -506,6 +506,9 @@ class Scheduler:
|
||||
model_resident=worker.is_warm(task.engine, task.model_id),
|
||||
model_downloaded=True,
|
||||
input_seconds=float(task.params.get("input_seconds") or 0.0),
|
||||
execution_device=worker.execution_device(
|
||||
task.engine, task.model_id, task.operation
|
||||
),
|
||||
)
|
||||
attempt.renew_lease(budget.accept_seconds, now=now)
|
||||
self._save(task, now=now)
|
||||
@@ -997,6 +1000,10 @@ class Scheduler:
|
||||
text=task.params.get("text"),
|
||||
model_resident=bool(worker and worker.is_warm(task.engine, task.model_id)),
|
||||
input_seconds=float(task.params.get("input_seconds") or 0.0),
|
||||
execution_device=(
|
||||
worker.execution_device(task.engine, task.model_id, task.operation)
|
||||
if worker else None
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
|
||||
@@ -57,6 +57,10 @@ REQUIRED_FEATURES = frozenset({
|
||||
"task_progress_v1",
|
||||
"task_inputs_v1",
|
||||
"remote_model_download_v1",
|
||||
# A generic backend.generate() call accepts the same wire shape but drops
|
||||
# profile conditioning controls. Require the canonical worker render path
|
||||
# so an older peer cannot successfully return a different voice.
|
||||
"remote_tts_render_v1",
|
||||
})
|
||||
|
||||
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
# VoiceStudio
|
||||
|
||||
**The open-source ElevenLabs alternative.** Real-time dictation, zero-shot voice
|
||||
cloning, and cinematic video dubbing — fully local, no API keys, no accounts.
|
||||
cloning, and cinematic video dubbing — fully local, with no cloud API keys or accounts.
|
||||
**646 languages.**
|
||||
|
||||
[](https://hub.docker.com/r/palashdeb/omnivoice-studio)
|
||||
@@ -30,6 +30,14 @@ weights + cache (20 GB+ comfortable), and optionally a GPU — 4 GB VRAM works
|
||||
the entire pipeline runs on CPU, just slower. Pull size: ~5 GB compressed
|
||||
(CUDA/CPU image), ~15 GB for the `:rocm` variant.
|
||||
|
||||
## See it in action
|
||||
|
||||
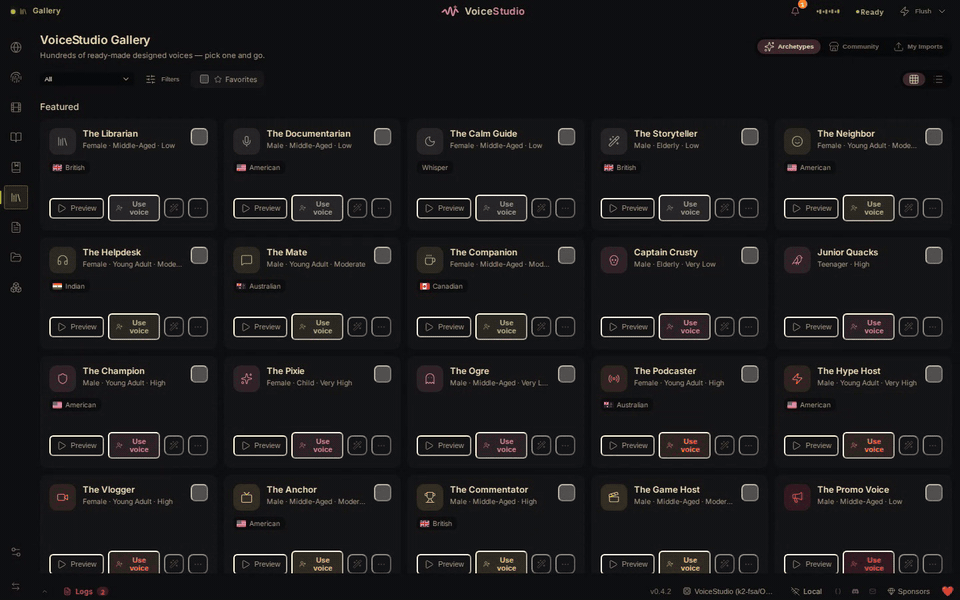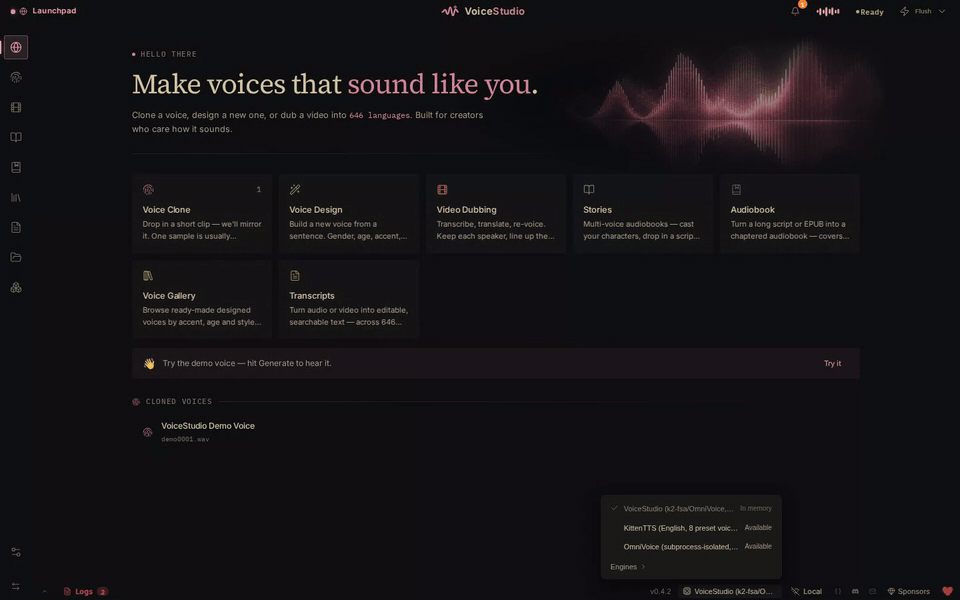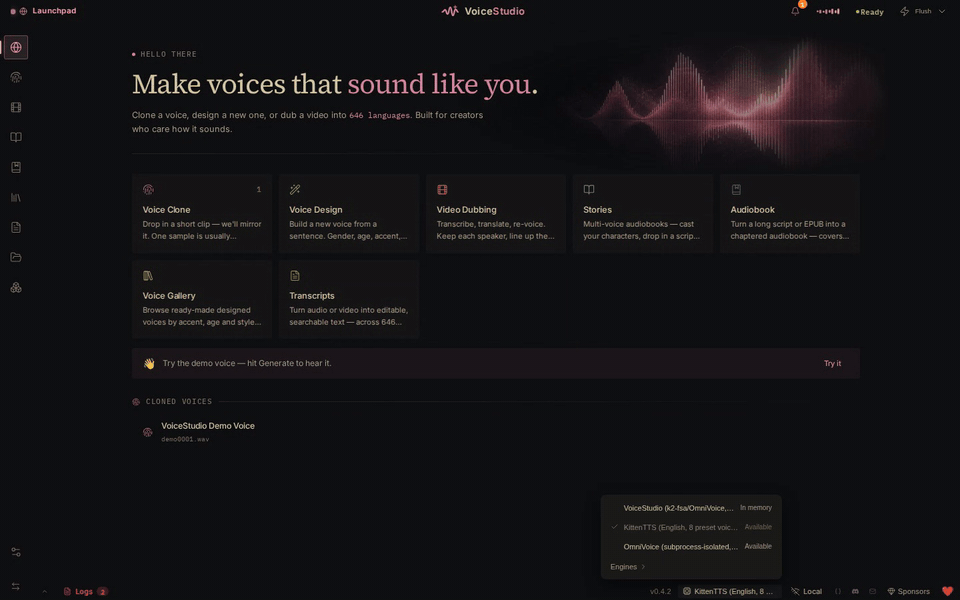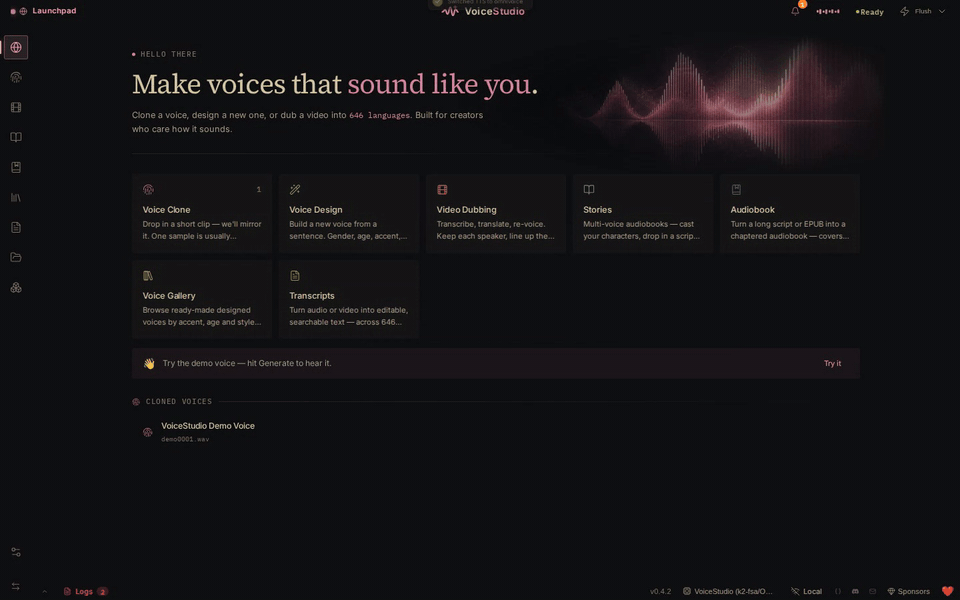
|
||||
|
||||
| Model catalogue | Save a gallery voice |
|
||||
|---|---|
|
||||
| 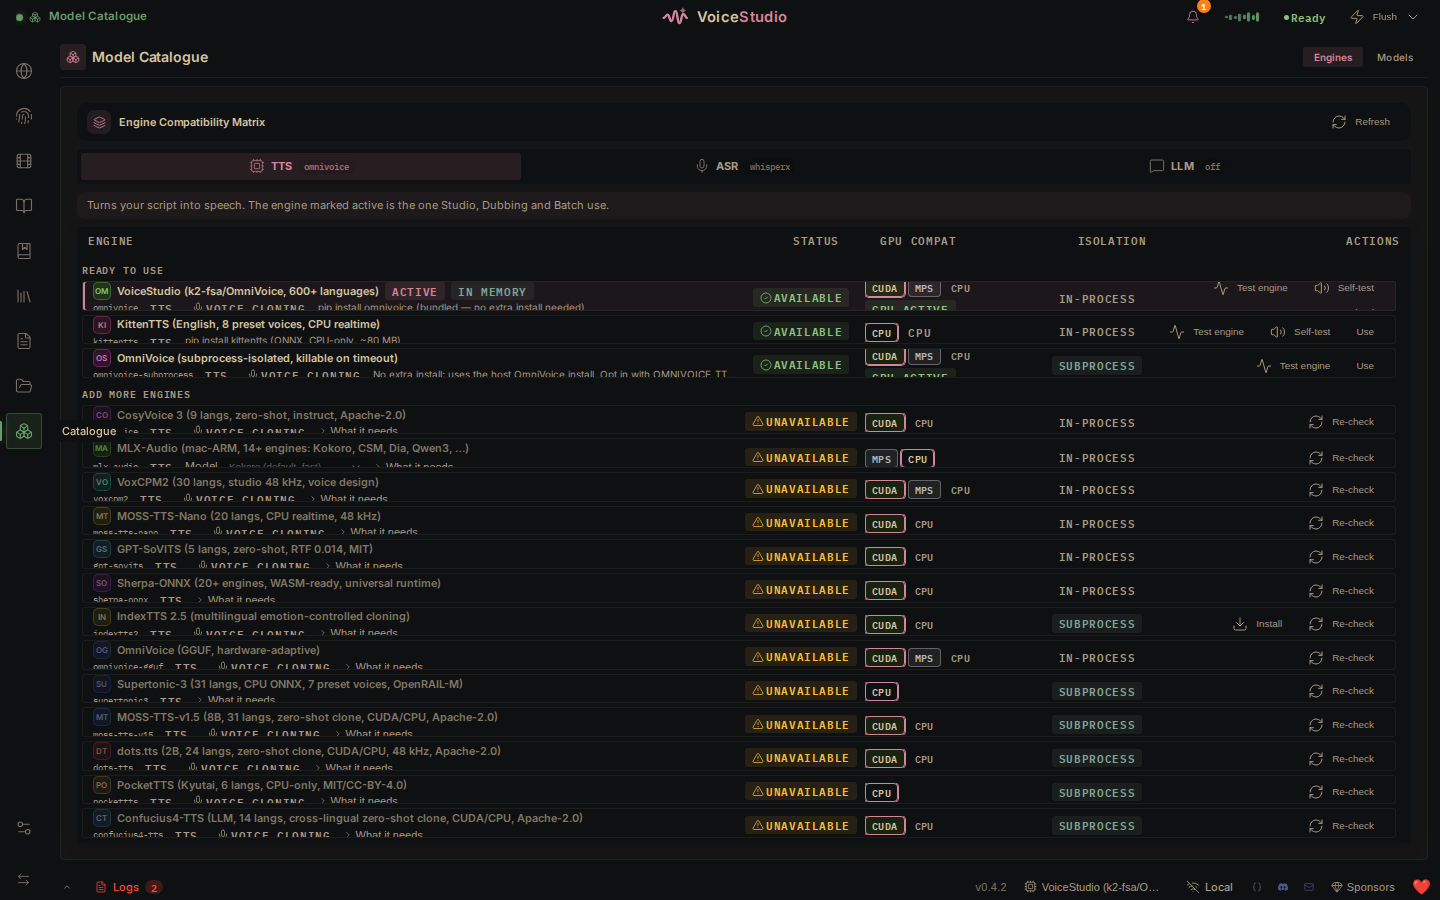 | 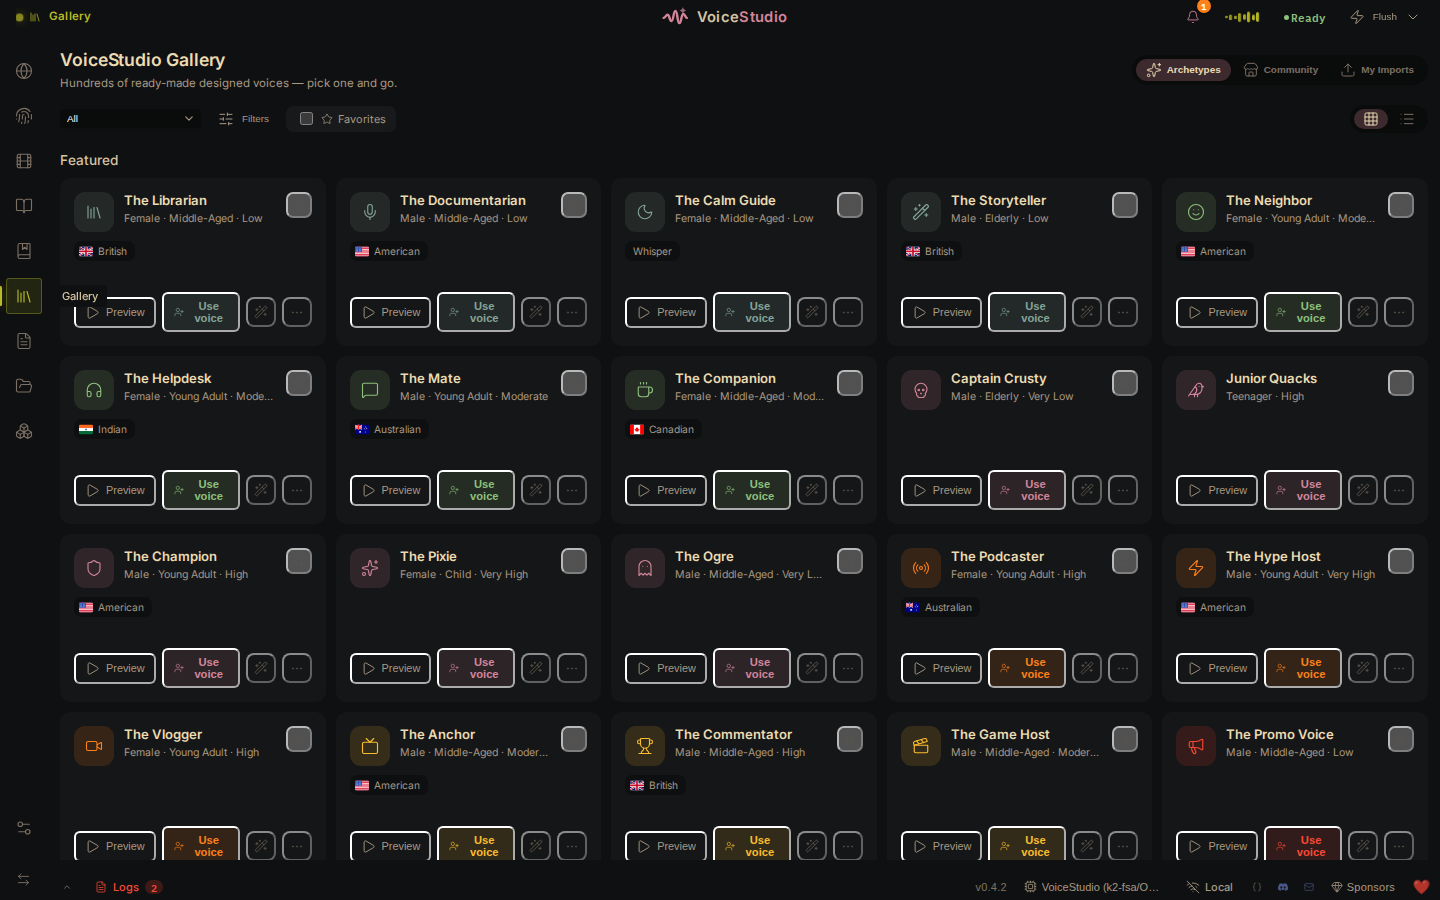 |
|
||||
|
||||
---
|
||||
|
||||
## Quick start (CPU)
|
||||
@@ -90,12 +98,12 @@ There's also a Compose file in the repo with `cpu` / `gpu` / `rocm` profiles
|
||||
|-----|--------------|
|
||||
| `:latest` | **Rolling preview** — latest commit on `main`, at or ahead of the last release. This is the preview channel; pin `:stable` for production. |
|
||||
| `:stable` | Most recent versioned release (updated on every `v*` git tag) |
|
||||
| `:0.4.1` | Exact release version |
|
||||
| `:0.4` | Latest patch within the `0.4` minor |
|
||||
| `:0.5.0` | Exact release version |
|
||||
| `:0.5` | Latest patch within the `0.5` minor |
|
||||
| `:main` | Alias of the same rolling `main` build as `:latest` |
|
||||
| `:sha-xxxxxxx` | A specific commit (produced by manual workflow dispatch) |
|
||||
| `:rocm` | **AMD GPU (ROCm) build** of the rolling preview — the ROCm analogue of `:latest` |
|
||||
| `:stable-rocm`, `:0.4.1-rocm`, `:0.4-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding tags above |
|
||||
| `:stable-rocm`, `:0.5.0-rocm`, `:0.5-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding tags above |
|
||||
|
||||
Preview builds always come from `main` and never version-sort below `:stable`,
|
||||
so upgrades flow naturally. The same images and tags
|
||||
@@ -143,11 +151,17 @@ more), auto-detected and selectable in Settings.
|
||||
- The image ships with `OMNIVOICE_SERVER_MODE=1`, which relaxes the desktop-only
|
||||
loopback-origin gate so the admin UI works through Docker's NAT. Set it to `0`
|
||||
if you front the container with your own loopback auth proxy.
|
||||
- For LAN or internet-facing deployments, set a long random
|
||||
`OMNIVOICE_API_KEY` and pass the same key through the browser's login prompt.
|
||||
A six-digit share PIN is also available for casual LAN access, but it does
|
||||
not authorize administration or dictation; see the
|
||||
[API authentication guide](https://github.com/debpalash/VoiceStudio/blob/main/docs/api-auth.md).
|
||||
|
||||
> **Security:** VoiceStudio ships **no authentication**. Anything that can reach the
|
||||
> URL can use the app. Before exposing it beyond localhost, put it behind a
|
||||
> reverse proxy with auth (Caddy `basic_auth`, nginx + htpasswd) or a private
|
||||
> overlay (Tailscale, ZeroTier).
|
||||
> **Security:** Loopback-only publishing is the safe default. Before exposing
|
||||
> VoiceStudio on a trusted LAN, configure `OMNIVOICE_API_KEY`. On any untrusted
|
||||
> network, plain HTTP is not safe for the API key or session cookie. Keep the
|
||||
> backend on an encrypted private overlay such as Tailscale/ZeroTier; do not
|
||||
> expose it directly to the public internet.
|
||||
|
||||
---
|
||||
|
||||
|
||||
+8
-8
@@ -17,7 +17,7 @@ Phase 4 · The two bets ▓▓▓▓▓▓▓▓▓▓ 6 / 6 ✅
|
||||
Phase 5 · Productisation ░░░░░░░░░░ 0 / 5 🚫 demand-driven
|
||||
|
||||
Design track ▓▓▓▓▓▓▓▓▓░ ongoing · 14 primitives + ~67 migrated inline styles · DubTab/Header/Sidebar/CloneDesignTab drained
|
||||
Performance track ░░░░░░░░░░ not started
|
||||
Performance track ▓▓▓░░░░░░░ underway · profiling, preload, isolated engines + cache-remix I/O
|
||||
Feature-magic track ░░░░░░░░░░ not started
|
||||
Quality track ▓▓░░░░░░░░ 12 smoke tests, 10 error messages rewritten
|
||||
```
|
||||
@@ -193,16 +193,16 @@ None on the critical path to world-class. All are answers to real demand.
|
||||
| Design-system primitives (14) | ✅ | Full inventory above. |
|
||||
| Migrate remaining inline styles | 🟡 | **Four biggest offenders drained 2026-04-20** — DubTab **93 → 2**, Header **24 → 1**, Sidebar **21 → 8**, CloneDesignTab **33 → 0**. All remaining are genuinely dynamic (per-row `--row-accent` CSS custom props in Sidebar, per-bar `height/animationDelay` in WaveBars, `opacity` computed from index in skeleton rows, `fontSize` by prop). New class systems: `.dub-*` (DubTab), `.hq-col-*/.hq-stats__*/.hq-logo-*` (Header), `.sidebar-tile--*/.sidebar__scroll/.history-*--*` (Sidebar), `.clone-*/.label-row--*` (CloneDesignTab). Drag-hover on `.file-drag` and `.dub-idle-drop` now toggles `.is-dragging` instead of mutating styles via DOM. Remaining 119 across the tail (Launchpad, KeyboardCheatsheet, DubSegmentRow, WaveformTimeline, etc.) — less concentrated, lower-leverage. |
|
||||
|
||||
### ⚡ Performance track _(⏳ not started)_
|
||||
### ⚡ Performance track _(🟡 underway)_
|
||||
|
||||
| Item | Status | Current measurement |
|
||||
|------|:---:|------|
|
||||
| Batched TTS (8–16 segments per forward pass) | ⏳ | 1 segment per call today. |
|
||||
| Kill per-segment disk round-trip | ⏳ | `dub_generate.py:132-133` saves + re-reads per segment. |
|
||||
| Cold start ≤1.5 s to first audible sample | ⏳ | Currently 4+ s on Apple Silicon. |
|
||||
| Batched TTS (host-derived width per forward pass) | 🟡 | The batch queue feeds OmniVoice's native variable-length forward pass, with the width derived from device headroom (1 on CPU/low-VRAM hosts, up to 8) and overridable via `OMNIVOICE_DUB_BATCH_WIDTH`; adapters without native batching retain the single-segment fallback. |
|
||||
| Kill per-segment disk round-trip | 🟡 | Long-video assembly stays disk-backed to bound RAM. Unchanged same-rate natural segments now skip the redundant decode → scratch encode → decode cycle; fresh segments still persist once and reload for assembly. |
|
||||
| Cold start ≤1.5 s to first audible sample | 🟡 | Installed models preload in the background and `scripts/bench_pipeline.py` measures cold/warm synthesis; target is not yet verified. |
|
||||
| Speculative regeneration on hover | ⏳ | — |
|
||||
| Crash-sandbox engines (subprocess isolation) | ⏳ | Single CUDA OOM still kills server. |
|
||||
| Interaction budgets (<50 ms UI, <200 ms preview, <4 s first seg) | ⏳ | Not measured. |
|
||||
| Crash-sandbox engines (subprocess isolation) | 🟡 | Killable sidecar engines and opt-in `omnivoice-subprocess` are live; the default in-process engine can still take down the server on a native crash. |
|
||||
| Interaction budgets (<50 ms UI, <200 ms preview, <4 s first seg) | 🟡 | `/ws/tts` reports real TTFA, total generation time and RTF; frontend responsiveness instrumentation exists, but no cross-surface budget gate yet. |
|
||||
| Dedicated dev-week per quarter | ⏳ | Cadence not yet booked. |
|
||||
|
||||
### ✨ Feature-magic track _(⏳ not started)_
|
||||
@@ -220,7 +220,7 @@ None on the critical path to world-class. All are answers to real demand.
|
||||
| Item | Status | Notes |
|
||||
|------|:---:|------|
|
||||
| Every bug ships a regression test | ⏳ | Rule written, not yet enforced in CI. |
|
||||
| Perf regression budget (≤5 % on fixture clip) | ⏳ | No fixture clip yet. |
|
||||
| Perf regression budget (≤5 % on fixture clip) | ✅ | Shipped 2026-08-20 as hardware-independent **operation-count budgets** (`tests/test_perf_operation_budgets.py`) — stricter than 5 %, and CI-stable where wall-clock on varying runners is not: one generate per sentence on `/ws/tts`, zero TTS calls on cached dub re-mixes; zero decode/rewrite and ⌈N/W⌉ `generate_batch` guards activate with their respective fast paths. See docs/performance.md §Performance budgets. |
|
||||
| Accessibility (keyboard-first, WCAG AA, ARIA live regions) | 🟡 | Focus rings token defined; full audit pending. |
|
||||
| Privacy (zero telemetry by default, per-feature opt-in) | ✅ | Enforced in Settings → Privacy tab. |
|
||||
| Docs updated per phase | 🟡 | STRUCTURE.md, ROADMAP.md, ui/README.md current (research/ + design/ retired 2026-07-12). |
|
||||
|
||||
+5
-1
@@ -60,10 +60,14 @@ VoiceStudio/
|
||||
│ └── frontend/ Node-based frontend tests
|
||||
│
|
||||
├── scripts/ ⟵ dev / build / release shell + python scripts
|
||||
│ ├── install.sh universal installer
|
||||
│ ├── install.sh universal installer (macOS/Linux/WSL)
|
||||
│ ├── install.ps1 universal installer (Windows)
|
||||
│ ├── run.sh universal launcher
|
||||
│ ├── smoke-test.sh end-to-end validation
|
||||
│ └── desktop-prod.sh production desktop build
|
||||
|
||||
├── infra/ ⟵ edge/deploy workers (not the Docker deploy path)
|
||||
│ └── install-redirect/ voicestudio.sh/install — UA-sniffing installer worker
|
||||
│
|
||||
├── deploy/ ⟵ Docker deployment configs
|
||||
│ ├── Dockerfile single-stage CUDA image
|
||||
|
||||
+1
-1
@@ -342,7 +342,7 @@ arbitrary path merely because it ends in `/ws/events` or `/ws/transcribe`.
|
||||
| Code | Meaning | What to do |
|
||||
|---|---|---|
|
||||
| **401** | Consumption auth failed — `{"detail": "PIN required"}` or `{"detail": "API key required"}`. | Supply the PIN / key (header, cookie, or query param above). A WebSocket surfaces this as close code **1008**. |
|
||||
| **403** | Authorization failed: loopback/native access was required, cookie Origin/CSRF validation failed, a server-mode mutation lacked an admin credential, or a native path capability was invalid/expired. | A PIN cannot grant admin or filesystem access. Re-authenticate the UI; scripts should use the API-key header; run native operations from the desktop app. |
|
||||
| **403** | Authorization failed: loopback/native access was required, cookie Origin/CSRF validation failed, a server-mode mutation lacked an admin credential, or a native path capability was invalid/expired. | A PIN cannot grant admin or filesystem access. Re-authenticate the UI; scripts should use the API-key header; run native operations from the desktop app. The admin gate names the key only when one can satisfy it: server mode with `OMNIVOICE_API_KEY` configured answers `{"detail": "loopback origin or admin API key required"}` (the bundled UI routes it to the API-key login form); PIN-only/no-key server mode and the desktop build answer `{"detail": "loopback origin required"}` (only loopback can satisfy the gate). |
|
||||
| **429** | A failed administrator-session exchange exceeded its per-client limit, the GPU pool is saturated, or a model download is rate-limited. Ships with `Retry-After`; workload throttles also carry `X-VoiceStudio-Retryable: true`. | Back off for `Retry-After` seconds. For authentication, verify the master before retrying; a correct master is never locked out. |
|
||||
|
||||
---
|
||||
|
||||
@@ -0,0 +1,56 @@
|
||||
# Benchmarks
|
||||
|
||||
Measured numbers per engine and device — how long a generation actually
|
||||
takes on real hardware. Every number here is produced by the in-repo
|
||||
harness, on named hardware, at a named version; nothing is estimated.
|
||||
|
||||
## How numbers are measured
|
||||
|
||||
```bash
|
||||
# stop the app first — a running backend holds a model and skews numbers
|
||||
uv run python scripts/bench_pipeline.py # everything
|
||||
uv run python scripts/bench_pipeline.py tts # just the TTS stage
|
||||
```
|
||||
|
||||
`scripts/bench_pipeline.py` profiles each pipeline stage one at a time,
|
||||
memory-safely: it refuses to start a stage without enough free RAM and
|
||||
unloads models between stages. See [performance.md](performance.md) for
|
||||
what each stage spends its time on.
|
||||
|
||||
The `tts` stage emits the two values this table collects:
|
||||
|
||||
- **RTF** (real-time factor) — seconds of compute per second of generated
|
||||
audio, printed next to each warm measurement. RTF < 1 means faster than
|
||||
real time. Use the **short line (warm)** RTF for the table.
|
||||
- **Peak VRAM** — printed on CUDA only. MPS is unified memory and CPU has
|
||||
no VRAM; subprocess-isolated engines allocate outside the harness's view
|
||||
(it prints `n/a` for them). Leave the column blank in all those cases.
|
||||
|
||||
## Results
|
||||
|
||||
No verified rows yet — this table fills from maintainer runs and community
|
||||
submissions.
|
||||
|
||||
| Engine | Device | RTF (warm) | Peak VRAM (GB) | App version | Source |
|
||||
|---|---|---|---|---|---|
|
||||
| _none yet — contribute yours below_ | | | | | |
|
||||
|
||||
Column meanings: **Engine** — the TTS engine the harness resolved (printed
|
||||
at stage start). **Device** — one string naming what ran the model, e.g.
|
||||
`RTX 3060 12 GB`, `Apple M2 Pro`, `Ryzen 7 5800X (CPU)`. **RTF (warm)** —
|
||||
the short-line warm RTF from the harness. **Peak VRAM** — the harness's
|
||||
CUDA peak, blank on MPS/CPU. **App version** — from `Settings → About`.
|
||||
**Source** — a link to the PR that added the row.
|
||||
|
||||
## Contributing a row
|
||||
|
||||
1. Run the harness on an otherwise-idle machine (app stopped) and copy its
|
||||
summary table.
|
||||
2. Open a PR adding one row using the column meanings above, and paste the
|
||||
raw harness output into the PR description — that PR link becomes the
|
||||
row's **Source**.
|
||||
3. One row per engine+device pair; a newer app version replaces the old row.
|
||||
|
||||
Numbers from different machines aren't directly comparable — that's fine.
|
||||
The point is honest expectations ("this engine on this class of GPU ≈ this
|
||||
fast"), not a leaderboard.
|
||||
@@ -0,0 +1,6 @@
|
||||
# Exporting dubbed video
|
||||
|
||||
Video exports can contain both the source audio and one or more dubbed tracks.
|
||||
VoiceStudio marks the selected dubbed language as the default so ordinary video
|
||||
players and messaging apps play the dub immediately. Choose **Original** in the
|
||||
Default Track control when the source audio should play first instead.
|
||||
@@ -215,6 +215,14 @@ launching the backend (or in **Settings → Credentials**):
|
||||
pro endpoint).
|
||||
- **Microsoft Translator:** `MICROSOFT_API_KEY` (optionally `MICROSOFT_BASE_URL`).
|
||||
|
||||
## Editing workspace
|
||||
|
||||
After transcription, drag the divider between the video/timeline and transcript
|
||||
columns to give either side more room. The divider also works from the keyboard:
|
||||
focus it, use Left/Right Arrow in 5% steps, or Home/End for the minimum/maximum.
|
||||
VoiceStudio remembers the split on this device. Narrow workspaces stack the two
|
||||
panels instead so neither editor becomes unusably small.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- **"The 'google' translation engine needs the optional deep_translator Python
|
||||
|
||||
@@ -0,0 +1,61 @@
|
||||
# Engine guides
|
||||
|
||||
One page per engine: what it's for, what it needs, how to enable it, and its
|
||||
quirks. Select engines in **Model Catalogue → Engines** (or quick-switch with
|
||||
<kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd>), or pin one with
|
||||
`OMNIVOICE_TTS_BACKEND` / `OMNIVOICE_ASR_BACKEND`.
|
||||
|
||||
The compute device (CUDA/ROCm/MPS/CPU) is auto-detected; pin it under
|
||||
**Settings → Performance & Device** (or `OMNIVOICE_DEVICE`) if auto-detect
|
||||
picks wrong — see [performance](../performance.md).
|
||||
|
||||
Measured speed/VRAM numbers live in [benchmarks](../benchmarks.md); what each
|
||||
engine can do expressively in [expressive-speech](../expressive-speech.md);
|
||||
sidecar disk footprints in [disk-usage](disk-usage.md); the bar a new engine
|
||||
must clear in [engine-acceptance](../engine-acceptance.md).
|
||||
|
||||
New to VoiceStudio? Install the app first — [macOS](../install/macos.md)
|
||||
(first launch needs the one-time right-click → **Open** Gatekeeper
|
||||
approval), [Windows](../install/windows.md), [Linux](../install/linux.md),
|
||||
[Docker](../install/docker.md).
|
||||
|
||||
## Text-to-speech
|
||||
|
||||
| Engine | Guide | Runs on | Cloning | Enabled by |
|
||||
|---|---|---|---|---|
|
||||
| VoiceStudio (OmniVoice) — **default** | [omnivoice](omnivoice.md) | CUDA · MPS · CPU | ✅ | installed by default |
|
||||
| VoxCPM2 | [voxcpm2](voxcpm2.md) | CUDA · MPS · CPU | ✅ + voice design | `pip install "voxcpm>=2.0.3"` |
|
||||
| MOSS-TTS-Nano | [moss-tts-nano](moss-tts-nano.md) | CUDA · CPU | ✅ (ref only) | clone + `uv pip install -e .` |
|
||||
| KittenTTS | [kittentts](kittentts.md) | CPU | — (8 preset voices) | `pip install kittentts` |
|
||||
| MLX-Audio (Kokoro, CSM, Dia, …) | [mlx-audio](mlx-audio.md) | Apple Silicon | model-dependent | `pip install mlx-audio` |
|
||||
| CosyVoice 3 | [cosyvoice](cosyvoice.md) | CUDA · CPU | ✅ | clone + requirements |
|
||||
| GPT-SoVITS | [gpt-sovits](gpt-sovits.md) | external server | ✅ | its own API server |
|
||||
| Sherpa-ONNX | [sherpa-onnx](sherpa-onnx.md) | CUDA · CPU | — | `pip install sherpa-onnx` + model dir |
|
||||
| IndexTTS 2.5 | [indextts](indextts.md) | CUDA · CPU | ✅ + emotion | one-click sidecar install |
|
||||
| OmniVoice GGUF | [omnivoice-gguf](omnivoice-gguf.md) | CUDA · MPS · CPU | ✅ | bundled binary |
|
||||
| Supertonic-3 | [supertonic3](supertonic3.md) | CPU | — (7 preset voices) | `uv sync --extra supertonic` + license |
|
||||
| MOSS-TTS-v1.5 (8B) | [moss-tts-v15](moss-tts-v15.md) | CUDA · CPU | ✅ | clone + env var |
|
||||
| dots.tts (2B) | [dots-tts](dots-tts.md) | CUDA · CPU (not Windows) | ✅ | clone + env var |
|
||||
| OmniVoice (subprocess) | [omnivoice-subprocess](omnivoice-subprocess.md) | CUDA · MPS · CPU | ✅ | opt-in pick, no install |
|
||||
| PocketTTS (Kyutai) | [pockettts](pockettts.md) | CPU (not Intel Mac) | ✅ | `uv sync --extra pockettts` + license |
|
||||
| Confucius4-TTS | [confucius4-tts](confucius4-tts.md) | CUDA · CPU | ✅ | clone + env var |
|
||||
|
||||
## Speech-to-text
|
||||
|
||||
| Engine | Guide | Runs on | Best at | Enabled by |
|
||||
|---|---|---|---|---|
|
||||
| WhisperX | [whisperx](whisperx.md) | CUDA · CPU | dubbing (word timestamps + diarization) | installed by default |
|
||||
| Faster-Whisper | [faster-whisper](faster-whisper.md) | CUDA · CPU | general transcription | installed by default |
|
||||
| Faster-Whisper (isolated) | [faster-whisper-isolated](faster-whisper-isolated.md) | CUDA · CPU | unattended batches | opt-in pick |
|
||||
| MLX Whisper | [mlx-whisper](mlx-whisper.md) | Apple Silicon | Mac default | `pip install mlx-whisper` |
|
||||
| PyTorch Whisper | [pytorch-whisper](pytorch-whisper.md) | CUDA · MPS · CPU | ROCm hosts | installed by default |
|
||||
| Parakeet TDT (NeMo) | [nemo-parakeet](nemo-parakeet.md) | CUDA · CPU | 25 languages, fast CPU | separate venv (never the app's) |
|
||||
| Parakeet TDT (MLX) | [parakeet-mlx](parakeet-mlx.md) | Apple Silicon | dictation, 25 EU languages | default on mac-ARM source installs |
|
||||
| Moonshine | [moonshine](moonshine.md) | CPU | edge/low-power, no timestamps | `pip install` (see guide) |
|
||||
| FunASR (SenseVoice) | [funasr](funasr.md) | CUDA · CPU | 50+ languages, inline diarization | `pip install funasr` |
|
||||
| Sherpa-ONNX dictation | [sherpa-onnx-asr](sherpa-onnx-asr.md) | CPU | live streaming dictation | curated model download |
|
||||
| OpenAI-compatible (remote) | [openai-compatible-asr](openai-compatible-asr.md) | network | offloading to a server (audio leaves the machine) | Model Catalogue |
|
||||
|
||||
Speaker diarization is not an engine registry of its own — the dub pipeline
|
||||
uses pyannote (HF-gated; see [diarization](../features/diarization.md)) and
|
||||
FunASR can diarize inline with its `cam++` speaker model.
|
||||
@@ -0,0 +1,61 @@
|
||||
# VoiceStudio — Faster-Whisper (Crash-Isolated) Engine
|
||||
|
||||
The same CTranslate2 Whisper engine as [faster-whisper](faster-whisper.md),
|
||||
run in a **separate child process** ("sidecar"). CTranslate2's GPU teardown
|
||||
can segfault — the endemic faster-whisper crash — and a hung or crashed
|
||||
transcribe in-process takes the whole backend down with it. Isolated, the
|
||||
child can crash or be force-killed to reclaim a hung transcribe and its VRAM
|
||||
while the backend stays up
|
||||
([#730](https://github.com/debpalash/VoiceStudio/issues/730)).
|
||||
|
||||
There is nothing extra to install: the sidecar reuses the app's own venv —
|
||||
only the process boundary is new.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the crash-isolated row, or
|
||||
- pin it with `OMNIVOICE_ASR_BACKEND=faster-whisper-isolated`.
|
||||
|
||||
It is never picked by auto-detect — it's an explicit opt-in escape hatch.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Long batch runs** where one bad file must not kill the backend.
|
||||
- Machines where in-process faster-whisper has crashed or hung before:
|
||||
a sidecar crash fails only that job, and the next transcribe respawns a
|
||||
fresh sidecar automatically.
|
||||
|
||||
## Platform support
|
||||
|
||||
Same as faster-whisper: CUDA float16 or CPU int8 on macOS, Windows, and
|
||||
Linux. The sidecar picks cuda/cpu itself and walks the same
|
||||
float16 → int8_float16 → int8 degrade chain on GPUs without efficient fp16
|
||||
([#551](https://github.com/debpalash/VoiceStudio/issues/551)).
|
||||
|
||||
## Model selection
|
||||
|
||||
- `ASR_MODEL_FASTER` — the shared model selection, same as the in-process
|
||||
engine: set it once and both variants load the same weights.
|
||||
- `ASR_MODEL_FW` — optional sidecar-only override; when set it wins over
|
||||
`ASR_MODEL_FASTER` for this engine. Default `large-v3`.
|
||||
- `ASR_COMPUTE_TYPE` — optional: pin the sidecar to one CTranslate2 compute
|
||||
type instead of the automatic degrade chain.
|
||||
|
||||
Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
## Trade-offs and quirks
|
||||
|
||||
- **Slightly slower per call** than in-process faster-whisper (IPC overhead);
|
||||
the model stays warm inside the sidecar between calls, so the cost is per
|
||||
request, not per chunk of audio.
|
||||
- Word timestamps are Whisper-native (±100–300 ms) — no forced alignment.
|
||||
For dubbing lip-sync, use [whisperx](whisperx.md) or
|
||||
[mlx-whisper](mlx-whisper.md).
|
||||
- If the sidecar dies mid-transcription the job fails with a clear
|
||||
"sidecar crashed" error and the backend stays up — retry to respawn.
|
||||
- **cuDNN 8 is still required on CUDA** — same CTranslate2 requirement as the
|
||||
in-process engine. It's checked up front so a missing cuDNN 8 shows as
|
||||
"unavailable" in Model Catalogue → Engines instead of a sidecar that
|
||||
silently fails every transcribe
|
||||
([#1371](https://github.com/debpalash/VoiceStudio/issues/1371)).
|
||||
@@ -0,0 +1,70 @@
|
||||
# VoiceStudio — Faster-Whisper Engine
|
||||
|
||||
Faster-Whisper runs Whisper on CTranslate2 — the same transcription core
|
||||
WhisperX uses, **without** the wav2vec2 forced-alignment pass. It's the safe
|
||||
cross-platform fallback when whisperx isn't installed, and the capture/dictation
|
||||
fallback on non-Apple machines.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the Faster-Whisper row, or
|
||||
- pin it with `OMNIVOICE_ASR_BACKEND=faster-whisper`.
|
||||
|
||||
Auto-detect only picks it when [whisperx](whisperx.md) is unavailable.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Subtitles, dictation buffers, and batch transcription** where Whisper's
|
||||
native word timing (±100–300 ms) is good enough.
|
||||
- For dubbing lip-sync, prefer [whisperx](whisperx.md) (or
|
||||
[mlx-whisper](mlx-whisper.md) on Apple Silicon) — their forced alignment is
|
||||
an order of magnitude tighter on word boundaries.
|
||||
|
||||
## Platform support
|
||||
|
||||
- **CUDA** — float16, with automatic degradation (below).
|
||||
- **CPU** — int8 on macOS, Windows, and Linux.
|
||||
- **Apple Silicon GPU / ROCm** — not supported: CTranslate2 has no Metal or
|
||||
HIP build, so those hosts run on CPU
|
||||
([#1529](https://github.com/debpalash/VoiceStudio/issues/1529)); auto-detect
|
||||
routes them to mlx-whisper / pytorch-whisper instead.
|
||||
|
||||
## Model selection
|
||||
|
||||
`ASR_MODEL_FASTER` — default `Systran/faster-whisper-large-v3`. Accepts the
|
||||
size aliases (`tiny` … `large-v3`, `distil-large-v3`) or any CTranslate2
|
||||
Whisper repo on HF. Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
Segments are cleaned up by faster-whisper's built-in Silero VAD before
|
||||
transcription.
|
||||
|
||||
## Degradation chains
|
||||
|
||||
- GPUs without efficient fp16 (older Maxwell/Pascal, GTX 16xx, or a
|
||||
CTranslate2/cuDNN mismatch) fail at model construction with a compute-type
|
||||
error; the engine walks float16 → int8_float16 → int8 instead of failing
|
||||
every chunk ([#551](https://github.com/debpalash/VoiceStudio/issues/551)).
|
||||
- A CUDA out-of-memory falls back to CPU (slower, same model and accuracy) —
|
||||
flushing the resident TTS model frees VRAM for GPU-speed ASR
|
||||
([#255](https://github.com/debpalash/VoiceStudio/issues/255)).
|
||||
|
||||
## Quirks
|
||||
|
||||
- **cuDNN 8 required on CUDA** — a missing cuDNN 8 would fast-fail the whole
|
||||
process, so the engine checks up front and reports itself unavailable
|
||||
instead ([#1371](https://github.com/debpalash/VoiceStudio/issues/1371)).
|
||||
pytorch-whisper covers that case on torch's bundled cuDNN 9.
|
||||
- On some hardened Linux kernels the CTranslate2 native library is rejected
|
||||
with "cannot enable executable stack" (an OSError, not an ImportError) —
|
||||
reported as unavailable rather than crashing engine selection
|
||||
([#692](https://github.com/debpalash/VoiceStudio/issues/692)).
|
||||
- CTranslate2's GPU teardown can rarely segfault the process at unload. If
|
||||
you hit that, switch to the crash-isolated variant —
|
||||
[faster-whisper-isolated](faster-whisper-isolated.md)
|
||||
([#730](https://github.com/debpalash/VoiceStudio/issues/730)).
|
||||
- Transcribes are time-bounded: `OMNIVOICE_TRANSCRIBE_CHUNK_TIMEOUT_S`
|
||||
(default 120 s per dub chunk) and `OMNIVOICE_ASR_TRANSCRIBE_TIMEOUT_S`
|
||||
(default 300 s whole-file).
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
@@ -0,0 +1,62 @@
|
||||
# VoiceStudio — FunASR (SenseVoice) Engine
|
||||
|
||||
FunASR drives Alibaba's SenseVoiceSmall with FSMN-VAD: an all-in-one
|
||||
multilingual pipeline — transcription with punctuation and inverse text
|
||||
normalization across **50+ languages**, plus optional **inline speaker
|
||||
diarization** via the cam++ speaker model. It's the opt-in alternative to
|
||||
WhisperX ([#182](https://github.com/debpalash/VoiceStudio/issues/182));
|
||||
WhisperX remains the cross-platform default.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- Install it into the app venv: `uv pip install funasr`.
|
||||
- Then **Model Catalogue → Engines**, ASR tab → **Use** on the FunASR row, or
|
||||
`OMNIVOICE_ASR_BACKEND=funasr`.
|
||||
|
||||
Auto-detect never picks it; it's an explicit opt-in.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Multi-speaker transcription without any HuggingFace token.** This is the
|
||||
only ASR engine with diarization built in: cam++ labels each sentence
|
||||
(`Speaker 1`, `Speaker 2`, ...) in the same pass — no gated pyannote
|
||||
model, no license click-through. Compare
|
||||
[diarization](../features/diarization.md) for the pyannote/WhisperX route
|
||||
and what each buys you.
|
||||
- **Broad language coverage** beyond Whisper's strongest languages, with
|
||||
punctuation included.
|
||||
|
||||
## Not suited for
|
||||
|
||||
- **Lip-sync dubbing** — FunASR returns sentence-level timestamps, not
|
||||
word-level ones. Use [whisperx](whisperx.md) /
|
||||
[mlx-whisper](mlx-whisper.md) when word timing matters.
|
||||
|
||||
## Platform support
|
||||
|
||||
CUDA or CPU, on macOS, Windows, and Linux.
|
||||
|
||||
## Model selection
|
||||
|
||||
| Variable | Default | Role |
|
||||
| --- | --- | --- |
|
||||
| `ASR_MODEL_FUNASR` | `iic/SenseVoiceSmall` | main ASR model |
|
||||
| `ASR_FUNASR_VAD` | `fsmn-vad` | VAD segmentation model |
|
||||
| `ASR_FUNASR_SPK` | `cam++` | speaker model; set to empty (`ASR_FUNASR_SPK=`) to disable diarization and use the dub pipeline's pyannote/heuristic path instead |
|
||||
|
||||
Weights download on first load (through FunASR's own model hub) — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
## Quirks
|
||||
|
||||
- With the speaker model enabled, long recordings are transcribed in **one
|
||||
call** and split by FunASR's internal VAD — cam++ assigns speaker cluster
|
||||
IDs per call, so this is what keeps "Speaker 1" meaning the same person
|
||||
across the whole file.
|
||||
- The engine runs with `spk_mode="vad_segment"`: FunASR 1.3.1's default
|
||||
(`punc_segment`) requires a separate punctuation model and crashes when
|
||||
SenseVoice is loaded without one.
|
||||
- SenseVoice's rich-token markup (language/emotion/event tags around the
|
||||
text) is stripped from the output automatically.
|
||||
- Language detection is automatic (`language: auto`); the detected language
|
||||
is reported per file.
|
||||
@@ -0,0 +1,78 @@
|
||||
# VoiceStudio — GPT-SoVITS Engine
|
||||
|
||||
GPT-SoVITS (RVC-Boss) is one of the most popular open-source voice-cloning
|
||||
systems (57k+ GitHub stars, MIT-licensed). It does zero-shot and few-shot
|
||||
cloning with excellent naturalness in Chinese, English, Japanese, Cantonese,
|
||||
and Korean, and it is very fast (RTF ~0.014 on suitable hardware).
|
||||
|
||||
Unlike VoiceStudio's other engines, GPT-SoVITS does not run inside the app.
|
||||
It ships as a standalone API server, and VoiceStudio connects to it over
|
||||
HTTP.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You already run (or want to run) a GPT-SoVITS server, e.g. with few-shot
|
||||
fine-tuned voices.
|
||||
- You need fast, natural cloning in zh/en/ja/yue/ko.
|
||||
|
||||
## Setup
|
||||
|
||||
1. Install and start the GPT-SoVITS API server (upstream project):
|
||||
|
||||
```bash
|
||||
cd GPT-SoVITS
|
||||
python api_v2.py -a 127.0.0.1 -p 9880 -c GPT_SoVITS/configs/tts_infer.yaml
|
||||
```
|
||||
|
||||
2. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=gpt-sovits`.
|
||||
|
||||
VoiceStudio marks the engine available only when the server responds
|
||||
(2-second reachability probe).
|
||||
|
||||
## Configuration
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_GPTSOVITS_URL` | `http://127.0.0.1:9880` | API server URL |
|
||||
| `OMNIVOICE_TRUSTED_NETWORKS` | (unset) | Required to allow a non-loopback server |
|
||||
|
||||
**Remote servers:** by default VoiceStudio only talks to loopback addresses
|
||||
— part of the local-first guarantee. To point at a server on another
|
||||
machine (e.g. a GPU box on your LAN), add its network to
|
||||
`OMNIVOICE_TRUSTED_NETWORKS`; otherwise the connection is refused as an
|
||||
untrusted endpoint.
|
||||
|
||||
Prefer `https://` (or a private tunnel such as Tailscale/WireGuard) for any
|
||||
non-loopback server: with plain `http://` the text you synthesize and the
|
||||
audio that comes back cross the network unencrypted. VoiceStudio does not
|
||||
disable certificate verification, so a TLS endpoint needs a certificate the
|
||||
system trusts.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 32 kHz mono (server output is resampled if needed).
|
||||
- Cloning passes your reference clip path and optional transcript to the
|
||||
server; the reference path must be readable **by the server process**, so
|
||||
remote servers need the clip on their own filesystem.
|
||||
- Speed control is forwarded as the server's `speed_factor`.
|
||||
- The GPU is whatever the GPT-SoVITS server itself uses (CUDA preferred);
|
||||
VoiceStudio's side is just an HTTP client.
|
||||
|
||||
## Known limits
|
||||
|
||||
- Five languages only; for broader coverage use
|
||||
[OmniVoice](omnivoice.md) ([languages.md](../languages.md)).
|
||||
- No voice design; server availability is your responsibility — if the
|
||||
server stops, generations fail with a "server not reachable" error.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "GPT-SoVITS server not reachable": start the server with the command
|
||||
above, or fix `OMNIVOICE_GPTSOVITS_URL`.
|
||||
- "endpoint is outside loopback or OMNIVOICE_TRUSTED_NETWORKS": see
|
||||
Configuration above.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[expressive-speech.md](../expressive-speech.md).
|
||||
@@ -77,6 +77,14 @@ missing, preventing slow disks or antivirus scans from hiding a valid venv.
|
||||
Set `OMNIVOICE_INDEXTTS_IMPORT_PROBE_TIMEOUT_S` to raise the default 60-second
|
||||
probe limit.
|
||||
|
||||
### Long-text generation
|
||||
|
||||
A long passage can keep `infer()` busy for several minutes. The sidecar emits a
|
||||
keep-alive frame every 5 seconds while it works, so the parent can tell a slow
|
||||
synthesis from a wedged one, and waits up to 900 seconds for a sidecar that has
|
||||
gone genuinely silent. Set `OMNIVOICE_INDEXTTS_RECV_TIMEOUT_S` (minimum 30) to
|
||||
tune that ceiling.
|
||||
|
||||
IndexTTS 2.5 requires a language token. VoiceStudio maps locale codes and
|
||||
language names to the five supported languages and detects Chinese, Japanese,
|
||||
or Arabic script for Auto requests. Ambiguous Latin text defaults to English.
|
||||
@@ -95,9 +103,14 @@ confirm that the configured directory contains:
|
||||
```text
|
||||
pyproject.toml
|
||||
indextts/infer_v2_5.py
|
||||
checkpoints/config_v2_5.yaml
|
||||
checkpoints/config.yaml
|
||||
```
|
||||
|
||||
`IndexTeam/IndexTTS-2.5` ships the model config as `config.yaml`. Earlier
|
||||
installs only worked after hand-renaming it to `config_v2_5.yaml`; both names
|
||||
are accepted, so a renamed checkout keeps working as-is and needs no
|
||||
reinstall.
|
||||
|
||||
### `uv` not found
|
||||
|
||||
Install `uv` from <https://docs.astral.sh/uv/> or configure the bundled binary
|
||||
|
||||
@@ -0,0 +1,75 @@
|
||||
# VoiceStudio — KittenTTS Engine
|
||||
|
||||
KittenTTS (KittenML) is the lightweight English "flash" tier: a 25–80 MB
|
||||
ONNX model with 8 preset voices that runs realtime on any CPU — no torch, no
|
||||
CUDA, no GPU of any kind. Use it when you just need quick English narration
|
||||
(voiceovers, demo reads, short phrases) with no reference sample.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- English-only content where speed and a tiny install matter more than
|
||||
cloning.
|
||||
- Machines with no usable GPU.
|
||||
|
||||
The trade-off against [OmniVoice](omnivoice.md): no voice cloning, English
|
||||
only — but a much faster and much smaller install.
|
||||
|
||||
## Setup
|
||||
|
||||
```bash
|
||||
pip install kittentts
|
||||
```
|
||||
|
||||
Then select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=kittentts`.
|
||||
|
||||
## Voices
|
||||
|
||||
Eight preset voices, four male/female pairs:
|
||||
|
||||
```text
|
||||
expr-voice-2-m expr-voice-2-f (default: expr-voice-2-f)
|
||||
expr-voice-3-m expr-voice-3-f
|
||||
expr-voice-4-m expr-voice-4-f
|
||||
expr-voice-5-m expr-voice-5-f
|
||||
```
|
||||
|
||||
An unknown voice id logs an info message and falls back to the default.
|
||||
|
||||
## Model selection
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_KITTENTTS_MODEL` | `KittenML/kitten-tts-mini-0.8` | HuggingFace checkpoint to load |
|
||||
|
||||
The ~80 MB model downloads from HuggingFace on first use (retried once on a
|
||||
flaky connection). See [downloading-models.md](../downloading-models.md).
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 24 kHz mono.
|
||||
- CPU-only by design — the ONNX graph has no CUDA/MPS path.
|
||||
- Non-English `language` values are ignored with a log line pointing at
|
||||
OmniVoice; reference audio is likewise ignored (no cloning).
|
||||
- **Long-input hardening
|
||||
([#1173](https://github.com/debpalash/VoiceStudio/issues/1173)):** the
|
||||
shipped ONNX graph has a hard 512-token cap, and phonemization can expand
|
||||
text massively (digits especially). VoiceStudio pre-measures every chunk
|
||||
with the model's own tokenizer and splits oversized chunks at word
|
||||
boundaries, so long or digit-heavy inputs no longer abort inside
|
||||
onnxruntime with an opaque "invalid expand shape" error.
|
||||
|
||||
## Known limits
|
||||
|
||||
- English only; no cloning, no voice design, no emotion controls
|
||||
(see [expressive-speech.md](../expressive-speech.md)).
|
||||
- Preset voices only — speed is the one knob.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- Engine unavailable: `pip install kittentts` into VoiceStudio's Python
|
||||
environment and restart.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,76 @@
|
||||
# VoiceStudio — MLX-Audio Engine (Apple Silicon)
|
||||
|
||||
MLX-Audio (Blaizzy/mlx-audio) wraps 14+ TTS engines — Kokoro, CSM, Dia,
|
||||
Qwen3-TTS, Chatterbox, MeloTTS, OuteTTS, and more — behind a single adapter
|
||||
that runs on Apple's MLX framework. It is **Apple Silicon only**: the engine
|
||||
is not shipped on Linux, Windows, or Intel Macs, and a stray wheel on those
|
||||
platforms never reports as available
|
||||
([#390](https://github.com/debpalash/VoiceStudio/issues/390)).
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You're on an M-series Mac and want small, fast models tuned for it.
|
||||
- You want one of the specific hosted models (Kokoro for small multilingual,
|
||||
CSM for cloning, Qwen3-TTS for voice design, Dia for dialogue, …).
|
||||
|
||||
## Setup
|
||||
|
||||
```bash
|
||||
pip install mlx-audio
|
||||
```
|
||||
|
||||
Then select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=mlx-audio`.
|
||||
|
||||
## Model selection
|
||||
|
||||
One backend hosts many models. The curated set:
|
||||
|
||||
| Key | Model | Niche |
|
||||
| --- | --- | --- |
|
||||
| `kokoro` (default) | `mlx-community/Kokoro-82M-bf16` | small multilingual |
|
||||
| `csm` | `mlx-community/csm-1b-8bit` | voice cloning |
|
||||
| `qwen3-tts` | `mlx-community/Qwen3-TTS-12Hz-1.7B-VoiceDesign-4bit` | voice design |
|
||||
| `dia` | `mlx-community/Dia-1.6B` | dialogue |
|
||||
| `chatterbox` | `mlx-community/Chatterbox-TTS-4bit` | expressive |
|
||||
| `melotts` | `mlx-community/MeloTTS-English-v3-MLX` | lightweight VITS |
|
||||
| `outetts` | `mlx-community/Llama-OuteTTS-1.0-1B-4bit` | LM-based |
|
||||
|
||||
Pick a model in the **Model Catalogue → Engines** curated picker
|
||||
([#981](https://github.com/debpalash/VoiceStudio/issues/981)) or set
|
||||
`OMNIVOICE_MLX_AUDIO_MODEL` to either a curated key (`kokoro`) or any full
|
||||
HF repo id. The env var overrides the persisted UI choice.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 24 kHz mono for most hosted models.
|
||||
- **Cloning works only with the `csm` model** — it is the only curated model
|
||||
confirmed to accept a reference clip. Other models silently ignore
|
||||
reference audio, so the engine reports cloning support only when CSM is
|
||||
selected (dub/batch jobs gate on this).
|
||||
- Voice design (text description → voice) is available through the
|
||||
Qwen3-TTS VoiceDesign model.
|
||||
- Language support is per-model (Kokoro ~8 languages, others vary). An
|
||||
unsupported language for Kokoro produces a clear error naming what it
|
||||
does support ([#977](https://github.com/debpalash/VoiceStudio/issues/977))
|
||||
— leave language on Auto or switch to a multilingual engine.
|
||||
|
||||
## Platform notes
|
||||
|
||||
This engine is exempt from cross-platform parity as a platform-only
|
||||
capability behind explicit opt-in: it exists only where Apple's MLX runtime
|
||||
exists. On any other platform the engine picker shows it unavailable with
|
||||
the reason.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- Unavailable on an M-series Mac: `pip install mlx-audio` into
|
||||
VoiceStudio's Python environment; in a packaged app build, MLX's native
|
||||
libraries may fail to load — the engine reports unavailable rather than
|
||||
crashing.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[languages.md](../languages.md),
|
||||
[downloading-models.md](../downloading-models.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,57 @@
|
||||
# VoiceStudio — MLX Whisper Engine
|
||||
|
||||
MLX Whisper runs Whisper on the Apple Silicon GPU via MLX. It exists because
|
||||
CTranslate2 (whisperx / faster-whisper) has **no Metal build** — on a Mac
|
||||
those engines transcribe on the CPU no matter what GPU is present. Measured
|
||||
on an M2 with whisper-large-v3, one 30 s dub chunk: **90.4 s on WhisperX
|
||||
(CPU) vs 20.5 s on MLX (GPU)** — which is why auto-detect picks MLX Whisper
|
||||
on every Apple Silicon machine
|
||||
([#1127](https://github.com/debpalash/VoiceStudio/issues/1127)).
|
||||
|
||||
## Selecting it
|
||||
|
||||
- Nothing to do on Apple Silicon — auto-detect prefers it there.
|
||||
- Or explicitly: **Model Catalogue → Engines**, ASR tab → **Use**, or
|
||||
`OMNIVOICE_ASR_BACKEND=mlx-whisper`.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Dubbing on a Mac** — it layers the same wav2vec2 forced alignment
|
||||
WhisperX uses on top of the GPU transcription, so word timing (±10–30 ms)
|
||||
and therefore lip-sync accuracy are unchanged. Same model, same alignment,
|
||||
~4x the speed.
|
||||
- **Dictation/capture** — the capture path automatically swaps in
|
||||
`mlx-community/whisper-large-v3-turbo` (~5x faster than large-v3) unless a
|
||||
sherpa dictation model or [parakeet-mlx](parakeet-mlx.md) is preferred.
|
||||
|
||||
## Platform support
|
||||
|
||||
**Apple Silicon only.** A shared platform gate refuses Linux, Windows, and
|
||||
Intel Macs before any package import, so a stray `mlx-whisper` wheel on the
|
||||
wrong platform never reports itself available
|
||||
([#390](https://github.com/debpalash/VoiceStudio/issues/390)). All other
|
||||
platforms use the CUDA/CPU engines instead.
|
||||
|
||||
## Model selection
|
||||
|
||||
- `ASR_MODEL` — default `mlx-community/whisper-large-v3-mlx`. Any MLX-format
|
||||
Whisper repo works. Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
- `OMNIVOICE_ALIGN_DEVICE` — force the wav2vec2 aligner's device. The aligner
|
||||
runs on MPS when it can and falls back to CPU; languages without a bundled
|
||||
aligner (~20 major languages have one) keep Whisper's native word
|
||||
timestamps.
|
||||
|
||||
## Quirks
|
||||
|
||||
- Audio is decoded through VoiceStudio's validated ffmpeg rather than the
|
||||
bare `ffmpeg` PATH lookup mlx-whisper would do on its own — a clean
|
||||
from-source install with no system ffmpeg works fine
|
||||
([#479](https://github.com/debpalash/VoiceStudio/issues/479)).
|
||||
- The model is warmed into unified memory in the background, so the first
|
||||
transcribe after startup doesn't pay the load cost.
|
||||
- In a packaged app, a native MLX library that fails to load is reported as
|
||||
"unavailable" (with fallback to another engine) rather than crashing the
|
||||
engine list.
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
@@ -0,0 +1,48 @@
|
||||
# VoiceStudio — Moonshine Engine
|
||||
|
||||
Moonshine is an edge-optimized ASR family built for CPU-only machines.
|
||||
Unlike Whisper it processes variable-length audio (no padding everything to
|
||||
30 s), which keeps latency low on short clips — sub-200 ms class on capture
|
||||
buffers. It's the lightest local option for quick transcription on hardware
|
||||
where even int8 whisper-large is too slow.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- Install one of the runtimes into the app venv:
|
||||
`uv pip install moonshine-onnx` (lighter, tried first) or
|
||||
`moonshine-voice`.
|
||||
- Then **Model Catalogue → Engines**, ASR tab → **Use** on the Moonshine row,
|
||||
or `OMNIVOICE_ASR_BACKEND=moonshine`.
|
||||
|
||||
Auto-detect never picks it; it's an explicit opt-in.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Quick notes and short-clip transcription on low-power CPU machines.**
|
||||
- Environments where a sub-1 GB footprint matters more than word timing or
|
||||
language coverage.
|
||||
|
||||
## Not suited for
|
||||
|
||||
- **Dubbing.** Output is plain text as a **single segment spanning the whole
|
||||
file — no word or segment timestamps** — so there's nothing for lip-sync
|
||||
or subtitle timing to work with. Use a Whisper-family engine or
|
||||
[sherpa-onnx-asr](sherpa-onnx-asr.md) for those jobs.
|
||||
- Multilingual work: results report English; for broad language coverage use
|
||||
[whisperx](whisperx.md) or [funasr](funasr.md).
|
||||
|
||||
## Platform support
|
||||
|
||||
CPU only, by design — macOS, Windows, and Linux. It claims no GPU.
|
||||
|
||||
## Model selection
|
||||
|
||||
`ASR_MODEL_MOONSHINE` — default `moonshine/base`. Weights download on first
|
||||
load — see [downloading-models](../downloading-models.md).
|
||||
|
||||
## Quirks
|
||||
|
||||
- The engine tries `moonshine_onnx` first and falls back to
|
||||
`moonshine_voice` — installing either one is enough.
|
||||
- Segment bounds are synthesized from the audio duration (start 0, end =
|
||||
file length), since the model reports none.
|
||||
@@ -0,0 +1,78 @@
|
||||
# VoiceStudio — MOSS-TTS-Nano Engine
|
||||
|
||||
MOSS-TTS-Nano (OpenMOSS) is the low-resource, broad-language pick: a
|
||||
100M-parameter autoregressive codec LM that runs realtime on a 4-core CPU —
|
||||
no GPU required — with native 48 kHz output and 20 languages under an
|
||||
Apache-2.0 license. It fills the "runs on a fanless laptop" tier while still
|
||||
covering languages like Arabic, Hebrew, Persian, Korean, and Turkish.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- CPU-only or low-power hardware, but you still need cloning and non-English
|
||||
coverage.
|
||||
- Your language is among: Chinese, English, German, Spanish, French,
|
||||
Japanese, Italian, Hebrew, Korean, Russian, Persian, Arabic, Polish,
|
||||
Portuguese, Czech, Danish, Swedish, Hungarian, Greek, Turkish.
|
||||
|
||||
## Setup
|
||||
|
||||
The package is **not on PyPI** — install it from the upstream repo into
|
||||
VoiceStudio's Python environment:
|
||||
|
||||
```bash
|
||||
git clone https://github.com/OpenMOSS/MOSS-TTS-Nano.git
|
||||
cd MOSS-TTS-Nano
|
||||
uv pip install -e .
|
||||
```
|
||||
|
||||
Then select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=moss-tts-nano`.
|
||||
|
||||
## Model selection
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_MOSS_TTS_MODEL` | `OpenMOSS-Team/MOSS-TTS-Nano` | HuggingFace checkpoint to load |
|
||||
|
||||
The first use downloads the weights (retried once on a truncated download).
|
||||
See [downloading-models.md](../downloading-models.md).
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- **Cloning is reference-only**: pass a reference clip. Style instructions,
|
||||
preset speakers, and speed control are not supported and are silently
|
||||
ignored, so mixed-engine call sites keep working.
|
||||
- The model emits 48 kHz stereo; VoiceStudio downmixes to mono, matching the
|
||||
rest of the pipeline (the dub mixer treats TTS output as mono per
|
||||
segment).
|
||||
- Runs on CPU or CUDA.
|
||||
|
||||
## Upstream is unpinned
|
||||
|
||||
The upstream repo is installed straight from git with no pinned release, and
|
||||
the model class it exports has changed before
|
||||
([#1287](https://github.com/debpalash/VoiceStudio/issues/1287)). VoiceStudio
|
||||
therefore verifies that a usable model class actually exists — not just that
|
||||
the package imports — before reporting the engine as ready. If the engine
|
||||
shows unavailable with a "does not expose a usable model class" message,
|
||||
pull the latest upstream and re-run `uv pip install -e .`, or open an issue
|
||||
with the version you have.
|
||||
|
||||
## Known limits
|
||||
|
||||
- No voice design, no instruct, no speed control — cloning from a reference
|
||||
clip only.
|
||||
- Quality sits below the large engines; see
|
||||
[benchmarks.md](../benchmarks.md).
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "moss_tts_nano package not installed": run the clone + `uv pip install -e .`
|
||||
steps above.
|
||||
- Entry-point errors after an upstream update: see "Upstream is unpinned"
|
||||
above.
|
||||
- General issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [languages.md](../languages.md),
|
||||
[expressive-speech.md](../expressive-speech.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,59 @@
|
||||
# VoiceStudio — Parakeet TDT (NVIDIA NeMo) Engine
|
||||
|
||||
NVIDIA's Parakeet TDT via the NeMo toolkit: a FastConformer encoder with a
|
||||
Token-and-Duration Transducer decoder. It beats Whisper large-v3 on English
|
||||
benchmarks (~6% WER) and supports **25 (mostly European) languages** with
|
||||
automatic language detection. The 0.6B model is fast even on CPU — measured
|
||||
RTF 0.08–0.23 on an Apple Silicon M2 CPU (2026-07-02), ~20x faster than
|
||||
faster-whisper large-v3 int8 on the same host.
|
||||
|
||||
## Do not install NeMo into the app venv
|
||||
|
||||
`nemo_toolkit`'s ASR extras pin `transformers>=4.57,<4.58`, which conflicts
|
||||
with VoiceStudio's own `transformers>=5.3` requirement and **will break the
|
||||
backend** (ImportError on startup) if installed into the shared venv. There
|
||||
is currently no safe in-app install path for this engine; in-app isolation
|
||||
is tracked separately.
|
||||
|
||||
If you want the Parakeet models without a separate environment, use these
|
||||
instead — same model family, no NeMo dependency:
|
||||
|
||||
- **Apple Silicon:** [parakeet-mlx](parakeet-mlx.md) (installed by default on
|
||||
mac-ARM source installs).
|
||||
- **Any platform, CPU:** [sherpa-onnx-asr](sherpa-onnx-asr.md) — selectable
|
||||
int8 ONNX exports of Parakeet TDT v2/v3; Whisper Tiny remains the
|
||||
cross-platform dictation default.
|
||||
|
||||
## Selecting it
|
||||
|
||||
Only meaningful if you've set up `nemo_toolkit[asr]` in a **separate,
|
||||
dedicated Python environment** that runs the backend:
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the Parakeet TDT row, or
|
||||
- `OMNIVOICE_ASR_BACKEND=nemo-parakeet`.
|
||||
|
||||
Auto-detect never picks it; it's an explicit opt-in.
|
||||
|
||||
## Best at
|
||||
|
||||
- **English and European-language transcription** where WER matters more
|
||||
than word-level subtitle timing.
|
||||
- **CPU-only hosts** — faster than realtime without any GPU.
|
||||
|
||||
## Platform support
|
||||
|
||||
CUDA or CPU (the old hard CUDA gate was removed — see the RTF numbers
|
||||
above). Availability is a pure dependency check on `nemo.collections.asr`.
|
||||
|
||||
## Model selection
|
||||
|
||||
`ASR_MODEL_NEMO` — default `nvidia/parakeet-tdt-0.6b-v3`. Weights download
|
||||
on first load — see [downloading-models](../downloading-models.md).
|
||||
|
||||
## Quirks
|
||||
|
||||
- Output is a **single segment** for the whole file (NeMo doesn't VAD-split
|
||||
like Whisper), with word timestamps when the model exposes them — fine for
|
||||
dictation and plain transcripts, not ideal for long-form subtitles.
|
||||
- The detected language isn't exposed cleanly by NeMo, so results report
|
||||
`en` regardless of the actual (auto-detected) language.
|
||||
@@ -0,0 +1,83 @@
|
||||
# VoiceStudio — OmniVoice GGUF Engine
|
||||
|
||||
OmniVoice GGUF runs the same OmniVoice model as the [default
|
||||
engine](omnivoice.md), but through a bundled native binary
|
||||
(`bin/omnivoice-tts-<platform>`) loading quantized GGUF weights. It is
|
||||
hardware-adaptive: a probe picks the quantization that fits your machine, so
|
||||
small GPUs and CPU-only hosts get a working OmniVoice instead of a paging,
|
||||
timing-out one.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- Your GPU is below the default engine's 6 GB VRAM floor.
|
||||
- CPU-only machines that still want OmniVoice's voice and language coverage.
|
||||
- You want generation isolated in a separate process (a crash or leak never
|
||||
takes the app down — each generation spawns the binary fresh).
|
||||
|
||||
## Quantization selection
|
||||
|
||||
Weights come from the `Serveurperso/OmniVoice-GGUF` HuggingFace repo, pinned
|
||||
to an exact revision. The hardware probe selects:
|
||||
|
||||
| Hardware | Quant | Approx. VRAM use |
|
||||
| --- | --- | --- |
|
||||
| 12 GB+ VRAM | BF16 | ~1.6 GB (quality-first) |
|
||||
| 4–12 GB VRAM | Q8_0 | ~945 MB (recommended balance) |
|
||||
| 1–4 GB VRAM | Q4_K_M | ~659 MB (minimal footprint) |
|
||||
| CPU-only | Q4_K_M | RAM-bound, latency-tolerable |
|
||||
|
||||
You can override the selection from Settings; overrides are allow-listed
|
||||
against the same table (an F32 reference quant, ~3.2 GB, is override-only).
|
||||
|
||||
## Setup
|
||||
|
||||
Nothing to install: installer and CI builds bundle the binary for your
|
||||
platform. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=omnivoice-gguf`. The quant weights download on first
|
||||
use (see [downloading-models.md](../downloading-models.md)) — install them
|
||||
ahead of time from **Model Catalogue → Models** if you want the first
|
||||
generation to be quick; a long first render is the download, not a hang.
|
||||
|
||||
**Source checkouts:** the repo ships zero-byte placeholders in `bin/` — real
|
||||
binaries come from CI or the installer. The engine detects a placeholder and
|
||||
reports unavailable with instructions
|
||||
([#1172](https://github.com/debpalash/VoiceStudio/issues/1172)) instead of
|
||||
failing at spawn time; build one with
|
||||
`scripts/build-omnivoice-tts.sh --platform <slug>` or use the default
|
||||
in-process engine.
|
||||
|
||||
## Integrity and self-healing
|
||||
|
||||
Before reporting ready, the engine:
|
||||
|
||||
- verifies the binary against the SHA-256 manifest (`bin/checksums.sha256`);
|
||||
- detects macOS Gatekeeper quarantine and prints the exact
|
||||
`xattr -cr '/Applications/VoiceStudio.app'` fix;
|
||||
- restores a missing execute bit (a git clone or zip extract on POSIX can
|
||||
drop `+x`, which used to surface as a permission error mislabeled as
|
||||
out-of-memory — [#437](https://github.com/debpalash/VoiceStudio/issues/437)).
|
||||
The chmod runs only after the SHA check confirms it's the right file.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 24 kHz mono — same model, same rate as in-process OmniVoice.
|
||||
- Cloning from a reference clip (with optional transcript) and style
|
||||
instructions are supported; no voice design.
|
||||
- Same multilingual surface as OmniVoice ([languages.md](../languages.md)).
|
||||
- Because generation runs in another process, the app's own GPU counters
|
||||
don't see its allocations — diagnostics label it accordingly.
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_GGUF_GENERATE_TIMEOUT_S` | (generous built-in) | Per-generation timeout for the spawned binary |
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "GGUF binary missing": this build doesn't bundle the runtime for your
|
||||
platform — use the default engine.
|
||||
- Checksum mismatch or quarantine messages: follow the printed fix, or
|
||||
reinstall.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[performance.md](../performance.md), [disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,105 @@
|
||||
# VoiceStudio — OmniVoice Engine (default)
|
||||
|
||||
OmniVoice (k2-fsa/OmniVoice) is VoiceStudio's default TTS engine — the one a
|
||||
fresh install uses without any configuration. It does zero-shot voice cloning
|
||||
across 600+ languages and outputs 24 kHz mono audio. Voice cloning, dubbing,
|
||||
and dictation all run on it out of the box.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You want cloning plus the broadest language coverage (see
|
||||
[languages.md](../languages.md)).
|
||||
- You have a GPU (CUDA or Apple Silicon MPS) with ~6 GB VRAM or more.
|
||||
- You just installed VoiceStudio — it's already selected.
|
||||
|
||||
For low-VRAM or CPU-only machines, the
|
||||
[OmniVoice GGUF](omnivoice-gguf.md) variant runs the same model through a
|
||||
quantized native binary with a much smaller memory footprint.
|
||||
|
||||
## Requirements
|
||||
|
||||
- Runs on CUDA, MPS (Apple Silicon), or CPU — auto-detected.
|
||||
- Recommended VRAM floor: **6 GB** on a dedicated GPU. This is the only
|
||||
engine with a measured floor: on 4 GB cards (GTX 1650 Ti, Quadro P2000 —
|
||||
issues [#1226](https://github.com/debpalash/VoiceStudio/issues/1226) /
|
||||
[#1222](https://github.com/debpalash/VoiceStudio/issues/1222)) the driver
|
||||
pages to system RAM and a render that should take seconds runs for minutes
|
||||
until the compute budget kills it. The UI warns before you wait; nothing
|
||||
hard-blocks, since short inputs can still fit.
|
||||
- No extra install — the model ships with the app and downloads its weights
|
||||
on first use (see [downloading-models.md](../downloading-models.md)).
|
||||
|
||||
## Selecting the engine
|
||||
|
||||
OmniVoice is the default, so normally there is nothing to do. If you switched
|
||||
away and want it back:
|
||||
|
||||
- **Model Catalogue → Engines**, or
|
||||
- set `OMNIVOICE_TTS_BACKEND=omnivoice`.
|
||||
|
||||
The env var overrides the persisted UI choice.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Weights load lazily on first use and are shared with the rest of the app
|
||||
(dubbing, dictation) — the model is never double-loaded.
|
||||
- On CUDA the model runs fp16 with `torch.compile`; a speech recognizer is
|
||||
co-loaded for the cloning path.
|
||||
- Output is 24 kHz mono; the shared mastering chain (highpass + compressor)
|
||||
is tuned for this rate and applied automatically.
|
||||
- Cloning takes a short reference clip (`ref_audio`); 3–10 seconds is the
|
||||
sweet spot. A transcript of the clip improves conditioning — if the profile
|
||||
has none, VoiceStudio transcribes the clip automatically on first use and
|
||||
saves the result to the profile. A clip with a supplied transcript is limited
|
||||
to 20 seconds so the two stay aligned; trim both to the same passage. Without
|
||||
a transcript, VoiceStudio can search up to 75 seconds in five contiguous,
|
||||
bounded transcription passes and selects the passage with detected speech.
|
||||
Longer clips must be trimmed first. If no spoken words are detected, trim to
|
||||
a clear 3–10 second passage or provide its matching transcript.
|
||||
- Encoded voice references persist on disk (`prompt_cache/` in the app data
|
||||
dir), so the first generation with a known voice after a restart skips the
|
||||
re-encode and any transcription pass. Set `OMNIVOICE_PROMPT_DISK_CACHE=0`
|
||||
to keep the cache in memory only.
|
||||
- Style attributes (`instruct`) and a reference clip can be **combined**:
|
||||
when they agree, the instruct stabilizes cloning for the attributes it
|
||||
names (upstream documents dialect cloning as the canonical case — dialect
|
||||
reference + matching dialect instruct). When they conflict, the reference
|
||||
audio wins.
|
||||
- Inline pronunciation control: Chinese via pinyin with tone numbers
|
||||
(`打ZHE2出售`), English via bracketed CMU phonemes (`[B EY1 S]`). Non-verbal
|
||||
tags like `[laughter]` are covered in
|
||||
[expressive-speech.md](../expressive-speech.md).
|
||||
- Voice design works from attributes (gender, age, pitch, whisper, English
|
||||
accents, Chinese dialects) via the Design tab — no reference audio needed.
|
||||
- Optional FlashInfer acceleration on CUDA: set `OMNIVOICE_FLASHINFER=1`
|
||||
(or `=graph` for CUDA-graph capture, best for one render at a time) after
|
||||
installing the `flashinfer-python` package — see
|
||||
[performance.md](../performance.md). Off by default; if the package is
|
||||
missing or a kernel fails, the app logs why and continues on the standard
|
||||
path.
|
||||
|
||||
## Known limits
|
||||
|
||||
- Voice design understands only the fixed attribute vocabulary — free-form
|
||||
design *prose* is mapped onto those attributes, and wording outside them
|
||||
is ignored. Design is trained on English and Chinese and can be unstable
|
||||
in low-resource languages; for description-driven design in other cases
|
||||
try [VoxCPM2](voxcpm2.md).
|
||||
- Below the 6 GB VRAM floor, expect very slow renders or budget timeouts;
|
||||
prefer [OmniVoice GGUF](omnivoice-gguf.md) or a CPU engine such as
|
||||
[PocketTTS](pockettts.md).
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "Too heavy for the available compute" on a small GPU: see the VRAM floor
|
||||
above — switch to OmniVoice GGUF or close other GPU apps.
|
||||
- First generation is slow: the first call downloads multi-GB weights. To
|
||||
keep the first render quick, install the model ahead of time from
|
||||
**Model Catalogue → Models** — a long first generate is almost always the
|
||||
download, not a hang.
|
||||
- General install issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[performance.md](../performance.md),
|
||||
[expressive-speech.md](../expressive-speech.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,58 @@
|
||||
# VoiceStudio — Parakeet TDT v3 (MLX) Engine
|
||||
|
||||
NVIDIA's Parakeet TDT v3 on the Apple Silicon GPU, via the small pure-Python
|
||||
`parakeet-mlx` package. It gives Macs the Parakeet tier CUDA/CPU users get
|
||||
through NeMo or sherpa-onnx: **25 European languages**, word timestamps from
|
||||
the TDT decoder itself (no wav2vec2 alignment pass needed), ~1.2 GB download,
|
||||
~2 GB unified memory, dictation-grade speed on the GPU.
|
||||
|
||||
Unlike [nemo-parakeet](nemo-parakeet.md) it needs no `nemo_toolkit` (whose
|
||||
transformers pin conflicts with the app's) — it is **installed by default on
|
||||
Apple Silicon source installs since 0.3.22**.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the Parakeet TDT v3
|
||||
(MLX) row, or `OMNIVOICE_ASR_BACKEND=parakeet-mlx`.
|
||||
- **Dictation prefers it automatically**: once the model weights are
|
||||
installed (Model Catalogue → Models — the auto-pick never triggers a
|
||||
download), live dictation/capture uses it whenever your system language is
|
||||
one of the 25 covered European languages. Other languages keep the
|
||||
multilingual Whisper engine, so dictation coverage never regresses.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Live dictation on a Mac** — TDT decoding is fast enough for the capture
|
||||
path, at Parakeet's better-than-Whisper English WER.
|
||||
- **European-language transcription** with word timestamps at a fraction of
|
||||
whisper-large-v3's memory and compute.
|
||||
|
||||
For languages outside the 25 (CJK, Arabic, ...), use
|
||||
[mlx-whisper](mlx-whisper.md) instead.
|
||||
|
||||
## Platform support
|
||||
|
||||
**Apple Silicon only** — the same shared MLX platform gate as mlx-whisper
|
||||
refuses Linux, Windows, and Intel Macs before any import
|
||||
([#390](https://github.com/debpalash/VoiceStudio/issues/390)). It runs on the
|
||||
unified-memory GPU; there is no CPU tier.
|
||||
|
||||
## Model selection
|
||||
|
||||
`ASR_MODEL_PARAKEET_MLX` — default `mlx-community/parakeet-tdt-0.6b-v3`.
|
||||
Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
## Quirks
|
||||
|
||||
- Long files are processed in 120 s chunks internally to bound unified-memory
|
||||
use; short dictation buffers and dub chunks are unaffected.
|
||||
- Parakeet v3 auto-detects among its 25 languages but doesn't expose the
|
||||
pick, so the reported language is the one you requested (or none) — it is
|
||||
never hardcoded to English.
|
||||
- Word timestamps are merged from the decoder's subword tokens — good for
|
||||
subtitles and dictation; for lip-sync-critical dubbing the wav2vec2-aligned
|
||||
engines ([mlx-whisper](mlx-whisper.md), [whisperx](whisperx.md)) remain the
|
||||
accuracy tier.
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
@@ -0,0 +1,87 @@
|
||||
# VoiceStudio — PocketTTS Engine
|
||||
|
||||
PocketTTS (kyutai-labs/pocket-tts, 100M parameters) is the fastest-CPU-render
|
||||
pick: small, low-latency, CPU-only, with zero-shot voice cloning from a
|
||||
reference clip. It covers six languages — English, French, German,
|
||||
Portuguese, Italian, Spanish — with one model per language, and measures
|
||||
roughly 8–9x real-time on an Apple M3 Pro.
|
||||
|
||||
It complements the quality engines: where they fall back to CPU, PocketTTS
|
||||
is built for it. CPU-only is deliberate — upstream observes no GPU speedup
|
||||
for this model.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- CPU-only machines that need fast rendering *and* voice cloning.
|
||||
- Latency-sensitive use (dictation-style, short utterances) in one of the
|
||||
six languages.
|
||||
|
||||
## Setup
|
||||
|
||||
1. Install the optional dependency:
|
||||
|
||||
```bash
|
||||
uv sync --extra pockettts
|
||||
```
|
||||
|
||||
(Or enable it from **Model Catalogue → Engines**.)
|
||||
|
||||
2. **Accept the license in-app**
|
||||
([#1306](https://github.com/debpalash/VoiceStudio/issues/1306)). The code
|
||||
is MIT and the weights are CC-BY-4.0, but the weights are **gated on
|
||||
HuggingFace** behind an access agreement with an acceptable-use clause.
|
||||
VoiceStudio surfaces this before first use: the engine stays unavailable
|
||||
until you review and accept in **Model Catalogue → Engines → PocketTTS**.
|
||||
You also need HuggingFace access to the gated repo (see
|
||||
[downloading-models.md](../downloading-models.md) for token setup).
|
||||
|
||||
3. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=pockettts`.
|
||||
|
||||
## Platform notes
|
||||
|
||||
- Works on Linux, Windows, macOS Apple Silicon — CPU only everywhere.
|
||||
- **Not available on Intel Macs**: the required PyTorch version has no
|
||||
macOS x86_64 wheel. The engine reports this plainly instead of failing
|
||||
mid-install.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 24 kHz mono.
|
||||
- Six languages, one model per language, chosen by the `language` you
|
||||
request; cloning takes a short reference clip.
|
||||
- Runs in a crash-isolated sidecar process (parent Python environment): a
|
||||
wedged generation is hard-killed by a watchdog and its memory reclaimed —
|
||||
something an in-process engine cannot do.
|
||||
- The first use downloads the gated weights; the sidecar heartbeats
|
||||
progress during the download so the watchdog doesn't fire.
|
||||
- **French always renders through the 24-layer checkpoint** (`french_24l`) —
|
||||
pocket-tts ships no 6-layer French model — so French render speed is the
|
||||
24-layer figure (roughly half this page's headline speed, still faster
|
||||
than real-time), not the 6-layer one.
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_POCKETTTS_RECV_TIMEOUT_S` | `600` | Sidecar response deadline in seconds (min 30; cold loads download weights) |
|
||||
| `OMNIVOICE_POCKETTTS_24L` | off | When truthy, load the 24-layer checkpoint for languages that ship one (it/de/es/pt/fr) instead of the 6-layer default. Better prosody at roughly 2x render time (still faster than real-time); no effect where no 24-layer model exists (e.g. English). Opt-in: the default stays the fast model. French always uses `french_24l` — pocket-tts ships no 6-layer French model and rejects `language="french"` |
|
||||
|
||||
## Known limits
|
||||
|
||||
- No voice design, no emotion controls
|
||||
(see [expressive-speech.md](../expressive-speech.md)).
|
||||
- Six languages only — for broader coverage use
|
||||
[OmniVoice](omnivoice.md) ([languages.md](../languages.md)).
|
||||
- Revoking the license acceptance takes effect immediately, without a
|
||||
restart — subsequent generations refuse.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "pocket_tts package not installed": run the `uv sync` above.
|
||||
- "license not accepted": open **Model Catalogue → Engines → PocketTTS**
|
||||
and review/accept.
|
||||
- Timeouts on a slow connection: raise
|
||||
`OMNIVOICE_POCKETTTS_RECV_TIMEOUT_S` for the first (download-heavy) run.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[performance.md](../performance.md), [disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,63 @@
|
||||
# VoiceStudio — PyTorch Whisper Engine
|
||||
|
||||
Whisper through the plain `transformers` pipeline, riding torch itself. No
|
||||
extra install — transformers ships with the app — and because it runs on
|
||||
torch's own stack (including torch's bundled cuDNN 9), it works on machines
|
||||
where the CTranslate2 engines can't load. It is also the engine that
|
||||
genuinely uses **AMD ROCm** GPUs, so auto-detect picks it on ROCm hosts
|
||||
([#1529](https://github.com/debpalash/VoiceStudio/issues/1529)).
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the PyTorch Whisper
|
||||
row, or `OMNIVOICE_ASR_BACKEND=pytorch-whisper`.
|
||||
- `OMNIVOICE_ASR_BACKEND=omnivoice` is accepted as a compatibility alias and
|
||||
selects this same PyTorch-native ASR path on ROCm hosts.
|
||||
- Auto-detect picks it on ROCm, and as the last resort everywhere else.
|
||||
|
||||
## Best at
|
||||
|
||||
- **ROCm dubbing/transcription** — the only Whisper engine that uses the HIP
|
||||
GPU (CTranslate2 has no HIP build, MLX is Apple-only).
|
||||
- **Rescue engine** when whisperx/faster-whisper can't load — e.g. the
|
||||
missing-cuDNN-8 case
|
||||
([#255](https://github.com/debpalash/VoiceStudio/issues/255)) — since it
|
||||
needs neither CTranslate2 nor cuDNN 8.
|
||||
|
||||
For lip-sync-grade word timing prefer [whisperx](whisperx.md) or
|
||||
[mlx-whisper](mlx-whisper.md); this engine returns the pipeline's own word
|
||||
timestamps.
|
||||
|
||||
## Platform support
|
||||
|
||||
CUDA, Apple Silicon (MPS), ROCm (HIP), and CPU — wherever torch runs, on
|
||||
macOS, Windows, and Linux.
|
||||
|
||||
## Model selection
|
||||
|
||||
`OMNIVOICE_PYTORCH_ASR_MODEL` — default `openai/whisper-large-v3-turbo`. Any
|
||||
transformers-format Whisper repo works. Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
## VRAM preflight
|
||||
|
||||
whisper-large-v3-turbo needs roughly 3.2 GiB before generation adds its
|
||||
workspace; loading it onto a nearly-full card "succeeds" and then the first
|
||||
transcribe OOMs with zero segments. So on CUDA the engine checks free VRAM
|
||||
against a 5 GB budget before loading and uses the CPU instead when the card
|
||||
is too full (flush the TTS model to restore GPU-speed ASR). Disable with
|
||||
`OMNIVOICE_ASR_VRAM_PREFLIGHT=0`.
|
||||
|
||||
## Quirks
|
||||
|
||||
- If the pipeline fails to import (`AutoFeatureExtractor` errors), the cause
|
||||
is either an incomplete transformers install or a torch/torchvision
|
||||
version mismatch — the error message names the exact reinstall command;
|
||||
the trio has to move together at the pinned versions
|
||||
([#549](https://github.com/debpalash/VoiceStudio/issues/549),
|
||||
[#1376](https://github.com/debpalash/VoiceStudio/issues/1376)).
|
||||
- Transcribes are time-bounded like every local engine:
|
||||
`OMNIVOICE_TRANSCRIBE_CHUNK_TIMEOUT_S` (default 120 s per dub chunk),
|
||||
`OMNIVOICE_ASR_TRANSCRIBE_TIMEOUT_S` (default 300 s whole-file).
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
@@ -0,0 +1,74 @@
|
||||
# VoiceStudio — Sherpa-ONNX Dictation Engine
|
||||
|
||||
The k2-fsa/sherpa-onnx ONNX runtime as a **live dictation** engine: small
|
||||
int8 models that transcribe faster than realtime on CPU, with identical
|
||||
behavior on macOS (arm64 + x86_64), Windows, and Linux — no CUDA dependency.
|
||||
Streaming models emit partial text frame-by-frame as you speak; offline
|
||||
models re-transcribe a growing buffer on a short cadence, so you see live
|
||||
partials either way.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- Ensure `sherpa-onnx` is installed (`uv add sherpa-onnx` on source installs).
|
||||
- Pick a dictation model in the app (Model Catalogue → Models lists the
|
||||
selectable set below), or **Model Catalogue → Engines**, ASR tab → **Use**, or
|
||||
pin `OMNIVOICE_ASR_BACKEND=sherpa-onnx-asr`.
|
||||
- `OMNIVOICE_SHERPA_ASR_MODEL` selects the model — default
|
||||
`sherpa-whisper-tiny`.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Live dictation on CPU** — the whole point of this engine. Fast partials,
|
||||
automatic endpointing on silence, no GPU required.
|
||||
- It also honors the regular offline `transcribe` contract, so any of its
|
||||
models can transcribe a file — plain text, single segment, no word
|
||||
timestamps, which makes it a dictation/notes tool rather than a dubbing
|
||||
engine.
|
||||
|
||||
## The 7 selectable models
|
||||
|
||||
| Id | Type | Languages | Download |
|
||||
| --- | --- | --- | --- |
|
||||
| `sherpa-parakeet-tdt-v3` | offline | 25 European languages | 0.67 GB |
|
||||
| `sherpa-parakeet-tdt-v2` | offline | English | 0.66 GB |
|
||||
| `sherpa-zipformer-bilingual-zh-en` | streaming | Chinese + English | 0.20 GB |
|
||||
| `sherpa-paraformer-bilingual-zh-en` | streaming | Chinese + English | 0.24 GB |
|
||||
| `sherpa-zipformer-en-20m` | streaming | English | 0.044 GB |
|
||||
| `sherpa-zipformer-zh-14m` | streaming | Chinese | 0.025 GB |
|
||||
| `sherpa-whisper-tiny` (default, recommended) | offline | 90+ languages (auto-detect) | 0.104 GB |
|
||||
|
||||
Sizes are measured on-disk download sizes. Weights are int8 ONNX checkpoints
|
||||
that download on first use through the same HF cache as everything else —
|
||||
see [downloading-models](../downloading-models.md). Peak RAM for the 0.6B
|
||||
Parakeets is noticeably higher than their download size (onnxruntime's arena
|
||||
allocator holds onto freed blocks).
|
||||
|
||||
## Platform support
|
||||
|
||||
CPU on every platform, by the strict cross-platform default-parity rule. The
|
||||
[upstream CPU wheels](https://k2-fsa.github.io/sherpa/onnx/python/install.html)
|
||||
cover Linux, macOS, and Windows, and upstream documents Whisper as a
|
||||
[supported non-streaming model family](https://k2-fsa.github.io/sherpa/onnx/pretrained_models/whisper/index.html).
|
||||
`OMNIVOICE_SHERPA_ASR_PROVIDER` can override the ONNX provider on a verified
|
||||
GPU build, but the default never diverges.
|
||||
|
||||
## Tuning
|
||||
|
||||
- `OMNIVOICE_SHERPA_ASR_THREADS` — decode threads (default 2; the 0.6B
|
||||
Parakeets automatically use up to 4 when the host has the cores, so decode
|
||||
keeps ahead of the speaker).
|
||||
- `OMNIVOICE_DICTATION_ENDPOINT_R1` / `OMNIVOICE_DICTATION_ENDPOINT_R2` —
|
||||
streaming endpoint rules in seconds (defaults 1.0 / 0.6: text commits
|
||||
~0.6 s after you stop speaking). Applied without a restart.
|
||||
|
||||
## Quirks
|
||||
|
||||
- The recognizer is **pre-warmed in the background** so the first dictation
|
||||
session doesn't pay the 1.3–2.5 s ONNX session load
|
||||
([#888](https://github.com/debpalash/VoiceStudio/issues/888)); it's then
|
||||
shared warm across sessions.
|
||||
- On Apple Silicon, installing the [parakeet-mlx](parakeet-mlx.md) model
|
||||
makes dictation prefer the GPU Parakeet automatically for the 25 covered
|
||||
languages; an explicitly selected sherpa model still wins.
|
||||
- The offline `transcribe` path reports `language: auto` — per-file language
|
||||
detection is only meaningful for the Whisper Tiny model.
|
||||
@@ -0,0 +1,75 @@
|
||||
# VoiceStudio — Sherpa-ONNX Engine
|
||||
|
||||
Sherpa-ONNX (k2-fsa/sherpa-onnx) is a unified C++ ONNX runtime that wraps
|
||||
20+ TTS model families (VITS, MeloTTS, Piper, Kokoro, Matcha, and more)
|
||||
behind one API, with pre-built wheels for Linux, Windows, and macOS (x86 and
|
||||
ARM). You bring the model: point VoiceStudio at any downloaded sherpa-onnx
|
||||
TTS model directory.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You want a specific community model (e.g. a Piper or VITS voice for your
|
||||
language) that no other engine hosts.
|
||||
- You need a dependable CPU engine with optional CUDA acceleration.
|
||||
|
||||
## Setup
|
||||
|
||||
1. Install the runtime:
|
||||
|
||||
```bash
|
||||
pip install sherpa-onnx
|
||||
```
|
||||
|
||||
2. Download a TTS model from the
|
||||
[sherpa-onnx releases](https://github.com/k2-fsa/sherpa-onnx/releases)
|
||||
and unpack it somewhere permanent.
|
||||
|
||||
3. Point VoiceStudio at the model directory and restart:
|
||||
|
||||
```bash
|
||||
export OMNIVOICE_SHERPA_MODEL=/path/to/model-dir
|
||||
```
|
||||
|
||||
4. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=sherpa-onnx`.
|
||||
|
||||
The directory must contain `model.onnx` and `tokens.txt`. Sherpa-ONNX ships
|
||||
no bundled default model, so the engine reports unavailable — with the
|
||||
reason — until `OMNIVOICE_SHERPA_MODEL` points at a valid directory. (Before
|
||||
this gate, selecting the engine unconfigured produced a failure mislabeled
|
||||
as out-of-memory —
|
||||
[#919](https://github.com/debpalash/VoiceStudio/issues/919).)
|
||||
|
||||
## Configuration
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_SHERPA_MODEL` | (unset) | Directory containing `model.onnx` + `tokens.txt` |
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output defaults to 22.05 kHz (the VITS default); once a model is loaded,
|
||||
its own sample rate is used.
|
||||
- CPU is the universal baseline; the CUDA onnxruntime provider is available
|
||||
on Linux/Windows installs.
|
||||
- **No cloning**: voices come from the model itself. Multi-speaker VITS
|
||||
models select a voice by numeric speaker id; speed is supported.
|
||||
- Languages depend entirely on the model you download.
|
||||
|
||||
## Known limits
|
||||
|
||||
- One model at a time — switching models means changing
|
||||
`OMNIVOICE_SHERPA_MODEL` and restarting.
|
||||
- No voice design, no reference-audio cloning, no emotion controls
|
||||
(see [expressive-speech.md](../expressive-speech.md)).
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "OMNIVOICE_SHERPA_MODEL not set" / "No model.onnx in …": follow Setup
|
||||
above — the variable must point at the *unpacked* model directory, not
|
||||
the archive.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[languages.md](../languages.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,76 @@
|
||||
# VoiceStudio — Supertonic-3 Engine
|
||||
|
||||
Supertonic-3 (Supertone Inc.) is a ~99M-parameter ONNX TTS engine covering
|
||||
31 languages with 7 preset voices at native 44.1 kHz. It is CPU-only by
|
||||
design — pure ONNX Runtime on the CPU execution provider, with no CUDA or
|
||||
MPS path in the upstream SDK — and runs in its own sidecar process so
|
||||
crashes and cold init never block the rest of VoiceStudio.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- Broad language coverage on machines with no usable GPU.
|
||||
- Preset-voice narration at a higher sample rate than the default engine.
|
||||
|
||||
## Setup
|
||||
|
||||
1. Install the optional dependency into VoiceStudio's environment:
|
||||
|
||||
```bash
|
||||
uv sync --extra supertonic
|
||||
```
|
||||
|
||||
(Or enable it from **Model Catalogue → Engines**, which installs the
|
||||
pinned `supertonic` wheel for you.)
|
||||
|
||||
2. **Accept the license in-app.** First use is gated behind an explicit
|
||||
acceptance dialog: the inference SDK is MIT, but the model weights are
|
||||
**OpenRAIL-M**, which carries use restrictions. The engine stays
|
||||
unavailable until you review and accept in **Model Catalogue → Engines →
|
||||
Supertonic-3**.
|
||||
|
||||
3. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=supertonic3`.
|
||||
|
||||
The first synthesis cold-downloads ~400 MB of model weights, pinned to an
|
||||
exact HuggingFace revision SHA so the bytes match what the SDK was validated
|
||||
against. See [downloading-models.md](../downloading-models.md).
|
||||
|
||||
## Voices
|
||||
|
||||
Seven preset voices are surfaced: `M1` (default), `M3`, `M4`, `M5`, `F3`,
|
||||
`F4`, `F5`. The SDK itself accepts the full `M1`–`M5` / `F1`–`F5` set if a
|
||||
caller passes one explicitly; unknown ids fall back to the default with a
|
||||
log line.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 44.1 kHz mono.
|
||||
- Runs as a long-lived sidecar in the parent Python environment (its
|
||||
dependencies — onnxruntime, numpy, soundfile — already match
|
||||
VoiceStudio's pins); subsequent calls reuse the warm ONNX session.
|
||||
- `speed` is clamped to 0.7–2.0; quality steps clamp to 5–12.
|
||||
- Language is an ISO 639-1 code; Auto engages the SDK's multilingual
|
||||
fallback.
|
||||
|
||||
## Known limits
|
||||
|
||||
- **No cloning and no voice design** — preset voices only. Dub/batch jobs
|
||||
that need cloning won't select it.
|
||||
- CPU-only: hardware acceleration is a property of the upstream SDK, not a
|
||||
VoiceStudio limitation.
|
||||
- OpenRAIL-M weights are not covered by VoiceStudio's blanket
|
||||
commercial-use statement — review the model license terms in the
|
||||
acceptance dialog.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "supertonic package not installed": run the `uv sync` above or enable
|
||||
from the Model Catalogue.
|
||||
- "license not accepted": open **Model Catalogue → Engines → Supertonic-3**
|
||||
and accept.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[languages.md](../languages.md),
|
||||
[expressive-speech.md](../expressive-speech.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,76 @@
|
||||
# VoiceStudio — VoxCPM2 Engine
|
||||
|
||||
VoxCPM2 (OpenBMB) is the studio-quality option: native 48 kHz output,
|
||||
zero-shot voice cloning, and — uniquely among VoiceStudio's engines —
|
||||
**voice design**: creating a synthetic voice from a text description
|
||||
("young female, warm tone, British accent") with no reference audio at all.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You want voice design without a reference clip.
|
||||
- You want the highest output sample rate (48 kHz vs OmniVoice's 24 kHz).
|
||||
- Your language is among its 30 supported languages: Arabic, Burmese,
|
||||
Chinese, Danish, Dutch, English, Finnish, French, German, Greek, Hebrew,
|
||||
Hindi, Indonesian, Italian, Japanese, Khmer, Korean, Lao, Malay,
|
||||
Norwegian, Polish, Portuguese, Russian, Spanish, Swahili, Swedish,
|
||||
Tagalog, Thai, Turkish, Vietnamese.
|
||||
|
||||
## Requirements
|
||||
|
||||
- Python ≥ 3.10, PyTorch ≥ 2.5.
|
||||
- CUDA ≥ 12 recommended for full speed; MPS (Apple Silicon) and CPU also
|
||||
work.
|
||||
|
||||
## Setup
|
||||
|
||||
Install the package into VoiceStudio's Python environment:
|
||||
|
||||
```bash
|
||||
pip install "voxcpm>=2.0.3"
|
||||
```
|
||||
|
||||
That is a version **floor**, not a pin — an older install still works, but
|
||||
the engine logs an upgrade hint at load time. Then select the engine via
|
||||
**Model Catalogue → Engines** or `OMNIVOICE_TTS_BACKEND=voxcpm2`.
|
||||
|
||||
## Model selection
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_VOXCPM_MODEL` | `openbmb/VoxCPM2` | HuggingFace checkpoint to load |
|
||||
|
||||
The first use downloads a multi-GB checkpoint from HuggingFace. A download
|
||||
interrupted near the end used to abort the load outright
|
||||
([#1224](https://github.com/debpalash/VoiceStudio/issues/1224)); the load is
|
||||
now retried once with a fresh client. See
|
||||
[downloading-models.md](../downloading-models.md).
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- **Voice design:** provide a description and no reference audio.
|
||||
- **Cloning:** the reference clip is prepared before use (edge-silence trim
|
||||
and length cap) so dead air in a raw clip doesn't condition the output; on
|
||||
any prep problem the raw clip is used as-is.
|
||||
- **Style instructions** are passed as an inline prefix to the text.
|
||||
- VoxCPM2 emits mastered, studio-grade audio, so VoiceStudio **skips its
|
||||
shared mastering chain** (which is tuned for 24 kHz engines) — only benign
|
||||
loudness normalization applies.
|
||||
- A trailing-silence guard trims long near-silent tails from generations,
|
||||
keeping a short natural tail.
|
||||
|
||||
## Known limits
|
||||
|
||||
- Slower than the lightweight CPU engines — see
|
||||
[benchmarks.md](../benchmarks.md) and [performance.md](../performance.md).
|
||||
- Language coverage is 30 languages; for anything else use the default
|
||||
[OmniVoice](omnivoice.md) engine ([languages.md](../languages.md)).
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- Engine shows unavailable: the `voxcpm` package isn't installed — run the
|
||||
`pip install` above and restart VoiceStudio.
|
||||
- Repeated first-download failures: check connectivity/HF access, then see
|
||||
[install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [expressive-speech.md](../expressive-speech.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,80 @@
|
||||
# VoiceStudio — WhisperX Engine
|
||||
|
||||
WhisperX is the default ASR engine on CUDA and plain-CPU hosts: faster-whisper
|
||||
(CTranslate2) transcription plus a **wav2vec2 forced-alignment** pass that
|
||||
snaps word boundaries to ±10–30 ms (Whisper's own timestamps are ±100–300 ms).
|
||||
That word timing is what dubbing lip-sync depends on, which is why auto-detect
|
||||
prefers it wherever CTranslate2 can use the GPU.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the WhisperX row, or
|
||||
- pin it with `OMNIVOICE_ASR_BACKEND=whisperx` (the env var always wins over
|
||||
the Settings pick; with neither set, auto-detect chooses per-hardware).
|
||||
|
||||
## Best at
|
||||
|
||||
- **Dubbing** — the forced alignment is the accuracy tier lip-sync needs.
|
||||
- **Batch transcription** with word-level subtitles.
|
||||
- Multi-speaker work: it pairs with pyannote speaker diarization — see
|
||||
[diarization](../features/diarization.md).
|
||||
|
||||
## Platform support
|
||||
|
||||
| Host | What happens |
|
||||
| --- | --- |
|
||||
| NVIDIA CUDA | GPU, float16 (degrades automatically, see below) |
|
||||
| CPU (any OS) | int8 — works, but slow for large-v3 |
|
||||
| Apple Silicon | CPU only — CTranslate2 has no Metal build, so auto-detect prefers [mlx-whisper](mlx-whisper.md) there ([#1127](https://github.com/debpalash/VoiceStudio/issues/1127)) |
|
||||
| AMD ROCm | CPU only — CTranslate2 has no HIP build, so auto-detect prefers [pytorch-whisper](pytorch-whisper.md) there ([#1529](https://github.com/debpalash/VoiceStudio/issues/1529)) |
|
||||
|
||||
## Model selection
|
||||
|
||||
- `ASR_MODEL_WHISPERX` — default `large-v3`. Accepts the usual size aliases
|
||||
(`tiny` … `large-v3`, `distil-large-v3`) or a full HF repo id. Weights
|
||||
download on first load — see [downloading-models](../downloading-models.md).
|
||||
- `OMNIVOICE_ALIGN_DEVICE` — force the wav2vec2 aligner's device. Aligners
|
||||
exist for ~20 major languages; other languages keep Whisper's native word
|
||||
timestamps instead of failing.
|
||||
|
||||
## VRAM preflight and degradation
|
||||
|
||||
Loading fp16 large-v3 onto a nearly-full 8 GB card dies as a *native* CUDA
|
||||
abort — no Python exception, the whole backend goes down
|
||||
([#723](https://github.com/debpalash/VoiceStudio/issues/723)). So before every
|
||||
load the engine checks free VRAM against per-compute-type budgets
|
||||
(float16 5.0 GB, int8_float16 3.5 GB, int8 3.0 GB, scaled down for smaller
|
||||
models) and degrades the compute type — or falls to CPU int8 — instead of
|
||||
starting a load that would kill the process. Disable with
|
||||
`OMNIVOICE_ASR_VRAM_PREFLIGHT=0`.
|
||||
|
||||
Two more fallback chains run at load time:
|
||||
|
||||
- GPUs without efficient fp16 (older Maxwell/Pascal, GTX 16xx) raise a
|
||||
compute-type error — the engine retries int8_float16, then int8
|
||||
([#551](https://github.com/debpalash/VoiceStudio/issues/551)).
|
||||
- A genuine CUDA OOM retries on CPU int8, so dubbing still completes
|
||||
(slower, same model and accuracy).
|
||||
|
||||
## Quirks
|
||||
|
||||
- **cuDNN 8 required on CUDA.** CTranslate2 links cuDNN 8; if it's missing the
|
||||
process fast-fails with no traceback, so the engine is reported unavailable
|
||||
up front and selection falls through to pytorch-whisper, which uses torch's
|
||||
own cuDNN 9 ([#1371](https://github.com/debpalash/VoiceStudio/issues/1371)).
|
||||
- On some hardened Linux kernels CTranslate2's native library is rejected with
|
||||
"cannot enable executable stack" — reported as unavailable, not a crash
|
||||
([#692](https://github.com/debpalash/VoiceStudio/issues/692)).
|
||||
- A partially-installed environment (interrupted sync, antivirus quarantine)
|
||||
can break WhisperX's deep import chain (whisperx → pyannote →
|
||||
lightning_fabric). The engine is then reported unavailable with a repair
|
||||
hint — reinstall, or `uv sync --reinstall` on a source checkout
|
||||
([#1185](https://github.com/debpalash/VoiceStudio/issues/1185)).
|
||||
- Audio is decoded through VoiceStudio's validated ffmpeg, not a bare `ffmpeg`
|
||||
PATH lookup ([#479](https://github.com/debpalash/VoiceStudio/issues/479)).
|
||||
- Transcribes are time-bounded: each dub chunk by
|
||||
`OMNIVOICE_TRANSCRIBE_CHUNK_TIMEOUT_S` (default 120 s), whole files by
|
||||
`OMNIVOICE_ASR_TRANSCRIBE_TIMEOUT_S` (default 300 s). Raise them for very
|
||||
long files on slow hardware.
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
@@ -95,4 +95,5 @@ docs:
|
||||
- docs/install/linux.md
|
||||
- docs/install/docker.md
|
||||
- docs/install/troubleshooting.md
|
||||
- docs/features/dictation.md
|
||||
- docs/migration/real-time-voice-cloning.md
|
||||
|
||||
@@ -0,0 +1,63 @@
|
||||
# Dictation
|
||||
|
||||
VoiceStudio dictation records from the system-wide shortcut, transcribes
|
||||
locally, and—where the desktop permits it—inserts the result into the app where
|
||||
the shortcut was pressed. The pill never needs keyboard focus.
|
||||
|
||||
## Use it
|
||||
|
||||
1. Choose an installed dictation model in the Model Catalogue.
|
||||
2. Set the shortcut and hold/toggle behavior in **Settings → Hotkey**.
|
||||
3. Put the cursor in a text field, press the shortcut, speak, then release or
|
||||
press again.
|
||||
|
||||
Whisper Tiny is the recommended default on macOS, Windows, and Linux. It
|
||||
auto-detects more than 90 languages. Parakeet TDT v3 remains available for its
|
||||
25 supported European languages, but it is not selected automatically.
|
||||
|
||||
The pill reports **Inserted** only after native delivery succeeds. **Copied**
|
||||
means automatic insertion was unavailable and the complete final transcript is
|
||||
ready for a normal paste. VoiceStudio retries a speech-level empty Sherpa decode
|
||||
only through another ASR model whose weights are already installed; when that
|
||||
fallback confirms the audio contains words, the silent model is demoted. This
|
||||
recovery never starts a download.
|
||||
|
||||
## Destination and clipboard safety
|
||||
|
||||
The desktop captures the target at shortcut-down and carries its session ID
|
||||
through partial, utterance, and summary messages. A late result from an older
|
||||
session cannot use a newer session's target. macOS, Windows, and X11 validate
|
||||
and reactivate the captured process/window before insertion. Wayland does not
|
||||
expose a portable target identity or arbitrary foreign-window activation, so
|
||||
the safe default leaves the transcript copied instead of guessing which app
|
||||
should receive it. The GTK pill remains non-focusable.
|
||||
|
||||
For paste delivery, VoiceStudio snapshots text, HTML (with its plain-text
|
||||
alternative), image, or file-list clipboard content, stages the transcript,
|
||||
and restores the snapshot after the target consumes it.
|
||||
Streaming segments share a generation-tracked lease: a stale restore cannot
|
||||
win over a newer segment, and VoiceStudio never overwrites clipboard content
|
||||
you copied during transcription. Unsupported clipboard formats cannot be
|
||||
round-tripped; in that case the transcript remains on the clipboard instead of
|
||||
attempting a lossy restore.
|
||||
|
||||
## Platform behavior
|
||||
|
||||
| Platform | Automatic insertion |
|
||||
| --- | --- |
|
||||
| macOS | Reactivates the captured application and sends Command-V. Without Accessibility permission, the result stays copied. |
|
||||
| Windows | Validates the captured window and process, requests foreground activation, then sends Ctrl-V. If Windows denies activation, the result stays copied. |
|
||||
| Linux X11 | Reactivates the captured X11 window through EWMH, verifies it, then sends Ctrl-V. |
|
||||
| Wayland | Leaves the complete transcript copied because a portable captured-window identity is unavailable. |
|
||||
| Browser mode | Copies the transcript; browsers cannot target another desktop app. |
|
||||
|
||||
Advanced Wayland users can set `VOICESTUDIO_WAYLAND_UNTARGETED_INSERT=1` to
|
||||
insert into whichever client owns keyboard focus when transcription finishes.
|
||||
wlroots compositors use `wtype`; KDE Plasma and GNOME can use clipboard paste
|
||||
through `dotool` or `ydotool`. Helpers run with host loader variables from an
|
||||
AppImage, have a bounded timeout, and never retry after one may have emitted
|
||||
partial input. This opt-in cannot promise the shortcut-down target if focus
|
||||
changes. `dotool` needs direct write access to `/dev/uinput`; `ydotool` 1.0+
|
||||
needs a running `ydotoold` with that access and a user-readable socket.
|
||||
VoiceStudio checks these prerequisites before selection. Tray-started Wayland
|
||||
dictation always stays copy-only.
|
||||
+19
-8
@@ -13,12 +13,12 @@ and [`palashdeb/omnivoice-studio` on Docker Hub](https://hub.docker.com/r/palash
|
||||
> |-----|--------------|
|
||||
> | `:latest` | **Rolling preview** — latest commit on `main`, at or ahead of the last release. This is the preview channel; pin `:stable` for production. |
|
||||
> | `:stable` | Most recent versioned release (updated on every `v*` git tag) |
|
||||
> | `:0.4.1` | Exact release version |
|
||||
> | `:0.4` | Latest patch within the 0.4 minor |
|
||||
> | `:0.5.0` | Exact release version |
|
||||
> | `:0.5` | Latest patch within the 0.5 minor |
|
||||
> | `:main` | Alias of the same rolling `main` build as `:latest` |
|
||||
> | `:sha-xxxxxxx` | Specific commit (produced by manual workflow dispatch) |
|
||||
> | `:rocm` | **AMD GPU (ROCm) build** of the rolling preview — the ROCm analogue of `:latest` |
|
||||
> | `:stable-rocm`, `:0.4.1-rocm`, `:0.4-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding CUDA tags above |
|
||||
> | `:stable-rocm`, `:0.5.0-rocm`, `:0.5-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding CUDA tags above |
|
||||
>
|
||||
> Versioning rule: preview builds always come from `main` and never
|
||||
> version-sort below `:stable` — upgrades flow naturally.
|
||||
@@ -89,7 +89,7 @@ PublishPort=127.0.0.1:3900:3900
|
||||
Volume=omnivoice-data:/app/omnivoice_data
|
||||
```
|
||||
|
||||
Release pins exist too: `:stable-rocm`, `:0.4.1-rocm`, `:0.4-rocm` mirror
|
||||
Release pins exist too: `:stable-rocm`, `:0.5.0-rocm`, `:0.5-rocm` mirror
|
||||
the CUDA tags exactly.
|
||||
|
||||
> **Consumer cards and APUs (RX 6000/7000, Strix Point/Halo):** the backend
|
||||
@@ -192,10 +192,14 @@ docker run -e OMNIVOICE_PUBLIC_API_BASE=https://api.your-host.example \
|
||||
> may instead bake `VITE_OMNIVOICE_API` at build time, but the runtime var above
|
||||
> is simpler and image-agnostic.
|
||||
|
||||
> **Security:** VoiceStudio ships no authentication. Anything on your LAN with
|
||||
> the URL can use the app. Put it behind a reverse proxy with `basic_auth`
|
||||
> (Caddy / nginx + htpasswd) or a private network overlay (Tailscale, ZeroTier)
|
||||
> before exposing publicly.
|
||||
> **Security:** Loopback-only publishing is the safe default. On a trusted LAN,
|
||||
> set a long random `OMNIVOICE_API_KEY` with `docker run -e` or Compose; the
|
||||
> browser will prompt for it. The optional six-digit share PIN permits casual
|
||||
> consumption access but does not authorize administration or dictation. On any
|
||||
> untrusted network, plain HTTP is not safe for the API key or session cookie.
|
||||
> Keep the backend on an encrypted private overlay such as Tailscale/ZeroTier;
|
||||
> do not expose it directly to the public internet. See [API
|
||||
> authentication](../api-auth.md) for the complete access model.
|
||||
|
||||
## Volume mounts
|
||||
|
||||
@@ -214,6 +218,13 @@ Two paths are worth persisting across container restarts:
|
||||
The running version is now shown in **Settings → About → Version** (read live
|
||||
from the backend), so the web UI no longer displays a dash in Docker.
|
||||
- **Checking which version is running:** `docker exec <container> python3 -c "import importlib.metadata; print(importlib.metadata.version('omnivoice'))"`, or hit the `/health` endpoint — it returns `{"status": "ok", "device": ..., "version": "0.3.x"}`. Use the container name listed by `docker compose ps` (or `omnivoice` for the `docker run` examples).
|
||||
- **Watching startup:** the port answers within about a second of container
|
||||
start, but heavy initialization (PyTorch, API routes, database migration)
|
||||
continues in the background. During that window `/health` returns **503**
|
||||
with the current step, and `GET /startup/progress` returns the full
|
||||
step-by-step ledger (`status`, current `step`/`label`, per-step states) —
|
||||
useful when a start seems slow and you want to see where it actually is.
|
||||
The Docker `HEALTHCHECK` flips healthy only once `/health` is 200.
|
||||
- **"Loopback origin required" errors (and a blank version):** the desktop
|
||||
build restricts the `/system/*` and `/api/settings/*` routes to a loopback
|
||||
origin, but Docker's NAT makes every request look non-loopback, so the gate
|
||||
|
||||
@@ -52,6 +52,14 @@ Everything above, plus the toolchain:
|
||||
|
||||
## Install (from source)
|
||||
|
||||
One-liner (installs prerequisites, clones, and builds; WSL works too):
|
||||
|
||||
```bash
|
||||
curl -fsSL https://voicestudio.sh/install | sh
|
||||
```
|
||||
|
||||
Or manually:
|
||||
|
||||
```bash
|
||||
git clone https://github.com/debpalash/VoiceStudio.git
|
||||
cd VoiceStudio
|
||||
@@ -100,6 +108,22 @@ where the protocol gives applications no say in their own placement and the
|
||||
compositor decides where it appears. The capsule works the same either way; only
|
||||
its position is out of the app's hands there.
|
||||
|
||||
Wayland does not expose a portable identity for the app focused at shortcut
|
||||
down, so VoiceStudio safely leaves the complete transcript on the clipboard and
|
||||
the pill says **Copied** instead of risking insertion into a different app.
|
||||
|
||||
Advanced users can opt into current-focus insertion with
|
||||
`VOICESTUDIO_WAYLAND_UNTARGETED_INSERT=1`. wlroots compositors such as Sway and
|
||||
Hyprland use `wtype`; KDE Plasma and GNOME can use `dotool` or `ydotool` to
|
||||
paste the Unicode clipboard payload. The
|
||||
opt-in targets whichever client owns keyboard focus when transcription
|
||||
finishes, not necessarily the app where dictation started. Tray-started
|
||||
dictation remains copy-only. `dotool` needs direct write access to
|
||||
`/dev/uinput` (normally through a distribution udev rule/group). `ydotool`
|
||||
1.0+ needs the `ydotoold` daemon running with that access and its socket
|
||||
available to the desktop user. VoiceStudio skips either helper when its
|
||||
readiness check fails.
|
||||
|
||||
If the global shortcut stops working, restart your desktop's portal service,
|
||||
then save the shortcut again in **Settings → Hotkey** to reopen consent. Portal
|
||||
packages and support vary by desktop; use the backend recommended by your
|
||||
|
||||
@@ -51,6 +51,14 @@ Optional but recommended:
|
||||
|
||||
## Install (from source)
|
||||
|
||||
One-liner (installs prerequisites, clones, and builds):
|
||||
|
||||
```bash
|
||||
curl -fsSL https://voicestudio.sh/install | sh
|
||||
```
|
||||
|
||||
Or manually:
|
||||
|
||||
```bash
|
||||
git clone https://github.com/debpalash/VoiceStudio.git
|
||||
cd VoiceStudio
|
||||
|
||||
@@ -138,6 +138,28 @@ failing outright.
|
||||
|
||||
**Linked issue:** [#1185](https://github.com/debpalash/VoiceStudio/issues/1185)
|
||||
|
||||
## 1c. Setup blocked: "System RAM … The app will OOM on first dub"
|
||||
|
||||
**Symptom:** the setup wizard's System Check shows **System RAM** in red and
|
||||
"Resolve blockers to continue" stays disabled — often on an 8 GB machine that
|
||||
reports ~7.8 GB usable (firmware and integrated graphics reserve a slice of
|
||||
installed RAM).
|
||||
|
||||
**Cause:** the preflight compares OS-reported RAM against the 8 GB minimum.
|
||||
Since [#1618](https://github.com/debpalash/VoiceStudio/issues/1618) the check
|
||||
tolerates that reserved-memory gap, so 8 GB-installed machines pass.
|
||||
|
||||
**Fix:** update to the latest release. If your machine is genuinely below the
|
||||
minimum and you accept the out-of-memory risk (long dubs may crash), set
|
||||
`OMNIVOICE_RAM_PREFLIGHT=0` before launching — the hard block becomes a
|
||||
warning. On Windows run PowerShell
|
||||
`[Environment]::SetEnvironmentVariable('OMNIVOICE_RAM_PREFLIGHT','0','User')`
|
||||
and relaunch; on macOS/Linux export it in the shell that starts the app. (The
|
||||
in-app Settings panel can't help here — this blocker appears before setup
|
||||
completes.)
|
||||
|
||||
**Linked issues:** [#1618](https://github.com/debpalash/VoiceStudio/issues/1618)
|
||||
|
||||
## 2. HF 401 / pyannote license not accepted
|
||||
|
||||
**Symptom:** dubbing fails with `HfHubHTTPError: 401 Client Error: Unauthorized
|
||||
@@ -524,6 +546,11 @@ and `OMNIVOICE_GENERATE_TIMEOUT_S` (generation) — both in seconds, default 300
|
||||
default 120). **Raise** them for very long single files/generations, **lower**
|
||||
them to fail faster on a small machine.
|
||||
|
||||
CPU-only hosts use a bounded 600-second generation floor because correct CPU
|
||||
synthesis can take longer than the accelerated five-minute budget. Override it
|
||||
with `OMNIVOICE_CPU_GENERATE_TIMEOUT_S`; an explicit higher
|
||||
or lower `OMNIVOICE_GENERATE_TIMEOUT_S` always wins.
|
||||
|
||||
**Two things changed here** ([#1190](https://github.com/debpalash/VoiceStudio/issues/1190)):
|
||||
|
||||
- **Waiting in line is no longer counted as compute.** The generate budget used
|
||||
@@ -763,7 +790,8 @@ unaffected and works normally.
|
||||
> **Tip:** current builds surface the live OS grant state in-app — **Settings →
|
||||
> Permissions** shows whether the microphone (and, on macOS, Accessibility) is
|
||||
> granted, denied, or not asked yet, with an **Open Settings** button that
|
||||
> deep-links the exact OS pane described above.
|
||||
> deep-links the exact OS pane described above. The dictation blocker rechecks
|
||||
> Accessibility while it is visible and closes as soon as macOS reports the grant.
|
||||
|
||||
## Dub: "translation engine needs the optional … package"
|
||||
|
||||
@@ -807,6 +835,15 @@ VoiceStudio now tries, in order: the default GitHub host → a gh-proxy mirror
|
||||
|
||||
**Linked issues:** [#130](https://github.com/debpalash/VoiceStudio/issues/130), [#60](https://github.com/debpalash/VoiceStudio/issues/60), [#57](https://github.com/debpalash/VoiceStudio/issues/57)
|
||||
|
||||
## Workspace navigation crashes with `insertBefore` / `NotFoundError`
|
||||
|
||||
This was a `v0.5.0` workspace-lifecycle bug exposed by rapid Launchpad ↔ Dub
|
||||
navigation while media renderers were cleaning up. Current builds isolate each
|
||||
workspace under its own DOM owner. Update VoiceStudio; no model or project data
|
||||
repair is required.
|
||||
|
||||
**Linked issue:** [#1590](https://github.com/debpalash/VoiceStudio/issues/1590)
|
||||
|
||||
## Uninstalling / removing all of VoiceStudio's data
|
||||
|
||||
VoiceStudio is fully local — no accounts, no services, nothing to deactivate. To
|
||||
|
||||
@@ -51,7 +51,14 @@ see [linux.md — AMD GPU (ROCm)](linux.md#amd-gpu-rocm).
|
||||
|
||||
## Install (from source)
|
||||
|
||||
Run from a regular (non-admin) PowerShell:
|
||||
One-liner from a regular (non-admin) PowerShell — installs Git, FFmpeg, uv,
|
||||
and bun via winget, then clones and builds:
|
||||
|
||||
```powershell
|
||||
irm https://voicestudio.sh/install | iex
|
||||
```
|
||||
|
||||
Or manually:
|
||||
|
||||
```bash
|
||||
git clone https://github.com/debpalash/VoiceStudio.git
|
||||
|
||||
@@ -80,6 +80,9 @@ None of them are required — the defaults are chosen for the common case.
|
||||
|
||||
| Variable | Default | What it does |
|
||||
|---|---|---|
|
||||
| `OMNIVOICE_DEVICE` | `auto` | Pin the compute device (`cuda` / `rocm` / `xpu` / `mps` / `cpu`) instead of auto-detect. Same control lives in **Settings → Performance & Device** (the env var wins over the UI pick). Honored only for devices the host actually has — a family that isn't detected is noted and ignored, never obeyed blindly. Applies at the next backend start. |
|
||||
| `OMNIVOICE_FLASHINFER` | `0` | CUDA-only accelerated decoding for the default engine via [FlashInfer](https://github.com/flashinfer-ai/flashinfer) kernels (packed CFG attention, fused RMSNorm/RoPE/GEMM) — ~2x on upstream's benchmarks. `1` enables it; `graph` also captures CUDA graphs (best when you render one thing at a time). Requires installing the optional `flashinfer-python` package into the backend environment first (`uv pip install flashinfer-python flashinfer-jit-cache --extra-index-url https://flashinfer.ai/whl/cu128/`, matching your CUDA build). Replaces `torch.compile` for that session, pins inference to a single GPU thread (the FlashInfer attention plan is per-generation state), and keeps fused copies of the attention/MLP weights resident (~roughly half the LLM's weight size extra VRAM) — leave it off on tight-VRAM cards. If the package is missing or a FlashInfer/CUDA-graph kernel fails at runtime, the app logs the reason and falls back to the standard path; failures outside those kernels (e.g. a genuine out-of-memory) surface normally. |
|
||||
| `OMNIVOICE_PROMPT_DISK_CACHE` | `1` | Persist encoded voice-clone references (`prompt_cache/` in the app data dir, ~10 KB per voice, 32 newest kept) so the first generation with a known voice after a restart skips the reference re-encode and any auto-transcription. Set `0` to keep the cache in memory only. |
|
||||
| `OMNIVOICE_IDLE_TIMEOUT_S` | `900` | Seconds of idle before the TTS model unloads to free memory. Raise it (e.g. `3600`) if you generate in bursts and dislike the ~8 s reload; lower it on tight-memory machines. |
|
||||
| `OMNIVOICE_SIDECAR_IDLE_TIMEOUT_S` | `300` | Same idea for sidecar engines (IndexTTS 2.5 etc.). |
|
||||
| `OMNIVOICE_LLM_CONCURRENCY` | `6` | Parallel LLM translation calls during a dub. Raise for a fast API endpoint, lower if your provider rate-limits. |
|
||||
@@ -229,6 +232,50 @@ uv run python scripts/bench_pipeline.py tts clone # just these stages
|
||||
If you report a performance issue, pasting its table (plus your platform and
|
||||
RAM/VRAM) turns a guessing game into a bisect.
|
||||
|
||||
Measured results per engine/device — and how to contribute yours — live in
|
||||
[benchmarks.md](benchmarks.md).
|
||||
|
||||
## Performance budgets
|
||||
|
||||
CI guards the hot paths above against regressions — not with wall-clock
|
||||
budgets (CI hardware varies too much for a stable "≤5 % slower" threshold),
|
||||
but with **operation-count budgets** in
|
||||
`tests/test_perf_operation_budgets.py`, which fail on *any* regression:
|
||||
|
||||
- **Streaming TTS (`/ws/tts`)**: exactly one engine `generate` per sentence
|
||||
chunk, and exactly one text-normalization pass per request (never one per
|
||||
sentence).
|
||||
- **Dub re-mix**: a fit-only re-mix (`regen_only=[]`) of cached segments
|
||||
makes **zero** TTS calls. The zero-decode / zero-rewrite budget activates
|
||||
with the natural-rate cached fast path (each cache is then decoded exactly
|
||||
once, by the final assembly).
|
||||
- **Batch dubbing (native batches)**: N renderable segments at batch width W
|
||||
cost exactly ⌈N/W⌉ `generate_batch` calls and zero per-segment `generate`
|
||||
calls when native batching is enabled.
|
||||
|
||||
Updating a budget is a deliberate act: if a change legitimately adds an
|
||||
operation to a guarded path, change the expected count in the same PR with a
|
||||
comment justifying the new floor. Never loosen a budget just to make CI pass
|
||||
— that is the regression the budget exists to catch.
|
||||
|
||||
## Batch and streaming behavior
|
||||
|
||||
Batch dubbing renders several segments in one native forward pass when the
|
||||
selected engine supports it. The width is derived from the host rather than
|
||||
fixed, because a wider forward pass needs proportionally more device memory:
|
||||
CPU hosts and cards with less than ~2 GB of headroom above the engine's
|
||||
single-job requirement stay at one segment, and the width steps up to 2, 4,
|
||||
and 8 as headroom allows. `OMNIVOICE_DUB_BATCH_WIDTH` overrides it (1 disables
|
||||
batching, 16 is the ceiling). Engines without native batching inherit a
|
||||
compatibility fallback that preserves the one-segment behavior.
|
||||
|
||||
Streaming clients also receive measured latency in the `/ws/tts` terminal
|
||||
`done` frame: `ttfa_ms` is request-to-first-audio, `gen_time_s` is the
|
||||
end-to-end wall clock including delivery, and `rtf` is *synthesis* time
|
||||
divided by generated-audio duration — measured around the render calls only,
|
||||
so a slow client cannot inflate it. The backend log records the same values, so a slow first chunk is
|
||||
distinguishable from a fast first chunk followed by a long render.
|
||||
|
||||
## Things that look like knobs but aren't
|
||||
|
||||
- **Deleting and re-adding a voice** doesn't speed anything up; the reference
|
||||
|
||||
+13
-2
@@ -153,6 +153,15 @@ fallback is reported once. ASR, diarization and translation also remain local. D
|
||||
runs here, deliberately and permanently, because there latency *is* the
|
||||
feature. The remaining operations are being ported one at a time.
|
||||
|
||||
### Voice identity parity
|
||||
|
||||
For TTS, the worker receives the complete local rendering contract: the voice
|
||||
profile's reference audio and transcript, its pinned seed, model quality
|
||||
controls, text chunking/crossfade settings, and output effect preset. The
|
||||
worker runs the same native or generic rendering pipeline as local
|
||||
`/generate`; selecting a gallery voice therefore does not turn it into a new
|
||||
random voice merely because it was rendered on another GPU.
|
||||
|
||||
The picker knows this. It resolves against the surface you are on, so a chosen
|
||||
worker reads **Local** on a tab whose work has no remote path yet and names the
|
||||
reason, instead of showing a green dot next to a GPU that receives nothing. The
|
||||
@@ -210,10 +219,12 @@ what is genuinely still in flight.
|
||||
**Version or feature mismatch.** The protocol keeps a two-release compatibility
|
||||
window, but release numbers alone do not prove that a worker understands every
|
||||
additive command. Registration therefore also declares named features for task
|
||||
inputs, progress leases, and remote model downloads. A worker outside the
|
||||
inputs, progress leases, remote model downloads, and the voice-identity render
|
||||
pipeline. A worker outside the
|
||||
version window, or one missing a required feature, is refused with
|
||||
`UPGRADE_REQUIRED` and an update instruction before any task runs. It can never
|
||||
silently render without reference audio or leave a download stuck at 0%.
|
||||
silently render without reference audio, substitute a different voice, or leave
|
||||
a download stuck at 0%.
|
||||
|
||||
Every remote failure includes a concrete next step. Capacity, missing models,
|
||||
expired leases or sessions, authentication, rejected inputs, and result upload
|
||||
|
||||
@@ -16,6 +16,10 @@ For another device on the same network — e.g. opening the web UI on your phone
|
||||
|
||||
You can also drive this from **Settings → Sharing & Remote Access**.
|
||||
|
||||
Desktop installers include the web interface used by the LAN address; another
|
||||
device does not need VoiceStudio installed and the host does not need a source
|
||||
checkout or a separate frontend development server.
|
||||
|
||||
### How the PIN works
|
||||
- A fresh 6-digit PIN is generated each time you enable sharing; it is never written to disk.
|
||||
- The QR encodes the PIN (`…/?pin=######`) so scanning connects in one step. Typing the bare URL instead prompts for the PIN.
|
||||
|
||||
@@ -30,9 +30,9 @@ VoiceStudio today is **asymmetric** across its three longform surfaces:
|
||||
The dub pipeline **already** content-addresses segments so that editing one line re-synthesizes only that line:
|
||||
|
||||
- **`backend/services/incremental.py`** — `segment_fingerprint(seg)` (52–67) is a sha1 over the **generation inputs that actually affect TTS output**: `_GEN_INPUT_FIELDS = ("text","target_lang","profile_id","instruct","speed","direction","effect_preset")` (line 23). `_canon_value` (32–49) normalizes None/""/missing and int↔float so the **server-parsed view** and the **client-raw view** of the same logical segment hash identically — the root-cause fix for #281 ("1 edit re-dubs all N lines"). `fit_fingerprint(params)` (101–116) hashes the **fit configuration separately and on purpose** (70–76): a fit-knob change must trigger a **re-mix** of already-rendered natural-rate WAVs (`regen_only=[]`), never a re-TTS. `plan_incremental(segments, *, stored_hashes)` (119–157) returns `{stale, fresh, total, fingerprints}`.
|
||||
- **`backend/api/routers/dub_generate.py`** — honors `regen_only` (113): for a segment **not** in `regen_only` it reloads the cached `dub_seg_path(job_id, seg_id)` (160–197, with a legacy index-name fallback at 162–166) instead of re-running TTS; for stale segments it runs `_gen(...)`. After the loop it **always re-stitches the full `dubbed_{lang}.wav`** (766–770) and persists `job["seg_hashes"]` (498–512) + `seg_order` (127). The `done` SSE ships `seg_hashes`/`seg_num_step` back (840). Strategy-transition guard (122–123) and `seg_wav_kind` (830) keep smart_fit reuse correct.
|
||||
- **`backend/api/routers/dub_generate.py`** — honors `regen_only`: for a segment **not** in `regen_only` it reuses the cached WAV at `dub_seg_path(job_id, f"{lang_code}_{seg_key}")` (`_seg_lang_path` — the key is language-qualified, so each target language caches its own render) instead of re-running TTS; same-rate natural caches go straight into the bounded-memory assembly manifest, while strict-slot or sample-rate conversion keeps the transformed scratch path. After the loop it **always re-stitches the full `dubbed_{lang}.wav`** and persists `job["seg_hashes"]` + `seg_order`. The `done` SSE ships `seg_hashes`/`seg_num_step` back. The strategy-transition guard and `seg_wav_kind` prevent every natural-rate mode (`concise`, `stretch_video`, `smart_fit`) from reusing destructively slotted audio.
|
||||
- **`tests/test_redub_incremental.py`** — already asserts the contract end-to-end with a mocked TTS engine: `test_edited_line_produces_different_cached_output` (228–281) proves an edited line's cached WAV changes, the **untouched line's cached WAV is reused byte-for-byte** (272–273), TTS ran exactly once (266), and the final track was rebuilt (281). `test_one_edit_marks_exactly_one_segment_stale` (101–118) proves the planner.
|
||||
- **Per-segment audio + metadata keying.** Audio lives on disk as `{DUB_DIR}/{job_id}/seg_{seg_id}.wav` via `dub_seg_path(job_id, seg_id)` (`backend/core/config.py:54–71`). Metadata lives in the job's `job_data` JSON blob (`dub_history` table, `backend/core/db.py:74–85`), holding `segments`, `seg_order`, `seg_hashes`, `seg_num_step`, `seg_wav_kind`, `dubbed_tracks`, `fit_plans`, `video_stretch_plans`. Stable ids are minted at transcribe time (`s{NNNNN:05x}`, `dub_core.py:600`). Job persistence is `dub_pipeline.get_job`/`save_job`/`put_job` (`backend/services/dub_pipeline.py:158–214`).
|
||||
- **Per-segment audio + metadata keying.** Audio lives on disk as `{DUB_DIR}/{job_id}/seg_{lang}_{seg_id}.wav` via `_seg_lang_path` → `dub_seg_path(job_id, f"{lang_code}_{seg_key}")` (`backend/core/config.py:54–71` for the path guard); legacy unqualified `seg_{seg_id}.wav` files from single-language-era jobs remain readable through the gated `_legacy_seg_cache_ok` fallback. Metadata lives in the job's `job_data` JSON blob (`dub_history` table, `backend/core/db.py:74–85`), holding `segments`, `seg_order`, `seg_hashes`, `seg_num_step`, `seg_wav_kind`, `dubbed_tracks`, `fit_plans`, `video_stretch_plans`. Stable ids are minted at transcribe time (`s{NNNNN:05x}`, `dub_core.py:600`). Job persistence is `dub_pipeline.get_job`/`save_job`/`put_job` (`backend/services/dub_pipeline.py:158–214`).
|
||||
- **Longform (Audiobook + Stories) share one renderer** `_render_longform_sse` (`backend/api/routers/audiobook.py:403–595`) and one **chapter-level** content-addressed key `chapter_cache_key` (`backend/services/longform_render.py:110–136`), cached under `OUTPUTS_DIR/longform_cache` (`_render_chapter_cached`, `audiobook.py:314–355`). The lexicon is folded into the key (338–341). Resume (`audiobook.py:714–759`) reuses already-rendered chapters because the key is content-based. **But the granularity is the whole chapter** (longform_render.py:117–125) — that is the gap.
|
||||
|
||||
**Conclusion:** Dub is the reference implementation. Stories already has the *editor UI* but no incremental backend. Audiobook has neither a per-line editor nor sub-chapter incrementality. This spec makes all three behave like a "Studio" by (1) standardizing the editor affordances and (2) pushing the dub-proven `fingerprint → stale → regen_only → re-stitch` loop down into the longform renderer at **span granularity**.
|
||||
@@ -250,7 +250,7 @@ Each slice is independently shippable, continuous-to-main, with its own regressi
|
||||
| **Fingerprint parity drift** (server vs client hash differently → every span looks stale → degrades to full render, the #281 regression class). | Reuse `incremental._canon_value` verbatim; add the server-vs-client parity test first (TDD), exactly as dub did. |
|
||||
| **Parser-twin divergence** (Python `longform_parser` vs JS `longformParser.js` mint different span ids). | Stable ids derived from `(chapter_index, span_index)` are computed identically in both; the existing golden-corpus byte-for-byte test (#27) gates it. |
|
||||
| **Stitch seams** (per-span WAVs stitched may click vs a monolithic chapter render). | `synthesize_chapter` already crossfades spans (50 ms) and hard-concats silences (`services/audiobook.py:121–139`) — the seam behavior is identical whether a span was freshly rendered or cache-loaded (same WAV bytes). |
|
||||
| **smart_fit-style double-processing on dub** (reusing a slotted WAV under smart_fit). | Already solved: the strategy-transition guard (`dub_generate.py:122–123`) + `seg_wav_kind` (830) force a full regen when the cached WAVs are the wrong kind. No new exposure. |
|
||||
| **Timing-mode double-processing on dub** (reusing a slotted WAV in a natural-rate mode). | The strategy-transition guard + `seg_wav_kind` force a full regen when `concise`, `stretch_video`, or `smart_fit` sees the wrong cache kind. No new exposure. |
|
||||
| **Existing projects forced to re-render.** | First edit treats unknown-hash spans as stale **once** (correct output), never corrupts cache; no upgrade-time mass re-render. |
|
||||
| **Emotion/style field lands in the wrong fingerprint bucket** (re-TTS when it should re-mix, or vice-versa, wasting compute or shipping stale audio). | Q1 decision pins the bucket per field; the `fit_fingerprint` precedent (incremental.py:70–116) gives both buckets a tested home; 03f ships last, after the field's semantics are known. |
|
||||
|
||||
|
||||
@@ -1,14 +1,14 @@
|
||||
# Dictation Flow Program — local WhisperFlow-class dictation on Parakeet
|
||||
# Dictation Flow Program — local cross-platform flow dictation
|
||||
|
||||
*Spec, 2026-07-16. Research inputs: three-agent study — product landscape (Wispr Flow, jamiepine/voicebox, Handy, VoiceInk, Whispering, Talon, Claude Code `/voice`), in-repo capability map, and Parakeet TDT/Nemotron feasibility (sherpa-onnx). Sources cited inline where load-bearing.*
|
||||
*Spec, 2026-07-16. Research inputs: a multi-agent product-landscape study, in-repo capability map, and local ASR feasibility review. Sources are cited inline where load-bearing.*
|
||||
|
||||
## Why
|
||||
|
||||
Dictating prompts to AI agents is the fastest-growing text-input workload (Claude Code shipped built-in `/voice`; Wispr Flow raised at ~$2B on it) — and every polished option is **cloud** (Wispr: cloud-only, no Linux, one privacy scandal already; Claude Code voice: cloud-only, no SSH). The best open competitor, **jamiepine/voicebox** (41.7k★, MIT — our refinement layer is already adapted from it), only ships reliable auto-paste on macOS. VoiceStudio already has the hard parts: a Wispr-style pill, global hotkey, sherpa-onnx streaming WS, **Parakeet TDT v3 int8 as the shipped default**, clipboard-restoring paste, and local-LLM refinement. A local, cross-platform, private flow-dictation experience is reachable and strategically differentiating — the wedge is **local + Linux/Wayland + agent-prompting**, where nobody credible plays.
|
||||
Dictating prompts to AI agents is a rapidly growing text-input workload, while polished options remain cloud-first and Linux support is uneven. VoiceStudio already has the hard parts: a compact capture pill, global hotkey, sherpa-onnx streaming WS, **Whisper Tiny int8 as the shipped cross-platform default**, clipboard-restoring paste, and local-LLM refinement. A local, cross-platform, private flow-dictation experience is reachable and strategically differentiating — the wedge is **local + Linux/Wayland + agent-prompting**.
|
||||
|
||||
## Current state (verified in-repo)
|
||||
|
||||
Widget: pill webview + `tauri-plugin-global-shortcut` (`CmdOrCtrl+Shift+Space`, toggle/hold) on macOS, Windows and X11 + the GlobalShortcuts desktop portal on Wayland + browser-mode keyboard fallback; `getUserMedia` → raw-PCM WS `/ws/transcribe`; paste via arboard+enigo with clipboard restore, macOS a11y fail-loud, Windows no-activate. Backend: 7 sherpa models (Parakeet TDT v3 default), streaming path (zipformer/paraformer) + chunked-offline path (0.8 s partial cadence, **RMS silence gate**), `text_polish` on finals, opt-in LLM refinement (Ollama/LM Studio, ≤4 s wall clock). Gaps: no real VAD, no dictionary/hotwords, no per-app awareness, no command grammar, no language picker, enigo-only Linux insertion, no comprehensive dictation feature guide beyond the Linux installation note, picker understates model size ~4×.
|
||||
Widget: pill webview + `tauri-plugin-global-shortcut` (`CmdOrCtrl+Shift+Space`, toggle/hold) on macOS, Windows and X11 + the GlobalShortcuts desktop portal on Wayland + browser-mode keyboard fallback; `getUserMedia` → 16 kHz raw-PCM WS `/ws/transcribe`; a native session captures the destination before the pill appears, restores an untouched clipboard by generation, reactivates macOS/Windows/X11 targets, and uses a truthful copy fallback on Wayland unless current-focus insertion is explicitly enabled. Backend: 7 sherpa models (Whisper Tiny default), streaming path (zipformer/paraformer) + chunked-offline path (0.8 s partial cadence, **RMS silence gate**), shared speech-evidence model demotion with installed-only ASR fallback, `text_polish` on finals, opt-in LLM refinement (Ollama/LM Studio, ≤4 s wall clock). Gaps: no real VAD, no dictionary/hotwords, no per-app formatting profiles, no command grammar, no language picker, picker understates model size ~4×.
|
||||
|
||||
## Program phases
|
||||
|
||||
@@ -41,7 +41,7 @@ Parakeet's one real weakness is OOV technical terms — and the dictionary is Wi
|
||||
|
||||
### Phase 4 — insertion reliability + Wayland (beat everyone on Linux)
|
||||
- **Reliability engineering** (the boring 20% that reads professional; Wispr does 5 retries): retry-with-backoff on paste, transcript stays on clipboard + toast on failure, password-field refusal, Windows elevated-window detection.
|
||||
- **Wayland insertion chain** replacing bare enigo on Linux: kwtype→wtype→dotool→ydotool→wl-copy+notify fallback (Handy's proven cascade), IBus/Fcitx5 input-method commit path evaluated for GNOME (highest quality, nobody mainstream ships it), libei/RemoteDesktop-portal as the forward bet. Wispr has no Linux at all; voicebox has no Linux paste — this is the moat.
|
||||
- **Wayland insertion chain** replacing bare enigo on Linux: wtype→dotool→ydotool→wl-copy+notify fallback, IBus/Fcitx5 input-method commit path evaluated for GNOME (highest quality, nobody mainstream ships it), libei/RemoteDesktop-portal as the forward bet. Reliable local Linux insertion is the moat.
|
||||
|
||||
### Phase 5 — command mode (headline, local-only differentiator)
|
||||
Second hotkey → speak an instruction over selected text → local LLM rewrite → explicit Apply. Wispr charges for this; ours is local and free. Requires configured LLM; hidden otherwise (existing `llm_ready` plumbing).
|
||||
@@ -56,10 +56,10 @@ Second hotkey → speak an instruction over selected text → local LLM rewrite
|
||||
| Use case | Model | Partials | Final after pause | Disk/RAM |
|
||||
|---|---|---|---|---|
|
||||
| English, best feel | nemotron-streaming-en 160 ms (new, Ph. 1) | 200–400 ms | ~0.5–0.7 s | 0.66 GB / ~1.2 GB |
|
||||
| Multilingual default | parakeet-tdt-v3 + silero-VAD (upgraded path) | 0.8 s cadence | ~0.4–0.7 s | 0.67 GB / ~1.2 GB |
|
||||
| European languages (opt-in) | parakeet-tdt-v3 + silero-VAD (upgraded path) | 0.8 s cadence | ~0.4–0.7 s | 0.67 GB / ~1.2 GB |
|
||||
| Multilingual streaming (opt-in) | Nemotron-3.5 320 ms (new) | ~400 ms | ~0.7 s | 0.68 GB / ~1.2 GB |
|
||||
| Low-RAM | zipformer-20M (existing) | ~100 ms | ~0.6 s | 0.13 GB / ~0.3 GB |
|
||||
| CJK / 90+ langs | whisper-tiny (existing; consider small) | n/a | seconds | 0.12 GB |
|
||||
| Multilingual default / CJK | whisper-tiny (existing; consider small) | n/a | seconds | 0.104 GB |
|
||||
|
||||
## Top risks
|
||||
|
||||
|
||||
@@ -0,0 +1,479 @@
|
||||
# Frontend Responsiveness: Persistence Write-Amplification Remediation Plan
|
||||
|
||||
| Field | Decision |
|
||||
| --- | --- |
|
||||
| Status | Implemented in draft PR #1541; CI and review pending |
|
||||
| Target | One focused frontend PR |
|
||||
| Priority | P1 responsiveness and data-safety hardening |
|
||||
| Risk | Medium: persistence timing changes, persisted formats do not |
|
||||
| Dependencies | None |
|
||||
| Rollback | Revert the PR; the existing keys and schemas remain readable |
|
||||
|
||||
## Executive decision
|
||||
|
||||
The first optimization PR should remove synchronous JSON serialization and `localStorage` writes from high-frequency interaction paths. It should preserve the existing `omnivoice.app` and `omni_ui` contracts, coalesce each burst to the latest value, flush within a bounded window, and prevent deferred writes from undoing Factory Reset.
|
||||
|
||||
This is the best first change because it addresses a measured, cross-workspace bottleneck without combining it with a storage migration, backend change, or `App.jsx` rewrite. Incremental-dub scheduling, transactional undo, and workspace decomposition remain separate follow-ups with their own evidence and rollback boundaries.
|
||||
|
||||
## Evidence and diagnosis
|
||||
|
||||
### Static path
|
||||
|
||||
Two independent persistence paths run on the browser main thread:
|
||||
|
||||
1. Every Zustand `set` invokes the persist middleware. The middleware runs `partialize`, serializes the complete persisted projection, and calls synchronous `localStorage.setItem('omnivoice.app', ...)`, even when the mutation only changes transient state.
|
||||
2. `useAppData` has a broad effect that serializes and writes `omni_ui` whenever text, dub segments, transcript, tracks, history, or a related preference changes.
|
||||
|
||||
The resulting hot path is:
|
||||
|
||||
`input -> store update -> render/effects -> full projection -> JSON.stringify -> localStorage.setItem`
|
||||
|
||||
The cost scales with document size rather than with the small field the user changed. `localStorage` is synchronous, so both serialization and the physical write compete with the next frame.
|
||||
|
||||
### Local runtime baseline
|
||||
|
||||
The following measurements are diagnostic baselines from commit `3e3189d04d2d6dba69b4dd07fefc8725b9c94af6`, not portable CI thresholds. Each scenario performs 20 UI-scale interactions; raw storage timing excludes `JSON.stringify`, so it is a lower bound. Two unrelated contact-key writes were excluded from the target-key counts but included in the aggregate raw timing.
|
||||
|
||||
| Fixture | Writes to target keys | Input-to-next-frame | Raw `setItem` time |
|
||||
| --- | ---: | ---: | ---: |
|
||||
| Small local state | 40 `omnivoice.app` + 20 `omni_ui` | 13.9 ms average, 18.9 ms max | 1.9 ms |
|
||||
| 1,800 dub segments + 400 story tracks | 40 + 20 | 23.6 ms average, 39.0 ms max | 50.7 ms |
|
||||
| 3,000 dub segments + 3,000 story tracks | 40 + 20 | Repeated 56-114 ms long tasks | 809 ms |
|
||||
|
||||
Representative serialized sizes were approximately 156 KB for `omnivoice.app` and 1.5 MB for `omni_ui`. A direct text-edit probe also produced one write to each key for each change.
|
||||
|
||||
### Baseline verification
|
||||
|
||||
- Baseline commit: `3e3189d04d2d6dba69b4dd07fefc8725b9c94af6`.
|
||||
- `bun run test -- src/utils/prefKeys.test.js src/test/omniUiSchema.test.js src/test/dubStepRestoreClamp.test.js src/store/uiScaleMigration.test.ts src/test/dubPerLangTranslations.test.jsx src/test/dubVoiceMatchRequest.test.jsx` passes: 6 files, 35 tests.
|
||||
- The production build passes. The main application chunk is approximately 381.82 KB minified / 116.27 KB gzip.
|
||||
- `backend/api/routers/mcp_bindings.py` is not implicated: its list handler is a thin delegation, and the bindings panel already loads bindings and profiles concurrently.
|
||||
- The large Settings/OpenAPI chunk is lazy and is not the interaction-time bottleneck targeted here.
|
||||
|
||||
## Goal
|
||||
|
||||
For a rapid sequence of edits, perform no JSON serialization or physical storage write in the originating interaction task and persist only the newest value after the burst, while retaining synchronous hydration and the current recovery formats.
|
||||
|
||||
## Scope
|
||||
|
||||
### In scope
|
||||
|
||||
- One shared, typed, coalescing JSON writer for browser `localStorage`.
|
||||
- A Zustand-compatible structured storage adapter that defers serialization itself.
|
||||
- Deferred `omni_ui` persistence with its exact current field set.
|
||||
- Trailing flush, maximum-wait flush, and page-lifecycle flush.
|
||||
- Single-writer protection for the standalone Tauri capture widget.
|
||||
- Factory Reset cancellation so pending values cannot recreate deleted keys.
|
||||
- Deterministic unit/integration tests, a before/after browser trace, and an Unreleased changelog entry.
|
||||
|
||||
### Explicitly out of scope
|
||||
|
||||
- IndexedDB, workers, new storage keys, schema changes, or a Zustand version bump.
|
||||
- Removing duplicated fields from `omni_ui` or changing restore precedence.
|
||||
- Backend/API/database changes, including MCP bindings.
|
||||
- Debouncing `/tools/incremental` in this PR.
|
||||
- Changing undo/redo semantics or snapshot representation.
|
||||
- Splitting stores, decomposing `App.jsx`, or moving workspace imports.
|
||||
- New dependencies, user-visible strings, locale files, or an app version bump.
|
||||
- Hardware-sensitive timing assertions in CI.
|
||||
|
||||
## Compatibility and safety invariants
|
||||
|
||||
The implementation must preserve all of the following:
|
||||
|
||||
| Contract | Required invariant |
|
||||
| --- | --- |
|
||||
| Zustand key | `omnivoice.app` |
|
||||
| Zustand envelope | `{ state, version: 7 }`, serialized with normal `JSON.stringify` semantics |
|
||||
| Zustand projection | Existing `partialize` fields and transient-field stripping remain semantically unchanged |
|
||||
| Zustand migration | Existing v1-v7 migration behavior remains unchanged |
|
||||
| Legacy recovery key | `omni_ui` |
|
||||
| Legacy recovery shape | Exact current field names, omission behavior, and `sanitizeOmniUi` restore path |
|
||||
| Hydration | Synchronous; no loading gate or async race is introduced |
|
||||
| Durability | When serialization/storage succeeds and the browser runs timers, a dirty key is attempted within 1,000 ms of its first unflushed change |
|
||||
| Lifecycle | `pagehide` and hidden-document events attempt pending values; both events together cause at most one physical write per unchanged generation |
|
||||
| Reset | A removed preference key cannot be recreated by old or newly queued work before the reset reload |
|
||||
| Desktop windows | Persistence starts in an unknown/read-only role; the resolved main webview is activated as the only writer and the standalone widget stays read-only |
|
||||
| Privacy | Logs may contain a key and error name, never persisted user content |
|
||||
| Platform parity | Same default behavior on macOS, Windows, Linux, browser, and Docker |
|
||||
|
||||
Direct consumers such as `utils/donationMoments.js`, E2E state seeding, long-form recovery, and the preference-key registry must continue to parse the existing envelope without changes. The donation opt-out's primary `omnivoice.donate.optOut` flag remains an immediate, separate write; add a compatibility assertion that its immediate behavior and the flushed legacy-envelope fallback both remain valid.
|
||||
|
||||
Concurrent browser/Docker tabs are explicitly not promoted to a coordinated multi-writer system in this PR. They retain unsupported last-physical-writer-wins behavior. The PR description must state that boundary; adding cross-tab revisions or `BroadcastChannel` arbitration would be a separate data-consistency design.
|
||||
|
||||
## Proposed design
|
||||
|
||||
### 1. Shared coalescing writer
|
||||
|
||||
Create `frontend/src/utils/coalescedJsonStorage.ts` with an injectable core and one application singleton. The public contract should be small:
|
||||
|
||||
| API | Contract |
|
||||
| --- | --- |
|
||||
| `queueJsonWrite(key, readLatestValue)` | Mark `key` dirty and replace its lazy provider; return a generation-bound disposer that can cancel only this registration |
|
||||
| `createZustandJsonStorage()` | Return a `PersistStorage` adapter whose `getItem` is synchronous and whose `setItem` queues the structured `StorageValue` |
|
||||
| `flushPendingWrites()` | Synchronously serialize and attempt every pending write; return a summary for tests/diagnostics |
|
||||
| `discardPendingWrites(predicate?)` | Cancel timers and pending values matching a key predicate |
|
||||
| `suspendJsonWrites(predicate)` | Discard matching work and reject later matching queues until the returned resume callback is used |
|
||||
| `configurePersistenceRole(role)` | Resolve the singleton from initial `unknown` to `main` or `readonly`; activate staged main work or discard all staged widget work |
|
||||
| Adapter `removeItem(key)` | Cancel/stage-remove that key before raw removal; propagate main-window removal errors; remain inert in a read-only widget |
|
||||
| `installPersistenceLifecycleFlush()` | Install the singleton listener pair once for the main bootstrap owner; cleanup is idempotent and reserved for tests/HMR teardown |
|
||||
|
||||
Required scheduling semantics:
|
||||
|
||||
- Quiet delay: 250 ms after the latest value for a key.
|
||||
- Hard maximum: 1,000 ms from the first unflushed value for that key; continuous input must not starve persistence.
|
||||
- Last scheduled value wins.
|
||||
- The queued provider is evaluated on the JavaScript thread only at flush, so the value serialized is the latest application value at flush time rather than a deep-cloned event-time object.
|
||||
- The quiet timer resets on replacement; the maximum timer does not.
|
||||
- A successful maximum flush starts a new window for later updates.
|
||||
- Use standard timers. Do not make `requestIdleCallback` part of the correctness path; availability differs across the supported webviews.
|
||||
- Do not wrap `createJSONStorage`. It stringifies before calling the adapter and would leave the main cost inside the interaction path.
|
||||
|
||||
Flush behavior:
|
||||
|
||||
1. Read the latest provider and serialize only at flush time.
|
||||
2. Compare the serialized value with the currently durable raw value and skip an identical physical write.
|
||||
3. Call `setItem` once at most for each dirty key in that flush.
|
||||
4. Mark the entry clean only after a successful write or confirmed identical value.
|
||||
5. Ensure an old timer cannot commit after a newer value, cancellation, or removal.
|
||||
|
||||
`getItem` must evaluate and return the latest pending structured value when one exists; otherwise it must synchronously parse the durable raw value. This keeps explicit Zustand `rehydrate()` calls internally consistent without changing cold-start hydration.
|
||||
|
||||
The lazy-provider contract avoids copying a 1.5 MB document on every input. Task 0 must audit every persisted nested container for in-place mutation. React/Zustand setters are expected to publish replacements; any isolated violation must be fixed or explicitly converted to a safe value provider before wiring this scheduler. If the audit reveals a broad mutable-data convention, stop and redesign this PR rather than hiding a state-model refactor inside it. A deterministic test must pin current-at-flush semantics: mutate/replace the provider's source without serializing, then flush and verify the current value is written.
|
||||
|
||||
### 2. Failure semantics
|
||||
|
||||
- `JSON.stringify` or storage failures must not escape through a Zustand setter, React effect, or lifecycle event.
|
||||
- A serialization failure discards that invalid value after a warning; a later valid update can proceed.
|
||||
- Every flush attempt clears both timers first.
|
||||
- A quota/security/write failure leaves the previous durable blob untouched and keeps the newest value dirty, but disarms automatic retry. A later queue starts a fresh 250/1,000 ms window; an explicit/lifecycle flush attempts it once. Advancing timers alone must not create a retry loop.
|
||||
- A multi-key flush is isolated per key: successful keys become clean; a failed key remains dirty; retrying the failed key must not rewrite successful siblings.
|
||||
- Warn once per key/operation/error class to avoid console floods.
|
||||
- Never log the value, text, segment data, or serialized payload.
|
||||
- Adapter `removeItem` and Factory Reset remain truthful: cancel pending work first, then allow a main-window raw removal failure to reach the caller.
|
||||
- The 1,000 ms durability statement applies only when the browser schedules the timer and storage succeeds. Timer throttling, quota denial, a crashed process, or a failed lifecycle write cannot be promised durable; these cases are observable and non-crashing.
|
||||
|
||||
### 3. Main-window ownership
|
||||
|
||||
The Tauri widget imports the same Zustand store in a separate webview and calls setters for runtime dictation state. Today those transient setters can persist an older projection over the main window's current preferences.
|
||||
|
||||
Do not duplicate widget detection inside the storage utility. `detectIsWidget()` already resolves the initialization marker, Tauri `getCurrentWindow().label`, and legacy development URL. `bootstrapApp()` must pass that exact resolved result to `configurePersistenceRole()` before React renders.
|
||||
|
||||
The singleton begins in `unknown`: hydration reads work, but writes/removals can only be staged and no timer, serialization, or raw mutation may run. Resolving `main` replays only the latest staged operation per key and starts its 250/1,000 ms clocks at activation; time spent awaiting role detection does not count against a window in which writing was forbidden. Resolving `readonly` discards staged work and makes both `setItem` and `removeItem` inert. This is necessary because the store is statically imported before asynchronous window detection completes. The in-page browser capture pill shares the main document and remains writable.
|
||||
|
||||
Tests that import the store without `bootstrapApp()` must use an isolated writer or explicitly configure `main` in setup and reset role, staged work, suspensions, timers, and listeners in teardown. Existing migration tests must clear scheduler state before seeding raw fixtures; otherwise a staged pending value can mask the fixture during `persist.rehydrate()`.
|
||||
|
||||
### 4. Lifecycle ownership
|
||||
|
||||
After `detectIsWidget()` resolves, `bootstrapApp()` should configure the role and install lifecycle flushing before rendering only for the main window. Bootstrap is the sole production owner; an isolated writer instance or explicit teardown resets listeners in tests.
|
||||
|
||||
- Flush on `pagehide`.
|
||||
- Flush on `visibilitychange` only when `document.visibilityState === 'hidden'`.
|
||||
- Do not add `beforeunload`; it is unnecessary and can interfere with back/forward caching.
|
||||
- Lifecycle flush uses the same generation/cancellation checks as timer flushes. If hidden visibility and `pagehide` both fire, the second invocation observes a clean generation and performs no second serialization/write.
|
||||
|
||||
### 5. Zustand integration
|
||||
|
||||
In `frontend/src/store/index.ts`:
|
||||
|
||||
- Replace `createJSONStorage(() => localStorage)` with the structured coalescing adapter.
|
||||
- Preserve `name`, `partialize`, `version: 7`, and `migrate` semantically unchanged.
|
||||
- Keep the long-form projection and removal of `generating`/`audioUrl` intact.
|
||||
- Do not add `text`, dub segments, or other legacy recovery fields to this key.
|
||||
|
||||
This PR deliberately leaves `partialize` synchronous. If post-change profiling shows its `storyTracks.map(...)` is still material, optimize projection scheduling in a separate change rather than replacing hydration and migration machinery here.
|
||||
|
||||
### 6. `omni_ui` integration
|
||||
|
||||
In `frontend/src/hooks/useAppData.js`:
|
||||
|
||||
- Build the same recovery object with the same property order and values.
|
||||
- Replace direct `JSON.stringify` + `localStorage.setItem` with a lazy `queueJsonWrite('omni_ui', readLatestOmniUi)` provider.
|
||||
- Keep synchronous parsing, `sanitizeOmniUi`, legacy `clone`/`design` handling, and dub-step clamping unchanged.
|
||||
- Add an explicit `omniUiRestoreComplete` readiness state. The initial persistence effect must queue nothing; the restore effect sets all recovered values and flips readiness in the same batch, and the subsequent render supplies the first writable value.
|
||||
- Prove an immediate lifecycle event between the initial effects and the restored render cannot persist defaults.
|
||||
- Feed a lazy latest-value provider to the writer and invoke its generation-bound disposer in effect cleanup. An obsolete StrictMode/unmounted effect may cancel only its own registration, never a newer mount's provider. Do not deep-clone at queue time; the immutability audit and current-at-flush contract above define ownership.
|
||||
|
||||
### 7. Factory Reset integration
|
||||
|
||||
In `clearLocalPreferences`:
|
||||
|
||||
1. Suspend and discard every pending key for which `isPrefKey(key)` is true.
|
||||
2. Enumerate and remove durable preference keys exactly as today.
|
||||
3. Preserve connection credentials and user-data keys exactly as today.
|
||||
|
||||
The suspension lasts for the remainder of the successful reset session, because background store activity can occur during the 400 ms before reload. Wrap the entire enumerate-and-remove transaction, including `length`, `key()`, and key filtering/access, so any failure resumes writes before rethrowing. This prevents the existing reset error path from leaving persistence silently disabled. This ordering is mandatory: a stale timer, a new post-reset store update, or the later `pagehide` could otherwise resurrect `omnivoice.app` or `omni_ui` after deletion. Tests that simulate a successful reset without a real reload must explicitly reset the isolated writer afterward.
|
||||
|
||||
## File-level change budget
|
||||
|
||||
| File | Change |
|
||||
| --- | --- |
|
||||
| `frontend/src/utils/coalescedJsonStorage.ts` | New lazy scheduler, Zustand adapter, role configuration, suspension, and lifecycle ownership |
|
||||
| `frontend/src/utils/coalescedJsonStorage.test.ts` | New deterministic scheduler/failure/lifecycle/widget tests |
|
||||
| `frontend/src/store/index.ts` | Swap storage adapter only; preserve projection and migrations |
|
||||
| `frontend/src/store/persistenceScheduling.test.ts` | New Zustand envelope, coalescing, hydration, and long-form projection tests |
|
||||
| `frontend/src/hooks/useAppData.js` | Gate restore readiness and queue the existing `omni_ui` value provider |
|
||||
| `frontend/src/hooks/useAppData.persistence.test.jsx` | New restore and burst-write integration tests |
|
||||
| `frontend/src/main-app.jsx` | Configure the resolved window role, then install main-only lifecycle flushing |
|
||||
| `frontend/src/main-app.test.jsx` | Extend label/marker/URL role-order coverage |
|
||||
| `frontend/src/utils/prefKeys.js` | Suspend pending and future preference writes across successful reset |
|
||||
| `frontend/src/utils/prefKeys.test.js` | Add no-resurrection coverage |
|
||||
| `frontend/src/utils/donationMoments.test.js` | Preserve immediate primary opt-out and flushed legacy fallback behavior |
|
||||
| `frontend/e2e-perf/responsiveness.spec.ts` | Add opt-in production-bundle fixture, route mocks, instrumentation, and JSON artifact; no wall-clock CI assertions |
|
||||
| `frontend/playwright.perf.config.ts` | Add cross-platform production-preview benchmark config derived from the existing prod smoke config |
|
||||
| `CHANGELOG.md` | One Unreleased performance/fix line once the PR number exists |
|
||||
|
||||
No backend, locale, package manifest, lockfile, or persisted-schema file should change.
|
||||
|
||||
## Implementation sequence
|
||||
|
||||
### Task 0: Freeze the current contracts
|
||||
|
||||
- [ ] Record the parent commit SHA and rerun the browser baseline with identical fixtures.
|
||||
- [ ] Add characterization assertions for the exact Zustand envelope, version, legacy snapshot keys, direct readers, and reset key registry; these must pass before production changes.
|
||||
- [ ] Add integration assertions for burst write counts and initial-default overwrite behavior; these must fail on the current immediate writer for the expected reason.
|
||||
- [ ] Confirm existing direct readers (`donationMoments`, E2E helpers) against the frozen fixture.
|
||||
- [ ] Audit the persisted Zustand projection and every `omni_ui` nested value for in-place mutation. Record the search paths in the PR; resolve any hit before adopting lazy providers.
|
||||
- [ ] Keep the current 35 targeted tests green while adding fail-before cases.
|
||||
|
||||
Exit condition: characterization tests pass; behavioral integration tests fail only because writes are immediate/repeated or startup persistence is ungated. Scheduler-specific unit tests are introduced with the new utility rather than pretending to fail before their seam exists.
|
||||
|
||||
### Task 1: Implement the storage primitive
|
||||
|
||||
- [ ] Implement per-key quiet and maximum timers with injected clock/storage/serializer dependencies.
|
||||
- [ ] Make value materialization and serialization lazy and deduplicate against the durable raw string.
|
||||
- [ ] Implement synchronous pending/durable reads.
|
||||
- [ ] Implement generation-bound provider disposers plus flush, discard, and removal guards.
|
||||
- [ ] Implement predicate-based suspension for destructive reset windows.
|
||||
- [ ] Define failed attempts as timer-disarmed; a later queue starts a new maximum window.
|
||||
- [ ] Isolate partial failures across multiple dirty keys.
|
||||
- [ ] Recover from throwing providers, durable reads, malformed JSON, and raw writes without poisoning later valid operations.
|
||||
- [ ] Deduplicate warnings and prove no value, serialized payload, or error message containing user content is logged.
|
||||
- [ ] Contain and deduplicate errors without logging payloads.
|
||||
- [ ] Add `unknown -> main|readonly` role configuration; unknown work cannot reach raw storage.
|
||||
- [ ] Make adapter removal obey cancellation, role, and error-propagation contracts.
|
||||
- [ ] Add single-owner lifecycle installation and idempotent teardown.
|
||||
- [ ] Add a full isolated-writer reset hook for tests: role, staged operations, suspensions, timers, listeners, and warning registry.
|
||||
|
||||
Exit condition: all utility tests pass without importing React or the application store.
|
||||
|
||||
### Task 2: Wire Zustand without changing its contract
|
||||
|
||||
- [ ] Replace `createJSONStorage` with the structured adapter.
|
||||
- [ ] Keep `partialize`, `version`, and `migrate` unchanged except for any mechanical key constant extraction needed by tests.
|
||||
- [ ] Prove that 100 rapid transient updates cause zero synchronous serializations/writes and at most one trailing write.
|
||||
- [ ] Prove the final JSON contains the latest persisted update and `{ version: 7 }`.
|
||||
- [ ] Prove `persist.clearStorage()` cannot be undone by timers/lifecycle and is inert in the widget role.
|
||||
- [ ] Update raw-seeded migration tests to reset pending/staged writer state before `rehydrate()`.
|
||||
- [ ] Prove long-form fields round-trip while `generating` and `audioUrl` remain excluded.
|
||||
- [ ] Prove v6-to-v7 and older accepted fixtures still hydrate synchronously.
|
||||
|
||||
Exit condition: existing store migration tests plus the new scheduling suite pass.
|
||||
|
||||
### Task 3: Wire `omni_ui`
|
||||
|
||||
- [ ] Extract snapshot construction only if needed for a precise shape test; do not redesign ownership.
|
||||
- [ ] Add the restore-complete state gate, then queue a latest-value provider rather than serializing in the effect.
|
||||
- [ ] Add a seeded-restore test proving the initial defaults never become the durable winner.
|
||||
- [ ] Dispatch lifecycle flush before the post-restore render and prove it writes no defaults.
|
||||
- [ ] Add a burst test proving the latest text and dub segment data win after one write.
|
||||
- [ ] Cover StrictMode double effects plus unmount/remount before the quiet timer; no obsolete provider may win.
|
||||
- [ ] Re-run schema, legacy-mode, and restored-dub-step tests unchanged.
|
||||
|
||||
Exit condition: a reload after explicit flush restores a deep-equal latest snapshot through `sanitizeOmniUi`.
|
||||
|
||||
### Task 4: Close lifecycle and reset races
|
||||
|
||||
- [ ] Configure the exact `detectIsWidget()` result before render, then install main-window lifecycle flushing.
|
||||
- [ ] Prove marker, Tauri-label-only, and legacy-URL detection; pre-role setters cannot leak from a widget.
|
||||
- [ ] Prove unknown-role set→remove ends removed, remove→set activates the set, and the 1-second clock starts at main-role activation.
|
||||
- [ ] Prove duplicate installation does not duplicate listeners and teardown removes the exact callbacks.
|
||||
- [ ] Prove hidden visibility plus `pagehide` produce at most one serialization/write for an unchanged pending generation.
|
||||
- [ ] Suspend pending and future preference values before Factory Reset removal.
|
||||
- [ ] Queue another store update, advance every fake timer, and dispatch lifecycle events after reset; both target keys must remain absent.
|
||||
- [ ] Prove raw removal and enumeration/access failures resume normal persistence before propagating the error.
|
||||
- [ ] Prove preserved connection/data keys remain untouched.
|
||||
- [ ] Prove standalone-widget setters and `persist.clearStorage()` cannot mutate durable state, while main-window operations still work.
|
||||
|
||||
Exit condition: neither stale timers, lifecycle events, StrictMode, nor the widget can overwrite newer or deliberately removed durable state.
|
||||
|
||||
### Task 5: Verify and document
|
||||
|
||||
- [ ] Run targeted tests during iteration.
|
||||
- [ ] Run frontend typecheck, lint, format check, full Vitest, build, and production-bundle smoke.
|
||||
- [ ] Run the repository's backend suites offline before landing, despite no backend diff, because they are merge gates.
|
||||
- [ ] Check in the opt-in Playwright benchmark with deterministic fixture generation and JSON output.
|
||||
- [ ] Run an alternating parent/implementation/parent (A/B/A) benchmark sequence with five repeats per leg; repeat if same-commit variance exceeds 5%.
|
||||
- [ ] Attach counts, payload sizes, p50/p95/max interaction latency, and long-task evidence to the PR.
|
||||
- [ ] Open the draft PR to obtain its number, then add/amend the Unreleased changelog line before requesting review.
|
||||
|
||||
Exit condition: deterministic acceptance criteria pass; build/merge gates are green; browser timing is attached as reproducible decision evidence rather than a hardware-sensitive CI gate.
|
||||
|
||||
## Required deterministic tests
|
||||
|
||||
| Scenario | Required result |
|
||||
| --- | --- |
|
||||
| 100 replacements in one burst | 0 synchronous provider/serializer/write calls; 1 trailing write with value 100 |
|
||||
| Lazy provider source changes before flush | Current-at-flush value is written; no deep clone or serialization occurred while queueing |
|
||||
| Obsolete provider disposer | Cancels only its generation; it cannot cancel a newer provider for the same key |
|
||||
| Continuous updates beyond 1 second | A maximum-wait flush occurs; later updates start a new window |
|
||||
| Identical durable value | Serialization may occur at flush; physical `setItem` is skipped |
|
||||
| Explicit `getItem` before flush | Latest pending structured value is returned synchronously |
|
||||
| Hidden document followed by `pagehide` | At most one serialization/write for the unchanged pending generation |
|
||||
| Cancel/remove followed by all timers | Deleted key stays absent |
|
||||
| Zustand `persist.clearStorage()` | Pending/staged key is cancelled; timer/lifecycle cannot resurrect it |
|
||||
| Successful reset followed by a new store update | Matching writes remain suspended and deleted keys stay absent until reload |
|
||||
| Failed reset removal | Error propagates and write suspension is released |
|
||||
| Reset enumeration/access failure | Error propagates and write suspension is released |
|
||||
| Serialization error | Caller does not throw; invalid entry does not poison a later valid update |
|
||||
| Provider throws | Caller/lifecycle does not crash; invalid entry is discarded and a later valid provider succeeds |
|
||||
| Durable `getItem` throws | Hydration falls back to defaults without crashing; a later valid queue can persist |
|
||||
| Malformed durable JSON | Hydration follows the current safe fallback/migration behavior and later persistence repairs it |
|
||||
| Quota/security error | Caller does not throw; old durable value remains; timers do not retry; one later queue starts one new window |
|
||||
| Two-key partial failure | Successful key stays clean; failed key alone retries later |
|
||||
| Unknown staged set→remove / remove→set | Only the final operation activates on `main`; its clocks start at activation |
|
||||
| Unknown/standalone-widget update and removal | Reads work; no raw mutation before role resolution or after read-only resolution |
|
||||
| Duplicate lifecycle installation/teardown | One listener set; exact callbacks are removed once |
|
||||
| Zustand transient burst | At most one `omnivoice.app` write and unchanged v7 envelope |
|
||||
| Legacy recovery burst | At most one `omni_ui` write with latest text/segments |
|
||||
| Seeded initial recovery | Defaults never overwrite restored state, including immediate lifecycle and StrictMode/unmount races |
|
||||
| Factory Reset race | Both pending target keys remain absent after timers and lifecycle events |
|
||||
| Donation opt-out compatibility | Primary opt-out remains immediately visible; flushed v7 legacy fallback remains readable |
|
||||
| Repeated warning | One warning per key/operation/error class; no value, serialized payload, or content-bearing error message appears |
|
||||
|
||||
Do not use elapsed milliseconds as Vitest pass/fail assertions. Use fake timers and call counts for CI; use browser traces for performance evidence.
|
||||
|
||||
## Verification commands
|
||||
|
||||
Run targeted tests while iterating:
|
||||
|
||||
```powershell
|
||||
cd frontend
|
||||
bun run test -- src/utils/coalescedJsonStorage.test.ts src/store/persistenceScheduling.test.ts src/hooks/useAppData.persistence.test.jsx src/main-app.test.jsx src/utils/prefKeys.test.js src/utils/donationMoments.test.js src/test/omniUiSchema.test.js src/test/dubStepRestoreClamp.test.js src/store/uiScaleMigration.test.ts
|
||||
```
|
||||
|
||||
Run the frontend landing gate:
|
||||
|
||||
```powershell
|
||||
cd frontend
|
||||
bun run typecheck:ci
|
||||
bun run lint
|
||||
bun run format:check
|
||||
bun run test
|
||||
bun run test:prod-bundle
|
||||
bun run test:legacy
|
||||
```
|
||||
|
||||
`test:prod-bundle` already performs the production build before its smoke test, so a separate `bun run build` would only duplicate work. Run it separately only when build output is needed during iteration.
|
||||
|
||||
Run the backend CI-equivalent suites from the repository root with a genuinely empty Hugging Face cache:
|
||||
|
||||
```powershell
|
||||
$previousOffline = $env:HF_HUB_OFFLINE
|
||||
$previousCache = $env:HF_HUB_CACHE
|
||||
$tempRoot = [IO.Path]::GetFullPath([IO.Path]::GetTempPath())
|
||||
$emptyHfCache = [IO.Path]::GetFullPath((Join-Path $tempRoot ("omnivoice-hf-empty-" + [guid]::NewGuid())))
|
||||
if (-not $emptyHfCache.StartsWith($tempRoot, [StringComparison]::OrdinalIgnoreCase)) { throw 'Unsafe cache path' }
|
||||
New-Item -ItemType Directory -Path $emptyHfCache | Out-Null
|
||||
try {
|
||||
if (@(Get-ChildItem -LiteralPath $emptyHfCache -Force).Count -ne 0) { throw 'HF cache is not empty' }
|
||||
$env:HF_HUB_OFFLINE = '1'
|
||||
$env:HF_HUB_CACHE = $emptyHfCache
|
||||
uv run --no-sync pytest tests/ -q --tb=short
|
||||
if ($LASTEXITCODE -ne 0) { throw "tests/ failed with exit code $LASTEXITCODE" }
|
||||
uv run --no-sync pytest backend/tests/ -q --tb=short
|
||||
if ($LASTEXITCODE -ne 0) { throw "backend/tests/ failed with exit code $LASTEXITCODE" }
|
||||
} finally {
|
||||
$env:HF_HUB_OFFLINE = $previousOffline
|
||||
$env:HF_HUB_CACHE = $previousCache
|
||||
Remove-Item -LiteralPath $emptyHfCache -Recurse -Force
|
||||
}
|
||||
```
|
||||
|
||||
These are repository landing gates, not evidence that the frontend optimization itself works. The unique cache and restored environment prevent a populated developer cache or leaked shell state from masking failures.
|
||||
|
||||
## Browser validation protocol
|
||||
|
||||
Check in `frontend/e2e-perf/responsiveness.spec.ts` and `frontend/playwright.perf.config.ts` as a non-CI production-bundle benchmark harness. Keeping it outside `e2e-prod/` ensures the existing production-smoke CI command cannot discover this manual benchmark. The config must mirror `playwright.prod.config.ts`: build the real `dist/`, serve it with `vite preview` on a dedicated strict port, honor `PLAYWRIGHT_CHROMIUM`, use `/usr/bin/chromium` only when it exists, and otherwise fall back to Playwright's bundled browser. It must not use the dev-server E2E config.
|
||||
|
||||
The spec must generate fixtures from fixed seeds, install all required API/WebSocket route mocks or a deterministic bootstrap bypass before navigation, and make no assumption that a backend is running on port 3900. It must use `page.addInitScript` before application code to wrap target-key storage writes and `PerformanceObserver`, drive selectors rather than arbitrary sleeps, and emit machine-readable JSON under Playwright's `test-results` directory. It asserts final state and observable deterministic write counts, but it does not assert elapsed milliseconds or claim to observe serializer task identity. The injected Vitest scheduler tests own the stronger “no provider/serializer execution in the originating task” assertion.
|
||||
|
||||
Run it with:
|
||||
|
||||
```powershell
|
||||
cd frontend
|
||||
node ./node_modules/@playwright/test/cli.js test --config=playwright.perf.config.ts responsiveness.spec.ts --repeat-each=5 --reporter=line
|
||||
```
|
||||
|
||||
Run `bun install --frozen-lockfile` first. The command above is verified from `frontend/` to resolve the installed Playwright 1.61.0 CLI by exact package path; do not replace it with `bun x playwright` or a global `bun run` shim, which can select another Playwright version, fetch a package, or even resolve a stale Windows shim. If `PLAYWRIGHT_CHROMIUM` is unset and no supported system Chromium exists, install the pinned browser once with `node ./node_modules/@playwright/test/cli.js install chromium`. This adds no project dependency, and the dedicated config provides the cross-platform executable fallback. The config owns port 4174 and never reuses an existing listener, so a stale preview fails loudly and every successful run tears down the exact server it started.
|
||||
|
||||
Use the same browser version, build mode, machine power state, and fixture on both commits.
|
||||
|
||||
1. Instrument target-key `setItem` count, serialized byte length, and call duration before the app loads.
|
||||
2. Observe long tasks and event-to-next-`requestAnimationFrame` latency.
|
||||
3. Seed 1,800 dub segments and 400 story tracks using the current v7/legacy formats.
|
||||
4. Run 20 UI-scale updates 25 ms apart, keeping the complete burst below the hard maximum.
|
||||
5. Run 20 Studio text updates under the same cadence.
|
||||
6. End each burst, wait 1,250 ms, and verify the durable latest values by parsing both keys.
|
||||
7. Run A/B/A (parent, implementation, parent), five repeats per leg; compare median p95 and retain every JSON artifact.
|
||||
8. Run the 3,000/3,000 fixture once as a diagnostic stress case, not as a product limit.
|
||||
|
||||
Deterministic merge gates:
|
||||
|
||||
- A sub-1-second 20-event burst produces no more than one physical write per target key after the burst: at least a 96% reduction from the measured 60 target writes.
|
||||
- Injected utility/integration tests prove no target-key provider, serialization, or write executes in the originating input task; the browser harness independently verifies observable physical writes.
|
||||
- Both parsed durable values contain the final interaction's state.
|
||||
|
||||
Manual decision thresholds, not CI merge gates:
|
||||
|
||||
- Target at least 20% lower median p95 input-to-frame latency on the representative fixture.
|
||||
- Target no more than 5% median-p95 regression on the small fixture.
|
||||
- Expect no greater-than-50-ms task during the interaction burst with persistence work in its trace stack.
|
||||
- If either target is missed or same-commit A/A variance exceeds 5%, treat the timing as inconclusive, attach the raw artifacts, and re-profile. Do not widen this PR merely to manufacture a favorable number.
|
||||
|
||||
## Acceptance criteria
|
||||
|
||||
The PR is ready for review only when all are true:
|
||||
|
||||
- [ ] Existing keys, field sets, JSON envelope, version, migrations, and restore behavior are unchanged.
|
||||
- [ ] One burst yields at most one trailing write per dirty key and the newest value wins.
|
||||
- [ ] Normal continuous input schedules an attempt within 1 second; failure and timer-throttling limits are documented accurately.
|
||||
- [ ] With healthy storage, orderly hide/navigation flushes synchronously and a hard process termination can lose at most the scheduled unflushed window; failure/throttling exceptions are documented.
|
||||
- [ ] Factory Reset cannot be undone by pending work.
|
||||
- [ ] Unknown-role work cannot reach raw storage, and the standalone widget cannot write or remove main-window preferences.
|
||||
- [ ] Storage failures cannot crash input handling and never leak user content to logs.
|
||||
- [ ] Deterministic tests meet merge gates; the checked-in A/B/A benchmark and raw timing artifacts are attached as non-CI decision evidence.
|
||||
- [ ] Frontend and backend merge gates pass.
|
||||
- [ ] No dependency, lockfile, locale, backend, persisted-version, or package-version change is present.
|
||||
- [ ] The PR remains reviewable as one persistence concern; no opportunistic refactor is included.
|
||||
|
||||
## Risks and mitigations
|
||||
|
||||
| Risk | Mitigation |
|
||||
| --- | --- |
|
||||
| Up to the scheduled window of edits lost on a hard process kill | 250 ms quiet flush, 1,000 ms maximum attempt, hidden/pagehide flush; disclose timer/storage limitations |
|
||||
| Pending or newly queued write recreates reset data | Suspend by `isPrefKey` before raw removal; post-reset update + timer + lifecycle regression test |
|
||||
| Widget flushes stale main-window state | Resolve the existing detector before render; unknown cannot write; widget set/remove operations stay read-only |
|
||||
| Older timer overwrites a newer value | Per-key generation token and last-value-wins tests |
|
||||
| Mutable data changes before deferred serialization | Lazy current-value provider plus a documented mutation audit; never claim event-time snapshot semantics |
|
||||
| Quota or disabled storage breaks the UI | Contain write errors, preserve the previous durable blob, disarm timers, retry only on later activity/explicit flush |
|
||||
| Concurrent browser tabs overwrite each other | Keep the unsupported last-physical-writer boundary explicit; do not add an incomplete conflict protocol here |
|
||||
| Trailing flush is still expensive for pathological documents | Measure it; do not hide it. Escalate to document storage/worker design in a separate PR if representative flush exceeds the budget |
|
||||
| Middleware contract accidentally changes | Exact envelope/fixture tests plus existing migration and direct-reader suites |
|
||||
| Lifecycle listeners duplicate in development/tests | One production owner, isolated test instances, idempotent teardown, and duplicate-install test |
|
||||
| Timing benchmark flakes in CI | Keep wall-clock evidence informational/manual; gate deterministic operation counts |
|
||||
|
||||
## Rollback plan
|
||||
|
||||
No data rollback or migration is required. Reverting the adapter wiring restores immediate writes, and both old and new builds read the same `omnivoice.app` v7 envelope and `omni_ui` object. If a release-only issue appears, revert the PR rather than introducing a second persistence mode or format.
|
||||
|
||||
## Follow-up queue
|
||||
|
||||
These are intentionally not part of the first PR:
|
||||
|
||||
1. **Incremental dub scheduling.** Add a 300 ms debounce, pass `AbortController.signal` through `apiPost`, use a monotonic request revision, cancel outside Dub, and prove one request per burst plus stale-response rejection.
|
||||
2. **Transactional dub undo.** Profile `pushUndo`, which currently stringifies the complete segment array per edit and retains up to 50 snapshots. If material, group edits by segment/field and focus or idle boundary while preserving one-step undo behavior.
|
||||
3. **Workspace isolation.** Profile React commits after persistence remediation; then extract one workspace at a time, moving heavy hooks/imports behind lazy boundaries. Source length and selector count alone are not success metrics.
|
||||
4. **Document storage migration.** Consider IndexedDB or a worker only if representative post-PR flushes remain over budget. That work requires an independent migration, downgrade, reset, quota, and async-hydration design.
|
||||
|
||||
Each follow-up must begin from a fresh trace. None should be pulled into this PR merely because it is nearby.
|
||||
@@ -0,0 +1,529 @@
|
||||
import { expect, test, type Page, type TestInfo } from '@playwright/test';
|
||||
import { writeFile } from 'node:fs/promises';
|
||||
|
||||
const APP_STORE_KEY = 'omnivoice.app';
|
||||
const OMNI_UI_KEY = 'omni_ui';
|
||||
const TARGET_KEYS = [APP_STORE_KEY, OMNI_UI_KEY] as const;
|
||||
const UPDATE_COUNT = 20;
|
||||
const UPDATE_INTERVAL_MS = 25;
|
||||
const TRAILING_FLUSH_SETTLE_MS = 1_250;
|
||||
|
||||
type TargetKey = (typeof TARGET_KEYS)[number];
|
||||
|
||||
interface PhysicalWrite {
|
||||
phase: string;
|
||||
key: TargetKey;
|
||||
atMs: number;
|
||||
bytes: number;
|
||||
durationMs: number;
|
||||
}
|
||||
|
||||
interface LongTaskSample {
|
||||
phase: string;
|
||||
atMs: number;
|
||||
durationMs: number;
|
||||
}
|
||||
|
||||
interface InputFrameSample {
|
||||
phase: string;
|
||||
target: 'ui-scale' | 'studio-text';
|
||||
atMs: number;
|
||||
durationMs: number;
|
||||
}
|
||||
|
||||
interface BrowserMetrics {
|
||||
phase: string;
|
||||
writes: PhysicalWrite[];
|
||||
longTasks: LongTaskSample[];
|
||||
inputToNextRaf: InputFrameSample[];
|
||||
}
|
||||
|
||||
declare global {
|
||||
interface Window {
|
||||
__OV_WINDOW__?: string;
|
||||
__OMNIVOICE_API_BASE__?: string;
|
||||
__ovResponsivenessMetrics?: BrowserMetrics;
|
||||
__ovSetResponsivenessPhase?: (phase: string) => void;
|
||||
}
|
||||
}
|
||||
|
||||
function makeStoryTracks() {
|
||||
return Array.from({ length: 400 }, (_, index) => ({
|
||||
id: index + 1,
|
||||
character: index % 2 === 0 ? 'narrator' : 'guest',
|
||||
text: `Story track ${index.toString().padStart(3, '0')} ${'narration '.repeat(8)}`,
|
||||
profileId: null,
|
||||
emotion: index % 3 === 0 ? 'warm' : null,
|
||||
speed: 1,
|
||||
}));
|
||||
}
|
||||
|
||||
function makeDubSegments() {
|
||||
return Array.from({ length: 1_800 }, (_, index) => ({
|
||||
id: `segment-${index.toString().padStart(4, '0')}`,
|
||||
start: index * 2.5,
|
||||
end: index * 2.5 + 2.25,
|
||||
speaker: index % 2 === 0 ? 'SPEAKER_00' : 'SPEAKER_01',
|
||||
text_original: `Original line ${index} ${'source '.repeat(7)}`,
|
||||
text: `Translated line ${index} ${'target '.repeat(7)}`,
|
||||
profile_id: null,
|
||||
direction: '',
|
||||
}));
|
||||
}
|
||||
|
||||
function persistedFixtures() {
|
||||
return {
|
||||
app: {
|
||||
state: {
|
||||
mode: 'settings',
|
||||
defineMethod: 'audio',
|
||||
uiScale: 1,
|
||||
uiScaleConfigured: true,
|
||||
navStyle: 'rail',
|
||||
locale: 'en',
|
||||
localeChosen: true,
|
||||
langPromptSeen: true,
|
||||
storyTracks: makeStoryTracks(),
|
||||
},
|
||||
version: 7,
|
||||
},
|
||||
omniUi: {
|
||||
uiScale: 1,
|
||||
text: 'Seeded studio text',
|
||||
mode: 'settings',
|
||||
defineMethod: 'audio',
|
||||
vdStates: {
|
||||
Gender: 'Auto',
|
||||
Age: 'Auto',
|
||||
Pitch: 'Auto',
|
||||
Style: 'Auto',
|
||||
EnglishAccent: 'Auto',
|
||||
ChineseDialect: 'Auto',
|
||||
},
|
||||
language: 'Auto',
|
||||
isSidebarCollapsed: false,
|
||||
sidebarTab: 'projects',
|
||||
dubJobId: 'responsiveness-fixture',
|
||||
dubFilename: 'responsiveness-fixture.mp4',
|
||||
dubDuration: 4_500,
|
||||
dubSegments: makeDubSegments(),
|
||||
dubLang: 'English',
|
||||
dubLangCode: 'en',
|
||||
dubTracks: [],
|
||||
dubStep: 'editing',
|
||||
dubTranscript: '',
|
||||
exportTracks: {},
|
||||
preserveBg: true,
|
||||
defaultTrack: 'dialogue',
|
||||
exportHistory: [],
|
||||
speed: 1,
|
||||
steps: 16,
|
||||
cfg: 2,
|
||||
denoise: true,
|
||||
showOverrides: false,
|
||||
},
|
||||
};
|
||||
}
|
||||
|
||||
async function installDeterministicBrowserState(page: Page): Promise<Set<string>> {
|
||||
const fixtures = persistedFixtures();
|
||||
const unexpectedRequests = new Set<string>();
|
||||
await page.addInitScript(
|
||||
({ appKey, omniUiKey, app, omniUi }) => {
|
||||
// Fix window identity and API routing before any application module runs.
|
||||
window.__OV_WINDOW__ = 'main';
|
||||
window.__OMNIVOICE_API_BASE__ = window.location.origin;
|
||||
|
||||
// Seed through the native method so fixture setup is not counted as an
|
||||
// application write. Both payloads intentionally match production schema.
|
||||
const nativeSetItem = Storage.prototype.setItem;
|
||||
nativeSetItem.call(localStorage, appKey, JSON.stringify(app));
|
||||
nativeSetItem.call(localStorage, omniUiKey, JSON.stringify(omniUi));
|
||||
nativeSetItem.call(localStorage, 'omnivoice.settings.category', 'appearance');
|
||||
|
||||
const targetKeys = new Set([appKey, omniUiKey]);
|
||||
const metrics: BrowserMetrics = {
|
||||
phase: 'startup',
|
||||
writes: [],
|
||||
longTasks: [],
|
||||
inputToNextRaf: [],
|
||||
};
|
||||
window.__ovResponsivenessMetrics = metrics;
|
||||
window.__ovSetResponsivenessPhase = (phase) => {
|
||||
metrics.phase = phase;
|
||||
};
|
||||
|
||||
Storage.prototype.setItem = function setItem(key: string, value: string): void {
|
||||
const startedAt = performance.now();
|
||||
try {
|
||||
nativeSetItem.call(this, key, value);
|
||||
} finally {
|
||||
if (targetKeys.has(key)) {
|
||||
const durationMs = performance.now() - startedAt;
|
||||
metrics.writes.push({
|
||||
phase: metrics.phase,
|
||||
key: key as TargetKey,
|
||||
atMs: startedAt,
|
||||
// Encode after the native call so byte accounting is excluded
|
||||
// from the measured physical-storage duration.
|
||||
bytes: new TextEncoder().encode(value).byteLength,
|
||||
durationMs,
|
||||
});
|
||||
}
|
||||
}
|
||||
};
|
||||
|
||||
document.addEventListener(
|
||||
'input',
|
||||
(event) => {
|
||||
const target = event.target;
|
||||
if (!(target instanceof HTMLElement)) return;
|
||||
const sampleTarget = target.matches('.appearance-panel input[type="range"]')
|
||||
? 'ui-scale'
|
||||
: target.matches('textarea.studio-script-input')
|
||||
? 'studio-text'
|
||||
: null;
|
||||
if (!sampleTarget) return;
|
||||
const startedAt = performance.now();
|
||||
requestAnimationFrame(() => {
|
||||
metrics.inputToNextRaf.push({
|
||||
phase: metrics.phase,
|
||||
target: sampleTarget,
|
||||
atMs: startedAt,
|
||||
durationMs: performance.now() - startedAt,
|
||||
});
|
||||
});
|
||||
},
|
||||
true,
|
||||
);
|
||||
|
||||
if (
|
||||
'PerformanceObserver' in window &&
|
||||
PerformanceObserver.supportedEntryTypes?.includes('longtask')
|
||||
) {
|
||||
const observer = new PerformanceObserver((list) => {
|
||||
for (const entry of list.getEntries()) {
|
||||
metrics.longTasks.push({
|
||||
phase: metrics.phase,
|
||||
atMs: entry.startTime,
|
||||
durationMs: entry.duration,
|
||||
});
|
||||
}
|
||||
});
|
||||
observer.observe({ type: 'longtask', buffered: true });
|
||||
}
|
||||
|
||||
// Keep the realtime hook deterministic and fully local while preserving
|
||||
// the handler and EventTarget surfaces used by capture/realtime clients.
|
||||
class DeterministicWebSocket extends EventTarget {
|
||||
static readonly CONNECTING = 0;
|
||||
static readonly OPEN = 1;
|
||||
static readonly CLOSING = 2;
|
||||
static readonly CLOSED = 3;
|
||||
|
||||
readonly url: string;
|
||||
readyState = DeterministicWebSocket.CONNECTING;
|
||||
onopen: ((event: Event) => void) | null = null;
|
||||
onmessage: ((event: MessageEvent) => void) | null = null;
|
||||
onerror: ((event: Event) => void) | null = null;
|
||||
onclose: ((event: CloseEvent) => void) | null = null;
|
||||
|
||||
constructor(url: string | URL) {
|
||||
super();
|
||||
this.url = String(url);
|
||||
queueMicrotask(() => {
|
||||
if (this.readyState !== DeterministicWebSocket.CONNECTING) return;
|
||||
this.readyState = DeterministicWebSocket.OPEN;
|
||||
const event = new Event('open');
|
||||
this.dispatchEvent(event);
|
||||
this.onopen?.(event);
|
||||
});
|
||||
}
|
||||
|
||||
send(): void {}
|
||||
|
||||
close(): void {
|
||||
if (this.readyState === DeterministicWebSocket.CLOSED) return;
|
||||
this.readyState = DeterministicWebSocket.CLOSED;
|
||||
const event = new CloseEvent('close', { code: 1000, wasClean: true });
|
||||
this.dispatchEvent(event);
|
||||
this.onclose?.(event);
|
||||
}
|
||||
}
|
||||
|
||||
Object.defineProperty(window, 'WebSocket', {
|
||||
configurable: true,
|
||||
writable: true,
|
||||
value: DeterministicWebSocket,
|
||||
});
|
||||
},
|
||||
{
|
||||
appKey: APP_STORE_KEY,
|
||||
omniUiKey: OMNI_UI_KEY,
|
||||
app: fixtures.app,
|
||||
omniUi: fixtures.omniUi,
|
||||
},
|
||||
);
|
||||
|
||||
// Production resolves API calls to the preview origin. Fulfil every
|
||||
// fetch/XHR deterministically, while allowing HTML, chunks, fonts and CSS to
|
||||
// come from the real production bundle under test.
|
||||
await page.route('**/*', async (route) => {
|
||||
const request = route.request();
|
||||
if (!['fetch', 'xhr'].includes(request.resourceType())) {
|
||||
await route.continue();
|
||||
return;
|
||||
}
|
||||
|
||||
const path = new URL(request.url()).pathname;
|
||||
const responseByPath: Record<string, unknown> = {
|
||||
'/health': { status: 'ok' },
|
||||
'/setup/status': {
|
||||
models_ready: true,
|
||||
missing: [],
|
||||
hf_cache_dir: '/deterministic/models',
|
||||
disk_free_gb: 100,
|
||||
min_free_gb: 1,
|
||||
enough_disk: true,
|
||||
},
|
||||
'/model/status': { status: 'idle', sub_stage: null, detail: '', error: null, progress: null },
|
||||
'/profiles': [],
|
||||
'/personalities': [],
|
||||
'/history': [],
|
||||
'/dub/history': [],
|
||||
'/projects': [],
|
||||
'/export/history': [],
|
||||
'/engines': {
|
||||
tts: { active: null, backends: [] },
|
||||
asr: { active: null, backends: [] },
|
||||
llm: { active: null, backends: [] },
|
||||
},
|
||||
'/sysinfo': { cpu: 0, ram: 0, total_ram: 32, vram: 0, gpu_active: false },
|
||||
'/system/info': { platform: 'benchmark', device: 'deterministic' },
|
||||
'/system/notifications': { notifications: [] },
|
||||
'/system/last-run-crash': { record: null, acknowledged: false },
|
||||
'/system/logs': { path: '', exists: false, lines: [] },
|
||||
'/system/logs/tauri': { path: '', exists: false, lines: [] },
|
||||
'/system/network/state': { enabled: false },
|
||||
'/dictation/prefs': {
|
||||
enabled: false,
|
||||
mode: 'toggle',
|
||||
model_id: 'sherpa-parakeet-tdt-v3',
|
||||
},
|
||||
'/workers': { enabled: false, running: false, workers: [] },
|
||||
'/workers/target': {
|
||||
target: 'local',
|
||||
active: { remote: false },
|
||||
targets: [
|
||||
{ id: 'local', label: 'Local', is_local: true, status: 'ready', available: true },
|
||||
],
|
||||
},
|
||||
'/api/settings/analytics': { available: false, prompted: true, opted_in: false },
|
||||
'/donation_progress.json': {
|
||||
raised: 10,
|
||||
goal: 200,
|
||||
currency: 'USD',
|
||||
sponsorCount: 1,
|
||||
updated: '2026-06-17',
|
||||
},
|
||||
};
|
||||
|
||||
const responseBody = responseByPath[path];
|
||||
if (responseBody === undefined) {
|
||||
unexpectedRequests.add(`${request.method()} ${path}`);
|
||||
await route.fulfill({
|
||||
status: 501,
|
||||
contentType: 'application/json',
|
||||
headers: { 'x-omnivoice-backend': '1' },
|
||||
body: JSON.stringify({ detail: 'Unhandled deterministic benchmark route' }),
|
||||
});
|
||||
return;
|
||||
}
|
||||
|
||||
await route.fulfill({
|
||||
status: 200,
|
||||
contentType: 'application/json',
|
||||
headers: { 'x-omnivoice-backend': '1' },
|
||||
body: JSON.stringify(responseBody),
|
||||
});
|
||||
});
|
||||
return unexpectedRequests;
|
||||
}
|
||||
|
||||
async function setPhase(page: Page, phase: string): Promise<void> {
|
||||
await page.evaluate((nextPhase) => window.__ovSetResponsivenessPhase?.(nextPhase), phase);
|
||||
}
|
||||
|
||||
async function driveNativeInputBurst(
|
||||
page: Page,
|
||||
selector: string,
|
||||
values: string[],
|
||||
): Promise<void> {
|
||||
await page.locator(selector).evaluate(
|
||||
async (node, burst) => {
|
||||
const element = node as HTMLInputElement | HTMLTextAreaElement;
|
||||
const prototype =
|
||||
element instanceof HTMLTextAreaElement
|
||||
? HTMLTextAreaElement.prototype
|
||||
: HTMLInputElement.prototype;
|
||||
const nativeValueSetter = Object.getOwnPropertyDescriptor(prototype, 'value')?.set;
|
||||
if (!nativeValueSetter) throw new Error(`No native value setter for ${element.tagName}`);
|
||||
|
||||
await new Promise<void>((resolve) => {
|
||||
// Schedule against one common origin. Measuring UI work must not add
|
||||
// another 25 ms after every handler and accidentally turn a 475 ms
|
||||
// burst into a >1 s stream that rightfully crosses the max-flush gate.
|
||||
burst.values.forEach((value, index) => {
|
||||
setTimeout(() => {
|
||||
nativeValueSetter.call(element, value);
|
||||
element.dispatchEvent(new Event('input', { bubbles: true, composed: true }));
|
||||
if (index === burst.values.length - 1) resolve();
|
||||
}, index * burst.intervalMs);
|
||||
});
|
||||
});
|
||||
},
|
||||
{ values, intervalMs: UPDATE_INTERVAL_MS },
|
||||
);
|
||||
}
|
||||
|
||||
async function readDurableValues(page: Page) {
|
||||
return page.evaluate(
|
||||
({ appKey, omniUiKey }) => ({
|
||||
app: JSON.parse(localStorage.getItem(appKey) || 'null'),
|
||||
omniUi: JSON.parse(localStorage.getItem(omniUiKey) || 'null'),
|
||||
}),
|
||||
{ appKey: APP_STORE_KEY, omniUiKey: OMNI_UI_KEY },
|
||||
);
|
||||
}
|
||||
|
||||
function writesFor(metrics: BrowserMetrics, phase: string, key: TargetKey): PhysicalWrite[] {
|
||||
return metrics.writes.filter((write) => write.phase === phase && write.key === key);
|
||||
}
|
||||
|
||||
async function writeReport(testInfo: TestInfo, report: unknown): Promise<void> {
|
||||
const artifactPath = testInfo.outputPath('responsiveness.json');
|
||||
await writeFile(artifactPath, `${JSON.stringify(report, null, 2)}\n`, 'utf8');
|
||||
await testInfo.attach('responsiveness.json', {
|
||||
path: artifactPath,
|
||||
contentType: 'application/json',
|
||||
});
|
||||
}
|
||||
|
||||
test('coalesces large-state persistence during rapid UI input', async ({ page }, testInfo) => {
|
||||
const unexpectedRequests = await installDeterministicBrowserState(page);
|
||||
await page.goto('/', { waitUntil: 'domcontentloaded' });
|
||||
|
||||
const listenerProbe = await page.evaluate(async () => {
|
||||
const socket = new WebSocket('ws://benchmark.invalid');
|
||||
let onceCalls = 0;
|
||||
let removedCalls = 0;
|
||||
const removedListener = () => {
|
||||
removedCalls += 1;
|
||||
};
|
||||
socket.addEventListener(
|
||||
'open',
|
||||
() => {
|
||||
onceCalls += 1;
|
||||
},
|
||||
{ once: true },
|
||||
);
|
||||
socket.addEventListener('open', removedListener);
|
||||
socket.removeEventListener('open', removedListener);
|
||||
await Promise.resolve();
|
||||
socket.dispatchEvent(new Event('open'));
|
||||
socket.close();
|
||||
return { onceCalls, removedCalls };
|
||||
});
|
||||
expect(listenerProbe).toEqual({ onceCalls: 1, removedCalls: 0 });
|
||||
|
||||
const scaleSelector = '.appearance-panel input[type="range"]';
|
||||
await expect(page.locator(scaleSelector)).toBeVisible();
|
||||
|
||||
// Let startup restoration and its trailing persistence window fully settle;
|
||||
// subsequent records are phase-labelled and attributable to one burst.
|
||||
await page.waitForTimeout(TRAILING_FLUSH_SETTLE_MS);
|
||||
|
||||
const scaleValues = Array.from({ length: UPDATE_COUNT }, (_, index) =>
|
||||
(0.65 + index * 0.05).toFixed(2),
|
||||
);
|
||||
const finalScale = Number(scaleValues.at(-1));
|
||||
await setPhase(page, 'ui-scale');
|
||||
await driveNativeInputBurst(page, scaleSelector, scaleValues);
|
||||
await page.waitForTimeout(TRAILING_FLUSH_SETTLE_MS);
|
||||
|
||||
const afterScale = await readDurableValues(page);
|
||||
expect(afterScale.app?.state?.uiScale).toBe(finalScale);
|
||||
expect(afterScale.omniUi?.uiScale).toBe(finalScale);
|
||||
|
||||
// Navigate through the real production UI. Waiting before phase assignment
|
||||
// prevents the navigation write from being counted as a text-input write.
|
||||
await setPhase(page, 'navigation');
|
||||
await page.locator('.nav-rail button[aria-label="Voice"]').click();
|
||||
const textSelector = 'textarea.studio-script-input';
|
||||
await expect(page.locator(textSelector)).toBeVisible();
|
||||
await page.waitForTimeout(TRAILING_FLUSH_SETTLE_MS);
|
||||
|
||||
const textValues = Array.from(
|
||||
{ length: UPDATE_COUNT },
|
||||
(_, index) => `responsiveness-${index.toString().padStart(2, '0')}-${'voice '.repeat(8)}`,
|
||||
);
|
||||
const finalText = textValues.at(-1);
|
||||
await setPhase(page, 'studio-text');
|
||||
await driveNativeInputBurst(page, textSelector, textValues);
|
||||
await page.waitForTimeout(TRAILING_FLUSH_SETTLE_MS);
|
||||
|
||||
const durable = await readDurableValues(page);
|
||||
const metrics = await page.evaluate(() => window.__ovResponsivenessMetrics as BrowserMetrics);
|
||||
|
||||
const report = {
|
||||
schemaVersion: 1,
|
||||
fixture: { appStoreVersion: 7, storyTracks: 400, dubSegments: 1_800 },
|
||||
burst: { updates: UPDATE_COUNT, requestedIntervalMs: UPDATE_INTERVAL_MS },
|
||||
durable: {
|
||||
appUiScale: durable.app?.state?.uiScale,
|
||||
omniUiScale: durable.omniUi?.uiScale,
|
||||
omniUiText: durable.omniUi?.text,
|
||||
},
|
||||
phases: {
|
||||
uiScale: {
|
||||
writes: Object.fromEntries(
|
||||
TARGET_KEYS.map((key) => [key, writesFor(metrics, 'ui-scale', key)]),
|
||||
),
|
||||
inputToNextRaf: metrics.inputToNextRaf.filter((sample) => sample.phase === 'ui-scale'),
|
||||
longTasks: metrics.longTasks.filter((sample) => sample.phase === 'ui-scale'),
|
||||
},
|
||||
studioText: {
|
||||
writes: Object.fromEntries(
|
||||
TARGET_KEYS.map((key) => [key, writesFor(metrics, 'studio-text', key)]),
|
||||
),
|
||||
inputToNextRaf: metrics.inputToNextRaf.filter((sample) => sample.phase === 'studio-text'),
|
||||
longTasks: metrics.longTasks.filter((sample) => sample.phase === 'studio-text'),
|
||||
},
|
||||
},
|
||||
startup: {
|
||||
writes: metrics.writes.filter((write) => write.phase === 'startup'),
|
||||
longTasks: metrics.longTasks.filter((sample) => sample.phase === 'startup'),
|
||||
},
|
||||
network: { unexpectedRequests: [...unexpectedRequests].sort() },
|
||||
};
|
||||
await writeReport(testInfo, report);
|
||||
|
||||
expect(durable.omniUi?.text).toBe(finalText);
|
||||
expect([...unexpectedRequests].sort(), 'every fetch/XHR must have an explicit fixture').toEqual(
|
||||
[],
|
||||
);
|
||||
expect(metrics.inputToNextRaf.filter((sample) => sample.phase === 'ui-scale')).toHaveLength(
|
||||
UPDATE_COUNT,
|
||||
);
|
||||
expect(metrics.inputToNextRaf.filter((sample) => sample.phase === 'studio-text')).toHaveLength(
|
||||
UPDATE_COUNT,
|
||||
);
|
||||
for (const phase of ['ui-scale', 'studio-text']) {
|
||||
for (const key of TARGET_KEYS) {
|
||||
expect(
|
||||
writesFor(metrics, phase, key).length,
|
||||
`${phase} should physically write ${key} no more than once`,
|
||||
).toBeLessThanOrEqual(1);
|
||||
}
|
||||
}
|
||||
});
|
||||
+42
-42
@@ -27,67 +27,67 @@
|
||||
"test:visual:update": "playwright test --config=playwright.visual.config.ts --update-snapshots"
|
||||
},
|
||||
"dependencies": {
|
||||
"@fontsource-variable/inter": "^5.2.8",
|
||||
"@fontsource-variable/source-serif-4": "^5.2.9",
|
||||
"@fontsource/ibm-plex-mono": "^5.2.7",
|
||||
"@radix-ui/react-dialog": "^1.1.17",
|
||||
"@radix-ui/react-dropdown-menu": "^2.1.18",
|
||||
"@radix-ui/react-progress": "^1.1.10",
|
||||
"@radix-ui/react-select": "^2.3.1",
|
||||
"@radix-ui/react-slider": "^1.4.1",
|
||||
"@radix-ui/react-slot": "^1.3.0",
|
||||
"@radix-ui/react-tabs": "^1.1.15",
|
||||
"@radix-ui/react-toggle": "^1.1.12",
|
||||
"@radix-ui/react-toggle-group": "^1.1.13",
|
||||
"@radix-ui/react-tooltip": "^1.2.10",
|
||||
"@scalar/api-reference-react": "^0.9.52",
|
||||
"@tailwindcss/vite": "^4.3.1",
|
||||
"@tanstack/react-query": "^5.101.0",
|
||||
"@fontsource-variable/inter": "^5.3.0",
|
||||
"@fontsource-variable/source-serif-4": "^5.3.0",
|
||||
"@fontsource/ibm-plex-mono": "^5.3.0",
|
||||
"@radix-ui/react-dialog": "^1.1.23",
|
||||
"@radix-ui/react-dropdown-menu": "^2.1.24",
|
||||
"@radix-ui/react-progress": "^1.1.16",
|
||||
"@radix-ui/react-select": "^2.3.7",
|
||||
"@radix-ui/react-slider": "^1.4.7",
|
||||
"@radix-ui/react-slot": "^1.3.3",
|
||||
"@radix-ui/react-tabs": "^1.1.21",
|
||||
"@radix-ui/react-toggle": "^1.1.18",
|
||||
"@radix-ui/react-toggle-group": "^1.1.19",
|
||||
"@radix-ui/react-tooltip": "^1.2.16",
|
||||
"@scalar/api-reference-react": "^0.9.63",
|
||||
"@tailwindcss/vite": "^4.3.3",
|
||||
"@tanstack/react-query": "^5.101.4",
|
||||
"@tanstack/react-table": "^8.21.3",
|
||||
"@tanstack/react-virtual": "^3.14.3",
|
||||
"@tauri-apps/plugin-dialog": "^2.7.1",
|
||||
"@tanstack/react-virtual": "^3.14.9",
|
||||
"@tauri-apps/plugin-dialog": "^2.7.2",
|
||||
"@tauri-apps/plugin-opener": "^2.5.4",
|
||||
"@tauri-apps/plugin-process": "^2.3.1",
|
||||
"@tauri-apps/plugin-updater": "^2.10.1",
|
||||
"@tauri-apps/plugin-window-state": "^2.4.1",
|
||||
"class-variance-authority": "^0.7.1",
|
||||
"clsx": "^2.1.1",
|
||||
"country-flag-icons": "^1.6.17",
|
||||
"i18next": "^26.3.1",
|
||||
"country-flag-icons": "^1.6.20",
|
||||
"i18next": "^26.3.6",
|
||||
"i18next-browser-languagedetector": "^8.2.1",
|
||||
"lucide-react": "^1.18.0",
|
||||
"posthog-js": "^1.399.2",
|
||||
"lucide-react": "^1.31.0",
|
||||
"posthog-js": "^1.417.0",
|
||||
"qrcode": "^1.5.4",
|
||||
"react": "^19.2.7",
|
||||
"react-dom": "^19.2.7",
|
||||
"react": "^19.2.8",
|
||||
"react-dom": "^19.2.8",
|
||||
"react-hot-toast": "^2.6.0",
|
||||
"react-i18next": "^17.0.8",
|
||||
"react-window": "^2.2.7",
|
||||
"react-i18next": "^17.0.11",
|
||||
"react-window": "^2.3.0",
|
||||
"tailwind-merge": "^3.6.0",
|
||||
"tailwindcss": "^4.3.1",
|
||||
"tailwindcss": "^4.3.3",
|
||||
"tw-animate-css": "^1.4.0",
|
||||
"wavesurfer.js": "^7.12.8",
|
||||
"zustand": "^5.0.14"
|
||||
"wavesurfer.js": "^7.12.11",
|
||||
"zustand": "^5.0.15"
|
||||
},
|
||||
"devDependencies": {
|
||||
"@playwright/test": "^1.61.0",
|
||||
"@tauri-apps/api": "^2.11.0",
|
||||
"@tauri-apps/cli": "^2.11.2",
|
||||
"@playwright/test": "^1.62.1",
|
||||
"@tauri-apps/api": "^2.11.1",
|
||||
"@tauri-apps/cli": "^2.11.4",
|
||||
"@testing-library/jest-dom": "^6.9.1",
|
||||
"@testing-library/react": "^16.3.2",
|
||||
"@types/react": "^19.2.17",
|
||||
"@types/react-dom": "^19.2.3",
|
||||
"@vitejs/plugin-react": "^6.0.2",
|
||||
"eslint": "^10.5.0",
|
||||
"@types/react": "^19.2.18",
|
||||
"@types/react-dom": "^19.2.4",
|
||||
"@vitejs/plugin-react": "^6.0.5",
|
||||
"eslint": "^10.8.1",
|
||||
"eslint-plugin-react-hooks": "^7.1.1",
|
||||
"globals": "^17.6.0",
|
||||
"globals": "^17.11.0",
|
||||
"jsdom": "^29.1.1",
|
||||
"knip": "^6.23.0",
|
||||
"knip": "^6.32.2",
|
||||
"oxfmt": "^0.57.0",
|
||||
"oxlint": "^1.71.0",
|
||||
"playwright-core": "1.61.0",
|
||||
"oxlint": "1.71.0",
|
||||
"playwright-core": "1.62.1",
|
||||
"typescript": "^6.0.3",
|
||||
"vite": "^8.0.16",
|
||||
"vitest": "^4.1.9"
|
||||
"vite": "^8.2.1",
|
||||
"vitest": "4.1.9"
|
||||
}
|
||||
}
|
||||
|
||||
@@ -0,0 +1,47 @@
|
||||
import { defineConfig, devices } from '@playwright/test';
|
||||
import { existsSync } from 'node:fs';
|
||||
|
||||
// Opt-in production-bundle responsiveness benchmark. Keep it separate from
|
||||
// playwright.prod.config.ts: the smoke suite is a CI correctness gate, while
|
||||
// this harness records machine-dependent timing diagnostics for local review.
|
||||
const PORT = Number(process.env.E2E_PERF_PORT || 4174);
|
||||
|
||||
// An explicit browser wins; Linux CI/dev containers commonly provide a system
|
||||
// Chromium; contributors on Windows/macOS fall back to Playwright's bundle.
|
||||
const SYSTEM_CHROMIUM = '/usr/bin/chromium';
|
||||
const browserPath =
|
||||
process.env.PLAYWRIGHT_CHROMIUM || (existsSync(SYSTEM_CHROMIUM) ? SYSTEM_CHROMIUM : undefined);
|
||||
|
||||
export default defineConfig({
|
||||
testDir: './e2e-perf',
|
||||
testMatch: 'responsiveness.spec.ts',
|
||||
timeout: 120_000,
|
||||
expect: { timeout: 15_000 },
|
||||
fullyParallel: false,
|
||||
// `--repeat-each=5` is a variance sample, not five independent load tests.
|
||||
// Keep repeats serial so they do not contend with each other or distort the
|
||||
// input/long-task evidence on high-core development machines.
|
||||
workers: 1,
|
||||
retries: 0,
|
||||
reporter: [['list']],
|
||||
outputDir: 'test-results/responsiveness',
|
||||
use: {
|
||||
baseURL: `http://localhost:${PORT}`,
|
||||
headless: true,
|
||||
trace: 'retain-on-failure',
|
||||
...(browserPath ? { launchOptions: { executablePath: browserPath } } : {}),
|
||||
},
|
||||
projects: [{ name: 'chromium', use: { ...devices['Desktop Chrome'] } }],
|
||||
webServer: {
|
||||
// Playwright launches through the platform shell. Invoke the repo-pinned
|
||||
// Vite binary directly so Windows does not depend on whichever global Bun
|
||||
// shim happens to precede the checked-in toolchain on PATH.
|
||||
command: `node ./node_modules/vite/bin/vite.js build && node ./node_modules/vite/bin/vite.js preview --port ${PORT} --strictPort`,
|
||||
url: `http://localhost:${PORT}`,
|
||||
// Always own the production preview used for a measurement. Reusing an
|
||||
// arbitrary listener can benchmark stale dist bytes and leaves teardown
|
||||
// ownership ambiguous; a stale 4174 listener should fail loudly instead.
|
||||
reuseExistingServer: false,
|
||||
timeout: 180_000,
|
||||
},
|
||||
});
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user