 Tim Visée
040c79a7f6
* Add repro test for Gridstore stale-gaps allocation panic

The region gaps (gaps.dat) are an acceleration structure derived from
the bitmask (bitmask.dat), persisted to a separate file without
ordering guarantees. After an unclean shutdown (power loss, kernel
crash) the gaps can claim free space where the bitmask has the blocks
marked used. An allocation in that state panics with "New page has
just been created", seen in production during WAL replay on startup.

This test simulates the torn state and expects it to be recovered; it
fails with that panic until the next commit.

* Rebuild Gridstore region gaps once on detected inconsistency

Offsets returned by the block search always come from scanning the
bitmask itself; the region gaps only steer where to look. Stale gaps
can therefore only cause missed allocations, never a wrong allocation:
every torn state funnels into the allocation failure that used to
panic with "New page has just been created".

Instead of paying for gaps validation on every open, detect the
inconsistency at that failure point, log a warning, rebuild the gaps
from the bitmask (repairing content and length), and retry. This is
allowed at most once per instance: after a rebuild the gaps are kept
consistent in memory, so a second failure would be a logic bug and
still panics. Also clamp proposed search windows to the bitmask length
so a length-diverged gaps file reaches the recoverable path instead of
an out-of-bounds panic.

* Fix typo

* Add repro test for gaps length divergence breaking page creation

BitmaskGaps::extend grows the file with zeroes before writing the new
all-free entries through the mmap. After an unclean shutdown the growth
can be persisted while the entry contents are lost, leaving phantom
all-zero entries beyond the bitmask, each claiming a full region.

Phantom full entries are invisible to the gap search, but they force
trailing_free_blocks to report zero, so the next allocation always
tries to create a new page and cover_new_page panics on its "Bitmask
length mismatch" assertion — before the lazy gaps rebuild from the
previous commit can detect anything.

The test expects opening the storage to repair the divergence; it
fails with that panic until the next commit.

* Repair gaps-to-bitmask length divergence when opening Gridstore

The number of regions the gaps file covers must match the bitmask, but
an unclean shutdown can break that: a lost extend writeback leaves
phantom all-zero entries beyond the bitmask, and a lost file growth
leaves the gaps file short. Phantom full entries force page creation
(they zero out trailing_free_blocks) and cover_new_page then panics on
its length assertion — before the lazy content rebuild can detect
anything, so that path cannot recover from this state.

Comparing the lengths is cheap, so do it on every open: on divergence,
log a warning, rebuild the gaps from the bitmask right away, and
consume the once-per-instance rebuild allowance. Allocation behavior
is unchanged on consistent storages.

* Reference to pull request

* Make gaps rebuild safe on Windows

Windows refuses to resize a file with a live user mapping, so the gaps
reset that recreated the file under its own mapping failed there with
OS error 1224 (ERROR_USER_MAPPED_FILE).

Split the rebuild along that constraint. The lazy content rebuild
keeps the mapping and overwrites the entries in place: it never needs
to resize, because a length divergence is repaired when the storage is
opened, and refuses with an error if it encounters one anyway. The
open-time length repair consumes the Bitmask by value so it can drop
the gaps mapping, atomically replace the file with the rebuilt
entries, and map it again — no resize of a mapped file on any
platform.

* Simplify gaps rebuild code

Cleanups from a review pass, no behavior change:

- compute_gaps: one read_all pass over region chunks instead of a
  read_bit_range call per region, which also removes the loop body
  duplicated from update_region_gaps
- BitmaskGaps::overwrite: take a slice instead of collecting an
  iterator the only caller already holds as a Vec
- find_available_blocks: gate the divergence clamp on the O(1)
  bit_len instead of hoisting read_all above it
- Gridstore::open: flatten the match-to-tuple into an if let, and
  shorten the rebuild warning to match the runtime one
- tests: shared bitmask setup and value read-back helpers; drop the
  length-divergence scenario from test_rebuild_gaps that
  test_gaps_length_mismatch already covers (its search assertion
  moved there)
- fix garbled log and comment wording

Vector Search Engine for the next generation of AI applications



Qdrant (read: quadrant) is a vector similarity search engine and vector database. It provides a production-ready service with a convenient API to store, search, and manage points—vectors with an additional payload. Qdrant is tailored for extended filtering support, making it useful for all sorts of neural-network or semantic-based matching, faceted search, and other applications.
Qdrant is written in Rust 🦀, which makes it fast and reliable even under high load. See benchmarks.
With Qdrant, embeddings or neural network encoders can be turned into full-fledged applications for matching, searching, recommending, and much more!
Qdrant is also available as a fully managed Qdrant Cloud ⛅ including a free tier.
Quick Start • Agent Skills • Client Libraries • Demo Projects • Integrations • Contact
Getting Started
Agent Skills
Qdrant provides a collection of ready-to-use agent skills that bring Qdrant's vector search capabilities directly into your AI coding assistant. Install these skills to empower your agent in making critical engineering decisions for optimal vector search performance, such as quantization, sharding, tenant isolation, hybrid search, model migration, and more.
Client-Server
To experience the full power of Qdrant locally, run the container with this command:
docker run -p 6333:6333 qdrant/qdrant
Note that this starts an insecure deployment without authentication, open to all network interfaces. Please refer to secure your instance.
Now you can connect to the server with any client. For example, using Python:
from qdrant_client import QdrantClient

client = QdrantClient(url="http://localhost:6333")
Before deploying Qdrant to production, be sure to read our installation and security guides.
Clients
Qdrant offers the following client libraries to help you integrate it into your application stack:
- Official:
- Community:
Qdrant Edge
Qdrant Edge is a lightweight version of Qdrant designed for edge devices and resource-constrained environments. Unlike Qdrant Server, which uses a client-server architecture, Qdrant Edge runs inside the application process. Data is stored and queried locally and can be synchronized with a Qdrant server. It offers the same powerful vector search capabilities as the client-server version but with a smaller footprint, making it ideal for applications that require low latency and offline functionality.
To get started with Qdrant Edge from Python or Rust, initialize an instance of EdgeShard, which exposes methods to manage data, query it, and restore snapshots. For example:
from qdrant_edge import Distance, EdgeConfig, EdgeVectorParams, EdgeShard, Point, UpdateOperation

shard = EdgeShard.create("./shard", EdgeConfig(
    vectors={"my-vector": EdgeVectorParams(size=4, distance=Distance.Cosine)}
))
shard.update(UpdateOperation.upsert_points([
    Point(id=1, vector={"my-vector": [0.1, 0.2, 0.3, 0.4]}, payload={"color": "red"})
]))
Where Do I Go from Here?
- Quick Start Guide
- Detailed Documentation
- Take the Qdrant Essentials course
- Follow this tutorial to create a semantic search engine with Qdrant
Demo Projects
Discover Semantic Text Search 🔍
Unlock the power of semantic embeddings with Qdrant, transcending keyword-based search to find meaningful connections in short texts. Deploy a neural search in minutes using a pre-trained neural network, and experience the future of text search. Try it online!
Explore Similar Image Search - Food Discovery 🍕
There's more to discovery than text search, especially when it comes to food. People often choose meals based on appearance rather than descriptions and ingredients. Let Qdrant help your users find their next delicious meal using visual search, even if they don't know the dish's name. Check it out!
Master Extreme Classification - E-Commerce Product Categorization 📺
Enter the cutting-edge realm of extreme classification, an emerging machine learning field tackling multi-class and multi-label problems with millions of labels. Harness the potential of similarity learning models, and see how a pre-trained transformer model and Qdrant can revolutionize e-commerce product categorization. Play with it online!
API
REST
Qdrant provides a REST API with an OpenAPI 3.0 specification, enabling client generation for virtually any framework or programming language.
You can also download the raw OpenAPI definitions.
gRPC
For faster, production-tier searches, Qdrant also provides a gRPC interface.
Features
Dense, Sparse, and Multi Vector Search
Qdrant supports dense vectors for semantic similarity, sparse vectors for full-text search, and multivector search for objects with multiple embeddings or late interaction models like ColBERT.
Filtering on Payload
Attach any JSON payload to your vectors and filter on it using a rich set of conditions—keyword matching, full-text, numeric ranges, geo-locations, and more—combined with should, must, and must_not clauses.
Hybrid Search
Combine multiple vectors in a single query to get the best of semantic understanding and keyword precision, with results merged via configurable fusion strategies, such as Reciprocal Rank Fusion (RRF) and Distribution-Based Score Fusion (DBSF).
Vector Quantization and On-Disk Storage
Built-in quantization cuts RAM usage by up to 97% and lets you tune the trade-off between search speed and precision.
Distributed Deployment
Scale horizontally with sharding and replication, and update or resize collections with zero downtime.
Highlighted Features
- Faceting - aggregate search results by payload values.
- Recommendation - use positive and negative examples to find similar points.
- Discovery - constrain search to a specific region of the vector space.
- Search Relevance Tuning - tools for adjusting search results, such as Maximal Marginal Relevance (MMR) and the Relevance Feedback Query.
- Multitenancy - scalable partitioning of data for multi-user environments.
- Observability - comprehensive metrics, telemetry, and audit logging for monitoring and debugging.
- Query Planning and Payload Indexes - leverages stored payload information to optimize query execution strategy.
- SIMD Hardware Acceleration - utilizes modern CPU x86-x64 and Neon architectures to deliver better performance.
- GPU Support - for accelerated indexing, with support for NVIDIA and AMD GPUs.
- Async I/O - uses
io_uringto maximize disk throughput utilization even on network-attached storage. - Write-Ahead Logging - ensures data persistence with update confirmation, even during power outages.
Web UI
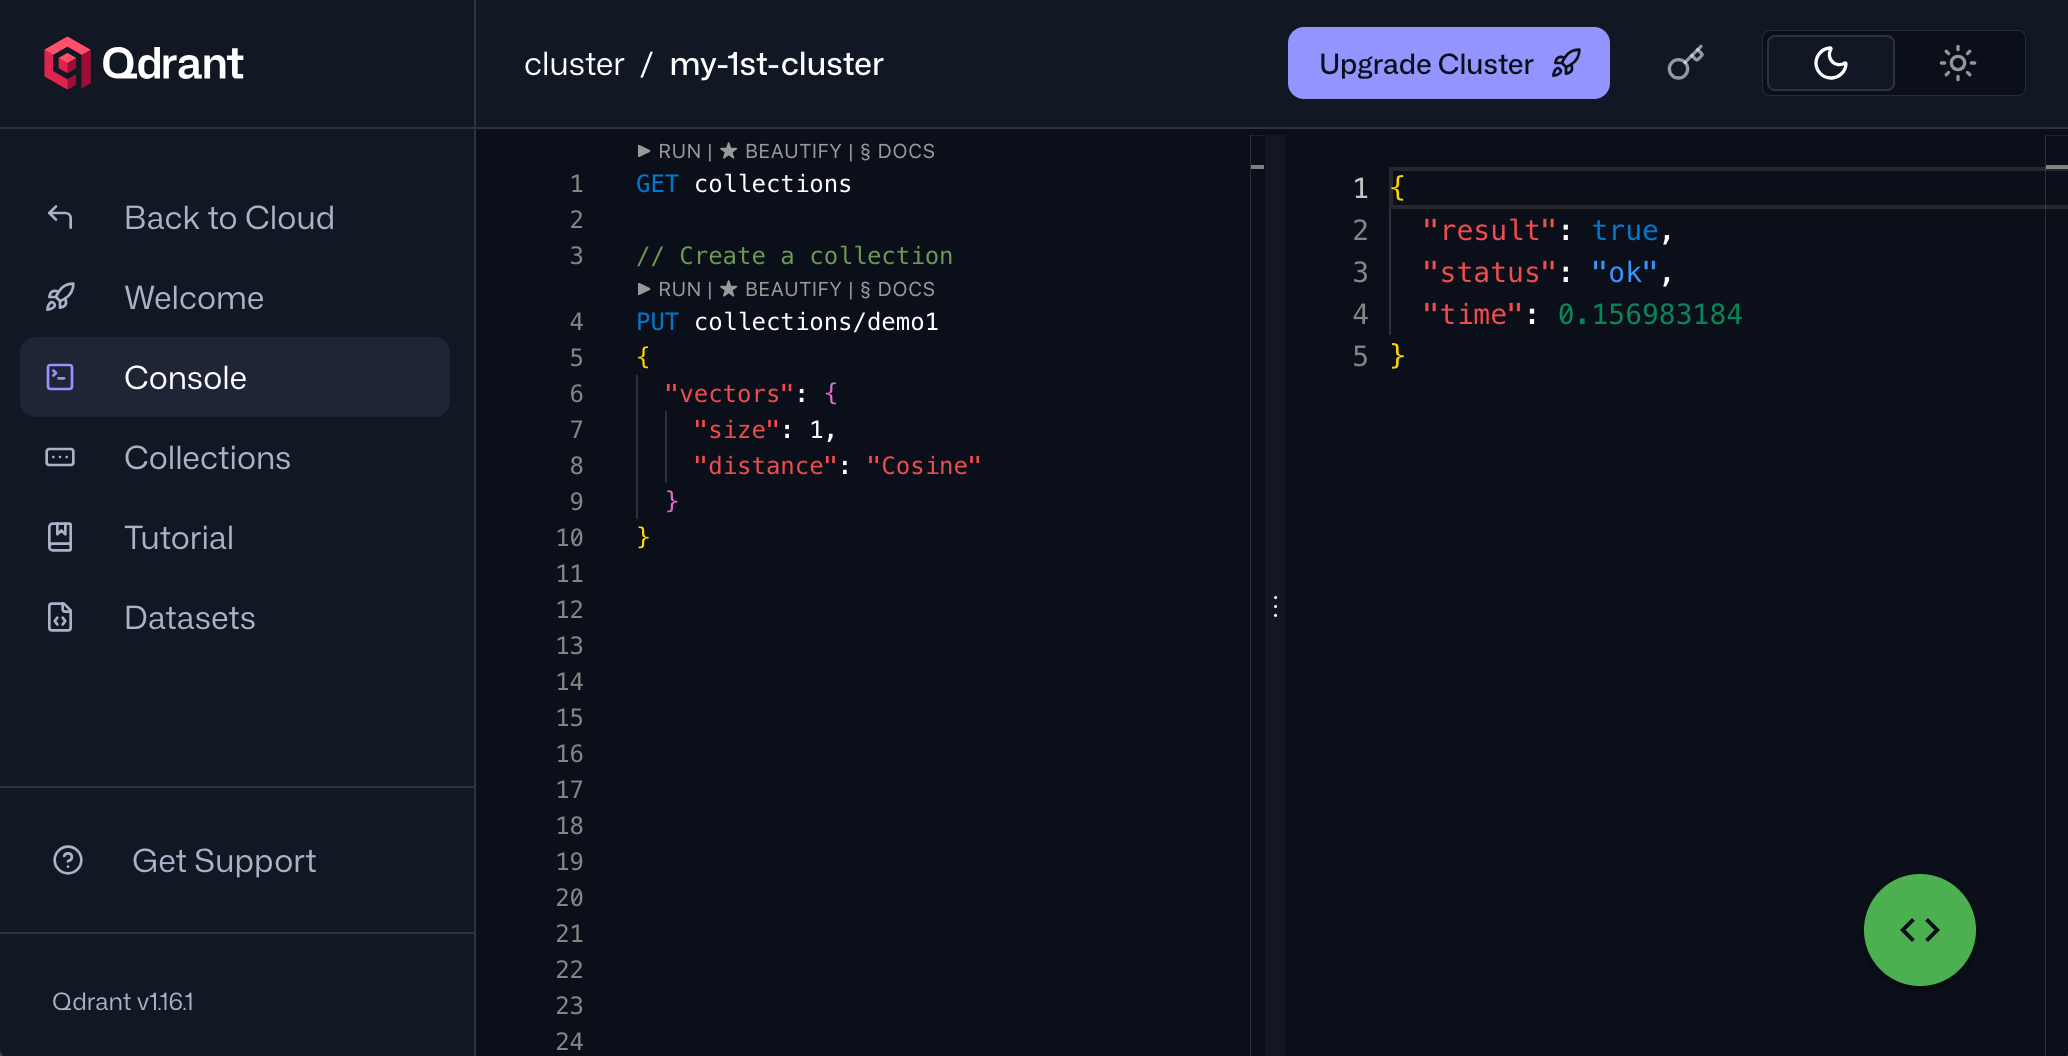
Web UI provides a visual way to interact with your data and monitor the health of your deployment. It enables you to explore your collections, manage data, interact with the REST API, and more.
Integrations
Qdrant integrates with the tools you're already using across every stage of your AI stack. You can connect to embedding providers, AI application frameworks, and data pipeline tools, as well as observability platforms for monitoring and tracing your vector search in production. No-code and low-code automation platforms are supported too. Refer to the Ecosystem page for the complete list.
Contributing
We are happy to receive your contributions! Before opening a pull request, please read our Contributing Guide.
Important
Our development branch is
dev, notmaster. Please fork the repo, branch fromdev, and open your pull request againstdev. PRs targetingmasterwill be asked to retarget.
Contacts
- Have questions? Join our Discord channel or mention @qdrant_engine on X
- Want to stay in touch with the latest releases? Subscribe to our Newsletters
- Looking for a managed cloud? Check pricing. Need something personalized? We're at info@qdrant.tech
License
Qdrant is licensed under the Apache License, Version 2.0. View a copy of the License file.