 Andrey VasnetsovandClaude Opus 4.8
046934fe2a
* feat: read-only edge shard follower (ReadOnlyEdgeShard)

Add a read-only follower of EdgeShard, mirroring the segment-level
ReadOnlySegment + live_reload design one level up at the shard. A leader
process owns a read-write EdgeShard; one or more followers open the same
on-disk directory as a ReadOnlyEdgeShard, serve reads, and periodically
refresh() to pick up the leader's flushed writes and optimizations.

Shared read logic lives once in a crate-internal EdgeReadView<H>, generic
over a ReadSegmentHandle: the follower is monomorphized over the concrete
ReadOnlySegment<S> (no dynamic dispatch), while the read-write shard's
heterogeneous Segment/ProxySegment holder uses the LockedSegment enum
(the only dyn ReadSegmentEntry left, mirroring LockedSegment::get_read).

EdgeShardRead is the public read API: it exposes the read methods
(search/query/retrieve/count/facet/scroll/info/...) as default methods,
requiring implementors only to provide read_segments() + config_snapshot().
EdgeShard keeps its inherent read methods for backwards compatibility.

Segment discovery is injected via a SegmentEnumerator (temporary seam):
LocalSegmentEnumerator scans the segments/ directory for the local/mmap
case; S3 followers supply their own. This will be replaced by an on-disk
segment manifest in follow-up work.

shard: add LockedSegment::get_read_arc(); split retrieve_blocking into a
handle-collecting wrapper + generic retrieve_over; generalize the private
_read_points over the segment type (public signatures unchanged); remove
the now-unused read_points_locked.

Co-Authored-By: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01Emj8TFxdtrf3K32eWhGgor

* feat: manifest-based segment loading for ReadOnlyEdgeShard

Replace the read-only follower's directory-scan discovery with the segment
manifest from the leader, the proper mechanism the SegmentEnumerator seam
was a placeholder for.

shard: add SegmentsManifest::load so readers can read manifest.json.

edge (leader): EdgeShard now writes segments/manifest.json (gated by the
write_segment_manifest feature flag), initialized from the live segment
set on new/load and refreshed after optimize() swaps segments.

edge (follower): ManifestSegmentEnumerator reads the manifest's `active`
segments instead of scanning, and open_mmap uses it. It requires a manifest
and errors when none is present (no silent scan fallback); discover by
scanning explicitly via open() with a LocalSegmentEnumerator instead.

Since the manifest only reports ready segments (and future versions will
mark segments retiring/under-construction rather than removing them from
active immediately), the read path no longer races with the leader, so the
defensive `is_transient_open_error` skip handling is removed — a failure to
open a reported segment is now a genuine error and propagates.

Co-Authored-By: Claude Opus 4.8 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01Emj8TFxdtrf3K32eWhGgor

* feat: edge-s3-scroll experiment binary for ReadOnlyEdgeShard over S3

Adds a standalone `edge-s3-scroll` binary that opens a ReadOnlyEdgeShard
directly over an S3 (or S3-compatible) bucket and runs a single scroll
request with a hard-coded filter, for experimentation.

Takes the bucket endpoint, credentials and key prefix as CLI flags/env
vars, builds an S3-backed BlobFs, and discovers segments via a custom
enumerator that reads the segment manifest over object storage. The
edge_config.json is fetched to a local temp dir because
ReadOnlyEdgeShard::open reads config from the local filesystem.

Co-Authored-By: Claude Opus 4.8 (1M context) <noreply@anthropic.com>

* filter config in s3 scroll tool

* fix: read segment manifest from new location after dev rebase

dev #9564 moved the segment manifest next to (rather than inside) the
segments/ directory and named it segments_manifest.json. Adapt the
read-only follower enumerators accordingly so the follower reads the
manifest where the leader now writes it:

- ManifestSegmentEnumerator reads via segment_manifest_path() (shard root)
  while still resolving segment dirs under segments/<uuid>.
- The S3 scroll tool's enumerator mirrors the same layout.

Co-Authored-By: Claude Opus 4.8 (1M context) <noreply@anthropic.com>

* feat: read-only edge shard works over object storage without edge_config

Make ReadOnlyEdgeShard self-sufficient over arbitrary backends (S3/GCS),
and harden the read-only segment loading it depends on.

- ReadOnlyEdgeShard derives its config from the segments via
  EdgeConfig::from_segment_config instead of requiring edge_config.json
  (open and refresh both derive); a follower never has that file.
- ReadOnlyEdgeShard::open(fs, path) no longer takes an enumerator: a
  read-only follower always discovers segments through the manifest.
  open_with_enumerator remains as a pub(crate) seam for tests.
- ManifestSegmentEnumerator is generic over UniversalReadFs (reads the
  manifest via read_json_via), so it works over local mmap or a blob/S3
  backend; the tool's bespoke enumerator is removed.
- Read-only mutable ID tracker tolerates absent mappings/versions files
  (they are not written while empty), matching MutableIdTracker::open:
  files are opened lazily and NotFound is treated as empty, avoiding an
  extra exists() round-trip on object storage.

edge-s3-scroll experiment tool:
- Supports AWS S3 / S3-compatible and GCS backends (--backend), with a
  hard-coded-free --filter-key/--filter-value scroll filter.
- Reads segment data through a DiskCache so remote blocks are fetched
  once and served from a local mirror afterwards.

Co-Authored-By: Claude Opus 4.8 (1M context) <noreply@anthropic.com>

* refactor: remove unused SegmentsManifest::load

Its only caller (edge's ManifestSegmentEnumerator) now reads the manifest
via read_json_via over UniversalReadFs, so the local-only load helper is
dead. Drop it and its now-unused read_json/Path imports.

Co-Authored-By: Claude Opus 4.8 (1M context) <noreply@anthropic.com>

---------

Co-authored-by: Claude Opus 4.8 (1M context) <noreply@anthropic.com>

Vector Search Engine for the next generation of AI applications



Qdrant (read: quadrant) is a vector similarity search engine and vector database. It provides a production-ready service with a convenient API to store, search, and manage points—vectors with an additional payload. Qdrant is tailored for extended filtering support, making it useful for all sorts of neural-network or semantic-based matching, faceted search, and other applications.
Qdrant is written in Rust 🦀, which makes it fast and reliable even under high load. See benchmarks.
With Qdrant, embeddings or neural network encoders can be turned into full-fledged applications for matching, searching, recommending, and much more!
Qdrant is also available as a fully managed Qdrant Cloud ⛅ including a free tier.
Quick Start • Agent Skills • Client Libraries • Demo Projects • Integrations • Contact
Getting Started
Agent Skills
Qdrant provides a collection of ready-to-use agent skills that bring Qdrant's vector search capabilities directly into your AI coding assistant. Install these skills to empower your agent in making critical engineering decisions for optimal vector search performance, such as quantization, sharding, tenant isolation, hybrid search, model migration, and more.
Client-Server
To experience the full power of Qdrant locally, run the container with this command:
docker run -p 6333:6333 qdrant/qdrant
Note that this starts an insecure deployment without authentication, open to all network interfaces. Please refer to secure your instance.
Now you can connect to the server with any client. For example, using Python:
from qdrant_client import QdrantClient

client = QdrantClient(url="http://localhost:6333")
Before deploying Qdrant to production, be sure to read our installation and security guides.
Clients
Qdrant offers the following client libraries to help you integrate it into your application stack:
- Official:
- Community:
Qdrant Edge
Qdrant Edge is a lightweight version of Qdrant designed for edge devices and resource-constrained environments. Unlike Qdrant Server, which uses a client-server architecture, Qdrant Edge runs inside the application process. Data is stored and queried locally and can be synchronized with a Qdrant server. It offers the same powerful vector search capabilities as the client-server version but with a smaller footprint, making it ideal for applications that require low latency and offline functionality.
To get started with Qdrant Edge from Python or Rust, initialize an instance of EdgeShard, which exposes methods to manage data, query it, and restore snapshots. For example:
from qdrant_edge import Distance, EdgeConfig, EdgeVectorParams, EdgeShard, Point, UpdateOperation

shard = EdgeShard.create("./shard", EdgeConfig(
    vectors={"my-vector": EdgeVectorParams(size=4, distance=Distance.Cosine)}
))
shard.update(UpdateOperation.upsert_points([
    Point(id=1, vector={"my-vector": [0.1, 0.2, 0.3, 0.4]}, payload={"color": "red"})
]))
Where Do I Go from Here?
- Quick Start Guide
- Detailed Documentation
- Take the Qdrant Essentials course
- Follow this tutorial to create a semantic search engine with Qdrant
Demo Projects
Discover Semantic Text Search 🔍
Unlock the power of semantic embeddings with Qdrant, transcending keyword-based search to find meaningful connections in short texts. Deploy a neural search in minutes using a pre-trained neural network, and experience the future of text search. Try it online!
Explore Similar Image Search - Food Discovery 🍕
There's more to discovery than text search, especially when it comes to food. People often choose meals based on appearance rather than descriptions and ingredients. Let Qdrant help your users find their next delicious meal using visual search, even if they don't know the dish's name. Check it out!
Master Extreme Classification - E-Commerce Product Categorization 📺
Enter the cutting-edge realm of extreme classification, an emerging machine learning field tackling multi-class and multi-label problems with millions of labels. Harness the potential of similarity learning models, and see how a pre-trained transformer model and Qdrant can revolutionize e-commerce product categorization. Play with it online!
API
REST
Qdrant provides a REST API with an OpenAPI 3.0 specification, enabling client generation for virtually any framework or programming language.
You can also download the raw OpenAPI definitions.
gRPC
For faster, production-tier searches, Qdrant also provides a gRPC interface.
Features
Dense, Sparse, and Multi Vector Search
Qdrant supports dense vectors for semantic similarity, sparse vectors for full-text search, and multivector search for objects with multiple embeddings or late interaction models like ColBERT.
Filtering on Payload
Attach any JSON payload to your vectors and filter on it using a rich set of conditions—keyword matching, full-text, numeric ranges, geo-locations, and more—combined with should, must, and must_not clauses.
Hybrid Search
Combine multiple vectors in a single query to get the best of semantic understanding and keyword precision, with results merged via configurable fusion strategies, such as Reciprocal Rank Fusion (RRF) and Distribution-Based Score Fusion (DBSF).
Vector Quantization and On-Disk Storage
Built-in quantization cuts RAM usage by up to 97% and lets you tune the trade-off between search speed and precision.
Distributed Deployment
Scale horizontally with sharding and replication, and update or resize collections with zero downtime.
Highlighted Features
- Faceting - aggregate search results by payload values.
- Recommendation - use positive and negative examples to find similar points.
- Discovery - constrain search to a specific region of the vector space.
- Search Relevance Tuning - tools for adjusting search results, such as Maximal Marginal Relevance (MMR) and the Relevance Feedback Query.
- Multitenancy - scalable partitioning of data for multi-user environments.
- Observability - comprehensive metrics, telemetry, and audit logging for monitoring and debugging.
- Query Planning and Payload Indexes - leverages stored payload information to optimize query execution strategy.
- SIMD Hardware Acceleration - utilizes modern CPU x86-x64 and Neon architectures to deliver better performance.
- GPU Support - for accelerated indexing, with support for NVIDIA and AMD GPUs.
- Async I/O - uses
io_uringto maximize disk throughput utilization even on network-attached storage. - Write-Ahead Logging - ensures data persistence with update confirmation, even during power outages.
Web UI
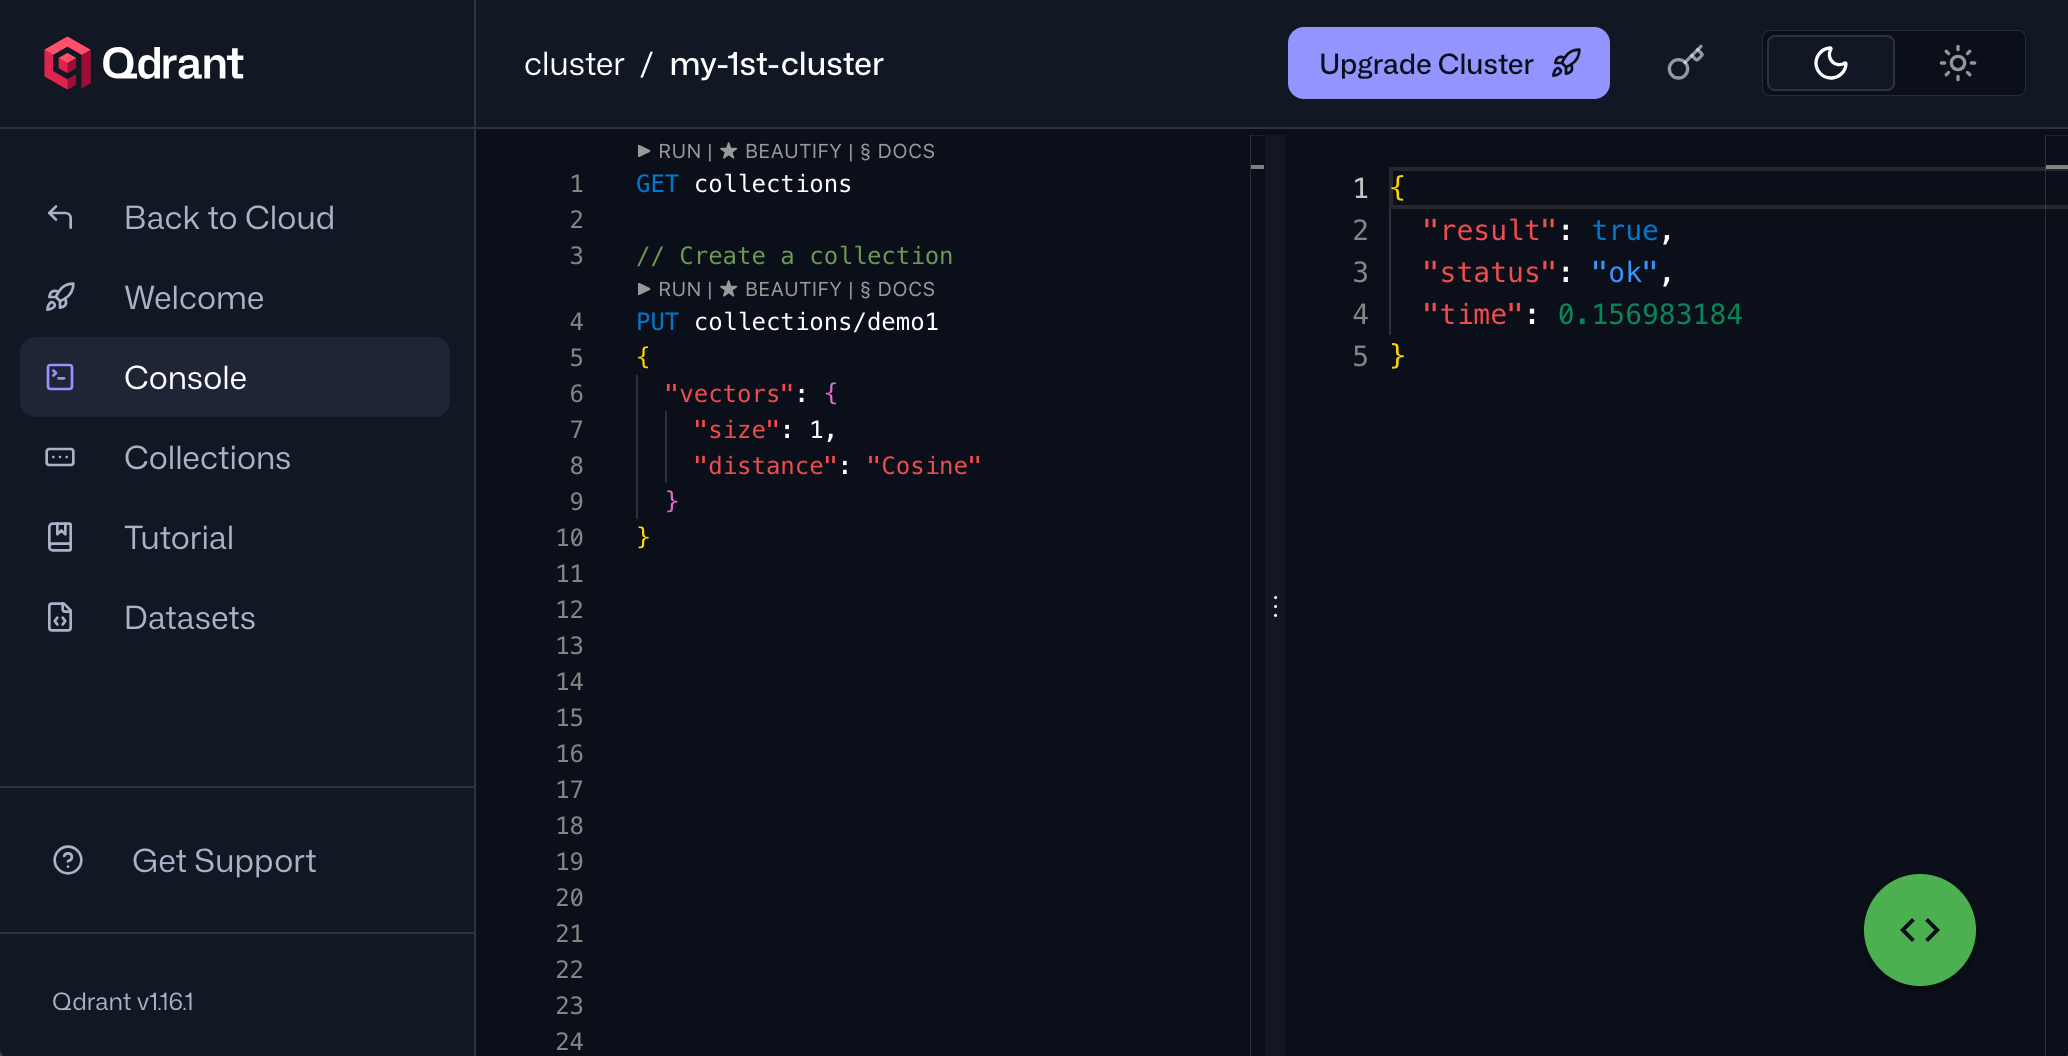
Web UI provides a visual way to interact with your data and monitor the health of your deployment. It enables you to explore your collections, manage data, interact with the REST API, and more.
Integrations
Qdrant integrates with the tools you're already using across every stage of your AI stack. You can connect to embedding providers, AI application frameworks, and data pipeline tools, as well as observability platforms for monitoring and tracing your vector search in production. No-code and low-code automation platforms are supported too. Refer to the Ecosystem page for the complete list.
Contributing
We are happy to receive your contributions! Before opening a pull request, please read our Contributing Guide.
Important
Our development branch is
dev, notmaster. Please fork the repo, branch fromdev, and open your pull request againstdev. PRs targetingmasterwill be asked to retarget.
Contacts
- Have questions? Join our Discord channel or mention @qdrant_engine on X
- Want to stay in touch with the latest releases? Subscribe to our Newsletters
- Looking for a managed cloud? Check pricing. Need something personalized? We're at info@qdrant.tech
License
Qdrant is licensed under the Apache License, Version 2.0. View a copy of the License file.