Compare commits
20
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 debpalash |
2d7df6a75c | ||
|
debpalash
|
a2577e46ea | ||
|
debpalash
|
eed841a8ca | ||
|
debpalash
|
df4d016a7d | ||
|
Palash Debnath
|
ca7fb9c68d | ||
|
debpalash
|
fd6d21401b | ||
|
debpalash
|
c9adcb2647 | ||
|
debpalash
|
51163cf260 | ||
|
Palash Debnath
|
4ce4f05c06 | ||
|
debpalash
|
e77feae817 | ||
|
debpalash
|
fdc02b398e | ||
|
Palash Debnath
|
6e1bb44e0d | ||
|
Palash Debnath
|
4dc90a7f4f | ||
|
debpalash
|
3b64d317ae | ||
|
debpalash
|
ee7202b1eb | ||
|
Paolo Antinori
|
871d68a6ff | ||
|
Palash Debnath
|
b37466b2e5 | ||
|
Palash DebnathandClaude Fable 5
|
2d5f2e800e | ||
|
Palash DebnathandClaude Fable 5
|
4db02d0c97 | ||
|
Eman-Yousaf
|
579f2e0a2e |
@@ -0,0 +1,60 @@
|
||||
---
|
||||
name: fastapi-python
|
||||
description: Expert in FastAPI Python development with best practices for APIs and async operations
|
||||
---
|
||||
|
||||
# FastAPI Python
|
||||
|
||||
You are an expert in FastAPI and Python backend development.
|
||||
|
||||
## Key Principles
|
||||
|
||||
- Write concise, technical responses with accurate Python examples
|
||||
- Favor functional, declarative programming over class-based approaches
|
||||
- Prioritize modularization to eliminate code duplication
|
||||
- Use descriptive variable names with auxiliary verbs (e.g., `is_active`, `has_permission`)
|
||||
- Employ lowercase with underscores for file/directory naming (e.g., `routers/user_routes.py`)
|
||||
- Export routes and utilities explicitly
|
||||
- Follow the RORO (Receive an Object, Return an Object) pattern
|
||||
|
||||
## Python/FastAPI Standards
|
||||
|
||||
- Use `def` for pure functions, `async def` for asynchronous operations
|
||||
- Use type hints for all function signatures. Prefer Pydantic models over raw dictionaries
|
||||
- Structure: exported router, sub-routes, utilities, static content, types (models, schemas)
|
||||
- Use ordinary Python control flow; prefer readability over compressed one-line conditionals
|
||||
|
||||
## Error Handling
|
||||
|
||||
- Handle edge cases at function entry points
|
||||
- Employ early returns for error conditions
|
||||
- Place happy path logic last
|
||||
- Avoid unnecessary else statements; use if-return patterns
|
||||
- Implement guard clauses for preconditions
|
||||
- Provide proper error logging and user-friendly messaging
|
||||
|
||||
## FastAPI-Specific Guidelines
|
||||
|
||||
- Use functional components (plain functions) and Pydantic models for input validation
|
||||
- Declare routes with clear return type annotations
|
||||
- Prefer lifespan context managers for managing startup and shutdown events
|
||||
- Leverage middleware for logging, error monitoring, and optimization
|
||||
- Use HTTPException for expected errors and model them as specific HTTP responses
|
||||
- Apply Pydantic's BaseModel consistently for validation
|
||||
|
||||
## Performance Optimization
|
||||
|
||||
- Minimize blocking I/O. In `async def` handlers, use awaitable database/API clients; put synchronous SQLite or other blocking work in synchronous routes or explicitly offload it
|
||||
- Implement caching with Redis or in-memory stores
|
||||
- Optimize Pydantic serialization/deserialization
|
||||
- Use lazy loading for large datasets
|
||||
|
||||
## Key Conventions
|
||||
|
||||
1. Rely on FastAPI's dependency injection system
|
||||
2. Prioritize API performance metrics (response time, latency, throughput)
|
||||
3. Structure routes and dependencies for readability and maintainability
|
||||
|
||||
## Dependencies
|
||||
|
||||
FastAPI, Pydantic v2, asyncpg/aiomysql, SQLAlchemy 2.0
|
||||
@@ -0,0 +1,357 @@
|
||||
---
|
||||
name: vite
|
||||
description: Expert guidance for Vite development with modern build tooling, HMR, framework integrations, and performance optimization
|
||||
---
|
||||
|
||||
# Vite Development
|
||||
|
||||
You are an expert in Vite, modern JavaScript/TypeScript build tooling, and frontend development.
|
||||
|
||||
## Key Principles
|
||||
|
||||
- Leverage native ES modules for fast development
|
||||
- Use Vite's opinionated defaults when possible
|
||||
- Configure only what needs customization
|
||||
- Understand the dev/build differences
|
||||
- Optimize for both development speed and production performance
|
||||
|
||||
## Project Setup
|
||||
|
||||
### Basic Configuration
|
||||
```typescript
|
||||
// vite.config.ts
|
||||
import { defineConfig } from 'vite';
|
||||
import react from '@vitejs/plugin-react';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [react()],
|
||||
server: {
|
||||
port: 3000,
|
||||
open: true,
|
||||
},
|
||||
build: {
|
||||
outDir: 'dist',
|
||||
sourcemap: true,
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
### Path Aliases
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
|
||||
export default defineConfig({
|
||||
resolve: {
|
||||
alias: {
|
||||
'@': new URL('./src', import.meta.url).pathname,
|
||||
'@components': new URL('./src/components', import.meta.url).pathname,
|
||||
'@utils': new URL('./src/utils', import.meta.url).pathname,
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
### Usage
|
||||
```typescript
|
||||
// .env
|
||||
VITE_API_URL=https://api.example.com
|
||||
VITE_APP_TITLE=My App
|
||||
|
||||
// In code
|
||||
const apiUrl = import.meta.env.VITE_API_URL;
|
||||
const isDev = import.meta.env.DEV;
|
||||
const isProd = import.meta.env.PROD;
|
||||
const mode = import.meta.env.MODE;
|
||||
```
|
||||
|
||||
### Type Definitions
|
||||
```typescript
|
||||
// src/vite-env.d.ts
|
||||
/// <reference types="vite/client" />
|
||||
|
||||
interface ImportMetaEnv {
|
||||
readonly VITE_API_URL: string;
|
||||
readonly VITE_APP_TITLE: string;
|
||||
}
|
||||
|
||||
interface ImportMeta {
|
||||
readonly env: ImportMetaEnv;
|
||||
}
|
||||
```
|
||||
|
||||
## Hot Module Replacement
|
||||
|
||||
### Manual HMR
|
||||
```typescript
|
||||
// For libraries without HMR support
|
||||
if (import.meta.hot) {
|
||||
import.meta.hot.accept('./module.ts', (newModule) => {
|
||||
// Handle the updated module
|
||||
console.log('Module updated:', newModule);
|
||||
});
|
||||
|
||||
import.meta.hot.dispose(() => {
|
||||
// Cleanup before module is replaced
|
||||
});
|
||||
}
|
||||
```
|
||||
|
||||
## Asset Handling
|
||||
|
||||
### Static Assets
|
||||
```typescript
|
||||
// Import as URL
|
||||
import imageUrl from './image.png';
|
||||
// <img src={imageUrl} />
|
||||
|
||||
// Import as string (raw)
|
||||
import shaderCode from './shader.glsl?raw';
|
||||
|
||||
// Import as worker
|
||||
import Worker from './worker.ts?worker';
|
||||
const worker = new Worker();
|
||||
```
|
||||
|
||||
### Public Directory
|
||||
```
|
||||
public/
|
||||
├── favicon.ico # Served at /favicon.ico
|
||||
├── robots.txt # Served at /robots.txt
|
||||
└── images/ # Served at /images/
|
||||
```
|
||||
|
||||
## Framework Integrations
|
||||
|
||||
### React
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
import react from '@vitejs/plugin-react';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [
|
||||
react({
|
||||
// Babel plugins
|
||||
babel: {
|
||||
plugins: ['@emotion/babel-plugin'],
|
||||
},
|
||||
}),
|
||||
],
|
||||
});
|
||||
```
|
||||
|
||||
### Vue
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
import vue from '@vitejs/plugin-vue';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [vue()],
|
||||
});
|
||||
```
|
||||
|
||||
### Svelte
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
import { svelte } from '@sveltejs/vite-plugin-svelte';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [svelte()],
|
||||
});
|
||||
```
|
||||
|
||||
## Build Optimization
|
||||
|
||||
### Code Splitting
|
||||
```typescript
|
||||
// Dynamic imports create separate chunks
|
||||
const AdminPanel = lazy(() => import('./AdminPanel'));
|
||||
|
||||
// Manual chunks
|
||||
export default defineConfig({
|
||||
build: {
|
||||
rollupOptions: {
|
||||
output: {
|
||||
manualChunks: {
|
||||
vendor: ['react', 'react-dom'],
|
||||
utils: ['lodash', 'date-fns'],
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
### Chunk Size Optimization
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
build: {
|
||||
chunkSizeWarningLimit: 500,
|
||||
rollupOptions: {
|
||||
output: {
|
||||
manualChunks(id) {
|
||||
if (id.includes('node_modules')) {
|
||||
return id.split('node_modules/')[1].split('/')[0];
|
||||
}
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## CSS Handling
|
||||
|
||||
### CSS Modules
|
||||
```typescript
|
||||
// styles.module.css is auto-detected
|
||||
import styles from './styles.module.css';
|
||||
|
||||
// <div className={styles.container}>
|
||||
```
|
||||
|
||||
### PostCSS
|
||||
```javascript
|
||||
// postcss.config.js
|
||||
export default {
|
||||
plugins: {
|
||||
tailwindcss: {},
|
||||
autoprefixer: {},
|
||||
},
|
||||
};
|
||||
```
|
||||
|
||||
### Preprocessors
|
||||
```typescript
|
||||
// Automatically handled with package installed
|
||||
// npm install -D sass
|
||||
import './styles.scss';
|
||||
```
|
||||
|
||||
## Proxy Configuration
|
||||
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
server: {
|
||||
proxy: {
|
||||
'/api': {
|
||||
target: 'http://localhost:4000',
|
||||
changeOrigin: true,
|
||||
rewrite: (path) => path.replace(/^\/api/, ''),
|
||||
},
|
||||
'/socket.io': {
|
||||
target: 'ws://localhost:4000',
|
||||
ws: true,
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Plugin Development
|
||||
|
||||
```typescript
|
||||
// my-vite-plugin.ts
|
||||
import type { Plugin } from 'vite';
|
||||
|
||||
export function myPlugin(): Plugin {
|
||||
return {
|
||||
name: 'my-plugin',
|
||||
|
||||
// Hook: modify config
|
||||
config(config, { mode }) {
|
||||
return {
|
||||
define: {
|
||||
__BUILD_TIME__: JSON.stringify(new Date().toISOString()),
|
||||
},
|
||||
};
|
||||
},
|
||||
|
||||
// Hook: transform code
|
||||
transform(code, id) {
|
||||
if (id.endsWith('.md')) {
|
||||
return {
|
||||
code: `export default ${JSON.stringify(code)}`,
|
||||
map: null,
|
||||
};
|
||||
}
|
||||
},
|
||||
|
||||
// Hook: configure dev server
|
||||
configureServer(server) {
|
||||
server.middlewares.use((req, res, next) => {
|
||||
// Custom middleware
|
||||
next();
|
||||
});
|
||||
},
|
||||
};
|
||||
}
|
||||
```
|
||||
|
||||
## Testing with Vitest
|
||||
|
||||
```typescript
|
||||
// vitest.config.ts
|
||||
import { defineConfig } from 'vitest/config';
|
||||
|
||||
export default defineConfig({
|
||||
test: {
|
||||
globals: true,
|
||||
environment: 'jsdom',
|
||||
setupFiles: './src/test/setup.ts',
|
||||
coverage: {
|
||||
provider: 'v8',
|
||||
reporter: ['text', 'json', 'html'],
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## SSR Configuration
|
||||
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
build: {
|
||||
ssr: true,
|
||||
rollupOptions: {
|
||||
input: './src/entry-server.ts',
|
||||
},
|
||||
},
|
||||
ssr: {
|
||||
external: ['express'],
|
||||
noExternal: ['my-ui-library'],
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Library Mode
|
||||
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
build: {
|
||||
lib: {
|
||||
entry: './src/index.ts',
|
||||
name: 'MyLib',
|
||||
fileName: (format) => `my-lib.${format}.js`,
|
||||
},
|
||||
rollupOptions: {
|
||||
external: ['react', 'react-dom'],
|
||||
output: {
|
||||
globals: {
|
||||
react: 'React',
|
||||
'react-dom': 'ReactDOM',
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
- Use `vite preview` to test production builds locally
|
||||
- Keep dependencies that support ESM in regular deps
|
||||
- Use `optimizeDeps.include` for CommonJS dependencies
|
||||
- Enable `build.sourcemap` for debugging production
|
||||
- Use `server.warmup` for faster dev server starts
|
||||
@@ -25,4 +25,6 @@ regexes = [
|
||||
'''^hf_QWERTYUIOPasdfghjklZXCVBNM0123456789xyzAB$''',
|
||||
# NLLB generation length argument, not the value of a credential.
|
||||
'''^max_length=400$''',
|
||||
# cryptography's Ed25519 private-key type name, not key material.
|
||||
'''^Ed25519PrivateKey$''',
|
||||
]
|
||||
|
||||
@@ -35,6 +35,10 @@ Binding for every AI agent (Claude, Codex, Cursor, review bots, …). CLAUDE.md
|
||||
|
||||
## Agent skills
|
||||
|
||||
Project development skills are pinned in `skills-lock.json` and installed under
|
||||
`.agents/skills/`: Vite and FastAPI.
|
||||
Repository rules and tracker mappings override generic skill guidance.
|
||||
|
||||
### Issue tracker
|
||||
|
||||
GitHub Issues on `debpalash/VoiceStudio`, via the `gh` CLI. See `docs/agents/issue-tracker.md`.
|
||||
|
||||
@@ -18,18 +18,30 @@ the frozen-backend fallback mirror it for their toolchains.
|
||||
- The backend binds its port immediately and reports startup progress live — `/health` answers 503-with-step and a new `/startup/progress` endpoint lists every step while PyTorch, API routes, and database migrations load in the background, so "starting at step X" is never mistakable for "dead"; the desktop splash narrates each step (#1550)
|
||||
|
||||
### Added
|
||||
- Voices you've cloned stay "warm" across restarts — encoded references now persist to disk (~10 KB each), so the first generation of a session skips the re-encode and any transcription pass; `OMNIVOICE_PROMPT_DISK_CACHE=0` opts out (#1565)
|
||||
- Optional FlashInfer acceleration for the default engine on CUDA (`OMNIVOICE_FLASHINFER=1`, ~2.2x measured) — needs the optional `flashinfer-python` package; missing package or kernel failure logs why and falls back to the standard path (#1565)
|
||||
- The bug reporter notices when you're on an outdated build and offers the latest release before filing — with a "File anyway" escape hatch — and stamps a `Build status` line into every report so up-to-date reports are tellable from stale ones (#1547)
|
||||
- Settings → Performance & Device gains a compute-device override (Auto / CUDA / ROCm / XPU / MPS / CPU, or `OMNIVOICE_DEVICE`) — pin the device when auto-detect picks wrong; only devices your machine actually has are offered (#1557)
|
||||
|
||||
### Docs
|
||||
- The Docker Hub overview now shows the current engine-switching demo, Model Catalogue, and gallery voice workflow (#1593)
|
||||
- The Docker Hub overview and install guide now show the v0.5 tags and the built-in API-key/share-PIN security model instead of obsolete v0.4 and no-authentication guidance (#1592)
|
||||
- The READMEs now lead with download buttons and a three-step first-clone walkthrough, and a new benchmarks page anchors measured per-engine/per-device numbers on the in-repo harness (#1555)
|
||||
- Every engine now has its own guide — 21 new pages under docs/engines plus an index covering all 16 TTS and 11 ASR engines, linked from both READMEs (#1556)
|
||||
- The OmniVoice guide now covers combining style attributes with a reference clip (consistent instruct stabilizes cloning; the reference wins conflicts), inline pronunciation control (pinyin / CMU phonemes), and corrects the claim that the default engine can't do voice design — it can, from attributes (#1565)
|
||||
|
||||
### Fixed
|
||||
- Network Sharing from Windows MSI/portable installs now serves the bundled web interface to LAN devices instead of redirecting them to their own `localhost` (#1589) — thanks @TWIISTED-STUDIOS!
|
||||
- Stored artifact subpaths now resolve after moving a data directory between Windows, macOS, Linux, and Docker, while traversal and symlink escapes remain blocked (#1559) — thanks @Eman-Yousaf!
|
||||
- A remote browser hitting an API-key-configured server's admin 403 now gets the API-key login form instead of endless console 403s, while desktop and PIN-only/no-key servers keep the plain loopback error so guests are never offered a login no key can satisfy (#1568) — thanks @paoloantinori!
|
||||
- The crash-isolated ASR sidecar and its download preflight now agree on which model to load — setting the shared faster-whisper model variable applies to both variants instead of the sidecar quietly using a different one (#1556)
|
||||
- "Ready" now requires the deep health probe (a working database-backed route), not just the identity probe — a backend whose install broke underneath can no longer be announced up while every real request fails (#1548)
|
||||
- Supervisor restarts after repeat crashes now back off (immediate, then 5s, then 15s) instead of respawning back-to-back, so a tight crash loop can't burn the whole restart budget in seconds (#1548)
|
||||
|
||||
### CI
|
||||
- Project agents now share pinned Vite and FastAPI skills from skills.sh (#1594)
|
||||
- Weekly full-history secret scans no longer mistake the Ed25519 private-key type name for committed key material (#1591)
|
||||
|
||||
## [0.5.0] — 2026-08-13
|
||||
|
||||
**Highlights**
|
||||
|
||||
@@ -66,7 +66,10 @@ Architecture not yet mapped. Follow existing patterns found in the codebase.
|
||||
<!-- GSD:skills-start source:skills/ -->
|
||||
## Project Skills
|
||||
|
||||
No project skills found. Add skills to any of: `.claude/skills/`, `.agents/skills/`, `.cursor/skills/`, `.github/skills/`, or `.codex/skills/` with a `SKILL.md` index file.
|
||||
- `vite` — Vite configuration, assets, HMR, builds, and Vitest guidance.
|
||||
- `fastapi-python` — FastAPI and Pydantic implementation patterns.
|
||||
|
||||
Canonical copies live under `.agents/skills/`; `skills-lock.json` pins their sources and hashes. Claude should follow these paths directly, avoiding cross-platform symlinks.
|
||||
<!-- GSD:skills-end -->
|
||||
|
||||
<!-- GSD:workflow-start source:GSD defaults -->
|
||||
|
||||
@@ -157,6 +157,31 @@ def require_loopback(request: Request) -> None:
|
||||
raise HTTPException(status_code=403, detail="loopback origin required")
|
||||
|
||||
|
||||
def _admin_gate_403() -> None:
|
||||
"""Raise the admin-gate 403 with a detail that states what would ACTUALLY
|
||||
satisfy the gate. The bundled UI routes any 403 whose detail mentions
|
||||
"admin api key" to the API-key login form (frontend ``client.ts``; the
|
||||
literal contract is locked by ``tests/test_auth_gate_detail_lockstep.py``),
|
||||
so the wording must not name a key where presenting one cannot help.
|
||||
|
||||
The detail names the key only when the gate would accept one: server mode
|
||||
WITH an API key configured. Every other rejection — desktop mode (the
|
||||
credential checks in the callers only run under server mode) and a
|
||||
server-mode deployment with only a share PIN or nothing configured — keeps
|
||||
the plain loopback detail, because only loopback can use admin there.
|
||||
Naming the key in those cases would trap a LAN-share guest in a login
|
||||
form that can never succeed (#1213, #1525; PR #1569 review).
|
||||
"""
|
||||
raise HTTPException(
|
||||
status_code=403,
|
||||
detail=(
|
||||
"loopback origin or admin API key required"
|
||||
if _server_mode() and remote_api_key()
|
||||
else "loopback origin required"
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
def require_admin(request: Request) -> None:
|
||||
"""Gate RCE/filesystem-capable admin routers.
|
||||
|
||||
@@ -180,7 +205,7 @@ def require_admin(request: Request) -> None:
|
||||
return
|
||||
if _request_presents_admin_credential(request):
|
||||
return
|
||||
raise HTTPException(status_code=403, detail="loopback origin or admin API key required")
|
||||
_admin_gate_403()
|
||||
|
||||
|
||||
def require_admin_action(request: Request) -> None:
|
||||
@@ -198,7 +223,7 @@ def require_admin_action(request: Request) -> None:
|
||||
side_effectful_get=True,
|
||||
):
|
||||
return
|
||||
raise HTTPException(status_code=403, detail="loopback origin or admin API key required")
|
||||
_admin_gate_403()
|
||||
|
||||
|
||||
def require_desktop(request: Request) -> None:
|
||||
|
||||
@@ -17,6 +17,13 @@ _WINDOWS_RESERVED_NAMES = frozenset({"CON", "PRN", "AUX", "NUL"}) | frozenset(
|
||||
f"{prefix}{number}" for prefix in ("COM", "LPT") for number in range(1, 10)
|
||||
)
|
||||
|
||||
# Both separator families, so a stored sub-path splits into the same components
|
||||
# on every host. Windows accepts ``/`` as a real separator, so splitting on
|
||||
# ``os.sep`` alone left ``"job/out.mp4"`` as a single component there while the
|
||||
# identical value split cleanly on POSIX. POSIX input never reaches this with a
|
||||
# backslash — it is rejected as a foreign separator before the split.
|
||||
_PATH_SEPARATORS = re.compile(r"[\\/]")
|
||||
|
||||
|
||||
class UnsafePath(ValueError):
|
||||
"""Raised when a path crosses its allowed filesystem boundary."""
|
||||
@@ -52,11 +59,10 @@ def resolve_within(root: os.PathLike[str] | str, value: os.PathLike[str] | str)
|
||||
raw = os.fspath(value) if value is not None else ""
|
||||
if not isinstance(raw, str) or not raw:
|
||||
raise UnsafePath("path is empty")
|
||||
# Treat both separator families as structural on every host. Otherwise a
|
||||
# Windows traversal string is an innocent-looking filename when validated
|
||||
# on Linux (and can become dangerous after persisted data is moved).
|
||||
if os.sep != "\\" and ("\\" in raw or bool(ntpath.splitdrive(raw)[0])):
|
||||
raise UnsafePath("path uses a foreign separator or drive")
|
||||
# Treat both separator families as structural on every host while still
|
||||
# rejecting Windows drive paths before rebuilding relative components.
|
||||
if os.sep != "\\" and bool(ntpath.splitdrive(raw)[0]):
|
||||
raise UnsafePath("path uses a drive")
|
||||
root_path = Path(root).expanduser().resolve(strict=False)
|
||||
root_text = str(root_path)
|
||||
if os.path.isabs(raw):
|
||||
@@ -69,7 +75,7 @@ def resolve_within(root: os.PathLike[str] | str, value: os.PathLike[str] | str)
|
||||
# containment proof explicit to static analysis, this rejects empty,
|
||||
# dot, parent, drive, and separator-bearing components before Path sees
|
||||
# any persisted/request-derived string.
|
||||
parts = raw.split(os.sep)
|
||||
parts = _PATH_SEPARATORS.split(raw)
|
||||
clean_parts: list[str] = []
|
||||
for part in parts:
|
||||
clean = os.path.basename(part)
|
||||
|
||||
@@ -57,6 +57,99 @@ def _force_compile_requested() -> bool:
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
|
||||
|
||||
# ── FlashInfer opt-in (upstream k2-fsa port) ────────────────────────────────
|
||||
# Explicit power-user opt-in, CUDA-only: OMNIVOICE_FLASHINFER=1 patches the
|
||||
# OmniVoice model with flashinfer packed attention (~2x per upstream's
|
||||
# benchmarks); =graph additionally captures CUDA graphs (best at batch=1).
|
||||
# Off by default — `flashinfer` is not a shipped dependency, and an
|
||||
# optimization must never be a point of failure. Session-sticky failure
|
||||
# latch mirrors torch.compile's (#278).
|
||||
_FLASHINFER_ENV = "OMNIVOICE_FLASHINFER"
|
||||
_flashinfer_runtime_failure: Optional[str] = None
|
||||
|
||||
|
||||
def flashinfer_mode() -> str:
|
||||
"""The user's ``OMNIVOICE_FLASHINFER`` request: 'off' | 'on' | 'graph'.
|
||||
|
||||
Unknown values normalize to 'off' with a log line naming the env var, so
|
||||
a typo degrades to the default path instead of half-applying.
|
||||
"""
|
||||
value = os.environ.get(_FLASHINFER_ENV, "").strip().lower()
|
||||
if value in {"", "0", "false", "no", "off"}:
|
||||
return "off"
|
||||
if value in {"1", "true", "yes", "on"}:
|
||||
return "on"
|
||||
if value == "graph":
|
||||
return "graph"
|
||||
logger.warning(
|
||||
"%s=%r not recognized (valid: 0, 1, graph) — FlashInfer stays off.",
|
||||
_FLASHINFER_ENV, value,
|
||||
)
|
||||
return "off"
|
||||
|
||||
|
||||
def should_flashinfer(device: str) -> str:
|
||||
"""Resolve the FlashInfer request against this host: 'off' | 'on' | 'graph'.
|
||||
|
||||
Requires all of: the ``OMNIVOICE_FLASHINFER`` opt-in, device == "cuda"
|
||||
(flashinfer is CUDA-only), the ``flashinfer`` package importable, and no
|
||||
earlier runtime failure this session. Every refusal is logged with the
|
||||
reason and the knob's name — the user asked for it, so silence would read
|
||||
as "the setting doesn't work".
|
||||
"""
|
||||
mode = flashinfer_mode()
|
||||
if mode == "off":
|
||||
return "off"
|
||||
if device != "cuda":
|
||||
logger.warning(
|
||||
"%s requested but the compute device is %r — FlashInfer is "
|
||||
"CUDA-only, continuing without it.", _FLASHINFER_ENV, device,
|
||||
)
|
||||
return "off"
|
||||
if importlib.util.find_spec("flashinfer") is None:
|
||||
logger.warning(
|
||||
"%s requested but the `flashinfer` package is not installed — "
|
||||
"continuing without it. Install with: uv pip install "
|
||||
"flashinfer-python flashinfer-jit-cache "
|
||||
"--extra-index-url https://flashinfer.ai/whl/cu128/ "
|
||||
"(pick the index matching your CUDA build).", _FLASHINFER_ENV,
|
||||
)
|
||||
return "off"
|
||||
if _flashinfer_runtime_failure is not None:
|
||||
logger.info(
|
||||
"FlashInfer skipped: failed earlier this session (%s) — using the "
|
||||
"standard path.", _flashinfer_runtime_failure,
|
||||
)
|
||||
return "off"
|
||||
return mode
|
||||
|
||||
|
||||
def mark_flashinfer_runtime_failure(reason: str) -> None:
|
||||
"""Latch a FlashInfer apply/runtime failure for the rest of the process,
|
||||
same contract as ``mark_compile_runtime_failure``."""
|
||||
global _flashinfer_runtime_failure
|
||||
try:
|
||||
# Import/kernel errors embed absolute paths (wheels under the user's
|
||||
# home) — redact before latching, since the reason is logged here and
|
||||
# re-logged on every later skip.
|
||||
from core.failure import sanitize
|
||||
|
||||
reason = sanitize(reason)
|
||||
except Exception:
|
||||
# Fail closed: if the redactor itself breaks, latching the raw text
|
||||
# would defeat the redaction. Keep only the exception class (the part
|
||||
# before ':' in our "Type: message" reasons) and drop the message.
|
||||
reason = (
|
||||
f"{(reason or '').split(':', 1)[0][:80]} "
|
||||
"(details redacted: sanitizer unavailable)"
|
||||
).strip()
|
||||
_flashinfer_runtime_failure = reason or "unknown FlashInfer runtime failure"
|
||||
logger.warning(
|
||||
"FlashInfer disabled for this session after a runtime failure: %s",
|
||||
_flashinfer_runtime_failure,
|
||||
)
|
||||
|
||||
|
||||
def _cuda_arch_supported_for_compile() -> "tuple[bool, str]":
|
||||
"""Check the GPU's architecture against this torch build's arch list.
|
||||
|
||||
|
||||
@@ -1376,6 +1376,122 @@ def _install_compile_fallback(_model) -> None:
|
||||
_model.generate = _generate_with_compile_fallback
|
||||
|
||||
|
||||
# ── FlashInfer runtime fallback (upstream k2-fsa port) ──────────────────────
|
||||
|
||||
|
||||
def _is_flashinfer_runtime_failure(exc: BaseException) -> bool:
|
||||
"""True when an exception originates in the FlashInfer fast path (the
|
||||
flashinfer package, our omnivoice_flashinfer patch module, or CUDA-graph
|
||||
capture/replay) rather than in the model or the request itself. Same
|
||||
chain/traceback walk as ``_is_compile_runtime_failure``."""
|
||||
import traceback as _tb
|
||||
|
||||
tb_markers = ("/flashinfer/", "omnivoice_flashinfer")
|
||||
msg_markers = ("flashinfer", "cuda graph", "cudagraph")
|
||||
seen: set[int] = set()
|
||||
cur: BaseException | None = exc
|
||||
while cur is not None and id(cur) not in seen:
|
||||
seen.add(id(cur))
|
||||
mod = type(cur).__module__ or ""
|
||||
if mod.startswith("flashinfer"):
|
||||
return True
|
||||
msg = str(cur).lower()
|
||||
if any(marker in msg for marker in msg_markers):
|
||||
return True
|
||||
try:
|
||||
for frame in _tb.extract_tb(cur.__traceback__):
|
||||
filename = (frame.filename or "").replace("\\", "/")
|
||||
if any(marker in filename for marker in tb_markers):
|
||||
return True
|
||||
except Exception:
|
||||
pass
|
||||
if cur.__cause__ is not None:
|
||||
cur = cur.__cause__
|
||||
elif not cur.__suppress_context__:
|
||||
cur = cur.__context__
|
||||
else:
|
||||
cur = None
|
||||
return False
|
||||
|
||||
|
||||
def _unapply_flashinfer(_model) -> None:
|
||||
"""Restore the standard execution path on a FlashInfer-patched model.
|
||||
|
||||
``apply_flashinfer`` works entirely through *instance-level* state —
|
||||
MethodType-bound ``forward``/``_generate_iterative`` overrides and
|
||||
``_fi_*`` attributes — so deleting those attributes restores the class
|
||||
implementations exactly. The attention implementation is restored to the
|
||||
one captured before apply (``_fi_orig_attn_impl`` — could be
|
||||
flash_attention_2, not just sdpa), and use_cache is re-enabled."""
|
||||
llm = getattr(_model, "llm", None)
|
||||
orig_attn = getattr(_model, "_fi_orig_attn_impl", None) or "sdpa"
|
||||
if llm is not None:
|
||||
for module in llm.modules():
|
||||
if "forward" in vars(module):
|
||||
del module.forward
|
||||
for attr in ("_fi_w_qkv", "_fi_qkv_split", "_fi_rope_theta", "_fi_w_gate_up"):
|
||||
if attr in vars(module):
|
||||
delattr(module, attr)
|
||||
try:
|
||||
llm.set_attn_implementation(orig_attn)
|
||||
except Exception:
|
||||
logger.exception(
|
||||
"failed to restore %s attention after FlashInfer", orig_attn
|
||||
)
|
||||
llm.config.use_cache = True
|
||||
for attr in (
|
||||
"_fi_orig_attn_impl",
|
||||
"_generate_iterative",
|
||||
"_fi_runner",
|
||||
"_fi_graph_cache",
|
||||
"_fi_enable_cuda_graph",
|
||||
"_fi_graph_buckets",
|
||||
"_fi_overhead_budget",
|
||||
):
|
||||
if attr in vars(_model):
|
||||
delattr(_model, attr)
|
||||
|
||||
|
||||
def _install_flashinfer_fallback(_model) -> None:
|
||||
"""Wrap ``model.generate`` so a FlashInfer failure at inference time falls
|
||||
back to the standard path instead of failing the generation — the same
|
||||
contract as ``_install_compile_fallback`` (#278): an optimization must
|
||||
never turn a working generation into an error."""
|
||||
orig_generate = _model.generate
|
||||
|
||||
def _generate_with_flashinfer_fallback(*args, **kwargs):
|
||||
try:
|
||||
return orig_generate(*args, **kwargs)
|
||||
except Exception as exc:
|
||||
if not _is_flashinfer_runtime_failure(exc):
|
||||
raise
|
||||
logger.warning(
|
||||
"FlashInfer runtime failure during generation (%s: %s) — "
|
||||
"restoring the standard path and disabling FlashInfer for "
|
||||
"this session. Generation is being retried without it.",
|
||||
type(exc).__name__, exc,
|
||||
)
|
||||
from services import engine_env
|
||||
engine_env.mark_flashinfer_runtime_failure(
|
||||
f"{type(exc).__name__}: {exc}"
|
||||
)
|
||||
# Unapply BEFORE exposing the eager path: while the teardown
|
||||
# mutates modules, _model.generate still routes through the
|
||||
# thread-affinity wrapper, so a concurrent render queues behind
|
||||
# this call instead of racing the half-restored model (Greptile,
|
||||
# #1565 round 2). Only a fully restored model is published.
|
||||
_unapply_flashinfer(_model)
|
||||
_model.generate = orig_generate
|
||||
try:
|
||||
return orig_generate(*args, **kwargs)
|
||||
except Exception as plain_exc:
|
||||
# `from None`: a genuine standard-path failure must not be
|
||||
# chained to — and misread as — the FlashInfer error.
|
||||
raise plain_exc from None
|
||||
|
||||
_model.generate = _generate_with_flashinfer_fallback
|
||||
|
||||
|
||||
# ── #315: thread affinity for cudagraph-compiled models ─────────────────────
|
||||
# `torch.compile(mode="reduce-overhead")` captures CUDA graphs, and captured
|
||||
# graph state is **thread-local** (torch/_inductor/cudagraph_trees keys its
|
||||
@@ -2117,6 +2233,57 @@ def _load_model_sync():
|
||||
"to stop preloading it alongside TTS."
|
||||
) from asr_exc
|
||||
|
||||
# FlashInfer opt-in (upstream k2-fsa port): packed CFG attention +
|
||||
# fused kernels, ~2x on upstream's benchmarks. Applied INSTEAD of
|
||||
# torch.compile — both rewrite the llm's execution and they do not
|
||||
# compose. Best-effort: any apply failure latches the session off and
|
||||
# the standard path continues untouched.
|
||||
flashinfer_applied = False
|
||||
try:
|
||||
from services.engine_env import (
|
||||
mark_flashinfer_runtime_failure,
|
||||
should_flashinfer,
|
||||
)
|
||||
|
||||
fi_mode = should_flashinfer(device)
|
||||
if fi_mode != "off":
|
||||
_set_loading("compiling", "Applying FlashInfer kernels…")
|
||||
try:
|
||||
from omnivoice.models.omnivoice_flashinfer import apply_flashinfer
|
||||
|
||||
# Captured BEFORE apply so unapply (either the failure
|
||||
# branch below or the generate-time fallback) restores
|
||||
# the true prior implementation.
|
||||
_model._fi_orig_attn_impl = getattr(
|
||||
_model.llm.config, "_attn_implementation", "sdpa"
|
||||
)
|
||||
apply_flashinfer(_model, enable_cuda_graph=(fi_mode == "graph"))
|
||||
except Exception as fi_exc: # noqa: BLE001 — perf opt, never fatal
|
||||
mark_flashinfer_runtime_failure(
|
||||
f"{type(fi_exc).__name__}: {fi_exc}"
|
||||
)
|
||||
# apply_flashinfer mutates the model as it goes — a
|
||||
# failure partway leaves half-patched modules that would
|
||||
# crash the next render (Greptile, #1565). Restore fully.
|
||||
_unapply_flashinfer(_model)
|
||||
else:
|
||||
flashinfer_applied = True
|
||||
_install_flashinfer_fallback(_model)
|
||||
# BOTH modes pin inference to one thread. Graph mode for
|
||||
# the #315 reason (captured CUDA-graph state is
|
||||
# thread-local); eager mode because the FlashInfer
|
||||
# attention wrapper and packed position ids are planned
|
||||
# per generation in module state — two _gpu_pool workers
|
||||
# interleaving plan() and run() would corrupt each
|
||||
# other's layout (CodeRabbit/Greptile, #1565).
|
||||
_install_compile_thread_affinity(_model)
|
||||
logger.info(
|
||||
"FlashInfer applied (mode=%s) — torch.compile skipped "
|
||||
"for this load.", fi_mode,
|
||||
)
|
||||
except Exception:
|
||||
logger.exception("FlashInfer opt-in check failed; continuing without")
|
||||
|
||||
try:
|
||||
# plan-02 (#65): gate on Triton availability (+ user setting), not
|
||||
# just device==cuda. Triton has no Windows wheel, so the old
|
||||
@@ -2124,7 +2291,7 @@ def _load_model_sync():
|
||||
# falls back to eager there.
|
||||
from services.engine_env import should_torch_compile
|
||||
|
||||
if should_torch_compile(device):
|
||||
if not flashinfer_applied and should_torch_compile(device):
|
||||
_set_loading("compiling", "Compiling model (torch.compile)…")
|
||||
try:
|
||||
_model.llm = torch.compile(_model.llm, mode=_TORCH_COMPILE_MODE)
|
||||
|
||||
@@ -412,6 +412,95 @@ _PROMPT_CACHE_MAX = 8
|
||||
_prompt_cache: "OrderedDict[tuple, object]" = OrderedDict()
|
||||
_prompt_cache_lock = threading.Lock()
|
||||
|
||||
# Disk layer under the in-memory LRU (upstream k2-fsa VoiceClonePrompt.save/
|
||||
# load format). The in-memory cache dies with the process, so the first
|
||||
# generation of every session re-encodes each voice (~0.4 s + an ASR pass when
|
||||
# ref_text is missing). Encoded prompts are tiny (a (8, T) int token tensor +
|
||||
# transcript), so we persist them and reload across restarts. Keyed by the
|
||||
# same tuple as the memory cache — the ref file's mtime is inside the key, so
|
||||
# an edited reference never matches a stale file; stale files age out via the
|
||||
# mtime prune. Best-effort like the memory cache: any failure means "no disk
|
||||
# hit / no disk write", never a failed generation. OMNIVOICE_PROMPT_DISK_CACHE=0
|
||||
# disables the layer entirely.
|
||||
_PROMPT_DISK_CACHE_MAX = 32
|
||||
|
||||
|
||||
def _prompt_disk_dir():
|
||||
"""Return the prompt-cache directory (created on first use), or None when
|
||||
the layer is disabled or the directory can't be created."""
|
||||
if os.environ.get("OMNIVOICE_PROMPT_DISK_CACHE", "1") == "0":
|
||||
return None
|
||||
try:
|
||||
from core.config import DATA_DIR
|
||||
|
||||
path = os.path.join(str(DATA_DIR), "prompt_cache")
|
||||
os.makedirs(path, exist_ok=True)
|
||||
return path
|
||||
except Exception as e: # noqa: BLE001 — cache layer must never break synthesis
|
||||
logger.debug("prompt disk cache unavailable: %s", e)
|
||||
return None
|
||||
|
||||
|
||||
def _prompt_disk_path(cache_dir: str, key: tuple) -> str:
|
||||
import hashlib
|
||||
|
||||
digest = hashlib.sha256(repr(key).encode("utf-8")).hexdigest()[:32]
|
||||
return os.path.join(cache_dir, f"{digest}.pt")
|
||||
|
||||
|
||||
def _prompt_disk_load(key: tuple):
|
||||
"""Load a persisted prompt for ``key``, or None. Never raises."""
|
||||
cache_dir = _prompt_disk_dir()
|
||||
if cache_dir is None:
|
||||
return None
|
||||
path = _prompt_disk_path(cache_dir, key)
|
||||
if not os.path.exists(path):
|
||||
return None
|
||||
try:
|
||||
from omnivoice.models.omnivoice import VoiceClonePrompt
|
||||
|
||||
prompt = VoiceClonePrompt.load(path)
|
||||
# Freshen so the LRU prune (by mtime) keeps actively used voices.
|
||||
os.utime(path, None)
|
||||
return prompt
|
||||
except Exception as e: # noqa: BLE001
|
||||
logger.warning("failed to load cached voice prompt %s: %s", path, e)
|
||||
try:
|
||||
os.remove(path) # corrupt/incompatible file — don't retry it forever
|
||||
except OSError:
|
||||
pass
|
||||
return None
|
||||
|
||||
|
||||
def _prompt_disk_save(key: tuple, prompt) -> None:
|
||||
"""Persist ``prompt`` under ``key`` and prune old entries. Never raises."""
|
||||
cache_dir = _prompt_disk_dir()
|
||||
if cache_dir is None:
|
||||
return
|
||||
path = _prompt_disk_path(cache_dir, key)
|
||||
try:
|
||||
# Unique per write: two GPU-pool threads missing the same key must not
|
||||
# interleave writes into one tmp file (os.replace stays atomic).
|
||||
import uuid
|
||||
|
||||
tmp = f"{path}.tmp.{os.getpid()}.{uuid.uuid4().hex[:8]}"
|
||||
prompt.save(tmp)
|
||||
os.replace(tmp, path)
|
||||
except Exception as e: # noqa: BLE001
|
||||
logger.warning("failed to persist voice prompt to %s: %s", path, e)
|
||||
return
|
||||
try:
|
||||
entries = [
|
||||
os.path.join(cache_dir, f)
|
||||
for f in os.listdir(cache_dir)
|
||||
if f.endswith(".pt")
|
||||
]
|
||||
entries.sort(key=lambda p: os.path.getmtime(p), reverse=True)
|
||||
for old in entries[_PROMPT_DISK_CACHE_MAX:]:
|
||||
os.remove(old)
|
||||
except OSError as e:
|
||||
logger.debug("prompt disk cache prune skipped: %s", e)
|
||||
|
||||
|
||||
def _clone_prompt_key(ref_audio: str, ref_text, preprocess_prompt: bool = True):
|
||||
try:
|
||||
@@ -450,15 +539,24 @@ def _get_clone_prompt(
|
||||
if hit is not None:
|
||||
_prompt_cache.move_to_end(key)
|
||||
return hit
|
||||
try:
|
||||
# Encode outside the lock (slow). Mirrors exactly what generate() would
|
||||
# do inline for this ref (omnivoice.py:964-978), so output is identical.
|
||||
prompt = model.create_voice_clone_prompt(
|
||||
ref_audio, ref_text=ref_text, preprocess_prompt=preprocess_prompt
|
||||
)
|
||||
except Exception as e: # noqa: BLE001 — fall back, never break synthesis
|
||||
logger.warning("voice-clone prompt precompute failed; using inline ref: %s", e)
|
||||
return None
|
||||
# Memory miss → disk (survives restarts). A disk hit skips the encode AND
|
||||
# the ASR transcription pass a ref_text-less reference would trigger.
|
||||
prompt = _prompt_disk_load(key)
|
||||
if prompt is None:
|
||||
try:
|
||||
# Encode outside the lock (slow). Mirrors exactly what generate()
|
||||
# would do inline for this ref (omnivoice.py:964-978), so output is
|
||||
# identical.
|
||||
prompt = model.create_voice_clone_prompt(
|
||||
ref_audio, ref_text=ref_text, preprocess_prompt=preprocess_prompt
|
||||
)
|
||||
except Exception as e: # noqa: BLE001 — fall back, never break synthesis
|
||||
logger.warning(
|
||||
"voice-clone prompt precompute failed; using inline ref: %s", e
|
||||
)
|
||||
return None
|
||||
if store:
|
||||
_prompt_disk_save(key, prompt)
|
||||
if not store:
|
||||
return prompt
|
||||
with _prompt_cache_lock:
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
# VoiceStudio
|
||||
|
||||
**The open-source ElevenLabs alternative.** Real-time dictation, zero-shot voice
|
||||
cloning, and cinematic video dubbing — fully local, no API keys, no accounts.
|
||||
cloning, and cinematic video dubbing — fully local, with no cloud API keys or accounts.
|
||||
**646 languages.**
|
||||
|
||||
[](https://hub.docker.com/r/palashdeb/omnivoice-studio)
|
||||
@@ -30,6 +30,14 @@ weights + cache (20 GB+ comfortable), and optionally a GPU — 4 GB VRAM works
|
||||
the entire pipeline runs on CPU, just slower. Pull size: ~5 GB compressed
|
||||
(CUDA/CPU image), ~15 GB for the `:rocm` variant.
|
||||
|
||||
## See it in action
|
||||
|
||||
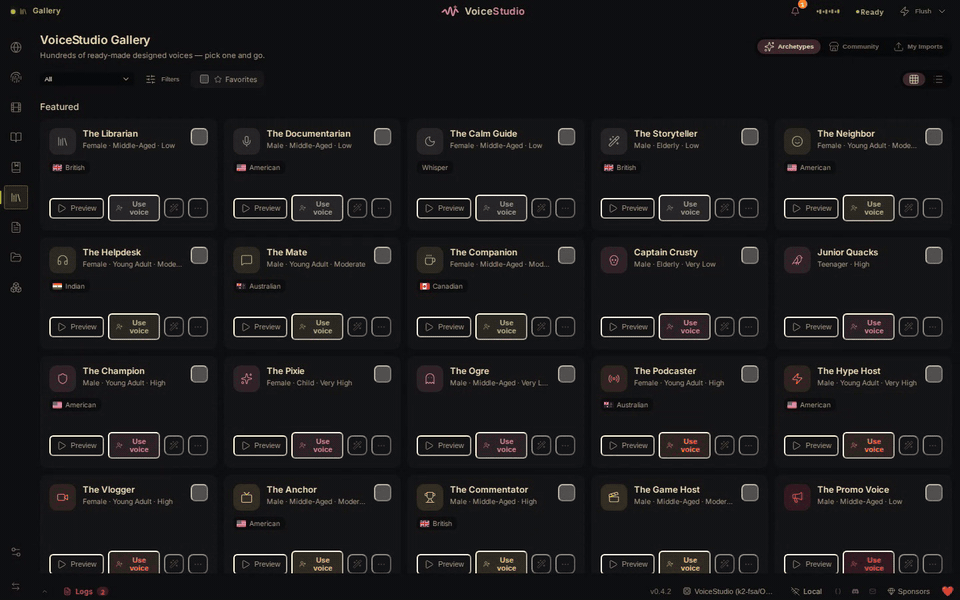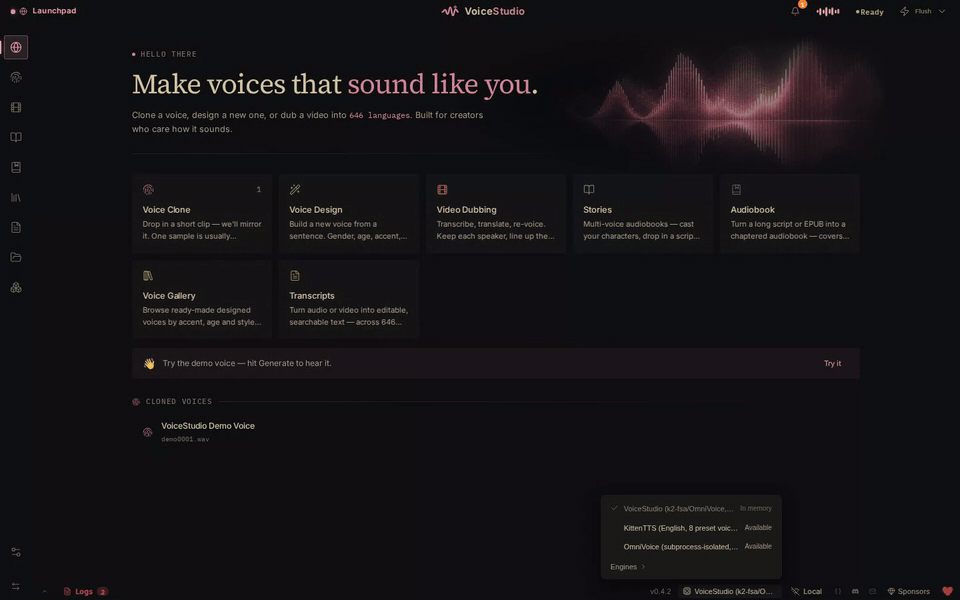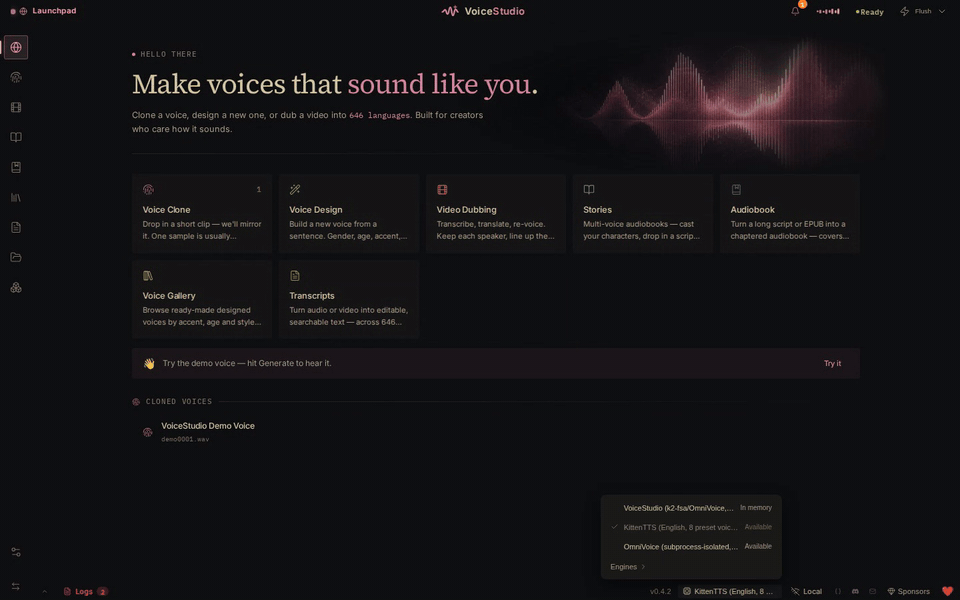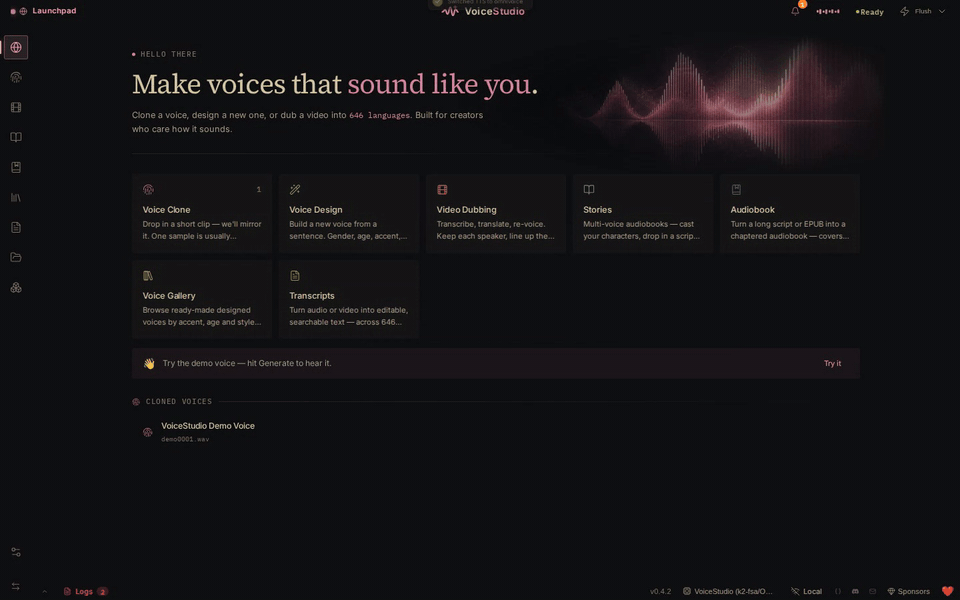
|
||||
|
||||
| Model catalogue | Save a gallery voice |
|
||||
|---|---|
|
||||
| 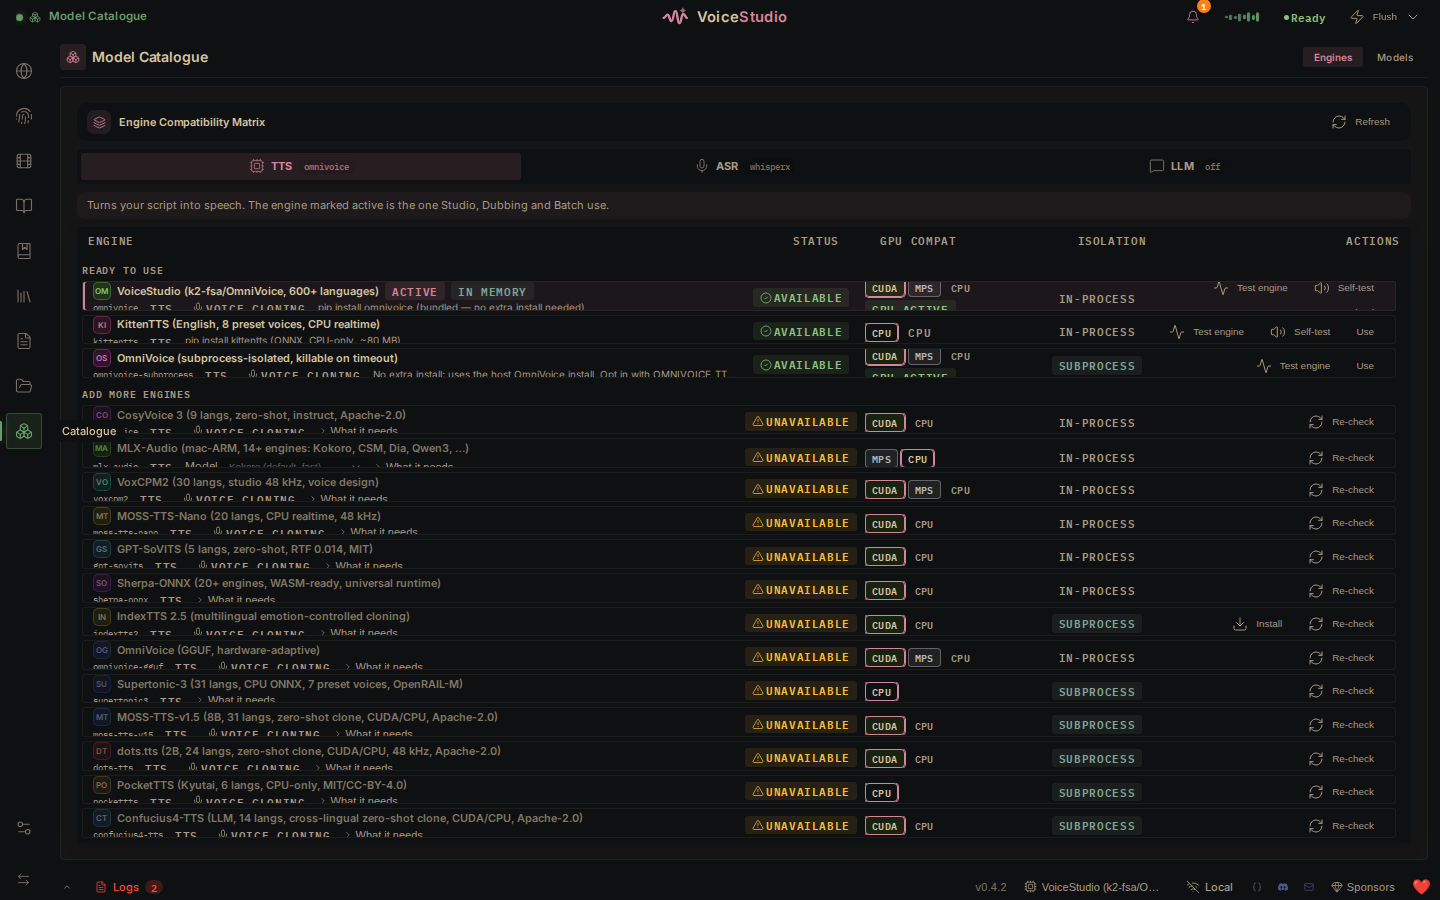 | 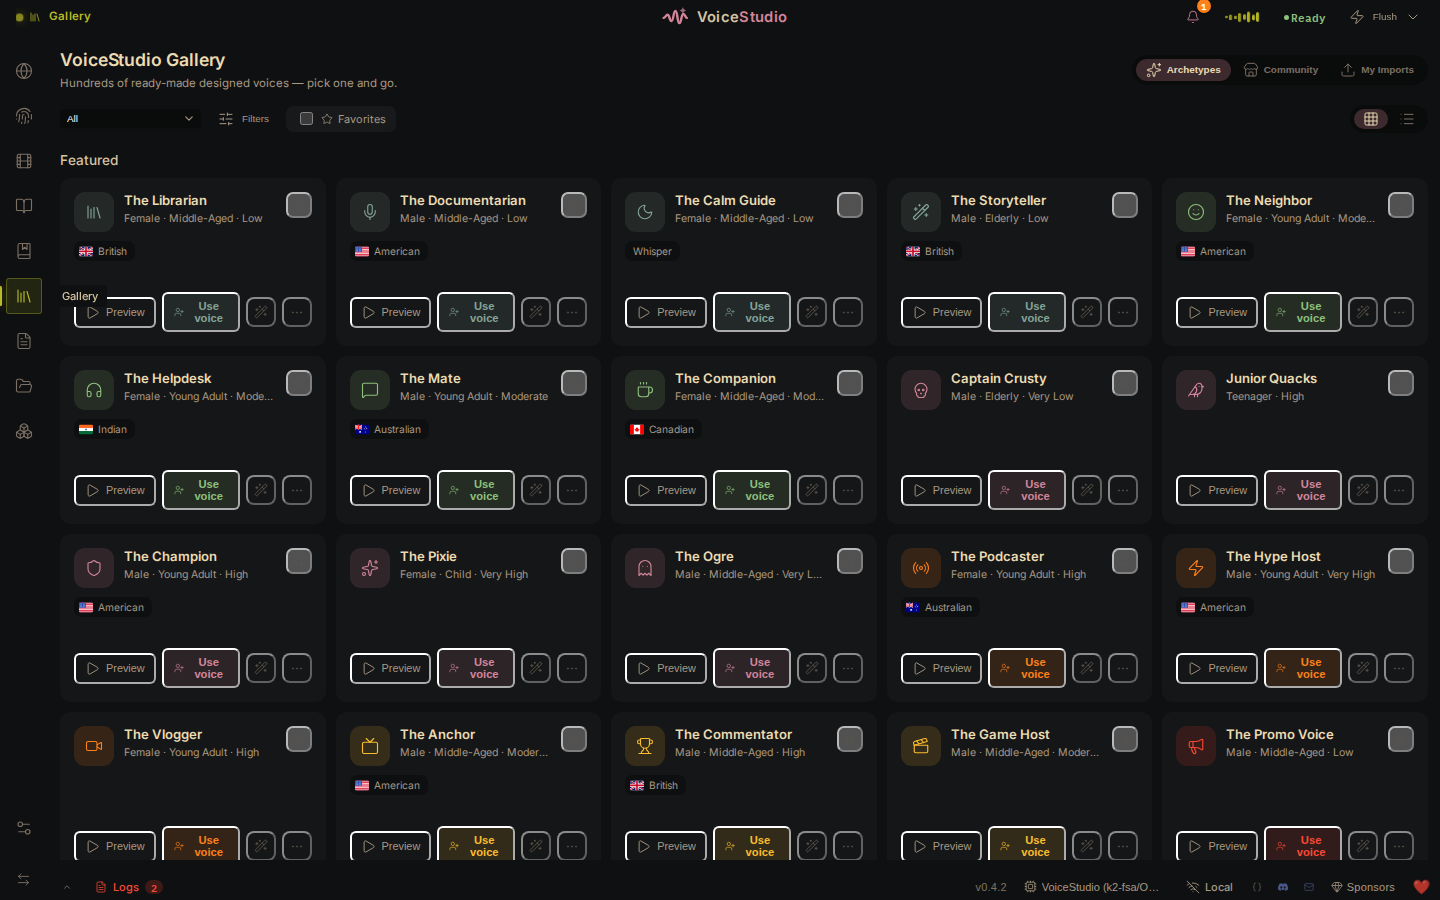 |
|
||||
|
||||
---
|
||||
|
||||
## Quick start (CPU)
|
||||
@@ -90,12 +98,12 @@ There's also a Compose file in the repo with `cpu` / `gpu` / `rocm` profiles
|
||||
|-----|--------------|
|
||||
| `:latest` | **Rolling preview** — latest commit on `main`, at or ahead of the last release. This is the preview channel; pin `:stable` for production. |
|
||||
| `:stable` | Most recent versioned release (updated on every `v*` git tag) |
|
||||
| `:0.4.1` | Exact release version |
|
||||
| `:0.4` | Latest patch within the `0.4` minor |
|
||||
| `:0.5.0` | Exact release version |
|
||||
| `:0.5` | Latest patch within the `0.5` minor |
|
||||
| `:main` | Alias of the same rolling `main` build as `:latest` |
|
||||
| `:sha-xxxxxxx` | A specific commit (produced by manual workflow dispatch) |
|
||||
| `:rocm` | **AMD GPU (ROCm) build** of the rolling preview — the ROCm analogue of `:latest` |
|
||||
| `:stable-rocm`, `:0.4.1-rocm`, `:0.4-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding tags above |
|
||||
| `:stable-rocm`, `:0.5.0-rocm`, `:0.5-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding tags above |
|
||||
|
||||
Preview builds always come from `main` and never version-sort below `:stable`,
|
||||
so upgrades flow naturally. The same images and tags
|
||||
@@ -143,11 +151,17 @@ more), auto-detected and selectable in Settings.
|
||||
- The image ships with `OMNIVOICE_SERVER_MODE=1`, which relaxes the desktop-only
|
||||
loopback-origin gate so the admin UI works through Docker's NAT. Set it to `0`
|
||||
if you front the container with your own loopback auth proxy.
|
||||
- For LAN or internet-facing deployments, set a long random
|
||||
`OMNIVOICE_API_KEY` and pass the same key through the browser's login prompt.
|
||||
A six-digit share PIN is also available for casual LAN access, but it does
|
||||
not authorize administration or dictation; see the
|
||||
[API authentication guide](https://github.com/debpalash/VoiceStudio/blob/main/docs/api-auth.md).
|
||||
|
||||
> **Security:** VoiceStudio ships **no authentication**. Anything that can reach the
|
||||
> URL can use the app. Before exposing it beyond localhost, put it behind a
|
||||
> reverse proxy with auth (Caddy `basic_auth`, nginx + htpasswd) or a private
|
||||
> overlay (Tailscale, ZeroTier).
|
||||
> **Security:** Loopback-only publishing is the safe default. Before exposing
|
||||
> VoiceStudio on a trusted LAN, configure `OMNIVOICE_API_KEY`. On any untrusted
|
||||
> network, plain HTTP is not safe for the API key or session cookie. Keep the
|
||||
> backend on an encrypted private overlay such as Tailscale/ZeroTier; do not
|
||||
> expose it directly to the public internet.
|
||||
|
||||
---
|
||||
|
||||
|
||||
+1
-1
@@ -342,7 +342,7 @@ arbitrary path merely because it ends in `/ws/events` or `/ws/transcribe`.
|
||||
| Code | Meaning | What to do |
|
||||
|---|---|---|
|
||||
| **401** | Consumption auth failed — `{"detail": "PIN required"}` or `{"detail": "API key required"}`. | Supply the PIN / key (header, cookie, or query param above). A WebSocket surfaces this as close code **1008**. |
|
||||
| **403** | Authorization failed: loopback/native access was required, cookie Origin/CSRF validation failed, a server-mode mutation lacked an admin credential, or a native path capability was invalid/expired. | A PIN cannot grant admin or filesystem access. Re-authenticate the UI; scripts should use the API-key header; run native operations from the desktop app. |
|
||||
| **403** | Authorization failed: loopback/native access was required, cookie Origin/CSRF validation failed, a server-mode mutation lacked an admin credential, or a native path capability was invalid/expired. | A PIN cannot grant admin or filesystem access. Re-authenticate the UI; scripts should use the API-key header; run native operations from the desktop app. The admin gate names the key only when one can satisfy it: server mode with `OMNIVOICE_API_KEY` configured answers `{"detail": "loopback origin or admin API key required"}` (the bundled UI routes it to the API-key login form); PIN-only/no-key server mode and the desktop build answer `{"detail": "loopback origin required"}` (only loopback can satisfy the gate). |
|
||||
| **429** | A failed administrator-session exchange exceeded its per-client limit, the GPU pool is saturated, or a model download is rate-limited. Ships with `Retry-After`; workload throttles also carry `X-VoiceStudio-Retryable: true`. | Back off for `Retry-After` seconds. For authentication, verify the master before retrying; a correct master is never locked out. |
|
||||
|
||||
---
|
||||
|
||||
@@ -47,13 +47,39 @@ The env var overrides the persisted UI choice.
|
||||
co-loaded for the cloning path.
|
||||
- Output is 24 kHz mono; the shared mastering chain (highpass + compressor)
|
||||
is tuned for this rate and applied automatically.
|
||||
- Cloning takes a short reference clip (`ref_audio`); an optional transcript
|
||||
of the clip improves conditioning.
|
||||
- Cloning takes a short reference clip (`ref_audio`); 3–10 seconds is the
|
||||
sweet spot. A transcript of the clip improves conditioning — if the profile
|
||||
has none, VoiceStudio transcribes the clip automatically on first use and
|
||||
saves the result to the profile.
|
||||
- Encoded voice references persist on disk (`prompt_cache/` in the app data
|
||||
dir), so the first generation with a known voice after a restart skips the
|
||||
re-encode and any transcription pass. Set `OMNIVOICE_PROMPT_DISK_CACHE=0`
|
||||
to keep the cache in memory only.
|
||||
- Style attributes (`instruct`) and a reference clip can be **combined**:
|
||||
when they agree, the instruct stabilizes cloning for the attributes it
|
||||
names (upstream documents dialect cloning as the canonical case — dialect
|
||||
reference + matching dialect instruct). When they conflict, the reference
|
||||
audio wins.
|
||||
- Inline pronunciation control: Chinese via pinyin with tone numbers
|
||||
(`打ZHE2出售`), English via bracketed CMU phonemes (`[B EY1 S]`). Non-verbal
|
||||
tags like `[laughter]` are covered in
|
||||
[expressive-speech.md](../expressive-speech.md).
|
||||
- Voice design works from attributes (gender, age, pitch, whisper, English
|
||||
accents, Chinese dialects) via the Design tab — no reference audio needed.
|
||||
- Optional FlashInfer acceleration on CUDA: set `OMNIVOICE_FLASHINFER=1`
|
||||
(or `=graph` for CUDA-graph capture, best for one render at a time) after
|
||||
installing the `flashinfer-python` package — see
|
||||
[performance.md](../performance.md). Off by default; if the package is
|
||||
missing or a kernel fails, the app logs why and continues on the standard
|
||||
path.
|
||||
|
||||
## Known limits
|
||||
|
||||
- No voice design from a text description — use [VoxCPM2](voxcpm2.md) for
|
||||
that.
|
||||
- Voice design understands only the fixed attribute vocabulary — free-form
|
||||
design *prose* is mapped onto those attributes, and wording outside them
|
||||
is ignored. Design is trained on English and Chinese and can be unstable
|
||||
in low-resource languages; for description-driven design in other cases
|
||||
try [VoxCPM2](voxcpm2.md).
|
||||
- Below the 6 GB VRAM floor, expect very slow renders or budget timeouts;
|
||||
prefer [OmniVoice GGUF](omnivoice-gguf.md) or a CPU engine such as
|
||||
[PocketTTS](pockettts.md).
|
||||
|
||||
+12
-8
@@ -13,12 +13,12 @@ and [`palashdeb/omnivoice-studio` on Docker Hub](https://hub.docker.com/r/palash
|
||||
> |-----|--------------|
|
||||
> | `:latest` | **Rolling preview** — latest commit on `main`, at or ahead of the last release. This is the preview channel; pin `:stable` for production. |
|
||||
> | `:stable` | Most recent versioned release (updated on every `v*` git tag) |
|
||||
> | `:0.4.1` | Exact release version |
|
||||
> | `:0.4` | Latest patch within the 0.4 minor |
|
||||
> | `:0.5.0` | Exact release version |
|
||||
> | `:0.5` | Latest patch within the 0.5 minor |
|
||||
> | `:main` | Alias of the same rolling `main` build as `:latest` |
|
||||
> | `:sha-xxxxxxx` | Specific commit (produced by manual workflow dispatch) |
|
||||
> | `:rocm` | **AMD GPU (ROCm) build** of the rolling preview — the ROCm analogue of `:latest` |
|
||||
> | `:stable-rocm`, `:0.4.1-rocm`, `:0.4-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding CUDA tags above |
|
||||
> | `:stable-rocm`, `:0.5.0-rocm`, `:0.5-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding CUDA tags above |
|
||||
>
|
||||
> Versioning rule: preview builds always come from `main` and never
|
||||
> version-sort below `:stable` — upgrades flow naturally.
|
||||
@@ -89,7 +89,7 @@ PublishPort=127.0.0.1:3900:3900
|
||||
Volume=omnivoice-data:/app/omnivoice_data
|
||||
```
|
||||
|
||||
Release pins exist too: `:stable-rocm`, `:0.4.1-rocm`, `:0.4-rocm` mirror
|
||||
Release pins exist too: `:stable-rocm`, `:0.5.0-rocm`, `:0.5-rocm` mirror
|
||||
the CUDA tags exactly.
|
||||
|
||||
> **Consumer cards and APUs (RX 6000/7000, Strix Point/Halo):** the backend
|
||||
@@ -192,10 +192,14 @@ docker run -e OMNIVOICE_PUBLIC_API_BASE=https://api.your-host.example \
|
||||
> may instead bake `VITE_OMNIVOICE_API` at build time, but the runtime var above
|
||||
> is simpler and image-agnostic.
|
||||
|
||||
> **Security:** VoiceStudio ships no authentication. Anything on your LAN with
|
||||
> the URL can use the app. Put it behind a reverse proxy with `basic_auth`
|
||||
> (Caddy / nginx + htpasswd) or a private network overlay (Tailscale, ZeroTier)
|
||||
> before exposing publicly.
|
||||
> **Security:** Loopback-only publishing is the safe default. On a trusted LAN,
|
||||
> set a long random `OMNIVOICE_API_KEY` with `docker run -e` or Compose; the
|
||||
> browser will prompt for it. The optional six-digit share PIN permits casual
|
||||
> consumption access but does not authorize administration or dictation. On any
|
||||
> untrusted network, plain HTTP is not safe for the API key or session cookie.
|
||||
> Keep the backend on an encrypted private overlay such as Tailscale/ZeroTier;
|
||||
> do not expose it directly to the public internet. See [API
|
||||
> authentication](../api-auth.md) for the complete access model.
|
||||
|
||||
## Volume mounts
|
||||
|
||||
|
||||
@@ -81,6 +81,8 @@ None of them are required — the defaults are chosen for the common case.
|
||||
| Variable | Default | What it does |
|
||||
|---|---|---|
|
||||
| `OMNIVOICE_DEVICE` | `auto` | Pin the compute device (`cuda` / `rocm` / `xpu` / `mps` / `cpu`) instead of auto-detect. Same control lives in **Settings → Performance & Device** (the env var wins over the UI pick). Honored only for devices the host actually has — a family that isn't detected is noted and ignored, never obeyed blindly. Applies at the next backend start. |
|
||||
| `OMNIVOICE_FLASHINFER` | `0` | CUDA-only accelerated decoding for the default engine via [FlashInfer](https://github.com/flashinfer-ai/flashinfer) kernels (packed CFG attention, fused RMSNorm/RoPE/GEMM) — ~2x on upstream's benchmarks. `1` enables it; `graph` also captures CUDA graphs (best when you render one thing at a time). Requires installing the optional `flashinfer-python` package into the backend environment first (`uv pip install flashinfer-python flashinfer-jit-cache --extra-index-url https://flashinfer.ai/whl/cu128/`, matching your CUDA build). Replaces `torch.compile` for that session, pins inference to a single GPU thread (the FlashInfer attention plan is per-generation state), and keeps fused copies of the attention/MLP weights resident (~roughly half the LLM's weight size extra VRAM) — leave it off on tight-VRAM cards. If the package is missing or a FlashInfer/CUDA-graph kernel fails at runtime, the app logs the reason and falls back to the standard path; failures outside those kernels (e.g. a genuine out-of-memory) surface normally. |
|
||||
| `OMNIVOICE_PROMPT_DISK_CACHE` | `1` | Persist encoded voice-clone references (`prompt_cache/` in the app data dir, ~10 KB per voice, 32 newest kept) so the first generation with a known voice after a restart skips the reference re-encode and any auto-transcription. Set `0` to keep the cache in memory only. |
|
||||
| `OMNIVOICE_IDLE_TIMEOUT_S` | `900` | Seconds of idle before the TTS model unloads to free memory. Raise it (e.g. `3600`) if you generate in bursts and dislike the ~8 s reload; lower it on tight-memory machines. |
|
||||
| `OMNIVOICE_SIDECAR_IDLE_TIMEOUT_S` | `300` | Same idea for sidecar engines (IndexTTS 2.5 etc.). |
|
||||
| `OMNIVOICE_LLM_CONCURRENCY` | `6` | Parallel LLM translation calls during a dub. Raise for a fast API endpoint, lower if your provider rate-limits. |
|
||||
|
||||
@@ -16,6 +16,10 @@ For another device on the same network — e.g. opening the web UI on your phone
|
||||
|
||||
You can also drive this from **Settings → Sharing & Remote Access**.
|
||||
|
||||
Desktop installers include the web interface used by the LAN address; another
|
||||
device does not need VoiceStudio installed and the host does not need a source
|
||||
checkout or a separate frontend development server.
|
||||
|
||||
### How the PIN works
|
||||
- A fresh 6-digit PIN is generated each time you enable sharing; it is never written to disk.
|
||||
- The QR encodes the PIN (`…/?pin=######`) so scanning connects in one step. Typing the bare URL instead prompts for the PIN.
|
||||
|
||||
@@ -845,6 +845,59 @@ pub fn copy_dir_recursive(src: &Path, dst: &Path) -> io::Result<()> {
|
||||
Ok(())
|
||||
}
|
||||
|
||||
/// Install the production SPA beside `backend/`, where the Python server's
|
||||
/// static-file mount resolves it for Network Sharing clients.
|
||||
fn sync_packaged_frontend(resource_root: &Path, project_dir: &Path) -> io::Result<()> {
|
||||
let source = resource_root.join("frontend").join("dist");
|
||||
if !source.join("index.html").is_file() {
|
||||
return Err(io::Error::new(
|
||||
io::ErrorKind::NotFound,
|
||||
"bundled frontend is missing index.html",
|
||||
));
|
||||
}
|
||||
|
||||
let destination = project_dir.join("frontend").join("dist");
|
||||
let frontend_dir = destination.parent().expect("frontend dist has a parent");
|
||||
let staging = frontend_dir.join(".dist-staging");
|
||||
let backup = frontend_dir.join(".dist-backup");
|
||||
fs::create_dir_all(frontend_dir)?;
|
||||
if staging.exists() {
|
||||
fs::remove_dir_all(&staging)?;
|
||||
}
|
||||
// A previous process may have died after moving the live shell aside but
|
||||
// before installing staging. Restore the only known-good SPA before doing
|
||||
// any new work; never discard that recovery copy merely because startup
|
||||
// retried.
|
||||
if !destination.exists() && backup.exists() {
|
||||
fs::rename(&backup, &destination)?;
|
||||
}
|
||||
if let Err(error) = copy_dir_recursive(&source, &staging) {
|
||||
let _ = fs::remove_dir_all(&staging);
|
||||
return Err(error);
|
||||
}
|
||||
|
||||
if destination.exists() {
|
||||
if backup.exists() {
|
||||
// An interrupted cleanup can leave an incomplete backup. Remove
|
||||
// it before touching the known-working destination; if cleanup
|
||||
// fails, abort with the live shell still intact.
|
||||
fs::remove_dir_all(&backup)?;
|
||||
}
|
||||
fs::rename(&destination, &backup)?;
|
||||
}
|
||||
if let Err(error) = fs::rename(&staging, &destination) {
|
||||
if backup.exists() {
|
||||
let _ = fs::rename(&backup, &destination);
|
||||
}
|
||||
let _ = fs::remove_dir_all(&staging);
|
||||
return Err(error);
|
||||
}
|
||||
if backup.exists() {
|
||||
fs::remove_dir_all(backup)?;
|
||||
}
|
||||
Ok(())
|
||||
}
|
||||
|
||||
/// Refresh `pyproject.toml` + `uv.lock` in the project dir from the bundled
|
||||
/// resources, so an upgraded app never runs freshly-synced backend code against
|
||||
/// the stale dependency manifests from when the venv was first created (#307 —
|
||||
@@ -1539,11 +1592,13 @@ manually, then relaunch.",
|
||||
if let Some(ref res) = resource_dir {
|
||||
let flat = res.clone();
|
||||
let up2 = res.join("_up_").join("_up_");
|
||||
let (res_omni, res_backend) = if flat.join("pyproject.toml").is_file() {
|
||||
(flat.join("omnivoice"), flat.join("backend"))
|
||||
let res_root = if flat.join("pyproject.toml").is_file() {
|
||||
flat
|
||||
} else {
|
||||
(up2.join("omnivoice"), up2.join("backend"))
|
||||
up2
|
||||
};
|
||||
let res_omni = res_root.join("omnivoice");
|
||||
let res_backend = res_root.join("backend");
|
||||
if res_omni.is_dir() {
|
||||
let omnivoice_dir = project_dir.join("omnivoice");
|
||||
let _ = fs::remove_dir_all(&omnivoice_dir);
|
||||
@@ -1561,6 +1616,11 @@ manually, then relaunch.",
|
||||
}
|
||||
log::info!("Synced backend/ from bundle");
|
||||
}
|
||||
if let Err(e) = sync_packaged_frontend(&res_root, &project_dir) {
|
||||
fail(progress, &format!("Failed to sync frontend/dist: {}", e));
|
||||
return None;
|
||||
}
|
||||
log::info!("Synced frontend/dist from bundle");
|
||||
// #307: the source dirs above track the bundle, so the
|
||||
// dependency manifests must too — otherwise an upgrade runs
|
||||
// new code against a venv that predates newly added deps.
|
||||
@@ -1659,6 +1719,17 @@ the existing venv; newly added dependencies may be missing (#307)",
|
||||
// copies from when the venv was first created.
|
||||
if let Ok(res) = app.path().resource_dir() {
|
||||
let _ = refresh_project_manifests(&res, &project_dir);
|
||||
let flat = res.clone();
|
||||
let up2 = res.join("_up_").join("_up_");
|
||||
let res_root = if flat.join("pyproject.toml").is_file() {
|
||||
flat
|
||||
} else {
|
||||
up2
|
||||
};
|
||||
if let Err(e) = sync_packaged_frontend(&res_root, &project_dir) {
|
||||
fail(progress, &format!("Failed to sync frontend/dist: {}", e));
|
||||
return None;
|
||||
}
|
||||
}
|
||||
let mut repair_cmd = Command::new(&uv_path);
|
||||
scrub_python_env(&mut repair_cmd); // #144: don't inherit AppImage's bundled Python
|
||||
@@ -1763,16 +1834,22 @@ the existing venv; newly added dependencies may be missing (#307)",
|
||||
let flat = resource_dir.clone();
|
||||
let up2 = resource_dir.join("_up_").join("_up_");
|
||||
|
||||
let (resource_pyproject, resource_uvlock, resource_readme, resource_changelog, resource_omnivoice, resource_backend) = if flat.join("pyproject.toml").is_file() {
|
||||
(flat.join("pyproject.toml"), flat.join("uv.lock"), flat.join("README.md"), flat.join("CHANGELOG.md"), flat.join("omnivoice"), flat.join("backend"))
|
||||
let resource_root = if flat.join("pyproject.toml").is_file() {
|
||||
flat
|
||||
} else if up2.join("pyproject.toml").is_file() {
|
||||
(up2.join("pyproject.toml"), up2.join("uv.lock"), up2.join("README.md"), up2.join("CHANGELOG.md"), up2.join("omnivoice"), up2.join("backend"))
|
||||
up2
|
||||
} else {
|
||||
fail(progress, &format!(
|
||||
"Missing bootstrap resources — checked flat={} and _up_={}",
|
||||
flat.display(), up2.display()));
|
||||
return None;
|
||||
};
|
||||
let resource_pyproject = resource_root.join("pyproject.toml");
|
||||
let resource_uvlock = resource_root.join("uv.lock");
|
||||
let resource_readme = resource_root.join("README.md");
|
||||
let resource_changelog = resource_root.join("CHANGELOG.md");
|
||||
let resource_omnivoice = resource_root.join("omnivoice");
|
||||
let resource_backend = resource_root.join("backend");
|
||||
|
||||
if !resource_pyproject.is_file() || !resource_backend.is_dir() {
|
||||
fail(progress, &format!(
|
||||
@@ -1821,6 +1898,10 @@ the existing venv; newly added dependencies may be missing (#307)",
|
||||
fail(progress, &format!("copy backend/: {}", e));
|
||||
return None;
|
||||
}
|
||||
if let Err(e) = sync_packaged_frontend(&resource_root, &project_dir) {
|
||||
fail(progress, &format!("copy frontend/dist: {}", e));
|
||||
return None;
|
||||
}
|
||||
|
||||
let uv_path = match resolve_uv(app, &app_data, progress) {
|
||||
Ok(p) => p,
|
||||
@@ -2051,6 +2132,118 @@ mod tests {
|
||||
use super::*;
|
||||
use std::collections::HashMap;
|
||||
|
||||
#[test]
|
||||
fn packaged_frontend_is_installed_for_the_lan_server() {
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
let source = resources.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(source.join("assets")).unwrap();
|
||||
fs::write(source.join("index.html"), "new shell").unwrap();
|
||||
fs::write(source.join("assets").join("client.js"), "new client").unwrap();
|
||||
|
||||
let installed = project.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(&installed).unwrap();
|
||||
fs::write(installed.join("index.html"), "stale shell").unwrap();
|
||||
|
||||
sync_packaged_frontend(resources.path(), project.path()).unwrap();
|
||||
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("index.html")).unwrap(),
|
||||
"new shell"
|
||||
);
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("assets").join("client.js")).unwrap(),
|
||||
"new client"
|
||||
);
|
||||
}
|
||||
|
||||
#[test]
|
||||
fn packaged_frontend_error_does_not_expose_resource_path() {
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
|
||||
let error = sync_packaged_frontend(resources.path(), project.path()).unwrap_err();
|
||||
|
||||
assert_eq!(error.kind(), io::ErrorKind::NotFound);
|
||||
assert_eq!(error.to_string(), "bundled frontend is missing index.html");
|
||||
assert!(!error.to_string().contains(&resources.path().display().to_string()));
|
||||
}
|
||||
|
||||
#[cfg(unix)]
|
||||
#[test]
|
||||
fn failed_packaged_frontend_copy_preserves_installed_shell() {
|
||||
use std::os::unix::fs::symlink;
|
||||
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
let source = resources.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(source.join("assets")).unwrap();
|
||||
fs::write(source.join("index.html"), "new shell").unwrap();
|
||||
symlink("missing-client.js", source.join("assets").join("client.js")).unwrap();
|
||||
|
||||
let installed = project.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(&installed).unwrap();
|
||||
fs::write(installed.join("index.html"), "working shell").unwrap();
|
||||
|
||||
sync_packaged_frontend(resources.path(), project.path()).unwrap_err();
|
||||
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("index.html")).unwrap(),
|
||||
"working shell"
|
||||
);
|
||||
}
|
||||
|
||||
#[cfg(unix)]
|
||||
#[test]
|
||||
fn interrupted_frontend_swap_recovers_backup_before_a_later_copy_failure() {
|
||||
use std::os::unix::fs::symlink;
|
||||
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
let source = resources.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(source.join("assets")).unwrap();
|
||||
fs::write(source.join("index.html"), "new shell").unwrap();
|
||||
symlink("missing-client.js", source.join("assets").join("client.js")).unwrap();
|
||||
|
||||
let frontend = project.path().join("frontend");
|
||||
let installed = frontend.join("dist");
|
||||
let backup = frontend.join(".dist-backup");
|
||||
fs::create_dir_all(&backup).unwrap();
|
||||
fs::write(backup.join("index.html"), "working backup shell").unwrap();
|
||||
|
||||
sync_packaged_frontend(resources.path(), project.path()).unwrap_err();
|
||||
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("index.html")).unwrap(),
|
||||
"working backup shell"
|
||||
);
|
||||
}
|
||||
|
||||
#[test]
|
||||
fn interrupted_backup_cleanup_failure_preserves_working_destination() {
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
let source = resources.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(&source).unwrap();
|
||||
fs::write(source.join("index.html"), "new shell").unwrap();
|
||||
|
||||
let frontend = project.path().join("frontend");
|
||||
let installed = frontend.join("dist");
|
||||
let backup = frontend.join(".dist-backup");
|
||||
fs::create_dir_all(&installed).unwrap();
|
||||
fs::write(installed.join("index.html"), "working shell").unwrap();
|
||||
// A non-directory at the interrupted backup path makes cleanup fail
|
||||
// and would also prevent the live destination from being renamed.
|
||||
fs::write(&backup, "partial backup").unwrap();
|
||||
|
||||
sync_packaged_frontend(resources.path(), project.path()).unwrap_err();
|
||||
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("index.html")).unwrap(),
|
||||
"working shell"
|
||||
);
|
||||
}
|
||||
|
||||
#[test]
|
||||
fn update_drift_sync_preserves_user_installed_engines() {
|
||||
// #1029: the routine update sync must carry --inexact so a
|
||||
|
||||
@@ -79,7 +79,8 @@
|
||||
"../../README.md",
|
||||
"../../CHANGELOG.md",
|
||||
"../../omnivoice",
|
||||
"../../backend"
|
||||
"../../backend",
|
||||
"../../frontend/dist"
|
||||
],
|
||||
"externalBin": [
|
||||
"binaries/uv",
|
||||
|
||||
@@ -182,15 +182,16 @@ describe('apiFetch 401 routing', () => {
|
||||
dispatch.mockRestore();
|
||||
});
|
||||
|
||||
const stub401 = (detail: string) =>
|
||||
const stubStatus = (status: number, statusText: string, detail: string) =>
|
||||
vi.fn(() =>
|
||||
Promise.resolve({
|
||||
ok: false,
|
||||
status: 401,
|
||||
statusText: 'Unauthorized',
|
||||
status,
|
||||
statusText,
|
||||
text: async () => JSON.stringify({ detail }),
|
||||
}),
|
||||
) as any;
|
||||
const stub401 = (detail: string) => stubStatus(401, 'Unauthorized', detail);
|
||||
|
||||
const authEvent = () =>
|
||||
dispatch.mock.calls.map((c) => c[0]).find((e) => (e as Event).type === 'ov:auth-required');
|
||||
@@ -227,6 +228,70 @@ describe('apiFetch 401 routing', () => {
|
||||
expect(authEvent()).toBeTruthy();
|
||||
expect((authEvent() as any).detail.mode).toBe('pin');
|
||||
});
|
||||
|
||||
const stub403 = (detail: string) => stubStatus(403, 'Forbidden', detail);
|
||||
|
||||
it('dispatches ov:auth-required {mode:"apikey"} on an admin-gate 403 (#1525)', async () => {
|
||||
globalThis.fetch = stub403('loopback origin or admin API key required');
|
||||
const { apiFetch } = await import('./client');
|
||||
try {
|
||||
await apiFetch('/system/info');
|
||||
} catch {
|
||||
/* ApiError expected */
|
||||
}
|
||||
expect(authEvent()).toBeTruthy();
|
||||
expect((authEvent() as any).detail.mode).toBe('apikey');
|
||||
});
|
||||
|
||||
it('does not dispatch ov:auth-required on other 403s (CSRF / desktop-only)', async () => {
|
||||
globalThis.fetch = stub403('browser origin rejected');
|
||||
const { apiFetch } = await import('./client');
|
||||
try {
|
||||
await apiFetch('/system/info');
|
||||
} catch {
|
||||
/* ApiError expected */
|
||||
}
|
||||
expect(authEvent()).toBeFalsy();
|
||||
});
|
||||
|
||||
it('a stale 403 neither clears a new session nor reopens the auth gate (PR #1569 race)', async () => {
|
||||
// The request goes out with an old credential; while it is in flight the
|
||||
// user completes another key exchange. A late 403 may only invalidate the
|
||||
// credentials the failed request actually carried — wiping the fresh
|
||||
// session or reopening the gate would undo the successful login.
|
||||
sessionStorage.setItem(
|
||||
ADMIN_SESSION_STORAGE_KEY,
|
||||
JSON.stringify({
|
||||
token: `ovs_admin_session_${'O'.repeat(43)}`,
|
||||
expiresAt: Date.now() / 1000 + 3600,
|
||||
apiBase: API,
|
||||
}),
|
||||
);
|
||||
globalThis.fetch = vi.fn(() => {
|
||||
sessionStorage.setItem(
|
||||
ADMIN_SESSION_STORAGE_KEY,
|
||||
JSON.stringify({
|
||||
token: `ovs_admin_session_${'N'.repeat(43)}`,
|
||||
expiresAt: Date.now() / 1000 + 3600,
|
||||
apiBase: API,
|
||||
}),
|
||||
);
|
||||
return Promise.resolve({
|
||||
ok: false,
|
||||
status: 403,
|
||||
statusText: 'Forbidden',
|
||||
text: async () => JSON.stringify({ detail: 'loopback origin or admin API key required' }),
|
||||
});
|
||||
}) as any;
|
||||
const { apiFetch } = await import('./client');
|
||||
try {
|
||||
await apiFetch('/system/info');
|
||||
} catch {
|
||||
/* ApiError expected */
|
||||
}
|
||||
expect(authEvent()).toBeFalsy();
|
||||
expect(sessionStorage.getItem(ADMIN_SESSION_STORAGE_KEY)).not.toBeNull();
|
||||
});
|
||||
});
|
||||
|
||||
describe('apiFetch 404 from a non-VoiceStudio server (#1385)', () => {
|
||||
|
||||
@@ -528,15 +528,37 @@ export async function apiFetch(path: string, opts: ApiFetchOptions = {}): Promis
|
||||
// "API key required" (BearerKeyMiddleware, OMNIVOICE_API_KEY) vs anything
|
||||
// else, i.e. "PIN required" (NetworkAccessMiddleware). Both are 401; the
|
||||
// detail is the only discriminator (only two 401 sites exist backend-side).
|
||||
if (backendTarget && res.status === 401 && typeof window !== 'undefined') {
|
||||
// The router-level admin gates answer 403 "loopback origin or admin API
|
||||
// key required" (require_admin/require_admin_action) — same situation, the
|
||||
// client just isn't admin-authenticated — so it routes to the API-key form
|
||||
// too. Other 403s (CSRF "browser origin rejected", loopback-only routes)
|
||||
// are NOT credential gaps; presenting a key won't help, so they stay plain
|
||||
// errors.
|
||||
const adminGate403 =
|
||||
res.status === 403 &&
|
||||
typeof detail === 'string' &&
|
||||
detail.toLowerCase().includes('admin api key');
|
||||
if (backendTarget && (res.status === 401 || adminGate403) && typeof window !== 'undefined') {
|
||||
// readError's declared `string` return isn't guaranteed at runtime —
|
||||
// `j.detail` can be a structured object/array on a future 401. Match only
|
||||
// real strings (avoids both a `.toLowerCase()` crash and `String()` itself
|
||||
// throwing on a malformed object); anything else falls back to PIN.
|
||||
// (No adminGate403 arm here: "admin api key" ⊇ "api key", so the sniff
|
||||
// below already yields 'apikey' for every admin-gate 403.)
|
||||
const mode =
|
||||
typeof detail === 'string' && detail.toLowerCase().includes('api key') ? 'apikey' : 'pin';
|
||||
if (mode === 'apikey') clearAdminSession();
|
||||
window.dispatchEvent(new CustomEvent('ov:auth-required', { detail: { mode } }));
|
||||
// A failed response may only invalidate the credentials it actually
|
||||
// carried (`session` is captured at send time). Clearing blindly let
|
||||
// a stale 403 that landed after a key exchange wipe the fresh
|
||||
// session, reloading a successful login straight back into the gate.
|
||||
const currentSession = getAdminSession(API);
|
||||
const staleAdminResponse = mode === 'apikey' && currentSession?.token !== session?.token;
|
||||
if (mode === 'apikey' && !staleAdminResponse && session) {
|
||||
clearAdminSession();
|
||||
}
|
||||
if (!staleAdminResponse) {
|
||||
window.dispatchEvent(new CustomEvent('ov:auth-required', { detail: { mode } }));
|
||||
}
|
||||
}
|
||||
// Structured details (e.g. the typed asr_model_missing 409) carry a
|
||||
// human-readable `message` — use it for the Error message instead of
|
||||
|
||||
@@ -91,12 +91,60 @@ class OmniVoiceModelAssetError(RuntimeError):
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
_VOICE_CLONE_PROMPT_FORMAT_VERSION = 1
|
||||
|
||||
|
||||
@dataclass
|
||||
class VoiceClonePrompt:
|
||||
ref_audio_tokens: torch.Tensor # (C, T)
|
||||
ref_text: str
|
||||
ref_rms: float
|
||||
|
||||
def save(self, path: str) -> None:
|
||||
"""Save this prompt to ``path`` for reuse in a later session.
|
||||
|
||||
The file stores a plain dict with the audio tokens moved to CPU, so
|
||||
it can be loaded with ``torch.load(weights_only=True)`` (the default
|
||||
since torch 2.6) and is portable across devices.
|
||||
|
||||
Args:
|
||||
path: Destination file path (e.g. ``"my_voice.pt"``).
|
||||
"""
|
||||
torch.save(
|
||||
{
|
||||
"format_version": _VOICE_CLONE_PROMPT_FORMAT_VERSION,
|
||||
"ref_audio_tokens": self.ref_audio_tokens.detach().cpu(),
|
||||
"ref_text": self.ref_text,
|
||||
"ref_rms": float(self.ref_rms),
|
||||
},
|
||||
path,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def load(cls, path: str, map_location: str = "cpu") -> "VoiceClonePrompt":
|
||||
"""Load a prompt saved with :meth:`save`.
|
||||
|
||||
The returned prompt can be passed directly to
|
||||
:meth:`OmniVoice.generate`; the audio tokens are moved to the model
|
||||
device automatically during generation, so no manual ``.to(device)``
|
||||
is needed.
|
||||
|
||||
Args:
|
||||
path: File path previously written by :meth:`save`.
|
||||
map_location: Device to load the audio tokens onto.
|
||||
Returns:
|
||||
The restored :class:`VoiceClonePrompt`.
|
||||
"""
|
||||
data = torch.load(path, map_location=map_location, weights_only=True)
|
||||
version = data.get("format_version")
|
||||
if version != _VOICE_CLONE_PROMPT_FORMAT_VERSION:
|
||||
raise ValueError(f"Unsupported VoiceClonePrompt format version: {version}")
|
||||
return cls(
|
||||
ref_audio_tokens=data["ref_audio_tokens"],
|
||||
ref_text=data["ref_text"],
|
||||
ref_rms=data["ref_rms"],
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class OmniVoiceGenerationConfig:
|
||||
|
||||
@@ -0,0 +1,667 @@
|
||||
# SPDX-FileCopyrightText: Copyright (c) 2026, NVIDIA CORPORATION. All rights reserved.
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
"""FlashInfer-accelerated iterative decoding for OmniVoice.
|
||||
|
||||
Approach (mirrors CosyVoice/runtime/triton_trtllm/token2wav_dit_flashinfer.py):
|
||||
|
||||
- Sequence packing: the baseline pads the uncond (CFG) sequence to the cond
|
||||
length and runs batch=2 with a (2,1,S,S) bool mask. Here cond+uncond are
|
||||
packed into ONE row of length c_len+u_len with per-document positions and
|
||||
flashinfer ragged attention (qo_indptr = document boundaries) — no pad
|
||||
compute, no S^2 mask materialization.
|
||||
- Attention: registered as a custom HF attention implementation
|
||||
("omnivoice_fi") via AttentionInterface; reads the wrapper planned
|
||||
once per generation from a module-level context. HF mask construction is
|
||||
bypassed by passing attention_mask={"full_attention": None}.
|
||||
- KV cache: disabled (llm.config.use_cache=False). Iterative bidirectional
|
||||
decoding recomputes the full sequence every step, so the DynamicCache the
|
||||
baseline builds each forward is pure overhead.
|
||||
- Optional CUDA graphs: one graph per packed shape; all 32 denoising steps
|
||||
replay the same graph (input_ids/audio_mask/position_ids are copied into
|
||||
static buffers). Each shape owns a private flashinfer wrapper, since a
|
||||
plan bakes its launch metadata into the captured graph.
|
||||
|
||||
Usage:
|
||||
from omnivoice_flashinfer import apply_flashinfer
|
||||
apply_flashinfer(model, enable_cuda_graph=True)
|
||||
|
||||
Ported from upstream k2-fsa/OmniVoice master with one behavioural change:
|
||||
the unmasking schedule uses ``num_step + 1`` timesteps to match this repo's
|
||||
``_generate_iterative``. VoiceStudio enables it via ``OMNIVOICE_FLASHINFER``
|
||||
(see services/model_manager.py); ``flashinfer`` is an optional dependency and
|
||||
this module must only be imported after that opt-in.
|
||||
"""
|
||||
|
||||
import math
|
||||
import time
|
||||
from types import MethodType
|
||||
from typing import List
|
||||
|
||||
import flashinfer
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from transformers.modeling_utils import AttentionInterface
|
||||
|
||||
from omnivoice.models.omnivoice import (
|
||||
GenerationTask,
|
||||
OmniVoiceGenerationConfig,
|
||||
_get_time_steps,
|
||||
_gumbel_sample,
|
||||
)
|
||||
|
||||
_WORKSPACE_SIZE = 128 * 1024 * 1024
|
||||
# Context read by the registered attention function. "wrapper" must be planned
|
||||
# for the current packed layout before any llm forward.
|
||||
_CTX = {"wrapper": None}
|
||||
|
||||
|
||||
def _flashinfer_attention(
|
||||
module, query, key, value, attention_mask, scaling=None, dropout=0.0, **kwargs
|
||||
):
|
||||
"""query (1, Hq, S, D), key/value (1, Hkv, S, D) — packed documents."""
|
||||
_b, hq, s, d = query.shape
|
||||
hkv = key.shape[1]
|
||||
q = query.transpose(1, 2).reshape(s, hq, d)
|
||||
k = key.transpose(1, 2).reshape(s, hkv, d)
|
||||
v = value.transpose(1, 2).reshape(s, hkv, d)
|
||||
out = _CTX["wrapper"].run(q, k, v) # (S, Hq, D)
|
||||
return out.view(1, s, hq, d), None
|
||||
|
||||
|
||||
AttentionInterface.register("omnivoice_fi", _flashinfer_attention)
|
||||
|
||||
|
||||
def _fi_rmsnorm_forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
|
||||
"""Single-kernel replacement for Qwen3RMSNorm.forward (a 7-kernel
|
||||
fp32-upcast chain in eager mode). flashinfer.norm.rmsnorm computes in
|
||||
fp32 internally and matches to fp16 rounding."""
|
||||
shape = hidden_states.shape
|
||||
out = flashinfer.norm.rmsnorm(
|
||||
hidden_states.reshape(-1, shape[-1]).contiguous(),
|
||||
self.weight,
|
||||
eps=self.variance_epsilon,
|
||||
)
|
||||
return out.view(shape)
|
||||
|
||||
|
||||
def _patch_rmsnorm(llm):
|
||||
from transformers.models.qwen3.modeling_qwen3 import Qwen3RMSNorm
|
||||
|
||||
n = 0
|
||||
for module in llm.modules():
|
||||
if isinstance(module, Qwen3RMSNorm):
|
||||
module.forward = MethodType(_fi_rmsnorm_forward, module)
|
||||
n += 1
|
||||
return n
|
||||
|
||||
|
||||
def _fi_attention_module_forward(
|
||||
self,
|
||||
hidden_states,
|
||||
position_embeddings=None,
|
||||
attention_mask=None,
|
||||
past_key_values=None,
|
||||
**kwargs,
|
||||
):
|
||||
"""NHD-layout replacement for Qwen3Attention.forward (packed batch=1).
|
||||
|
||||
The stock forward works in (B, H, S, D): the rotate-half RoPE costs a cat
|
||||
plus four elementwise passes, and handing (B,H,S,D) to the ragged wrapper
|
||||
costs three transpose copies. Keeping everything in (S, H, D) removes all
|
||||
of that; RoPE is one fused in-place kernel driven by packed position ids
|
||||
(read from _CTX, set per generation / baked per graph)."""
|
||||
s = hidden_states.shape[1]
|
||||
x = hidden_states[0] # (S, hidden)
|
||||
if getattr(self, "_fi_w_qkv", None) is not None:
|
||||
qkv = F.linear(x, self._fi_w_qkv)
|
||||
q, k, v = qkv.split(self._fi_qkv_split, dim=-1)
|
||||
# split views are strided; reshape materializes contiguous copies
|
||||
# (q/k would be copied inside the fused rmsnorm anyway)
|
||||
q = self.q_norm(q.reshape(s, -1, self.head_dim))
|
||||
k = self.k_norm(k.reshape(s, -1, self.head_dim))
|
||||
v = v.reshape(s, -1, self.head_dim)
|
||||
else:
|
||||
q = self.q_norm(self.q_proj(x).view(s, -1, self.head_dim))
|
||||
k = self.k_norm(self.k_proj(x).view(s, -1, self.head_dim))
|
||||
v = self.v_proj(x).view(s, -1, self.head_dim)
|
||||
flashinfer.rope.apply_rope_pos_ids_inplace(
|
||||
q, k, _CTX["pos_ids"], rope_theta=self._fi_rope_theta, interleave=False
|
||||
)
|
||||
slots = _CTX.get("doc_slots")
|
||||
if slots is not None:
|
||||
# bucketed-graph mode: a flashinfer plan bakes document boundaries
|
||||
# into the graph, so attention runs per fixed-length document slot as
|
||||
# SDPA with an O(slot) key-padding mask whose contents are rewritten
|
||||
# per generation. (A dense (S,S) block-diag mask scales quadratically
|
||||
# and the enable_gqa+mask combo drops SDPA to the math backend, so
|
||||
# k/v are pre-expanded to full heads instead.)
|
||||
ng = self.num_key_value_groups
|
||||
k = k.repeat_interleave(ng, dim=1) # (S, Hq, D)
|
||||
v = v.repeat_interleave(ng, dim=1)
|
||||
out = torch.empty_like(q)
|
||||
for start, slot_len, m in slots:
|
||||
od = F.scaled_dot_product_attention(
|
||||
q[start : start + slot_len].transpose(0, 1).unsqueeze(0),
|
||||
k[start : start + slot_len].transpose(0, 1).unsqueeze(0),
|
||||
v[start : start + slot_len].transpose(0, 1).unsqueeze(0),
|
||||
attn_mask=m,
|
||||
)
|
||||
out[start : start + slot_len] = od.squeeze(0).transpose(0, 1)
|
||||
else:
|
||||
out = _CTX["wrapper"].run(q, k, v) # (S, Hq, D)
|
||||
return self.o_proj(out.reshape(s, -1)).unsqueeze(0), None
|
||||
|
||||
|
||||
def _patch_attention_forward(llm, fuse_qkv=True):
|
||||
theta = llm.config.rope_parameters["rope_theta"]
|
||||
for layer in llm.layers:
|
||||
attn = layer.self_attn
|
||||
attn._fi_rope_theta = theta
|
||||
if fuse_qkv:
|
||||
attn._fi_w_qkv = torch.cat(
|
||||
[attn.q_proj.weight, attn.k_proj.weight, attn.v_proj.weight], dim=0
|
||||
)
|
||||
attn._fi_qkv_split = [
|
||||
attn.q_proj.weight.shape[0],
|
||||
attn.k_proj.weight.shape[0],
|
||||
attn.v_proj.weight.shape[0],
|
||||
]
|
||||
attn.forward = MethodType(_fi_attention_module_forward, attn)
|
||||
|
||||
|
||||
def _fi_mlp_forward(self, x):
|
||||
"""Qwen3MLP with fused gate+up GEMM and flashinfer silu_and_mul
|
||||
(2 GEMMs + silu + mul -> 1 GEMM + 1 fused kernel)."""
|
||||
y = F.linear(x[0], self._fi_w_gate_up) # (S, 2*inter)
|
||||
y = flashinfer.activation.silu_and_mul(y)
|
||||
return self.down_proj(y).unsqueeze(0)
|
||||
|
||||
|
||||
def _patch_mlp(llm):
|
||||
for layer in llm.layers:
|
||||
mlp = layer.mlp
|
||||
mlp._fi_w_gate_up = torch.cat([mlp.gate_proj.weight, mlp.up_proj.weight], dim=0)
|
||||
mlp.forward = MethodType(_fi_mlp_forward, mlp)
|
||||
|
||||
|
||||
class PackedAttnRunner:
|
||||
def __init__(
|
||||
self,
|
||||
num_qo_heads,
|
||||
num_kv_heads,
|
||||
head_dim,
|
||||
device,
|
||||
workspace_size=_WORKSPACE_SIZE,
|
||||
):
|
||||
self.num_qo_heads = num_qo_heads
|
||||
self.num_kv_heads = num_kv_heads
|
||||
self.head_dim = head_dim
|
||||
self.device = device
|
||||
self._workspace = torch.zeros(workspace_size, dtype=torch.uint8, device=device)
|
||||
self.wrapper = flashinfer.BatchPrefillWithRaggedKVCacheWrapper(
|
||||
self._workspace, "NHD"
|
||||
)
|
||||
self._planned_key = None
|
||||
|
||||
def plan(self, doc_lens: List[int], dtype: torch.dtype):
|
||||
key = (tuple(doc_lens), dtype)
|
||||
if key == self._planned_key:
|
||||
return
|
||||
indptr = torch.zeros(len(doc_lens) + 1, dtype=torch.int32, device=self.device)
|
||||
indptr[1:] = torch.cumsum(
|
||||
torch.tensor(doc_lens, dtype=torch.int32, device=self.device), dim=0
|
||||
)
|
||||
self.wrapper.plan(
|
||||
indptr,
|
||||
indptr,
|
||||
self.num_qo_heads,
|
||||
self.num_kv_heads,
|
||||
self.head_dim,
|
||||
causal=False,
|
||||
sm_scale=self.head_dim**-0.5,
|
||||
q_data_type=dtype,
|
||||
kv_data_type=dtype,
|
||||
)
|
||||
self._planned_key = key
|
||||
|
||||
|
||||
def _generate_iterative_packed(
|
||||
self, task: GenerationTask, gen_config: OmniVoiceGenerationConfig
|
||||
) -> List[torch.Tensor]:
|
||||
"""Packed-sequence rewrite of OmniVoice._generate_iterative.
|
||||
|
||||
Documents are packed as [cond_0, uncond_0, cond_1, uncond_1, ...] into a
|
||||
single batch row; the scoring/unmasking math is identical to the original.
|
||||
"""
|
||||
B = task.batch_size
|
||||
inputs_list = [
|
||||
self._prepare_inference_inputs(
|
||||
task.texts[i],
|
||||
task.target_lens[i],
|
||||
task.ref_texts[i],
|
||||
task.ref_audio_tokens[i],
|
||||
task.langs[i],
|
||||
task.instructs[i],
|
||||
gen_config.denoise,
|
||||
)
|
||||
for i in range(B)
|
||||
]
|
||||
|
||||
c_lens = [inp["input_ids"].size(2) for inp in inputs_list]
|
||||
u_lens = list(task.target_lens)
|
||||
doc_lens = []
|
||||
for c, u in zip(c_lens, u_lens):
|
||||
doc_lens.extend([c, u])
|
||||
|
||||
use_graph = getattr(self, "_fi_enable_cuda_graph", False)
|
||||
buckets = getattr(self, "_fi_graph_buckets", None) # durations in seconds
|
||||
|
||||
# Choose the packed layout. Bucketed-graph mode places each item in fixed
|
||||
# slots [C_budget | U_budget] so one graph per (batch, duration bucket)
|
||||
# serves any sample that fits; otherwise pack tightly.
|
||||
bucket_U = None
|
||||
if use_graph and buckets is not None:
|
||||
frame_rate = self.audio_tokenizer.config.frame_rate
|
||||
t_max = max(u_lens)
|
||||
overhead_max = max(c - u for c, u in zip(c_lens, u_lens))
|
||||
bucket_U = next(
|
||||
(int(d * frame_rate) for d in sorted(buckets) if d * frame_rate >= t_max),
|
||||
None,
|
||||
)
|
||||
if bucket_U is None or overhead_max > self._fi_overhead_budget:
|
||||
bucket_U = None
|
||||
use_graph = False # too long for the buckets: eager fallback
|
||||
|
||||
if bucket_U is not None:
|
||||
U_b = bucket_U
|
||||
C_b = U_b + self._fi_overhead_budget
|
||||
offsets = []
|
||||
for i in range(B):
|
||||
offsets.extend([i * (C_b + U_b), i * (C_b + U_b) + C_b])
|
||||
total_len = B * (C_b + U_b)
|
||||
else:
|
||||
offsets = [0]
|
||||
for l in doc_lens[:-1]:
|
||||
offsets.append(offsets[-1] + l)
|
||||
total_len = sum(doc_lens)
|
||||
|
||||
C = self.config.num_audio_codebook
|
||||
packed_ids = torch.full(
|
||||
(1, C, total_len),
|
||||
self.config.audio_mask_id,
|
||||
dtype=torch.long,
|
||||
device=self.device,
|
||||
)
|
||||
packed_audio_mask = torch.zeros(
|
||||
(1, total_len), dtype=torch.bool, device=self.device
|
||||
)
|
||||
position_ids = torch.zeros((1, total_len), dtype=torch.long, device=self.device)
|
||||
|
||||
for i, inp in enumerate(inputs_list):
|
||||
c_off, u_off = offsets[2 * i], offsets[2 * i + 1]
|
||||
c_len, u_len = c_lens[i], u_lens[i]
|
||||
packed_ids[0, :, c_off : c_off + c_len] = inp["input_ids"][0]
|
||||
packed_audio_mask[0, c_off : c_off + c_len] = inp["audio_mask"][0]
|
||||
position_ids[0, c_off : c_off + c_len] = torch.arange(c_len, device=self.device)
|
||||
# uncond doc = target region only
|
||||
packed_ids[0, :, u_off : u_off + u_len] = inp["input_ids"][0, :, -u_len:]
|
||||
packed_audio_mask[0, u_off : u_off + u_len] = inp["audio_mask"][0, -u_len:]
|
||||
position_ids[0, u_off : u_off + u_len] = torch.arange(u_len, device=self.device)
|
||||
|
||||
# num_step + 1 mirrors our _generate_iterative's schedule (a local
|
||||
# divergence from upstream k2-fsa): packed decoding must unmask on exactly
|
||||
# the same schedule as the eager path or outputs differ between the two.
|
||||
timesteps = _get_time_steps(
|
||||
t_start=0.0,
|
||||
t_end=1.0,
|
||||
num_step=gen_config.num_step + 1,
|
||||
t_shift=gen_config.t_shift,
|
||||
).tolist()
|
||||
schedules = []
|
||||
for t_len in task.target_lens:
|
||||
total_mask = t_len * C
|
||||
rem = total_mask
|
||||
sched = []
|
||||
for step in range(gen_config.num_step):
|
||||
num = (
|
||||
rem
|
||||
if step == gen_config.num_step - 1
|
||||
else min(
|
||||
math.ceil(total_mask * (timesteps[step + 1] - timesteps[step])), rem
|
||||
)
|
||||
)
|
||||
sched.append(int(num))
|
||||
rem -= int(num)
|
||||
schedules.append(sched)
|
||||
|
||||
layer_ids = torch.arange(C, device=self.device).view(1, -1, 1)
|
||||
|
||||
# gather indices of the logits-consuming positions, laid out as
|
||||
# [all cond-target blocks | all uncond blocks] so the guidance/scoring
|
||||
# math can run over every item in one batched pass. flat_spans[i] gives
|
||||
# the item's (start, len) within each half; in bucket mode items sit at a
|
||||
# fixed stride U_b with junk rows (pointing at position 0) in between.
|
||||
cond_ranges, uncond_ranges = [], []
|
||||
flat_spans = []
|
||||
for i in range(B):
|
||||
c_off, u_off = offsets[2 * i], offsets[2 * i + 1]
|
||||
c_len, t_len = c_lens[i], task.target_lens[i]
|
||||
if bucket_U is not None:
|
||||
flat_spans.append((U_b * i, t_len))
|
||||
cond_rows = torch.zeros(U_b, dtype=torch.long, device=self.device)
|
||||
cond_rows[:t_len] = torch.arange(
|
||||
c_off + c_len - t_len, c_off + c_len, device=self.device
|
||||
)
|
||||
uncond_rows = torch.zeros(U_b, dtype=torch.long, device=self.device)
|
||||
uncond_rows[:t_len] = torch.arange(u_off, u_off + t_len, device=self.device)
|
||||
cond_ranges.append(cond_rows)
|
||||
uncond_ranges.append(uncond_rows)
|
||||
else:
|
||||
prev = 0 if i == 0 else flat_spans[-1][0] + flat_spans[-1][1]
|
||||
flat_spans.append((prev, t_len))
|
||||
cond_ranges.append(
|
||||
torch.arange(c_off + c_len - t_len, c_off + c_len, device=self.device)
|
||||
)
|
||||
uncond_ranges.append(torch.arange(u_off, u_off + t_len, device=self.device))
|
||||
T_flat = (U_b * B) if bucket_U is not None else sum(task.target_lens)
|
||||
tgt_index = torch.cat(cond_ranges + uncond_ranges)
|
||||
|
||||
# flat per-position token state aligned with the cond half of the gathered
|
||||
# layout. Junk positions (bucket-mode slot padding) are initialized to -1
|
||||
# so the global "already unmasked" fill gives them -inf scores and topk
|
||||
# never selects them.
|
||||
tokens_flat = torch.full((C, T_flat), -1, dtype=torch.long, device=self.device)
|
||||
for st, t_len in flat_spans:
|
||||
tokens_flat[:, st : st + t_len] = self.config.audio_mask_id
|
||||
|
||||
if use_graph and bucket_U is not None:
|
||||
graph_entry = _get_or_capture_bucket_graph(self, B, U_b, C_b)
|
||||
# refresh the per-generation static contents (shape-invariant, data-variant)
|
||||
graph_entry["audio_mask"].copy_(packed_audio_mask)
|
||||
graph_entry["position_ids"].copy_(position_ids)
|
||||
graph_entry["pos_ids_i32"].copy_(position_ids[0].to(torch.int32))
|
||||
graph_entry["tgt_index"].copy_(tgt_index)
|
||||
for d_idx, m in enumerate(graph_entry["doc_masks"]):
|
||||
length = c_lens[d_idx // 2] if d_idx % 2 == 0 else u_lens[d_idx // 2]
|
||||
m[..., :length] = True
|
||||
m[..., length:] = False
|
||||
elif use_graph:
|
||||
graph_entry = _get_or_capture_graph(self, tuple(doc_lens), tgt_index)
|
||||
graph_entry["audio_mask"].copy_(packed_audio_mask)
|
||||
graph_entry["position_ids"].copy_(position_ids)
|
||||
else:
|
||||
self._fi_runner.plan(doc_lens, torch.float16)
|
||||
_CTX["wrapper"] = self._fi_runner.wrapper
|
||||
_CTX["pos_ids"] = position_ids[0].to(torch.int32)
|
||||
_CTX["doc_slots"] = None
|
||||
|
||||
# optional llm timing hook (set by the benchmark; graph replays bypass
|
||||
# model.forward, so wrapping forward would miss them)
|
||||
stats = getattr(self, "_fi_llm_stats", None)
|
||||
|
||||
for step in range(gen_config.num_step):
|
||||
if stats is not None:
|
||||
torch.cuda.synchronize()
|
||||
t0 = time.perf_counter()
|
||||
if use_graph:
|
||||
graph_entry["input_ids"].copy_(packed_ids)
|
||||
graph_entry["graph"].replay()
|
||||
batch_logits = graph_entry["logits"].to(torch.float32)
|
||||
else:
|
||||
batch_logits = _forward_logits(
|
||||
self, packed_ids, packed_audio_mask, position_ids, tgt_index
|
||||
).to(torch.float32)
|
||||
if stats is not None:
|
||||
torch.cuda.synchronize()
|
||||
stats["seconds"] += time.perf_counter() - t0
|
||||
stats["calls"] += 1
|
||||
|
||||
# batched scoring over every item at once: the guidance/log_softmax/
|
||||
# argmax/gumbel chain (the GPU-heavy part) runs on the whole
|
||||
# [cond | uncond] halves; only topk + scatter stay per item.
|
||||
c_logits_all = batch_logits[:, :, :T_flat, :]
|
||||
u_logits_all = batch_logits[:, :, T_flat:, :]
|
||||
pred_all, scores_all = self._predict_tokens_with_scoring(
|
||||
c_logits_all, u_logits_all, gen_config
|
||||
)
|
||||
scores_all = scores_all - (layer_ids * gen_config.layer_penalty_factor)
|
||||
if gen_config.position_temperature > 0.0:
|
||||
scores_all = _gumbel_sample(scores_all, gen_config.position_temperature)
|
||||
# -inf for already-unmasked positions AND bucket-slot junk (-1)
|
||||
scores_all.masked_fill_(
|
||||
(tokens_flat != self.config.audio_mask_id).unsqueeze(0), -float("inf")
|
||||
)
|
||||
pred_all, scores_all = pred_all[0], scores_all[0] # (C, T_flat)
|
||||
|
||||
for i in range(B):
|
||||
k = schedules[i][step]
|
||||
if k <= 0:
|
||||
continue
|
||||
c_off, u_off = offsets[2 * i], offsets[2 * i + 1]
|
||||
c_len, t_len = c_lens[i], task.target_lens[i]
|
||||
st, _ = flat_spans[i]
|
||||
|
||||
_, topk_idx = torch.topk(scores_all[:, st : st + t_len].reshape(-1), k)
|
||||
flat_tokens = tokens_flat[:, st : st + t_len].reshape(-1)
|
||||
flat_tokens[topk_idx] = pred_all[:, st : st + t_len].reshape(-1)[topk_idx]
|
||||
new_tokens = flat_tokens.view(C, t_len)
|
||||
tokens_flat[:, st : st + t_len] = new_tokens
|
||||
|
||||
packed_ids[0, :, c_off + c_len - t_len : c_off + c_len] = new_tokens
|
||||
packed_ids[0, :, u_off : u_off + t_len] = new_tokens
|
||||
|
||||
return [tokens_flat[:, st : st + t_len] for (st, t_len) in flat_spans]
|
||||
|
||||
|
||||
def _forward_logits(model, input_ids, audio_mask, position_ids, tgt_index):
|
||||
"""LLM forward + audio head over target positions only.
|
||||
|
||||
The scoring step consumes logits at the cond-target and uncond ranges
|
||||
(2*sum(t_len) of the packed positions); running the 1024->8200 audio_heads
|
||||
GEMM and the fp32 upcast on the full packed length is wasted work.
|
||||
Returns logits of shape (1, C, 2*sum(t_len), V) laid out as
|
||||
[all cond-target blocks | all uncond blocks] — matching tgt_index
|
||||
(torch.cat(cond_ranges + uncond_ranges)) and the caller's split at T_flat.
|
||||
"""
|
||||
inputs_embeds = model._prepare_embed_inputs(input_ids, audio_mask)
|
||||
hidden = model.llm(
|
||||
inputs_embeds=inputs_embeds,
|
||||
attention_mask={"full_attention": None},
|
||||
return_dict=True,
|
||||
position_ids=position_ids,
|
||||
)[0]
|
||||
tgt_hidden = hidden[0, tgt_index] # (2T, hidden)
|
||||
logits_flat = model.audio_heads(tgt_hidden)
|
||||
n = tgt_hidden.shape[0]
|
||||
return logits_flat.view(
|
||||
1, n, model.config.num_audio_codebook, model.config.audio_vocab_size
|
||||
).permute(0, 2, 1, 3)
|
||||
|
||||
|
||||
def _get_or_capture_graph(model, doc_lens_key, tgt_index):
|
||||
cache = model._fi_graph_cache
|
||||
entry = cache.get(doc_lens_key)
|
||||
if entry is not None:
|
||||
return entry
|
||||
|
||||
device = model.device
|
||||
total_len = sum(doc_lens_key)
|
||||
C = model.config.num_audio_codebook
|
||||
llm_cfg = model.config.llm_config
|
||||
runner = PackedAttnRunner(
|
||||
llm_cfg.num_attention_heads,
|
||||
llm_cfg.num_key_value_heads,
|
||||
llm_cfg.head_dim,
|
||||
device,
|
||||
workspace_size=64 * 1024 * 1024,
|
||||
)
|
||||
runner.plan(list(doc_lens_key), torch.float16)
|
||||
_CTX["wrapper"] = runner.wrapper
|
||||
|
||||
# positions are fully determined by doc_lens (the cache key), so both the
|
||||
# long buffer (model-level rotary) and the int32 copy (fused rope) can be
|
||||
# baked with their final values
|
||||
positions = torch.cat([torch.arange(l, device=device) for l in doc_lens_key])
|
||||
static = {
|
||||
"input_ids": torch.full(
|
||||
(1, C, total_len),
|
||||
model.config.audio_mask_id,
|
||||
dtype=torch.long,
|
||||
device=device,
|
||||
),
|
||||
"audio_mask": torch.zeros((1, total_len), dtype=torch.bool, device=device),
|
||||
"position_ids": positions.unsqueeze(0).contiguous(),
|
||||
}
|
||||
pos_ids_i32 = positions.to(torch.int32)
|
||||
_CTX["pos_ids"] = pos_ids_i32
|
||||
_CTX["doc_slots"] = None
|
||||
|
||||
side_stream = torch.cuda.Stream()
|
||||
side_stream.wait_stream(torch.cuda.current_stream())
|
||||
with torch.cuda.stream(side_stream):
|
||||
for _ in range(2):
|
||||
_forward_logits(
|
||||
model,
|
||||
static["input_ids"],
|
||||
static["audio_mask"],
|
||||
static["position_ids"],
|
||||
tgt_index,
|
||||
)
|
||||
torch.cuda.current_stream().wait_stream(side_stream)
|
||||
torch.cuda.synchronize()
|
||||
|
||||
graph = torch.cuda.CUDAGraph()
|
||||
with torch.cuda.graph(graph):
|
||||
# tgt_index depends only on doc_lens (the cache key), so it is safe
|
||||
# to bake into the graph
|
||||
logits = _forward_logits(
|
||||
model,
|
||||
static["input_ids"],
|
||||
static["audio_mask"],
|
||||
static["position_ids"],
|
||||
tgt_index,
|
||||
)
|
||||
|
||||
# tgt_index is baked into the captured gather by pointer — the entry must
|
||||
# keep it alive or the allocator will reuse its memory for later samples
|
||||
entry = {
|
||||
"graph": graph,
|
||||
"logits": logits,
|
||||
"runner": runner,
|
||||
"tgt_index": tgt_index,
|
||||
"pos_ids_i32": pos_ids_i32,
|
||||
**static,
|
||||
}
|
||||
cache[doc_lens_key] = entry
|
||||
return entry
|
||||
|
||||
|
||||
def _get_or_capture_bucket_graph(model, B, U_b, C_b):
|
||||
"""One graph per (batch, duration-bucket): items sit in fixed
|
||||
[C_budget | U_budget] slots; attention runs as SDPA over a runtime-updated
|
||||
block-diagonal mask, so any sample that fits the slots replays exactly."""
|
||||
key = ("bucket", B, U_b)
|
||||
cache = model._fi_graph_cache
|
||||
entry = cache.get(key)
|
||||
if entry is not None:
|
||||
return entry
|
||||
|
||||
device = model.device
|
||||
total_len = B * (C_b + U_b)
|
||||
C = model.config.num_audio_codebook
|
||||
|
||||
static = {
|
||||
"input_ids": torch.full(
|
||||
(1, C, total_len),
|
||||
model.config.audio_mask_id,
|
||||
dtype=torch.long,
|
||||
device=device,
|
||||
),
|
||||
"audio_mask": torch.zeros((1, total_len), dtype=torch.bool, device=device),
|
||||
"position_ids": torch.zeros((1, total_len), dtype=torch.long, device=device),
|
||||
"pos_ids_i32": torch.zeros(total_len, dtype=torch.int32, device=device),
|
||||
"tgt_index": torch.zeros(2 * B * U_b, dtype=torch.long, device=device),
|
||||
}
|
||||
# per-document key-padding masks (contents updated per generation);
|
||||
# init all-True so warmup/capture has no fully-masked softmax rows
|
||||
doc_masks, doc_slots = [], []
|
||||
for i in range(B):
|
||||
for slot_start, slot_len in (
|
||||
(i * (C_b + U_b), C_b),
|
||||
(i * (C_b + U_b) + C_b, U_b),
|
||||
):
|
||||
m = torch.ones(1, 1, 1, slot_len, dtype=torch.bool, device=device)
|
||||
doc_masks.append(m)
|
||||
doc_slots.append((slot_start, slot_len, m))
|
||||
|
||||
_CTX["wrapper"] = None
|
||||
_CTX["pos_ids"] = static["pos_ids_i32"]
|
||||
_CTX["doc_slots"] = doc_slots
|
||||
|
||||
side_stream = torch.cuda.Stream()
|
||||
side_stream.wait_stream(torch.cuda.current_stream())
|
||||
with torch.cuda.stream(side_stream):
|
||||
for _ in range(2):
|
||||
_forward_logits(
|
||||
model,
|
||||
static["input_ids"],
|
||||
static["audio_mask"],
|
||||
static["position_ids"],
|
||||
static["tgt_index"],
|
||||
)
|
||||
torch.cuda.current_stream().wait_stream(side_stream)
|
||||
torch.cuda.synchronize()
|
||||
|
||||
graph = torch.cuda.CUDAGraph()
|
||||
with torch.cuda.graph(graph):
|
||||
logits = _forward_logits(
|
||||
model,
|
||||
static["input_ids"],
|
||||
static["audio_mask"],
|
||||
static["position_ids"],
|
||||
static["tgt_index"],
|
||||
)
|
||||
|
||||
entry = {
|
||||
"graph": graph,
|
||||
"logits": logits,
|
||||
"doc_masks": doc_masks,
|
||||
"doc_slots": doc_slots,
|
||||
**static,
|
||||
}
|
||||
cache[key] = entry
|
||||
return entry
|
||||
|
||||
|
||||
def apply_flashinfer(
|
||||
model,
|
||||
enable_cuda_graph: bool = False,
|
||||
fuse_rmsnorm: bool = True,
|
||||
fuse_attention: bool = True,
|
||||
cuda_graph_buckets=None,
|
||||
overhead_budget: int = 512,
|
||||
):
|
||||
"""Patch an OmniVoice instance to use flashinfer packed attention."""
|
||||
model.llm.set_attn_implementation("omnivoice_fi")
|
||||
if fuse_rmsnorm:
|
||||
_patch_rmsnorm(model.llm)
|
||||
if fuse_attention:
|
||||
_patch_attention_forward(model.llm)
|
||||
_patch_mlp(model.llm)
|
||||
# Bidirectional iterative decoding recomputes everything each step; the
|
||||
# DynamicCache the baseline allocates+fills per forward is pure overhead.
|
||||
model.llm.config.use_cache = False
|
||||
|
||||
llm_cfg = model.config.llm_config
|
||||
model._fi_runner = PackedAttnRunner(
|
||||
llm_cfg.num_attention_heads,
|
||||
llm_cfg.num_key_value_heads,
|
||||
llm_cfg.head_dim,
|
||||
model.device,
|
||||
)
|
||||
model._fi_graph_cache = {}
|
||||
model._fi_enable_cuda_graph = enable_cuda_graph or cuda_graph_buckets is not None
|
||||
model._fi_graph_buckets = cuda_graph_buckets
|
||||
model._fi_overhead_budget = overhead_budget
|
||||
model._generate_iterative = MethodType(_generate_iterative_packed, model)
|
||||
return model
|
||||
@@ -0,0 +1,17 @@
|
||||
{
|
||||
"version": 1,
|
||||
"skills": {
|
||||
"fastapi-python": {
|
||||
"source": "mindrally/skills",
|
||||
"sourceType": "github",
|
||||
"skillPath": "fastapi-python/SKILL.md",
|
||||
"computedHash": "cd9c84b3bf2e4cf55f4a3f97b102d3affad2682680eb3d8ec8d2f68020ba5c8d"
|
||||
},
|
||||
"vite": {
|
||||
"source": "mindrally/skills",
|
||||
"sourceType": "github",
|
||||
"skillPath": "vite/SKILL.md",
|
||||
"computedHash": "8995600ea3cf7c18208105011f65b9098a547a19dff446fb774e42ac726d36b1"
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -627,7 +627,7 @@ def test_engine_health_is_admin_gated(fresh_app):
|
||||
client = _client(fresh_app, host="10.0.0.5")
|
||||
r = client.get("/engines/omnivoice/health")
|
||||
assert r.status_code == 403
|
||||
assert r.json()["detail"] == "loopback origin or admin API key required"
|
||||
assert r.json()["detail"] == "loopback origin required"
|
||||
|
||||
|
||||
def test_server_mode_engine_mutations_require_api_key(fresh_app, monkeypatch):
|
||||
@@ -802,7 +802,7 @@ def test_selftest_unknown_id_is_404(fresh_app):
|
||||
def test_selftest_is_admin_gated(fresh_app):
|
||||
r = _client(fresh_app, host="10.0.0.9").post("/engines/omnivoice/selftest")
|
||||
assert r.status_code == 403
|
||||
assert r.json()["detail"] == "loopback origin or admin API key required"
|
||||
assert r.json()["detail"] == "loopback origin required"
|
||||
|
||||
|
||||
def test_selftest_captures_synth_exception_without_500(fresh_app):
|
||||
|
||||
@@ -0,0 +1,76 @@
|
||||
"""Cross-layer contract lock for the admin-gate 403 detail string.
|
||||
|
||||
The backend's ``require_admin``/``require_admin_action`` answer 403 with a
|
||||
mode-distinct ``detail`` (``_admin_gate_403`` in backend/api/dependencies.py):
|
||||
"loopback origin or admin API key required" in server mode, plain
|
||||
"loopback origin required" on the desktop build. The SPA's ``apiFetch`` routes
|
||||
a 403 to the API-key login gate exactly when the detail contains the substring
|
||||
"admin api key" (frontend/src/api/client.ts) — i.e. when presenting the key
|
||||
could actually satisfy the gate. The per-mode behaviour is pinned by
|
||||
tests/test_loopback_server_mode.py; this file pins the LITERAL contract across
|
||||
layers: a backend reword keeps backend tests green while the frontend matcher
|
||||
silently stops firing, and a LAN user is back to raw 403 spam instead of the
|
||||
login form.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from pathlib import Path
|
||||
|
||||
ROOT = Path(__file__).resolve().parents[1]
|
||||
DEPS = ROOT / "backend" / "api" / "dependencies.py"
|
||||
CLIENT = ROOT / "frontend" / "src" / "api" / "client.ts"
|
||||
|
||||
|
||||
def _frontend_sniff() -> str:
|
||||
"""The substring apiFetch matches on a 403 to admit it to the auth gate."""
|
||||
text = CLIENT.read_text(encoding="utf-8")
|
||||
# adminGate403 = ... detail.toLowerCase().includes('<sniff>')
|
||||
m = re.search(r"adminGate403 =.*?includes\('([^']+)'\)", text, re.DOTALL)
|
||||
assert m, "adminGate403 matcher not found in frontend/src/api/client.ts"
|
||||
return m.group(1)
|
||||
|
||||
|
||||
def _key_named_details() -> set[str]:
|
||||
"""Every quoted string in dependencies.py that names the admin API key."""
|
||||
return set(re.findall(r'"([^"]*admin API key[^"]*)"', DEPS.read_text(encoding="utf-8")))
|
||||
|
||||
|
||||
def test_key_named_details_match_frontend_sniff():
|
||||
"""Every backend literal naming the admin key must contain the SPA matcher."""
|
||||
details = _key_named_details()
|
||||
assert details, (
|
||||
"no 'admin API key' detail literal left in dependencies.py — moved or "
|
||||
"reworded? Update frontend/src/api/client.ts in the same change."
|
||||
)
|
||||
sniff = _frontend_sniff()
|
||||
for detail in details:
|
||||
# Case-insensitive substring, mirroring apiFetch's toLowerCase match.
|
||||
assert sniff in detail.lower(), (
|
||||
f"backend detail {detail!r} no longer contains the frontend matcher "
|
||||
f"{sniff!r} — the SPA would stop routing it to the API-key gate. "
|
||||
"Update frontend/src/api/client.ts in the same change."
|
||||
)
|
||||
|
||||
|
||||
def test_frontend_sniff_rejects_details_a_key_cannot_fix():
|
||||
"""The sniff must not swallow 403s an API key cannot satisfy.
|
||||
|
||||
The desktop admin-gate arm (loopback-only regardless of credentials), the
|
||||
legacy require_loopback desktop 403, the CSRF rejection, and the
|
||||
desktop-only filesystem gate: routing any of these to the login form would
|
||||
trap the user in a form that can never succeed.
|
||||
"""
|
||||
sniff = _frontend_sniff()
|
||||
unfixable = (
|
||||
"loopback origin required", # desktop admin arm + require_loopback
|
||||
"browser origin rejected", # BearerKeyMiddleware CSRF (main.py)
|
||||
"desktop origin required", # require_desktop — loopback-only forever
|
||||
"native filesystem access requires loopback origin", # require_native
|
||||
)
|
||||
for detail in unfixable:
|
||||
assert sniff not in detail.lower(), (
|
||||
f"frontend matcher {sniff!r} now also matches {detail!r}, which "
|
||||
"an API key cannot satisfy — the login gate would loop."
|
||||
)
|
||||
@@ -52,6 +52,41 @@ def test_resolve_within_accepts_relative_and_existing_absolute_paths(tmp_path):
|
||||
assert resolve_within(root, item) == item
|
||||
|
||||
|
||||
def test_stored_subpaths_split_on_both_separator_families():
|
||||
"""The component split is host-independent.
|
||||
|
||||
Asserted on the splitter itself, not through ``resolve_within``: the
|
||||
Python suite runs on Linux only, where ``os.sep`` splitting already
|
||||
handled ``/``. A behavioural test would pass here whether or not the
|
||||
Windows path is fixed, so it would not guard the regression.
|
||||
"""
|
||||
from core.path_security import _PATH_SEPARATORS
|
||||
assert _PATH_SEPARATORS.split("sub/voice.wav") == ["sub", "voice.wav"]
|
||||
assert _PATH_SEPARATORS.split(r"sub\voice.wav") == ["sub", "voice.wav"]
|
||||
|
||||
|
||||
@pytest.mark.parametrize("stored_path", ["sub/voice.wav", r"sub\voice.wav"])
|
||||
def test_resolve_within_reads_a_stored_subpath(tmp_path, stored_path):
|
||||
"""A persisted sub-path resolves to the same file on Windows and POSIX.
|
||||
|
||||
Rows written on Windows, POSIX, or Docker must resolve identically after
|
||||
the same data directory is opened on another supported host.
|
||||
"""
|
||||
from core.path_security import resolve_within
|
||||
root = tmp_path / "root"
|
||||
(root / "sub").mkdir(parents=True)
|
||||
assert resolve_within(root, stored_path) == root / "sub" / "voice.wav"
|
||||
|
||||
|
||||
def test_resolve_within_rejects_traversal_through_either_separator(tmp_path):
|
||||
"""Splitting on both separators must not open a traversal path."""
|
||||
from core.path_security import UnsafePath, resolve_within
|
||||
root = tmp_path / "root"
|
||||
(root / "sub").mkdir(parents=True)
|
||||
with pytest.raises(UnsafePath):
|
||||
resolve_within(root, "sub/../../secret.wav")
|
||||
|
||||
|
||||
def test_resolve_within_rejects_parent_and_absolute_escape(tmp_path):
|
||||
from core.path_security import UnsafePath, resolve_within
|
||||
root = tmp_path / "root"
|
||||
@@ -76,7 +111,10 @@ def test_resolve_within_rejects_symlink_escape(tmp_path):
|
||||
(root / "link").symlink_to(outside, target_is_directory=True)
|
||||
except OSError:
|
||||
pytest.skip("symlink creation is unavailable on this host")
|
||||
with pytest.raises(UnsafePath):
|
||||
# Match the reason, not just the type: when ``/`` was not treated as a
|
||||
# separator on Windows this call failed at component validation instead,
|
||||
# so the containment check below it was never exercised there.
|
||||
with pytest.raises(UnsafePath, match="escapes its allowed root"):
|
||||
resolve_within(root, "link/secret.wav")
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,214 @@
|
||||
"""The FlashInfer opt-in (OMNIVOICE_FLASHINFER, upstream k2-fsa port).
|
||||
|
||||
An optimization must never be a point of failure (#278 contract, same as
|
||||
torch.compile): the env knob is CUDA-only, off by default, refuses with a
|
||||
named reason when the host can't honor it, latches off for the session after
|
||||
a runtime failure, and a mid-generation FlashInfer error unapplies the patch
|
||||
and retries the standard path once.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import pytest
|
||||
|
||||
torch = pytest.importorskip("torch")
|
||||
|
||||
|
||||
def _ee():
|
||||
import services.engine_env as m
|
||||
return m
|
||||
|
||||
|
||||
def _mm():
|
||||
import services.model_manager as m
|
||||
return m
|
||||
|
||||
|
||||
@pytest.fixture(autouse=True)
|
||||
def _reset_latch(monkeypatch):
|
||||
monkeypatch.setattr(_ee(), "_flashinfer_runtime_failure", None)
|
||||
monkeypatch.delenv("OMNIVOICE_FLASHINFER", raising=False)
|
||||
|
||||
|
||||
# ── the env knob ────────────────────────────────────────────────────────────
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"value,expected",
|
||||
[
|
||||
("", "off"), ("0", "off"), ("false", "off"), ("off", "off"),
|
||||
("1", "on"), ("true", "on"), ("ON", "on"),
|
||||
("graph", "graph"), ("GRAPH", "graph"),
|
||||
("banana", "off"), # typo → default path, not a crash
|
||||
],
|
||||
)
|
||||
def test_flashinfer_mode_parsing(monkeypatch, value, expected):
|
||||
if value:
|
||||
monkeypatch.setenv("OMNIVOICE_FLASHINFER", value)
|
||||
assert _ee().flashinfer_mode() == expected
|
||||
|
||||
|
||||
def test_should_flashinfer_refuses_non_cuda(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_FLASHINFER", "1")
|
||||
assert _ee().should_flashinfer("cpu") == "off"
|
||||
assert _ee().should_flashinfer("mps") == "off"
|
||||
|
||||
|
||||
def test_should_flashinfer_refuses_without_the_package(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_FLASHINFER", "1")
|
||||
ee = _ee()
|
||||
monkeypatch.setattr(ee.importlib.util, "find_spec", lambda name: None)
|
||||
assert ee.should_flashinfer("cuda") == "off"
|
||||
|
||||
|
||||
def test_latched_reason_is_sanitized(monkeypatch):
|
||||
# Wheel import errors embed the user's home path — the latch must store
|
||||
# the redacted form (core.failure.sanitize maps $HOME → "~").
|
||||
import os
|
||||
|
||||
home = os.path.expanduser("~")
|
||||
_ee().mark_flashinfer_runtime_failure(
|
||||
f"ImportError: {home}/.venv/lib/flashinfer/_kernels.so: bad ELF"
|
||||
)
|
||||
latched = _ee()._flashinfer_runtime_failure
|
||||
assert home not in latched
|
||||
assert "ImportError" in latched
|
||||
|
||||
|
||||
def test_sanitizer_failure_never_latches_the_raw_reason(monkeypatch):
|
||||
# Fail closed: a broken redactor must not leak the original message.
|
||||
import core.failure
|
||||
|
||||
def _boom(_):
|
||||
raise RuntimeError("sanitizer exploded (test)")
|
||||
|
||||
monkeypatch.setattr(core.failure, "sanitize", _boom)
|
||||
_ee().mark_flashinfer_runtime_failure(
|
||||
"ImportError: /home/someone/secret-project/creds.so missing"
|
||||
)
|
||||
latched = _ee()._flashinfer_runtime_failure
|
||||
assert "secret-project" not in latched and "/home/" not in latched
|
||||
assert latched.startswith("ImportError")
|
||||
assert "redacted" in latched
|
||||
|
||||
|
||||
def test_runtime_failure_latches_the_session_off(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_FLASHINFER", "graph")
|
||||
ee = _ee()
|
||||
monkeypatch.setattr(ee.importlib.util, "find_spec", lambda name: object())
|
||||
assert ee.should_flashinfer("cuda") == "graph"
|
||||
ee.mark_flashinfer_runtime_failure("boom")
|
||||
assert ee.should_flashinfer("cuda") == "off"
|
||||
|
||||
|
||||
# ── failure classification ──────────────────────────────────────────────────
|
||||
|
||||
|
||||
def test_classifier_matches_flashinfer_markers():
|
||||
mm = _mm()
|
||||
assert mm._is_flashinfer_runtime_failure(RuntimeError("flashinfer plan failed"))
|
||||
assert mm._is_flashinfer_runtime_failure(RuntimeError("CUDA graph capture aborted"))
|
||||
assert not mm._is_flashinfer_runtime_failure(ValueError("Unsupported instruct items"))
|
||||
assert not mm._is_flashinfer_runtime_failure(RuntimeError("CUDA out of memory"))
|
||||
|
||||
|
||||
def test_classifier_walks_the_cause_chain():
|
||||
mm = _mm()
|
||||
inner = RuntimeError("flashinfer workspace too small")
|
||||
outer = RuntimeError("generation failed")
|
||||
outer.__cause__ = inner
|
||||
assert mm._is_flashinfer_runtime_failure(outer)
|
||||
# `raise ... from None` severs the chain — a genuine error must not be
|
||||
# re-classified via a suppressed FlashInfer context.
|
||||
severed = RuntimeError("generation failed")
|
||||
severed.__context__ = inner
|
||||
severed.__suppress_context__ = True
|
||||
assert not mm._is_flashinfer_runtime_failure(severed)
|
||||
|
||||
|
||||
# ── unapply restores the class implementations ──────────────────────────────
|
||||
|
||||
|
||||
class _MiniModel:
|
||||
class _Llm(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.lin = torch.nn.Linear(2, 2)
|
||||
self.config = type("C", (), {"use_cache": False})()
|
||||
self.attn_impl = None
|
||||
|
||||
def set_attn_implementation(self, name):
|
||||
self.attn_impl = name
|
||||
|
||||
def __init__(self):
|
||||
self.llm = self._Llm()
|
||||
|
||||
def _generate_iterative(self, *a):
|
||||
return "class-impl"
|
||||
|
||||
|
||||
def test_unapply_flashinfer_restores_instance_state():
|
||||
from types import MethodType
|
||||
|
||||
m = _MiniModel()
|
||||
# Simulate apply_flashinfer's instance-level patching.
|
||||
m.llm.lin.forward = MethodType(lambda self, x: "patched", m.llm.lin)
|
||||
m.llm.lin._fi_w_qkv = torch.zeros(1)
|
||||
m._generate_iterative = MethodType(lambda self, *a: "patched", m)
|
||||
m._fi_runner = object()
|
||||
m._fi_graph_cache = {}
|
||||
m._fi_enable_cuda_graph = True
|
||||
|
||||
_mm()._unapply_flashinfer(m)
|
||||
|
||||
assert "forward" not in vars(m.llm.lin), "instance forward override must go"
|
||||
assert not hasattr(m.llm.lin, "_fi_w_qkv")
|
||||
assert m._generate_iterative() == "class-impl"
|
||||
assert not hasattr(m, "_fi_runner")
|
||||
assert m.llm.attn_impl == "sdpa"
|
||||
assert m.llm.config.use_cache is True
|
||||
|
||||
|
||||
def test_unapply_restores_the_captured_attention_impl():
|
||||
# The pre-apply impl may be flash_attention_2, not sdpa — unapply must
|
||||
# put back what was actually there (CodeRabbit/Greptile, #1565).
|
||||
m = _MiniModel()
|
||||
m._fi_orig_attn_impl = "flash_attention_2"
|
||||
_mm()._unapply_flashinfer(m)
|
||||
assert m.llm.attn_impl == "flash_attention_2"
|
||||
assert not hasattr(m, "_fi_orig_attn_impl")
|
||||
|
||||
|
||||
# ── generate-time fallback ──────────────────────────────────────────────────
|
||||
|
||||
|
||||
def test_generate_fallback_unapplies_and_retries_once():
|
||||
mm = _mm()
|
||||
calls = {"n": 0}
|
||||
|
||||
class _Model(_MiniModel):
|
||||
def generate(self, **kw):
|
||||
calls["n"] += 1
|
||||
if calls["n"] == 1:
|
||||
raise RuntimeError("flashinfer ragged attention failed")
|
||||
return ["ok"]
|
||||
|
||||
m = _Model()
|
||||
m._fi_runner = object()
|
||||
mm._install_flashinfer_fallback(m)
|
||||
assert m.generate() == ["ok"]
|
||||
assert calls["n"] == 2
|
||||
assert not hasattr(m, "_fi_runner"), "fallback must unapply the patch"
|
||||
assert _ee()._flashinfer_runtime_failure is not None
|
||||
|
||||
|
||||
def test_generate_fallback_leaves_real_errors_alone():
|
||||
mm = _mm()
|
||||
|
||||
class _Model(_MiniModel):
|
||||
def generate(self, **kw):
|
||||
raise ValueError("Unsupported instruct items")
|
||||
|
||||
m = _Model()
|
||||
mm._install_flashinfer_fallback(m)
|
||||
with pytest.raises(ValueError):
|
||||
m.generate()
|
||||
@@ -17,6 +17,7 @@ EXPECTED_EXACT_REGEXES = {
|
||||
"^hf_abcdefghijklmnopqrstuvwxyz0123456789ABCDEF$",
|
||||
"^hf_QWERTYUIOPasdfghjklZXCVBNM0123456789xyzAB$",
|
||||
"^max_length=400$",
|
||||
"^Ed25519PrivateKey$",
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -253,6 +253,89 @@ def test_side_effectful_get_rejects_remote_api_key_outside_server_mode(monkeypat
|
||||
assert exc.value.status_code == 403
|
||||
|
||||
|
||||
# Mode-distinct admin-gate detail: the 403 message must state what would
|
||||
# ACTUALLY satisfy the gate. The bundled UI routes any 403 whose detail
|
||||
# mentions "admin api key" to the API-key login form (frontend client.ts;
|
||||
# the literal contract is locked by tests/test_auth_gate_detail_lockstep.py).
|
||||
# Server mode accepts the key, so naming it is right. Desktop mode rejects
|
||||
# every non-loopback client regardless of credentials — the checks above only
|
||||
# run under server mode — so it must keep the plain loopback detail: naming
|
||||
# the key there invites a login form that can never succeed (a desktop
|
||||
# LAN-share guest would lose the whole consumption UI to it, #1213).
|
||||
|
||||
|
||||
def test_require_admin_desktop_detail_is_plain_loopback(monkeypatch):
|
||||
"""Desktop build: no presented key can satisfy the gate."""
|
||||
monkeypatch.delenv("OMNIVOICE_SERVER_MODE", raising=False)
|
||||
monkeypatch.setenv("OMNIVOICE_API_KEY", "s3cret") # a valid key can't help here
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin(
|
||||
_req_full("10.0.0.5", headers={"authorization": "Bearer s3cret"})
|
||||
)
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin required"
|
||||
|
||||
|
||||
def test_require_admin_server_mode_detail_names_the_key(monkeypatch):
|
||||
"""Server mode with an API key configured: the 403 names the key."""
|
||||
monkeypatch.setenv("OMNIVOICE_SERVER_MODE", "1")
|
||||
monkeypatch.setenv("OMNIVOICE_API_KEY", "s3cret")
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin(_req_full("172.17.0.1")) # credential configured, none presented
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin or admin API key required"
|
||||
|
||||
|
||||
def test_require_admin_pin_only_server_mode_detail_is_plain_loopback(monkeypatch):
|
||||
"""Server mode with ONLY a share PIN (Greptile P1, PR #1569): the PIN
|
||||
closes read-only bootstrap but no API key exists to present, so naming
|
||||
the key would send the browser to a login form that can never succeed.
|
||||
Only loopback can use admin here — the plain detail says so, and the
|
||||
SPA leaves it a plain error instead of gating the whole UI."""
|
||||
monkeypatch.setenv("OMNIVOICE_SERVER_MODE", "1")
|
||||
monkeypatch.delenv("OMNIVOICE_API_KEY", raising=False)
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin(_req_full("172.17.0.1", pin="424242")) # PIN ≠ admin credential
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin required"
|
||||
|
||||
|
||||
def test_require_admin_action_desktop_detail_is_plain_loopback(monkeypatch):
|
||||
"""Desktop build, side-effectful GET: plain loopback detail."""
|
||||
monkeypatch.delenv("OMNIVOICE_SERVER_MODE", raising=False)
|
||||
monkeypatch.setenv("OMNIVOICE_API_KEY", "s3cret")
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin_action(
|
||||
_req_full(
|
||||
"10.0.0.5",
|
||||
method="GET",
|
||||
headers={"authorization": "Bearer s3cret"},
|
||||
)
|
||||
)
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin required"
|
||||
|
||||
|
||||
def test_require_admin_action_server_mode_detail_names_the_key(monkeypatch):
|
||||
"""Server mode + key configured, side-effectful GET: names the key."""
|
||||
monkeypatch.setenv("OMNIVOICE_SERVER_MODE", "1")
|
||||
monkeypatch.setenv("OMNIVOICE_API_KEY", "s3cret")
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin_action(_req_full("172.17.0.1", method="GET"))
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin or admin API key required"
|
||||
|
||||
|
||||
def test_side_effectful_get_rejects_pin_and_trusted_network(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_SERVER_MODE", "1")
|
||||
monkeypatch.setenv("OMNIVOICE_TRUSTED_NETWORKS", "10.0.0.0/8")
|
||||
|
||||
@@ -50,6 +50,7 @@ _ALLOWED_FILES = {
|
||||
"README_CN.md", # Chinese README (a translation)
|
||||
"docs/data_preparation.md", # multilingual example payloads
|
||||
"docs/voice-design.md", # EN/CJK attribute mapping table
|
||||
"docs/engines/omnivoice.md", # pinyin pronunciation-control example (functional CJK)
|
||||
"docs/superpowers/specs/2026-05-31-voice-gallery-design.md", # Chinese-dialect taxonomy reference table
|
||||
"examples/README.md", # multilingual example payloads
|
||||
# Text-processing (CJK punctuation inside sentence/clause-splitting regexes)
|
||||
|
||||
@@ -0,0 +1,20 @@
|
||||
"""Packaged desktop builds must carry the SPA used by Network Sharing."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
from pathlib import Path
|
||||
|
||||
|
||||
ROOT = Path(__file__).resolve().parents[1]
|
||||
|
||||
|
||||
def test_desktop_bundle_carries_the_lan_frontend() -> None:
|
||||
"""The backend cannot serve LAN clients from Tauri's embedded WebView assets."""
|
||||
config = json.loads((ROOT / "frontend/src-tauri/tauri.conf.json").read_text())
|
||||
resources = config["bundle"]["resources"]
|
||||
|
||||
assert "../../frontend/dist" in resources, (
|
||||
"frontend/dist must be a filesystem bundle resource so the packaged "
|
||||
"Python backend can serve Network Sharing clients"
|
||||
)
|
||||
@@ -0,0 +1,223 @@
|
||||
"""Voice-clone prompts persist across restarts (upstream VoiceClonePrompt port).
|
||||
|
||||
The in-memory prompt cache (#427/#473) dies with the process, so the first
|
||||
generation of every session re-encoded each voice — and re-ran ASR when the
|
||||
profile had no stored transcript. Upstream k2-fsa added
|
||||
``VoiceClonePrompt.save()/.load()`` for exactly this; we port the format
|
||||
(version-tagged dict, ``torch.load(weights_only=True)``-safe) and put a disk
|
||||
layer under the memory LRU, keyed identically (ref path + mtime + ref_text +
|
||||
preprocess flag). Restart is simulated here by clearing the memory cache: a
|
||||
second lookup must come from disk, not a re-encode.
|
||||
|
||||
The layer is best-effort by contract: disabled (env), unwritable, or corrupt
|
||||
disk state must never fail a generation — worst case is the old re-encode.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import pytest
|
||||
|
||||
torch = pytest.importorskip("torch")
|
||||
|
||||
|
||||
def _tb():
|
||||
"""The *live* services.tts_backend (same rationale as
|
||||
test_clone_prompt_wiring._tb: other suites purge services.* modules)."""
|
||||
import services.tts_backend as m
|
||||
return m
|
||||
|
||||
|
||||
def _VoiceClonePrompt():
|
||||
"""Resolved at call time — a module-level binding could go stale when
|
||||
another suite purges omnivoice.* from sys.modules (CodeRabbit, #1565)."""
|
||||
from omnivoice.models.omnivoice import VoiceClonePrompt
|
||||
return VoiceClonePrompt
|
||||
|
||||
|
||||
def _prompt():
|
||||
return _VoiceClonePrompt()(
|
||||
ref_audio_tokens=torch.arange(24, dtype=torch.long).reshape(8, 3),
|
||||
ref_text="Nice to meet you.",
|
||||
ref_rms=0.123,
|
||||
)
|
||||
|
||||
|
||||
class _StubModel:
|
||||
def __init__(self):
|
||||
self.encodes = 0
|
||||
|
||||
def create_voice_clone_prompt(self, ref_audio, ref_text=None, preprocess_prompt=True):
|
||||
self.encodes += 1
|
||||
return _prompt()
|
||||
|
||||
|
||||
@pytest.fixture(autouse=True)
|
||||
def _isolated(tmp_path, monkeypatch):
|
||||
"""Point the disk layer at a per-test dir and start with empty caches."""
|
||||
monkeypatch.setattr("core.config.DATA_DIR", tmp_path / "data")
|
||||
monkeypatch.delenv("OMNIVOICE_PROMPT_DISK_CACHE", raising=False)
|
||||
_tb().clear_clone_prompt_cache()
|
||||
yield
|
||||
_tb().clear_clone_prompt_cache()
|
||||
|
||||
|
||||
@pytest.fixture()
|
||||
def ref_wav(tmp_path):
|
||||
p = tmp_path / "ref.wav"
|
||||
p.write_bytes(b"\x00" * 256)
|
||||
return str(p)
|
||||
|
||||
|
||||
def _disk_files(tmp_path):
|
||||
d = tmp_path / "data" / "prompt_cache"
|
||||
return sorted(d.glob("*.pt")) if d.is_dir() else []
|
||||
|
||||
|
||||
# ── the ported save/load format ─────────────────────────────────────────────
|
||||
|
||||
|
||||
def test_prompt_save_load_roundtrip(tmp_path):
|
||||
p = _prompt()
|
||||
path = str(tmp_path / "voice.pt")
|
||||
p.save(path)
|
||||
loaded = _VoiceClonePrompt().load(path)
|
||||
assert torch.equal(loaded.ref_audio_tokens, p.ref_audio_tokens)
|
||||
assert loaded.ref_text == p.ref_text
|
||||
assert loaded.ref_rms == pytest.approx(p.ref_rms)
|
||||
# The file must stay loadable under torch's safe default (weights_only=True
|
||||
# since 2.6) — a pickled dataclass would not be.
|
||||
raw = torch.load(path, weights_only=True)
|
||||
assert raw["format_version"] == 1
|
||||
|
||||
|
||||
def test_prompt_load_rejects_unknown_format_version(tmp_path):
|
||||
path = str(tmp_path / "future.pt")
|
||||
torch.save({"format_version": 999}, path)
|
||||
with pytest.raises(ValueError, match="format version"):
|
||||
_VoiceClonePrompt().load(path)
|
||||
|
||||
|
||||
def test_saved_tokens_are_cpu_even_from_dataclass_on_another_device(tmp_path):
|
||||
# save() must detach+CPU the tokens so the file is portable. On CUDA hosts
|
||||
# this exercises the real device move; CI (CPU-only) still verifies the
|
||||
# detach and that the persisted payload is CPU-resident.
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
p = _VoiceClonePrompt()(
|
||||
ref_audio_tokens=torch.zeros(8, 3, requires_grad=True).to(device),
|
||||
ref_text="x",
|
||||
ref_rms=0.5,
|
||||
)
|
||||
path = str(tmp_path / "v.pt")
|
||||
p.save(path)
|
||||
loaded = _VoiceClonePrompt().load(path)
|
||||
assert not loaded.ref_audio_tokens.requires_grad
|
||||
assert loaded.ref_audio_tokens.device.type == "cpu"
|
||||
# The device move must happen at SAVE time (portability of the file
|
||||
# itself), not merely at load: the raw payload carries CPU tensors.
|
||||
assert torch.load(path, weights_only=True)["ref_audio_tokens"].device.type == "cpu"
|
||||
|
||||
|
||||
# ── the disk layer under the memory cache ───────────────────────────────────
|
||||
|
||||
|
||||
def test_disk_hit_survives_restart(tmp_path, ref_wav):
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
|
||||
first = tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert model.encodes == 1
|
||||
assert len(_disk_files(tmp_path)) == 1
|
||||
|
||||
tb.clear_clone_prompt_cache() # "restart": memory gone, disk remains
|
||||
second = tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert model.encodes == 1, "restart re-encoded despite a persisted prompt"
|
||||
assert torch.equal(second.ref_audio_tokens, first.ref_audio_tokens)
|
||||
assert second.ref_text == first.ref_text
|
||||
|
||||
|
||||
def test_edited_reference_is_not_served_a_stale_prompt(tmp_path, ref_wav):
|
||||
import os
|
||||
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
tb.clear_clone_prompt_cache()
|
||||
|
||||
# Same path, new content+mtime → new key → the old file must not match.
|
||||
with open(ref_wav, "wb") as f:
|
||||
f.write(b"\x01" * 512)
|
||||
os.utime(ref_wav, (1, 1))
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert model.encodes == 2
|
||||
|
||||
|
||||
def test_single_use_refs_never_touch_disk(tmp_path, ref_wav):
|
||||
tb = _tb()
|
||||
tb._get_clone_prompt(_StubModel(), ref_wav, "hello", True, store=False)
|
||||
assert _disk_files(tmp_path) == [], (
|
||||
"store=False (dub per-segment clips) must not spray single-use "
|
||||
"prompts onto disk — same scan-resistance as the memory LRU"
|
||||
)
|
||||
|
||||
|
||||
def test_env_kill_switch_disables_the_layer(tmp_path, ref_wav, monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_PROMPT_DISK_CACHE", "0")
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert _disk_files(tmp_path) == []
|
||||
tb.clear_clone_prompt_cache()
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert model.encodes == 2 # no disk → honest re-encode
|
||||
|
||||
|
||||
def test_corrupt_disk_entry_is_dropped_and_reencoded(tmp_path, ref_wav):
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
tb.clear_clone_prompt_cache()
|
||||
|
||||
disk = _disk_files(tmp_path)
|
||||
assert len(disk) == 1
|
||||
disk[0].write_bytes(b"not a torch file")
|
||||
|
||||
prompt = tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert prompt is not None
|
||||
assert model.encodes == 2, "corrupt file must fall back to encoding"
|
||||
# ...and the corrupt file was removed, then replaced by the fresh save.
|
||||
fresh = _disk_files(tmp_path)
|
||||
assert len(fresh) == 1
|
||||
assert torch.load(str(fresh[0]), weights_only=True)["format_version"] == 1
|
||||
|
||||
|
||||
def test_prune_keeps_only_the_newest(tmp_path, monkeypatch):
|
||||
import os
|
||||
import time
|
||||
|
||||
tb = _tb()
|
||||
monkeypatch.setattr(tb, "_PROMPT_DISK_CACHE_MAX", 3)
|
||||
model = _StubModel()
|
||||
refs = []
|
||||
for i in range(5):
|
||||
p = tmp_path / f"ref{i}.wav"
|
||||
p.write_bytes(bytes([i]) * 64)
|
||||
os.utime(p, (i + 1, i + 1))
|
||||
refs.append(str(p))
|
||||
for i, r in enumerate(refs):
|
||||
tb._get_clone_prompt(model, r, f"text {i}", True)
|
||||
# mtime is the prune order; keep saves strictly ordered even on
|
||||
# filesystems with coarse timestamps.
|
||||
files = _disk_files(tmp_path)
|
||||
newest = max(files, key=lambda f: f.stat().st_mtime)
|
||||
os.utime(newest, (1000 + i, 1000 + i))
|
||||
assert len(_disk_files(tmp_path)) == 3
|
||||
|
||||
|
||||
def test_unwritable_cache_dir_never_breaks_prompt_building(ref_wav, monkeypatch):
|
||||
# Simulate an unwritable data dir: the layer must vanish, not raise.
|
||||
monkeypatch.setattr(
|
||||
"core.config.DATA_DIR", "/proc/omnivoice-definitely-not-writable"
|
||||
)
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
assert tb._get_clone_prompt(model, ref_wav, "hello", True) is not None
|
||||
assert model.encodes == 1
|
||||
@@ -21,7 +21,9 @@ tests/test_synthetic_audio_watermark_1169.py.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import io
|
||||
import re
|
||||
import tokenize
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
@@ -75,6 +77,46 @@ _PRODUCERS = [
|
||||
]
|
||||
|
||||
|
||||
def _code_only(src: str) -> str:
|
||||
"""``src`` with comments and string literals blanked to spaces.
|
||||
|
||||
ee35d238 made a module a "producer" by *mentioning* ``backend.generate()``
|
||||
in a comment — prose can't synthesize audio. Only real call sites may
|
||||
match ``_SYNTH_CALL``, so blank every COMMENT/STRING token span (spaces,
|
||||
not deletion, to keep the layout the regexes were written against).
|
||||
Unparseable source falls back to the raw text — fail closed, a module we
|
||||
can't tokenize still gets scanned.
|
||||
|
||||
f-strings stay conservative (Greptile P1 on #1564): on Python ≤3.11 the
|
||||
whole f-string — replacement expressions included — is ONE STRING token,
|
||||
so blanking it would let ``f"{backend.generate(t)}"`` evade the guard.
|
||||
f-prefixed strings are therefore kept raw there (a literal f-string
|
||||
*mentioning* a primitive false-positives toward the allowlist — fail
|
||||
closed). On 3.12+ (PEP 701) replacement code arrives as ordinary tokens
|
||||
and only the literal FSTRING_MIDDLE text is blanked.
|
||||
"""
|
||||
fstring_middle = getattr(tokenize, "FSTRING_MIDDLE", None)
|
||||
lines = src.splitlines(keepends=True)
|
||||
try:
|
||||
tokens = list(tokenize.generate_tokens(io.StringIO(src).readline))
|
||||
except (tokenize.TokenError, IndentationError, SyntaxError):
|
||||
return src
|
||||
for tok in tokens:
|
||||
if tok.type == tokenize.STRING:
|
||||
prefix = tok.string.split(tok.string[-1], 1)[0].rstrip("\"'")
|
||||
if "f" in prefix.lower():
|
||||
continue # pre-3.12 f-string: may contain executable code
|
||||
elif tok.type not in (tokenize.COMMENT, fstring_middle):
|
||||
continue
|
||||
(srow, scol), (erow, ecol) = tok.start, tok.end
|
||||
for row in range(srow - 1, erow):
|
||||
line = lines[row]
|
||||
lo = scol if row == srow - 1 else 0
|
||||
hi = ecol if row == erow - 1 else len(line.rstrip("\r\n"))
|
||||
lines[row] = line[:lo] + " " * (hi - lo) + line[hi:]
|
||||
return "".join(lines)
|
||||
|
||||
|
||||
def _py_files():
|
||||
for sub in ("api", "services", "worker"):
|
||||
for p in sorted((_BACKEND / sub).rglob("*.py")):
|
||||
@@ -84,9 +126,11 @@ def _py_files():
|
||||
def test_every_synthesis_module_routes_through_mark_synthetic():
|
||||
offenders = []
|
||||
for rel, src in _py_files():
|
||||
if not _SYNTH_CALL.search(src):
|
||||
if not _SYNTH_CALL.search(_code_only(src)):
|
||||
continue
|
||||
if rel in _ALLOWED or "mark_synthetic" in src:
|
||||
# The satisfying reference must be code too — a comment saying
|
||||
# "mark_synthetic" must not certify a module (CodeRabbit, #1564).
|
||||
if rel in _ALLOWED or "mark_synthetic" in _code_only(src):
|
||||
continue
|
||||
offenders.append(rel)
|
||||
assert not offenders, (
|
||||
@@ -100,7 +144,7 @@ def test_every_synthesis_module_routes_through_mark_synthetic():
|
||||
@pytest.mark.parametrize("rel", _PRODUCERS)
|
||||
def test_known_producer_still_marks(rel):
|
||||
src = (_BACKEND / rel).read_text(encoding="utf-8")
|
||||
assert "mark_synthetic" in src, (
|
||||
assert "mark_synthetic" in _code_only(src), (
|
||||
f"{rel} lost its mark_synthetic call — its synthetic audio would ship "
|
||||
"without the Art. 50(2) provenance mark (#1169)."
|
||||
)
|
||||
@@ -127,12 +171,34 @@ def test_allowlist_is_not_stale():
|
||||
p = _BACKEND / rel
|
||||
assert p.is_file(), f"watermark-coverage list names a missing file: {rel}"
|
||||
for rel in _ALLOWED:
|
||||
assert _SYNTH_CALL.search((_BACKEND / rel).read_text(encoding="utf-8")), (
|
||||
assert _SYNTH_CALL.search(_code_only((_BACKEND / rel).read_text(encoding="utf-8"))), (
|
||||
f"{rel} no longer matches a synthesis primitive — remove it from "
|
||||
"tests/test_watermark_route_coverage.py so the guard stays sharp."
|
||||
)
|
||||
|
||||
|
||||
def test_prose_mentions_are_not_producers():
|
||||
"""The ee35d238 regression: a comment (or log string / docstring) naming a
|
||||
synthesis primitive must not make a module a producer — only a call can."""
|
||||
prose = (
|
||||
"# A generic backend.generate() call accepts the same wire shape\n"
|
||||
'MSG = "route through generate_with_cached_ref(model) instead"\n'
|
||||
"def f():\n"
|
||||
' """Docs may mention _run_inference( freely."""\n'
|
||||
" return 1\n"
|
||||
)
|
||||
assert not _SYNTH_CALL.search(_code_only(prose))
|
||||
real = "def f(backend):\n return backend.generate(text='hi')\n"
|
||||
assert _SYNTH_CALL.search(_code_only(real))
|
||||
# Greptile P1: a call inside an f-string replacement field is code and
|
||||
# must still be caught, on every supported Python (≤3.11 tokenizes the
|
||||
# whole f-string as one STRING; 3.12+ splits out the expression tokens).
|
||||
fstring_call = 'def f(backend):\n return f"{backend.generate(text=\'hi\')}"\n'
|
||||
assert _SYNTH_CALL.search(_code_only(fstring_call))
|
||||
# ...and a comment claiming mark_synthetic must not certify a producer.
|
||||
assert "mark_synthetic" not in _code_only("# routes via mark_synthetic\nx = 1\n")
|
||||
|
||||
|
||||
# ── mark_synthetic unit contract (delegation, not new policy) ────────────────
|
||||
|
||||
|
||||
|
||||
Reference in New Issue
Block a user