Compare commits
26
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 debpalash |
2d7df6a75c | ||
|
debpalash
|
a2577e46ea | ||
|
debpalash
|
eed841a8ca | ||
|
debpalash
|
df4d016a7d | ||
|
Palash Debnath
|
ca7fb9c68d | ||
|
debpalash
|
fd6d21401b | ||
|
debpalash
|
c9adcb2647 | ||
|
debpalash
|
51163cf260 | ||
|
Palash Debnath
|
4ce4f05c06 | ||
|
debpalash
|
e77feae817 | ||
|
debpalash
|
fdc02b398e | ||
|
Palash Debnath
|
6e1bb44e0d | ||
|
Palash Debnath
|
4dc90a7f4f | ||
|
debpalash
|
3b64d317ae | ||
|
debpalash
|
ee7202b1eb | ||
|
Paolo Antinori
|
871d68a6ff | ||
|
Palash Debnath
|
b37466b2e5 | ||
|
Palash DebnathandClaude Fable 5
|
2d5f2e800e | ||
|
Palash DebnathandClaude Fable 5
|
4db02d0c97 | ||
|
velixio
|
ee35d2389e | ||
|
velixio
|
1fda5bdf96 | ||
|
Palash Debnath
|
2477dde688 | ||
|
Palash DebnathandClaude Fable 5
|
48c9a3b1f8 | ||
|
Palash DebnathandClaude Fable 5
|
030d5ea01f | ||
|
Palash DebnathandClaude Fable 5
|
b79ba9bd3b | ||
|
Eman-Yousaf
|
579f2e0a2e |
@@ -0,0 +1,60 @@
|
||||
---
|
||||
name: fastapi-python
|
||||
description: Expert in FastAPI Python development with best practices for APIs and async operations
|
||||
---
|
||||
|
||||
# FastAPI Python
|
||||
|
||||
You are an expert in FastAPI and Python backend development.
|
||||
|
||||
## Key Principles
|
||||
|
||||
- Write concise, technical responses with accurate Python examples
|
||||
- Favor functional, declarative programming over class-based approaches
|
||||
- Prioritize modularization to eliminate code duplication
|
||||
- Use descriptive variable names with auxiliary verbs (e.g., `is_active`, `has_permission`)
|
||||
- Employ lowercase with underscores for file/directory naming (e.g., `routers/user_routes.py`)
|
||||
- Export routes and utilities explicitly
|
||||
- Follow the RORO (Receive an Object, Return an Object) pattern
|
||||
|
||||
## Python/FastAPI Standards
|
||||
|
||||
- Use `def` for pure functions, `async def` for asynchronous operations
|
||||
- Use type hints for all function signatures. Prefer Pydantic models over raw dictionaries
|
||||
- Structure: exported router, sub-routes, utilities, static content, types (models, schemas)
|
||||
- Use ordinary Python control flow; prefer readability over compressed one-line conditionals
|
||||
|
||||
## Error Handling
|
||||
|
||||
- Handle edge cases at function entry points
|
||||
- Employ early returns for error conditions
|
||||
- Place happy path logic last
|
||||
- Avoid unnecessary else statements; use if-return patterns
|
||||
- Implement guard clauses for preconditions
|
||||
- Provide proper error logging and user-friendly messaging
|
||||
|
||||
## FastAPI-Specific Guidelines
|
||||
|
||||
- Use functional components (plain functions) and Pydantic models for input validation
|
||||
- Declare routes with clear return type annotations
|
||||
- Prefer lifespan context managers for managing startup and shutdown events
|
||||
- Leverage middleware for logging, error monitoring, and optimization
|
||||
- Use HTTPException for expected errors and model them as specific HTTP responses
|
||||
- Apply Pydantic's BaseModel consistently for validation
|
||||
|
||||
## Performance Optimization
|
||||
|
||||
- Minimize blocking I/O. In `async def` handlers, use awaitable database/API clients; put synchronous SQLite or other blocking work in synchronous routes or explicitly offload it
|
||||
- Implement caching with Redis or in-memory stores
|
||||
- Optimize Pydantic serialization/deserialization
|
||||
- Use lazy loading for large datasets
|
||||
|
||||
## Key Conventions
|
||||
|
||||
1. Rely on FastAPI's dependency injection system
|
||||
2. Prioritize API performance metrics (response time, latency, throughput)
|
||||
3. Structure routes and dependencies for readability and maintainability
|
||||
|
||||
## Dependencies
|
||||
|
||||
FastAPI, Pydantic v2, asyncpg/aiomysql, SQLAlchemy 2.0
|
||||
@@ -0,0 +1,357 @@
|
||||
---
|
||||
name: vite
|
||||
description: Expert guidance for Vite development with modern build tooling, HMR, framework integrations, and performance optimization
|
||||
---
|
||||
|
||||
# Vite Development
|
||||
|
||||
You are an expert in Vite, modern JavaScript/TypeScript build tooling, and frontend development.
|
||||
|
||||
## Key Principles
|
||||
|
||||
- Leverage native ES modules for fast development
|
||||
- Use Vite's opinionated defaults when possible
|
||||
- Configure only what needs customization
|
||||
- Understand the dev/build differences
|
||||
- Optimize for both development speed and production performance
|
||||
|
||||
## Project Setup
|
||||
|
||||
### Basic Configuration
|
||||
```typescript
|
||||
// vite.config.ts
|
||||
import { defineConfig } from 'vite';
|
||||
import react from '@vitejs/plugin-react';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [react()],
|
||||
server: {
|
||||
port: 3000,
|
||||
open: true,
|
||||
},
|
||||
build: {
|
||||
outDir: 'dist',
|
||||
sourcemap: true,
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
### Path Aliases
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
|
||||
export default defineConfig({
|
||||
resolve: {
|
||||
alias: {
|
||||
'@': new URL('./src', import.meta.url).pathname,
|
||||
'@components': new URL('./src/components', import.meta.url).pathname,
|
||||
'@utils': new URL('./src/utils', import.meta.url).pathname,
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Environment Variables
|
||||
|
||||
### Usage
|
||||
```typescript
|
||||
// .env
|
||||
VITE_API_URL=https://api.example.com
|
||||
VITE_APP_TITLE=My App
|
||||
|
||||
// In code
|
||||
const apiUrl = import.meta.env.VITE_API_URL;
|
||||
const isDev = import.meta.env.DEV;
|
||||
const isProd = import.meta.env.PROD;
|
||||
const mode = import.meta.env.MODE;
|
||||
```
|
||||
|
||||
### Type Definitions
|
||||
```typescript
|
||||
// src/vite-env.d.ts
|
||||
/// <reference types="vite/client" />
|
||||
|
||||
interface ImportMetaEnv {
|
||||
readonly VITE_API_URL: string;
|
||||
readonly VITE_APP_TITLE: string;
|
||||
}
|
||||
|
||||
interface ImportMeta {
|
||||
readonly env: ImportMetaEnv;
|
||||
}
|
||||
```
|
||||
|
||||
## Hot Module Replacement
|
||||
|
||||
### Manual HMR
|
||||
```typescript
|
||||
// For libraries without HMR support
|
||||
if (import.meta.hot) {
|
||||
import.meta.hot.accept('./module.ts', (newModule) => {
|
||||
// Handle the updated module
|
||||
console.log('Module updated:', newModule);
|
||||
});
|
||||
|
||||
import.meta.hot.dispose(() => {
|
||||
// Cleanup before module is replaced
|
||||
});
|
||||
}
|
||||
```
|
||||
|
||||
## Asset Handling
|
||||
|
||||
### Static Assets
|
||||
```typescript
|
||||
// Import as URL
|
||||
import imageUrl from './image.png';
|
||||
// <img src={imageUrl} />
|
||||
|
||||
// Import as string (raw)
|
||||
import shaderCode from './shader.glsl?raw';
|
||||
|
||||
// Import as worker
|
||||
import Worker from './worker.ts?worker';
|
||||
const worker = new Worker();
|
||||
```
|
||||
|
||||
### Public Directory
|
||||
```
|
||||
public/
|
||||
├── favicon.ico # Served at /favicon.ico
|
||||
├── robots.txt # Served at /robots.txt
|
||||
└── images/ # Served at /images/
|
||||
```
|
||||
|
||||
## Framework Integrations
|
||||
|
||||
### React
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
import react from '@vitejs/plugin-react';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [
|
||||
react({
|
||||
// Babel plugins
|
||||
babel: {
|
||||
plugins: ['@emotion/babel-plugin'],
|
||||
},
|
||||
}),
|
||||
],
|
||||
});
|
||||
```
|
||||
|
||||
### Vue
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
import vue from '@vitejs/plugin-vue';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [vue()],
|
||||
});
|
||||
```
|
||||
|
||||
### Svelte
|
||||
```typescript
|
||||
import { defineConfig } from 'vite';
|
||||
import { svelte } from '@sveltejs/vite-plugin-svelte';
|
||||
|
||||
export default defineConfig({
|
||||
plugins: [svelte()],
|
||||
});
|
||||
```
|
||||
|
||||
## Build Optimization
|
||||
|
||||
### Code Splitting
|
||||
```typescript
|
||||
// Dynamic imports create separate chunks
|
||||
const AdminPanel = lazy(() => import('./AdminPanel'));
|
||||
|
||||
// Manual chunks
|
||||
export default defineConfig({
|
||||
build: {
|
||||
rollupOptions: {
|
||||
output: {
|
||||
manualChunks: {
|
||||
vendor: ['react', 'react-dom'],
|
||||
utils: ['lodash', 'date-fns'],
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
### Chunk Size Optimization
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
build: {
|
||||
chunkSizeWarningLimit: 500,
|
||||
rollupOptions: {
|
||||
output: {
|
||||
manualChunks(id) {
|
||||
if (id.includes('node_modules')) {
|
||||
return id.split('node_modules/')[1].split('/')[0];
|
||||
}
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## CSS Handling
|
||||
|
||||
### CSS Modules
|
||||
```typescript
|
||||
// styles.module.css is auto-detected
|
||||
import styles from './styles.module.css';
|
||||
|
||||
// <div className={styles.container}>
|
||||
```
|
||||
|
||||
### PostCSS
|
||||
```javascript
|
||||
// postcss.config.js
|
||||
export default {
|
||||
plugins: {
|
||||
tailwindcss: {},
|
||||
autoprefixer: {},
|
||||
},
|
||||
};
|
||||
```
|
||||
|
||||
### Preprocessors
|
||||
```typescript
|
||||
// Automatically handled with package installed
|
||||
// npm install -D sass
|
||||
import './styles.scss';
|
||||
```
|
||||
|
||||
## Proxy Configuration
|
||||
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
server: {
|
||||
proxy: {
|
||||
'/api': {
|
||||
target: 'http://localhost:4000',
|
||||
changeOrigin: true,
|
||||
rewrite: (path) => path.replace(/^\/api/, ''),
|
||||
},
|
||||
'/socket.io': {
|
||||
target: 'ws://localhost:4000',
|
||||
ws: true,
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Plugin Development
|
||||
|
||||
```typescript
|
||||
// my-vite-plugin.ts
|
||||
import type { Plugin } from 'vite';
|
||||
|
||||
export function myPlugin(): Plugin {
|
||||
return {
|
||||
name: 'my-plugin',
|
||||
|
||||
// Hook: modify config
|
||||
config(config, { mode }) {
|
||||
return {
|
||||
define: {
|
||||
__BUILD_TIME__: JSON.stringify(new Date().toISOString()),
|
||||
},
|
||||
};
|
||||
},
|
||||
|
||||
// Hook: transform code
|
||||
transform(code, id) {
|
||||
if (id.endsWith('.md')) {
|
||||
return {
|
||||
code: `export default ${JSON.stringify(code)}`,
|
||||
map: null,
|
||||
};
|
||||
}
|
||||
},
|
||||
|
||||
// Hook: configure dev server
|
||||
configureServer(server) {
|
||||
server.middlewares.use((req, res, next) => {
|
||||
// Custom middleware
|
||||
next();
|
||||
});
|
||||
},
|
||||
};
|
||||
}
|
||||
```
|
||||
|
||||
## Testing with Vitest
|
||||
|
||||
```typescript
|
||||
// vitest.config.ts
|
||||
import { defineConfig } from 'vitest/config';
|
||||
|
||||
export default defineConfig({
|
||||
test: {
|
||||
globals: true,
|
||||
environment: 'jsdom',
|
||||
setupFiles: './src/test/setup.ts',
|
||||
coverage: {
|
||||
provider: 'v8',
|
||||
reporter: ['text', 'json', 'html'],
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## SSR Configuration
|
||||
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
build: {
|
||||
ssr: true,
|
||||
rollupOptions: {
|
||||
input: './src/entry-server.ts',
|
||||
},
|
||||
},
|
||||
ssr: {
|
||||
external: ['express'],
|
||||
noExternal: ['my-ui-library'],
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Library Mode
|
||||
|
||||
```typescript
|
||||
export default defineConfig({
|
||||
build: {
|
||||
lib: {
|
||||
entry: './src/index.ts',
|
||||
name: 'MyLib',
|
||||
fileName: (format) => `my-lib.${format}.js`,
|
||||
},
|
||||
rollupOptions: {
|
||||
external: ['react', 'react-dom'],
|
||||
output: {
|
||||
globals: {
|
||||
react: 'React',
|
||||
'react-dom': 'ReactDOM',
|
||||
},
|
||||
},
|
||||
},
|
||||
},
|
||||
});
|
||||
```
|
||||
|
||||
## Best Practices
|
||||
|
||||
- Use `vite preview` to test production builds locally
|
||||
- Keep dependencies that support ESM in regular deps
|
||||
- Use `optimizeDeps.include` for CommonJS dependencies
|
||||
- Enable `build.sourcemap` for debugging production
|
||||
- Use `server.warmup` for faster dev server starts
|
||||
@@ -25,4 +25,6 @@ regexes = [
|
||||
'''^hf_QWERTYUIOPasdfghjklZXCVBNM0123456789xyzAB$''',
|
||||
# NLLB generation length argument, not the value of a credential.
|
||||
'''^max_length=400$''',
|
||||
# cryptography's Ed25519 private-key type name, not key material.
|
||||
'''^Ed25519PrivateKey$''',
|
||||
]
|
||||
|
||||
@@ -35,6 +35,10 @@ Binding for every AI agent (Claude, Codex, Cursor, review bots, …). CLAUDE.md
|
||||
|
||||
## Agent skills
|
||||
|
||||
Project development skills are pinned in `skills-lock.json` and installed under
|
||||
`.agents/skills/`: Vite and FastAPI.
|
||||
Repository rules and tracker mappings override generic skill guidance.
|
||||
|
||||
### Issue tracker
|
||||
|
||||
GitHub Issues on `debpalash/VoiceStudio`, via the `gh` CLI. See `docs/agents/issue-tracker.md`.
|
||||
|
||||
@@ -18,12 +18,30 @@ the frozen-backend fallback mirror it for their toolchains.
|
||||
- The backend binds its port immediately and reports startup progress live — `/health` answers 503-with-step and a new `/startup/progress` endpoint lists every step while PyTorch, API routes, and database migrations load in the background, so "starting at step X" is never mistakable for "dead"; the desktop splash narrates each step (#1550)
|
||||
|
||||
### Added
|
||||
- Voices you've cloned stay "warm" across restarts — encoded references now persist to disk (~10 KB each), so the first generation of a session skips the re-encode and any transcription pass; `OMNIVOICE_PROMPT_DISK_CACHE=0` opts out (#1565)
|
||||
- Optional FlashInfer acceleration for the default engine on CUDA (`OMNIVOICE_FLASHINFER=1`, ~2.2x measured) — needs the optional `flashinfer-python` package; missing package or kernel failure logs why and falls back to the standard path (#1565)
|
||||
- The bug reporter notices when you're on an outdated build and offers the latest release before filing — with a "File anyway" escape hatch — and stamps a `Build status` line into every report so up-to-date reports are tellable from stale ones (#1547)
|
||||
- Settings → Performance & Device gains a compute-device override (Auto / CUDA / ROCm / XPU / MPS / CPU, or `OMNIVOICE_DEVICE`) — pin the device when auto-detect picks wrong; only devices your machine actually has are offered (#1557)
|
||||
|
||||
### Docs
|
||||
- The Docker Hub overview now shows the current engine-switching demo, Model Catalogue, and gallery voice workflow (#1593)
|
||||
- The Docker Hub overview and install guide now show the v0.5 tags and the built-in API-key/share-PIN security model instead of obsolete v0.4 and no-authentication guidance (#1592)
|
||||
- The READMEs now lead with download buttons and a three-step first-clone walkthrough, and a new benchmarks page anchors measured per-engine/per-device numbers on the in-repo harness (#1555)
|
||||
- Every engine now has its own guide — 21 new pages under docs/engines plus an index covering all 16 TTS and 11 ASR engines, linked from both READMEs (#1556)
|
||||
- The OmniVoice guide now covers combining style attributes with a reference clip (consistent instruct stabilizes cloning; the reference wins conflicts), inline pronunciation control (pinyin / CMU phonemes), and corrects the claim that the default engine can't do voice design — it can, from attributes (#1565)
|
||||
|
||||
### Fixed
|
||||
- Network Sharing from Windows MSI/portable installs now serves the bundled web interface to LAN devices instead of redirecting them to their own `localhost` (#1589) — thanks @TWIISTED-STUDIOS!
|
||||
- Stored artifact subpaths now resolve after moving a data directory between Windows, macOS, Linux, and Docker, while traversal and symlink escapes remain blocked (#1559) — thanks @Eman-Yousaf!
|
||||
- A remote browser hitting an API-key-configured server's admin 403 now gets the API-key login form instead of endless console 403s, while desktop and PIN-only/no-key servers keep the plain loopback error so guests are never offered a login no key can satisfy (#1568) — thanks @paoloantinori!
|
||||
- The crash-isolated ASR sidecar and its download preflight now agree on which model to load — setting the shared faster-whisper model variable applies to both variants instead of the sidecar quietly using a different one (#1556)
|
||||
- "Ready" now requires the deep health probe (a working database-backed route), not just the identity probe — a backend whose install broke underneath can no longer be announced up while every real request fails (#1548)
|
||||
- Supervisor restarts after repeat crashes now back off (immediate, then 5s, then 15s) instead of respawning back-to-back, so a tight crash loop can't burn the whole restart budget in seconds (#1548)
|
||||
|
||||
### CI
|
||||
- Project agents now share pinned Vite and FastAPI skills from skills.sh (#1594)
|
||||
- Weekly full-history secret scans no longer mistake the Ed25519 private-key type name for committed key material (#1591)
|
||||
|
||||
## [0.5.0] — 2026-08-13
|
||||
|
||||
**Highlights**
|
||||
|
||||
@@ -66,7 +66,10 @@ Architecture not yet mapped. Follow existing patterns found in the codebase.
|
||||
<!-- GSD:skills-start source:skills/ -->
|
||||
## Project Skills
|
||||
|
||||
No project skills found. Add skills to any of: `.claude/skills/`, `.agents/skills/`, `.cursor/skills/`, `.github/skills/`, or `.codex/skills/` with a `SKILL.md` index file.
|
||||
- `vite` — Vite configuration, assets, HMR, builds, and Vitest guidance.
|
||||
- `fastapi-python` — FastAPI and Pydantic implementation patterns.
|
||||
|
||||
Canonical copies live under `.agents/skills/`; `skills-lock.json` pins their sources and hashes. Claude should follow these paths directly, avoiding cross-platform symlinks.
|
||||
<!-- GSD:skills-end -->
|
||||
|
||||
<!-- GSD:workflow-start source:GSD defaults -->
|
||||
|
||||
@@ -1,551 +1,385 @@
|
||||
<div align="center">
|
||||
<img src="docs/logo.png" alt="VoiceStudio Logo" width="120" height="120" />
|
||||
<img src="docs/logo.png" alt="VoiceStudio logo" width="120" height="120" />
|
||||
<h1>VoiceStudio</h1>
|
||||
<p><sub><em>previously OmniVoice-Studio</em></sub></p>
|
||||
<h3>Make voices. Tell stories. Keep the files. ♡</h3>
|
||||
<p>Clone, design, dub, dictate, and build audiobooks in one open-source desktop studio.<br/><b>Local-first by default.</b> No subscription or usage meter. Optional online services stay opt-in.</p>
|
||||
<p><sub>Previously OmniVoice-Studio</sub></p>
|
||||
<h3>Local voice cloning, dubbing, dictation, and long-form audio.</h3>
|
||||
<p>16 TTS engines · 11 ASR engines · 646-language catalogue · macOS, Windows, and Linux</p>
|
||||
<p><strong>Local-first.</strong> No account, API key, subscription, or usage meter for the core workflow.</p>
|
||||
|
||||
<p>
|
||||
<a href="#quickstart">Quickstart</a> ·
|
||||
<a href="#install">Install</a> ·
|
||||
<a href="#features">Features</a> ·
|
||||
<a href="#why-voicestudio">Why VoiceStudio</a> ·
|
||||
<a href="#tts-engines">Engines</a> ·
|
||||
<a href="#openai-api">API</a> ·
|
||||
<a href="#sponsor--donate">Donate</a> ·
|
||||
<a href="#contributing">Contributing</a> ·
|
||||
<a href="https://voicestudio.sh">Website</a> ·
|
||||
<a href="https://voicestudio.sh/docs">Docs</a> ·
|
||||
<a href="https://status.voicestudio.sh">Status</a> ·
|
||||
<a href="https://discord.gg/bzQavDfVV9">Discord</a> ·
|
||||
<a href="https://x.com/idebpalash">X</a> ·
|
||||
<a href="#comparison">Compare</a> ·
|
||||
<a href="#requirements">Requirements</a> ·
|
||||
<a href="#engines">Engines</a> ·
|
||||
<a href="#architecture">Architecture</a> ·
|
||||
<a href="#api">API</a> ·
|
||||
<a href="#documentation">Docs</a> ·
|
||||
<a href="README_CN.md"><strong>简体中文</strong></a>
|
||||
</p>
|
||||
|
||||
<p>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/stargazers"><img src="https://img.shields.io/github/stars/debpalash/VoiceStudio?style=flat-square&color=f59e0b" alt="Stars" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/stargazers"><img src="https://img.shields.io/github/stars/debpalash/VoiceStudio?style=flat-square&color=f59e0b" alt="GitHub stars" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases"><img src="https://img.shields.io/github/downloads/debpalash/VoiceStudio/total?style=flat-square&color=8b5cf6&label=downloads" alt="Total downloads" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/github/v/release/debpalash/VoiceStudio?style=flat-square&color=10b981" alt="Release" /></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/license-AGPL--3.0-blue?style=flat-square" alt="License" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/issues"><img src="https://img.shields.io/github/issues/debpalash/VoiceStudio?style=flat-square&color=ef4444" alt="Issues" /></a>
|
||||
<a href="https://discord.gg/bzQavDfVV9"><img src="https://img.shields.io/badge/Discord-Join_Community-5865F2?style=flat-square&logo=discord&logoColor=white" alt="Discord" /></a>
|
||||
<a href="https://x.com/idebpalash"><img src="https://img.shields.io/badge/X-Follow_for_updates-000000?style=flat-square&logo=x&logoColor=white" alt="Follow on X" /></a>
|
||||
<a href="https://ko-fi.com/debpalash"><img src="https://img.shields.io/badge/Ko--fi-Support_Us-FF5E5B?style=flat-square&logo=ko-fi&logoColor=white" alt="Ko-fi" /></a>
|
||||
<a href="https://paypal.me/palashCoder"><img src="https://img.shields.io/badge/PayPal-Donate-00457C?style=flat-square&logo=paypal&logoColor=white" alt="PayPal" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/github/v/release/debpalash/VoiceStudio?style=flat-square&color=10b981" alt="Latest release" /></a>
|
||||
<a href="LICENSE"><img src="https://img.shields.io/badge/license-AGPL--3.0-blue?style=flat-square" alt="AGPL-3.0 license" /></a>
|
||||
<a href="https://discord.gg/bzQavDfVV9"><img src="https://img.shields.io/badge/Discord-Community-5865F2?style=flat-square&logo=discord&logoColor=white" alt="Discord community" /></a>
|
||||
</p>
|
||||
|
||||
<p>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/⬇_Download-macOS_·_Windows_·_Linux-10b981?style=for-the-badge" alt="Download the latest release" /></a>
|
||||
</p>
|
||||
|
||||
<p>
|
||||
<a href="https://trendshift.io/repositories/28176?utm_source=trendshift-badge&utm_medium=badge&utm_campaign=badge-trendshift-28176" target="_blank" rel="noopener noreferrer"><img src="https://trendshift.io/api/badge/trendshift/repositories/28176/daily?language=Python" alt="debpalash%2FVoiceStudio | Trendshift" width="250" height="55"/></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Download-macOS_·_Windows_·_Linux-10b981?style=for-the-badge" alt="Download VoiceStudio" /></a>
|
||||
</p>
|
||||
</div>
|
||||
|
||||
<br/>
|
||||
|
||||
<div align="center">
|
||||
<img src="docs/screenshot-launchpad.png" alt="VoiceStudio — Launchpad" width="100%"/>
|
||||
<img src="docs/media/0.5.0/quick-switch.gif" alt="Switching TTS engines from the VoiceStudio status bar" width="100%" />
|
||||
</div>
|
||||
|
||||
> **Your voice is personal. Your studio should feel personal too.** VoiceStudio keeps its core workflow on your hardware: clone, design, dub, dictate, and publish in 646 languages without a subscription or usage meter. Network-backed engines and services are optional, visible choices—not hidden requirements.
|
||||
|
||||
> [!WARNING]
|
||||
> **Active beta.** Things may break between releases — for the newest fixes, run from source. Bug reports and PRs are very welcome: [open an issue](https://github.com/debpalash/VoiceStudio/issues) or [join Discord](https://discord.gg/bzQavDfVV9).
|
||||
> **Active beta.** Use the [latest release](https://github.com/debpalash/VoiceStudio/releases/latest) for stable work or `main` for current fixes. Report problems through [GitHub Issues](https://github.com/debpalash/VoiceStudio/issues).
|
||||
|
||||
<a id="whats-new"></a>
|
||||
## At a glance
|
||||
|
||||
## 🆕 What's new in 0.5.0
|
||||
| | VoiceStudio |
|
||||
|---|---|
|
||||
| **Workflows** | Voice cloning and design, video dubbing, dictation, stories, audiobooks, batch generation |
|
||||
| **Language catalogue** | 646 TTS languages; actual coverage and quality depend on the selected engine |
|
||||
| **Engines** | 16 TTS · 11 ASR · switch in Model Catalogue or with <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd> |
|
||||
| **Platforms** | macOS 13.3+ on Apple Silicon · Windows 10/11 x64 · Linux x86_64 with glibc 2.39+ |
|
||||
| **Compute** | CUDA · Apple Silicon MPS/MLX · ROCm on Linux · CPU · optional remote workers |
|
||||
| **Interfaces** | Desktop app · local REST/SSE/WebSocket API · OpenAI-compatible audio API · MCP Server |
|
||||
| **Storage** | Voices, projects, settings, and outputs stay on the machine by default |
|
||||
| **License** | AGPL-3.0; optional engines keep their own model licenses |
|
||||
|
||||
The rename release — full notes: [v0.5.0 release](https://github.com/debpalash/VoiceStudio/releases/tag/v0.5.0) · [CHANGELOG](CHANGELOG.md).
|
||||
<a id="install"></a>
|
||||
|
||||
- 🏷️ **A new name** — VoiceStudio (previously OmniVoice-Studio): one waveform-and-spark identity across app, docs, and installers. Your data folder, settings, and Docker image paths stay put.
|
||||
- 📚 **Model Catalogue** — engines and models in one workspace: every TTS, ASR, and LLM engine with its device routing and install state; pick defaults, install or remove weights.
|
||||
- ⚡ **Engine quick-switch** — change TTS/ASR/LLM engines from the status bar or anywhere with <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd> — ready-only choices, memory status, environment-pin protection.
|
||||
- 🖧 **Remote GPU workers** — lend another machine's GPU with a join code and a QR scan; a **Compute** control picks where jobs run, and several people can share one GPU box over revocable, certificate-pinned connections.
|
||||
- 🔐 **Hardened server mode** — admin actions require an API key, exchanged for short-lived scoped sessions that never sit in browser storage or WebSocket URLs.
|
||||
- 💾 **Gallery voices → local profiles** — save any gallery voice as a profile of your own and use it in every picker.
|
||||
- 🎤 **Dictation on Wayland** — the portal shortcut actually fires now, and the recording pill is back on every desktop.
|
||||
## Install
|
||||
|
||||
<div align="center">
|
||||
<img src="docs/media/0.5.0/quick-switch.gif" alt="Switching engines from the status bar" width="640"/>
|
||||
<br/><sub>Engine quick-switch from the status bar — <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd> from any workspace</sub>
|
||||
</div>
|
||||
| Platform | Package | Guide |
|
||||
|---|---|---|
|
||||
| macOS 13.3+ | DMG, Apple Silicon | [Install on macOS](docs/install/macos.md) |
|
||||
| Windows 10/11 | MSI, x64 | [Install on Windows](docs/install/windows.md) |
|
||||
| Linux | AppImage, x86_64 with glibc 2.39+ | [Install on Linux](docs/install/linux.md) |
|
||||
| Docker | CUDA, ROCm, or CPU | [Run with Docker](docs/install/docker.md) |
|
||||
|
||||
<br/>
|
||||
Download packages from the [latest release](https://github.com/debpalash/VoiceStudio/releases/latest). First launch creates a managed Python environment and downloads the default model. Later launches reuse both.
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td width="50%"><img src="docs/media/0.5.0/catalogue.png" alt="Model Catalogue — engines pane" width="100%"/></td>
|
||||
<td width="50%"><img src="docs/media/0.5.0/gallery-save.png" alt="Saving a gallery voice as a profile" width="100%"/></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center"><sub><b>Model Catalogue</b> — every engine, its routing and install state</sub></td>
|
||||
<td align="center"><sub><b>Gallery → profile</b> — keep a gallery voice as your own</sub></td>
|
||||
</tr>
|
||||
</table>
|
||||
> [!NOTE]
|
||||
> On macOS, first launch needs a one-time right-click → **Open** approval. Intel Macs cannot run the local Python backend; use a [remote backend](docs/install/macos.md) instead.
|
||||
|
||||
### First voice
|
||||
|
||||
1. Launch VoiceStudio and open **Voice Cloning**.
|
||||
2. Add a clean voice sample. Three seconds works; 5–15 seconds usually gives a better prompt.
|
||||
3. Enter text, choose a language, then select **Generate**.
|
||||
|
||||
### Run from source
|
||||
|
||||
Install the [development prerequisites](.github/CONTRIBUTING.md#development-setup), then:
|
||||
|
||||
```bash
|
||||
git clone https://github.com/debpalash/VoiceStudio.git
|
||||
cd VoiceStudio
|
||||
bun install
|
||||
bun run desktop
|
||||
```
|
||||
|
||||
Use `bun run dev` for the browser UI. See [Contributing](.github/CONTRIBUTING.md) for services, tests, and platform packages.
|
||||
|
||||
### If setup fails
|
||||
|
||||
- Run **Settings → About → Run self-check** or `uv run python backend/main.py --diagnose --deep`.
|
||||
- Check [install troubleshooting](docs/install/troubleshooting.md).
|
||||
- Save a scrubbed diagnostic bundle from the app when opening an issue.
|
||||
- For slow generation, compare [measured benchmarks](docs/benchmarks.md) and [performance settings](docs/performance.md).
|
||||
|
||||
<a id="features"></a>
|
||||
|
||||
## ✨ Features
|
||||
## Features
|
||||
|
||||
Three flagships, five more headliners, and a dozen under the fold.
|
||||
| Area | Included |
|
||||
|---|---|
|
||||
| **Voice Cloning** | Zero-shot synthesis from a short reference clip |
|
||||
| **Voice Design** | Create a voice from age, accent, pitch, style, and delivery instructions |
|
||||
| **Video Dubbing** | Transcribe, translate, preserve speakers, synthesize, and export video |
|
||||
| **Stories and audiobooks** | Multi-voice scripts · EPUB/PDF import · chapter rendering · `.m4b` export |
|
||||
| **Dictation Widget** | System-wide shortcut, live transcription, optional local-LLM cleanup |
|
||||
| **Vocal Isolation** | Demucs speech/background separation |
|
||||
| **Speaker Diarization** | Pyannote and WhisperX speaker assignment |
|
||||
| **Batch Queue** | Queue large sets of audio and video jobs with per-job progress |
|
||||
| **Model Catalogue** | Install, remove, select, and route TTS, ASR, and LLM models |
|
||||
| **Remote Model Downloads** | Install models on enrolled remote workers with live progress |
|
||||
| **GPU Auto-Detect** | CUDA, MPS, ROCm, and CPU routing with per-engine checks |
|
||||
| **AI Watermark** | AudioSeal embedding and detection |
|
||||
| **MCP Server** | Synthesis and transcription tools for MCP clients |
|
||||
| **Diagnostics** | Self-checks, error journal, logs, and scrubbed support bundles |
|
||||
| **Local-first** | Core creation stays local; network-backed features are explicit opt-ins |
|
||||
| **Extensible** | Registry-based TTS, ASR, and plugin interfaces |
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td width="33%"><img src="docs/features/clone.png" alt="Voice Cloning" width="100%"/></td>
|
||||
<td width="33%"><img src="docs/features/design.png" alt="Voice Design" width="100%"/></td>
|
||||
<td width="33%"><img src="docs/features/dub.png" alt="Video Dubbing" width="100%"/></td>
|
||||
<td width="50%"><img src="docs/media/0.5.0/catalogue.png" alt="VoiceStudio Model Catalogue" width="100%" /></td>
|
||||
<td width="50%"><img src="docs/media/0.5.0/gallery-save.png" alt="Saving a gallery voice as a local profile" width="100%" /></td>
|
||||
</tr>
|
||||
<tr>
|
||||
<td align="center">🎙️ <b>Voice Cloning</b><br/><sub>3-sec clip → any voice · 646 languages · zero-shot</sub></td>
|
||||
<td align="center">🎨 <b>Voice Design</b><br/><sub>Describe it — gender, age, accent, emotion</sub></td>
|
||||
<td align="center">🎬 <b>Video Dubbing</b><br/><sub>Transcribe → translate → re-voice → MP4</sub></td>
|
||||
<td align="center"><sub>Model Catalogue: engine, device, and install state</sub></td>
|
||||
<td align="center"><sub>Gallery: save a shared voice as a local profile</sub></td>
|
||||
</tr>
|
||||
</table>
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
<td align="center" width="20%">📖<br/><b>Audiobook</b><br/><sub>EPUB/PDF → .m4b, multi-voice cast</sub></td>
|
||||
<td align="center" width="20%">🎭<br/><b>Stories</b><br/><sub>Multi-voice script editor</sub></td>
|
||||
<td align="center" width="20%">⌨️<br/><b>Dictation Widget</b><br/><sub><kbd>⌘⇧Space</kbd> in any app</sub></td>
|
||||
<td align="center" width="20%">🔐<br/><b>Local-first</b><br/><sub>Core creation stays on your machine</sub></td>
|
||||
<td align="center" width="20%">🤖<br/><b>MCP Server</b><br/><sub>Use from Claude, Cursor, …</sub></td>
|
||||
</tr>
|
||||
</table>
|
||||
<a id="comparison"></a>
|
||||
|
||||
<details>
|
||||
<summary><b>…and 12 more</b> — catalogue, remote GPUs, isolation, diarization, batch, watermarking, and friends</summary>
|
||||
## Comparison
|
||||
|
||||
<br/>
|
||||
VoiceStudio trades managed cloud compute for local control. This is the practical difference:
|
||||
|
||||
- 📚 **Model Catalogue** — one workspace for every TTS/ASR/LLM engine and model: defaults, device routing, install or remove weights — and quick-switch engines from anywhere with <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd>.
|
||||
- 🖧 **Remote GPU workers** — send jobs to GPUs on your other machines: join code + QR enrolment, Remote Model Downloads with per-worker live progress, chapter-by-chapter audiobook rendering with local fallback. Off by default; see [docs/remote-workers.md](docs/remote-workers.md).
|
||||
- 🔊 **Vocal Isolation** — Demucs-powered: splits speech from music and keeps the background bed.
|
||||
- 👥 **Speaker Diarization** — Pyannote + WhisperX auto-identify who said what.
|
||||
- 📦 **Batch Queue** — drop 50 videos, walk away; per-job progress bars.
|
||||
- 🛡️ **AI Watermark** — AudioSeal (Meta): invisible, survives compression.
|
||||
- 🔬 **Diagnostics** — self-check suite, error journal, scrubbed diagnostic bundles.
|
||||
- ⚡ **GPU Auto-Detect & Routing** — CUDA · MPS · ROCm (Linux, opt-in) · CPU; ≤8 GB VRAM auto-offloads; per-engine GPU preflight, no silent CPU fallback.
|
||||
- 🧩 **Extensible** — subclass `TTSBackend`, add any engine in ~50 lines.
|
||||
- 🎒 **Portable personas** — export voices as `.ovsvoice` bundles: identity + watermark.
|
||||
- ♾️ **Unlimited TTS** — sentence-chunked generation, no length cap, streaming via WebSocket.
|
||||
- 🧠 **Dictation + LLM** — local-LLM cleanup of transcripts, optional echo cancellation.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="quickstart"></a>
|
||||
|
||||
## ⚡ Quickstart
|
||||
|
||||
<div align="center">
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/macOS-DMG_(Apple_Silicon)-000?style=for-the-badge&logo=apple&logoColor=white" alt="Download macOS DMG" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Windows-MSI_(x64)-0078D4?style=for-the-badge&logo=windows&logoColor=white" alt="Download Windows MSI" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Linux-AppImage_(x64)-FCC624?style=for-the-badge&logo=linux&logoColor=black" alt="Download Linux AppImage" /></a>
|
||||
<br/>
|
||||
<sub><b>macOS:</b> first launch needs a one-time approval — right-click → <b>Open</b> (or System Settings → Privacy & Security → <b>"Open Anyway"</b> on macOS 15). No Terminal needed. <a href="docs/install/macos.md#gatekeeper-quarantine">Why?</a> · <b>Intel Macs:</b> local backend unsupported (<a href="https://github.com/debpalash/VoiceStudio/issues/889">#889</a>) — <a href="docs/install/macos.md">details</a>.</sub>
|
||||
</div>
|
||||
|
||||
**Install guide:** [🍎 macOS](docs/install/macos.md) · [🪟 Windows](docs/install/windows.md) · [🐧 Linux](docs/install/linux.md) · [🐳 Docker](docs/install/docker.md)
|
||||
|
||||
<details>
|
||||
<summary><b>🧰 Troubleshooting · slow generation · HF tokens · restricted networks</b></summary>
|
||||
|
||||
<br/>
|
||||
|
||||
- **Something broke?** Run the self-check — **Settings → About → "Run self-check"** (or `uv run python backend/main.py --diagnose --deep`) — then the [top 10 install errors](docs/install/troubleshooting.md). **"Save diagnostic bundle"** packages scrubbed logs for a bug report.
|
||||
- **Feels slow?** [docs/performance.md](docs/performance.md) — where the time goes and how to tune it.
|
||||
- **Want breaths, laughter, emotion?** [docs/expressive-speech.md](docs/expressive-speech.md) — what each engine can do today.
|
||||
- **HF tokens · diarization · download speed / mirrors:** [tokens](docs/setup/huggingface-token.md) · [diarization](docs/features/diarization.md) · [downloads](docs/downloading-models.md).
|
||||
- **Coming from [Real-Time-Voice-Cloning](https://github.com/CorentinJ/Real-Time-Voice-Cloning)?** [Migration guide](docs/migration/real-time-voice-cloning.md).
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="why-voicestudio"></a>
|
||||
|
||||
## ⚖️ Why VoiceStudio
|
||||
|
||||
Cloud voice tools are convenient, but they put your workflow behind an account, a meter, and somebody else's infrastructure. VoiceStudio gives you a capable studio that runs on your hardware, with optional integrations when you choose them.
|
||||
|
||||
| | **ElevenLabs** | **VoiceStudio** |
|
||||
| | **VoiceStudio** | **Typical hosted voice service** |
|
||||
|---|---|---|
|
||||
| **Pricing** | Subscription and usage limits | Free & open-source (AGPL-3.0) · [Commercial license](#license) for proprietary use |
|
||||
| **Voice Cloning** | ✅ 3s clip | ✅ 3s clip, zero-shot |
|
||||
| **Voice Design** | ✅ Gender, age | ✅ Gender, age, accent, pitch, style, dialect |
|
||||
| **Audiobook / Stories** | ❌ | ✅ Full audiobook editor + multi-voice stories (EPUB/PDF import, .m4b export) |
|
||||
| **Languages** | Plan/model dependent | **646** |
|
||||
| **Video Dubbing** | ✅ Cloud-only | ✅ Fully local |
|
||||
| **Data Privacy** | Audio is processed remotely | Core workflow runs locally; online services are explicit opt-ins |
|
||||
| **API Keys** | Account required | Not needed for the local workflow |
|
||||
| **GPU Support** | N/A (cloud) | CUDA · Apple Silicon · ROCm (Linux) · CPU — plus your other machines' GPUs as [remote workers](docs/remote-workers.md) |
|
||||
| **Desktop App** | ❌ | ✅ macOS · Windows · Linux |
|
||||
| **TTS Engines** | 1 | **16** — [full matrix](#tts-engines) |
|
||||
| **ASR Engines** | 1 | **11** — [full lineup](#asr-engines) |
|
||||
| **MCP Server** | ❌ | ✅ Use from Claude, Cursor, any MCP client |
|
||||
| **Self-check** | ❌ | ✅ Diagnostics suite, error journal, scrubbed debug bundles |
|
||||
| **Customizable** | ❌ Closed | ✅ Fork it, extend it, ship it |
|
||||
| **Best fit** | Private, offline, self-hosted, or high-volume work | Fast setup without local model management |
|
||||
| **Data path** | Local by default; remote features are opt-in | Audio and text are processed by the provider |
|
||||
| **Cost model** | Free software; you supply the hardware | Subscription, credits, or metered API use |
|
||||
| **Setup** | Install the app and model weights | Create an account and use the web app or API |
|
||||
| **Performance** | Depends on your engine and hardware | Provider manages compute and scaling |
|
||||
| **Offline use** | Yes, after required models are installed | Usually requires a network connection |
|
||||
| **Customization** | Source, engines, models, API, and routing are open | Limited to provider options |
|
||||
| **Maintenance** | You manage updates, disk, and compute | Provider manages infrastructure |
|
||||
|
||||
Professional-grade voice AI, minus the subscription and the cloud. Convinced? [Come build with us.](https://discord.gg/bzQavDfVV9)
|
||||
<a id="requirements"></a>
|
||||
|
||||
---
|
||||
## Requirements
|
||||
|
||||
## 🖥️ System Requirements
|
||||
Requirements vary by engine. These values cover the default local workflow.
|
||||
|
||||
| | **Minimum** | **Recommended** |
|
||||
|---|---|---|
|
||||
| **OS** | Windows 10, macOS 13.3+ (Apple Silicon), Ubuntu 24.04+ (glibc 2.39+) | Any modern 64-bit OS |
|
||||
| **OS** | Windows 10 x64 · macOS 13.3 Apple Silicon · Linux x86_64 with glibc 2.39+ | Current supported OS release |
|
||||
| **RAM** | 8 GB | 16 GB+ |
|
||||
| **VRAM (GPU)** | 4 GB (auto-offloads TTS to CPU) | 8 GB+ (NVIDIA RTX 3060+) |
|
||||
| **Disk** | 10 GB free (models + cache) | 20 GB+ SSD |
|
||||
| **Python** | 3.10+ (managed by `uv`) | 3.11–3.12 |
|
||||
| **GPU** | Optional — CPU works | NVIDIA CUDA · Apple Silicon MPS · AMD ROCm (Linux only) |
|
||||
| **Disk** | 10 GB free | 20 GB+ SSD |
|
||||
| **GPU** | Optional; CPU mode is supported | NVIDIA CUDA or Apple Silicon |
|
||||
| **VRAM** | 4 GB when using a GPU | 8 GB+; large optional engines need more |
|
||||
| **Python from source** | 3.11+ | 3.11–3.12 |
|
||||
|
||||
> [!NOTE]
|
||||
> **A GPU is optional** — the whole pipeline runs on CPU (just slower), and on ≤8 GB VRAM, TTS auto-offloads to CPU. Caveats: **AMD ROCm** is Linux-only + opt-in ([Linux](docs/install/linux.md#amd-gpu-rocm)) — Windows AMD/Ryzen AI is CPU-only ([Windows](docs/install/windows.md#gpu-support)); **macOS Intel** can't run the local backend, so point it at a remote one ([#889](https://github.com/debpalash/VoiceStudio/issues/889) · [macOS](docs/install/macos.md)).
|
||||
ROCm is Linux-only and opt-in. Windows AMD/Ryzen AI uses CPU. Systems with limited VRAM offload work to CPU when required. See [performance](docs/performance.md), [benchmarks](docs/benchmarks.md), and [engine disk usage](docs/engines/disk-usage.md).
|
||||
|
||||
<a id="engines"></a>
|
||||
|
||||
## Engines
|
||||
|
||||
Engine support is capability-specific. Check cloning, language, platform, memory, and license before choosing one. Full setup guides: [docs/engines](docs/engines/README.md).
|
||||
|
||||
<a id="tts-engines"></a>
|
||||
|
||||
### 🗣️ TTS Engines
|
||||
|
||||
**16 engines, one picker.** VoiceStudio (default, 600+ languages) is always available; seven more are opt-in and auto-detected (CosyVoice 3, GPT-SoVITS, VoxCPM2, MOSS-TTS-Nano, KittenTTS, MLX-Audio, Sherpa-ONNX), plus eight lazy-installed opt-ins (IndexTTS 2.5, OmniVoice GGUF, OmniVoice subprocess, PocketTTS, Supertonic 3, MOSS-TTS-v1.5, dots.tts, Confucius4-TTS). Switch in **Model Catalogue → Engines** — or from anywhere with <kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd>; the choice applies everywhere synthesis happens.
|
||||
|
||||
<details>
|
||||
<summary><b>📊 The full matrix</b> — 16 engines × platform × clone/instruct × license</summary>
|
||||
|
||||
<br/>
|
||||
### Text to speech
|
||||
|
||||
| Engine | Languages | Clone | Instruct | Linux | macOS ARM | Windows | License |
|
||||
|--------|:---------:|:-----:|:--------:|:-----:|:---------:|:-------:|:-------:|
|
||||
| **VoiceStudio** (default, powered by k2-fsa/OmniVoice) | 600+ | ✅ | ✅ | ✅ CUDA/CPU | ✅ MPS | ✅ CUDA/CPU | Built-in |
|
||||
| **CosyVoice 3** | 9 + 18 dialects | ✅ | ✅ | ✅ CUDA/CPU | ✅ MPS | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **GPT-SoVITS** | 5 | ✅ | — | ✅ CUDA/CPU | — | ✅ CUDA/CPU | MIT |
|
||||
| **VoxCPM2** | 30 | ✅ | ✅ | ✅ CUDA/CPU | ✅ MPS | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **MOSS-TTS-Nano** | 20 | ✅ | — | ✅ CUDA/CPU | ✅ CPU | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **KittenTTS** | English | — | — | ✅ CPU | ✅ CPU | ✅ CPU | MIT |
|
||||
| **MLX-Audio** (Kokoro, Qwen3-TTS, CSM, Dia, …) | Multi | Varies | Varies | ❌ | ✅ Native | ❌ | Varies |
|
||||
| **Sherpa-ONNX** | 20+ | — | — | ✅ CUDA/CPU | ✅ CPU | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **IndexTTS 2.5** ⚡ | ZH · EN · JA · ES · AR | ✅ | — | ✅ CUDA | — | ✅ CUDA | Bilibili model license¹ |
|
||||
| **OmniVoice GGUF** ⚡ | 600+ | ✅ | ✅ | ✅ CPU | ✅ CPU | ✅ CPU | Built-in |
|
||||
| **OmniVoice (subprocess)** ⚡² | 600+ | ✅ | ✅ | ✅ CUDA/CPU | ✅ MPS | ✅ CUDA/CPU | Built-in |
|
||||
| **PocketTTS** ⚡ (Kyutai) | EN · FR · DE · PT · IT · ES | ✅ | — | ✅ CPU | ✅ CPU | ✅ CPU | CC-BY-4.0 (gated)³ |
|
||||
| **Supertonic 3** ⚡ | 31 | — | — | ✅ CPU | ✅ CPU | ✅ CPU | OpenRAIL-M |
|
||||
| **MOSS-TTS-v1.5** ⚡ (8B) | 31 | ✅ | — | ✅ CUDA/CPU | ✅ CPU | ✅ CUDA/CPU | Apache-2.0 |
|
||||
| **dots.tts** ⚡ (2B) | 24 | ✅ | — | ✅ CUDA/CPU | ✅ CPU | ❌ | Apache-2.0 |
|
||||
| **Confucius4-TTS** ⚡ | 14 | ✅ | — | ✅ CUDA/CPU | ✅ CPU | ✅ CUDA/CPU | Apache-2.0 |
|
||||
|---|:---:|:---:|:---:|:---:|:---:|:---:|---|
|
||||
| **VoiceStudio** (default, powered by k2-fsa/OmniVoice) | 600+ | Yes | Yes | CUDA/CPU | MPS | CUDA/CPU | [AGPL-3.0](LICENSE) app · [Apache-2.0](LICENSE-NOTICE.md) model |
|
||||
| **CosyVoice 3** | 9 + 18 dialects | Yes | Yes | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
| **GPT-SoVITS** | 5 | Yes | — | CUDA/CPU | — | CUDA/CPU | MIT |
|
||||
| **VoxCPM2** | 30 | Yes | Yes | CUDA/CPU | MPS | CUDA/CPU | Apache-2.0 |
|
||||
| **MOSS-TTS-Nano** | 20 | Yes | — | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
| **KittenTTS** | English | — | — | CPU | CPU | CPU | MIT |
|
||||
| **MLX-Audio** | Model-dependent | Varies | Varies | — | MLX | — | Varies |
|
||||
| **Sherpa-ONNX** | 20+ | — | — | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
| **IndexTTS 2.5** ⚡ | ZH · EN · JA · ES · AR | Yes | — | CUDA/CPU | CPU | CUDA/CPU | Bilibili model license¹ |
|
||||
| **OmniVoice GGUF** ⚡ | 600+ | Yes | Yes | CUDA/CPU | MPS/CPU | CUDA/CPU | [AGPL-3.0](LICENSE) app · [Apache-2.0](LICENSE-NOTICE.md) model |
|
||||
| **OmniVoice (subprocess)** ⚡ | 600+ | Yes | Yes | CUDA/CPU | MPS | CUDA/CPU | [AGPL-3.0](LICENSE) app · [Apache-2.0](LICENSE-NOTICE.md) model |
|
||||
| **PocketTTS** ⚡ | EN · FR · DE · PT · IT · ES | Yes | — | CPU | CPU | CPU | CC-BY-4.0, gated² |
|
||||
| **Supertonic 3** ⚡ | 31 | — | — | CPU | CPU | CPU | OpenRAIL-M |
|
||||
| **MOSS-TTS-v1.5** ⚡ | 31 | Yes | — | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
| **dots.tts** ⚡ | 24 | Yes | — | CUDA/CPU | CPU | — | Apache-2.0 |
|
||||
| **Confucius4-TTS** ⚡ | 14 | Yes | — | CUDA/CPU | CPU | CUDA/CPU | Apache-2.0 |
|
||||
|
||||
¹ IndexTTS 2.5 requires a separate written Bilibili license above 100 million
|
||||
monthly active users or RMB 1 billion in annual revenue. Review its
|
||||
[model license](https://huggingface.co/IndexTeam/IndexTTS-2.5/blob/main/LICENSE)
|
||||
before enabling the optional sidecar.
|
||||
⚡ Installed or registered on demand.
|
||||
|
||||
² **OmniVoice (subprocess)** is the same resident model as the default engine, run
|
||||
in a crash-isolated child process: a wedged generation can be hard-killed and its
|
||||
VRAM reclaimed. Opt-in for unattended synthesis and VRAM-tight MPS hosts —
|
||||
[docs/engines/omnivoice-subprocess.md](docs/engines/omnivoice-subprocess.md).
|
||||
¹ IndexTTS 2.5 requires a separate written Bilibili license above 100 million monthly active users or RMB 1 billion annual revenue. Review the [model license](https://huggingface.co/IndexTeam/IndexTTS-2.5/blob/main/LICENSE).
|
||||
|
||||
³ **PocketTTS** (Kyutai) is a fast, low-latency CPU engine with zero-shot cloning;
|
||||
its gated model access and CC-BY-4.0 conditions are shown for review in-app before
|
||||
first use.
|
||||
² PocketTTS shows its gated-access and CC-BY-4.0 terms before first use.
|
||||
|
||||
GPT-SoVITS connects to `http://127.0.0.1:9880` by default. To use a server on
|
||||
another machine, set `OMNIVOICE_GPTSOVITS_URL` to its credential-free
|
||||
`http://` or `https://` origin and add that machine's CIDR to
|
||||
`OMNIVOICE_TRUSTED_NETWORKS`; redirects and untrusted destinations are rejected.
|
||||
|
||||
> **CUDA** = GPU-accelerated · **MPS** = Apple Silicon Metal · **CPU** = runs everywhere, slower for large models · KittenTTS, MOSS-TTS-Nano, and PocketTTS run realtime on CPU · MLX-Audio is Apple Silicon only · ⚡ = lazy-registered (installed on first use)
|
||||
>
|
||||
> **Clone** matters beyond single-clip generation: Video Dubbing (and any Batch job with a pinned voice) needs reference-audio cloning to preserve speaker identity, so picking a Clone-less engine (KittenTTS, Sherpa-ONNX, Supertonic 3) as the active engine fails those jobs up front with an actionable message instead of silently falling back to VoiceStudio.
|
||||
>
|
||||
> **MOSS-TTS-v1.5** (8B, ~16 GB), **dots.tts** (2B, ~9 GB), and **Confucius4-TTS** are heavyweight opt-ins that run in their own isolated venv from a local clone. None claims Apple-Silicon MPS (CPU on Macs); dots.tts has no Windows path; Confucius4 wants CUDA (CPU works, ~17× realtime). Details: [MOSS-TTS-v1.5](docs/engines/moss-tts-v15.md) · [dots.tts](docs/engines/dots-tts.md) · [Confucius4-TTS](docs/engines/confucius4-tts.md).
|
||||
|
||||
</details>
|
||||
Clone-less engines cannot preserve a reference speaker in dubbing or pinned-voice batch jobs. VoiceStudio rejects those jobs instead of silently changing engines. Heavy engines have separate memory and platform limits; check their engine guide first.
|
||||
|
||||
<a id="asr-engines"></a>
|
||||
|
||||
### 🎧 ASR Engines
|
||||
### Speech to text
|
||||
|
||||
**11 engines** — they power dictation, video dubbing, and subtitles. **WhisperX** is the cross-platform default (~100 languages, word-level timing); the rest are opt-in and auto-detected. Switch in **Model Catalogue → Engines**. Ten run fully on-device; the eleventh (OpenAI-compatible) is an optional remote client for Qwen3-ASR or any compatible server.
|
||||
| Engine | ID | Languages | Best fit |
|
||||
|---|---|:---:|---|
|
||||
| **WhisperX** (default) | `whisperx` | ~100 | Dubbing, subtitles, word-level timing |
|
||||
| **Faster-Whisper** | `faster-whisper` | ~100 | General cross-platform transcription |
|
||||
| **Faster-Whisper (isolated)** | `faster-whisper-isolated` | ~100 | Crash-isolated batch transcription |
|
||||
| **MLX Whisper** | `mlx-whisper` | ~100 | Apple Silicon |
|
||||
| **PyTorch Whisper** | `pytorch-whisper` | ~100 | CUDA, MPS, and CPU fallback |
|
||||
| **Parakeet TDT** | `nemo-parakeet` | English + 25 EU | Fast CPU/CUDA transcription |
|
||||
| **Parakeet TDT v3 (MLX)** | `parakeet-mlx` | 25 EU | Apple Silicon dictation and word timestamps |
|
||||
| **Moonshine** | `moonshine` | English | Low-power, low-latency ONNX |
|
||||
| **FunASR** | `funasr` | 50+ | VAD and inline diarization |
|
||||
| **sherpa-onnx** (live dictation) | `sherpa-onnx-asr` | Model-dependent | Streaming CPU dictation |
|
||||
| **OpenAI-compatible** ⚠️ remote | `openai-compat-asr` | Server-dependent | Qwen3-ASR or another compatible endpoint; audio leaves the machine |
|
||||
|
||||
<details>
|
||||
<summary><b>📊 The full lineup</b> — 11 engines, what each is best at, and compute-type notes</summary>
|
||||
WhisperX and Faster-Whisper retry with `int8` when efficient `float16` is unavailable. Pin `ASR_COMPUTE_TYPE=int8` or `float32` only if automatic selection still fails.
|
||||
|
||||
<br/>
|
||||
<a id="architecture"></a>
|
||||
|
||||
| Engine | `OMNIVOICE_ASR_BACKEND` | Languages | Best for |
|
||||
|--------|-------------------------|:---------:|----------|
|
||||
| **WhisperX** (default) | `whisperx` | ~100 | Dubbing & subtitles — word-level timing via wav2vec2 forced alignment |
|
||||
| **Faster-Whisper** | `faster-whisper` | ~100 | Fast transcription on Linux / macOS / Windows (CTranslate2) |
|
||||
| **Faster-Whisper (isolated)** | `faster-whisper-isolated` | ~100 | Same as Faster-Whisper but crash-isolated in a subprocess — an ASR crash won't take down the app |
|
||||
| **MLX Whisper** | `mlx-whisper` | ~100 | Native Apple Silicon speed (Apple MLX / Metal) |
|
||||
| **PyTorch Whisper** | `pytorch-whisper` | ~100 | CUDA / CPU fallback via 🤗 Transformers (no cuDNN 8 needed) |
|
||||
| **Parakeet TDT** | `nemo-parakeet` | English + 25 EU | SOTA accuracy at ~10× realtime even on CPU, auto language detection (NVIDIA NeMo, CUDA/CPU) |
|
||||
| **Parakeet TDT v3 (MLX)** | `parakeet-mlx` | 25 EU | The Parakeet tier for Apple Silicon — word timestamps, ~2 GB unified memory, dictation-grade speed via MLX. Dictation prefers it automatically for its 25 European languages; other languages keep multilingual Whisper. |
|
||||
| **Moonshine** | `moonshine` | English | Edge / low-latency, ONNX |
|
||||
| **FunASR** | `funasr` | 50+ | All-in-one multilingual — built-in VAD + inline speaker diarization (SenseVoice) |
|
||||
| **sherpa-onnx** (live dictation) | `sherpa-onnx-asr` | 25 EU + 90+ | Live, faster-than-real-time dictation — small streaming/offline ONNX models, CPU, identical on macOS / Windows / Linux. Picked per-model in **Settings → Voice**. |
|
||||
| **OpenAI-compatible** ⚠️ remote | `openai-compat-asr` | Server-dependent | A path to **Qwen3-ASR** today (self-hosted server), any OpenAI-compatible transcription endpoint, or OpenAI's own API — configure + test in **Model Catalogue → Engines** (ASR tab). Audio leaves your machine to whatever server you point it at; see [docs/engines/openai-compatible-asr.md](docs/engines/openai-compatible-asr.md). |
|
||||
## Architecture
|
||||
|
||||
> If Dubbing needs an ASR model that is not installed yet, it offers the recommended download in place, shows its progress, and retries transcription on the same job when the model is ready.
|
||||
>
|
||||
> **GPU without efficient float16?** On older NVIDIA GPUs (Maxwell/Pascal, GTX 16xx) or after a CTranslate2/cuDNN mismatch, the CTranslate2 ASR engines (WhisperX, Faster-Whisper) can't run `float16` and VoiceStudio automatically retries on `int8` — no config needed. If transcription still fails, pin the compute type with `ASR_COMPUTE_TYPE=int8` (or `float32` for CPU) and restart the backend.
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
## 🏗️ Architecture
|
||||
|
||||
A **Tauri v2** desktop shell (Rust) wraps a **React** UI and a bundled **Python/FastAPI** backend that runs as a local sidecar on `localhost:3900`. Every layer runs on your machine by default; the only network paths are the ones you opt into (remote GPU workers, a remote backend, or an OpenAI-compatible ASR endpoint).
|
||||
|
||||
```
|
||||
┌────────────────────────────────────────────────────────────────────┐
|
||||
│ Tauri v2 shell — Rust │
|
||||
│ window state · global dictation hotkey · system tray · │
|
||||
│ signed auto-updater (stable/preview) · single-instance · │
|
||||
│ first-run bootstrap (installs uv + Python venv) · blank guard │
|
||||
├────────────────────────────────────────────────────────────────────┤
|
||||
│ Frontend — React + Vite │
|
||||
│ Studio · Dub · Stories · Audiobook · Gallery · Catalogue · │
|
||||
│ Dictation · Batch · Diagnostics — Zustand store · WS bus │
|
||||
│ ▲ IPC / HTTP + WS │
|
||||
├──────────────────────────┼─────────────────────────────────────────┤
|
||||
│ Backend — FastAPI sidecar @ localhost:3900 │
|
||||
│ 100+ REST endpoints · SSE + WebSocket streaming · │
|
||||
│ SQLite + Alembic (omnivoice_data/) · OpenAI-compatible API │
|
||||
├───────────┬───────────┬───────────┬───────────┬────────────────────┤
|
||||
│ TTS ×16 │ ASR ×11 │ Demucs │ Pyannote │ AudioSeal │
|
||||
│ clone / │ WhisperX │ vocal │ speaker │ watermark │
|
||||
│ design │ +10 more │ isolation│ diariz. │ embed / detect │
|
||||
├───────────┴───────────┴───────────┴───────────┴────────────────────┤
|
||||
│ Engine routing — per-engine GPU preflight, no silent CPU fallback │
|
||||
│ Hardware: CUDA · MPS · ROCm (Linux) · CPU (auto-detected) │
|
||||
│ + optional remote GPU workers on your other machines │
|
||||
└────────────────────────────────────────────────────────────────────┘
|
||||
```text
|
||||
Tauri v2 desktop shell (Rust)
|
||||
│ IPC
|
||||
React + Vite UI
|
||||
│ HTTP · SSE · WebSocket on localhost:3900
|
||||
FastAPI backend
|
||||
├── TTS / ASR engine registries
|
||||
├── dubbing / audio / long-form pipelines
|
||||
├── OpenAI-compatible API and MCP server
|
||||
└── SQLite + Alembic → omnivoice_data/
|
||||
```
|
||||
|
||||
<a id="openai-api"></a>
|
||||
| Layer | Path | Responsibility |
|
||||
|---|---|---|
|
||||
| Desktop shell | `frontend/src-tauri/` | Window lifecycle, tray, shortcuts, updater, sidecar bootstrap |
|
||||
| Frontend | `frontend/src/` | React UI, Zustand state, API and event clients, i18n |
|
||||
| API | `backend/api/` | REST routes, schemas, auth boundaries, streaming |
|
||||
| Core services | `backend/services/` | Generation, dubbing, audio processing, persistence |
|
||||
| Engines | `backend/engines/` | Isolated and optional engine adapters |
|
||||
| Worker system | `backend/worker/` | Authenticated remote compute and job transport |
|
||||
| Data | `omnivoice_data/` | Projects, voices, settings, logs, and SQLite state |
|
||||
| Delivery | `scripts/`, `deploy/`, `.github/workflows/` | Development, packaging, containers, releases, CI |
|
||||
|
||||
## 🔌 OpenAI-compatible API
|
||||
### Network boundary
|
||||
|
||||
<div align="center">
|
||||
- The desktop talks to a loopback-only backend on `localhost:3900`.
|
||||
- Loopback API calls need no server key. Remote access requires a share PIN or API key.
|
||||
- Remote workers and OpenAI-compatible ASR are opt-in. The UI identifies when audio leaves the machine.
|
||||
- Analytics is off until consent. If enabled, it sends allowlisted, content-free usage metadata—not text, audio, file names, or projects.
|
||||
|
||||
**Drop-in replacement for OpenAI / ElevenLabs audio.** One line — no key, no code changes:
|
||||
<a id="api"></a>
|
||||
|
||||
## OpenAI-compatible API
|
||||
|
||||
Point an OpenAI-compatible audio client at the local backend:
|
||||
|
||||
```diff
|
||||
- base_url="https://api.openai.com/v1"
|
||||
+ base_url="http://localhost:3900/v1"
|
||||
```
|
||||
|
||||
</div>
|
||||
|
||||
Your existing scripts, agents, and OpenAI/ElevenLabs SDK calls now run **locally** on whatever engine you have active. What the cloud can't do: `voice` takes **your own cloned-voice profile IDs**, and `model` can pin a **specific engine** per request.
|
||||
|
||||
| Endpoint | What it does |
|
||||
| Endpoint | Purpose |
|
||||
|---|---|
|
||||
| `POST /v1/audio/speech` | TTS — text in; `mp3` / `opus` / `aac` / `flac` / `wav` / `pcm` out. `model`: `tts-1`/`tts-1-hd` (active engine) or a specific one (`voxcpm2`, `cosyvoice`, …). `voice`: a cloned profile ID, `default`, or an OpenAI name (`alloy`, …). `speed` supported. |
|
||||
| `POST /v1/audio/transcriptions` | STT — audio file in; `json` / `text` / `verbose_json` / `srt` / `vtt` out (`verbose_json` adds word-level timings). `whisper-1` maps to your active ASR engine. |
|
||||
| `GET /v1/audio/voices` | VoiceStudio extension — lists every voice profile and engine, so clients can discover your clones. |
|
||||
|
||||
**Speak with your own cloned voice:**
|
||||
| `POST /v1/audio/speech` | TTS to `mp3`, `opus`, `aac`, `flac`, `wav`, or `pcm`; select a profile with `voice` and an engine with `model` |
|
||||
| `POST /v1/audio/transcriptions` | STT to `json`, `text`, `verbose_json`, `srt`, or `vtt` |
|
||||
| `GET /v1/audio/voices` | List local voice profiles and engines |
|
||||
|
||||
```python
|
||||
from openai import OpenAI
|
||||
client = OpenAI(base_url="http://localhost:3900/v1", api_key="none") # any string — nothing checks it
|
||||
|
||||
# Find your cloned voices: GET /v1/audio/voices lists profile IDs
|
||||
client = OpenAI(base_url="http://localhost:3900/v1", api_key="local")
|
||||
|
||||
with client.audio.speech.with_streaming_response.create(
|
||||
model="tts-1", voice="<profile-id>", input="Made on my own hardware.") as r:
|
||||
r.stream_to_file("speech.wav")
|
||||
|
||||
# STT
|
||||
print(client.audio.transcriptions.create(model="whisper-1", file=open("clip.wav", "rb")).text)
|
||||
model="tts-1",
|
||||
voice="<profile-id>",
|
||||
input="Made on my own hardware.",
|
||||
response_format="wav",
|
||||
) as response:
|
||||
response.stream_to_file("speech.wav")
|
||||
```
|
||||
|
||||
Want the whole surface (100+ endpoints)? The full REST API reference is embedded in the app — **Settings → OpenAPI Reference** (Scalar-powered), or the `{}` button in the footer.
|
||||
The full API reference is in **Settings → OpenAPI Reference**. For LAN, Tailscale, or proxy access, read [API authentication](docs/api-auth.md) before exposing the backend.
|
||||
|
||||
Calling the backend from **another machine** (LAN, Tailscale, behind a proxy)? It's loopback-only and unauthenticated by default; to reach it remotely you set a share PIN or an API key, and admin actions require the key — exchanged for short-lived scoped sessions. [docs/api-auth.md](docs/api-auth.md) covers the exact headers, query params, `401`/`403`/`429` meanings, and the `OMNIVOICE_TRUSTED_NETWORKS` exemption.
|
||||
### Agent skills
|
||||
|
||||
### 📓 Run on Google Colab
|
||||
Install the VoiceStudio skills for Claude Code, Codex, Cursor, and other [skills.sh](https://skills.sh)-compatible agents:
|
||||
|
||||
[](https://colab.research.google.com/github/debpalash/VoiceStudio/blob/main/notebooks/OmniVoice_Studio_Colab.ipynb)
|
||||
|
||||
No local GPU? The [official notebook](notebooks/OmniVoice_Studio_Colab.ipynb) boots the full app — web UI included — on a free Colab T4, then walks the whole feature surface as a guided tour with inline playback. No tunnels, no API keys.
|
||||
|
||||
### 🤝 Agent Skills
|
||||
|
||||
Teach your coding agent to speak and listen through your local VoiceStudio — one command, works with **Claude Code, Codex, Cursor, Grok, Kimi, opencode**, and any [skills.sh](https://skills.sh)-compatible agent:
|
||||
|
||||
```sh
|
||||
```bash
|
||||
npx skills add debpalash/omnivoice-studio
|
||||
```
|
||||
|
||||
Ships two skills: **`omnivoice`** — generate speech (including your cloned voices) and transcribe audio from any agent, free and fully offline — and **`oss-maintainer`** — the maintainer methodology this project is run with.
|
||||
- `omnivoice`: synthesize speech and transcribe audio through local VoiceStudio.
|
||||
- `oss-maintainer`: the repository's open-source maintenance workflow.
|
||||
|
||||
---
|
||||
### Google Colab
|
||||
|
||||
<a id="roadmap"></a>
|
||||
[](https://colab.research.google.com/github/debpalash/VoiceStudio/blob/main/notebooks/OmniVoice_Studio_Colab.ipynb)
|
||||
|
||||
## 🗺️ Roadmap
|
||||
The [notebook](notebooks/OmniVoice_Studio_Colab.ipynb) runs the app and web UI on a Colab GPU. Colab is remote compute, so uploaded audio and project data do not remain local to your machine.
|
||||
|
||||
What's up next (lip-sync v2, hosted demo, plugin marketplace, real-time voice changer) and the full history of everything shipped so far live in **[docs/ROADMAP.md](docs/ROADMAP.md)**.
|
||||
<a id="documentation"></a>
|
||||
|
||||
---
|
||||
## Documentation
|
||||
|
||||
<a id="sponsor--donate"></a>
|
||||
| Need | Read |
|
||||
|---|---|
|
||||
| Install | [macOS](docs/install/macos.md) · [Windows](docs/install/windows.md) · [Linux](docs/install/linux.md) · [Docker](docs/install/docker.md) |
|
||||
| Fix setup | [Troubleshooting](docs/install/troubleshooting.md) · [model downloads](docs/downloading-models.md) · [Hugging Face token](docs/setup/huggingface-token.md) |
|
||||
| Choose an engine | [Engine guides](docs/engines/README.md) · [benchmarks](docs/benchmarks.md) · [expressive speech](docs/expressive-speech.md) |
|
||||
| Tune hardware | [Performance](docs/performance.md) · [remote workers](docs/remote-workers.md) |
|
||||
| Build integrations | [API auth](docs/api-auth.md) · [MCP](docs/mcp.md) · [examples](examples/README.md) |
|
||||
| Build VoiceStudio | [Contributing](.github/CONTRIBUTING.md) · [engine acceptance](docs/engine-acceptance.md) |
|
||||
| Track changes | [Changelog](CHANGELOG.md) · [roadmap](docs/ROADMAP.md) · [latest release](https://github.com/debpalash/VoiceStudio/releases/latest) |
|
||||
| Remove everything | [Uninstall guide](docs/install/uninstall.md) |
|
||||
|
||||
## 💜 Sponsor / Donate
|
||||
## FAQ
|
||||
|
||||
One developer, real AI-agent bills. If VoiceStudio is useful to you, chipping in keeps development full-time — every dollar goes straight to the bills.
|
||||
<details>
|
||||
<summary><strong>Does it work on Apple Silicon and Intel Macs?</strong></summary>
|
||||
|
||||
Apple Silicon is supported with MPS and MLX options. Intel Macs cannot run the local backend because current PyTorch wheels are unavailable; they can connect to a remote backend. See [macOS installation](docs/install/macos.md).
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>How much VRAM do I need?</strong></summary>
|
||||
|
||||
A GPU is optional. Use 4 GB VRAM as the minimum for accelerated work and 8 GB+ for the default multi-stage workflow. Large optional engines can require 12–16 GB or more. Check the [benchmarks](docs/benchmarks.md) and engine guide.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>Why does a longer reference clip not always improve the clone?</strong></summary>
|
||||
|
||||
Cloning is zero-shot: the clip is a prompt, not training data. Use 5–15 seconds of one speaker, close to the microphone, without music, noise, or reverb. Match the tone and pace you want in the output. For training, see [data preparation](docs/data_preparation.md) and [training](docs/training.md).
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>Can I use generated audio commercially?</strong></summary>
|
||||
|
||||
Yes under VoiceStudio's AGPL-3.0 terms. Optional engines and model weights may use different licenses; review the selected engine's license before commercial use.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>Does VoiceStudio collect data?</strong></summary>
|
||||
|
||||
Not unless you opt in. Analytics is off by default and skipping consent keeps it off. When enabled, the app sends allowlisted, content-free usage metadata. Text, audio, file names, voices, and projects are excluded. Change this at **Settings → Privacy**.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><strong>How do I remove VoiceStudio and its data?</strong></summary>
|
||||
|
||||
Use `scripts/uninstall.sh` on macOS/Linux or `scripts\uninstall.ps1` on Windows. Both show a dry run before deletion. See the [uninstall guide](docs/install/uninstall.md) for every path.
|
||||
</details>
|
||||
|
||||
## Community and contributing
|
||||
|
||||
- [GitHub Issues](https://github.com/debpalash/VoiceStudio/issues) for reproducible bugs and feature requests.
|
||||
- [Discord](https://discord.gg/bzQavDfVV9) for setup help and project discussion.
|
||||
- [Good first issues](https://github.com/debpalash/VoiceStudio/labels/good%20first%20issue) for a scoped starting point.
|
||||
- [Contributing guide](.github/CONTRIBUTING.md) for setup, tests, and pull requests.
|
||||
|
||||
## Support development
|
||||
|
||||
VoiceStudio is free and has no paid tier. Donations fund development and infrastructure.
|
||||
|
||||
[Ko-fi](https://ko-fi.com/debpalash) · [PayPal](https://paypal.me/palashCoder) · [Sponsorship details](SPONSORS.md)
|
||||
|
||||
## License
|
||||
|
||||
VoiceStudio is licensed under [AGPL-3.0](LICENSE). You may run it, modify it, use it internally, and sell generated audio. If you modify VoiceStudio and provide that modified version as a network service, AGPL requires you to offer the corresponding source under the same license. A commercial license is available for proprietary embedding; contact **VoiceStudio@palash.dev**. See [LICENSE-NOTICE.md](LICENSE-NOTICE.md) for the plain-language scope.
|
||||
|
||||
Optional engines and downloaded models retain their own licenses. The bundled `omnivoice/` model remains Apache-2.0 upstream.
|
||||
|
||||
## Acknowledgments
|
||||
|
||||
VoiceStudio builds on [OmniVoice](https://github.com/k2-fsa/OmniVoice), [WhisperX](https://github.com/m-bain/whisperX), [Demucs](https://github.com/facebookresearch/demucs), [Pyannote](https://github.com/pyannote/pyannote-audio), [CTranslate2](https://github.com/OpenNMT/CTranslate2), [AudioSeal](https://github.com/facebookresearch/audioseal), [Tauri](https://tauri.app), [Supertonic](https://huggingface.co/Supertone/supertonic-3), [Sherpa-ONNX](https://github.com/k2-fsa/sherpa-onnx), [GPT-SoVITS](https://github.com/RVC-Boss/GPT-SoVITS), and [PocketTTS](https://kyutai.org).
|
||||
|
||||
<div align="center">
|
||||
|
||||
<img src="https://img.shields.io/badge/raised_%2410_of_%24200-5%25-EAB308?style=for-the-badge" alt="This month's agent-bill fund: $10 / $200" />
|
||||
|
||||
<br/><br/>
|
||||
|
||||
<a href="https://ko-fi.com/debpalash"><img src="https://img.shields.io/badge/Ko--fi-Support_❤️-FF5E5B?style=for-the-badge&logo=ko-fi&logoColor=white" alt="Ko-fi" /></a>
|
||||
|
||||
<a href="https://paypal.me/palashCoder"><img src="https://img.shields.io/badge/PayPal-Donate-00457C?style=for-the-badge&logo=paypal&logoColor=white" alt="PayPal" /></a>
|
||||
|
||||
</div>
|
||||
|
||||
<a id="sponsors"></a>
|
||||
|
||||
### 🌟 Sponsors
|
||||
|
||||
VoiceStudio is **free** and **AGPL-3.0** — no paid tier, no SaaS revenue. Sponsors keep development going, and in return get a logo slot here, in the app, and (for top tiers) on the project website. It's a thank-you, never a paywall. **[See tiers & become a sponsor →](SPONSORS.md)**
|
||||
|
||||
<div align="center">
|
||||
|
||||
<!-- SPONSORS:START — logo slots are filled here as sponsors come aboard; see SPONSORS.md -->
|
||||
|
||||
**Your logo here** — [become a sponsor](SPONSORS.md)
|
||||
|
||||
<!-- SPONSORS:END -->
|
||||
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
## 💬 Community
|
||||
|
||||
<div align="center">
|
||||
<a href="https://discord.gg/bzQavDfVV9"><img src="https://img.shields.io/badge/💬_Discord-Join_Community-5865F2?style=for-the-badge&logo=discord&logoColor=white" alt="Join Discord" /></a>
|
||||
<a href="https://x.com/idebpalash"><img src="https://img.shields.io/badge/𝕏_Follow-for_updates-000000?style=for-the-badge&logo=x&logoColor=white" alt="Follow on X" /></a>
|
||||
<br/>
|
||||
<sub>Release news, setup help, GPU troubleshooting, feature votes, and showing off your dubs. We respond to setup questions within hours, not days.</sub>
|
||||
</div>
|
||||
|
||||
---
|
||||
|
||||
<a id="contributing"></a>
|
||||
|
||||
## 🤝 Contributing
|
||||
|
||||
Yes please — bug fixes, new TTS engine adapters, UI improvements, docs, translations. All of it. Start with the **[Contributing Guide](.github/CONTRIBUTING.md)** (setup, code style, PR workflow), browse [good first issues](https://github.com/debpalash/VoiceStudio/labels/good%20first%20issue), or ask in [Discord](https://discord.gg/bzQavDfVV9).
|
||||
|
||||
---
|
||||
|
||||
## ❓ FAQ
|
||||
|
||||
<details>
|
||||
<summary><b>Does it work on Apple Silicon (M1/M2/M3/M4)?</b></summary>
|
||||
<br/>
|
||||
Yes. MPS acceleration is auto-detected. MLX-optimized Whisper models are available for faster transcription on Apple hardware. <b>Intel Macs are not supported</b>: the app UI installs, but the local Python backend cannot run because PyTorch no longer ships Intel-Mac wheels (<a href="https://github.com/debpalash/VoiceStudio/issues/889">#889</a>) — an Intel Mac can only be used with a remote backend.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>How much VRAM do I need?</b></summary>
|
||||
<br/>
|
||||
<b>4 GB minimum.</b> With ≤8 GB, the TTS model is automatically offloaded to CPU during transcription. With 8+ GB, everything runs on GPU simultaneously. No GPU at all? CPU mode works — just slower (~3× for TTS). You can also lend a GPU from another machine you own via <a href="docs/remote-workers.md">remote workers</a>.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>What languages are supported?</b></summary>
|
||||
<br/>
|
||||
646 languages for TTS via the VoiceStudio model. Transcription (WhisperX) supports 99 languages. Translation coverage depends on the target language pair.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Why doesn't a longer reference clip sound more like me?</b></summary>
|
||||
<br/>
|
||||
Because VoiceStudio's cloning is <b>zero-shot</b>: your clip is a <i>prompt</i> the model conditions on — it is never trained on, and past a short window extra audio is simply unused (the dubbing pipeline targets ~8 s and hard-caps at 15 s). <b>What moves clone quality is the clip, not its length</b>: record 5–15 seconds of continuous natural speech, close to the mic, in a quiet room with no reverb or music, one speaker, delivered in the tone and pace you want — the clone copies your delivery, not just your timbre. Want trained-on-your-voice fidelity? That's offline fine-tuning, not an in-app button: <a href="docs/data_preparation.md">docs/data_preparation.md</a> + <a href="docs/training.md">docs/training.md</a>.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Can I use this commercially?</b></summary>
|
||||
<br/>
|
||||
<b>Yes — commercial use is free</b> under the <a href="https://www.gnu.org/licenses/agpl-3.0.html">AGPL-3.0</a>: run it, sell the audio you make, dub client videos, deploy it across your team. One obligation: if you <b>modify</b> VoiceStudio and offer the modified version to others over a network, you must share that modified source under the same terms. Embedding it in a closed-source product instead? A commercial license is available — see <a href="#license">License</a>.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Can I add my own TTS engine?</b></summary>
|
||||
<br/>
|
||||
Yes. Subclass <code>TTSBackend</code> in <code>backend/services/tts_backend.py</code> and add it to the <code>_REGISTRY</code> dictionary — ~50 lines. The sixteen built-in engines all work this way; see <a href="#tts-engines">TTS Engines</a> and <a href="docs/engine-acceptance.md">docs/engine-acceptance.md</a>.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>Does VoiceStudio collect any data about me?</b></summary>
|
||||
<br/>
|
||||
<b>Not unless you explicitly say yes.</b> On first run the app <i>asks</i> — one screen, two equal-weight buttons, no pre-ticked box — and until you answer yes, VoiceStudio sends nothing: no analytics, no telemetry, no accounts, no phone-home. Skipping the question means no. Your text, audio, voices, and projects never leave your machine either way.
|
||||
|
||||
If you do opt in (also togglable anytime under <b>Settings → Privacy → "Help improve VoiceStudio"</b>), what's sent is anonymous, content-free usage stats: generations (engine, language, generation time, character <i>count</i>, error <i>type</i>), plus app lifecycle — an install ping, updates (version-to-version), crashes (error class and a <i>bucketed</i> uptime, never logs), error <i>types</i> (capped, deduplicated), and a single uninstall ping if you remove it. Never your text, audio, file names, or anything identifying — enforced in code by a property allowlist (<code>backend/core/analytics.py</code>), not just a promise. Every build — installer, Docker, or built from source — asks the same first-run question and stays off unless you say yes. Your own numbers live in <b>Settings → Usage</b>, computed locally, sent nowhere.
|
||||
</details>
|
||||
|
||||
<details>
|
||||
<summary><b>How do I uninstall it / remove all its data?</b></summary>
|
||||
<br/>
|
||||
VoiceStudio is fully local — uninstalling is just deleting the app plus the folders it wrote (model cache, Python env, your voices/projects, config). Run <code>scripts/uninstall.sh</code> (macOS/Linux) or <code>scripts\uninstall.ps1</code> (Windows) — it prints every folder with its size as a dry-run first, then deletes on <code>--yes</code>. The full per-platform path list and app-removal steps are in <a href="docs/install/uninstall.md"><b>docs/install/uninstall.md</b></a>.
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="license"></a>
|
||||
|
||||
## 📜 License
|
||||
|
||||
VoiceStudio is free and open-source software under the [**GNU Affero General Public License v3.0 (AGPL-3.0)**](https://www.gnu.org/licenses/agpl-3.0.html).
|
||||
|
||||
**Free for any use — including commercial and internal business use.** Run it, sell the audio you produce with it, dub your own or clients' videos, roll it out across your team — all free, no license needed. As a **network copyleft** license, AGPL adds one obligation: if you **modify** VoiceStudio and offer that modified version to others over a network, you must make the complete corresponding source of your modified version available to them under the same AGPL-3.0 terms.
|
||||
|
||||
A **commercial license** is available for organizations that want to embed VoiceStudio in a **closed-source or proprietary** product or service without the AGPL-3.0 copyleft obligations. **Pricing tiers coming soon.** Inquiries: **VoiceStudio@palash.dev**.
|
||||
|
||||
The bundled `omnivoice/` TTS model by Han Zhu remains Apache-2.0 upstream. See [`LICENSE`](LICENSE) for the full, binding terms, and [`LICENSE-NOTICE.md`](LICENSE-NOTICE.md) for the plain-language summary and scope.
|
||||
|
||||
---
|
||||
|
||||
## 🙏 Acknowledgments
|
||||
|
||||
VoiceStudio stands on exceptional open-source work: [OmniVoice (k2-fsa)](https://github.com/k2-fsa/OmniVoice) — the core zero-shot TTS model · [WhisperX](https://github.com/m-bain/whisperX) · [Demucs](https://github.com/facebookresearch/demucs) · [Pyannote](https://github.com/pyannote/pyannote-audio) · [CTranslate2](https://github.com/OpenNMT/CTranslate2) · [AudioSeal](https://github.com/facebookresearch/audioseal) · [Tauri](https://tauri.app) · [Supertonic](https://huggingface.co/Supertone/supertonic-3) · [Sherpa-ONNX](https://github.com/k2-fsa/sherpa-onnx) · [GPT-SoVITS](https://github.com/RVC-Boss/GPT-SoVITS) · [Kyutai PocketTTS](https://kyutai.org) — thank you.
|
||||
|
||||
<a id="more-from-the-maker"></a>
|
||||
|
||||
### 🧰 More local open-source from the maker
|
||||
|
||||
[**Opal** 💠](https://github.com/debpalash/Opal) — play everything: the media player for the AI era · [**memxt** 🧠](https://github.com/debpalash/memxt) — local long-term memory for coding agents. Same rule: **your data stays on your machine.**
|
||||
|
||||
---
|
||||
|
||||
<div align="center">
|
||||
|
||||
<br/>
|
||||
|
||||
If you read this far, you're our kind of person.<br/>
|
||||
**[⭐ Star this repo](https://github.com/debpalash/VoiceStudio)** so others can find it too.<br/>
|
||||
**[💬 Join the Discord](https://discord.gg/bzQavDfVV9)** to share what you build.<br/>
|
||||
**[❤️ Support development](https://ko-fi.com/debpalash)** — fund the AI agent bills that keep VoiceStudio shipping.
|
||||
|
||||
<br/>
|
||||
|
||||
<a href="https://star-history.com/#debpalash/VoiceStudio&Date">
|
||||
<picture>
|
||||
<source media="(prefers-color-scheme: dark)" srcset="https://api.star-history.com/svg?repos=debpalash/VoiceStudio&type=Date&theme=dark" />
|
||||
<source media="(prefers-color-scheme: light)" srcset="https://api.star-history.com/svg?repos=debpalash/VoiceStudio&type=Date" />
|
||||
<img alt="Star History" src="https://api.star-history.com/svg?repos=debpalash/VoiceStudio&type=Date&theme=dark" width="600" />
|
||||
</picture>
|
||||
</a>
|
||||
<strong><a href="https://github.com/debpalash/VoiceStudio/releases/latest">Download VoiceStudio</a></strong> ·
|
||||
<a href="https://github.com/debpalash/VoiceStudio">Star the project</a> ·
|
||||
<a href="https://discord.gg/bzQavDfVV9">Join Discord</a>
|
||||
</div>
|
||||
|
||||
+59
-52
@@ -37,7 +37,7 @@
|
||||
<br/>
|
||||
|
||||
<div align="center">
|
||||
<img src="docs/screenshot-launchpad.png" alt="VoiceStudio — 启动台" width="100%"/>
|
||||
<img src="docs/media/0.5.0/quick-switch.gif" alt="VoiceStudio — 从状态栏快速切换 TTS 引擎" width="100%"/>
|
||||
</div>
|
||||
|
||||
> **声音很私人,创作空间也应该真正属于你。** VoiceStudio 的核心流程运行在你的硬件上:克隆、设计、配音、听写,并以 646 种语言创作,不需要订阅,也没有用量计费。联网引擎和服务始终是清晰可见的可选项,而不是隐藏依赖。
|
||||
@@ -45,6 +45,56 @@
|
||||
> [!WARNING]
|
||||
> **活跃 Beta 阶段。** 各版本之间可能出现故障——如需最新修复,请从源码运行。非常欢迎 Bug 报告和 PR:[提交 Issue](https://github.com/debpalash/VoiceStudio/issues) 或 [加入 Discord](https://discord.gg/bzQavDfVV9)。
|
||||
|
||||
<a id="quickstart"></a>
|
||||
|
||||
## ⚡ 快速开始
|
||||
|
||||
<div align="center">
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/macOS-DMG_(Apple_Silicon)-000?style=for-the-badge&logo=apple&logoColor=white" alt="下载 macOS DMG" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Windows-MSI_(x64)-0078D4?style=for-the-badge&logo=windows&logoColor=white" alt="下载 Windows MSI" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Linux-AppImage_(x64)-FCC624?style=for-the-badge&logo=linux&logoColor=black" alt="下载 Linux AppImage" /></a>
|
||||
<br/>
|
||||
<sub>三个按钮都会打开最新发布页——在资源列表中下载对应你系统的安装包。</sub><br/>
|
||||
<sub><b>macOS:</b>首次启动需要一次性批准——右键点击 → <b>打开</b>(macOS 15 上为 系统设置 → 隐私与安全性 → <b>“仍要打开”</b>)。无需终端。<a href="docs/install/macos.md#gatekeeper-quarantine">为什么?</a> · <b>Intel Mac:</b>不支持本地后端(<a href="https://github.com/debpalash/VoiceStudio/issues/889">#889</a>)——<a href="docs/install/macos.md">详情</a>。</sub>
|
||||
</div>
|
||||
|
||||
选择你的操作系统,按指南从头到尾操作:
|
||||
|
||||
- 🍎 **macOS** — [docs/install/macos.md](docs/install/macos.md)
|
||||
- 🪟 **Windows** — [docs/install/windows.md](docs/install/windows.md)
|
||||
- 🐧 **Linux** — [docs/install/linux.md](docs/install/linux.md)
|
||||
- 🐳 **Docker** — [docs/install/docker.md](docs/install/docker.md) · [Docker Hub: `palashdeb/omnivoice-studio`](https://hub.docker.com/r/palashdeb/omnivoice-studio)
|
||||
|
||||
**三步克隆出你的第一个声音:**
|
||||
|
||||
1. **安装并启动。** 首次启动会自动搭建 Python 运行环境并下载模型权重——启动画面会逐步显示进度(仅首次,需要几分钟;之后即开即用)。
|
||||
2. 从启动台打开**语音克隆**,拖入任意声音的 **3 秒音频**。
|
||||
3. **输入一句话,点击生成。** 音频完全属于你——在你的设备上生成和保存,支持 646 种语言。
|
||||
|
||||
觉得慢?[docs/performance.md](docs/performance.md) 讲清了生成时间到底花在哪里、有哪些调优开关,以及“它变慢了”的三个经典原因。各引擎/设备的实测数据见 [docs/benchmarks.md](docs/benchmarks.md)。
|
||||
|
||||
> 正在从 **[CorentinJ/Real-Time-Voice-Cloning](https://github.com/CorentinJ/Real-Time-Voice-Cloning)**(现已归档)迁移过来?我们有专门的迁移指南:[docs/migration/real-time-voice-cloning.md](docs/migration/real-time-voice-cloning.md)。
|
||||
|
||||
<details>
|
||||
<summary><b>🧰 卡住了?自检、Token 与受限网络</b></summary>
|
||||
|
||||
<br/>
|
||||
|
||||
先运行内置自检——在应用中打开 **设置 → 关于 → “运行自检”**,或在源码检出目录中执行
|
||||
`uv run python backend/main.py --diagnose`(加 `--deep` 还会实际加载当前引擎进行测试)。然后查看
|
||||
[docs/install/troubleshooting.md](docs/install/troubleshooting.md) 中排名前
|
||||
10 的安装错误。运行时出错时,应用内的错误界面会直接深链到对应条目;**设置 → 关于 →
|
||||
“保存诊断包”** 会把脱敏日志与自检报告打包,方便附在 Bug 报告里。
|
||||
|
||||
Hugging Face Token 的配置见
|
||||
[docs/setup/huggingface-token.md](docs/setup/huggingface-token.md)。说话人分离相关的模型访问门槛见
|
||||
[docs/features/diarization.md](docs/features/diarization.md)。下载速度、⚡ 快速下载(Xet)状态,以及受限网络 / 镜像选项见
|
||||
[docs/downloading-models.md](docs/downloading-models.md)。
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="features"></a>
|
||||
|
||||
## ✨ 功能
|
||||
@@ -112,49 +162,6 @@
|
||||
|
||||
---
|
||||
|
||||
<a id="quickstart"></a>
|
||||
|
||||
## ⚡ 快速开始
|
||||
|
||||
<div align="center">
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/macOS-DMG_(Apple_Silicon)-000?style=for-the-badge&logo=apple&logoColor=white" alt="下载 macOS DMG" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Windows-MSI_(x64)-0078D4?style=for-the-badge&logo=windows&logoColor=white" alt="下载 Windows MSI" /></a>
|
||||
<a href="https://github.com/debpalash/VoiceStudio/releases/latest"><img src="https://img.shields.io/badge/Linux-AppImage_(x64)-FCC624?style=for-the-badge&logo=linux&logoColor=black" alt="下载 Linux AppImage" /></a>
|
||||
<br/>
|
||||
<sub><b>macOS:</b>首次启动需要一次性批准——右键点击 → <b>打开</b>(macOS 15 上为 系统设置 → 隐私与安全性 → <b>“仍要打开”</b>)。无需终端。<a href="docs/install/macos.md#gatekeeper-quarantine">为什么?</a> · <b>Intel Mac:</b>不支持本地后端(<a href="https://github.com/debpalash/VoiceStudio/issues/889">#889</a>)——<a href="docs/install/macos.md">详情</a>。</sub>
|
||||
</div>
|
||||
|
||||
选择你的操作系统,按指南从头到尾操作:
|
||||
|
||||
- 🍎 **macOS** — [docs/install/macos.md](docs/install/macos.md)
|
||||
- 🪟 **Windows** — [docs/install/windows.md](docs/install/windows.md)
|
||||
- 🐧 **Linux** — [docs/install/linux.md](docs/install/linux.md)
|
||||
- 🐳 **Docker** — [docs/install/docker.md](docs/install/docker.md) · [Docker Hub: `palashdeb/omnivoice-studio`](https://hub.docker.com/r/palashdeb/omnivoice-studio)
|
||||
|
||||
觉得慢?[docs/performance.md](docs/performance.md) 讲清了生成时间到底花在哪里、有哪些调优开关,以及“它变慢了”的三个经典原因。
|
||||
|
||||
> 正在从 **[CorentinJ/Real-Time-Voice-Cloning](https://github.com/CorentinJ/Real-Time-Voice-Cloning)**(现已归档)迁移过来?我们有专门的迁移指南:[docs/migration/real-time-voice-cloning.md](docs/migration/real-time-voice-cloning.md)。
|
||||
|
||||
<details>
|
||||
<summary><b>🧰 卡住了?自检、Token 与受限网络</b></summary>
|
||||
|
||||
<br/>
|
||||
|
||||
先运行内置自检——在应用中打开 **设置 → 关于 → “运行自检”**,或在源码检出目录中执行
|
||||
`uv run python backend/main.py --diagnose`(加 `--deep` 还会实际加载当前引擎进行测试)。然后查看
|
||||
[docs/install/troubleshooting.md](docs/install/troubleshooting.md) 中排名前
|
||||
10 的安装错误。运行时出错时,应用内的错误界面会直接深链到对应条目;**设置 → 关于 →
|
||||
“保存诊断包”** 会把脱敏日志与自检报告打包,方便附在 Bug 报告里。
|
||||
|
||||
Hugging Face Token 的配置见
|
||||
[docs/setup/huggingface-token.md](docs/setup/huggingface-token.md)。说话人分离相关的模型访问门槛见
|
||||
[docs/features/diarization.md](docs/features/diarization.md)。下载速度、⚡ 快速下载(Xet)状态,以及受限网络 / 镜像选项见
|
||||
[docs/downloading-models.md](docs/downloading-models.md)。
|
||||
|
||||
</details>
|
||||
|
||||
---
|
||||
|
||||
<a id="why-voicestudio"></a>
|
||||
|
||||
## 💡 为什么选择 VoiceStudio?
|
||||
@@ -173,8 +180,8 @@ Hugging Face Token 的配置见
|
||||
| **API 密钥** | 需要账号 | 本地流程不需要 |
|
||||
| **GPU 支持** | 不适用(云端) | CUDA · Apple Silicon · ROCm(Linux)· CPU |
|
||||
| **桌面应用** | ❌ | ✅ macOS · Windows · Linux |
|
||||
| **TTS 引擎** | 1 | **14** — [完整矩阵](#tts-engines) |
|
||||
| **ASR 引擎** | 1 | **10** — [完整阵容](#asr-engines) |
|
||||
| **TTS 引擎** | 1 | **16** — [完整矩阵](#tts-engines) |
|
||||
| **ASR 引擎** | 1 | **11** — [完整阵容](#asr-engines) |
|
||||
| **MCP 服务器** | ❌ | ✅ 可从 Claude、Cursor 及任何 MCP 客户端使用 |
|
||||
| **自检** | ❌ | ✅ 诊断套件、错误日志、脱敏调试包 |
|
||||
| **可定制** | ❌ 闭源 | ✅ 随你 Fork、扩展、发布 |
|
||||
@@ -214,10 +221,10 @@ Hugging Face Token 的配置见
|
||||
|
||||
### 🗣️ TTS 引擎
|
||||
|
||||
**14 个引擎,一个选择器。** VoiceStudio(默认,支持 600+ 语言)始终可用;另有七个引擎可选装并自动检测(CosyVoice 3、GPT-SoVITS、VoxCPM2、MOSS-TTS-Nano、KittenTTS、MLX-Audio、Sherpa-ONNX),外加六个按需延迟安装的重量级引擎(IndexTTS 2.5、OmniVoice GGUF、Supertonic 3、MOSS-TTS-v1.5、dots.tts、Confucius4-TTS)。在 **设置 → TTS 引擎** 中切换;所选引擎将应用于所有语音合成场景。
|
||||
**16 个引擎,一个选择器。** VoiceStudio(默认,支持 600+ 语言)始终可用;另有七个引擎可选装并自动检测(CosyVoice 3、GPT-SoVITS、VoxCPM2、MOSS-TTS-Nano、KittenTTS、MLX-Audio、Sherpa-ONNX),外加八个按需延迟安装的引擎(IndexTTS 2.5、OmniVoice GGUF、OmniVoice 子进程版、PocketTTS、Supertonic 3、MOSS-TTS-v1.5、dots.tts、Confucius4-TTS)。在 **设置 → TTS 引擎** 中切换;所选引擎将应用于所有语音合成场景。**每个引擎都有独立指南:[docs/engines](docs/engines/README.md)(英文)。**
|
||||
|
||||
<details>
|
||||
<summary><b>📊 完整矩阵</b>——14 个引擎 × 平台 × 克隆/指令 × 许可证</summary>
|
||||
<summary><b>📊 完整矩阵</b>——16 个引擎 × 平台 × 克隆/指令 × 许可证</summary>
|
||||
|
||||
<br/>
|
||||
|
||||
@@ -254,10 +261,10 @@ Hugging Face Token 的配置见
|
||||
|
||||
### 🎧 ASR 引擎
|
||||
|
||||
**10 个引擎**——它们驱动听写、视频配音和字幕。**WhisperX** 是跨平台的默认引擎(约 100 种语言,词级时间对齐);其余引擎均为可选装并自动检测。在 **设置 → 引擎** 中切换。九个完全在本地设备上运行;第十个(OpenAI 兼容)是可选的远程客户端,可用于 Qwen3-ASR 或任何兼容的服务器。
|
||||
**11 个引擎**——它们驱动听写、视频配音和字幕。**WhisperX** 是跨平台的默认引擎(约 100 种语言,词级时间对齐);其余引擎均为可选装并自动检测。在 **设置 → 引擎** 中切换。十个完全在本地设备上运行;第十一个(OpenAI 兼容)是可选的远程客户端,可用于 Qwen3-ASR 或任何兼容的服务器。
|
||||
|
||||
<details>
|
||||
<summary><b>📊 完整阵容</b>——10 个引擎、各自的强项与计算类型说明</summary>
|
||||
<summary><b>📊 完整阵容</b>——11 个引擎、各自的强项与计算类型说明</summary>
|
||||
|
||||
<br/>
|
||||
|
||||
@@ -274,7 +281,7 @@ Hugging Face Token 的配置见
|
||||
| **sherpa-onnx**(实时听写) | `sherpa-onnx-asr` | 25 种欧洲语言 + 90+ | 实时、快于实时的听写——小体积流式/离线 ONNX 模型(Parakeet TDT v3/v2、流式 Zipformer 与 Paraformer、Whisper Tiny),CPU 运行,macOS / Windows / Linux 表现完全一致。在 **设置 → 语音** 中按模型选择。 |
|
||||
| **OpenAI 兼容** ⚠️ 远程 | `openai-compat-asr` | 取决于服务器 | 当下通往 **Qwen3-ASR** 的路径(自托管服务器,无需等 transformers 支持)、任何 OpenAI 兼容的转录端点,或 OpenAI 官方 API——无需安装,在 **设置 → 引擎**(ASR 标签页)中配置并测试连接。音频会离开你的设备,发送到你指定的任何服务器;参见 [docs/engines/openai-compatible-asr.md](docs/engines/openai-compatible-asr.md)。 |
|
||||
|
||||
> Whisper 系列引擎覆盖约 100 种语言;**FunASR / SenseVoice** 额外提供一条多语言一体化路径,内置语音活动检测与行内说话人分离。**sherpa-onnx** 驱动实时听写的模型选择器——你边说,文字边出现。每个引擎都在本地设备上运行——无需 API 密钥,无需云端。
|
||||
> Whisper 系列引擎覆盖约 100 种语言;**FunASR / SenseVoice** 额外提供一条多语言一体化路径,内置语音活动检测与行内说话人分离。**sherpa-onnx** 驱动实时听写的模型选择器——你边说,文字边出现。除可选的 OpenAI 兼容远程客户端外,所有引擎都在本地设备上运行——无需 API 密钥,无需云端。
|
||||
|
||||
> **GPU 不支持高效 float16?** 在较老的 NVIDIA GPU(Maxwell/Pascal、GTX 16xx)上,或在 CTranslate2/cuDNN 版本不匹配之后,CTranslate2 系 ASR 引擎(WhisperX、Faster-Whisper)无法运行 `float16`,VoiceStudio 会自动改用 `int8` 重试——无需配置。如果转录仍然失败,可用 `ASR_COMPUTE_TYPE` 环境变量固定计算类型(逃生舱口):`ASR_COMPUTE_TYPE=int8`(CPU 用 `float32`)。将其设为 `int8` 并重启后端。
|
||||
|
||||
@@ -574,7 +581,7 @@ VoiceStudio 站在这些杰出开源工作的肩膀上:
|
||||
|
||||
## 🧰 来自同一作者的更多本地开源项目
|
||||
|
||||
喜欢这种本地优先的理念?它是一脉相承的——同一位作者,同一条准则:**你的数据只留在你的设备上。**
|
||||
喜欢这种本地优先的理念?它是一脉相承的——同一位作者,同一条准则:**你的数据只留在你的设备上。** 全部项目见 [palash.dev](https://palash.dev)。
|
||||
|
||||
<table>
|
||||
<tr>
|
||||
|
||||
@@ -157,6 +157,31 @@ def require_loopback(request: Request) -> None:
|
||||
raise HTTPException(status_code=403, detail="loopback origin required")
|
||||
|
||||
|
||||
def _admin_gate_403() -> None:
|
||||
"""Raise the admin-gate 403 with a detail that states what would ACTUALLY
|
||||
satisfy the gate. The bundled UI routes any 403 whose detail mentions
|
||||
"admin api key" to the API-key login form (frontend ``client.ts``; the
|
||||
literal contract is locked by ``tests/test_auth_gate_detail_lockstep.py``),
|
||||
so the wording must not name a key where presenting one cannot help.
|
||||
|
||||
The detail names the key only when the gate would accept one: server mode
|
||||
WITH an API key configured. Every other rejection — desktop mode (the
|
||||
credential checks in the callers only run under server mode) and a
|
||||
server-mode deployment with only a share PIN or nothing configured — keeps
|
||||
the plain loopback detail, because only loopback can use admin there.
|
||||
Naming the key in those cases would trap a LAN-share guest in a login
|
||||
form that can never succeed (#1213, #1525; PR #1569 review).
|
||||
"""
|
||||
raise HTTPException(
|
||||
status_code=403,
|
||||
detail=(
|
||||
"loopback origin or admin API key required"
|
||||
if _server_mode() and remote_api_key()
|
||||
else "loopback origin required"
|
||||
),
|
||||
)
|
||||
|
||||
|
||||
def require_admin(request: Request) -> None:
|
||||
"""Gate RCE/filesystem-capable admin routers.
|
||||
|
||||
@@ -180,7 +205,7 @@ def require_admin(request: Request) -> None:
|
||||
return
|
||||
if _request_presents_admin_credential(request):
|
||||
return
|
||||
raise HTTPException(status_code=403, detail="loopback origin or admin API key required")
|
||||
_admin_gate_403()
|
||||
|
||||
|
||||
def require_admin_action(request: Request) -> None:
|
||||
@@ -198,7 +223,7 @@ def require_admin_action(request: Request) -> None:
|
||||
side_effectful_get=True,
|
||||
):
|
||||
return
|
||||
raise HTTPException(status_code=403, detail="loopback origin or admin API key required")
|
||||
_admin_gate_403()
|
||||
|
||||
|
||||
def require_desktop(request: Request) -> None:
|
||||
|
||||
@@ -133,6 +133,83 @@ def set_torch_compile_disabled(body: _TorchCompileBody):
|
||||
return _torch_compile_state()
|
||||
|
||||
|
||||
# ── Compute-device override (Settings → Performance) ──────────────────────
|
||||
|
||||
|
||||
class _ComputeDeviceBody(BaseModel):
|
||||
value: str = Field(..., description="auto | cuda | rocm | xpu | mps | cpu")
|
||||
|
||||
|
||||
def _compute_device_state() -> dict:
|
||||
"""Everything the Performance panel needs to render the device control:
|
||||
the resolved pick (env > prefs > auto), what this process actually applied
|
||||
at probe time (differs after a change until restart — caps are immutable
|
||||
per process), what auto would pick, and which families exist here."""
|
||||
from core import device_caps
|
||||
|
||||
caps = device_caps.detect_host_caps()
|
||||
env_pin = (os.environ.get("OMNIVOICE_DEVICE") or "").strip().lower()
|
||||
auto_family = next(
|
||||
(f for f in ("cuda", "rocm", "xpu", "mps") if f in caps.available_families),
|
||||
"cpu",
|
||||
)
|
||||
value = device_caps.requested_device_override()
|
||||
return {
|
||||
"value": value,
|
||||
"applied": caps.requested_family,
|
||||
"restart_required": value != caps.requested_family,
|
||||
# The running process asked for a family it doesn't have (env pin on
|
||||
# the wrong machine, hardware removed): auto is in effect, and a
|
||||
# restart would not change that — the panel says so instead of
|
||||
# pretending the pick took.
|
||||
"override_ignored": (
|
||||
caps.requested_family not in ("auto", caps.family)
|
||||
),
|
||||
"effective_family": caps.family,
|
||||
"auto_family": auto_family,
|
||||
"available_families": list(caps.available_families),
|
||||
"env_pinned": env_pin in device_caps.DEVICE_OVERRIDE_CHOICES and env_pin != "",
|
||||
"choices": list(device_caps.DEVICE_OVERRIDE_CHOICES),
|
||||
}
|
||||
|
||||
|
||||
@router.get("/compute-device")
|
||||
def get_compute_device():
|
||||
"""Current compute-device override state (Settings → Performance)."""
|
||||
return _compute_device_state()
|
||||
|
||||
|
||||
@router.put("/compute-device")
|
||||
def set_compute_device(body: _ComputeDeviceBody):
|
||||
"""Persist the compute-device pick. Applied by the capability probe at
|
||||
the next backend start (host caps are immutable per process — same
|
||||
restart contract as the rest of the Performance tab). ``OMNIVOICE_DEVICE``
|
||||
always wins over this pick; the UI shows the pin instead of pretending."""
|
||||
from core import device_caps, prefs
|
||||
|
||||
value = (body.value or "").strip().lower()
|
||||
if value not in device_caps.DEVICE_OVERRIDE_CHOICES:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail=f"Unknown device '{value}'. Valid: {', '.join(device_caps.DEVICE_OVERRIDE_CHOICES)}",
|
||||
)
|
||||
caps = device_caps.detect_host_caps()
|
||||
if value not in ("auto", "cpu") and value not in caps.available_families:
|
||||
raise HTTPException(
|
||||
status_code=400,
|
||||
detail=(
|
||||
f"'{value}' is not available on this host "
|
||||
f"(have: {', '.join(caps.available_families)})"
|
||||
),
|
||||
)
|
||||
try:
|
||||
prefs.set_("compute_device", value)
|
||||
except Exception:
|
||||
logger.exception("set_compute_device failed")
|
||||
raise HTTPException(status_code=500, detail="Failed to persist setting")
|
||||
return _compute_device_state()
|
||||
|
||||
|
||||
# ── Generation-history retention (Studio takes rail) ──────────────────────
|
||||
|
||||
|
||||
|
||||
@@ -374,6 +374,33 @@ class HostCaps:
|
||||
probe_ok: bool = True
|
||||
"""``False`` only when torch could not be imported (degraded CPU-only)."""
|
||||
|
||||
requested_family: str = "auto"
|
||||
"""The user's compute-device override as requested — ``"auto"`` when none.
|
||||
``family`` reflects what was actually honored: an override that names a
|
||||
family this host doesn't have is noted and ignored, never obeyed blindly."""
|
||||
|
||||
|
||||
#: Every value the compute-device override accepts. "auto" = today's
|
||||
#: priority pick; "cpu" is always honorable (invariant: cpu is always
|
||||
#: available); accelerator names are honored only when detected.
|
||||
DEVICE_OVERRIDE_CHOICES: tuple[str, ...] = ("auto", "cuda", "rocm", "xpu", "mps", "cpu")
|
||||
|
||||
|
||||
def requested_device_override() -> str:
|
||||
"""The user's compute-device pick: ``OMNIVOICE_DEVICE`` env > the Settings
|
||||
choice (``compute_device`` in prefs.json) > ``"auto"``. Env wins so
|
||||
power-users can pin a device without the UI silently undoing it (same
|
||||
resolution order as engine selection, #981). Unknown values normalize to
|
||||
``"auto"`` — the probe must never raise."""
|
||||
try:
|
||||
from core import prefs
|
||||
|
||||
raw = prefs.resolve("compute_device", env="OMNIVOICE_DEVICE", default="auto")
|
||||
except Exception:
|
||||
raw = os.environ.get("OMNIVOICE_DEVICE", "auto")
|
||||
val = str(raw or "auto").strip().lower()
|
||||
return val if val in DEVICE_OVERRIDE_CHOICES else "auto"
|
||||
|
||||
|
||||
def _probe() -> HostCaps:
|
||||
"""Run the probe once. Enumerates every failure branch from the spec's
|
||||
@@ -386,6 +413,7 @@ def _probe() -> HostCaps:
|
||||
available_families=("cpu",),
|
||||
notes=("torch not importable; treating host as CPU-only",),
|
||||
probe_ok=False,
|
||||
requested_family=requested_device_override(),
|
||||
)
|
||||
|
||||
notes: list[str] = []
|
||||
@@ -507,6 +535,26 @@ def _probe() -> HostCaps:
|
||||
# available_families: every detected accelerator + cpu, deduped, cpu last.
|
||||
available: tuple[DeviceFamily, ...] = tuple(dict.fromkeys([*detected, "cpu"]))
|
||||
|
||||
# User override (Settings → Performance, or OMNIVOICE_DEVICE): honored
|
||||
# only when the named family actually exists on this host — an override
|
||||
# can steer, it cannot invent hardware. Applied here, at the single
|
||||
# choke point, so routing, model loads (get_best_device delegates its
|
||||
# family decision here), and every badge inherit it for free.
|
||||
requested = requested_device_override()
|
||||
if requested != "auto":
|
||||
if requested in available:
|
||||
if requested != family:
|
||||
notes.append(
|
||||
f"compute device pinned to '{requested}' by user override "
|
||||
f"(auto would pick '{family}')"
|
||||
)
|
||||
family = requested # type: ignore[assignment]
|
||||
else:
|
||||
notes.append(
|
||||
f"requested compute device '{requested}' is not available on "
|
||||
f"this host (have: {', '.join(available)}) — using '{family}'"
|
||||
)
|
||||
|
||||
return HostCaps(
|
||||
family=family,
|
||||
available_families=available,
|
||||
@@ -515,6 +563,7 @@ def _probe() -> HostCaps:
|
||||
driver=driver,
|
||||
notes=tuple(notes),
|
||||
probe_ok=True,
|
||||
requested_family=requested,
|
||||
)
|
||||
|
||||
|
||||
|
||||
@@ -17,6 +17,13 @@ _WINDOWS_RESERVED_NAMES = frozenset({"CON", "PRN", "AUX", "NUL"}) | frozenset(
|
||||
f"{prefix}{number}" for prefix in ("COM", "LPT") for number in range(1, 10)
|
||||
)
|
||||
|
||||
# Both separator families, so a stored sub-path splits into the same components
|
||||
# on every host. Windows accepts ``/`` as a real separator, so splitting on
|
||||
# ``os.sep`` alone left ``"job/out.mp4"`` as a single component there while the
|
||||
# identical value split cleanly on POSIX. POSIX input never reaches this with a
|
||||
# backslash — it is rejected as a foreign separator before the split.
|
||||
_PATH_SEPARATORS = re.compile(r"[\\/]")
|
||||
|
||||
|
||||
class UnsafePath(ValueError):
|
||||
"""Raised when a path crosses its allowed filesystem boundary."""
|
||||
@@ -52,11 +59,10 @@ def resolve_within(root: os.PathLike[str] | str, value: os.PathLike[str] | str)
|
||||
raw = os.fspath(value) if value is not None else ""
|
||||
if not isinstance(raw, str) or not raw:
|
||||
raise UnsafePath("path is empty")
|
||||
# Treat both separator families as structural on every host. Otherwise a
|
||||
# Windows traversal string is an innocent-looking filename when validated
|
||||
# on Linux (and can become dangerous after persisted data is moved).
|
||||
if os.sep != "\\" and ("\\" in raw or bool(ntpath.splitdrive(raw)[0])):
|
||||
raise UnsafePath("path uses a foreign separator or drive")
|
||||
# Treat both separator families as structural on every host while still
|
||||
# rejecting Windows drive paths before rebuilding relative components.
|
||||
if os.sep != "\\" and bool(ntpath.splitdrive(raw)[0]):
|
||||
raise UnsafePath("path uses a drive")
|
||||
root_path = Path(root).expanduser().resolve(strict=False)
|
||||
root_text = str(root_path)
|
||||
if os.path.isabs(raw):
|
||||
@@ -69,7 +75,7 @@ def resolve_within(root: os.PathLike[str] | str, value: os.PathLike[str] | str)
|
||||
# containment proof explicit to static analysis, this rejects empty,
|
||||
# dot, parent, drive, and separator-bearing components before Path sees
|
||||
# any persisted/request-derived string.
|
||||
parts = raw.split(os.sep)
|
||||
parts = _PATH_SEPARATORS.split(raw)
|
||||
clean_parts: list[str] = []
|
||||
for part in parts:
|
||||
clean = os.path.basename(part)
|
||||
|
||||
@@ -85,11 +85,27 @@ def _get_model():
|
||||
global _model
|
||||
if _model is None:
|
||||
from faster_whisper import WhisperModel
|
||||
name = os.environ.get("ASR_MODEL_FW", "large-v3")
|
||||
# Same weights as in-process faster-whisper: ASR_MODEL_FASTER selects
|
||||
# for BOTH variants, ASR_MODEL_FW stays as a sidecar-only override.
|
||||
# Before this, the sidecar read only ASR_MODEL_FW while the download
|
||||
# preflight read ASR_MODEL_FASTER — set one and the other variant (or
|
||||
# the preflight) quietly used a different model.
|
||||
name = (
|
||||
os.environ.get("ASR_MODEL_FW")
|
||||
or os.environ.get("ASR_MODEL_FASTER")
|
||||
or "large-v3"
|
||||
)
|
||||
try:
|
||||
import torch
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
# The probe honors the user compute-device override and the
|
||||
# ROCm/CT2 incompatibility (#1529) — the child must agree with
|
||||
# the parent's device decision, not re-derive its own.
|
||||
from core.device_caps import detect_host_caps
|
||||
device = "cuda" if detect_host_caps().family == "cuda" else "cpu"
|
||||
except Exception:
|
||||
# Fail SAFE: guessing "cuda" from torch here would bypass a cpu
|
||||
# override and hand CTranslate2 HIP-flavoured cuda on ROCm
|
||||
# (#1529). CPU always works; say why in the sidecar log.
|
||||
print("asr-sidecar: device probe failed — using cpu", file=sys.stderr, flush=True)
|
||||
device = "cpu"
|
||||
# Degrade fp16 → int8 rather than crash on GPUs without efficient fp16
|
||||
# (older Maxwell/Pascal, GTX 16xx, CTranslate2/cuDNN mismatch) (#551).
|
||||
|
||||
@@ -353,6 +353,9 @@ def _make_backend_class():
|
||||
display_name = "OmniVoice (GGUF, hardware-adaptive)"
|
||||
gpu_compat = ("cuda", "mps", "cpu")
|
||||
supports_voice_design = False
|
||||
# Every generate() spawns the external binary — allocations live in
|
||||
# that process, invisible to parent-side accelerator counters.
|
||||
runs_out_of_process = True
|
||||
|
||||
# 24 kHz mono Higgs Audio v2 — same as the in-process OmniVoice.
|
||||
_SAMPLE_RATE = 24_000
|
||||
|
||||
@@ -2325,7 +2325,7 @@ _INSTALL_HINTS: dict[str, str] = {
|
||||
"mac-ARM source installs since 0.3.22. Parakeet TDT v3 on the GPU via "
|
||||
"MLX: 25 European languages, word timestamps, ~2 GB unified memory.)"
|
||||
),
|
||||
"moonshine": "pip install useful-moonshine (edge/CPU-optimized ASR)",
|
||||
"moonshine": "uv pip install moonshine-onnx (or moonshine-voice; edge/CPU-optimized ASR)",
|
||||
"funasr": "pip install funasr (SenseVoiceSmall + FSMN-VAD; CUDA or CPU)",
|
||||
"sherpa-onnx-asr": "uv add sherpa-onnx (ONNX live dictation; CPU, cross-platform)",
|
||||
"openai-compat-asr": (
|
||||
@@ -2495,7 +2495,23 @@ def _ctranslate2_cuda_ok() -> bool:
|
||||
CUDA runtime version" — the #1529 report, an AMD RX 7900 XTX in the
|
||||
:rocm Docker image. Real CUDA only; ROCm hosts take the CPU path here
|
||||
(auto-detect prefers pytorch-whisper there, which does use HIP).
|
||||
|
||||
Also honors the user compute-device override (Settings → Performance /
|
||||
``OMNIVOICE_DEVICE``): a host pinned to cpu (or any non-cuda family)
|
||||
must not hand CTranslate2 a CUDA device — the probe applies the
|
||||
override, so gating on its family covers every CT2 loader at once.
|
||||
"""
|
||||
try:
|
||||
from core.device_caps import detect_host_caps
|
||||
|
||||
if detect_host_caps().family != "cuda":
|
||||
return False
|
||||
except Exception: # noqa: BLE001 — fail SAFE, not fast
|
||||
# Without a working probe we can't know whether an override or a
|
||||
# ROCm build is in play — guessing "cuda" from torch here is exactly
|
||||
# the #1529 crash. CPU always works.
|
||||
logger.warning("device probe failed — CTranslate2 taking the CPU path", exc_info=True)
|
||||
return False
|
||||
return _cuda_reported_available() and not _rocm_torch()
|
||||
|
||||
|
||||
@@ -3120,10 +3136,18 @@ def _offline_asr_repo(backend_id: str | None = None) -> str | None:
|
||||
bid = backend_id or active_backend_id()
|
||||
if bid == "whisperx":
|
||||
return _fw_repo(os.environ.get("ASR_MODEL_WHISPERX", "large-v3"))
|
||||
if bid in ("faster-whisper", "faster-whisper-isolated"):
|
||||
# The crash-isolated sidecar loads the SAME CT2 weights as in-process
|
||||
# faster-whisper (it reuses the ASR_MODEL_FASTER selection).
|
||||
if bid == "faster-whisper":
|
||||
return _fw_repo(os.environ.get("ASR_MODEL_FASTER", _FASTER_WHISPER_DEFAULT))
|
||||
if bid == "faster-whisper-isolated":
|
||||
# Mirror the sidecar's own resolution (_asr_sidecar/main.py):
|
||||
# ASR_MODEL_FW is a sidecar-only override, otherwise the shared
|
||||
# ASR_MODEL_FASTER selection applies — so the preflight can never
|
||||
# download a different repo than the sidecar will load.
|
||||
return _fw_repo(
|
||||
os.environ.get("ASR_MODEL_FW")
|
||||
or os.environ.get("ASR_MODEL_FASTER")
|
||||
or _FASTER_WHISPER_DEFAULT
|
||||
)
|
||||
if bid == "mlx-whisper":
|
||||
return os.environ.get("ASR_MODEL", _MLX_MODEL_DEFAULT)
|
||||
if bid == "parakeet-mlx":
|
||||
|
||||
@@ -57,6 +57,99 @@ def _force_compile_requested() -> bool:
|
||||
return value.strip().lower() in {"1", "true", "yes", "on"}
|
||||
|
||||
|
||||
# ── FlashInfer opt-in (upstream k2-fsa port) ────────────────────────────────
|
||||
# Explicit power-user opt-in, CUDA-only: OMNIVOICE_FLASHINFER=1 patches the
|
||||
# OmniVoice model with flashinfer packed attention (~2x per upstream's
|
||||
# benchmarks); =graph additionally captures CUDA graphs (best at batch=1).
|
||||
# Off by default — `flashinfer` is not a shipped dependency, and an
|
||||
# optimization must never be a point of failure. Session-sticky failure
|
||||
# latch mirrors torch.compile's (#278).
|
||||
_FLASHINFER_ENV = "OMNIVOICE_FLASHINFER"
|
||||
_flashinfer_runtime_failure: Optional[str] = None
|
||||
|
||||
|
||||
def flashinfer_mode() -> str:
|
||||
"""The user's ``OMNIVOICE_FLASHINFER`` request: 'off' | 'on' | 'graph'.
|
||||
|
||||
Unknown values normalize to 'off' with a log line naming the env var, so
|
||||
a typo degrades to the default path instead of half-applying.
|
||||
"""
|
||||
value = os.environ.get(_FLASHINFER_ENV, "").strip().lower()
|
||||
if value in {"", "0", "false", "no", "off"}:
|
||||
return "off"
|
||||
if value in {"1", "true", "yes", "on"}:
|
||||
return "on"
|
||||
if value == "graph":
|
||||
return "graph"
|
||||
logger.warning(
|
||||
"%s=%r not recognized (valid: 0, 1, graph) — FlashInfer stays off.",
|
||||
_FLASHINFER_ENV, value,
|
||||
)
|
||||
return "off"
|
||||
|
||||
|
||||
def should_flashinfer(device: str) -> str:
|
||||
"""Resolve the FlashInfer request against this host: 'off' | 'on' | 'graph'.
|
||||
|
||||
Requires all of: the ``OMNIVOICE_FLASHINFER`` opt-in, device == "cuda"
|
||||
(flashinfer is CUDA-only), the ``flashinfer`` package importable, and no
|
||||
earlier runtime failure this session. Every refusal is logged with the
|
||||
reason and the knob's name — the user asked for it, so silence would read
|
||||
as "the setting doesn't work".
|
||||
"""
|
||||
mode = flashinfer_mode()
|
||||
if mode == "off":
|
||||
return "off"
|
||||
if device != "cuda":
|
||||
logger.warning(
|
||||
"%s requested but the compute device is %r — FlashInfer is "
|
||||
"CUDA-only, continuing without it.", _FLASHINFER_ENV, device,
|
||||
)
|
||||
return "off"
|
||||
if importlib.util.find_spec("flashinfer") is None:
|
||||
logger.warning(
|
||||
"%s requested but the `flashinfer` package is not installed — "
|
||||
"continuing without it. Install with: uv pip install "
|
||||
"flashinfer-python flashinfer-jit-cache "
|
||||
"--extra-index-url https://flashinfer.ai/whl/cu128/ "
|
||||
"(pick the index matching your CUDA build).", _FLASHINFER_ENV,
|
||||
)
|
||||
return "off"
|
||||
if _flashinfer_runtime_failure is not None:
|
||||
logger.info(
|
||||
"FlashInfer skipped: failed earlier this session (%s) — using the "
|
||||
"standard path.", _flashinfer_runtime_failure,
|
||||
)
|
||||
return "off"
|
||||
return mode
|
||||
|
||||
|
||||
def mark_flashinfer_runtime_failure(reason: str) -> None:
|
||||
"""Latch a FlashInfer apply/runtime failure for the rest of the process,
|
||||
same contract as ``mark_compile_runtime_failure``."""
|
||||
global _flashinfer_runtime_failure
|
||||
try:
|
||||
# Import/kernel errors embed absolute paths (wheels under the user's
|
||||
# home) — redact before latching, since the reason is logged here and
|
||||
# re-logged on every later skip.
|
||||
from core.failure import sanitize
|
||||
|
||||
reason = sanitize(reason)
|
||||
except Exception:
|
||||
# Fail closed: if the redactor itself breaks, latching the raw text
|
||||
# would defeat the redaction. Keep only the exception class (the part
|
||||
# before ':' in our "Type: message" reasons) and drop the message.
|
||||
reason = (
|
||||
f"{(reason or '').split(':', 1)[0][:80]} "
|
||||
"(details redacted: sanitizer unavailable)"
|
||||
).strip()
|
||||
_flashinfer_runtime_failure = reason or "unknown FlashInfer runtime failure"
|
||||
logger.warning(
|
||||
"FlashInfer disabled for this session after a runtime failure: %s",
|
||||
_flashinfer_runtime_failure,
|
||||
)
|
||||
|
||||
|
||||
def _cuda_arch_supported_for_compile() -> "tuple[bool, str]":
|
||||
"""Check the GPU's architecture against this torch build's arch list.
|
||||
|
||||
|
||||
@@ -1376,6 +1376,122 @@ def _install_compile_fallback(_model) -> None:
|
||||
_model.generate = _generate_with_compile_fallback
|
||||
|
||||
|
||||
# ── FlashInfer runtime fallback (upstream k2-fsa port) ──────────────────────
|
||||
|
||||
|
||||
def _is_flashinfer_runtime_failure(exc: BaseException) -> bool:
|
||||
"""True when an exception originates in the FlashInfer fast path (the
|
||||
flashinfer package, our omnivoice_flashinfer patch module, or CUDA-graph
|
||||
capture/replay) rather than in the model or the request itself. Same
|
||||
chain/traceback walk as ``_is_compile_runtime_failure``."""
|
||||
import traceback as _tb
|
||||
|
||||
tb_markers = ("/flashinfer/", "omnivoice_flashinfer")
|
||||
msg_markers = ("flashinfer", "cuda graph", "cudagraph")
|
||||
seen: set[int] = set()
|
||||
cur: BaseException | None = exc
|
||||
while cur is not None and id(cur) not in seen:
|
||||
seen.add(id(cur))
|
||||
mod = type(cur).__module__ or ""
|
||||
if mod.startswith("flashinfer"):
|
||||
return True
|
||||
msg = str(cur).lower()
|
||||
if any(marker in msg for marker in msg_markers):
|
||||
return True
|
||||
try:
|
||||
for frame in _tb.extract_tb(cur.__traceback__):
|
||||
filename = (frame.filename or "").replace("\\", "/")
|
||||
if any(marker in filename for marker in tb_markers):
|
||||
return True
|
||||
except Exception:
|
||||
pass
|
||||
if cur.__cause__ is not None:
|
||||
cur = cur.__cause__
|
||||
elif not cur.__suppress_context__:
|
||||
cur = cur.__context__
|
||||
else:
|
||||
cur = None
|
||||
return False
|
||||
|
||||
|
||||
def _unapply_flashinfer(_model) -> None:
|
||||
"""Restore the standard execution path on a FlashInfer-patched model.
|
||||
|
||||
``apply_flashinfer`` works entirely through *instance-level* state —
|
||||
MethodType-bound ``forward``/``_generate_iterative`` overrides and
|
||||
``_fi_*`` attributes — so deleting those attributes restores the class
|
||||
implementations exactly. The attention implementation is restored to the
|
||||
one captured before apply (``_fi_orig_attn_impl`` — could be
|
||||
flash_attention_2, not just sdpa), and use_cache is re-enabled."""
|
||||
llm = getattr(_model, "llm", None)
|
||||
orig_attn = getattr(_model, "_fi_orig_attn_impl", None) or "sdpa"
|
||||
if llm is not None:
|
||||
for module in llm.modules():
|
||||
if "forward" in vars(module):
|
||||
del module.forward
|
||||
for attr in ("_fi_w_qkv", "_fi_qkv_split", "_fi_rope_theta", "_fi_w_gate_up"):
|
||||
if attr in vars(module):
|
||||
delattr(module, attr)
|
||||
try:
|
||||
llm.set_attn_implementation(orig_attn)
|
||||
except Exception:
|
||||
logger.exception(
|
||||
"failed to restore %s attention after FlashInfer", orig_attn
|
||||
)
|
||||
llm.config.use_cache = True
|
||||
for attr in (
|
||||
"_fi_orig_attn_impl",
|
||||
"_generate_iterative",
|
||||
"_fi_runner",
|
||||
"_fi_graph_cache",
|
||||
"_fi_enable_cuda_graph",
|
||||
"_fi_graph_buckets",
|
||||
"_fi_overhead_budget",
|
||||
):
|
||||
if attr in vars(_model):
|
||||
delattr(_model, attr)
|
||||
|
||||
|
||||
def _install_flashinfer_fallback(_model) -> None:
|
||||
"""Wrap ``model.generate`` so a FlashInfer failure at inference time falls
|
||||
back to the standard path instead of failing the generation — the same
|
||||
contract as ``_install_compile_fallback`` (#278): an optimization must
|
||||
never turn a working generation into an error."""
|
||||
orig_generate = _model.generate
|
||||
|
||||
def _generate_with_flashinfer_fallback(*args, **kwargs):
|
||||
try:
|
||||
return orig_generate(*args, **kwargs)
|
||||
except Exception as exc:
|
||||
if not _is_flashinfer_runtime_failure(exc):
|
||||
raise
|
||||
logger.warning(
|
||||
"FlashInfer runtime failure during generation (%s: %s) — "
|
||||
"restoring the standard path and disabling FlashInfer for "
|
||||
"this session. Generation is being retried without it.",
|
||||
type(exc).__name__, exc,
|
||||
)
|
||||
from services import engine_env
|
||||
engine_env.mark_flashinfer_runtime_failure(
|
||||
f"{type(exc).__name__}: {exc}"
|
||||
)
|
||||
# Unapply BEFORE exposing the eager path: while the teardown
|
||||
# mutates modules, _model.generate still routes through the
|
||||
# thread-affinity wrapper, so a concurrent render queues behind
|
||||
# this call instead of racing the half-restored model (Greptile,
|
||||
# #1565 round 2). Only a fully restored model is published.
|
||||
_unapply_flashinfer(_model)
|
||||
_model.generate = orig_generate
|
||||
try:
|
||||
return orig_generate(*args, **kwargs)
|
||||
except Exception as plain_exc:
|
||||
# `from None`: a genuine standard-path failure must not be
|
||||
# chained to — and misread as — the FlashInfer error.
|
||||
raise plain_exc from None
|
||||
|
||||
_model.generate = _generate_with_flashinfer_fallback
|
||||
|
||||
|
||||
# ── #315: thread affinity for cudagraph-compiled models ─────────────────────
|
||||
# `torch.compile(mode="reduce-overhead")` captures CUDA graphs, and captured
|
||||
# graph state is **thread-local** (torch/_inductor/cudagraph_trees keys its
|
||||
@@ -2117,6 +2233,57 @@ def _load_model_sync():
|
||||
"to stop preloading it alongside TTS."
|
||||
) from asr_exc
|
||||
|
||||
# FlashInfer opt-in (upstream k2-fsa port): packed CFG attention +
|
||||
# fused kernels, ~2x on upstream's benchmarks. Applied INSTEAD of
|
||||
# torch.compile — both rewrite the llm's execution and they do not
|
||||
# compose. Best-effort: any apply failure latches the session off and
|
||||
# the standard path continues untouched.
|
||||
flashinfer_applied = False
|
||||
try:
|
||||
from services.engine_env import (
|
||||
mark_flashinfer_runtime_failure,
|
||||
should_flashinfer,
|
||||
)
|
||||
|
||||
fi_mode = should_flashinfer(device)
|
||||
if fi_mode != "off":
|
||||
_set_loading("compiling", "Applying FlashInfer kernels…")
|
||||
try:
|
||||
from omnivoice.models.omnivoice_flashinfer import apply_flashinfer
|
||||
|
||||
# Captured BEFORE apply so unapply (either the failure
|
||||
# branch below or the generate-time fallback) restores
|
||||
# the true prior implementation.
|
||||
_model._fi_orig_attn_impl = getattr(
|
||||
_model.llm.config, "_attn_implementation", "sdpa"
|
||||
)
|
||||
apply_flashinfer(_model, enable_cuda_graph=(fi_mode == "graph"))
|
||||
except Exception as fi_exc: # noqa: BLE001 — perf opt, never fatal
|
||||
mark_flashinfer_runtime_failure(
|
||||
f"{type(fi_exc).__name__}: {fi_exc}"
|
||||
)
|
||||
# apply_flashinfer mutates the model as it goes — a
|
||||
# failure partway leaves half-patched modules that would
|
||||
# crash the next render (Greptile, #1565). Restore fully.
|
||||
_unapply_flashinfer(_model)
|
||||
else:
|
||||
flashinfer_applied = True
|
||||
_install_flashinfer_fallback(_model)
|
||||
# BOTH modes pin inference to one thread. Graph mode for
|
||||
# the #315 reason (captured CUDA-graph state is
|
||||
# thread-local); eager mode because the FlashInfer
|
||||
# attention wrapper and packed position ids are planned
|
||||
# per generation in module state — two _gpu_pool workers
|
||||
# interleaving plan() and run() would corrupt each
|
||||
# other's layout (CodeRabbit/Greptile, #1565).
|
||||
_install_compile_thread_affinity(_model)
|
||||
logger.info(
|
||||
"FlashInfer applied (mode=%s) — torch.compile skipped "
|
||||
"for this load.", fi_mode,
|
||||
)
|
||||
except Exception:
|
||||
logger.exception("FlashInfer opt-in check failed; continuing without")
|
||||
|
||||
try:
|
||||
# plan-02 (#65): gate on Triton availability (+ user setting), not
|
||||
# just device==cuda. Triton has no Windows wheel, so the old
|
||||
@@ -2124,7 +2291,7 @@ def _load_model_sync():
|
||||
# falls back to eager there.
|
||||
from services.engine_env import should_torch_compile
|
||||
|
||||
if should_torch_compile(device):
|
||||
if not flashinfer_applied and should_torch_compile(device):
|
||||
_set_loading("compiling", "Compiling model (torch.compile)…")
|
||||
try:
|
||||
_model.llm = torch.compile(_model.llm, mode=_TORCH_COMPILE_MODE)
|
||||
|
||||
@@ -363,6 +363,10 @@ class SubprocessBackend(TTSBackend):
|
||||
# A duck-typed marker survives that.
|
||||
_is_subprocess_isolated: bool = True
|
||||
|
||||
# Generation happens in the sidecar: parent-side accelerator counters
|
||||
# can't see its allocations (see TTSBackend.runs_out_of_process).
|
||||
runs_out_of_process: bool = True
|
||||
|
||||
# Default sample rate; subclasses override.
|
||||
_DEFAULT_SAMPLE_RATE = 24000
|
||||
|
||||
|
||||
+146
-14
@@ -300,6 +300,23 @@ class TTSBackend(ABC):
|
||||
#: 0 means "no meaningful floor" (CPU-class engines) and never warns.
|
||||
min_vram_gb: float = 0.0
|
||||
|
||||
#: True when generation allocates in ANOTHER process — a dedicated-venv
|
||||
#: sidecar (SubprocessBackend) or a spawned binary (omnivoice-gguf).
|
||||
#: Parent-process accelerator counters cannot see those allocations, so
|
||||
#: profilers/diagnostics must not attribute the parent's VRAM numbers to
|
||||
#: the engine. Duck-typed (attribute, not issubclass) for the same
|
||||
#: module-purge reason as `_is_subprocess_isolated`.
|
||||
runs_out_of_process: bool = False
|
||||
|
||||
def model_identity(self) -> Optional[str]:
|
||||
"""Which concrete model this backend would run, for adapter engines
|
||||
that host several very different models behind one backend id
|
||||
(mlx-audio, sherpa-onnx, cosyvoice). None means the engine id
|
||||
already names the model. Profilers and diagnostics use this to
|
||||
label results — without it, Kokoro-under-mlx and Dia-under-mlx
|
||||
rows are indistinguishable."""
|
||||
return None
|
||||
|
||||
@abstractmethod
|
||||
def generate(
|
||||
self,
|
||||
@@ -395,6 +412,95 @@ _PROMPT_CACHE_MAX = 8
|
||||
_prompt_cache: "OrderedDict[tuple, object]" = OrderedDict()
|
||||
_prompt_cache_lock = threading.Lock()
|
||||
|
||||
# Disk layer under the in-memory LRU (upstream k2-fsa VoiceClonePrompt.save/
|
||||
# load format). The in-memory cache dies with the process, so the first
|
||||
# generation of every session re-encodes each voice (~0.4 s + an ASR pass when
|
||||
# ref_text is missing). Encoded prompts are tiny (a (8, T) int token tensor +
|
||||
# transcript), so we persist them and reload across restarts. Keyed by the
|
||||
# same tuple as the memory cache — the ref file's mtime is inside the key, so
|
||||
# an edited reference never matches a stale file; stale files age out via the
|
||||
# mtime prune. Best-effort like the memory cache: any failure means "no disk
|
||||
# hit / no disk write", never a failed generation. OMNIVOICE_PROMPT_DISK_CACHE=0
|
||||
# disables the layer entirely.
|
||||
_PROMPT_DISK_CACHE_MAX = 32
|
||||
|
||||
|
||||
def _prompt_disk_dir():
|
||||
"""Return the prompt-cache directory (created on first use), or None when
|
||||
the layer is disabled or the directory can't be created."""
|
||||
if os.environ.get("OMNIVOICE_PROMPT_DISK_CACHE", "1") == "0":
|
||||
return None
|
||||
try:
|
||||
from core.config import DATA_DIR
|
||||
|
||||
path = os.path.join(str(DATA_DIR), "prompt_cache")
|
||||
os.makedirs(path, exist_ok=True)
|
||||
return path
|
||||
except Exception as e: # noqa: BLE001 — cache layer must never break synthesis
|
||||
logger.debug("prompt disk cache unavailable: %s", e)
|
||||
return None
|
||||
|
||||
|
||||
def _prompt_disk_path(cache_dir: str, key: tuple) -> str:
|
||||
import hashlib
|
||||
|
||||
digest = hashlib.sha256(repr(key).encode("utf-8")).hexdigest()[:32]
|
||||
return os.path.join(cache_dir, f"{digest}.pt")
|
||||
|
||||
|
||||
def _prompt_disk_load(key: tuple):
|
||||
"""Load a persisted prompt for ``key``, or None. Never raises."""
|
||||
cache_dir = _prompt_disk_dir()
|
||||
if cache_dir is None:
|
||||
return None
|
||||
path = _prompt_disk_path(cache_dir, key)
|
||||
if not os.path.exists(path):
|
||||
return None
|
||||
try:
|
||||
from omnivoice.models.omnivoice import VoiceClonePrompt
|
||||
|
||||
prompt = VoiceClonePrompt.load(path)
|
||||
# Freshen so the LRU prune (by mtime) keeps actively used voices.
|
||||
os.utime(path, None)
|
||||
return prompt
|
||||
except Exception as e: # noqa: BLE001
|
||||
logger.warning("failed to load cached voice prompt %s: %s", path, e)
|
||||
try:
|
||||
os.remove(path) # corrupt/incompatible file — don't retry it forever
|
||||
except OSError:
|
||||
pass
|
||||
return None
|
||||
|
||||
|
||||
def _prompt_disk_save(key: tuple, prompt) -> None:
|
||||
"""Persist ``prompt`` under ``key`` and prune old entries. Never raises."""
|
||||
cache_dir = _prompt_disk_dir()
|
||||
if cache_dir is None:
|
||||
return
|
||||
path = _prompt_disk_path(cache_dir, key)
|
||||
try:
|
||||
# Unique per write: two GPU-pool threads missing the same key must not
|
||||
# interleave writes into one tmp file (os.replace stays atomic).
|
||||
import uuid
|
||||
|
||||
tmp = f"{path}.tmp.{os.getpid()}.{uuid.uuid4().hex[:8]}"
|
||||
prompt.save(tmp)
|
||||
os.replace(tmp, path)
|
||||
except Exception as e: # noqa: BLE001
|
||||
logger.warning("failed to persist voice prompt to %s: %s", path, e)
|
||||
return
|
||||
try:
|
||||
entries = [
|
||||
os.path.join(cache_dir, f)
|
||||
for f in os.listdir(cache_dir)
|
||||
if f.endswith(".pt")
|
||||
]
|
||||
entries.sort(key=lambda p: os.path.getmtime(p), reverse=True)
|
||||
for old in entries[_PROMPT_DISK_CACHE_MAX:]:
|
||||
os.remove(old)
|
||||
except OSError as e:
|
||||
logger.debug("prompt disk cache prune skipped: %s", e)
|
||||
|
||||
|
||||
def _clone_prompt_key(ref_audio: str, ref_text, preprocess_prompt: bool = True):
|
||||
try:
|
||||
@@ -433,15 +539,24 @@ def _get_clone_prompt(
|
||||
if hit is not None:
|
||||
_prompt_cache.move_to_end(key)
|
||||
return hit
|
||||
try:
|
||||
# Encode outside the lock (slow). Mirrors exactly what generate() would
|
||||
# do inline for this ref (omnivoice.py:964-978), so output is identical.
|
||||
prompt = model.create_voice_clone_prompt(
|
||||
ref_audio, ref_text=ref_text, preprocess_prompt=preprocess_prompt
|
||||
)
|
||||
except Exception as e: # noqa: BLE001 — fall back, never break synthesis
|
||||
logger.warning("voice-clone prompt precompute failed; using inline ref: %s", e)
|
||||
return None
|
||||
# Memory miss → disk (survives restarts). A disk hit skips the encode AND
|
||||
# the ASR transcription pass a ref_text-less reference would trigger.
|
||||
prompt = _prompt_disk_load(key)
|
||||
if prompt is None:
|
||||
try:
|
||||
# Encode outside the lock (slow). Mirrors exactly what generate()
|
||||
# would do inline for this ref (omnivoice.py:964-978), so output is
|
||||
# identical.
|
||||
prompt = model.create_voice_clone_prompt(
|
||||
ref_audio, ref_text=ref_text, preprocess_prompt=preprocess_prompt
|
||||
)
|
||||
except Exception as e: # noqa: BLE001 — fall back, never break synthesis
|
||||
logger.warning(
|
||||
"voice-clone prompt precompute failed; using inline ref: %s", e
|
||||
)
|
||||
return None
|
||||
if store:
|
||||
_prompt_disk_save(key, prompt)
|
||||
if not store:
|
||||
return prompt
|
||||
with _prompt_cache_lock:
|
||||
@@ -1075,7 +1190,8 @@ class KittenTTSBackend(TTSBackend):
|
||||
- English only
|
||||
- Much faster + much smaller install
|
||||
|
||||
Preset voice is chosen via `extras["voice"]` (defaults to "Jasper"). Any
|
||||
Preset voice is chosen via `extras["voice"]` (defaults to DEFAULT_VOICE,
|
||||
"expr-voice-2-f"). Any
|
||||
`ref_audio` / `instruct` / `language` arg is ignored with a log line so
|
||||
the common call-site doesn't need to know which engine it's talking to.
|
||||
"""
|
||||
@@ -1384,6 +1500,9 @@ class MLXAudioBackend(TTSBackend):
|
||||
def sample_rate(self) -> int:
|
||||
return self._sr
|
||||
|
||||
def model_identity(self) -> Optional[str]:
|
||||
return self._model_id
|
||||
|
||||
@property
|
||||
def supported_languages(self) -> list[str]:
|
||||
# Per-model; Kokoro supports 8, Qwen3 ~4, Kugel 24. Return "multi"
|
||||
@@ -1571,6 +1690,18 @@ class CosyVoiceBackend(TTSBackend):
|
||||
def supported_languages(self) -> list[str]:
|
||||
return ["zh", "en", "ja", "ko", "yue", "de", "es", "fr", "it", "ru"]
|
||||
|
||||
@staticmethod
|
||||
def _resolved_model_dir() -> str:
|
||||
return os.environ.get(
|
||||
"OMNIVOICE_COSYVOICE_MODEL",
|
||||
"pretrained_models/Fun-CosyVoice3-0.5B",
|
||||
)
|
||||
|
||||
def model_identity(self) -> Optional[str]:
|
||||
# v1/v2/v3 all live behind the one "cosyvoice" id — the directory
|
||||
# basename is the only thing that tells the models apart.
|
||||
return os.path.basename(os.path.normpath(self._resolved_model_dir()))
|
||||
|
||||
def _ensure_loaded(self):
|
||||
if self._model is not None:
|
||||
return
|
||||
@@ -1578,10 +1709,7 @@ class CosyVoiceBackend(TTSBackend):
|
||||
if not ok:
|
||||
raise RuntimeError(f"CosyVoice unavailable: {msg}")
|
||||
from cosyvoice.cli.cosyvoice import AutoModel # type: ignore[import-not-found]
|
||||
model_dir = os.environ.get(
|
||||
"OMNIVOICE_COSYVOICE_MODEL",
|
||||
"pretrained_models/Fun-CosyVoice3-0.5B",
|
||||
)
|
||||
model_dir = self._resolved_model_dir()
|
||||
logger.info("Loading CosyVoice from %s", model_dir)
|
||||
self._model = AutoModel(model_dir=model_dir)
|
||||
|
||||
@@ -1814,6 +1942,10 @@ class SherpaOnnxBackend(TTSBackend):
|
||||
self._tts = None
|
||||
self._model_dir = os.environ.get("OMNIVOICE_SHERPA_MODEL", "")
|
||||
|
||||
def model_identity(self) -> Optional[str]:
|
||||
model_dir = (self._model_dir or "").strip()
|
||||
return os.path.basename(os.path.normpath(model_dir)) if model_dir else None
|
||||
|
||||
@classmethod
|
||||
def is_available(cls) -> tuple[bool, str]:
|
||||
try:
|
||||
|
||||
@@ -125,6 +125,16 @@ def test_faster_whisper_float16_unsupported_falls_back_to_int8(monkeypatch):
|
||||
)
|
||||
monkeypatch.setitem(sys.modules, "torch", fake_torch)
|
||||
|
||||
# The compute-device override gate consults the capability probe before
|
||||
# the torch mock above — pin it to a CUDA family so the fallback chain
|
||||
# under test is reachable on a cpu-only CI host.
|
||||
from core.device_caps import HostCaps
|
||||
|
||||
monkeypatch.setattr(
|
||||
"core.device_caps.detect_host_caps",
|
||||
lambda: HostCaps(family="cuda", available_families=("cuda", "cpu")),
|
||||
)
|
||||
|
||||
be = FasterWhisperBackend()
|
||||
be._ensure_model()
|
||||
|
||||
|
||||
+40
-15
@@ -460,30 +460,55 @@ class TaskExecutor:
|
||||
|
||||
@staticmethod
|
||||
def _synthesize(backend, text: str, params: dict):
|
||||
"""Call the engine through the same serial GPU gate local jobs use.
|
||||
"""Render through the same seeded pipeline as local ``/generate``.
|
||||
|
||||
Held against the idle sweep for the duration: a long generation touches
|
||||
the instance cache once, at the start, so on elapsed time alone it is
|
||||
indistinguishable from a model nobody wants any more.
|
||||
|
||||
Do not reduce this to ``backend.generate()``. The control plane sends
|
||||
a complete render contract (pinned gallery seed, synthetic reference,
|
||||
quality controls, chunking, effects); calling the adapter directly
|
||||
silently turns a selected gallery voice into a fresh random take.
|
||||
"""
|
||||
from services import tts_backend # noqa: PLC0415
|
||||
from api.routers.generation import _run_backend_inference, _run_inference # noqa: PLC0415
|
||||
|
||||
kwargs = {
|
||||
key: params[key]
|
||||
for key in (
|
||||
"ref_audio",
|
||||
"ref_text",
|
||||
"instruct",
|
||||
"language",
|
||||
"duration",
|
||||
"description",
|
||||
"speed",
|
||||
)
|
||||
if params.get(key) is not None
|
||||
}
|
||||
language = params.get("language")
|
||||
ref_audio = params.get("ref_audio")
|
||||
ref_text = params.get("ref_text")
|
||||
instruct = params.get("instruct")
|
||||
duration = params.get("duration")
|
||||
num_step = params.get("num_step", 16)
|
||||
guidance_scale = params.get("guidance_scale", 2.0)
|
||||
speed = params.get("speed", 1.0)
|
||||
denoise = params.get("denoise", True)
|
||||
postprocess_output = params.get("postprocess_output", True)
|
||||
used_seed = params.get("seed")
|
||||
effect_preset = params.get("effect_preset", "broadcast")
|
||||
max_chunk_chars = params.get("max_chunk_chars")
|
||||
crossfade_ms = params.get("crossfade_ms")
|
||||
try:
|
||||
with tts_backend.engine_in_use(backend):
|
||||
return backend.generate(text, **kwargs)
|
||||
if isinstance(backend, tts_backend.OmniVoiceBackend):
|
||||
# The OSS default engine has an extended native surface;
|
||||
# preserving it is required for a gallery preview and a
|
||||
# GPU-worker take to share the same voice identity.
|
||||
return _run_inference(
|
||||
backend._model, text, language, ref_audio, ref_text,
|
||||
instruct, duration, num_step, guidance_scale, speed,
|
||||
params.get("t_shift"), denoise, postprocess_output,
|
||||
params.get("layer_penalty_factor"),
|
||||
params.get("position_temperature"),
|
||||
params.get("class_temperature"), used_seed,
|
||||
effect_preset, max_chunk_chars, crossfade_ms,
|
||||
)
|
||||
return _run_backend_inference(
|
||||
backend, text, language, ref_audio, ref_text, instruct,
|
||||
duration, num_step, guidance_scale, speed, denoise,
|
||||
postprocess_output, used_seed, effect_preset,
|
||||
max_chunk_chars, crossfade_ms,
|
||||
)
|
||||
except Exception as exc:
|
||||
from worker import errors as worker_errors # noqa: PLC0415
|
||||
|
||||
|
||||
@@ -57,6 +57,10 @@ REQUIRED_FEATURES = frozenset({
|
||||
"task_progress_v1",
|
||||
"task_inputs_v1",
|
||||
"remote_model_download_v1",
|
||||
# A generic backend.generate() call accepts the same wire shape but drops
|
||||
# profile conditioning controls. Require the canonical worker render path
|
||||
# so an older peer cannot successfully return a different voice.
|
||||
"remote_tts_render_v1",
|
||||
})
|
||||
|
||||
|
||||
|
||||
@@ -1,7 +1,7 @@
|
||||
# VoiceStudio
|
||||
|
||||
**The open-source ElevenLabs alternative.** Real-time dictation, zero-shot voice
|
||||
cloning, and cinematic video dubbing — fully local, no API keys, no accounts.
|
||||
cloning, and cinematic video dubbing — fully local, with no cloud API keys or accounts.
|
||||
**646 languages.**
|
||||
|
||||
[](https://hub.docker.com/r/palashdeb/omnivoice-studio)
|
||||
@@ -30,6 +30,14 @@ weights + cache (20 GB+ comfortable), and optionally a GPU — 4 GB VRAM works
|
||||
the entire pipeline runs on CPU, just slower. Pull size: ~5 GB compressed
|
||||
(CUDA/CPU image), ~15 GB for the `:rocm` variant.
|
||||
|
||||
## See it in action
|
||||
|
||||
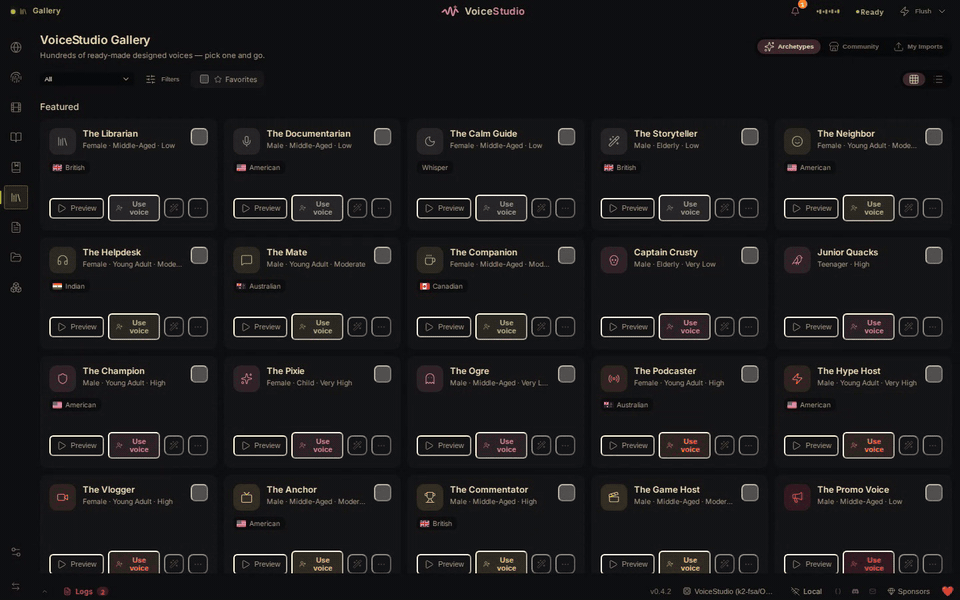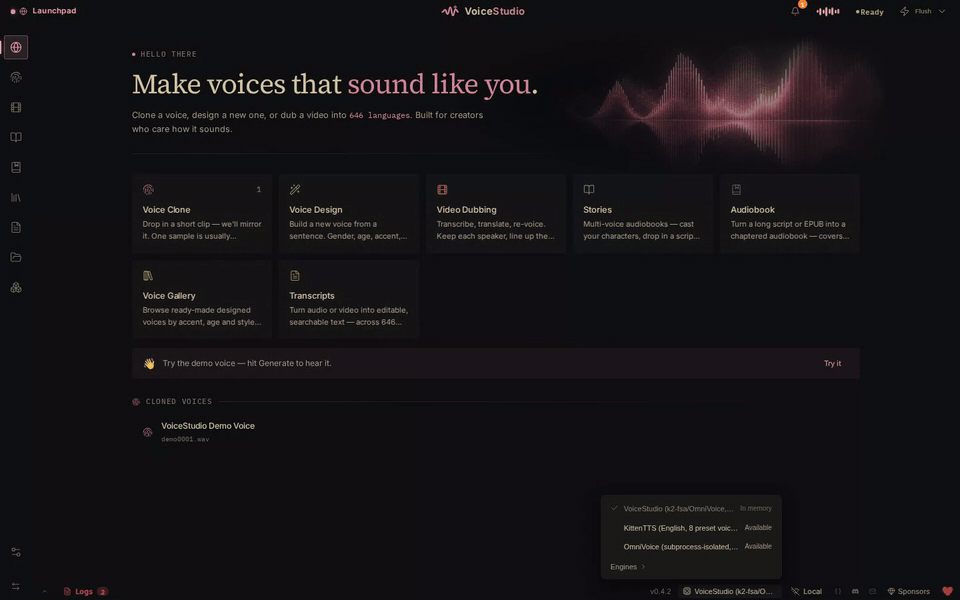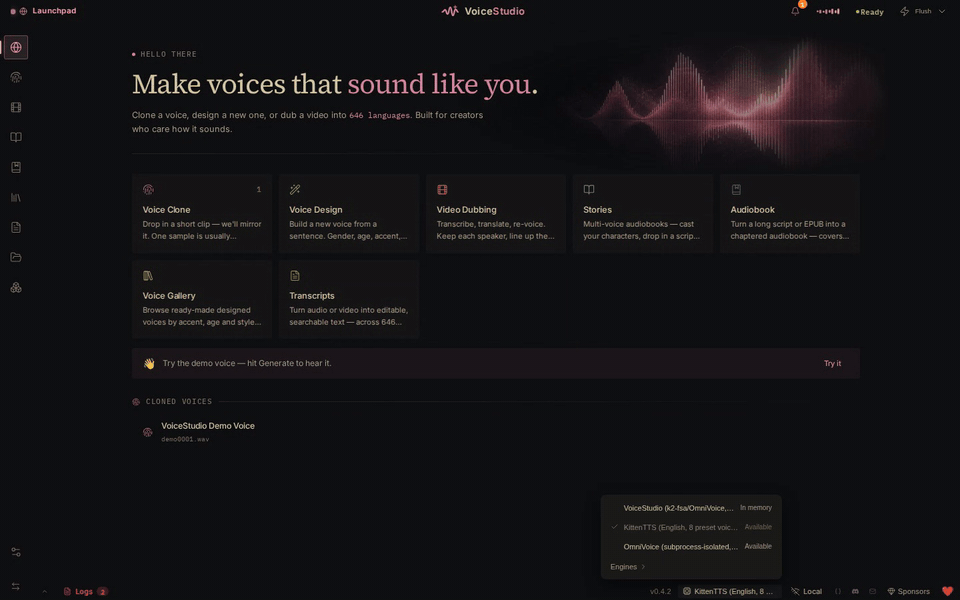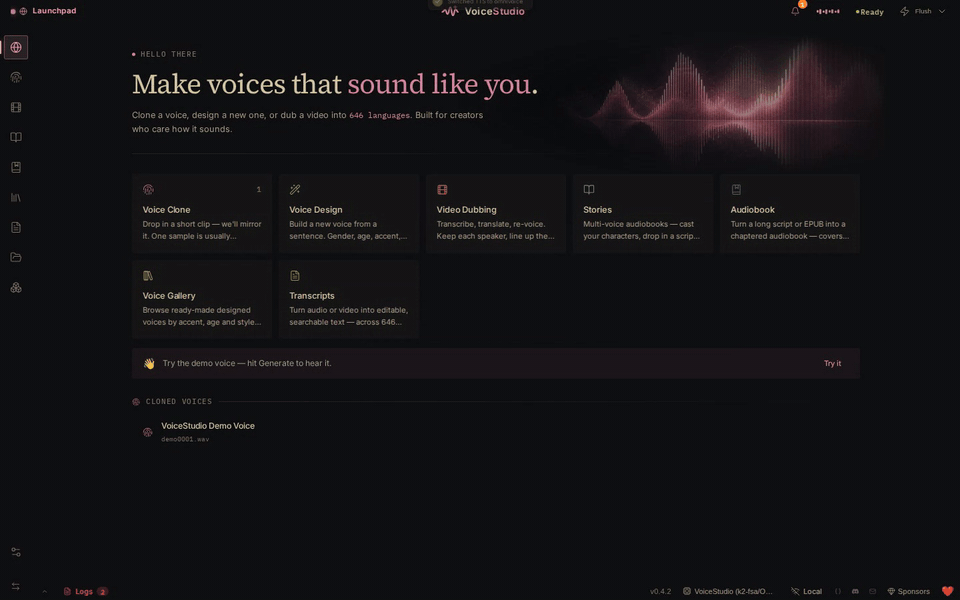
|
||||
|
||||
| Model catalogue | Save a gallery voice |
|
||||
|---|---|
|
||||
| 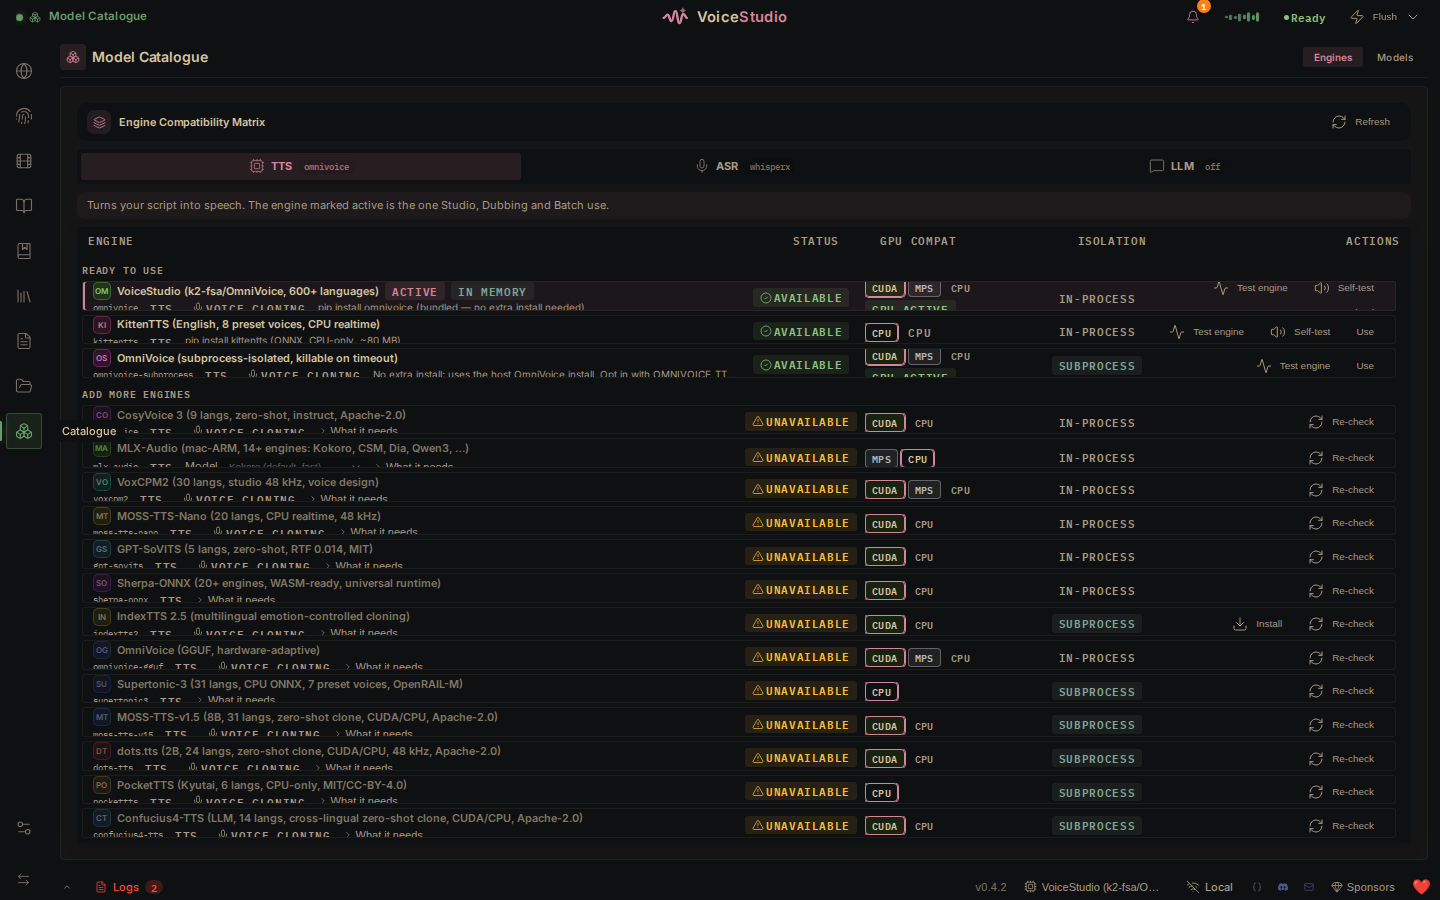 | 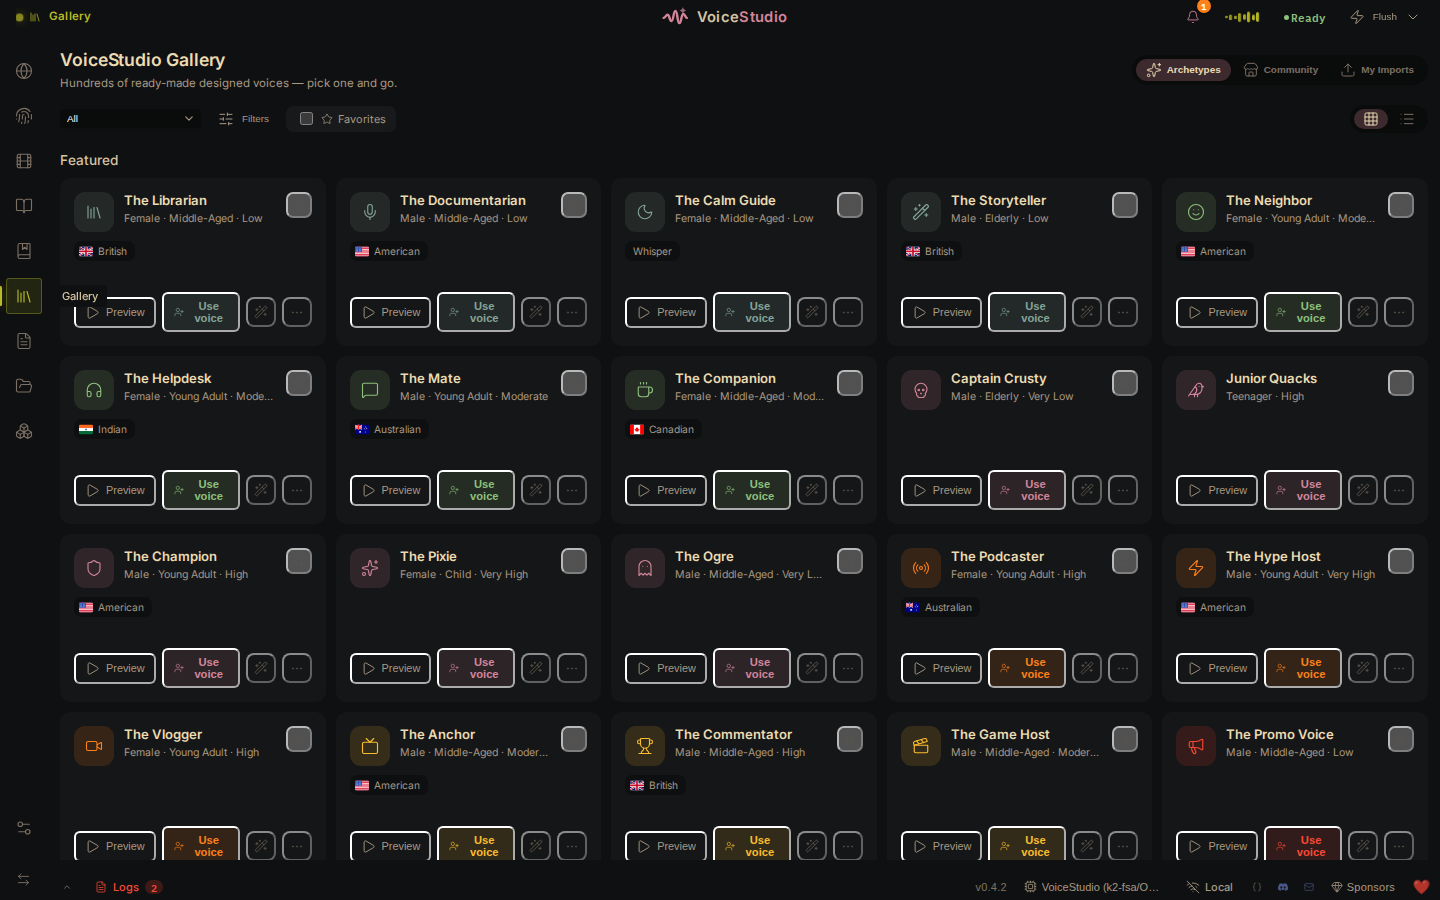 |
|
||||
|
||||
---
|
||||
|
||||
## Quick start (CPU)
|
||||
@@ -90,12 +98,12 @@ There's also a Compose file in the repo with `cpu` / `gpu` / `rocm` profiles
|
||||
|-----|--------------|
|
||||
| `:latest` | **Rolling preview** — latest commit on `main`, at or ahead of the last release. This is the preview channel; pin `:stable` for production. |
|
||||
| `:stable` | Most recent versioned release (updated on every `v*` git tag) |
|
||||
| `:0.4.1` | Exact release version |
|
||||
| `:0.4` | Latest patch within the `0.4` minor |
|
||||
| `:0.5.0` | Exact release version |
|
||||
| `:0.5` | Latest patch within the `0.5` minor |
|
||||
| `:main` | Alias of the same rolling `main` build as `:latest` |
|
||||
| `:sha-xxxxxxx` | A specific commit (produced by manual workflow dispatch) |
|
||||
| `:rocm` | **AMD GPU (ROCm) build** of the rolling preview — the ROCm analogue of `:latest` |
|
||||
| `:stable-rocm`, `:0.4.1-rocm`, `:0.4-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding tags above |
|
||||
| `:stable-rocm`, `:0.5.0-rocm`, `:0.5-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding tags above |
|
||||
|
||||
Preview builds always come from `main` and never version-sort below `:stable`,
|
||||
so upgrades flow naturally. The same images and tags
|
||||
@@ -143,11 +151,17 @@ more), auto-detected and selectable in Settings.
|
||||
- The image ships with `OMNIVOICE_SERVER_MODE=1`, which relaxes the desktop-only
|
||||
loopback-origin gate so the admin UI works through Docker's NAT. Set it to `0`
|
||||
if you front the container with your own loopback auth proxy.
|
||||
- For LAN or internet-facing deployments, set a long random
|
||||
`OMNIVOICE_API_KEY` and pass the same key through the browser's login prompt.
|
||||
A six-digit share PIN is also available for casual LAN access, but it does
|
||||
not authorize administration or dictation; see the
|
||||
[API authentication guide](https://github.com/debpalash/VoiceStudio/blob/main/docs/api-auth.md).
|
||||
|
||||
> **Security:** VoiceStudio ships **no authentication**. Anything that can reach the
|
||||
> URL can use the app. Before exposing it beyond localhost, put it behind a
|
||||
> reverse proxy with auth (Caddy `basic_auth`, nginx + htpasswd) or a private
|
||||
> overlay (Tailscale, ZeroTier).
|
||||
> **Security:** Loopback-only publishing is the safe default. Before exposing
|
||||
> VoiceStudio on a trusted LAN, configure `OMNIVOICE_API_KEY`. On any untrusted
|
||||
> network, plain HTTP is not safe for the API key or session cookie. Keep the
|
||||
> backend on an encrypted private overlay such as Tailscale/ZeroTier; do not
|
||||
> expose it directly to the public internet.
|
||||
|
||||
---
|
||||
|
||||
|
||||
+1
-1
@@ -342,7 +342,7 @@ arbitrary path merely because it ends in `/ws/events` or `/ws/transcribe`.
|
||||
| Code | Meaning | What to do |
|
||||
|---|---|---|
|
||||
| **401** | Consumption auth failed — `{"detail": "PIN required"}` or `{"detail": "API key required"}`. | Supply the PIN / key (header, cookie, or query param above). A WebSocket surfaces this as close code **1008**. |
|
||||
| **403** | Authorization failed: loopback/native access was required, cookie Origin/CSRF validation failed, a server-mode mutation lacked an admin credential, or a native path capability was invalid/expired. | A PIN cannot grant admin or filesystem access. Re-authenticate the UI; scripts should use the API-key header; run native operations from the desktop app. |
|
||||
| **403** | Authorization failed: loopback/native access was required, cookie Origin/CSRF validation failed, a server-mode mutation lacked an admin credential, or a native path capability was invalid/expired. | A PIN cannot grant admin or filesystem access. Re-authenticate the UI; scripts should use the API-key header; run native operations from the desktop app. The admin gate names the key only when one can satisfy it: server mode with `OMNIVOICE_API_KEY` configured answers `{"detail": "loopback origin or admin API key required"}` (the bundled UI routes it to the API-key login form); PIN-only/no-key server mode and the desktop build answer `{"detail": "loopback origin required"}` (only loopback can satisfy the gate). |
|
||||
| **429** | A failed administrator-session exchange exceeded its per-client limit, the GPU pool is saturated, or a model download is rate-limited. Ships with `Retry-After`; workload throttles also carry `X-VoiceStudio-Retryable: true`. | Back off for `Retry-After` seconds. For authentication, verify the master before retrying; a correct master is never locked out. |
|
||||
|
||||
---
|
||||
|
||||
@@ -0,0 +1,56 @@
|
||||
# Benchmarks
|
||||
|
||||
Measured numbers per engine and device — how long a generation actually
|
||||
takes on real hardware. Every number here is produced by the in-repo
|
||||
harness, on named hardware, at a named version; nothing is estimated.
|
||||
|
||||
## How numbers are measured
|
||||
|
||||
```bash
|
||||
# stop the app first — a running backend holds a model and skews numbers
|
||||
uv run python scripts/bench_pipeline.py # everything
|
||||
uv run python scripts/bench_pipeline.py tts # just the TTS stage
|
||||
```
|
||||
|
||||
`scripts/bench_pipeline.py` profiles each pipeline stage one at a time,
|
||||
memory-safely: it refuses to start a stage without enough free RAM and
|
||||
unloads models between stages. See [performance.md](performance.md) for
|
||||
what each stage spends its time on.
|
||||
|
||||
The `tts` stage emits the two values this table collects:
|
||||
|
||||
- **RTF** (real-time factor) — seconds of compute per second of generated
|
||||
audio, printed next to each warm measurement. RTF < 1 means faster than
|
||||
real time. Use the **short line (warm)** RTF for the table.
|
||||
- **Peak VRAM** — printed on CUDA only. MPS is unified memory and CPU has
|
||||
no VRAM; subprocess-isolated engines allocate outside the harness's view
|
||||
(it prints `n/a` for them). Leave the column blank in all those cases.
|
||||
|
||||
## Results
|
||||
|
||||
No verified rows yet — this table fills from maintainer runs and community
|
||||
submissions.
|
||||
|
||||
| Engine | Device | RTF (warm) | Peak VRAM (GB) | App version | Source |
|
||||
|---|---|---|---|---|---|
|
||||
| _none yet — contribute yours below_ | | | | | |
|
||||
|
||||
Column meanings: **Engine** — the TTS engine the harness resolved (printed
|
||||
at stage start). **Device** — one string naming what ran the model, e.g.
|
||||
`RTX 3060 12 GB`, `Apple M2 Pro`, `Ryzen 7 5800X (CPU)`. **RTF (warm)** —
|
||||
the short-line warm RTF from the harness. **Peak VRAM** — the harness's
|
||||
CUDA peak, blank on MPS/CPU. **App version** — from `Settings → About`.
|
||||
**Source** — a link to the PR that added the row.
|
||||
|
||||
## Contributing a row
|
||||
|
||||
1. Run the harness on an otherwise-idle machine (app stopped) and copy its
|
||||
summary table.
|
||||
2. Open a PR adding one row using the column meanings above, and paste the
|
||||
raw harness output into the PR description — that PR link becomes the
|
||||
row's **Source**.
|
||||
3. One row per engine+device pair; a newer app version replaces the old row.
|
||||
|
||||
Numbers from different machines aren't directly comparable — that's fine.
|
||||
The point is honest expectations ("this engine on this class of GPU ≈ this
|
||||
fast"), not a leaderboard.
|
||||
@@ -0,0 +1,61 @@
|
||||
# Engine guides
|
||||
|
||||
One page per engine: what it's for, what it needs, how to enable it, and its
|
||||
quirks. Select engines in **Model Catalogue → Engines** (or quick-switch with
|
||||
<kbd>Ctrl</kbd>/<kbd>Cmd</kbd>+<kbd>E</kbd>), or pin one with
|
||||
`OMNIVOICE_TTS_BACKEND` / `OMNIVOICE_ASR_BACKEND`.
|
||||
|
||||
The compute device (CUDA/ROCm/MPS/CPU) is auto-detected; pin it under
|
||||
**Settings → Performance & Device** (or `OMNIVOICE_DEVICE`) if auto-detect
|
||||
picks wrong — see [performance](../performance.md).
|
||||
|
||||
Measured speed/VRAM numbers live in [benchmarks](../benchmarks.md); what each
|
||||
engine can do expressively in [expressive-speech](../expressive-speech.md);
|
||||
sidecar disk footprints in [disk-usage](disk-usage.md); the bar a new engine
|
||||
must clear in [engine-acceptance](../engine-acceptance.md).
|
||||
|
||||
New to VoiceStudio? Install the app first — [macOS](../install/macos.md)
|
||||
(first launch needs the one-time right-click → **Open** Gatekeeper
|
||||
approval), [Windows](../install/windows.md), [Linux](../install/linux.md),
|
||||
[Docker](../install/docker.md).
|
||||
|
||||
## Text-to-speech
|
||||
|
||||
| Engine | Guide | Runs on | Cloning | Enabled by |
|
||||
|---|---|---|---|---|
|
||||
| VoiceStudio (OmniVoice) — **default** | [omnivoice](omnivoice.md) | CUDA · MPS · CPU | ✅ | installed by default |
|
||||
| VoxCPM2 | [voxcpm2](voxcpm2.md) | CUDA · MPS · CPU | ✅ + voice design | `pip install "voxcpm>=2.0.3"` |
|
||||
| MOSS-TTS-Nano | [moss-tts-nano](moss-tts-nano.md) | CUDA · CPU | ✅ (ref only) | clone + `uv pip install -e .` |
|
||||
| KittenTTS | [kittentts](kittentts.md) | CPU | — (8 preset voices) | `pip install kittentts` |
|
||||
| MLX-Audio (Kokoro, CSM, Dia, …) | [mlx-audio](mlx-audio.md) | Apple Silicon | model-dependent | `pip install mlx-audio` |
|
||||
| CosyVoice 3 | [cosyvoice](cosyvoice.md) | CUDA · CPU | ✅ | clone + requirements |
|
||||
| GPT-SoVITS | [gpt-sovits](gpt-sovits.md) | external server | ✅ | its own API server |
|
||||
| Sherpa-ONNX | [sherpa-onnx](sherpa-onnx.md) | CUDA · CPU | — | `pip install sherpa-onnx` + model dir |
|
||||
| IndexTTS 2.5 | [indextts](indextts.md) | CUDA · CPU | ✅ + emotion | one-click sidecar install |
|
||||
| OmniVoice GGUF | [omnivoice-gguf](omnivoice-gguf.md) | CUDA · MPS · CPU | ✅ | bundled binary |
|
||||
| Supertonic-3 | [supertonic3](supertonic3.md) | CPU | — (7 preset voices) | `uv sync --extra supertonic` + license |
|
||||
| MOSS-TTS-v1.5 (8B) | [moss-tts-v15](moss-tts-v15.md) | CUDA · CPU | ✅ | clone + env var |
|
||||
| dots.tts (2B) | [dots-tts](dots-tts.md) | CUDA · CPU (not Windows) | ✅ | clone + env var |
|
||||
| OmniVoice (subprocess) | [omnivoice-subprocess](omnivoice-subprocess.md) | CUDA · MPS · CPU | ✅ | opt-in pick, no install |
|
||||
| PocketTTS (Kyutai) | [pockettts](pockettts.md) | CPU (not Intel Mac) | ✅ | `uv sync --extra pockettts` + license |
|
||||
| Confucius4-TTS | [confucius4-tts](confucius4-tts.md) | CUDA · CPU | ✅ | clone + env var |
|
||||
|
||||
## Speech-to-text
|
||||
|
||||
| Engine | Guide | Runs on | Best at | Enabled by |
|
||||
|---|---|---|---|---|
|
||||
| WhisperX | [whisperx](whisperx.md) | CUDA · CPU | dubbing (word timestamps + diarization) | installed by default |
|
||||
| Faster-Whisper | [faster-whisper](faster-whisper.md) | CUDA · CPU | general transcription | installed by default |
|
||||
| Faster-Whisper (isolated) | [faster-whisper-isolated](faster-whisper-isolated.md) | CUDA · CPU | unattended batches | opt-in pick |
|
||||
| MLX Whisper | [mlx-whisper](mlx-whisper.md) | Apple Silicon | Mac default | `pip install mlx-whisper` |
|
||||
| PyTorch Whisper | [pytorch-whisper](pytorch-whisper.md) | CUDA · MPS · CPU | ROCm hosts | installed by default |
|
||||
| Parakeet TDT (NeMo) | [nemo-parakeet](nemo-parakeet.md) | CUDA · CPU | 25 languages, fast CPU | separate venv (never the app's) |
|
||||
| Parakeet TDT (MLX) | [parakeet-mlx](parakeet-mlx.md) | Apple Silicon | dictation, 25 EU languages | default on mac-ARM source installs |
|
||||
| Moonshine | [moonshine](moonshine.md) | CPU | edge/low-power, no timestamps | `pip install` (see guide) |
|
||||
| FunASR (SenseVoice) | [funasr](funasr.md) | CUDA · CPU | 50+ languages, inline diarization | `pip install funasr` |
|
||||
| Sherpa-ONNX dictation | [sherpa-onnx-asr](sherpa-onnx-asr.md) | CPU | live streaming dictation | curated model download |
|
||||
| OpenAI-compatible (remote) | [openai-compatible-asr](openai-compatible-asr.md) | network | offloading to a server (audio leaves the machine) | Model Catalogue |
|
||||
|
||||
Speaker diarization is not an engine registry of its own — the dub pipeline
|
||||
uses pyannote (HF-gated; see [diarization](../features/diarization.md)) and
|
||||
FunASR can diarize inline with its `cam++` speaker model.
|
||||
@@ -0,0 +1,61 @@
|
||||
# VoiceStudio — Faster-Whisper (Crash-Isolated) Engine
|
||||
|
||||
The same CTranslate2 Whisper engine as [faster-whisper](faster-whisper.md),
|
||||
run in a **separate child process** ("sidecar"). CTranslate2's GPU teardown
|
||||
can segfault — the endemic faster-whisper crash — and a hung or crashed
|
||||
transcribe in-process takes the whole backend down with it. Isolated, the
|
||||
child can crash or be force-killed to reclaim a hung transcribe and its VRAM
|
||||
while the backend stays up
|
||||
([#730](https://github.com/debpalash/VoiceStudio/issues/730)).
|
||||
|
||||
There is nothing extra to install: the sidecar reuses the app's own venv —
|
||||
only the process boundary is new.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the crash-isolated row, or
|
||||
- pin it with `OMNIVOICE_ASR_BACKEND=faster-whisper-isolated`.
|
||||
|
||||
It is never picked by auto-detect — it's an explicit opt-in escape hatch.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Long batch runs** where one bad file must not kill the backend.
|
||||
- Machines where in-process faster-whisper has crashed or hung before:
|
||||
a sidecar crash fails only that job, and the next transcribe respawns a
|
||||
fresh sidecar automatically.
|
||||
|
||||
## Platform support
|
||||
|
||||
Same as faster-whisper: CUDA float16 or CPU int8 on macOS, Windows, and
|
||||
Linux. The sidecar picks cuda/cpu itself and walks the same
|
||||
float16 → int8_float16 → int8 degrade chain on GPUs without efficient fp16
|
||||
([#551](https://github.com/debpalash/VoiceStudio/issues/551)).
|
||||
|
||||
## Model selection
|
||||
|
||||
- `ASR_MODEL_FASTER` — the shared model selection, same as the in-process
|
||||
engine: set it once and both variants load the same weights.
|
||||
- `ASR_MODEL_FW` — optional sidecar-only override; when set it wins over
|
||||
`ASR_MODEL_FASTER` for this engine. Default `large-v3`.
|
||||
- `ASR_COMPUTE_TYPE` — optional: pin the sidecar to one CTranslate2 compute
|
||||
type instead of the automatic degrade chain.
|
||||
|
||||
Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
## Trade-offs and quirks
|
||||
|
||||
- **Slightly slower per call** than in-process faster-whisper (IPC overhead);
|
||||
the model stays warm inside the sidecar between calls, so the cost is per
|
||||
request, not per chunk of audio.
|
||||
- Word timestamps are Whisper-native (±100–300 ms) — no forced alignment.
|
||||
For dubbing lip-sync, use [whisperx](whisperx.md) or
|
||||
[mlx-whisper](mlx-whisper.md).
|
||||
- If the sidecar dies mid-transcription the job fails with a clear
|
||||
"sidecar crashed" error and the backend stays up — retry to respawn.
|
||||
- **cuDNN 8 is still required on CUDA** — same CTranslate2 requirement as the
|
||||
in-process engine. It's checked up front so a missing cuDNN 8 shows as
|
||||
"unavailable" in Model Catalogue → Engines instead of a sidecar that
|
||||
silently fails every transcribe
|
||||
([#1371](https://github.com/debpalash/VoiceStudio/issues/1371)).
|
||||
@@ -0,0 +1,70 @@
|
||||
# VoiceStudio — Faster-Whisper Engine
|
||||
|
||||
Faster-Whisper runs Whisper on CTranslate2 — the same transcription core
|
||||
WhisperX uses, **without** the wav2vec2 forced-alignment pass. It's the safe
|
||||
cross-platform fallback when whisperx isn't installed, and the capture/dictation
|
||||
fallback on non-Apple machines.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the Faster-Whisper row, or
|
||||
- pin it with `OMNIVOICE_ASR_BACKEND=faster-whisper`.
|
||||
|
||||
Auto-detect only picks it when [whisperx](whisperx.md) is unavailable.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Subtitles, dictation buffers, and batch transcription** where Whisper's
|
||||
native word timing (±100–300 ms) is good enough.
|
||||
- For dubbing lip-sync, prefer [whisperx](whisperx.md) (or
|
||||
[mlx-whisper](mlx-whisper.md) on Apple Silicon) — their forced alignment is
|
||||
an order of magnitude tighter on word boundaries.
|
||||
|
||||
## Platform support
|
||||
|
||||
- **CUDA** — float16, with automatic degradation (below).
|
||||
- **CPU** — int8 on macOS, Windows, and Linux.
|
||||
- **Apple Silicon GPU / ROCm** — not supported: CTranslate2 has no Metal or
|
||||
HIP build, so those hosts run on CPU
|
||||
([#1529](https://github.com/debpalash/VoiceStudio/issues/1529)); auto-detect
|
||||
routes them to mlx-whisper / pytorch-whisper instead.
|
||||
|
||||
## Model selection
|
||||
|
||||
`ASR_MODEL_FASTER` — default `Systran/faster-whisper-large-v3`. Accepts the
|
||||
size aliases (`tiny` … `large-v3`, `distil-large-v3`) or any CTranslate2
|
||||
Whisper repo on HF. Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
Segments are cleaned up by faster-whisper's built-in Silero VAD before
|
||||
transcription.
|
||||
|
||||
## Degradation chains
|
||||
|
||||
- GPUs without efficient fp16 (older Maxwell/Pascal, GTX 16xx, or a
|
||||
CTranslate2/cuDNN mismatch) fail at model construction with a compute-type
|
||||
error; the engine walks float16 → int8_float16 → int8 instead of failing
|
||||
every chunk ([#551](https://github.com/debpalash/VoiceStudio/issues/551)).
|
||||
- A CUDA out-of-memory falls back to CPU (slower, same model and accuracy) —
|
||||
flushing the resident TTS model frees VRAM for GPU-speed ASR
|
||||
([#255](https://github.com/debpalash/VoiceStudio/issues/255)).
|
||||
|
||||
## Quirks
|
||||
|
||||
- **cuDNN 8 required on CUDA** — a missing cuDNN 8 would fast-fail the whole
|
||||
process, so the engine checks up front and reports itself unavailable
|
||||
instead ([#1371](https://github.com/debpalash/VoiceStudio/issues/1371)).
|
||||
pytorch-whisper covers that case on torch's bundled cuDNN 9.
|
||||
- On some hardened Linux kernels the CTranslate2 native library is rejected
|
||||
with "cannot enable executable stack" (an OSError, not an ImportError) —
|
||||
reported as unavailable rather than crashing engine selection
|
||||
([#692](https://github.com/debpalash/VoiceStudio/issues/692)).
|
||||
- CTranslate2's GPU teardown can rarely segfault the process at unload. If
|
||||
you hit that, switch to the crash-isolated variant —
|
||||
[faster-whisper-isolated](faster-whisper-isolated.md)
|
||||
([#730](https://github.com/debpalash/VoiceStudio/issues/730)).
|
||||
- Transcribes are time-bounded: `OMNIVOICE_TRANSCRIBE_CHUNK_TIMEOUT_S`
|
||||
(default 120 s per dub chunk) and `OMNIVOICE_ASR_TRANSCRIBE_TIMEOUT_S`
|
||||
(default 300 s whole-file).
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
@@ -0,0 +1,62 @@
|
||||
# VoiceStudio — FunASR (SenseVoice) Engine
|
||||
|
||||
FunASR drives Alibaba's SenseVoiceSmall with FSMN-VAD: an all-in-one
|
||||
multilingual pipeline — transcription with punctuation and inverse text
|
||||
normalization across **50+ languages**, plus optional **inline speaker
|
||||
diarization** via the cam++ speaker model. It's the opt-in alternative to
|
||||
WhisperX ([#182](https://github.com/debpalash/VoiceStudio/issues/182));
|
||||
WhisperX remains the cross-platform default.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- Install it into the app venv: `uv pip install funasr`.
|
||||
- Then **Model Catalogue → Engines**, ASR tab → **Use** on the FunASR row, or
|
||||
`OMNIVOICE_ASR_BACKEND=funasr`.
|
||||
|
||||
Auto-detect never picks it; it's an explicit opt-in.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Multi-speaker transcription without any HuggingFace token.** This is the
|
||||
only ASR engine with diarization built in: cam++ labels each sentence
|
||||
(`Speaker 1`, `Speaker 2`, ...) in the same pass — no gated pyannote
|
||||
model, no license click-through. Compare
|
||||
[diarization](../features/diarization.md) for the pyannote/WhisperX route
|
||||
and what each buys you.
|
||||
- **Broad language coverage** beyond Whisper's strongest languages, with
|
||||
punctuation included.
|
||||
|
||||
## Not suited for
|
||||
|
||||
- **Lip-sync dubbing** — FunASR returns sentence-level timestamps, not
|
||||
word-level ones. Use [whisperx](whisperx.md) /
|
||||
[mlx-whisper](mlx-whisper.md) when word timing matters.
|
||||
|
||||
## Platform support
|
||||
|
||||
CUDA or CPU, on macOS, Windows, and Linux.
|
||||
|
||||
## Model selection
|
||||
|
||||
| Variable | Default | Role |
|
||||
| --- | --- | --- |
|
||||
| `ASR_MODEL_FUNASR` | `iic/SenseVoiceSmall` | main ASR model |
|
||||
| `ASR_FUNASR_VAD` | `fsmn-vad` | VAD segmentation model |
|
||||
| `ASR_FUNASR_SPK` | `cam++` | speaker model; set to empty (`ASR_FUNASR_SPK=`) to disable diarization and use the dub pipeline's pyannote/heuristic path instead |
|
||||
|
||||
Weights download on first load (through FunASR's own model hub) — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
## Quirks
|
||||
|
||||
- With the speaker model enabled, long recordings are transcribed in **one
|
||||
call** and split by FunASR's internal VAD — cam++ assigns speaker cluster
|
||||
IDs per call, so this is what keeps "Speaker 1" meaning the same person
|
||||
across the whole file.
|
||||
- The engine runs with `spk_mode="vad_segment"`: FunASR 1.3.1's default
|
||||
(`punc_segment`) requires a separate punctuation model and crashes when
|
||||
SenseVoice is loaded without one.
|
||||
- SenseVoice's rich-token markup (language/emotion/event tags around the
|
||||
text) is stripped from the output automatically.
|
||||
- Language detection is automatic (`language: auto`); the detected language
|
||||
is reported per file.
|
||||
@@ -0,0 +1,78 @@
|
||||
# VoiceStudio — GPT-SoVITS Engine
|
||||
|
||||
GPT-SoVITS (RVC-Boss) is one of the most popular open-source voice-cloning
|
||||
systems (57k+ GitHub stars, MIT-licensed). It does zero-shot and few-shot
|
||||
cloning with excellent naturalness in Chinese, English, Japanese, Cantonese,
|
||||
and Korean, and it is very fast (RTF ~0.014 on suitable hardware).
|
||||
|
||||
Unlike VoiceStudio's other engines, GPT-SoVITS does not run inside the app.
|
||||
It ships as a standalone API server, and VoiceStudio connects to it over
|
||||
HTTP.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You already run (or want to run) a GPT-SoVITS server, e.g. with few-shot
|
||||
fine-tuned voices.
|
||||
- You need fast, natural cloning in zh/en/ja/yue/ko.
|
||||
|
||||
## Setup
|
||||
|
||||
1. Install and start the GPT-SoVITS API server (upstream project):
|
||||
|
||||
```bash
|
||||
cd GPT-SoVITS
|
||||
python api_v2.py -a 127.0.0.1 -p 9880 -c GPT_SoVITS/configs/tts_infer.yaml
|
||||
```
|
||||
|
||||
2. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=gpt-sovits`.
|
||||
|
||||
VoiceStudio marks the engine available only when the server responds
|
||||
(2-second reachability probe).
|
||||
|
||||
## Configuration
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_GPTSOVITS_URL` | `http://127.0.0.1:9880` | API server URL |
|
||||
| `OMNIVOICE_TRUSTED_NETWORKS` | (unset) | Required to allow a non-loopback server |
|
||||
|
||||
**Remote servers:** by default VoiceStudio only talks to loopback addresses
|
||||
— part of the local-first guarantee. To point at a server on another
|
||||
machine (e.g. a GPU box on your LAN), add its network to
|
||||
`OMNIVOICE_TRUSTED_NETWORKS`; otherwise the connection is refused as an
|
||||
untrusted endpoint.
|
||||
|
||||
Prefer `https://` (or a private tunnel such as Tailscale/WireGuard) for any
|
||||
non-loopback server: with plain `http://` the text you synthesize and the
|
||||
audio that comes back cross the network unencrypted. VoiceStudio does not
|
||||
disable certificate verification, so a TLS endpoint needs a certificate the
|
||||
system trusts.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 32 kHz mono (server output is resampled if needed).
|
||||
- Cloning passes your reference clip path and optional transcript to the
|
||||
server; the reference path must be readable **by the server process**, so
|
||||
remote servers need the clip on their own filesystem.
|
||||
- Speed control is forwarded as the server's `speed_factor`.
|
||||
- The GPU is whatever the GPT-SoVITS server itself uses (CUDA preferred);
|
||||
VoiceStudio's side is just an HTTP client.
|
||||
|
||||
## Known limits
|
||||
|
||||
- Five languages only; for broader coverage use
|
||||
[OmniVoice](omnivoice.md) ([languages.md](../languages.md)).
|
||||
- No voice design; server availability is your responsibility — if the
|
||||
server stops, generations fail with a "server not reachable" error.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "GPT-SoVITS server not reachable": start the server with the command
|
||||
above, or fix `OMNIVOICE_GPTSOVITS_URL`.
|
||||
- "endpoint is outside loopback or OMNIVOICE_TRUSTED_NETWORKS": see
|
||||
Configuration above.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[expressive-speech.md](../expressive-speech.md).
|
||||
@@ -0,0 +1,75 @@
|
||||
# VoiceStudio — KittenTTS Engine
|
||||
|
||||
KittenTTS (KittenML) is the lightweight English "flash" tier: a 25–80 MB
|
||||
ONNX model with 8 preset voices that runs realtime on any CPU — no torch, no
|
||||
CUDA, no GPU of any kind. Use it when you just need quick English narration
|
||||
(voiceovers, demo reads, short phrases) with no reference sample.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- English-only content where speed and a tiny install matter more than
|
||||
cloning.
|
||||
- Machines with no usable GPU.
|
||||
|
||||
The trade-off against [OmniVoice](omnivoice.md): no voice cloning, English
|
||||
only — but a much faster and much smaller install.
|
||||
|
||||
## Setup
|
||||
|
||||
```bash
|
||||
pip install kittentts
|
||||
```
|
||||
|
||||
Then select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=kittentts`.
|
||||
|
||||
## Voices
|
||||
|
||||
Eight preset voices, four male/female pairs:
|
||||
|
||||
```text
|
||||
expr-voice-2-m expr-voice-2-f (default: expr-voice-2-f)
|
||||
expr-voice-3-m expr-voice-3-f
|
||||
expr-voice-4-m expr-voice-4-f
|
||||
expr-voice-5-m expr-voice-5-f
|
||||
```
|
||||
|
||||
An unknown voice id logs an info message and falls back to the default.
|
||||
|
||||
## Model selection
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_KITTENTTS_MODEL` | `KittenML/kitten-tts-mini-0.8` | HuggingFace checkpoint to load |
|
||||
|
||||
The ~80 MB model downloads from HuggingFace on first use (retried once on a
|
||||
flaky connection). See [downloading-models.md](../downloading-models.md).
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 24 kHz mono.
|
||||
- CPU-only by design — the ONNX graph has no CUDA/MPS path.
|
||||
- Non-English `language` values are ignored with a log line pointing at
|
||||
OmniVoice; reference audio is likewise ignored (no cloning).
|
||||
- **Long-input hardening
|
||||
([#1173](https://github.com/debpalash/VoiceStudio/issues/1173)):** the
|
||||
shipped ONNX graph has a hard 512-token cap, and phonemization can expand
|
||||
text massively (digits especially). VoiceStudio pre-measures every chunk
|
||||
with the model's own tokenizer and splits oversized chunks at word
|
||||
boundaries, so long or digit-heavy inputs no longer abort inside
|
||||
onnxruntime with an opaque "invalid expand shape" error.
|
||||
|
||||
## Known limits
|
||||
|
||||
- English only; no cloning, no voice design, no emotion controls
|
||||
(see [expressive-speech.md](../expressive-speech.md)).
|
||||
- Preset voices only — speed is the one knob.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- Engine unavailable: `pip install kittentts` into VoiceStudio's Python
|
||||
environment and restart.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,76 @@
|
||||
# VoiceStudio — MLX-Audio Engine (Apple Silicon)
|
||||
|
||||
MLX-Audio (Blaizzy/mlx-audio) wraps 14+ TTS engines — Kokoro, CSM, Dia,
|
||||
Qwen3-TTS, Chatterbox, MeloTTS, OuteTTS, and more — behind a single adapter
|
||||
that runs on Apple's MLX framework. It is **Apple Silicon only**: the engine
|
||||
is not shipped on Linux, Windows, or Intel Macs, and a stray wheel on those
|
||||
platforms never reports as available
|
||||
([#390](https://github.com/debpalash/VoiceStudio/issues/390)).
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You're on an M-series Mac and want small, fast models tuned for it.
|
||||
- You want one of the specific hosted models (Kokoro for small multilingual,
|
||||
CSM for cloning, Qwen3-TTS for voice design, Dia for dialogue, …).
|
||||
|
||||
## Setup
|
||||
|
||||
```bash
|
||||
pip install mlx-audio
|
||||
```
|
||||
|
||||
Then select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=mlx-audio`.
|
||||
|
||||
## Model selection
|
||||
|
||||
One backend hosts many models. The curated set:
|
||||
|
||||
| Key | Model | Niche |
|
||||
| --- | --- | --- |
|
||||
| `kokoro` (default) | `mlx-community/Kokoro-82M-bf16` | small multilingual |
|
||||
| `csm` | `mlx-community/csm-1b-8bit` | voice cloning |
|
||||
| `qwen3-tts` | `mlx-community/Qwen3-TTS-12Hz-1.7B-VoiceDesign-4bit` | voice design |
|
||||
| `dia` | `mlx-community/Dia-1.6B` | dialogue |
|
||||
| `chatterbox` | `mlx-community/Chatterbox-TTS-4bit` | expressive |
|
||||
| `melotts` | `mlx-community/MeloTTS-English-v3-MLX` | lightweight VITS |
|
||||
| `outetts` | `mlx-community/Llama-OuteTTS-1.0-1B-4bit` | LM-based |
|
||||
|
||||
Pick a model in the **Model Catalogue → Engines** curated picker
|
||||
([#981](https://github.com/debpalash/VoiceStudio/issues/981)) or set
|
||||
`OMNIVOICE_MLX_AUDIO_MODEL` to either a curated key (`kokoro`) or any full
|
||||
HF repo id. The env var overrides the persisted UI choice.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 24 kHz mono for most hosted models.
|
||||
- **Cloning works only with the `csm` model** — it is the only curated model
|
||||
confirmed to accept a reference clip. Other models silently ignore
|
||||
reference audio, so the engine reports cloning support only when CSM is
|
||||
selected (dub/batch jobs gate on this).
|
||||
- Voice design (text description → voice) is available through the
|
||||
Qwen3-TTS VoiceDesign model.
|
||||
- Language support is per-model (Kokoro ~8 languages, others vary). An
|
||||
unsupported language for Kokoro produces a clear error naming what it
|
||||
does support ([#977](https://github.com/debpalash/VoiceStudio/issues/977))
|
||||
— leave language on Auto or switch to a multilingual engine.
|
||||
|
||||
## Platform notes
|
||||
|
||||
This engine is exempt from cross-platform parity as a platform-only
|
||||
capability behind explicit opt-in: it exists only where Apple's MLX runtime
|
||||
exists. On any other platform the engine picker shows it unavailable with
|
||||
the reason.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- Unavailable on an M-series Mac: `pip install mlx-audio` into
|
||||
VoiceStudio's Python environment; in a packaged app build, MLX's native
|
||||
libraries may fail to load — the engine reports unavailable rather than
|
||||
crashing.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[languages.md](../languages.md),
|
||||
[downloading-models.md](../downloading-models.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,57 @@
|
||||
# VoiceStudio — MLX Whisper Engine
|
||||
|
||||
MLX Whisper runs Whisper on the Apple Silicon GPU via MLX. It exists because
|
||||
CTranslate2 (whisperx / faster-whisper) has **no Metal build** — on a Mac
|
||||
those engines transcribe on the CPU no matter what GPU is present. Measured
|
||||
on an M2 with whisper-large-v3, one 30 s dub chunk: **90.4 s on WhisperX
|
||||
(CPU) vs 20.5 s on MLX (GPU)** — which is why auto-detect picks MLX Whisper
|
||||
on every Apple Silicon machine
|
||||
([#1127](https://github.com/debpalash/VoiceStudio/issues/1127)).
|
||||
|
||||
## Selecting it
|
||||
|
||||
- Nothing to do on Apple Silicon — auto-detect prefers it there.
|
||||
- Or explicitly: **Model Catalogue → Engines**, ASR tab → **Use**, or
|
||||
`OMNIVOICE_ASR_BACKEND=mlx-whisper`.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Dubbing on a Mac** — it layers the same wav2vec2 forced alignment
|
||||
WhisperX uses on top of the GPU transcription, so word timing (±10–30 ms)
|
||||
and therefore lip-sync accuracy are unchanged. Same model, same alignment,
|
||||
~4x the speed.
|
||||
- **Dictation/capture** — the capture path automatically swaps in
|
||||
`mlx-community/whisper-large-v3-turbo` (~5x faster than large-v3) unless a
|
||||
sherpa dictation model or [parakeet-mlx](parakeet-mlx.md) is preferred.
|
||||
|
||||
## Platform support
|
||||
|
||||
**Apple Silicon only.** A shared platform gate refuses Linux, Windows, and
|
||||
Intel Macs before any package import, so a stray `mlx-whisper` wheel on the
|
||||
wrong platform never reports itself available
|
||||
([#390](https://github.com/debpalash/VoiceStudio/issues/390)). All other
|
||||
platforms use the CUDA/CPU engines instead.
|
||||
|
||||
## Model selection
|
||||
|
||||
- `ASR_MODEL` — default `mlx-community/whisper-large-v3-mlx`. Any MLX-format
|
||||
Whisper repo works. Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
- `OMNIVOICE_ALIGN_DEVICE` — force the wav2vec2 aligner's device. The aligner
|
||||
runs on MPS when it can and falls back to CPU; languages without a bundled
|
||||
aligner (~20 major languages have one) keep Whisper's native word
|
||||
timestamps.
|
||||
|
||||
## Quirks
|
||||
|
||||
- Audio is decoded through VoiceStudio's validated ffmpeg rather than the
|
||||
bare `ffmpeg` PATH lookup mlx-whisper would do on its own — a clean
|
||||
from-source install with no system ffmpeg works fine
|
||||
([#479](https://github.com/debpalash/VoiceStudio/issues/479)).
|
||||
- The model is warmed into unified memory in the background, so the first
|
||||
transcribe after startup doesn't pay the load cost.
|
||||
- In a packaged app, a native MLX library that fails to load is reported as
|
||||
"unavailable" (with fallback to another engine) rather than crashing the
|
||||
engine list.
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
@@ -0,0 +1,48 @@
|
||||
# VoiceStudio — Moonshine Engine
|
||||
|
||||
Moonshine is an edge-optimized ASR family built for CPU-only machines.
|
||||
Unlike Whisper it processes variable-length audio (no padding everything to
|
||||
30 s), which keeps latency low on short clips — sub-200 ms class on capture
|
||||
buffers. It's the lightest local option for quick transcription on hardware
|
||||
where even int8 whisper-large is too slow.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- Install one of the runtimes into the app venv:
|
||||
`uv pip install moonshine-onnx` (lighter, tried first) or
|
||||
`moonshine-voice`.
|
||||
- Then **Model Catalogue → Engines**, ASR tab → **Use** on the Moonshine row,
|
||||
or `OMNIVOICE_ASR_BACKEND=moonshine`.
|
||||
|
||||
Auto-detect never picks it; it's an explicit opt-in.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Quick notes and short-clip transcription on low-power CPU machines.**
|
||||
- Environments where a sub-1 GB footprint matters more than word timing or
|
||||
language coverage.
|
||||
|
||||
## Not suited for
|
||||
|
||||
- **Dubbing.** Output is plain text as a **single segment spanning the whole
|
||||
file — no word or segment timestamps** — so there's nothing for lip-sync
|
||||
or subtitle timing to work with. Use a Whisper-family engine or
|
||||
[sherpa-onnx-asr](sherpa-onnx-asr.md) for those jobs.
|
||||
- Multilingual work: results report English; for broad language coverage use
|
||||
[whisperx](whisperx.md) or [funasr](funasr.md).
|
||||
|
||||
## Platform support
|
||||
|
||||
CPU only, by design — macOS, Windows, and Linux. It claims no GPU.
|
||||
|
||||
## Model selection
|
||||
|
||||
`ASR_MODEL_MOONSHINE` — default `moonshine/base`. Weights download on first
|
||||
load — see [downloading-models](../downloading-models.md).
|
||||
|
||||
## Quirks
|
||||
|
||||
- The engine tries `moonshine_onnx` first and falls back to
|
||||
`moonshine_voice` — installing either one is enough.
|
||||
- Segment bounds are synthesized from the audio duration (start 0, end =
|
||||
file length), since the model reports none.
|
||||
@@ -0,0 +1,78 @@
|
||||
# VoiceStudio — MOSS-TTS-Nano Engine
|
||||
|
||||
MOSS-TTS-Nano (OpenMOSS) is the low-resource, broad-language pick: a
|
||||
100M-parameter autoregressive codec LM that runs realtime on a 4-core CPU —
|
||||
no GPU required — with native 48 kHz output and 20 languages under an
|
||||
Apache-2.0 license. It fills the "runs on a fanless laptop" tier while still
|
||||
covering languages like Arabic, Hebrew, Persian, Korean, and Turkish.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- CPU-only or low-power hardware, but you still need cloning and non-English
|
||||
coverage.
|
||||
- Your language is among: Chinese, English, German, Spanish, French,
|
||||
Japanese, Italian, Hebrew, Korean, Russian, Persian, Arabic, Polish,
|
||||
Portuguese, Czech, Danish, Swedish, Hungarian, Greek, Turkish.
|
||||
|
||||
## Setup
|
||||
|
||||
The package is **not on PyPI** — install it from the upstream repo into
|
||||
VoiceStudio's Python environment:
|
||||
|
||||
```bash
|
||||
git clone https://github.com/OpenMOSS/MOSS-TTS-Nano.git
|
||||
cd MOSS-TTS-Nano
|
||||
uv pip install -e .
|
||||
```
|
||||
|
||||
Then select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=moss-tts-nano`.
|
||||
|
||||
## Model selection
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_MOSS_TTS_MODEL` | `OpenMOSS-Team/MOSS-TTS-Nano` | HuggingFace checkpoint to load |
|
||||
|
||||
The first use downloads the weights (retried once on a truncated download).
|
||||
See [downloading-models.md](../downloading-models.md).
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- **Cloning is reference-only**: pass a reference clip. Style instructions,
|
||||
preset speakers, and speed control are not supported and are silently
|
||||
ignored, so mixed-engine call sites keep working.
|
||||
- The model emits 48 kHz stereo; VoiceStudio downmixes to mono, matching the
|
||||
rest of the pipeline (the dub mixer treats TTS output as mono per
|
||||
segment).
|
||||
- Runs on CPU or CUDA.
|
||||
|
||||
## Upstream is unpinned
|
||||
|
||||
The upstream repo is installed straight from git with no pinned release, and
|
||||
the model class it exports has changed before
|
||||
([#1287](https://github.com/debpalash/VoiceStudio/issues/1287)). VoiceStudio
|
||||
therefore verifies that a usable model class actually exists — not just that
|
||||
the package imports — before reporting the engine as ready. If the engine
|
||||
shows unavailable with a "does not expose a usable model class" message,
|
||||
pull the latest upstream and re-run `uv pip install -e .`, or open an issue
|
||||
with the version you have.
|
||||
|
||||
## Known limits
|
||||
|
||||
- No voice design, no instruct, no speed control — cloning from a reference
|
||||
clip only.
|
||||
- Quality sits below the large engines; see
|
||||
[benchmarks.md](../benchmarks.md).
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "moss_tts_nano package not installed": run the clone + `uv pip install -e .`
|
||||
steps above.
|
||||
- Entry-point errors after an upstream update: see "Upstream is unpinned"
|
||||
above.
|
||||
- General issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [languages.md](../languages.md),
|
||||
[expressive-speech.md](../expressive-speech.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,58 @@
|
||||
# VoiceStudio — Parakeet TDT (NVIDIA NeMo) Engine
|
||||
|
||||
NVIDIA's Parakeet TDT via the NeMo toolkit: a FastConformer encoder with a
|
||||
Token-and-Duration Transducer decoder. It beats Whisper large-v3 on English
|
||||
benchmarks (~6% WER) and supports **25 (mostly European) languages** with
|
||||
automatic language detection. The 0.6B model is fast even on CPU — measured
|
||||
RTF 0.08–0.23 on an Apple Silicon M2 CPU (2026-07-02), ~20x faster than
|
||||
faster-whisper large-v3 int8 on the same host.
|
||||
|
||||
## Do not install NeMo into the app venv
|
||||
|
||||
`nemo_toolkit`'s ASR extras pin `transformers>=4.57,<4.58`, which conflicts
|
||||
with VoiceStudio's own `transformers>=5.3` requirement and **will break the
|
||||
backend** (ImportError on startup) if installed into the shared venv. There
|
||||
is currently no safe in-app install path for this engine; in-app isolation
|
||||
is tracked separately.
|
||||
|
||||
If you want the Parakeet models without a separate environment, use these
|
||||
instead — same model family, no NeMo dependency:
|
||||
|
||||
- **Apple Silicon:** [parakeet-mlx](parakeet-mlx.md) (installed by default on
|
||||
mac-ARM source installs).
|
||||
- **Any platform, CPU:** [sherpa-onnx-asr](sherpa-onnx-asr.md) — its default
|
||||
dictation model is an int8 ONNX export of Parakeet TDT v3.
|
||||
|
||||
## Selecting it
|
||||
|
||||
Only meaningful if you've set up `nemo_toolkit[asr]` in a **separate,
|
||||
dedicated Python environment** that runs the backend:
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the Parakeet TDT row, or
|
||||
- `OMNIVOICE_ASR_BACKEND=nemo-parakeet`.
|
||||
|
||||
Auto-detect never picks it; it's an explicit opt-in.
|
||||
|
||||
## Best at
|
||||
|
||||
- **English and European-language transcription** where WER matters more
|
||||
than word-level subtitle timing.
|
||||
- **CPU-only hosts** — faster than realtime without any GPU.
|
||||
|
||||
## Platform support
|
||||
|
||||
CUDA or CPU (the old hard CUDA gate was removed — see the RTF numbers
|
||||
above). Availability is a pure dependency check on `nemo.collections.asr`.
|
||||
|
||||
## Model selection
|
||||
|
||||
`ASR_MODEL_NEMO` — default `nvidia/parakeet-tdt-0.6b-v3`. Weights download
|
||||
on first load — see [downloading-models](../downloading-models.md).
|
||||
|
||||
## Quirks
|
||||
|
||||
- Output is a **single segment** for the whole file (NeMo doesn't VAD-split
|
||||
like Whisper), with word timestamps when the model exposes them — fine for
|
||||
dictation and plain transcripts, not ideal for long-form subtitles.
|
||||
- The detected language isn't exposed cleanly by NeMo, so results report
|
||||
`en` regardless of the actual (auto-detected) language.
|
||||
@@ -0,0 +1,83 @@
|
||||
# VoiceStudio — OmniVoice GGUF Engine
|
||||
|
||||
OmniVoice GGUF runs the same OmniVoice model as the [default
|
||||
engine](omnivoice.md), but through a bundled native binary
|
||||
(`bin/omnivoice-tts-<platform>`) loading quantized GGUF weights. It is
|
||||
hardware-adaptive: a probe picks the quantization that fits your machine, so
|
||||
small GPUs and CPU-only hosts get a working OmniVoice instead of a paging,
|
||||
timing-out one.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- Your GPU is below the default engine's 6 GB VRAM floor.
|
||||
- CPU-only machines that still want OmniVoice's voice and language coverage.
|
||||
- You want generation isolated in a separate process (a crash or leak never
|
||||
takes the app down — each generation spawns the binary fresh).
|
||||
|
||||
## Quantization selection
|
||||
|
||||
Weights come from the `Serveurperso/OmniVoice-GGUF` HuggingFace repo, pinned
|
||||
to an exact revision. The hardware probe selects:
|
||||
|
||||
| Hardware | Quant | Approx. VRAM use |
|
||||
| --- | --- | --- |
|
||||
| 12 GB+ VRAM | BF16 | ~1.6 GB (quality-first) |
|
||||
| 4–12 GB VRAM | Q8_0 | ~945 MB (recommended balance) |
|
||||
| 1–4 GB VRAM | Q4_K_M | ~659 MB (minimal footprint) |
|
||||
| CPU-only | Q4_K_M | RAM-bound, latency-tolerable |
|
||||
|
||||
You can override the selection from Settings; overrides are allow-listed
|
||||
against the same table (an F32 reference quant, ~3.2 GB, is override-only).
|
||||
|
||||
## Setup
|
||||
|
||||
Nothing to install: installer and CI builds bundle the binary for your
|
||||
platform. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=omnivoice-gguf`. The quant weights download on first
|
||||
use (see [downloading-models.md](../downloading-models.md)) — install them
|
||||
ahead of time from **Model Catalogue → Models** if you want the first
|
||||
generation to be quick; a long first render is the download, not a hang.
|
||||
|
||||
**Source checkouts:** the repo ships zero-byte placeholders in `bin/` — real
|
||||
binaries come from CI or the installer. The engine detects a placeholder and
|
||||
reports unavailable with instructions
|
||||
([#1172](https://github.com/debpalash/VoiceStudio/issues/1172)) instead of
|
||||
failing at spawn time; build one with
|
||||
`scripts/build-omnivoice-tts.sh --platform <slug>` or use the default
|
||||
in-process engine.
|
||||
|
||||
## Integrity and self-healing
|
||||
|
||||
Before reporting ready, the engine:
|
||||
|
||||
- verifies the binary against the SHA-256 manifest (`bin/checksums.sha256`);
|
||||
- detects macOS Gatekeeper quarantine and prints the exact
|
||||
`xattr -cr '/Applications/VoiceStudio.app'` fix;
|
||||
- restores a missing execute bit (a git clone or zip extract on POSIX can
|
||||
drop `+x`, which used to surface as a permission error mislabeled as
|
||||
out-of-memory — [#437](https://github.com/debpalash/VoiceStudio/issues/437)).
|
||||
The chmod runs only after the SHA check confirms it's the right file.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 24 kHz mono — same model, same rate as in-process OmniVoice.
|
||||
- Cloning from a reference clip (with optional transcript) and style
|
||||
instructions are supported; no voice design.
|
||||
- Same multilingual surface as OmniVoice ([languages.md](../languages.md)).
|
||||
- Because generation runs in another process, the app's own GPU counters
|
||||
don't see its allocations — diagnostics label it accordingly.
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_GGUF_GENERATE_TIMEOUT_S` | (generous built-in) | Per-generation timeout for the spawned binary |
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "GGUF binary missing": this build doesn't bundle the runtime for your
|
||||
platform — use the default engine.
|
||||
- Checksum mismatch or quarantine messages: follow the printed fix, or
|
||||
reinstall.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[performance.md](../performance.md), [disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,100 @@
|
||||
# VoiceStudio — OmniVoice Engine (default)
|
||||
|
||||
OmniVoice (k2-fsa/OmniVoice) is VoiceStudio's default TTS engine — the one a
|
||||
fresh install uses without any configuration. It does zero-shot voice cloning
|
||||
across 600+ languages and outputs 24 kHz mono audio. Voice cloning, dubbing,
|
||||
and dictation all run on it out of the box.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You want cloning plus the broadest language coverage (see
|
||||
[languages.md](../languages.md)).
|
||||
- You have a GPU (CUDA or Apple Silicon MPS) with ~6 GB VRAM or more.
|
||||
- You just installed VoiceStudio — it's already selected.
|
||||
|
||||
For low-VRAM or CPU-only machines, the
|
||||
[OmniVoice GGUF](omnivoice-gguf.md) variant runs the same model through a
|
||||
quantized native binary with a much smaller memory footprint.
|
||||
|
||||
## Requirements
|
||||
|
||||
- Runs on CUDA, MPS (Apple Silicon), or CPU — auto-detected.
|
||||
- Recommended VRAM floor: **6 GB** on a dedicated GPU. This is the only
|
||||
engine with a measured floor: on 4 GB cards (GTX 1650 Ti, Quadro P2000 —
|
||||
issues [#1226](https://github.com/debpalash/VoiceStudio/issues/1226) /
|
||||
[#1222](https://github.com/debpalash/VoiceStudio/issues/1222)) the driver
|
||||
pages to system RAM and a render that should take seconds runs for minutes
|
||||
until the compute budget kills it. The UI warns before you wait; nothing
|
||||
hard-blocks, since short inputs can still fit.
|
||||
- No extra install — the model ships with the app and downloads its weights
|
||||
on first use (see [downloading-models.md](../downloading-models.md)).
|
||||
|
||||
## Selecting the engine
|
||||
|
||||
OmniVoice is the default, so normally there is nothing to do. If you switched
|
||||
away and want it back:
|
||||
|
||||
- **Model Catalogue → Engines**, or
|
||||
- set `OMNIVOICE_TTS_BACKEND=omnivoice`.
|
||||
|
||||
The env var overrides the persisted UI choice.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Weights load lazily on first use and are shared with the rest of the app
|
||||
(dubbing, dictation) — the model is never double-loaded.
|
||||
- On CUDA the model runs fp16 with `torch.compile`; a speech recognizer is
|
||||
co-loaded for the cloning path.
|
||||
- Output is 24 kHz mono; the shared mastering chain (highpass + compressor)
|
||||
is tuned for this rate and applied automatically.
|
||||
- Cloning takes a short reference clip (`ref_audio`); 3–10 seconds is the
|
||||
sweet spot. A transcript of the clip improves conditioning — if the profile
|
||||
has none, VoiceStudio transcribes the clip automatically on first use and
|
||||
saves the result to the profile.
|
||||
- Encoded voice references persist on disk (`prompt_cache/` in the app data
|
||||
dir), so the first generation with a known voice after a restart skips the
|
||||
re-encode and any transcription pass. Set `OMNIVOICE_PROMPT_DISK_CACHE=0`
|
||||
to keep the cache in memory only.
|
||||
- Style attributes (`instruct`) and a reference clip can be **combined**:
|
||||
when they agree, the instruct stabilizes cloning for the attributes it
|
||||
names (upstream documents dialect cloning as the canonical case — dialect
|
||||
reference + matching dialect instruct). When they conflict, the reference
|
||||
audio wins.
|
||||
- Inline pronunciation control: Chinese via pinyin with tone numbers
|
||||
(`打ZHE2出售`), English via bracketed CMU phonemes (`[B EY1 S]`). Non-verbal
|
||||
tags like `[laughter]` are covered in
|
||||
[expressive-speech.md](../expressive-speech.md).
|
||||
- Voice design works from attributes (gender, age, pitch, whisper, English
|
||||
accents, Chinese dialects) via the Design tab — no reference audio needed.
|
||||
- Optional FlashInfer acceleration on CUDA: set `OMNIVOICE_FLASHINFER=1`
|
||||
(or `=graph` for CUDA-graph capture, best for one render at a time) after
|
||||
installing the `flashinfer-python` package — see
|
||||
[performance.md](../performance.md). Off by default; if the package is
|
||||
missing or a kernel fails, the app logs why and continues on the standard
|
||||
path.
|
||||
|
||||
## Known limits
|
||||
|
||||
- Voice design understands only the fixed attribute vocabulary — free-form
|
||||
design *prose* is mapped onto those attributes, and wording outside them
|
||||
is ignored. Design is trained on English and Chinese and can be unstable
|
||||
in low-resource languages; for description-driven design in other cases
|
||||
try [VoxCPM2](voxcpm2.md).
|
||||
- Below the 6 GB VRAM floor, expect very slow renders or budget timeouts;
|
||||
prefer [OmniVoice GGUF](omnivoice-gguf.md) or a CPU engine such as
|
||||
[PocketTTS](pockettts.md).
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "Too heavy for the available compute" on a small GPU: see the VRAM floor
|
||||
above — switch to OmniVoice GGUF or close other GPU apps.
|
||||
- First generation is slow: the first call downloads multi-GB weights. To
|
||||
keep the first render quick, install the model ahead of time from
|
||||
**Model Catalogue → Models** — a long first generate is almost always the
|
||||
download, not a hang.
|
||||
- General install issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[performance.md](../performance.md),
|
||||
[expressive-speech.md](../expressive-speech.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,58 @@
|
||||
# VoiceStudio — Parakeet TDT v3 (MLX) Engine
|
||||
|
||||
NVIDIA's Parakeet TDT v3 on the Apple Silicon GPU, via the small pure-Python
|
||||
`parakeet-mlx` package. It gives Macs the Parakeet tier CUDA/CPU users get
|
||||
through NeMo or sherpa-onnx: **25 European languages**, word timestamps from
|
||||
the TDT decoder itself (no wav2vec2 alignment pass needed), ~1.2 GB download,
|
||||
~2 GB unified memory, dictation-grade speed on the GPU.
|
||||
|
||||
Unlike [nemo-parakeet](nemo-parakeet.md) it needs no `nemo_toolkit` (whose
|
||||
transformers pin conflicts with the app's) — it is **installed by default on
|
||||
Apple Silicon source installs since 0.3.22**.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the Parakeet TDT v3
|
||||
(MLX) row, or `OMNIVOICE_ASR_BACKEND=parakeet-mlx`.
|
||||
- **Dictation prefers it automatically**: once the model weights are
|
||||
installed (Model Catalogue → Models — the auto-pick never triggers a
|
||||
download), live dictation/capture uses it whenever your system language is
|
||||
one of the 25 covered European languages. Other languages keep the
|
||||
multilingual Whisper engine, so dictation coverage never regresses.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Live dictation on a Mac** — TDT decoding is fast enough for the capture
|
||||
path, at Parakeet's better-than-Whisper English WER.
|
||||
- **European-language transcription** with word timestamps at a fraction of
|
||||
whisper-large-v3's memory and compute.
|
||||
|
||||
For languages outside the 25 (CJK, Arabic, ...), use
|
||||
[mlx-whisper](mlx-whisper.md) instead.
|
||||
|
||||
## Platform support
|
||||
|
||||
**Apple Silicon only** — the same shared MLX platform gate as mlx-whisper
|
||||
refuses Linux, Windows, and Intel Macs before any import
|
||||
([#390](https://github.com/debpalash/VoiceStudio/issues/390)). It runs on the
|
||||
unified-memory GPU; there is no CPU tier.
|
||||
|
||||
## Model selection
|
||||
|
||||
`ASR_MODEL_PARAKEET_MLX` — default `mlx-community/parakeet-tdt-0.6b-v3`.
|
||||
Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
## Quirks
|
||||
|
||||
- Long files are processed in 120 s chunks internally to bound unified-memory
|
||||
use; short dictation buffers and dub chunks are unaffected.
|
||||
- Parakeet v3 auto-detects among its 25 languages but doesn't expose the
|
||||
pick, so the reported language is the one you requested (or none) — it is
|
||||
never hardcoded to English.
|
||||
- Word timestamps are merged from the decoder's subword tokens — good for
|
||||
subtitles and dictation; for lip-sync-critical dubbing the wav2vec2-aligned
|
||||
engines ([mlx-whisper](mlx-whisper.md), [whisperx](whisperx.md)) remain the
|
||||
accuracy tier.
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
@@ -0,0 +1,82 @@
|
||||
# VoiceStudio — PocketTTS Engine
|
||||
|
||||
PocketTTS (kyutai-labs/pocket-tts, 100M parameters) is the fastest-CPU-render
|
||||
pick: small, low-latency, CPU-only, with zero-shot voice cloning from a
|
||||
reference clip. It covers six languages — English, French, German,
|
||||
Portuguese, Italian, Spanish — with one model per language, and measures
|
||||
roughly 8–9x real-time on an Apple M3 Pro.
|
||||
|
||||
It complements the quality engines: where they fall back to CPU, PocketTTS
|
||||
is built for it. CPU-only is deliberate — upstream observes no GPU speedup
|
||||
for this model.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- CPU-only machines that need fast rendering *and* voice cloning.
|
||||
- Latency-sensitive use (dictation-style, short utterances) in one of the
|
||||
six languages.
|
||||
|
||||
## Setup
|
||||
|
||||
1. Install the optional dependency:
|
||||
|
||||
```bash
|
||||
uv sync --extra pockettts
|
||||
```
|
||||
|
||||
(Or enable it from **Model Catalogue → Engines**.)
|
||||
|
||||
2. **Accept the license in-app**
|
||||
([#1306](https://github.com/debpalash/VoiceStudio/issues/1306)). The code
|
||||
is MIT and the weights are CC-BY-4.0, but the weights are **gated on
|
||||
HuggingFace** behind an access agreement with an acceptable-use clause.
|
||||
VoiceStudio surfaces this before first use: the engine stays unavailable
|
||||
until you review and accept in **Model Catalogue → Engines → PocketTTS**.
|
||||
You also need HuggingFace access to the gated repo (see
|
||||
[downloading-models.md](../downloading-models.md) for token setup).
|
||||
|
||||
3. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=pockettts`.
|
||||
|
||||
## Platform notes
|
||||
|
||||
- Works on Linux, Windows, macOS Apple Silicon — CPU only everywhere.
|
||||
- **Not available on Intel Macs**: the required PyTorch version has no
|
||||
macOS x86_64 wheel. The engine reports this plainly instead of failing
|
||||
mid-install.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 24 kHz mono.
|
||||
- Six languages, one model per language, chosen by the `language` you
|
||||
request; cloning takes a short reference clip.
|
||||
- Runs in a crash-isolated sidecar process (parent Python environment): a
|
||||
wedged generation is hard-killed by a watchdog and its memory reclaimed —
|
||||
something an in-process engine cannot do.
|
||||
- The first use downloads the gated weights; the sidecar heartbeats
|
||||
progress during the download so the watchdog doesn't fire.
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_POCKETTTS_RECV_TIMEOUT_S` | `600` | Sidecar response deadline in seconds (min 30; cold loads download weights) |
|
||||
|
||||
## Known limits
|
||||
|
||||
- No voice design, no emotion controls
|
||||
(see [expressive-speech.md](../expressive-speech.md)).
|
||||
- Six languages only — for broader coverage use
|
||||
[OmniVoice](omnivoice.md) ([languages.md](../languages.md)).
|
||||
- Revoking the license acceptance takes effect immediately, without a
|
||||
restart — subsequent generations refuse.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "pocket_tts package not installed": run the `uv sync` above.
|
||||
- "license not accepted": open **Model Catalogue → Engines → PocketTTS**
|
||||
and review/accept.
|
||||
- Timeouts on a slow connection: raise
|
||||
`OMNIVOICE_POCKETTTS_RECV_TIMEOUT_S` for the first (download-heavy) run.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[performance.md](../performance.md), [disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,61 @@
|
||||
# VoiceStudio — PyTorch Whisper Engine
|
||||
|
||||
Whisper through the plain `transformers` pipeline, riding torch itself. No
|
||||
extra install — transformers ships with the app — and because it runs on
|
||||
torch's own stack (including torch's bundled cuDNN 9), it works on machines
|
||||
where the CTranslate2 engines can't load. It is also the engine that
|
||||
genuinely uses **AMD ROCm** GPUs, so auto-detect picks it on ROCm hosts
|
||||
([#1529](https://github.com/debpalash/VoiceStudio/issues/1529)).
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the PyTorch Whisper
|
||||
row, or `OMNIVOICE_ASR_BACKEND=pytorch-whisper`.
|
||||
- Auto-detect picks it on ROCm, and as the last resort everywhere else.
|
||||
|
||||
## Best at
|
||||
|
||||
- **ROCm dubbing/transcription** — the only Whisper engine that uses the HIP
|
||||
GPU (CTranslate2 has no HIP build, MLX is Apple-only).
|
||||
- **Rescue engine** when whisperx/faster-whisper can't load — e.g. the
|
||||
missing-cuDNN-8 case
|
||||
([#255](https://github.com/debpalash/VoiceStudio/issues/255)) — since it
|
||||
needs neither CTranslate2 nor cuDNN 8.
|
||||
|
||||
For lip-sync-grade word timing prefer [whisperx](whisperx.md) or
|
||||
[mlx-whisper](mlx-whisper.md); this engine returns the pipeline's own word
|
||||
timestamps.
|
||||
|
||||
## Platform support
|
||||
|
||||
CUDA, Apple Silicon (MPS), ROCm (HIP), and CPU — wherever torch runs, on
|
||||
macOS, Windows, and Linux.
|
||||
|
||||
## Model selection
|
||||
|
||||
`OMNIVOICE_PYTORCH_ASR_MODEL` — default `openai/whisper-large-v3-turbo`. Any
|
||||
transformers-format Whisper repo works. Weights download on first load — see
|
||||
[downloading-models](../downloading-models.md).
|
||||
|
||||
## VRAM preflight
|
||||
|
||||
whisper-large-v3-turbo needs roughly 3.2 GiB before generation adds its
|
||||
workspace; loading it onto a nearly-full card "succeeds" and then the first
|
||||
transcribe OOMs with zero segments. So on CUDA the engine checks free VRAM
|
||||
against a 5 GB budget before loading and uses the CPU instead when the card
|
||||
is too full (flush the TTS model to restore GPU-speed ASR). Disable with
|
||||
`OMNIVOICE_ASR_VRAM_PREFLIGHT=0`.
|
||||
|
||||
## Quirks
|
||||
|
||||
- If the pipeline fails to import (`AutoFeatureExtractor` errors), the cause
|
||||
is either an incomplete transformers install or a torch/torchvision
|
||||
version mismatch — the error message names the exact reinstall command;
|
||||
the trio has to move together at the pinned versions
|
||||
([#549](https://github.com/debpalash/VoiceStudio/issues/549),
|
||||
[#1376](https://github.com/debpalash/VoiceStudio/issues/1376)).
|
||||
- Transcribes are time-bounded like every local engine:
|
||||
`OMNIVOICE_TRANSCRIBE_CHUNK_TIMEOUT_S` (default 120 s per dub chunk),
|
||||
`OMNIVOICE_ASR_TRANSCRIBE_TIMEOUT_S` (default 300 s whole-file).
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
@@ -0,0 +1,71 @@
|
||||
# VoiceStudio — Sherpa-ONNX Dictation Engine
|
||||
|
||||
The k2-fsa/sherpa-onnx ONNX runtime as a **live dictation** engine: small
|
||||
int8 models that transcribe faster than realtime on CPU, with identical
|
||||
behavior on macOS (arm64 + x86_64), Windows, and Linux — no CUDA dependency.
|
||||
Streaming models emit partial text frame-by-frame as you speak; offline
|
||||
models re-transcribe a growing buffer on a short cadence, so you see live
|
||||
partials either way.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- Ensure `sherpa-onnx` is installed (`uv add sherpa-onnx` on source installs).
|
||||
- Pick a dictation model in the app (Model Catalogue → Models lists the
|
||||
curated set below), or **Model Catalogue → Engines**, ASR tab → **Use**, or
|
||||
pin `OMNIVOICE_ASR_BACKEND=sherpa-onnx-asr`.
|
||||
- `OMNIVOICE_SHERPA_ASR_MODEL` selects the model — default
|
||||
`sherpa-parakeet-tdt-v3`.
|
||||
|
||||
## Best at
|
||||
|
||||
- **Live dictation on CPU** — the whole point of this engine. Fast partials,
|
||||
automatic endpointing on silence, no GPU required.
|
||||
- It also honors the regular offline `transcribe` contract, so any of its
|
||||
models can transcribe a file — plain text, single segment, no word
|
||||
timestamps, which makes it a dictation/notes tool rather than a dubbing
|
||||
engine.
|
||||
|
||||
## The 7 curated models
|
||||
|
||||
| Id | Type | Languages | Download |
|
||||
| --- | --- | --- | --- |
|
||||
| `sherpa-parakeet-tdt-v3` (default) | offline | 25 European languages | 0.67 GB |
|
||||
| `sherpa-parakeet-tdt-v2` | offline | English | 0.66 GB |
|
||||
| `sherpa-zipformer-bilingual-zh-en` | streaming | Chinese + English | 0.20 GB |
|
||||
| `sherpa-paraformer-bilingual-zh-en` | streaming | Chinese + English | 0.24 GB |
|
||||
| `sherpa-zipformer-en-20m` | streaming | English | 0.044 GB |
|
||||
| `sherpa-zipformer-zh-14m` | streaming | Chinese | 0.025 GB |
|
||||
| `sherpa-whisper-tiny` | offline | 90+ languages (auto-detect) | 0.104 GB |
|
||||
|
||||
Sizes are measured on-disk download sizes. Weights are int8 ONNX checkpoints
|
||||
that download on first use through the same HF cache as everything else —
|
||||
see [downloading-models](../downloading-models.md). Peak RAM for the 0.6B
|
||||
Parakeets is noticeably higher than their download size (onnxruntime's arena
|
||||
allocator holds onto freed blocks).
|
||||
|
||||
## Platform support
|
||||
|
||||
CPU on every platform, by the strict cross-platform default-parity rule.
|
||||
`OMNIVOICE_SHERPA_ASR_PROVIDER` can override the ONNX provider on a verified
|
||||
GPU build, but the default never diverges.
|
||||
|
||||
## Tuning
|
||||
|
||||
- `OMNIVOICE_SHERPA_ASR_THREADS` — decode threads (default 2; the 0.6B
|
||||
Parakeets automatically use up to 4 when the host has the cores, so decode
|
||||
keeps ahead of the speaker).
|
||||
- `OMNIVOICE_DICTATION_ENDPOINT_R1` / `OMNIVOICE_DICTATION_ENDPOINT_R2` —
|
||||
streaming endpoint rules in seconds (defaults 1.0 / 0.6: text commits
|
||||
~0.6 s after you stop speaking). Applied without a restart.
|
||||
|
||||
## Quirks
|
||||
|
||||
- The recognizer is **pre-warmed in the background** so the first dictation
|
||||
session doesn't pay the 1.3–2.5 s ONNX session load
|
||||
([#888](https://github.com/debpalash/VoiceStudio/issues/888)); it's then
|
||||
shared warm across sessions.
|
||||
- On Apple Silicon, installing the [parakeet-mlx](parakeet-mlx.md) model
|
||||
makes dictation prefer the GPU Parakeet automatically for the 25 covered
|
||||
languages; an explicitly selected sherpa model still wins.
|
||||
- The offline `transcribe` path reports `language: auto` — per-file language
|
||||
detection is only meaningful for the Whisper Tiny model.
|
||||
@@ -0,0 +1,75 @@
|
||||
# VoiceStudio — Sherpa-ONNX Engine
|
||||
|
||||
Sherpa-ONNX (k2-fsa/sherpa-onnx) is a unified C++ ONNX runtime that wraps
|
||||
20+ TTS model families (VITS, MeloTTS, Piper, Kokoro, Matcha, and more)
|
||||
behind one API, with pre-built wheels for Linux, Windows, and macOS (x86 and
|
||||
ARM). You bring the model: point VoiceStudio at any downloaded sherpa-onnx
|
||||
TTS model directory.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You want a specific community model (e.g. a Piper or VITS voice for your
|
||||
language) that no other engine hosts.
|
||||
- You need a dependable CPU engine with optional CUDA acceleration.
|
||||
|
||||
## Setup
|
||||
|
||||
1. Install the runtime:
|
||||
|
||||
```bash
|
||||
pip install sherpa-onnx
|
||||
```
|
||||
|
||||
2. Download a TTS model from the
|
||||
[sherpa-onnx releases](https://github.com/k2-fsa/sherpa-onnx/releases)
|
||||
and unpack it somewhere permanent.
|
||||
|
||||
3. Point VoiceStudio at the model directory and restart:
|
||||
|
||||
```bash
|
||||
export OMNIVOICE_SHERPA_MODEL=/path/to/model-dir
|
||||
```
|
||||
|
||||
4. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=sherpa-onnx`.
|
||||
|
||||
The directory must contain `model.onnx` and `tokens.txt`. Sherpa-ONNX ships
|
||||
no bundled default model, so the engine reports unavailable — with the
|
||||
reason — until `OMNIVOICE_SHERPA_MODEL` points at a valid directory. (Before
|
||||
this gate, selecting the engine unconfigured produced a failure mislabeled
|
||||
as out-of-memory —
|
||||
[#919](https://github.com/debpalash/VoiceStudio/issues/919).)
|
||||
|
||||
## Configuration
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_SHERPA_MODEL` | (unset) | Directory containing `model.onnx` + `tokens.txt` |
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output defaults to 22.05 kHz (the VITS default); once a model is loaded,
|
||||
its own sample rate is used.
|
||||
- CPU is the universal baseline; the CUDA onnxruntime provider is available
|
||||
on Linux/Windows installs.
|
||||
- **No cloning**: voices come from the model itself. Multi-speaker VITS
|
||||
models select a voice by numeric speaker id; speed is supported.
|
||||
- Languages depend entirely on the model you download.
|
||||
|
||||
## Known limits
|
||||
|
||||
- One model at a time — switching models means changing
|
||||
`OMNIVOICE_SHERPA_MODEL` and restarting.
|
||||
- No voice design, no reference-audio cloning, no emotion controls
|
||||
(see [expressive-speech.md](../expressive-speech.md)).
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "OMNIVOICE_SHERPA_MODEL not set" / "No model.onnx in …": follow Setup
|
||||
above — the variable must point at the *unpacked* model directory, not
|
||||
the archive.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[languages.md](../languages.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,76 @@
|
||||
# VoiceStudio — Supertonic-3 Engine
|
||||
|
||||
Supertonic-3 (Supertone Inc.) is a ~99M-parameter ONNX TTS engine covering
|
||||
31 languages with 7 preset voices at native 44.1 kHz. It is CPU-only by
|
||||
design — pure ONNX Runtime on the CPU execution provider, with no CUDA or
|
||||
MPS path in the upstream SDK — and runs in its own sidecar process so
|
||||
crashes and cold init never block the rest of VoiceStudio.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- Broad language coverage on machines with no usable GPU.
|
||||
- Preset-voice narration at a higher sample rate than the default engine.
|
||||
|
||||
## Setup
|
||||
|
||||
1. Install the optional dependency into VoiceStudio's environment:
|
||||
|
||||
```bash
|
||||
uv sync --extra supertonic
|
||||
```
|
||||
|
||||
(Or enable it from **Model Catalogue → Engines**, which installs the
|
||||
pinned `supertonic` wheel for you.)
|
||||
|
||||
2. **Accept the license in-app.** First use is gated behind an explicit
|
||||
acceptance dialog: the inference SDK is MIT, but the model weights are
|
||||
**OpenRAIL-M**, which carries use restrictions. The engine stays
|
||||
unavailable until you review and accept in **Model Catalogue → Engines →
|
||||
Supertonic-3**.
|
||||
|
||||
3. Select the engine via **Model Catalogue → Engines** or
|
||||
`OMNIVOICE_TTS_BACKEND=supertonic3`.
|
||||
|
||||
The first synthesis cold-downloads ~400 MB of model weights, pinned to an
|
||||
exact HuggingFace revision SHA so the bytes match what the SDK was validated
|
||||
against. See [downloading-models.md](../downloading-models.md).
|
||||
|
||||
## Voices
|
||||
|
||||
Seven preset voices are surfaced: `M1` (default), `M3`, `M4`, `M5`, `F3`,
|
||||
`F4`, `F5`. The SDK itself accepts the full `M1`–`M5` / `F1`–`F5` set if a
|
||||
caller passes one explicitly; unknown ids fall back to the default with a
|
||||
log line.
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- Output is 44.1 kHz mono.
|
||||
- Runs as a long-lived sidecar in the parent Python environment (its
|
||||
dependencies — onnxruntime, numpy, soundfile — already match
|
||||
VoiceStudio's pins); subsequent calls reuse the warm ONNX session.
|
||||
- `speed` is clamped to 0.7–2.0; quality steps clamp to 5–12.
|
||||
- Language is an ISO 639-1 code; Auto engages the SDK's multilingual
|
||||
fallback.
|
||||
|
||||
## Known limits
|
||||
|
||||
- **No cloning and no voice design** — preset voices only. Dub/batch jobs
|
||||
that need cloning won't select it.
|
||||
- CPU-only: hardware acceleration is a property of the upstream SDK, not a
|
||||
VoiceStudio limitation.
|
||||
- OpenRAIL-M weights are not covered by VoiceStudio's blanket
|
||||
commercial-use statement — review the model license terms in the
|
||||
acceptance dialog.
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- "supertonic package not installed": run the `uv sync` above or enable
|
||||
from the Model Catalogue.
|
||||
- "license not accepted": open **Model Catalogue → Engines → Supertonic-3**
|
||||
and accept.
|
||||
- Other issues: [install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [benchmarks.md](../benchmarks.md),
|
||||
[languages.md](../languages.md),
|
||||
[expressive-speech.md](../expressive-speech.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,76 @@
|
||||
# VoiceStudio — VoxCPM2 Engine
|
||||
|
||||
VoxCPM2 (OpenBMB) is the studio-quality option: native 48 kHz output,
|
||||
zero-shot voice cloning, and — uniquely among VoiceStudio's engines —
|
||||
**voice design**: creating a synthetic voice from a text description
|
||||
("young female, warm tone, British accent") with no reference audio at all.
|
||||
|
||||
## When to pick it
|
||||
|
||||
- You want voice design without a reference clip.
|
||||
- You want the highest output sample rate (48 kHz vs OmniVoice's 24 kHz).
|
||||
- Your language is among its 30 supported languages: Arabic, Burmese,
|
||||
Chinese, Danish, Dutch, English, Finnish, French, German, Greek, Hebrew,
|
||||
Hindi, Indonesian, Italian, Japanese, Khmer, Korean, Lao, Malay,
|
||||
Norwegian, Polish, Portuguese, Russian, Spanish, Swahili, Swedish,
|
||||
Tagalog, Thai, Turkish, Vietnamese.
|
||||
|
||||
## Requirements
|
||||
|
||||
- Python ≥ 3.10, PyTorch ≥ 2.5.
|
||||
- CUDA ≥ 12 recommended for full speed; MPS (Apple Silicon) and CPU also
|
||||
work.
|
||||
|
||||
## Setup
|
||||
|
||||
Install the package into VoiceStudio's Python environment:
|
||||
|
||||
```bash
|
||||
pip install "voxcpm>=2.0.3"
|
||||
```
|
||||
|
||||
That is a version **floor**, not a pin — an older install still works, but
|
||||
the engine logs an upgrade hint at load time. Then select the engine via
|
||||
**Model Catalogue → Engines** or `OMNIVOICE_TTS_BACKEND=voxcpm2`.
|
||||
|
||||
## Model selection
|
||||
|
||||
| Variable | Default | Meaning |
|
||||
| --- | --- | --- |
|
||||
| `OMNIVOICE_VOXCPM_MODEL` | `openbmb/VoxCPM2` | HuggingFace checkpoint to load |
|
||||
|
||||
The first use downloads a multi-GB checkpoint from HuggingFace. A download
|
||||
interrupted near the end used to abort the load outright
|
||||
([#1224](https://github.com/debpalash/VoiceStudio/issues/1224)); the load is
|
||||
now retried once with a fresh client. See
|
||||
[downloading-models.md](../downloading-models.md).
|
||||
|
||||
## Behaviour notes
|
||||
|
||||
- **Voice design:** provide a description and no reference audio.
|
||||
- **Cloning:** the reference clip is prepared before use (edge-silence trim
|
||||
and length cap) so dead air in a raw clip doesn't condition the output; on
|
||||
any prep problem the raw clip is used as-is.
|
||||
- **Style instructions** are passed as an inline prefix to the text.
|
||||
- VoxCPM2 emits mastered, studio-grade audio, so VoiceStudio **skips its
|
||||
shared mastering chain** (which is tuned for 24 kHz engines) — only benign
|
||||
loudness normalization applies.
|
||||
- A trailing-silence guard trims long near-silent tails from generations,
|
||||
keeping a short natural tail.
|
||||
|
||||
## Known limits
|
||||
|
||||
- Slower than the lightweight CPU engines — see
|
||||
[benchmarks.md](../benchmarks.md) and [performance.md](../performance.md).
|
||||
- Language coverage is 30 languages; for anything else use the default
|
||||
[OmniVoice](omnivoice.md) engine ([languages.md](../languages.md)).
|
||||
|
||||
## Troubleshooting
|
||||
|
||||
- Engine shows unavailable: the `voxcpm` package isn't installed — run the
|
||||
`pip install` above and restart VoiceStudio.
|
||||
- Repeated first-download failures: check connectivity/HF access, then see
|
||||
[install/troubleshooting.md](../install/troubleshooting.md).
|
||||
|
||||
See also: [expressive-speech.md](../expressive-speech.md),
|
||||
[disk usage](disk-usage.md).
|
||||
@@ -0,0 +1,80 @@
|
||||
# VoiceStudio — WhisperX Engine
|
||||
|
||||
WhisperX is the default ASR engine on CUDA and plain-CPU hosts: faster-whisper
|
||||
(CTranslate2) transcription plus a **wav2vec2 forced-alignment** pass that
|
||||
snaps word boundaries to ±10–30 ms (Whisper's own timestamps are ±100–300 ms).
|
||||
That word timing is what dubbing lip-sync depends on, which is why auto-detect
|
||||
prefers it wherever CTranslate2 can use the GPU.
|
||||
|
||||
## Selecting it
|
||||
|
||||
- **Model Catalogue → Engines**, ASR tab → **Use** on the WhisperX row, or
|
||||
- pin it with `OMNIVOICE_ASR_BACKEND=whisperx` (the env var always wins over
|
||||
the Settings pick; with neither set, auto-detect chooses per-hardware).
|
||||
|
||||
## Best at
|
||||
|
||||
- **Dubbing** — the forced alignment is the accuracy tier lip-sync needs.
|
||||
- **Batch transcription** with word-level subtitles.
|
||||
- Multi-speaker work: it pairs with pyannote speaker diarization — see
|
||||
[diarization](../features/diarization.md).
|
||||
|
||||
## Platform support
|
||||
|
||||
| Host | What happens |
|
||||
| --- | --- |
|
||||
| NVIDIA CUDA | GPU, float16 (degrades automatically, see below) |
|
||||
| CPU (any OS) | int8 — works, but slow for large-v3 |
|
||||
| Apple Silicon | CPU only — CTranslate2 has no Metal build, so auto-detect prefers [mlx-whisper](mlx-whisper.md) there ([#1127](https://github.com/debpalash/VoiceStudio/issues/1127)) |
|
||||
| AMD ROCm | CPU only — CTranslate2 has no HIP build, so auto-detect prefers [pytorch-whisper](pytorch-whisper.md) there ([#1529](https://github.com/debpalash/VoiceStudio/issues/1529)) |
|
||||
|
||||
## Model selection
|
||||
|
||||
- `ASR_MODEL_WHISPERX` — default `large-v3`. Accepts the usual size aliases
|
||||
(`tiny` … `large-v3`, `distil-large-v3`) or a full HF repo id. Weights
|
||||
download on first load — see [downloading-models](../downloading-models.md).
|
||||
- `OMNIVOICE_ALIGN_DEVICE` — force the wav2vec2 aligner's device. Aligners
|
||||
exist for ~20 major languages; other languages keep Whisper's native word
|
||||
timestamps instead of failing.
|
||||
|
||||
## VRAM preflight and degradation
|
||||
|
||||
Loading fp16 large-v3 onto a nearly-full 8 GB card dies as a *native* CUDA
|
||||
abort — no Python exception, the whole backend goes down
|
||||
([#723](https://github.com/debpalash/VoiceStudio/issues/723)). So before every
|
||||
load the engine checks free VRAM against per-compute-type budgets
|
||||
(float16 5.0 GB, int8_float16 3.5 GB, int8 3.0 GB, scaled down for smaller
|
||||
models) and degrades the compute type — or falls to CPU int8 — instead of
|
||||
starting a load that would kill the process. Disable with
|
||||
`OMNIVOICE_ASR_VRAM_PREFLIGHT=0`.
|
||||
|
||||
Two more fallback chains run at load time:
|
||||
|
||||
- GPUs without efficient fp16 (older Maxwell/Pascal, GTX 16xx) raise a
|
||||
compute-type error — the engine retries int8_float16, then int8
|
||||
([#551](https://github.com/debpalash/VoiceStudio/issues/551)).
|
||||
- A genuine CUDA OOM retries on CPU int8, so dubbing still completes
|
||||
(slower, same model and accuracy).
|
||||
|
||||
## Quirks
|
||||
|
||||
- **cuDNN 8 required on CUDA.** CTranslate2 links cuDNN 8; if it's missing the
|
||||
process fast-fails with no traceback, so the engine is reported unavailable
|
||||
up front and selection falls through to pytorch-whisper, which uses torch's
|
||||
own cuDNN 9 ([#1371](https://github.com/debpalash/VoiceStudio/issues/1371)).
|
||||
- On some hardened Linux kernels CTranslate2's native library is rejected with
|
||||
"cannot enable executable stack" — reported as unavailable, not a crash
|
||||
([#692](https://github.com/debpalash/VoiceStudio/issues/692)).
|
||||
- A partially-installed environment (interrupted sync, antivirus quarantine)
|
||||
can break WhisperX's deep import chain (whisperx → pyannote →
|
||||
lightning_fabric). The engine is then reported unavailable with a repair
|
||||
hint — reinstall, or `uv sync --reinstall` on a source checkout
|
||||
([#1185](https://github.com/debpalash/VoiceStudio/issues/1185)).
|
||||
- Audio is decoded through VoiceStudio's validated ffmpeg, not a bare `ffmpeg`
|
||||
PATH lookup ([#479](https://github.com/debpalash/VoiceStudio/issues/479)).
|
||||
- Transcribes are time-bounded: each dub chunk by
|
||||
`OMNIVOICE_TRANSCRIBE_CHUNK_TIMEOUT_S` (default 120 s), whole files by
|
||||
`OMNIVOICE_ASR_TRANSCRIBE_TIMEOUT_S` (default 300 s). Raise them for very
|
||||
long files on slow hardware.
|
||||
|
||||
Speed comparisons across engines live in [performance](../performance.md).
|
||||
+12
-8
@@ -13,12 +13,12 @@ and [`palashdeb/omnivoice-studio` on Docker Hub](https://hub.docker.com/r/palash
|
||||
> |-----|--------------|
|
||||
> | `:latest` | **Rolling preview** — latest commit on `main`, at or ahead of the last release. This is the preview channel; pin `:stable` for production. |
|
||||
> | `:stable` | Most recent versioned release (updated on every `v*` git tag) |
|
||||
> | `:0.4.1` | Exact release version |
|
||||
> | `:0.4` | Latest patch within the 0.4 minor |
|
||||
> | `:0.5.0` | Exact release version |
|
||||
> | `:0.5` | Latest patch within the 0.5 minor |
|
||||
> | `:main` | Alias of the same rolling `main` build as `:latest` |
|
||||
> | `:sha-xxxxxxx` | Specific commit (produced by manual workflow dispatch) |
|
||||
> | `:rocm` | **AMD GPU (ROCm) build** of the rolling preview — the ROCm analogue of `:latest` |
|
||||
> | `:stable-rocm`, `:0.4.1-rocm`, `:0.4-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding CUDA tags above |
|
||||
> | `:stable-rocm`, `:0.5.0-rocm`, `:0.5-rocm`, `:sha-xxxxxxx-rocm` | ROCm builds of the corresponding CUDA tags above |
|
||||
>
|
||||
> Versioning rule: preview builds always come from `main` and never
|
||||
> version-sort below `:stable` — upgrades flow naturally.
|
||||
@@ -89,7 +89,7 @@ PublishPort=127.0.0.1:3900:3900
|
||||
Volume=omnivoice-data:/app/omnivoice_data
|
||||
```
|
||||
|
||||
Release pins exist too: `:stable-rocm`, `:0.4.1-rocm`, `:0.4-rocm` mirror
|
||||
Release pins exist too: `:stable-rocm`, `:0.5.0-rocm`, `:0.5-rocm` mirror
|
||||
the CUDA tags exactly.
|
||||
|
||||
> **Consumer cards and APUs (RX 6000/7000, Strix Point/Halo):** the backend
|
||||
@@ -192,10 +192,14 @@ docker run -e OMNIVOICE_PUBLIC_API_BASE=https://api.your-host.example \
|
||||
> may instead bake `VITE_OMNIVOICE_API` at build time, but the runtime var above
|
||||
> is simpler and image-agnostic.
|
||||
|
||||
> **Security:** VoiceStudio ships no authentication. Anything on your LAN with
|
||||
> the URL can use the app. Put it behind a reverse proxy with `basic_auth`
|
||||
> (Caddy / nginx + htpasswd) or a private network overlay (Tailscale, ZeroTier)
|
||||
> before exposing publicly.
|
||||
> **Security:** Loopback-only publishing is the safe default. On a trusted LAN,
|
||||
> set a long random `OMNIVOICE_API_KEY` with `docker run -e` or Compose; the
|
||||
> browser will prompt for it. The optional six-digit share PIN permits casual
|
||||
> consumption access but does not authorize administration or dictation. On any
|
||||
> untrusted network, plain HTTP is not safe for the API key or session cookie.
|
||||
> Keep the backend on an encrypted private overlay such as Tailscale/ZeroTier;
|
||||
> do not expose it directly to the public internet. See [API
|
||||
> authentication](../api-auth.md) for the complete access model.
|
||||
|
||||
## Volume mounts
|
||||
|
||||
|
||||
@@ -80,6 +80,9 @@ None of them are required — the defaults are chosen for the common case.
|
||||
|
||||
| Variable | Default | What it does |
|
||||
|---|---|---|
|
||||
| `OMNIVOICE_DEVICE` | `auto` | Pin the compute device (`cuda` / `rocm` / `xpu` / `mps` / `cpu`) instead of auto-detect. Same control lives in **Settings → Performance & Device** (the env var wins over the UI pick). Honored only for devices the host actually has — a family that isn't detected is noted and ignored, never obeyed blindly. Applies at the next backend start. |
|
||||
| `OMNIVOICE_FLASHINFER` | `0` | CUDA-only accelerated decoding for the default engine via [FlashInfer](https://github.com/flashinfer-ai/flashinfer) kernels (packed CFG attention, fused RMSNorm/RoPE/GEMM) — ~2x on upstream's benchmarks. `1` enables it; `graph` also captures CUDA graphs (best when you render one thing at a time). Requires installing the optional `flashinfer-python` package into the backend environment first (`uv pip install flashinfer-python flashinfer-jit-cache --extra-index-url https://flashinfer.ai/whl/cu128/`, matching your CUDA build). Replaces `torch.compile` for that session, pins inference to a single GPU thread (the FlashInfer attention plan is per-generation state), and keeps fused copies of the attention/MLP weights resident (~roughly half the LLM's weight size extra VRAM) — leave it off on tight-VRAM cards. If the package is missing or a FlashInfer/CUDA-graph kernel fails at runtime, the app logs the reason and falls back to the standard path; failures outside those kernels (e.g. a genuine out-of-memory) surface normally. |
|
||||
| `OMNIVOICE_PROMPT_DISK_CACHE` | `1` | Persist encoded voice-clone references (`prompt_cache/` in the app data dir, ~10 KB per voice, 32 newest kept) so the first generation with a known voice after a restart skips the reference re-encode and any auto-transcription. Set `0` to keep the cache in memory only. |
|
||||
| `OMNIVOICE_IDLE_TIMEOUT_S` | `900` | Seconds of idle before the TTS model unloads to free memory. Raise it (e.g. `3600`) if you generate in bursts and dislike the ~8 s reload; lower it on tight-memory machines. |
|
||||
| `OMNIVOICE_SIDECAR_IDLE_TIMEOUT_S` | `300` | Same idea for sidecar engines (IndexTTS 2.5 etc.). |
|
||||
| `OMNIVOICE_LLM_CONCURRENCY` | `6` | Parallel LLM translation calls during a dub. Raise for a fast API endpoint, lower if your provider rate-limits. |
|
||||
@@ -229,6 +232,9 @@ uv run python scripts/bench_pipeline.py tts clone # just these stages
|
||||
If you report a performance issue, pasting its table (plus your platform and
|
||||
RAM/VRAM) turns a guessing game into a bisect.
|
||||
|
||||
Measured results per engine/device — and how to contribute yours — live in
|
||||
[benchmarks.md](benchmarks.md).
|
||||
|
||||
## Things that look like knobs but aren't
|
||||
|
||||
- **Deleting and re-adding a voice** doesn't speed anything up; the reference
|
||||
|
||||
+13
-2
@@ -153,6 +153,15 @@ fallback is reported once. ASR, diarization and translation also remain local. D
|
||||
runs here, deliberately and permanently, because there latency *is* the
|
||||
feature. The remaining operations are being ported one at a time.
|
||||
|
||||
### Voice identity parity
|
||||
|
||||
For TTS, the worker receives the complete local rendering contract: the voice
|
||||
profile's reference audio and transcript, its pinned seed, model quality
|
||||
controls, text chunking/crossfade settings, and output effect preset. The
|
||||
worker runs the same native or generic rendering pipeline as local
|
||||
`/generate`; selecting a gallery voice therefore does not turn it into a new
|
||||
random voice merely because it was rendered on another GPU.
|
||||
|
||||
The picker knows this. It resolves against the surface you are on, so a chosen
|
||||
worker reads **Local** on a tab whose work has no remote path yet and names the
|
||||
reason, instead of showing a green dot next to a GPU that receives nothing. The
|
||||
@@ -210,10 +219,12 @@ what is genuinely still in flight.
|
||||
**Version or feature mismatch.** The protocol keeps a two-release compatibility
|
||||
window, but release numbers alone do not prove that a worker understands every
|
||||
additive command. Registration therefore also declares named features for task
|
||||
inputs, progress leases, and remote model downloads. A worker outside the
|
||||
inputs, progress leases, remote model downloads, and the voice-identity render
|
||||
pipeline. A worker outside the
|
||||
version window, or one missing a required feature, is refused with
|
||||
`UPGRADE_REQUIRED` and an update instruction before any task runs. It can never
|
||||
silently render without reference audio or leave a download stuck at 0%.
|
||||
silently render without reference audio, substitute a different voice, or leave
|
||||
a download stuck at 0%.
|
||||
|
||||
Every remote failure includes a concrete next step. Capacity, missing models,
|
||||
expired leases or sessions, authentication, rejected inputs, and result upload
|
||||
|
||||
@@ -16,6 +16,10 @@ For another device on the same network — e.g. opening the web UI on your phone
|
||||
|
||||
You can also drive this from **Settings → Sharing & Remote Access**.
|
||||
|
||||
Desktop installers include the web interface used by the LAN address; another
|
||||
device does not need VoiceStudio installed and the host does not need a source
|
||||
checkout or a separate frontend development server.
|
||||
|
||||
### How the PIN works
|
||||
- A fresh 6-digit PIN is generated each time you enable sharing; it is never written to disk.
|
||||
- The QR encodes the PIN (`…/?pin=######`) so scanning connects in one step. Typing the bare URL instead prompts for the PIN.
|
||||
|
||||
@@ -845,6 +845,59 @@ pub fn copy_dir_recursive(src: &Path, dst: &Path) -> io::Result<()> {
|
||||
Ok(())
|
||||
}
|
||||
|
||||
/// Install the production SPA beside `backend/`, where the Python server's
|
||||
/// static-file mount resolves it for Network Sharing clients.
|
||||
fn sync_packaged_frontend(resource_root: &Path, project_dir: &Path) -> io::Result<()> {
|
||||
let source = resource_root.join("frontend").join("dist");
|
||||
if !source.join("index.html").is_file() {
|
||||
return Err(io::Error::new(
|
||||
io::ErrorKind::NotFound,
|
||||
"bundled frontend is missing index.html",
|
||||
));
|
||||
}
|
||||
|
||||
let destination = project_dir.join("frontend").join("dist");
|
||||
let frontend_dir = destination.parent().expect("frontend dist has a parent");
|
||||
let staging = frontend_dir.join(".dist-staging");
|
||||
let backup = frontend_dir.join(".dist-backup");
|
||||
fs::create_dir_all(frontend_dir)?;
|
||||
if staging.exists() {
|
||||
fs::remove_dir_all(&staging)?;
|
||||
}
|
||||
// A previous process may have died after moving the live shell aside but
|
||||
// before installing staging. Restore the only known-good SPA before doing
|
||||
// any new work; never discard that recovery copy merely because startup
|
||||
// retried.
|
||||
if !destination.exists() && backup.exists() {
|
||||
fs::rename(&backup, &destination)?;
|
||||
}
|
||||
if let Err(error) = copy_dir_recursive(&source, &staging) {
|
||||
let _ = fs::remove_dir_all(&staging);
|
||||
return Err(error);
|
||||
}
|
||||
|
||||
if destination.exists() {
|
||||
if backup.exists() {
|
||||
// An interrupted cleanup can leave an incomplete backup. Remove
|
||||
// it before touching the known-working destination; if cleanup
|
||||
// fails, abort with the live shell still intact.
|
||||
fs::remove_dir_all(&backup)?;
|
||||
}
|
||||
fs::rename(&destination, &backup)?;
|
||||
}
|
||||
if let Err(error) = fs::rename(&staging, &destination) {
|
||||
if backup.exists() {
|
||||
let _ = fs::rename(&backup, &destination);
|
||||
}
|
||||
let _ = fs::remove_dir_all(&staging);
|
||||
return Err(error);
|
||||
}
|
||||
if backup.exists() {
|
||||
fs::remove_dir_all(backup)?;
|
||||
}
|
||||
Ok(())
|
||||
}
|
||||
|
||||
/// Refresh `pyproject.toml` + `uv.lock` in the project dir from the bundled
|
||||
/// resources, so an upgraded app never runs freshly-synced backend code against
|
||||
/// the stale dependency manifests from when the venv was first created (#307 —
|
||||
@@ -1539,11 +1592,13 @@ manually, then relaunch.",
|
||||
if let Some(ref res) = resource_dir {
|
||||
let flat = res.clone();
|
||||
let up2 = res.join("_up_").join("_up_");
|
||||
let (res_omni, res_backend) = if flat.join("pyproject.toml").is_file() {
|
||||
(flat.join("omnivoice"), flat.join("backend"))
|
||||
let res_root = if flat.join("pyproject.toml").is_file() {
|
||||
flat
|
||||
} else {
|
||||
(up2.join("omnivoice"), up2.join("backend"))
|
||||
up2
|
||||
};
|
||||
let res_omni = res_root.join("omnivoice");
|
||||
let res_backend = res_root.join("backend");
|
||||
if res_omni.is_dir() {
|
||||
let omnivoice_dir = project_dir.join("omnivoice");
|
||||
let _ = fs::remove_dir_all(&omnivoice_dir);
|
||||
@@ -1561,6 +1616,11 @@ manually, then relaunch.",
|
||||
}
|
||||
log::info!("Synced backend/ from bundle");
|
||||
}
|
||||
if let Err(e) = sync_packaged_frontend(&res_root, &project_dir) {
|
||||
fail(progress, &format!("Failed to sync frontend/dist: {}", e));
|
||||
return None;
|
||||
}
|
||||
log::info!("Synced frontend/dist from bundle");
|
||||
// #307: the source dirs above track the bundle, so the
|
||||
// dependency manifests must too — otherwise an upgrade runs
|
||||
// new code against a venv that predates newly added deps.
|
||||
@@ -1659,6 +1719,17 @@ the existing venv; newly added dependencies may be missing (#307)",
|
||||
// copies from when the venv was first created.
|
||||
if let Ok(res) = app.path().resource_dir() {
|
||||
let _ = refresh_project_manifests(&res, &project_dir);
|
||||
let flat = res.clone();
|
||||
let up2 = res.join("_up_").join("_up_");
|
||||
let res_root = if flat.join("pyproject.toml").is_file() {
|
||||
flat
|
||||
} else {
|
||||
up2
|
||||
};
|
||||
if let Err(e) = sync_packaged_frontend(&res_root, &project_dir) {
|
||||
fail(progress, &format!("Failed to sync frontend/dist: {}", e));
|
||||
return None;
|
||||
}
|
||||
}
|
||||
let mut repair_cmd = Command::new(&uv_path);
|
||||
scrub_python_env(&mut repair_cmd); // #144: don't inherit AppImage's bundled Python
|
||||
@@ -1763,16 +1834,22 @@ the existing venv; newly added dependencies may be missing (#307)",
|
||||
let flat = resource_dir.clone();
|
||||
let up2 = resource_dir.join("_up_").join("_up_");
|
||||
|
||||
let (resource_pyproject, resource_uvlock, resource_readme, resource_changelog, resource_omnivoice, resource_backend) = if flat.join("pyproject.toml").is_file() {
|
||||
(flat.join("pyproject.toml"), flat.join("uv.lock"), flat.join("README.md"), flat.join("CHANGELOG.md"), flat.join("omnivoice"), flat.join("backend"))
|
||||
let resource_root = if flat.join("pyproject.toml").is_file() {
|
||||
flat
|
||||
} else if up2.join("pyproject.toml").is_file() {
|
||||
(up2.join("pyproject.toml"), up2.join("uv.lock"), up2.join("README.md"), up2.join("CHANGELOG.md"), up2.join("omnivoice"), up2.join("backend"))
|
||||
up2
|
||||
} else {
|
||||
fail(progress, &format!(
|
||||
"Missing bootstrap resources — checked flat={} and _up_={}",
|
||||
flat.display(), up2.display()));
|
||||
return None;
|
||||
};
|
||||
let resource_pyproject = resource_root.join("pyproject.toml");
|
||||
let resource_uvlock = resource_root.join("uv.lock");
|
||||
let resource_readme = resource_root.join("README.md");
|
||||
let resource_changelog = resource_root.join("CHANGELOG.md");
|
||||
let resource_omnivoice = resource_root.join("omnivoice");
|
||||
let resource_backend = resource_root.join("backend");
|
||||
|
||||
if !resource_pyproject.is_file() || !resource_backend.is_dir() {
|
||||
fail(progress, &format!(
|
||||
@@ -1821,6 +1898,10 @@ the existing venv; newly added dependencies may be missing (#307)",
|
||||
fail(progress, &format!("copy backend/: {}", e));
|
||||
return None;
|
||||
}
|
||||
if let Err(e) = sync_packaged_frontend(&resource_root, &project_dir) {
|
||||
fail(progress, &format!("copy frontend/dist: {}", e));
|
||||
return None;
|
||||
}
|
||||
|
||||
let uv_path = match resolve_uv(app, &app_data, progress) {
|
||||
Ok(p) => p,
|
||||
@@ -2051,6 +2132,118 @@ mod tests {
|
||||
use super::*;
|
||||
use std::collections::HashMap;
|
||||
|
||||
#[test]
|
||||
fn packaged_frontend_is_installed_for_the_lan_server() {
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
let source = resources.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(source.join("assets")).unwrap();
|
||||
fs::write(source.join("index.html"), "new shell").unwrap();
|
||||
fs::write(source.join("assets").join("client.js"), "new client").unwrap();
|
||||
|
||||
let installed = project.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(&installed).unwrap();
|
||||
fs::write(installed.join("index.html"), "stale shell").unwrap();
|
||||
|
||||
sync_packaged_frontend(resources.path(), project.path()).unwrap();
|
||||
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("index.html")).unwrap(),
|
||||
"new shell"
|
||||
);
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("assets").join("client.js")).unwrap(),
|
||||
"new client"
|
||||
);
|
||||
}
|
||||
|
||||
#[test]
|
||||
fn packaged_frontend_error_does_not_expose_resource_path() {
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
|
||||
let error = sync_packaged_frontend(resources.path(), project.path()).unwrap_err();
|
||||
|
||||
assert_eq!(error.kind(), io::ErrorKind::NotFound);
|
||||
assert_eq!(error.to_string(), "bundled frontend is missing index.html");
|
||||
assert!(!error.to_string().contains(&resources.path().display().to_string()));
|
||||
}
|
||||
|
||||
#[cfg(unix)]
|
||||
#[test]
|
||||
fn failed_packaged_frontend_copy_preserves_installed_shell() {
|
||||
use std::os::unix::fs::symlink;
|
||||
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
let source = resources.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(source.join("assets")).unwrap();
|
||||
fs::write(source.join("index.html"), "new shell").unwrap();
|
||||
symlink("missing-client.js", source.join("assets").join("client.js")).unwrap();
|
||||
|
||||
let installed = project.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(&installed).unwrap();
|
||||
fs::write(installed.join("index.html"), "working shell").unwrap();
|
||||
|
||||
sync_packaged_frontend(resources.path(), project.path()).unwrap_err();
|
||||
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("index.html")).unwrap(),
|
||||
"working shell"
|
||||
);
|
||||
}
|
||||
|
||||
#[cfg(unix)]
|
||||
#[test]
|
||||
fn interrupted_frontend_swap_recovers_backup_before_a_later_copy_failure() {
|
||||
use std::os::unix::fs::symlink;
|
||||
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
let source = resources.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(source.join("assets")).unwrap();
|
||||
fs::write(source.join("index.html"), "new shell").unwrap();
|
||||
symlink("missing-client.js", source.join("assets").join("client.js")).unwrap();
|
||||
|
||||
let frontend = project.path().join("frontend");
|
||||
let installed = frontend.join("dist");
|
||||
let backup = frontend.join(".dist-backup");
|
||||
fs::create_dir_all(&backup).unwrap();
|
||||
fs::write(backup.join("index.html"), "working backup shell").unwrap();
|
||||
|
||||
sync_packaged_frontend(resources.path(), project.path()).unwrap_err();
|
||||
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("index.html")).unwrap(),
|
||||
"working backup shell"
|
||||
);
|
||||
}
|
||||
|
||||
#[test]
|
||||
fn interrupted_backup_cleanup_failure_preserves_working_destination() {
|
||||
let resources = tempfile::tempdir().unwrap();
|
||||
let project = tempfile::tempdir().unwrap();
|
||||
let source = resources.path().join("frontend").join("dist");
|
||||
fs::create_dir_all(&source).unwrap();
|
||||
fs::write(source.join("index.html"), "new shell").unwrap();
|
||||
|
||||
let frontend = project.path().join("frontend");
|
||||
let installed = frontend.join("dist");
|
||||
let backup = frontend.join(".dist-backup");
|
||||
fs::create_dir_all(&installed).unwrap();
|
||||
fs::write(installed.join("index.html"), "working shell").unwrap();
|
||||
// A non-directory at the interrupted backup path makes cleanup fail
|
||||
// and would also prevent the live destination from being renamed.
|
||||
fs::write(&backup, "partial backup").unwrap();
|
||||
|
||||
sync_packaged_frontend(resources.path(), project.path()).unwrap_err();
|
||||
|
||||
assert_eq!(
|
||||
fs::read_to_string(installed.join("index.html")).unwrap(),
|
||||
"working shell"
|
||||
);
|
||||
}
|
||||
|
||||
#[test]
|
||||
fn update_drift_sync_preserves_user_installed_engines() {
|
||||
// #1029: the routine update sync must carry --inexact so a
|
||||
|
||||
@@ -79,7 +79,8 @@
|
||||
"../../README.md",
|
||||
"../../CHANGELOG.md",
|
||||
"../../omnivoice",
|
||||
"../../backend"
|
||||
"../../backend",
|
||||
"../../frontend/dist"
|
||||
],
|
||||
"externalBin": [
|
||||
"binaries/uv",
|
||||
|
||||
@@ -182,15 +182,16 @@ describe('apiFetch 401 routing', () => {
|
||||
dispatch.mockRestore();
|
||||
});
|
||||
|
||||
const stub401 = (detail: string) =>
|
||||
const stubStatus = (status: number, statusText: string, detail: string) =>
|
||||
vi.fn(() =>
|
||||
Promise.resolve({
|
||||
ok: false,
|
||||
status: 401,
|
||||
statusText: 'Unauthorized',
|
||||
status,
|
||||
statusText,
|
||||
text: async () => JSON.stringify({ detail }),
|
||||
}),
|
||||
) as any;
|
||||
const stub401 = (detail: string) => stubStatus(401, 'Unauthorized', detail);
|
||||
|
||||
const authEvent = () =>
|
||||
dispatch.mock.calls.map((c) => c[0]).find((e) => (e as Event).type === 'ov:auth-required');
|
||||
@@ -227,6 +228,70 @@ describe('apiFetch 401 routing', () => {
|
||||
expect(authEvent()).toBeTruthy();
|
||||
expect((authEvent() as any).detail.mode).toBe('pin');
|
||||
});
|
||||
|
||||
const stub403 = (detail: string) => stubStatus(403, 'Forbidden', detail);
|
||||
|
||||
it('dispatches ov:auth-required {mode:"apikey"} on an admin-gate 403 (#1525)', async () => {
|
||||
globalThis.fetch = stub403('loopback origin or admin API key required');
|
||||
const { apiFetch } = await import('./client');
|
||||
try {
|
||||
await apiFetch('/system/info');
|
||||
} catch {
|
||||
/* ApiError expected */
|
||||
}
|
||||
expect(authEvent()).toBeTruthy();
|
||||
expect((authEvent() as any).detail.mode).toBe('apikey');
|
||||
});
|
||||
|
||||
it('does not dispatch ov:auth-required on other 403s (CSRF / desktop-only)', async () => {
|
||||
globalThis.fetch = stub403('browser origin rejected');
|
||||
const { apiFetch } = await import('./client');
|
||||
try {
|
||||
await apiFetch('/system/info');
|
||||
} catch {
|
||||
/* ApiError expected */
|
||||
}
|
||||
expect(authEvent()).toBeFalsy();
|
||||
});
|
||||
|
||||
it('a stale 403 neither clears a new session nor reopens the auth gate (PR #1569 race)', async () => {
|
||||
// The request goes out with an old credential; while it is in flight the
|
||||
// user completes another key exchange. A late 403 may only invalidate the
|
||||
// credentials the failed request actually carried — wiping the fresh
|
||||
// session or reopening the gate would undo the successful login.
|
||||
sessionStorage.setItem(
|
||||
ADMIN_SESSION_STORAGE_KEY,
|
||||
JSON.stringify({
|
||||
token: `ovs_admin_session_${'O'.repeat(43)}`,
|
||||
expiresAt: Date.now() / 1000 + 3600,
|
||||
apiBase: API,
|
||||
}),
|
||||
);
|
||||
globalThis.fetch = vi.fn(() => {
|
||||
sessionStorage.setItem(
|
||||
ADMIN_SESSION_STORAGE_KEY,
|
||||
JSON.stringify({
|
||||
token: `ovs_admin_session_${'N'.repeat(43)}`,
|
||||
expiresAt: Date.now() / 1000 + 3600,
|
||||
apiBase: API,
|
||||
}),
|
||||
);
|
||||
return Promise.resolve({
|
||||
ok: false,
|
||||
status: 403,
|
||||
statusText: 'Forbidden',
|
||||
text: async () => JSON.stringify({ detail: 'loopback origin or admin API key required' }),
|
||||
});
|
||||
}) as any;
|
||||
const { apiFetch } = await import('./client');
|
||||
try {
|
||||
await apiFetch('/system/info');
|
||||
} catch {
|
||||
/* ApiError expected */
|
||||
}
|
||||
expect(authEvent()).toBeFalsy();
|
||||
expect(sessionStorage.getItem(ADMIN_SESSION_STORAGE_KEY)).not.toBeNull();
|
||||
});
|
||||
});
|
||||
|
||||
describe('apiFetch 404 from a non-VoiceStudio server (#1385)', () => {
|
||||
|
||||
@@ -528,15 +528,37 @@ export async function apiFetch(path: string, opts: ApiFetchOptions = {}): Promis
|
||||
// "API key required" (BearerKeyMiddleware, OMNIVOICE_API_KEY) vs anything
|
||||
// else, i.e. "PIN required" (NetworkAccessMiddleware). Both are 401; the
|
||||
// detail is the only discriminator (only two 401 sites exist backend-side).
|
||||
if (backendTarget && res.status === 401 && typeof window !== 'undefined') {
|
||||
// The router-level admin gates answer 403 "loopback origin or admin API
|
||||
// key required" (require_admin/require_admin_action) — same situation, the
|
||||
// client just isn't admin-authenticated — so it routes to the API-key form
|
||||
// too. Other 403s (CSRF "browser origin rejected", loopback-only routes)
|
||||
// are NOT credential gaps; presenting a key won't help, so they stay plain
|
||||
// errors.
|
||||
const adminGate403 =
|
||||
res.status === 403 &&
|
||||
typeof detail === 'string' &&
|
||||
detail.toLowerCase().includes('admin api key');
|
||||
if (backendTarget && (res.status === 401 || adminGate403) && typeof window !== 'undefined') {
|
||||
// readError's declared `string` return isn't guaranteed at runtime —
|
||||
// `j.detail` can be a structured object/array on a future 401. Match only
|
||||
// real strings (avoids both a `.toLowerCase()` crash and `String()` itself
|
||||
// throwing on a malformed object); anything else falls back to PIN.
|
||||
// (No adminGate403 arm here: "admin api key" ⊇ "api key", so the sniff
|
||||
// below already yields 'apikey' for every admin-gate 403.)
|
||||
const mode =
|
||||
typeof detail === 'string' && detail.toLowerCase().includes('api key') ? 'apikey' : 'pin';
|
||||
if (mode === 'apikey') clearAdminSession();
|
||||
window.dispatchEvent(new CustomEvent('ov:auth-required', { detail: { mode } }));
|
||||
// A failed response may only invalidate the credentials it actually
|
||||
// carried (`session` is captured at send time). Clearing blindly let
|
||||
// a stale 403 that landed after a key exchange wipe the fresh
|
||||
// session, reloading a successful login straight back into the gate.
|
||||
const currentSession = getAdminSession(API);
|
||||
const staleAdminResponse = mode === 'apikey' && currentSession?.token !== session?.token;
|
||||
if (mode === 'apikey' && !staleAdminResponse && session) {
|
||||
clearAdminSession();
|
||||
}
|
||||
if (!staleAdminResponse) {
|
||||
window.dispatchEvent(new CustomEvent('ov:auth-required', { detail: { mode } }));
|
||||
}
|
||||
}
|
||||
// Structured details (e.g. the typed asr_model_missing 409) carry a
|
||||
// human-readable `message` — use it for the Error message instead of
|
||||
|
||||
@@ -0,0 +1,164 @@
|
||||
/**
|
||||
* Settings → Performance: the compute-device override.
|
||||
*
|
||||
* Lets the user pin which device family the backend uses (auto / CUDA /
|
||||
* ROCm / XPU / MPS / CPU) instead of trusting auto-detect — the fix for the
|
||||
* "auto-detect picked wrong" issue class. Options are limited to families
|
||||
* that actually exist on this host (plus Auto and CPU, which always do);
|
||||
* the pick applies at the next backend start, same restart contract as the
|
||||
* rest of this tab. `OMNIVOICE_DEVICE` pins the value and disables the
|
||||
* control rather than pretending the UI choice would win.
|
||||
*
|
||||
* Endpoints:
|
||||
* GET /api/settings/compute-device
|
||||
* → {value, applied, restart_required, effective_family, auto_family,
|
||||
* available_families, env_pinned, choices}
|
||||
* PUT /api/settings/compute-device body {"value": "auto"|family}
|
||||
*/
|
||||
import React, { useCallback, useEffect, useState } from 'react';
|
||||
import { MonitorCog } from 'lucide-react';
|
||||
import { useTranslation } from 'react-i18next';
|
||||
import { apiJson, apiFetch } from '../../api/client';
|
||||
import { Select } from '../../ui';
|
||||
import { SettingsSection, SettingRow } from './primitives';
|
||||
import RestartBadge from './RestartBadge';
|
||||
|
||||
// English fallbacks; the rendered label comes from the locale files
|
||||
// (settings.device_family_*) so localized builds stay localized.
|
||||
const FAMILY_FALLBACKS = {
|
||||
cuda: 'NVIDIA GPU (CUDA)',
|
||||
rocm: 'AMD GPU (ROCm)',
|
||||
xpu: 'Intel GPU (XPU)',
|
||||
mps: 'Apple GPU (MPS)',
|
||||
cpu: 'CPU',
|
||||
};
|
||||
|
||||
export default function ComputeDevicePanel() {
|
||||
const { t } = useTranslation();
|
||||
const [state, setState] = useState(null);
|
||||
const [saving, setSaving] = useState(false);
|
||||
const [error, setError] = useState(null);
|
||||
|
||||
const refresh = useCallback(async () => {
|
||||
setError(null);
|
||||
try {
|
||||
setState(await apiJson('/api/settings/compute-device'));
|
||||
} catch (e) {
|
||||
setError(
|
||||
e?.message ||
|
||||
t('settings.device_load_failed', { defaultValue: 'Failed to load device setting' }),
|
||||
);
|
||||
}
|
||||
}, [t]);
|
||||
|
||||
useEffect(() => {
|
||||
refresh();
|
||||
}, [refresh]);
|
||||
|
||||
const onChange = async (e) => {
|
||||
const value = e.target.value;
|
||||
setSaving(true);
|
||||
setError(null);
|
||||
try {
|
||||
const res = await apiFetch('/api/settings/compute-device', {
|
||||
method: 'PUT',
|
||||
headers: { 'Content-Type': 'application/json' },
|
||||
body: JSON.stringify({ value }),
|
||||
});
|
||||
const body = await res.json().catch(() => null);
|
||||
if (body?.value) setState(body);
|
||||
else refresh();
|
||||
} catch (err) {
|
||||
setError(
|
||||
err?.message || t('settings.perf_save_failed', { defaultValue: 'Failed to save setting' }),
|
||||
);
|
||||
// Re-sync so the UI never shows a pick that didn't persist — but keep
|
||||
// the save error visible (refresh() would clear it).
|
||||
try {
|
||||
setState(await apiJson('/api/settings/compute-device'));
|
||||
} catch {
|
||||
/* the save error already on screen covers this */
|
||||
}
|
||||
} finally {
|
||||
setSaving(false);
|
||||
}
|
||||
};
|
||||
|
||||
const label = t('settings.compute_device', { defaultValue: 'Compute device' });
|
||||
const families = state?.available_families || [];
|
||||
const familyLabel = (f) =>
|
||||
t(`settings.device_family_${f}`, { defaultValue: FAMILY_FALLBACKS[f] || f });
|
||||
|
||||
return (
|
||||
<SettingsSection
|
||||
icon={MonitorCog}
|
||||
title={t('settings.compute_device_title', { defaultValue: 'Compute device' })}
|
||||
description={t('settings.compute_device_desc', {
|
||||
defaultValue: 'Which device the backend runs models on. Auto is right for almost everyone.',
|
||||
})}
|
||||
>
|
||||
{error && (
|
||||
<div className="perfpanel__error" role="alert">
|
||||
{error}
|
||||
</div>
|
||||
)}
|
||||
|
||||
<SettingRow
|
||||
title={
|
||||
<>
|
||||
{label}
|
||||
<RestartBadge />
|
||||
</>
|
||||
}
|
||||
subtitle={(() => {
|
||||
const pinned = state?.env_pinned
|
||||
? t('settings.compute_device_env_pinned', {
|
||||
defaultValue: 'Pinned by the OMNIVOICE_DEVICE environment variable',
|
||||
})
|
||||
: null;
|
||||
const ignored = state?.override_ignored
|
||||
? t('settings.compute_device_ignored', {
|
||||
defaultValue: 'That device was not detected on this machine — Auto is in effect',
|
||||
})
|
||||
: null;
|
||||
// An env pin naming absent hardware needs BOTH facts: why the
|
||||
// control is disabled, and that the pin is not actually in effect.
|
||||
if (pinned && ignored) return `${pinned} · ${ignored}`;
|
||||
if (pinned) return pinned;
|
||||
if (ignored) return ignored;
|
||||
return state?.restart_required
|
||||
? t('settings.compute_device_restart', {
|
||||
defaultValue: 'Takes effect after the app restarts',
|
||||
})
|
||||
: undefined;
|
||||
})()}
|
||||
note={t('settings.compute_device_note', {
|
||||
defaultValue:
|
||||
'Only devices detected on this machine are listed. CPU always works; pinning a device never invents hardware.',
|
||||
})}
|
||||
control={
|
||||
<Select
|
||||
size="sm"
|
||||
value={state?.value ?? 'auto'}
|
||||
onChange={onChange}
|
||||
disabled={!state || saving || state?.env_pinned}
|
||||
aria-label={label}
|
||||
data-testid="compute-device-select"
|
||||
>
|
||||
<option value="auto">
|
||||
{t('settings.compute_device_auto', {
|
||||
defaultValue: 'Auto (recommended)',
|
||||
})}
|
||||
{state?.auto_family ? ` — ${familyLabel(state.auto_family)}` : ''}
|
||||
</option>
|
||||
{families.map((f) => (
|
||||
<option key={f} value={f}>
|
||||
{familyLabel(f)}
|
||||
</option>
|
||||
))}
|
||||
</Select>
|
||||
}
|
||||
/>
|
||||
</SettingsSection>
|
||||
);
|
||||
}
|
||||
@@ -0,0 +1,104 @@
|
||||
import { describe, it, expect, vi, beforeEach } from 'vitest';
|
||||
import { fireEvent, render, screen, waitFor } from '@testing-library/react';
|
||||
import React from 'react';
|
||||
|
||||
function mockFetchSequence(...responses) {
|
||||
const fn = vi.fn();
|
||||
for (const r of responses) {
|
||||
fn.mockResolvedValueOnce({
|
||||
ok: r.status >= 200 && r.status < 300,
|
||||
status: r.status,
|
||||
json: async () => r.body,
|
||||
text: async () => JSON.stringify(r.body),
|
||||
});
|
||||
}
|
||||
return fn;
|
||||
}
|
||||
|
||||
import ComputeDevicePanel from './ComputeDevicePanel';
|
||||
|
||||
const CUDA_HOST = {
|
||||
value: 'auto',
|
||||
applied: 'auto',
|
||||
restart_required: false,
|
||||
effective_family: 'cuda',
|
||||
auto_family: 'cuda',
|
||||
available_families: ['cuda', 'cpu'],
|
||||
env_pinned: false,
|
||||
choices: ['auto', 'cuda', 'rocm', 'xpu', 'mps', 'cpu'],
|
||||
};
|
||||
|
||||
describe('ComputeDevicePanel', () => {
|
||||
beforeEach(() => {
|
||||
vi.restoreAllMocks();
|
||||
});
|
||||
|
||||
it('offers only the detected families plus Auto', async () => {
|
||||
global.fetch = mockFetchSequence({ status: 200, body: CUDA_HOST });
|
||||
render(<ComputeDevicePanel />);
|
||||
// Wait for the LOADED state (3 options), not just the select — it
|
||||
// renders disabled with only Auto before the GET resolves.
|
||||
await waitFor(() => expect(screen.getByTestId('compute-device-select').options.length).toBe(3));
|
||||
const options = [...screen.getByTestId('compute-device-select').options].map((o) => o.value);
|
||||
// No mps/rocm/xpu on a CUDA host — an override can steer, not invent.
|
||||
expect(options).toEqual(['auto', 'cuda', 'cpu']);
|
||||
});
|
||||
|
||||
it('changing the pick PUTs the value and shows the restart note', async () => {
|
||||
const fetchMock = mockFetchSequence(
|
||||
{ status: 200, body: CUDA_HOST }, // initial GET
|
||||
{
|
||||
status: 200,
|
||||
body: { ...CUDA_HOST, value: 'cpu', restart_required: true },
|
||||
}, // PUT echo
|
||||
);
|
||||
global.fetch = fetchMock;
|
||||
render(<ComputeDevicePanel />);
|
||||
await waitFor(() => expect(screen.getByTestId('compute-device-select').options.length).toBe(3));
|
||||
|
||||
fireEvent.change(screen.getByTestId('compute-device-select'), { target: { value: 'cpu' } });
|
||||
|
||||
await waitFor(() => {
|
||||
const put = fetchMock.mock.calls.find(([_u, opts]) => opts && opts.method === 'PUT');
|
||||
expect(put).toBeTruthy();
|
||||
expect(put[0]).toMatch(/\/api\/settings\/compute-device$/);
|
||||
expect(JSON.parse(put[1].body)).toEqual({ value: 'cpu' });
|
||||
});
|
||||
expect(screen.getByText(/after the app restarts/i)).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it('an OMNIVOICE_DEVICE pin disables the control and says so', async () => {
|
||||
global.fetch = mockFetchSequence({
|
||||
status: 200,
|
||||
body: { ...CUDA_HOST, value: 'cpu', applied: 'cpu', env_pinned: true },
|
||||
});
|
||||
render(<ComputeDevicePanel />);
|
||||
await waitFor(() => {
|
||||
expect(screen.getByTestId('compute-device-select')).toBeDisabled();
|
||||
});
|
||||
expect(screen.getByText(/OMNIVOICE_DEVICE/)).toBeInTheDocument();
|
||||
});
|
||||
|
||||
it('re-syncs from the server when the PUT fails, keeping the error visible', async () => {
|
||||
const fetchMock = mockFetchSequence(
|
||||
{ status: 200, body: CUDA_HOST }, // initial GET
|
||||
{ status: 500, body: { detail: 'nope' } }, // PUT fails
|
||||
{ status: 200, body: CUDA_HOST }, // re-sync GET
|
||||
);
|
||||
global.fetch = fetchMock;
|
||||
render(<ComputeDevicePanel />);
|
||||
await waitFor(() => expect(screen.getByTestId('compute-device-select').options.length).toBe(3));
|
||||
|
||||
fireEvent.change(screen.getByTestId('compute-device-select'), { target: { value: 'cpu' } });
|
||||
|
||||
await waitFor(() => {
|
||||
// Three calls: GET, failed PUT, re-sync GET — the select ends on the
|
||||
// server's truth (auto), never a pick that didn't persist.
|
||||
expect(fetchMock.mock.calls.length).toBe(3);
|
||||
});
|
||||
expect(screen.getByTestId('compute-device-select')).toHaveValue('auto');
|
||||
// The save error must survive the re-sync — a silent snap-back reads
|
||||
// as "the app ignored me".
|
||||
expect(screen.getByRole('alert')).toBeInTheDocument();
|
||||
});
|
||||
});
|
||||
@@ -18,6 +18,7 @@ import { Badge } from '../../ui';
|
||||
import { SettingsSection } from './primitives';
|
||||
import Row from './Row';
|
||||
import PerformancePanel from './PerformancePanel';
|
||||
import ComputeDevicePanel from './ComputeDevicePanel';
|
||||
|
||||
export default function PerformanceDeviceTab() {
|
||||
const { t } = useTranslation();
|
||||
@@ -29,6 +30,8 @@ export default function PerformanceDeviceTab() {
|
||||
<>
|
||||
<PerformancePanel />
|
||||
|
||||
<ComputeDevicePanel />
|
||||
|
||||
<SettingsSection
|
||||
icon={Gauge}
|
||||
title={t('settings.device', { defaultValue: 'Device & compute' })}
|
||||
|
||||
@@ -196,6 +196,12 @@ export const GROUPS = [
|
||||
'vram',
|
||||
'compute',
|
||||
'platform',
|
||||
'cuda',
|
||||
'rocm',
|
||||
'mps',
|
||||
'cpu',
|
||||
'xpu',
|
||||
'intel',
|
||||
],
|
||||
},
|
||||
{
|
||||
|
||||
@@ -67,6 +67,7 @@ describe('restart flag ↔ RestartBadge lockstep', () => {
|
||||
'RemoteBackendPanel.jsx': 'sharing',
|
||||
'AudioToolsPanel.jsx': 'audio-tools',
|
||||
'PerformancePanel.jsx': 'performance',
|
||||
'ComputeDevicePanel.jsx': 'performance',
|
||||
};
|
||||
|
||||
const panelsUsingRestartBadge = fs
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} متصل",
|
||||
"workers_token_expired": "انتهت الصلاحية — أنشئ رمزًا جديدًا",
|
||||
"workers_token_expires_in": "تنتهي الصلاحية خلال {{time}}",
|
||||
"workers_token_qr_hint": "على الجهاز الآخر: الإعدادات ← النظام ← العاملون البعيدون ← انضمام، ثم امسح أو الصق."
|
||||
"workers_token_qr_hint": "على الجهاز الآخر: الإعدادات ← النظام ← العاملون البعيدون ← انضمام، ثم امسح أو الصق.",
|
||||
"compute_device": "جهاز الحوسبة",
|
||||
"compute_device_title": "جهاز الحوسبة",
|
||||
"compute_device_desc": "الجهاز الذي يشغّل عليه الخادم النماذج. الوضع التلقائي مناسب للجميع تقريبًا.",
|
||||
"compute_device_env_pinned": "مثبّت بواسطة متغيّر البيئة OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "لم يُكتشف هذا الجهاز على هذا الحاسوب — الوضع التلقائي هو المعمول به",
|
||||
"compute_device_restart": "يسري بعد إعادة تشغيل التطبيق",
|
||||
"compute_device_note": "تُعرض فقط الأجهزة المكتشفة على هذا الحاسوب. تعمل CPU دائمًا؛ تثبيت جهاز لا يخترع عتادًا أبدًا.",
|
||||
"compute_device_auto": "تلقائي (مستحسن)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "تعذّر تحميل إعداد الجهاز",
|
||||
"perf_save_failed": "تعذّر حفظ الإعداد"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} online",
|
||||
"workers_token_expired": "Abgelaufen — erzeugen Sie ein neues",
|
||||
"workers_token_expires_in": "Läuft ab in {{time}}",
|
||||
"workers_token_qr_hint": "Auf dem anderen Rechner: Einstellungen → System → Remote-Worker → Beitreten, dann scannen oder einfügen."
|
||||
"workers_token_qr_hint": "Auf dem anderen Rechner: Einstellungen → System → Remote-Worker → Beitreten, dann scannen oder einfügen.",
|
||||
"compute_device": "Rechengerät",
|
||||
"compute_device_title": "Rechengerät",
|
||||
"compute_device_desc": "Auf welchem Gerät das Backend Modelle ausführt. Auto ist für fast alle richtig.",
|
||||
"compute_device_env_pinned": "Durch die Umgebungsvariable OMNIVOICE_DEVICE festgelegt",
|
||||
"compute_device_ignored": "Dieses Gerät wurde auf diesem Rechner nicht erkannt — Auto ist aktiv",
|
||||
"compute_device_restart": "Wird nach dem Neustart der App wirksam",
|
||||
"compute_device_note": "Es werden nur auf diesem Rechner erkannte Geräte angezeigt. CPU funktioniert immer; ein festgelegtes Gerät erfindet keine Hardware.",
|
||||
"compute_device_auto": "Auto (empfohlen)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Geräteeinstellung konnte nicht geladen werden",
|
||||
"perf_save_failed": "Einstellung konnte nicht gespeichert werden"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -890,7 +890,21 @@
|
||||
"workers_summary_online": "{{count}} online",
|
||||
"workers_token_expired": "Expired — generate a new one",
|
||||
"workers_token_expires_in": "Expires in {{time}}",
|
||||
"workers_token_qr_hint": "On the other machine: Settings → System → Remote workers → Join, then scan or paste."
|
||||
"workers_token_qr_hint": "On the other machine: Settings → System → Remote workers → Join, then scan or paste.",
|
||||
"compute_device": "Compute device",
|
||||
"compute_device_title": "Compute device",
|
||||
"compute_device_desc": "Which device the backend runs models on. Auto is right for almost everyone.",
|
||||
"compute_device_env_pinned": "Pinned by the OMNIVOICE_DEVICE environment variable",
|
||||
"compute_device_ignored": "That device was not detected on this machine — Auto is in effect",
|
||||
"compute_device_restart": "Takes effect after the app restarts",
|
||||
"compute_device_note": "Only devices detected on this machine are listed. CPU always works; pinning a device never invents hardware.",
|
||||
"compute_device_auto": "Auto (recommended)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Failed to load device setting"
|
||||
},
|
||||
"about": {
|
||||
"app": "App",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} en línea",
|
||||
"workers_token_expired": "Caducado — genera uno nuevo",
|
||||
"workers_token_expires_in": "Caduca en {{time}}",
|
||||
"workers_token_qr_hint": "En el otro equipo: Ajustes → Sistema → Trabajadores remotos → Unirse, y luego escanea o pega."
|
||||
"workers_token_qr_hint": "En el otro equipo: Ajustes → Sistema → Trabajadores remotos → Unirse, y luego escanea o pega.",
|
||||
"compute_device": "Dispositivo de cómputo",
|
||||
"compute_device_title": "Dispositivo de cómputo",
|
||||
"compute_device_desc": "En qué dispositivo ejecuta los modelos el backend. Auto es lo correcto para casi todos.",
|
||||
"compute_device_env_pinned": "Fijado por la variable de entorno OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Ese dispositivo no se detectó en esta máquina — Auto está en efecto",
|
||||
"compute_device_restart": "Surte efecto tras reiniciar la aplicación",
|
||||
"compute_device_note": "Solo se listan los dispositivos detectados en esta máquina. La CPU siempre funciona; fijar un dispositivo nunca inventa hardware.",
|
||||
"compute_device_auto": "Auto (recomendado)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "No se pudo cargar el ajuste del dispositivo",
|
||||
"perf_save_failed": "No se pudo guardar el ajuste"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} en ligne",
|
||||
"workers_token_expired": "Expiré — générez-en un nouveau",
|
||||
"workers_token_expires_in": "Expire dans {{time}}",
|
||||
"workers_token_qr_hint": "Sur l'autre machine : Paramètres → Système → Workers distants → Rejoindre, puis scannez ou collez."
|
||||
"workers_token_qr_hint": "Sur l'autre machine : Paramètres → Système → Workers distants → Rejoindre, puis scannez ou collez.",
|
||||
"compute_device": "Périphérique de calcul",
|
||||
"compute_device_title": "Périphérique de calcul",
|
||||
"compute_device_desc": "Sur quel périphérique le backend exécute les modèles. Auto convient à presque tout le monde.",
|
||||
"compute_device_env_pinned": "Épinglé par la variable d'environnement OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Ce périphérique n'a pas été détecté sur cette machine — Auto est en vigueur",
|
||||
"compute_device_restart": "Prend effet après le redémarrage de l'application",
|
||||
"compute_device_note": "Seuls les périphériques détectés sur cette machine sont listés. Le CPU fonctionne toujours ; épingler un périphérique n'invente jamais de matériel.",
|
||||
"compute_device_auto": "Auto (recommandé)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Impossible de charger le réglage du périphérique",
|
||||
"perf_save_failed": "Impossible d'enregistrer le réglage"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} ऑनलाइन",
|
||||
"workers_token_expired": "समाप्त हो गया — नया बनाएँ",
|
||||
"workers_token_expires_in": "{{time}} में समाप्त होगा",
|
||||
"workers_token_qr_hint": "दूसरी मशीन पर: सेटिंग्स → सिस्टम → रिमोट वर्कर → जुड़ें, फिर स्कैन या पेस्ट करें।"
|
||||
"workers_token_qr_hint": "दूसरी मशीन पर: सेटिंग्स → सिस्टम → रिमोट वर्कर → जुड़ें, फिर स्कैन या पेस्ट करें।",
|
||||
"compute_device": "कंप्यूट डिवाइस",
|
||||
"compute_device_title": "कंप्यूट डिवाइस",
|
||||
"compute_device_desc": "बैकएंड मॉडल किस डिवाइस पर चलाता है। लगभग सभी के लिए Auto सही है।",
|
||||
"compute_device_env_pinned": "OMNIVOICE_DEVICE पर्यावरण चर द्वारा पिन किया गया",
|
||||
"compute_device_ignored": "वह डिवाइस इस मशीन पर नहीं मिला — Auto प्रभावी है",
|
||||
"compute_device_restart": "ऐप के पुनरारंभ के बाद प्रभावी होगा",
|
||||
"compute_device_note": "केवल इस मशीन पर पाए गए डिवाइस सूचीबद्ध हैं। CPU हमेशा काम करता है; डिवाइस पिन करने से हार्डवेयर कभी नहीं बनता।",
|
||||
"compute_device_auto": "Auto (अनुशंसित)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "डिवाइस सेटिंग लोड नहीं हो सकी",
|
||||
"perf_save_failed": "सेटिंग सहेजी नहीं जा सकी"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} online",
|
||||
"workers_token_expired": "Kedaluwarsa — buat yang baru",
|
||||
"workers_token_expires_in": "Kedaluwarsa dalam {{time}}",
|
||||
"workers_token_qr_hint": "Di mesin yang lain: Pengaturan → Sistem → Pekerja jarak jauh → Gabung, lalu pindai atau tempelkan."
|
||||
"workers_token_qr_hint": "Di mesin yang lain: Pengaturan → Sistem → Pekerja jarak jauh → Gabung, lalu pindai atau tempelkan.",
|
||||
"compute_device": "Perangkat komputasi",
|
||||
"compute_device_title": "Perangkat komputasi",
|
||||
"compute_device_desc": "Di perangkat mana backend menjalankan model. Auto tepat untuk hampir semua orang.",
|
||||
"compute_device_env_pinned": "Disematkan oleh variabel lingkungan OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Perangkat itu tidak terdeteksi di mesin ini — Auto yang berlaku",
|
||||
"compute_device_restart": "Berlaku setelah aplikasi dimulai ulang",
|
||||
"compute_device_note": "Hanya perangkat yang terdeteksi di mesin ini yang ditampilkan. CPU selalu berfungsi; menyematkan perangkat tidak pernah mengarang perangkat keras.",
|
||||
"compute_device_auto": "Auto (disarankan)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Gagal memuat pengaturan perangkat",
|
||||
"perf_save_failed": "Gagal menyimpan pengaturan"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} online",
|
||||
"workers_token_expired": "Scaduto — generane uno nuovo",
|
||||
"workers_token_expires_in": "Scade tra {{time}}",
|
||||
"workers_token_qr_hint": "Sull'altro computer: Impostazioni → Sistema → Worker remoti → Collegati, poi scansiona o incolla."
|
||||
"workers_token_qr_hint": "Sull'altro computer: Impostazioni → Sistema → Worker remoti → Collegati, poi scansiona o incolla.",
|
||||
"compute_device": "Dispositivo di calcolo",
|
||||
"compute_device_title": "Dispositivo di calcolo",
|
||||
"compute_device_desc": "Su quale dispositivo il backend esegue i modelli. Auto va bene per quasi tutti.",
|
||||
"compute_device_env_pinned": "Bloccato dalla variabile d'ambiente OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Quel dispositivo non è stato rilevato su questa macchina — è attivo Auto",
|
||||
"compute_device_restart": "Ha effetto dopo il riavvio dell'app",
|
||||
"compute_device_note": "Sono elencati solo i dispositivi rilevati su questa macchina. La CPU funziona sempre; fissare un dispositivo non inventa mai hardware.",
|
||||
"compute_device_auto": "Auto (consigliato)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Impossibile caricare l'impostazione del dispositivo",
|
||||
"perf_save_failed": "Impossibile salvare l'impostazione"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} 台オンライン",
|
||||
"workers_token_expired": "期限切れ — 新しく生成してください",
|
||||
"workers_token_expires_in": "あと {{time}} で期限切れ",
|
||||
"workers_token_qr_hint": "もう一方のマシンで: 設定 → システム → リモートワーカー → 参加 を開き、スキャンするか貼り付けてください。"
|
||||
"workers_token_qr_hint": "もう一方のマシンで: 設定 → システム → リモートワーカー → 参加 を開き、スキャンするか貼り付けてください。",
|
||||
"compute_device": "計算デバイス",
|
||||
"compute_device_title": "計算デバイス",
|
||||
"compute_device_desc": "バックエンドがモデルを実行するデバイス。ほとんどの場合は「自動」が最適です。",
|
||||
"compute_device_env_pinned": "環境変数 OMNIVOICE_DEVICE により固定されています",
|
||||
"compute_device_ignored": "そのデバイスはこのマシンで検出されませんでした — 「自動」が適用されています",
|
||||
"compute_device_restart": "アプリの再起動後に有効になります",
|
||||
"compute_device_note": "このマシンで検出されたデバイスのみ表示されます。CPU は常に動作します。デバイスを固定してもハードウェアが増えることはありません。",
|
||||
"compute_device_auto": "自動(推奨)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "デバイス設定を読み込めませんでした",
|
||||
"perf_save_failed": "設定を保存できませんでした"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}}대 온라인",
|
||||
"workers_token_expired": "만료됨 — 새로 생성하세요",
|
||||
"workers_token_expires_in": "{{time}} 후 만료",
|
||||
"workers_token_qr_hint": "다른 컴퓨터에서: 설정 → 시스템 → 원격 워커 → 참여로 이동한 뒤 스캔하거나 붙여 넣으세요."
|
||||
"workers_token_qr_hint": "다른 컴퓨터에서: 설정 → 시스템 → 원격 워커 → 참여로 이동한 뒤 스캔하거나 붙여 넣으세요.",
|
||||
"compute_device": "연산 장치",
|
||||
"compute_device_title": "연산 장치",
|
||||
"compute_device_desc": "백엔드가 모델을 실행할 장치입니다. 거의 모든 경우 '자동'이 적합합니다.",
|
||||
"compute_device_env_pinned": "OMNIVOICE_DEVICE 환경 변수로 고정됨",
|
||||
"compute_device_ignored": "이 컴퓨터에서 해당 장치를 찾지 못했습니다 — '자동'이 적용 중입니다",
|
||||
"compute_device_restart": "앱을 다시 시작한 후 적용됩니다",
|
||||
"compute_device_note": "이 컴퓨터에서 감지된 장치만 표시됩니다. CPU는 항상 작동하며, 장치를 고정해도 없는 하드웨어가 생기지는 않습니다.",
|
||||
"compute_device_auto": "자동 (권장)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "장치 설정을 불러오지 못했습니다",
|
||||
"perf_save_failed": "설정을 저장하지 못했습니다"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} online",
|
||||
"workers_token_expired": "Verlopen — genereer een nieuwe",
|
||||
"workers_token_expires_in": "Verloopt over {{time}}",
|
||||
"workers_token_qr_hint": "Op de andere machine: Instellingen → Systeem → Externe workers → Koppelen, en scan of plak daar."
|
||||
"workers_token_qr_hint": "Op de andere machine: Instellingen → Systeem → Externe workers → Koppelen, en scan of plak daar.",
|
||||
"compute_device": "Rekenapparaat",
|
||||
"compute_device_title": "Rekenapparaat",
|
||||
"compute_device_desc": "Op welk apparaat de backend modellen draait. Auto is voor bijna iedereen juist.",
|
||||
"compute_device_env_pinned": "Vastgezet door de omgevingsvariabele OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Dat apparaat is op deze machine niet gedetecteerd — Auto is van kracht",
|
||||
"compute_device_restart": "Wordt van kracht na het herstarten van de app",
|
||||
"compute_device_note": "Alleen op deze machine gedetecteerde apparaten worden getoond. CPU werkt altijd; een vastgezet apparaat verzint nooit hardware.",
|
||||
"compute_device_auto": "Auto (aanbevolen)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Apparaatinstelling kon niet worden geladen",
|
||||
"perf_save_failed": "Instelling kon niet worden opgeslagen"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} online",
|
||||
"workers_token_expired": "Wygasł — wygeneruj nowy",
|
||||
"workers_token_expires_in": "Wygasa za {{time}}",
|
||||
"workers_token_qr_hint": "Na drugim komputerze: Ustawienia → Systemu → Zdalne workery → Dołącz, potem zeskanuj albo wklej."
|
||||
"workers_token_qr_hint": "Na drugim komputerze: Ustawienia → Systemu → Zdalne workery → Dołącz, potem zeskanuj albo wklej.",
|
||||
"compute_device": "Urządzenie obliczeniowe",
|
||||
"compute_device_title": "Urządzenie obliczeniowe",
|
||||
"compute_device_desc": "Na którym urządzeniu backend uruchamia modele. Auto jest właściwe dla niemal wszystkich.",
|
||||
"compute_device_env_pinned": "Przypięte przez zmienną środowiskową OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Tego urządzenia nie wykryto na tej maszynie — obowiązuje Auto",
|
||||
"compute_device_restart": "Zacznie obowiązywać po ponownym uruchomieniu aplikacji",
|
||||
"compute_device_note": "Wyświetlane są tylko urządzenia wykryte na tej maszynie. CPU zawsze działa; przypięcie urządzenia nigdy nie wymyśla sprzętu.",
|
||||
"compute_device_auto": "Auto (zalecane)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Nie udało się wczytać ustawienia urządzenia",
|
||||
"perf_save_failed": "Nie udało się zapisać ustawienia"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} online",
|
||||
"workers_token_expired": "Expirado — gere um novo",
|
||||
"workers_token_expires_in": "Expira em {{time}}",
|
||||
"workers_token_qr_hint": "Na outra máquina: Configurações → Sistema → Workers remotos → Associar, depois escaneie ou cole."
|
||||
"workers_token_qr_hint": "Na outra máquina: Configurações → Sistema → Workers remotos → Associar, depois escaneie ou cole.",
|
||||
"compute_device": "Dispositivo de computação",
|
||||
"compute_device_title": "Dispositivo de computação",
|
||||
"compute_device_desc": "Em qual dispositivo o backend executa os modelos. Auto é o certo para quase todos.",
|
||||
"compute_device_env_pinned": "Fixado pela variável de ambiente OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Esse dispositivo não foi detectado nesta máquina — Auto está em vigor",
|
||||
"compute_device_restart": "Entra em vigor após reiniciar o aplicativo",
|
||||
"compute_device_note": "Apenas dispositivos detectados nesta máquina são listados. A CPU sempre funciona; fixar um dispositivo nunca inventa hardware.",
|
||||
"compute_device_auto": "Auto (recomendado)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Falha ao carregar a configuração do dispositivo",
|
||||
"perf_save_failed": "Falha ao salvar a configuração"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} в сети",
|
||||
"workers_token_expired": "Истёк — создайте новый",
|
||||
"workers_token_expires_in": "Истекает через {{time}}",
|
||||
"workers_token_qr_hint": "На другой машине: Настройки → Система → Удалённые воркеры → Подключиться, затем отсканируйте или вставьте."
|
||||
"workers_token_qr_hint": "На другой машине: Настройки → Система → Удалённые воркеры → Подключиться, затем отсканируйте или вставьте.",
|
||||
"compute_device": "Устройство вычислений",
|
||||
"compute_device_title": "Устройство вычислений",
|
||||
"compute_device_desc": "На каком устройстве backend выполняет модели. Auto подходит почти всем.",
|
||||
"compute_device_env_pinned": "Закреплено переменной окружения OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Это устройство не обнаружено на этой машине — действует Auto",
|
||||
"compute_device_restart": "Вступит в силу после перезапуска приложения",
|
||||
"compute_device_note": "Показаны только устройства, обнаруженные на этой машине. CPU работает всегда; закрепление устройства не создаёт несуществующее оборудование.",
|
||||
"compute_device_auto": "Auto (рекомендуется)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Не удалось загрузить настройку устройства",
|
||||
"perf_save_failed": "Не удалось сохранить настройку"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} online",
|
||||
"workers_token_expired": "Har gått ut — skapa en ny",
|
||||
"workers_token_expires_in": "Går ut om {{time}}",
|
||||
"workers_token_qr_hint": "På den andra maskinen: Inställningar → System → Fjärrarbetare → Anslut, skanna eller klistra sedan in."
|
||||
"workers_token_qr_hint": "På den andra maskinen: Inställningar → System → Fjärrarbetare → Anslut, skanna eller klistra sedan in.",
|
||||
"compute_device": "Beräkningsenhet",
|
||||
"compute_device_title": "Beräkningsenhet",
|
||||
"compute_device_desc": "Vilken enhet backend kör modeller på. Auto är rätt för nästan alla.",
|
||||
"compute_device_env_pinned": "Låst av miljövariabeln OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Den enheten hittades inte på den här datorn — Auto gäller",
|
||||
"compute_device_restart": "Träder i kraft efter omstart av appen",
|
||||
"compute_device_note": "Endast enheter som hittats på den här datorn visas. CPU fungerar alltid; att låsa en enhet hittar aldrig på hårdvara.",
|
||||
"compute_device_auto": "Auto (rekommenderas)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Kunde inte läsa in enhetsinställningen",
|
||||
"perf_save_failed": "Kunde inte spara inställningen"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "ออนไลน์ {{count}} เครื่อง",
|
||||
"workers_token_expired": "หมดอายุแล้ว — สร้างใหม่",
|
||||
"workers_token_expires_in": "หมดอายุใน {{time}}",
|
||||
"workers_token_qr_hint": "บนเครื่องอีกเครื่อง: การตั้งค่า → ระบบ → ผู้ปฏิบัติงานระยะไกล → เข้าร่วม แล้วสแกนหรือวาง"
|
||||
"workers_token_qr_hint": "บนเครื่องอีกเครื่อง: การตั้งค่า → ระบบ → ผู้ปฏิบัติงานระยะไกล → เข้าร่วม แล้วสแกนหรือวาง",
|
||||
"compute_device": "อุปกรณ์ประมวลผล",
|
||||
"compute_device_title": "อุปกรณ์ประมวลผล",
|
||||
"compute_device_desc": "แบ็กเอนด์รันโมเดลบนอุปกรณ์ใด อัตโนมัติ เหมาะสำหรับเกือบทุกคน",
|
||||
"compute_device_env_pinned": "ถูกกำหนดโดยตัวแปรสภาพแวดล้อม OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "ไม่พบอุปกรณ์นั้นบนเครื่องนี้ — ใช้ อัตโนมัติ แทน",
|
||||
"compute_device_restart": "มีผลหลังจากรีสตาร์ตแอป",
|
||||
"compute_device_note": "แสดงเฉพาะอุปกรณ์ที่ตรวจพบบนเครื่องนี้ CPU ใช้ได้เสมอ การกำหนดอุปกรณ์ไม่เคยสร้างฮาร์ดแวร์ที่ไม่มีอยู่",
|
||||
"compute_device_auto": "อัตโนมัติ (แนะนำ)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "โหลดการตั้งค่าอุปกรณ์ไม่สำเร็จ",
|
||||
"perf_save_failed": "บันทึกการตั้งค่าไม่สำเร็จ"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} çevrimiçi",
|
||||
"workers_token_expired": "Süresi doldu — yenisini oluşturun",
|
||||
"workers_token_expires_in": "{{time}} içinde süresi dolacak",
|
||||
"workers_token_qr_hint": "Diğer makinede: Ayarlar → Sistem → Uzak işçiler → Katıl, sonra tarayın veya yapıştırın."
|
||||
"workers_token_qr_hint": "Diğer makinede: Ayarlar → Sistem → Uzak işçiler → Katıl, sonra tarayın veya yapıştırın.",
|
||||
"compute_device": "Hesaplama aygıtı",
|
||||
"compute_device_title": "Hesaplama aygıtı",
|
||||
"compute_device_desc": "Backend'in modelleri hangi aygıtta çalıştıracağı. Auto neredeyse herkes için doğrudur.",
|
||||
"compute_device_env_pinned": "OMNIVOICE_DEVICE ortam değişkeniyle sabitlendi",
|
||||
"compute_device_ignored": "Bu aygıt bu makinede algılanmadı — Auto geçerli",
|
||||
"compute_device_restart": "Uygulama yeniden başlatıldıktan sonra geçerli olur",
|
||||
"compute_device_note": "Yalnızca bu makinede algılanan aygıtlar listelenir. CPU her zaman çalışır; bir aygıtı sabitlemek asla donanım uydurmaz.",
|
||||
"compute_device_auto": "Auto (önerilen)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Aygıt ayarı yüklenemedi",
|
||||
"perf_save_failed": "Ayar kaydedilemedi"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} у мережі",
|
||||
"workers_token_expired": "Сплив — створіть новий",
|
||||
"workers_token_expires_in": "Спливає через {{time}}",
|
||||
"workers_token_qr_hint": "На іншій машині: Налаштування → система → Віддалені воркери → Підключитися, потім відскануйте або вставте."
|
||||
"workers_token_qr_hint": "На іншій машині: Налаштування → система → Віддалені воркери → Підключитися, потім відскануйте або вставте.",
|
||||
"compute_device": "Пристрій обчислень",
|
||||
"compute_device_title": "Пристрій обчислень",
|
||||
"compute_device_desc": "На якому пристрої backend виконує моделі. Auto підходить майже всім.",
|
||||
"compute_device_env_pinned": "Закріплено змінною середовища OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Цей пристрій не виявлено на цій машині — діє Auto",
|
||||
"compute_device_restart": "Набуде чинності після перезапуску застосунку",
|
||||
"compute_device_note": "Показано лише пристрої, виявлені на цій машині. CPU працює завжди; закріплення пристрою ніколи не вигадує обладнання.",
|
||||
"compute_device_auto": "Auto (рекомендовано)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Не вдалося завантажити налаштування пристрою",
|
||||
"perf_save_failed": "Не вдалося зберегти налаштування"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} trực tuyến",
|
||||
"workers_token_expired": "Đã hết hạn — hãy tạo mã mới",
|
||||
"workers_token_expires_in": "Hết hạn sau {{time}}",
|
||||
"workers_token_qr_hint": "Trên máy kia: Cài đặt → Hệ thống → Máy phụ từ xa → Tham gia, rồi quét hoặc dán."
|
||||
"workers_token_qr_hint": "Trên máy kia: Cài đặt → Hệ thống → Máy phụ từ xa → Tham gia, rồi quét hoặc dán.",
|
||||
"compute_device": "Thiết bị tính toán",
|
||||
"compute_device_title": "Thiết bị tính toán",
|
||||
"compute_device_desc": "Backend chạy mô hình trên thiết bị nào. Tự động phù hợp với hầu hết mọi người.",
|
||||
"compute_device_env_pinned": "Được ghim bởi biến môi trường OMNIVOICE_DEVICE",
|
||||
"compute_device_ignored": "Không phát hiện thiết bị đó trên máy này — Tự động đang có hiệu lực",
|
||||
"compute_device_restart": "Có hiệu lực sau khi khởi động lại ứng dụng",
|
||||
"compute_device_note": "Chỉ liệt kê các thiết bị được phát hiện trên máy này. CPU luôn hoạt động; ghim một thiết bị không bao giờ bịa ra phần cứng.",
|
||||
"compute_device_auto": "Tự động (khuyên dùng)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "Không tải được cài đặt thiết bị",
|
||||
"perf_save_failed": "Không lưu được cài đặt"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -551,7 +551,22 @@
|
||||
"workers_summary_online": "{{count}} 台在线",
|
||||
"workers_token_expired": "已过期——请重新生成",
|
||||
"workers_token_expires_in": "{{time}} 后过期",
|
||||
"workers_token_qr_hint": "在另一台机器上:设置 → 系统 → 远程工作机 → 加入,然后扫描或粘贴。"
|
||||
"workers_token_qr_hint": "在另一台机器上:设置 → 系统 → 远程工作机 → 加入,然后扫描或粘贴。",
|
||||
"compute_device": "计算设备",
|
||||
"compute_device_title": "计算设备",
|
||||
"compute_device_desc": "后端在哪个设备上运行模型。绝大多数情况下选「自动」即可。",
|
||||
"compute_device_env_pinned": "已被环境变量 OMNIVOICE_DEVICE 固定",
|
||||
"compute_device_ignored": "本机未检测到该设备——当前实际使用「自动」",
|
||||
"compute_device_restart": "重启应用后生效",
|
||||
"compute_device_note": "仅列出本机检测到的设备。CPU 始终可用;固定设备不会凭空造出硬件。",
|
||||
"compute_device_auto": "自动(推荐)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "无法加载设备设置",
|
||||
"perf_save_failed": "无法保存设置"
|
||||
},
|
||||
"about": {
|
||||
"app": "应用",
|
||||
|
||||
@@ -315,7 +315,22 @@
|
||||
"workers_summary_online": "{{count}} 台上線",
|
||||
"workers_token_expired": "已過期——請重新產生",
|
||||
"workers_token_expires_in": "{{time}} 後過期",
|
||||
"workers_token_qr_hint": "在另一台機器上:設定 → 系統 → 遠端工作機 → 加入,然後掃描或貼上。"
|
||||
"workers_token_qr_hint": "在另一台機器上:設定 → 系統 → 遠端工作機 → 加入,然後掃描或貼上。",
|
||||
"compute_device": "運算裝置",
|
||||
"compute_device_title": "運算裝置",
|
||||
"compute_device_desc": "後端在哪個裝置上執行模型。絕大多數情況下選「自動」即可。",
|
||||
"compute_device_env_pinned": "已由環境變數 OMNIVOICE_DEVICE 固定",
|
||||
"compute_device_ignored": "本機未偵測到該裝置——目前實際使用「自動」",
|
||||
"compute_device_restart": "重新啟動應用程式後生效",
|
||||
"compute_device_note": "僅列出本機偵測到的裝置。CPU 永遠可用;固定裝置不會憑空生出硬體。",
|
||||
"compute_device_auto": "自動(建議)",
|
||||
"device_family_cuda": "NVIDIA GPU (CUDA)",
|
||||
"device_family_rocm": "AMD GPU (ROCm)",
|
||||
"device_family_xpu": "Intel GPU (XPU)",
|
||||
"device_family_mps": "Apple GPU (MPS)",
|
||||
"device_family_cpu": "CPU",
|
||||
"device_load_failed": "無法載入裝置設定",
|
||||
"perf_save_failed": "無法儲存設定"
|
||||
},
|
||||
"bootstrap": {
|
||||
"title": "VoiceStudio",
|
||||
|
||||
@@ -91,12 +91,60 @@ class OmniVoiceModelAssetError(RuntimeError):
|
||||
# ---------------------------------------------------------------------------
|
||||
|
||||
|
||||
_VOICE_CLONE_PROMPT_FORMAT_VERSION = 1
|
||||
|
||||
|
||||
@dataclass
|
||||
class VoiceClonePrompt:
|
||||
ref_audio_tokens: torch.Tensor # (C, T)
|
||||
ref_text: str
|
||||
ref_rms: float
|
||||
|
||||
def save(self, path: str) -> None:
|
||||
"""Save this prompt to ``path`` for reuse in a later session.
|
||||
|
||||
The file stores a plain dict with the audio tokens moved to CPU, so
|
||||
it can be loaded with ``torch.load(weights_only=True)`` (the default
|
||||
since torch 2.6) and is portable across devices.
|
||||
|
||||
Args:
|
||||
path: Destination file path (e.g. ``"my_voice.pt"``).
|
||||
"""
|
||||
torch.save(
|
||||
{
|
||||
"format_version": _VOICE_CLONE_PROMPT_FORMAT_VERSION,
|
||||
"ref_audio_tokens": self.ref_audio_tokens.detach().cpu(),
|
||||
"ref_text": self.ref_text,
|
||||
"ref_rms": float(self.ref_rms),
|
||||
},
|
||||
path,
|
||||
)
|
||||
|
||||
@classmethod
|
||||
def load(cls, path: str, map_location: str = "cpu") -> "VoiceClonePrompt":
|
||||
"""Load a prompt saved with :meth:`save`.
|
||||
|
||||
The returned prompt can be passed directly to
|
||||
:meth:`OmniVoice.generate`; the audio tokens are moved to the model
|
||||
device automatically during generation, so no manual ``.to(device)``
|
||||
is needed.
|
||||
|
||||
Args:
|
||||
path: File path previously written by :meth:`save`.
|
||||
map_location: Device to load the audio tokens onto.
|
||||
Returns:
|
||||
The restored :class:`VoiceClonePrompt`.
|
||||
"""
|
||||
data = torch.load(path, map_location=map_location, weights_only=True)
|
||||
version = data.get("format_version")
|
||||
if version != _VOICE_CLONE_PROMPT_FORMAT_VERSION:
|
||||
raise ValueError(f"Unsupported VoiceClonePrompt format version: {version}")
|
||||
return cls(
|
||||
ref_audio_tokens=data["ref_audio_tokens"],
|
||||
ref_text=data["ref_text"],
|
||||
ref_rms=data["ref_rms"],
|
||||
)
|
||||
|
||||
|
||||
@dataclass
|
||||
class OmniVoiceGenerationConfig:
|
||||
|
||||
@@ -0,0 +1,667 @@
|
||||
# SPDX-FileCopyrightText: Copyright (c) 2026, NVIDIA CORPORATION. All rights reserved.
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
"""FlashInfer-accelerated iterative decoding for OmniVoice.
|
||||
|
||||
Approach (mirrors CosyVoice/runtime/triton_trtllm/token2wav_dit_flashinfer.py):
|
||||
|
||||
- Sequence packing: the baseline pads the uncond (CFG) sequence to the cond
|
||||
length and runs batch=2 with a (2,1,S,S) bool mask. Here cond+uncond are
|
||||
packed into ONE row of length c_len+u_len with per-document positions and
|
||||
flashinfer ragged attention (qo_indptr = document boundaries) — no pad
|
||||
compute, no S^2 mask materialization.
|
||||
- Attention: registered as a custom HF attention implementation
|
||||
("omnivoice_fi") via AttentionInterface; reads the wrapper planned
|
||||
once per generation from a module-level context. HF mask construction is
|
||||
bypassed by passing attention_mask={"full_attention": None}.
|
||||
- KV cache: disabled (llm.config.use_cache=False). Iterative bidirectional
|
||||
decoding recomputes the full sequence every step, so the DynamicCache the
|
||||
baseline builds each forward is pure overhead.
|
||||
- Optional CUDA graphs: one graph per packed shape; all 32 denoising steps
|
||||
replay the same graph (input_ids/audio_mask/position_ids are copied into
|
||||
static buffers). Each shape owns a private flashinfer wrapper, since a
|
||||
plan bakes its launch metadata into the captured graph.
|
||||
|
||||
Usage:
|
||||
from omnivoice_flashinfer import apply_flashinfer
|
||||
apply_flashinfer(model, enable_cuda_graph=True)
|
||||
|
||||
Ported from upstream k2-fsa/OmniVoice master with one behavioural change:
|
||||
the unmasking schedule uses ``num_step + 1`` timesteps to match this repo's
|
||||
``_generate_iterative``. VoiceStudio enables it via ``OMNIVOICE_FLASHINFER``
|
||||
(see services/model_manager.py); ``flashinfer`` is an optional dependency and
|
||||
this module must only be imported after that opt-in.
|
||||
"""
|
||||
|
||||
import math
|
||||
import time
|
||||
from types import MethodType
|
||||
from typing import List
|
||||
|
||||
import flashinfer
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
from transformers.modeling_utils import AttentionInterface
|
||||
|
||||
from omnivoice.models.omnivoice import (
|
||||
GenerationTask,
|
||||
OmniVoiceGenerationConfig,
|
||||
_get_time_steps,
|
||||
_gumbel_sample,
|
||||
)
|
||||
|
||||
_WORKSPACE_SIZE = 128 * 1024 * 1024
|
||||
# Context read by the registered attention function. "wrapper" must be planned
|
||||
# for the current packed layout before any llm forward.
|
||||
_CTX = {"wrapper": None}
|
||||
|
||||
|
||||
def _flashinfer_attention(
|
||||
module, query, key, value, attention_mask, scaling=None, dropout=0.0, **kwargs
|
||||
):
|
||||
"""query (1, Hq, S, D), key/value (1, Hkv, S, D) — packed documents."""
|
||||
_b, hq, s, d = query.shape
|
||||
hkv = key.shape[1]
|
||||
q = query.transpose(1, 2).reshape(s, hq, d)
|
||||
k = key.transpose(1, 2).reshape(s, hkv, d)
|
||||
v = value.transpose(1, 2).reshape(s, hkv, d)
|
||||
out = _CTX["wrapper"].run(q, k, v) # (S, Hq, D)
|
||||
return out.view(1, s, hq, d), None
|
||||
|
||||
|
||||
AttentionInterface.register("omnivoice_fi", _flashinfer_attention)
|
||||
|
||||
|
||||
def _fi_rmsnorm_forward(self, hidden_states: torch.Tensor) -> torch.Tensor:
|
||||
"""Single-kernel replacement for Qwen3RMSNorm.forward (a 7-kernel
|
||||
fp32-upcast chain in eager mode). flashinfer.norm.rmsnorm computes in
|
||||
fp32 internally and matches to fp16 rounding."""
|
||||
shape = hidden_states.shape
|
||||
out = flashinfer.norm.rmsnorm(
|
||||
hidden_states.reshape(-1, shape[-1]).contiguous(),
|
||||
self.weight,
|
||||
eps=self.variance_epsilon,
|
||||
)
|
||||
return out.view(shape)
|
||||
|
||||
|
||||
def _patch_rmsnorm(llm):
|
||||
from transformers.models.qwen3.modeling_qwen3 import Qwen3RMSNorm
|
||||
|
||||
n = 0
|
||||
for module in llm.modules():
|
||||
if isinstance(module, Qwen3RMSNorm):
|
||||
module.forward = MethodType(_fi_rmsnorm_forward, module)
|
||||
n += 1
|
||||
return n
|
||||
|
||||
|
||||
def _fi_attention_module_forward(
|
||||
self,
|
||||
hidden_states,
|
||||
position_embeddings=None,
|
||||
attention_mask=None,
|
||||
past_key_values=None,
|
||||
**kwargs,
|
||||
):
|
||||
"""NHD-layout replacement for Qwen3Attention.forward (packed batch=1).
|
||||
|
||||
The stock forward works in (B, H, S, D): the rotate-half RoPE costs a cat
|
||||
plus four elementwise passes, and handing (B,H,S,D) to the ragged wrapper
|
||||
costs three transpose copies. Keeping everything in (S, H, D) removes all
|
||||
of that; RoPE is one fused in-place kernel driven by packed position ids
|
||||
(read from _CTX, set per generation / baked per graph)."""
|
||||
s = hidden_states.shape[1]
|
||||
x = hidden_states[0] # (S, hidden)
|
||||
if getattr(self, "_fi_w_qkv", None) is not None:
|
||||
qkv = F.linear(x, self._fi_w_qkv)
|
||||
q, k, v = qkv.split(self._fi_qkv_split, dim=-1)
|
||||
# split views are strided; reshape materializes contiguous copies
|
||||
# (q/k would be copied inside the fused rmsnorm anyway)
|
||||
q = self.q_norm(q.reshape(s, -1, self.head_dim))
|
||||
k = self.k_norm(k.reshape(s, -1, self.head_dim))
|
||||
v = v.reshape(s, -1, self.head_dim)
|
||||
else:
|
||||
q = self.q_norm(self.q_proj(x).view(s, -1, self.head_dim))
|
||||
k = self.k_norm(self.k_proj(x).view(s, -1, self.head_dim))
|
||||
v = self.v_proj(x).view(s, -1, self.head_dim)
|
||||
flashinfer.rope.apply_rope_pos_ids_inplace(
|
||||
q, k, _CTX["pos_ids"], rope_theta=self._fi_rope_theta, interleave=False
|
||||
)
|
||||
slots = _CTX.get("doc_slots")
|
||||
if slots is not None:
|
||||
# bucketed-graph mode: a flashinfer plan bakes document boundaries
|
||||
# into the graph, so attention runs per fixed-length document slot as
|
||||
# SDPA with an O(slot) key-padding mask whose contents are rewritten
|
||||
# per generation. (A dense (S,S) block-diag mask scales quadratically
|
||||
# and the enable_gqa+mask combo drops SDPA to the math backend, so
|
||||
# k/v are pre-expanded to full heads instead.)
|
||||
ng = self.num_key_value_groups
|
||||
k = k.repeat_interleave(ng, dim=1) # (S, Hq, D)
|
||||
v = v.repeat_interleave(ng, dim=1)
|
||||
out = torch.empty_like(q)
|
||||
for start, slot_len, m in slots:
|
||||
od = F.scaled_dot_product_attention(
|
||||
q[start : start + slot_len].transpose(0, 1).unsqueeze(0),
|
||||
k[start : start + slot_len].transpose(0, 1).unsqueeze(0),
|
||||
v[start : start + slot_len].transpose(0, 1).unsqueeze(0),
|
||||
attn_mask=m,
|
||||
)
|
||||
out[start : start + slot_len] = od.squeeze(0).transpose(0, 1)
|
||||
else:
|
||||
out = _CTX["wrapper"].run(q, k, v) # (S, Hq, D)
|
||||
return self.o_proj(out.reshape(s, -1)).unsqueeze(0), None
|
||||
|
||||
|
||||
def _patch_attention_forward(llm, fuse_qkv=True):
|
||||
theta = llm.config.rope_parameters["rope_theta"]
|
||||
for layer in llm.layers:
|
||||
attn = layer.self_attn
|
||||
attn._fi_rope_theta = theta
|
||||
if fuse_qkv:
|
||||
attn._fi_w_qkv = torch.cat(
|
||||
[attn.q_proj.weight, attn.k_proj.weight, attn.v_proj.weight], dim=0
|
||||
)
|
||||
attn._fi_qkv_split = [
|
||||
attn.q_proj.weight.shape[0],
|
||||
attn.k_proj.weight.shape[0],
|
||||
attn.v_proj.weight.shape[0],
|
||||
]
|
||||
attn.forward = MethodType(_fi_attention_module_forward, attn)
|
||||
|
||||
|
||||
def _fi_mlp_forward(self, x):
|
||||
"""Qwen3MLP with fused gate+up GEMM and flashinfer silu_and_mul
|
||||
(2 GEMMs + silu + mul -> 1 GEMM + 1 fused kernel)."""
|
||||
y = F.linear(x[0], self._fi_w_gate_up) # (S, 2*inter)
|
||||
y = flashinfer.activation.silu_and_mul(y)
|
||||
return self.down_proj(y).unsqueeze(0)
|
||||
|
||||
|
||||
def _patch_mlp(llm):
|
||||
for layer in llm.layers:
|
||||
mlp = layer.mlp
|
||||
mlp._fi_w_gate_up = torch.cat([mlp.gate_proj.weight, mlp.up_proj.weight], dim=0)
|
||||
mlp.forward = MethodType(_fi_mlp_forward, mlp)
|
||||
|
||||
|
||||
class PackedAttnRunner:
|
||||
def __init__(
|
||||
self,
|
||||
num_qo_heads,
|
||||
num_kv_heads,
|
||||
head_dim,
|
||||
device,
|
||||
workspace_size=_WORKSPACE_SIZE,
|
||||
):
|
||||
self.num_qo_heads = num_qo_heads
|
||||
self.num_kv_heads = num_kv_heads
|
||||
self.head_dim = head_dim
|
||||
self.device = device
|
||||
self._workspace = torch.zeros(workspace_size, dtype=torch.uint8, device=device)
|
||||
self.wrapper = flashinfer.BatchPrefillWithRaggedKVCacheWrapper(
|
||||
self._workspace, "NHD"
|
||||
)
|
||||
self._planned_key = None
|
||||
|
||||
def plan(self, doc_lens: List[int], dtype: torch.dtype):
|
||||
key = (tuple(doc_lens), dtype)
|
||||
if key == self._planned_key:
|
||||
return
|
||||
indptr = torch.zeros(len(doc_lens) + 1, dtype=torch.int32, device=self.device)
|
||||
indptr[1:] = torch.cumsum(
|
||||
torch.tensor(doc_lens, dtype=torch.int32, device=self.device), dim=0
|
||||
)
|
||||
self.wrapper.plan(
|
||||
indptr,
|
||||
indptr,
|
||||
self.num_qo_heads,
|
||||
self.num_kv_heads,
|
||||
self.head_dim,
|
||||
causal=False,
|
||||
sm_scale=self.head_dim**-0.5,
|
||||
q_data_type=dtype,
|
||||
kv_data_type=dtype,
|
||||
)
|
||||
self._planned_key = key
|
||||
|
||||
|
||||
def _generate_iterative_packed(
|
||||
self, task: GenerationTask, gen_config: OmniVoiceGenerationConfig
|
||||
) -> List[torch.Tensor]:
|
||||
"""Packed-sequence rewrite of OmniVoice._generate_iterative.
|
||||
|
||||
Documents are packed as [cond_0, uncond_0, cond_1, uncond_1, ...] into a
|
||||
single batch row; the scoring/unmasking math is identical to the original.
|
||||
"""
|
||||
B = task.batch_size
|
||||
inputs_list = [
|
||||
self._prepare_inference_inputs(
|
||||
task.texts[i],
|
||||
task.target_lens[i],
|
||||
task.ref_texts[i],
|
||||
task.ref_audio_tokens[i],
|
||||
task.langs[i],
|
||||
task.instructs[i],
|
||||
gen_config.denoise,
|
||||
)
|
||||
for i in range(B)
|
||||
]
|
||||
|
||||
c_lens = [inp["input_ids"].size(2) for inp in inputs_list]
|
||||
u_lens = list(task.target_lens)
|
||||
doc_lens = []
|
||||
for c, u in zip(c_lens, u_lens):
|
||||
doc_lens.extend([c, u])
|
||||
|
||||
use_graph = getattr(self, "_fi_enable_cuda_graph", False)
|
||||
buckets = getattr(self, "_fi_graph_buckets", None) # durations in seconds
|
||||
|
||||
# Choose the packed layout. Bucketed-graph mode places each item in fixed
|
||||
# slots [C_budget | U_budget] so one graph per (batch, duration bucket)
|
||||
# serves any sample that fits; otherwise pack tightly.
|
||||
bucket_U = None
|
||||
if use_graph and buckets is not None:
|
||||
frame_rate = self.audio_tokenizer.config.frame_rate
|
||||
t_max = max(u_lens)
|
||||
overhead_max = max(c - u for c, u in zip(c_lens, u_lens))
|
||||
bucket_U = next(
|
||||
(int(d * frame_rate) for d in sorted(buckets) if d * frame_rate >= t_max),
|
||||
None,
|
||||
)
|
||||
if bucket_U is None or overhead_max > self._fi_overhead_budget:
|
||||
bucket_U = None
|
||||
use_graph = False # too long for the buckets: eager fallback
|
||||
|
||||
if bucket_U is not None:
|
||||
U_b = bucket_U
|
||||
C_b = U_b + self._fi_overhead_budget
|
||||
offsets = []
|
||||
for i in range(B):
|
||||
offsets.extend([i * (C_b + U_b), i * (C_b + U_b) + C_b])
|
||||
total_len = B * (C_b + U_b)
|
||||
else:
|
||||
offsets = [0]
|
||||
for l in doc_lens[:-1]:
|
||||
offsets.append(offsets[-1] + l)
|
||||
total_len = sum(doc_lens)
|
||||
|
||||
C = self.config.num_audio_codebook
|
||||
packed_ids = torch.full(
|
||||
(1, C, total_len),
|
||||
self.config.audio_mask_id,
|
||||
dtype=torch.long,
|
||||
device=self.device,
|
||||
)
|
||||
packed_audio_mask = torch.zeros(
|
||||
(1, total_len), dtype=torch.bool, device=self.device
|
||||
)
|
||||
position_ids = torch.zeros((1, total_len), dtype=torch.long, device=self.device)
|
||||
|
||||
for i, inp in enumerate(inputs_list):
|
||||
c_off, u_off = offsets[2 * i], offsets[2 * i + 1]
|
||||
c_len, u_len = c_lens[i], u_lens[i]
|
||||
packed_ids[0, :, c_off : c_off + c_len] = inp["input_ids"][0]
|
||||
packed_audio_mask[0, c_off : c_off + c_len] = inp["audio_mask"][0]
|
||||
position_ids[0, c_off : c_off + c_len] = torch.arange(c_len, device=self.device)
|
||||
# uncond doc = target region only
|
||||
packed_ids[0, :, u_off : u_off + u_len] = inp["input_ids"][0, :, -u_len:]
|
||||
packed_audio_mask[0, u_off : u_off + u_len] = inp["audio_mask"][0, -u_len:]
|
||||
position_ids[0, u_off : u_off + u_len] = torch.arange(u_len, device=self.device)
|
||||
|
||||
# num_step + 1 mirrors our _generate_iterative's schedule (a local
|
||||
# divergence from upstream k2-fsa): packed decoding must unmask on exactly
|
||||
# the same schedule as the eager path or outputs differ between the two.
|
||||
timesteps = _get_time_steps(
|
||||
t_start=0.0,
|
||||
t_end=1.0,
|
||||
num_step=gen_config.num_step + 1,
|
||||
t_shift=gen_config.t_shift,
|
||||
).tolist()
|
||||
schedules = []
|
||||
for t_len in task.target_lens:
|
||||
total_mask = t_len * C
|
||||
rem = total_mask
|
||||
sched = []
|
||||
for step in range(gen_config.num_step):
|
||||
num = (
|
||||
rem
|
||||
if step == gen_config.num_step - 1
|
||||
else min(
|
||||
math.ceil(total_mask * (timesteps[step + 1] - timesteps[step])), rem
|
||||
)
|
||||
)
|
||||
sched.append(int(num))
|
||||
rem -= int(num)
|
||||
schedules.append(sched)
|
||||
|
||||
layer_ids = torch.arange(C, device=self.device).view(1, -1, 1)
|
||||
|
||||
# gather indices of the logits-consuming positions, laid out as
|
||||
# [all cond-target blocks | all uncond blocks] so the guidance/scoring
|
||||
# math can run over every item in one batched pass. flat_spans[i] gives
|
||||
# the item's (start, len) within each half; in bucket mode items sit at a
|
||||
# fixed stride U_b with junk rows (pointing at position 0) in between.
|
||||
cond_ranges, uncond_ranges = [], []
|
||||
flat_spans = []
|
||||
for i in range(B):
|
||||
c_off, u_off = offsets[2 * i], offsets[2 * i + 1]
|
||||
c_len, t_len = c_lens[i], task.target_lens[i]
|
||||
if bucket_U is not None:
|
||||
flat_spans.append((U_b * i, t_len))
|
||||
cond_rows = torch.zeros(U_b, dtype=torch.long, device=self.device)
|
||||
cond_rows[:t_len] = torch.arange(
|
||||
c_off + c_len - t_len, c_off + c_len, device=self.device
|
||||
)
|
||||
uncond_rows = torch.zeros(U_b, dtype=torch.long, device=self.device)
|
||||
uncond_rows[:t_len] = torch.arange(u_off, u_off + t_len, device=self.device)
|
||||
cond_ranges.append(cond_rows)
|
||||
uncond_ranges.append(uncond_rows)
|
||||
else:
|
||||
prev = 0 if i == 0 else flat_spans[-1][0] + flat_spans[-1][1]
|
||||
flat_spans.append((prev, t_len))
|
||||
cond_ranges.append(
|
||||
torch.arange(c_off + c_len - t_len, c_off + c_len, device=self.device)
|
||||
)
|
||||
uncond_ranges.append(torch.arange(u_off, u_off + t_len, device=self.device))
|
||||
T_flat = (U_b * B) if bucket_U is not None else sum(task.target_lens)
|
||||
tgt_index = torch.cat(cond_ranges + uncond_ranges)
|
||||
|
||||
# flat per-position token state aligned with the cond half of the gathered
|
||||
# layout. Junk positions (bucket-mode slot padding) are initialized to -1
|
||||
# so the global "already unmasked" fill gives them -inf scores and topk
|
||||
# never selects them.
|
||||
tokens_flat = torch.full((C, T_flat), -1, dtype=torch.long, device=self.device)
|
||||
for st, t_len in flat_spans:
|
||||
tokens_flat[:, st : st + t_len] = self.config.audio_mask_id
|
||||
|
||||
if use_graph and bucket_U is not None:
|
||||
graph_entry = _get_or_capture_bucket_graph(self, B, U_b, C_b)
|
||||
# refresh the per-generation static contents (shape-invariant, data-variant)
|
||||
graph_entry["audio_mask"].copy_(packed_audio_mask)
|
||||
graph_entry["position_ids"].copy_(position_ids)
|
||||
graph_entry["pos_ids_i32"].copy_(position_ids[0].to(torch.int32))
|
||||
graph_entry["tgt_index"].copy_(tgt_index)
|
||||
for d_idx, m in enumerate(graph_entry["doc_masks"]):
|
||||
length = c_lens[d_idx // 2] if d_idx % 2 == 0 else u_lens[d_idx // 2]
|
||||
m[..., :length] = True
|
||||
m[..., length:] = False
|
||||
elif use_graph:
|
||||
graph_entry = _get_or_capture_graph(self, tuple(doc_lens), tgt_index)
|
||||
graph_entry["audio_mask"].copy_(packed_audio_mask)
|
||||
graph_entry["position_ids"].copy_(position_ids)
|
||||
else:
|
||||
self._fi_runner.plan(doc_lens, torch.float16)
|
||||
_CTX["wrapper"] = self._fi_runner.wrapper
|
||||
_CTX["pos_ids"] = position_ids[0].to(torch.int32)
|
||||
_CTX["doc_slots"] = None
|
||||
|
||||
# optional llm timing hook (set by the benchmark; graph replays bypass
|
||||
# model.forward, so wrapping forward would miss them)
|
||||
stats = getattr(self, "_fi_llm_stats", None)
|
||||
|
||||
for step in range(gen_config.num_step):
|
||||
if stats is not None:
|
||||
torch.cuda.synchronize()
|
||||
t0 = time.perf_counter()
|
||||
if use_graph:
|
||||
graph_entry["input_ids"].copy_(packed_ids)
|
||||
graph_entry["graph"].replay()
|
||||
batch_logits = graph_entry["logits"].to(torch.float32)
|
||||
else:
|
||||
batch_logits = _forward_logits(
|
||||
self, packed_ids, packed_audio_mask, position_ids, tgt_index
|
||||
).to(torch.float32)
|
||||
if stats is not None:
|
||||
torch.cuda.synchronize()
|
||||
stats["seconds"] += time.perf_counter() - t0
|
||||
stats["calls"] += 1
|
||||
|
||||
# batched scoring over every item at once: the guidance/log_softmax/
|
||||
# argmax/gumbel chain (the GPU-heavy part) runs on the whole
|
||||
# [cond | uncond] halves; only topk + scatter stay per item.
|
||||
c_logits_all = batch_logits[:, :, :T_flat, :]
|
||||
u_logits_all = batch_logits[:, :, T_flat:, :]
|
||||
pred_all, scores_all = self._predict_tokens_with_scoring(
|
||||
c_logits_all, u_logits_all, gen_config
|
||||
)
|
||||
scores_all = scores_all - (layer_ids * gen_config.layer_penalty_factor)
|
||||
if gen_config.position_temperature > 0.0:
|
||||
scores_all = _gumbel_sample(scores_all, gen_config.position_temperature)
|
||||
# -inf for already-unmasked positions AND bucket-slot junk (-1)
|
||||
scores_all.masked_fill_(
|
||||
(tokens_flat != self.config.audio_mask_id).unsqueeze(0), -float("inf")
|
||||
)
|
||||
pred_all, scores_all = pred_all[0], scores_all[0] # (C, T_flat)
|
||||
|
||||
for i in range(B):
|
||||
k = schedules[i][step]
|
||||
if k <= 0:
|
||||
continue
|
||||
c_off, u_off = offsets[2 * i], offsets[2 * i + 1]
|
||||
c_len, t_len = c_lens[i], task.target_lens[i]
|
||||
st, _ = flat_spans[i]
|
||||
|
||||
_, topk_idx = torch.topk(scores_all[:, st : st + t_len].reshape(-1), k)
|
||||
flat_tokens = tokens_flat[:, st : st + t_len].reshape(-1)
|
||||
flat_tokens[topk_idx] = pred_all[:, st : st + t_len].reshape(-1)[topk_idx]
|
||||
new_tokens = flat_tokens.view(C, t_len)
|
||||
tokens_flat[:, st : st + t_len] = new_tokens
|
||||
|
||||
packed_ids[0, :, c_off + c_len - t_len : c_off + c_len] = new_tokens
|
||||
packed_ids[0, :, u_off : u_off + t_len] = new_tokens
|
||||
|
||||
return [tokens_flat[:, st : st + t_len] for (st, t_len) in flat_spans]
|
||||
|
||||
|
||||
def _forward_logits(model, input_ids, audio_mask, position_ids, tgt_index):
|
||||
"""LLM forward + audio head over target positions only.
|
||||
|
||||
The scoring step consumes logits at the cond-target and uncond ranges
|
||||
(2*sum(t_len) of the packed positions); running the 1024->8200 audio_heads
|
||||
GEMM and the fp32 upcast on the full packed length is wasted work.
|
||||
Returns logits of shape (1, C, 2*sum(t_len), V) laid out as
|
||||
[all cond-target blocks | all uncond blocks] — matching tgt_index
|
||||
(torch.cat(cond_ranges + uncond_ranges)) and the caller's split at T_flat.
|
||||
"""
|
||||
inputs_embeds = model._prepare_embed_inputs(input_ids, audio_mask)
|
||||
hidden = model.llm(
|
||||
inputs_embeds=inputs_embeds,
|
||||
attention_mask={"full_attention": None},
|
||||
return_dict=True,
|
||||
position_ids=position_ids,
|
||||
)[0]
|
||||
tgt_hidden = hidden[0, tgt_index] # (2T, hidden)
|
||||
logits_flat = model.audio_heads(tgt_hidden)
|
||||
n = tgt_hidden.shape[0]
|
||||
return logits_flat.view(
|
||||
1, n, model.config.num_audio_codebook, model.config.audio_vocab_size
|
||||
).permute(0, 2, 1, 3)
|
||||
|
||||
|
||||
def _get_or_capture_graph(model, doc_lens_key, tgt_index):
|
||||
cache = model._fi_graph_cache
|
||||
entry = cache.get(doc_lens_key)
|
||||
if entry is not None:
|
||||
return entry
|
||||
|
||||
device = model.device
|
||||
total_len = sum(doc_lens_key)
|
||||
C = model.config.num_audio_codebook
|
||||
llm_cfg = model.config.llm_config
|
||||
runner = PackedAttnRunner(
|
||||
llm_cfg.num_attention_heads,
|
||||
llm_cfg.num_key_value_heads,
|
||||
llm_cfg.head_dim,
|
||||
device,
|
||||
workspace_size=64 * 1024 * 1024,
|
||||
)
|
||||
runner.plan(list(doc_lens_key), torch.float16)
|
||||
_CTX["wrapper"] = runner.wrapper
|
||||
|
||||
# positions are fully determined by doc_lens (the cache key), so both the
|
||||
# long buffer (model-level rotary) and the int32 copy (fused rope) can be
|
||||
# baked with their final values
|
||||
positions = torch.cat([torch.arange(l, device=device) for l in doc_lens_key])
|
||||
static = {
|
||||
"input_ids": torch.full(
|
||||
(1, C, total_len),
|
||||
model.config.audio_mask_id,
|
||||
dtype=torch.long,
|
||||
device=device,
|
||||
),
|
||||
"audio_mask": torch.zeros((1, total_len), dtype=torch.bool, device=device),
|
||||
"position_ids": positions.unsqueeze(0).contiguous(),
|
||||
}
|
||||
pos_ids_i32 = positions.to(torch.int32)
|
||||
_CTX["pos_ids"] = pos_ids_i32
|
||||
_CTX["doc_slots"] = None
|
||||
|
||||
side_stream = torch.cuda.Stream()
|
||||
side_stream.wait_stream(torch.cuda.current_stream())
|
||||
with torch.cuda.stream(side_stream):
|
||||
for _ in range(2):
|
||||
_forward_logits(
|
||||
model,
|
||||
static["input_ids"],
|
||||
static["audio_mask"],
|
||||
static["position_ids"],
|
||||
tgt_index,
|
||||
)
|
||||
torch.cuda.current_stream().wait_stream(side_stream)
|
||||
torch.cuda.synchronize()
|
||||
|
||||
graph = torch.cuda.CUDAGraph()
|
||||
with torch.cuda.graph(graph):
|
||||
# tgt_index depends only on doc_lens (the cache key), so it is safe
|
||||
# to bake into the graph
|
||||
logits = _forward_logits(
|
||||
model,
|
||||
static["input_ids"],
|
||||
static["audio_mask"],
|
||||
static["position_ids"],
|
||||
tgt_index,
|
||||
)
|
||||
|
||||
# tgt_index is baked into the captured gather by pointer — the entry must
|
||||
# keep it alive or the allocator will reuse its memory for later samples
|
||||
entry = {
|
||||
"graph": graph,
|
||||
"logits": logits,
|
||||
"runner": runner,
|
||||
"tgt_index": tgt_index,
|
||||
"pos_ids_i32": pos_ids_i32,
|
||||
**static,
|
||||
}
|
||||
cache[doc_lens_key] = entry
|
||||
return entry
|
||||
|
||||
|
||||
def _get_or_capture_bucket_graph(model, B, U_b, C_b):
|
||||
"""One graph per (batch, duration-bucket): items sit in fixed
|
||||
[C_budget | U_budget] slots; attention runs as SDPA over a runtime-updated
|
||||
block-diagonal mask, so any sample that fits the slots replays exactly."""
|
||||
key = ("bucket", B, U_b)
|
||||
cache = model._fi_graph_cache
|
||||
entry = cache.get(key)
|
||||
if entry is not None:
|
||||
return entry
|
||||
|
||||
device = model.device
|
||||
total_len = B * (C_b + U_b)
|
||||
C = model.config.num_audio_codebook
|
||||
|
||||
static = {
|
||||
"input_ids": torch.full(
|
||||
(1, C, total_len),
|
||||
model.config.audio_mask_id,
|
||||
dtype=torch.long,
|
||||
device=device,
|
||||
),
|
||||
"audio_mask": torch.zeros((1, total_len), dtype=torch.bool, device=device),
|
||||
"position_ids": torch.zeros((1, total_len), dtype=torch.long, device=device),
|
||||
"pos_ids_i32": torch.zeros(total_len, dtype=torch.int32, device=device),
|
||||
"tgt_index": torch.zeros(2 * B * U_b, dtype=torch.long, device=device),
|
||||
}
|
||||
# per-document key-padding masks (contents updated per generation);
|
||||
# init all-True so warmup/capture has no fully-masked softmax rows
|
||||
doc_masks, doc_slots = [], []
|
||||
for i in range(B):
|
||||
for slot_start, slot_len in (
|
||||
(i * (C_b + U_b), C_b),
|
||||
(i * (C_b + U_b) + C_b, U_b),
|
||||
):
|
||||
m = torch.ones(1, 1, 1, slot_len, dtype=torch.bool, device=device)
|
||||
doc_masks.append(m)
|
||||
doc_slots.append((slot_start, slot_len, m))
|
||||
|
||||
_CTX["wrapper"] = None
|
||||
_CTX["pos_ids"] = static["pos_ids_i32"]
|
||||
_CTX["doc_slots"] = doc_slots
|
||||
|
||||
side_stream = torch.cuda.Stream()
|
||||
side_stream.wait_stream(torch.cuda.current_stream())
|
||||
with torch.cuda.stream(side_stream):
|
||||
for _ in range(2):
|
||||
_forward_logits(
|
||||
model,
|
||||
static["input_ids"],
|
||||
static["audio_mask"],
|
||||
static["position_ids"],
|
||||
static["tgt_index"],
|
||||
)
|
||||
torch.cuda.current_stream().wait_stream(side_stream)
|
||||
torch.cuda.synchronize()
|
||||
|
||||
graph = torch.cuda.CUDAGraph()
|
||||
with torch.cuda.graph(graph):
|
||||
logits = _forward_logits(
|
||||
model,
|
||||
static["input_ids"],
|
||||
static["audio_mask"],
|
||||
static["position_ids"],
|
||||
static["tgt_index"],
|
||||
)
|
||||
|
||||
entry = {
|
||||
"graph": graph,
|
||||
"logits": logits,
|
||||
"doc_masks": doc_masks,
|
||||
"doc_slots": doc_slots,
|
||||
**static,
|
||||
}
|
||||
cache[key] = entry
|
||||
return entry
|
||||
|
||||
|
||||
def apply_flashinfer(
|
||||
model,
|
||||
enable_cuda_graph: bool = False,
|
||||
fuse_rmsnorm: bool = True,
|
||||
fuse_attention: bool = True,
|
||||
cuda_graph_buckets=None,
|
||||
overhead_budget: int = 512,
|
||||
):
|
||||
"""Patch an OmniVoice instance to use flashinfer packed attention."""
|
||||
model.llm.set_attn_implementation("omnivoice_fi")
|
||||
if fuse_rmsnorm:
|
||||
_patch_rmsnorm(model.llm)
|
||||
if fuse_attention:
|
||||
_patch_attention_forward(model.llm)
|
||||
_patch_mlp(model.llm)
|
||||
# Bidirectional iterative decoding recomputes everything each step; the
|
||||
# DynamicCache the baseline allocates+fills per forward is pure overhead.
|
||||
model.llm.config.use_cache = False
|
||||
|
||||
llm_cfg = model.config.llm_config
|
||||
model._fi_runner = PackedAttnRunner(
|
||||
llm_cfg.num_attention_heads,
|
||||
llm_cfg.num_key_value_heads,
|
||||
llm_cfg.head_dim,
|
||||
model.device,
|
||||
)
|
||||
model._fi_graph_cache = {}
|
||||
model._fi_enable_cuda_graph = enable_cuda_graph or cuda_graph_buckets is not None
|
||||
model._fi_graph_buckets = cuda_graph_buckets
|
||||
model._fi_overhead_budget = overhead_budget
|
||||
model._generate_iterative = MethodType(_generate_iterative_packed, model)
|
||||
return model
|
||||
@@ -75,8 +75,13 @@ def stage(name: str):
|
||||
"""Run a stage only if there's room, and always leave the machine clean."""
|
||||
release_everything()
|
||||
have = free_gb()
|
||||
if have < FLOOR_GB:
|
||||
print(f"\n=== {name}: SKIPPED — only {have:.1f} GB free (floor {FLOOR_GB} GB)", flush=True)
|
||||
# `not (have >= FLOOR_GB)` instead of `have < FLOOR_GB`: NaN (RAM
|
||||
# unmeasurable) fails every comparison, and an unmeasurable machine should
|
||||
# refuse the stage rather than risk the OOM the floor exists to prevent.
|
||||
# OMNIVOICE_BENCH_FLOOR_GB=0 disables the guard entirely.
|
||||
if FLOOR_GB > 0 and not (have >= FLOOR_GB):
|
||||
print(f"\n=== {name}: SKIPPED — only {have:.1f} GB free (floor {FLOOR_GB} GB; "
|
||||
f"OMNIVOICE_BENCH_FLOOR_GB=0 to force)", flush=True)
|
||||
RESULTS.append((name, "skipped", 0.0, f"only {have:.1f} GB free"))
|
||||
yield None
|
||||
return
|
||||
@@ -111,18 +116,102 @@ LONG = (
|
||||
)
|
||||
|
||||
|
||||
def _cuda_vram_tracking_start() -> None:
|
||||
try:
|
||||
import torch
|
||||
|
||||
if torch.cuda.is_available():
|
||||
torch.cuda.reset_peak_memory_stats()
|
||||
except Exception:
|
||||
# No torch / broken CUDA runtime: VRAM tracking is a bonus metric,
|
||||
# never a reason to abort the timing run.
|
||||
pass
|
||||
|
||||
|
||||
def _cuda_vram_peak_gb() -> "float | None":
|
||||
"""CUDA only. MPS is unified memory (the free-RAM lines already show it)
|
||||
and exposes no peak counter; CPU has no VRAM. Returning None keeps the
|
||||
report honest instead of printing a made-up zero."""
|
||||
try:
|
||||
import torch
|
||||
|
||||
if torch.cuda.is_available():
|
||||
# Reserved, not allocated: the allocator holds more from the
|
||||
# device than live tensors occupy, and reserved is the capacity
|
||||
# a card actually needs to run the engine.
|
||||
return torch.cuda.max_memory_reserved() / 1e9
|
||||
except Exception:
|
||||
# Same as tracking start: an unreadable counter degrades to "no VRAM
|
||||
# row", it must not fail the stage.
|
||||
pass
|
||||
return None
|
||||
|
||||
|
||||
def _engine_runs_out_of_process(backend) -> bool:
|
||||
"""Duck-typed on purpose: `isinstance(SubprocessBackend)` misses engines
|
||||
that spawn a binary per generate (omnivoice-gguf inherits TTSBackend
|
||||
directly), and class identity breaks under test-fixture module purges.
|
||||
The backends declare `runs_out_of_process` themselves."""
|
||||
return bool(getattr(backend, "runs_out_of_process", False))
|
||||
|
||||
|
||||
def bench_tts():
|
||||
"""Synthesis alone — no cloning, no reference. The floor for any dub."""
|
||||
"""Synthesis alone — no cloning, no reference. The floor for any dub.
|
||||
Warm measurements also report RTF (compute seconds per second of generated
|
||||
audio — the number docs/benchmarks.md collects; < 1 is faster than real
|
||||
time), and on CUDA the stage's peak VRAM."""
|
||||
import asyncio
|
||||
|
||||
from services.tts_backend import resolve_generation_backend
|
||||
from services.tts_backend import active_backend_id, resolve_generation_backend
|
||||
|
||||
# Tracking starts BEFORE resolution so any allocation the resolver makes
|
||||
# is inside the peak, and the engine is printed so a benchmarks.md row
|
||||
# can never attribute numbers to the wrong backend.
|
||||
_cuda_vram_tracking_start()
|
||||
b = asyncio.run(resolve_generation_backend(require_cloning=False))
|
||||
gen = lambda t: b.generate(text=t, language="en", denoise=True, postprocess_output=True)
|
||||
# Adapter engines host several very different models behind one backend
|
||||
# id — name the model too, or rows are unattributable. The backends
|
||||
# report it themselves (TTSBackend.model_identity), so this never needs
|
||||
# per-engine attribute knowledge again.
|
||||
try:
|
||||
model_id = b.model_identity()
|
||||
except Exception:
|
||||
model_id = None
|
||||
print(
|
||||
f" engine: {active_backend_id()}"
|
||||
+ (f" [{model_id}]" if model_id else "")
|
||||
+ f" ({type(b).__name__})",
|
||||
flush=True,
|
||||
)
|
||||
sr = getattr(b, "sample_rate", 0) or 0
|
||||
last: dict = {}
|
||||
|
||||
def gen(t):
|
||||
last["wav"] = b.generate(text=t, language="en", denoise=True, postprocess_output=True)
|
||||
|
||||
def rtf_note(secs: float) -> str:
|
||||
wav = last.get("wav")
|
||||
n = getattr(wav, "shape", [0])[-1] if wav is not None else 0
|
||||
if not (sr and n):
|
||||
return ""
|
||||
audio_s = n / sr
|
||||
return f"RTF {secs / audio_s:.2f} ({audio_s:.1f}s of audio)"
|
||||
|
||||
record("tts", "model load + first synth (cold)", timed(gen, SHORT))
|
||||
record("tts", "short line (warm)", timed(gen, SHORT))
|
||||
record("tts", "long line (warm)", timed(gen, LONG), "~2.5x the text")
|
||||
secs = timed(gen, SHORT)
|
||||
record("tts", "short line (warm)", secs, rtf_note(secs))
|
||||
secs = timed(gen, LONG)
|
||||
record("tts", "long line (warm)", secs, rtf_note(secs) or "~2.5x the text")
|
||||
if _engine_runs_out_of_process(b):
|
||||
# Subprocess-isolated engines (IndexTTS2, MOSS, PocketTTS, …) allocate
|
||||
# in their own process — the parent's CUDA counters read ~0, which
|
||||
# would publish a convincing lie. Say n/a instead.
|
||||
print(" peak VRAM: n/a — engine runs in a subprocess, invisible to "
|
||||
"the parent's CUDA counters", flush=True)
|
||||
else:
|
||||
peak = _cuda_vram_peak_gb()
|
||||
if peak is not None:
|
||||
record("tts", "peak VRAM (GB)", peak, "CUDA only — value column is GB")
|
||||
|
||||
|
||||
def bench_clone():
|
||||
@@ -211,7 +300,7 @@ def main() -> None:
|
||||
fn()
|
||||
|
||||
print("\n" + "=" * 68)
|
||||
print(f"{'stage':<8} {'measurement':<40} {'seconds':>8}")
|
||||
print(f"{'stage':<8} {'measurement':<40} {'value':>8}")
|
||||
print("-" * 68)
|
||||
for st, what, secs, note in RESULTS:
|
||||
print(f"{st:<8} {what:<40} {secs:>8.2f} {note}")
|
||||
|
||||
@@ -0,0 +1,17 @@
|
||||
{
|
||||
"version": 1,
|
||||
"skills": {
|
||||
"fastapi-python": {
|
||||
"source": "mindrally/skills",
|
||||
"sourceType": "github",
|
||||
"skillPath": "fastapi-python/SKILL.md",
|
||||
"computedHash": "cd9c84b3bf2e4cf55f4a3f97b102d3affad2682680eb3d8ec8d2f68020ba5c8d"
|
||||
},
|
||||
"vite": {
|
||||
"source": "mindrally/skills",
|
||||
"sourceType": "github",
|
||||
"skillPath": "vite/SKILL.md",
|
||||
"computedHash": "8995600ea3cf7c18208105011f65b9098a547a19dff446fb774e42ac726d36b1"
|
||||
}
|
||||
}
|
||||
}
|
||||
@@ -627,7 +627,7 @@ def test_engine_health_is_admin_gated(fresh_app):
|
||||
client = _client(fresh_app, host="10.0.0.5")
|
||||
r = client.get("/engines/omnivoice/health")
|
||||
assert r.status_code == 403
|
||||
assert r.json()["detail"] == "loopback origin or admin API key required"
|
||||
assert r.json()["detail"] == "loopback origin required"
|
||||
|
||||
|
||||
def test_server_mode_engine_mutations_require_api_key(fresh_app, monkeypatch):
|
||||
@@ -802,7 +802,7 @@ def test_selftest_unknown_id_is_404(fresh_app):
|
||||
def test_selftest_is_admin_gated(fresh_app):
|
||||
r = _client(fresh_app, host="10.0.0.9").post("/engines/omnivoice/selftest")
|
||||
assert r.status_code == 403
|
||||
assert r.json()["detail"] == "loopback origin or admin API key required"
|
||||
assert r.json()["detail"] == "loopback origin required"
|
||||
|
||||
|
||||
def test_selftest_captures_synth_exception_without_500(fresh_app):
|
||||
|
||||
@@ -0,0 +1,111 @@
|
||||
"""Tests for the compute-device override endpoints (Settings → Performance).
|
||||
|
||||
Covers the API contract of GET/PUT /api/settings/compute-device:
|
||||
- GET reports the resolved pick, what this process applied, and the host's
|
||||
available families (the UI renders only those + Auto).
|
||||
- PUT persists a valid pick to prefs.json and echoes the new state with
|
||||
restart_required=True (caps are immutable per process).
|
||||
- PUT rejects unknown values and accelerators this host doesn't have —
|
||||
a silent no-op pick would read as "the setting doesn't work".
|
||||
- An OMNIVOICE_DEVICE env pin is reported (env_pinned) and wins over PUT.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import sys
|
||||
|
||||
import pytest
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
def fresh_app(monkeypatch, tmp_path):
|
||||
"""Same isolation pattern as tests/backend/test_perf_settings.py."""
|
||||
monkeypatch.setenv("OMNIVOICE_DATA_DIR", str(tmp_path))
|
||||
monkeypatch.delenv("OMNIVOICE_DEVICE", raising=False)
|
||||
monkeypatch.delenv("HF_TOKEN", raising=False)
|
||||
monkeypatch.delenv("HUGGING_FACE_HUB_TOKEN", raising=False)
|
||||
|
||||
for mod in list(sys.modules):
|
||||
if (
|
||||
mod == "core" or mod.startswith("core.")
|
||||
or mod == "services" or mod.startswith("services.")
|
||||
or mod == "api" or mod.startswith("api.")
|
||||
):
|
||||
del sys.modules[mod]
|
||||
|
||||
from core import db as _db
|
||||
_db.init_db()
|
||||
|
||||
from fastapi import FastAPI
|
||||
from api.routers import settings as settings_router
|
||||
|
||||
app = FastAPI()
|
||||
app.include_router(settings_router.router)
|
||||
return app
|
||||
|
||||
|
||||
def _client(app):
|
||||
from fastapi.testclient import TestClient
|
||||
return TestClient(app, client=("127.0.0.1", 12345))
|
||||
|
||||
|
||||
def test_get_reports_state_and_families(fresh_app):
|
||||
c = _client(fresh_app)
|
||||
r = c.get("/api/settings/compute-device")
|
||||
assert r.status_code == 200, r.text
|
||||
body = r.json()
|
||||
assert body["value"] in body["choices"]
|
||||
assert "cpu" in body["available_families"] # invariant: cpu always present
|
||||
assert body["effective_family"] in body["available_families"]
|
||||
assert isinstance(body["env_pinned"], bool)
|
||||
|
||||
|
||||
def test_put_persists_and_flags_restart(fresh_app):
|
||||
c = _client(fresh_app)
|
||||
r = c.put("/api/settings/compute-device", json={"value": "cpu"})
|
||||
assert r.status_code == 200, r.text
|
||||
body = r.json()
|
||||
assert body["value"] == "cpu"
|
||||
# Caps are cached per process: the pick applies at next start, and the
|
||||
# endpoint must say so instead of pretending it already did.
|
||||
assert body["restart_required"] is True
|
||||
|
||||
from core import prefs
|
||||
assert prefs.resolve("compute_device", default="auto") == "cpu"
|
||||
|
||||
# auto round-trips back
|
||||
r = c.put("/api/settings/compute-device", json={"value": "auto"})
|
||||
assert r.status_code == 200
|
||||
assert r.json()["value"] == "auto"
|
||||
|
||||
|
||||
def test_put_rejects_unknown_and_unavailable_values(fresh_app):
|
||||
c = _client(fresh_app)
|
||||
r = c.put("/api/settings/compute-device", json={"value": "quantum"})
|
||||
assert r.status_code == 400
|
||||
assert "Valid:" in r.json()["detail"]
|
||||
|
||||
# Find an accelerator this host does NOT have (CI hosts are cpu-only,
|
||||
# but don't assume — pick from the full choice list minus available).
|
||||
state = c.get("/api/settings/compute-device").json()
|
||||
missing = [
|
||||
f for f in state["choices"]
|
||||
if f not in ("auto", "cpu") and f not in state["available_families"]
|
||||
]
|
||||
if missing:
|
||||
r = c.put("/api/settings/compute-device", json={"value": missing[0]})
|
||||
assert r.status_code == 400
|
||||
assert "not available" in r.json()["detail"]
|
||||
|
||||
|
||||
def test_env_pin_is_reported_and_wins(fresh_app, monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_DEVICE", "cpu")
|
||||
c = _client(fresh_app)
|
||||
state = c.get("/api/settings/compute-device").json()
|
||||
assert state["env_pinned"] is True
|
||||
assert state["value"] == "cpu"
|
||||
|
||||
# A PUT still persists (for after the pin is removed) but the resolved
|
||||
# value stays the env's — the UI disables the control and shows the pin.
|
||||
r = c.put("/api/settings/compute-device", json={"value": "auto"})
|
||||
assert r.status_code == 200
|
||||
assert r.json()["value"] == "cpu"
|
||||
Vendored
+2
@@ -26,6 +26,7 @@ GET /api/mcp/bindings
|
||||
GET /api/settings/analytics
|
||||
GET /api/settings/asr-openai-compat
|
||||
GET /api/settings/changelog
|
||||
GET /api/settings/compute-device
|
||||
GET /api/settings/db-backup
|
||||
GET /api/settings/dictation-refinement
|
||||
GET /api/settings/hf-mirror
|
||||
@@ -269,6 +270,7 @@ POST /workers/{worker_id}/resume
|
||||
PUT /api/mcp/bindings
|
||||
PUT /api/settings/analytics
|
||||
PUT /api/settings/asr-openai-compat
|
||||
PUT /api/settings/compute-device
|
||||
PUT /api/settings/dictation-refinement
|
||||
PUT /api/settings/hf-mirror
|
||||
PUT /api/settings/history-retention
|
||||
|
||||
@@ -436,6 +436,15 @@ def test_real_cuda_is_untouched_by_the_rocm_branch(monkeypatch):
|
||||
|
||||
def test_ctranslate2_never_gets_cuda_on_a_rocm_build(monkeypatch):
|
||||
"""The crash itself: whisperx's device pick must refuse HIP-flavoured cuda."""
|
||||
from core.device_caps import HostCaps
|
||||
|
||||
# The compute-device override gate consults the probe FIRST; pin it to a
|
||||
# CUDA family so this test keeps exercising the ROCm-specific refusal
|
||||
# (on a cpu-family CI host the gate would short-circuit before it).
|
||||
monkeypatch.setattr(
|
||||
"core.device_caps.detect_host_caps",
|
||||
lambda: HostCaps(family="cuda", available_families=("cuda", "cpu")),
|
||||
)
|
||||
monkeypatch.setattr(ab, "_rocm_torch", lambda: True)
|
||||
monkeypatch.setattr(ab, "_cuda_reported_available", lambda: True)
|
||||
assert ab._ctranslate2_cuda_ok() is False
|
||||
@@ -444,3 +453,15 @@ def test_ctranslate2_never_gets_cuda_on_a_rocm_build(monkeypatch):
|
||||
monkeypatch.setattr(ab, "_rocm_torch", lambda: False)
|
||||
assert ab._ctranslate2_cuda_ok() is True
|
||||
assert ab.WhisperXBackend._pick_device() == ("cuda", "float16")
|
||||
|
||||
|
||||
def test_ctranslate2_gate_fails_safe_when_the_probe_breaks(monkeypatch):
|
||||
"""A broken capability probe must mean CPU, never a torch-derived guess —
|
||||
guessing would bypass a cpu override and re-open #1529 on ROCm."""
|
||||
def _boom():
|
||||
raise RuntimeError("probe exploded")
|
||||
|
||||
monkeypatch.setattr("core.device_caps.detect_host_caps", _boom)
|
||||
monkeypatch.setattr(ab, "_cuda_reported_available", lambda: True)
|
||||
monkeypatch.setattr(ab, "_rocm_torch", lambda: False)
|
||||
assert ab._ctranslate2_cuda_ok() is False
|
||||
|
||||
@@ -0,0 +1,76 @@
|
||||
"""Cross-layer contract lock for the admin-gate 403 detail string.
|
||||
|
||||
The backend's ``require_admin``/``require_admin_action`` answer 403 with a
|
||||
mode-distinct ``detail`` (``_admin_gate_403`` in backend/api/dependencies.py):
|
||||
"loopback origin or admin API key required" in server mode, plain
|
||||
"loopback origin required" on the desktop build. The SPA's ``apiFetch`` routes
|
||||
a 403 to the API-key login gate exactly when the detail contains the substring
|
||||
"admin api key" (frontend/src/api/client.ts) — i.e. when presenting the key
|
||||
could actually satisfy the gate. The per-mode behaviour is pinned by
|
||||
tests/test_loopback_server_mode.py; this file pins the LITERAL contract across
|
||||
layers: a backend reword keeps backend tests green while the frontend matcher
|
||||
silently stops firing, and a LAN user is back to raw 403 spam instead of the
|
||||
login form.
|
||||
"""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import re
|
||||
from pathlib import Path
|
||||
|
||||
ROOT = Path(__file__).resolve().parents[1]
|
||||
DEPS = ROOT / "backend" / "api" / "dependencies.py"
|
||||
CLIENT = ROOT / "frontend" / "src" / "api" / "client.ts"
|
||||
|
||||
|
||||
def _frontend_sniff() -> str:
|
||||
"""The substring apiFetch matches on a 403 to admit it to the auth gate."""
|
||||
text = CLIENT.read_text(encoding="utf-8")
|
||||
# adminGate403 = ... detail.toLowerCase().includes('<sniff>')
|
||||
m = re.search(r"adminGate403 =.*?includes\('([^']+)'\)", text, re.DOTALL)
|
||||
assert m, "adminGate403 matcher not found in frontend/src/api/client.ts"
|
||||
return m.group(1)
|
||||
|
||||
|
||||
def _key_named_details() -> set[str]:
|
||||
"""Every quoted string in dependencies.py that names the admin API key."""
|
||||
return set(re.findall(r'"([^"]*admin API key[^"]*)"', DEPS.read_text(encoding="utf-8")))
|
||||
|
||||
|
||||
def test_key_named_details_match_frontend_sniff():
|
||||
"""Every backend literal naming the admin key must contain the SPA matcher."""
|
||||
details = _key_named_details()
|
||||
assert details, (
|
||||
"no 'admin API key' detail literal left in dependencies.py — moved or "
|
||||
"reworded? Update frontend/src/api/client.ts in the same change."
|
||||
)
|
||||
sniff = _frontend_sniff()
|
||||
for detail in details:
|
||||
# Case-insensitive substring, mirroring apiFetch's toLowerCase match.
|
||||
assert sniff in detail.lower(), (
|
||||
f"backend detail {detail!r} no longer contains the frontend matcher "
|
||||
f"{sniff!r} — the SPA would stop routing it to the API-key gate. "
|
||||
"Update frontend/src/api/client.ts in the same change."
|
||||
)
|
||||
|
||||
|
||||
def test_frontend_sniff_rejects_details_a_key_cannot_fix():
|
||||
"""The sniff must not swallow 403s an API key cannot satisfy.
|
||||
|
||||
The desktop admin-gate arm (loopback-only regardless of credentials), the
|
||||
legacy require_loopback desktop 403, the CSRF rejection, and the
|
||||
desktop-only filesystem gate: routing any of these to the login form would
|
||||
trap the user in a form that can never succeed.
|
||||
"""
|
||||
sniff = _frontend_sniff()
|
||||
unfixable = (
|
||||
"loopback origin required", # desktop admin arm + require_loopback
|
||||
"browser origin rejected", # BearerKeyMiddleware CSRF (main.py)
|
||||
"desktop origin required", # require_desktop — loopback-only forever
|
||||
"native filesystem access requires loopback origin", # require_native
|
||||
)
|
||||
for detail in unfixable:
|
||||
assert sniff not in detail.lower(), (
|
||||
f"frontend matcher {sniff!r} now also matches {detail!r}, which "
|
||||
"an API key cannot satisfy — the login gate would loop."
|
||||
)
|
||||
@@ -0,0 +1,147 @@
|
||||
"""The user compute-device override (Settings → Performance / OMNIVOICE_DEVICE).
|
||||
|
||||
The override is applied at the single choke point — `_probe()`'s family
|
||||
selection — so routing, `get_best_device()`, and every UI badge inherit it.
|
||||
Contract pinned here: an override steers, it cannot invent hardware (a family
|
||||
this host lacks is noted and ignored); "cpu" is always honorable; env beats
|
||||
the persisted Settings pick; unknown values normalize to "auto"; and the
|
||||
running process reports what it actually applied (`requested_family`) so the
|
||||
Settings panel can show restart-required truthfully.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import types
|
||||
from unittest.mock import patch
|
||||
|
||||
from core import device_caps
|
||||
|
||||
|
||||
def _torch_mock(*, cuda_available=False, mps_available=False):
|
||||
"""Minimal torch mock — just enough accelerator shape for the override
|
||||
tests (test_device_caps.py owns the full degradation matrix)."""
|
||||
cuda = types.SimpleNamespace(
|
||||
is_available=lambda: cuda_available,
|
||||
device_count=lambda: 1,
|
||||
get_device_name=lambda i: "NVIDIA RTX 4090",
|
||||
mem_get_info=lambda: (12 * 1024**3, 24 * 1024**3),
|
||||
get_device_capability=lambda i: (8, 9),
|
||||
_get_arch_list=lambda: [],
|
||||
)
|
||||
backends = types.SimpleNamespace(
|
||||
mps=types.SimpleNamespace(is_available=lambda: mps_available)
|
||||
)
|
||||
xpu = types.SimpleNamespace(
|
||||
is_available=lambda: False, get_device_name=lambda i: ""
|
||||
)
|
||||
return types.SimpleNamespace(
|
||||
cuda=cuda, version=types.SimpleNamespace(), backends=backends, xpu=xpu
|
||||
)
|
||||
|
||||
|
||||
def _probe_with(modules):
|
||||
with patch.dict("sys.modules", modules):
|
||||
return device_caps.refresh()
|
||||
|
||||
|
||||
def _cleanup():
|
||||
# Leave the process-wide cache in its no-override state for other tests.
|
||||
# The env var must go FIRST: this runs inside the test (before
|
||||
# monkeypatch teardown), so a refresh with OMNIVOICE_DEVICE still set
|
||||
# would cache the overridden caps for every later test in the session.
|
||||
import os
|
||||
|
||||
os.environ.pop("OMNIVOICE_DEVICE", None)
|
||||
device_caps.refresh()
|
||||
|
||||
|
||||
def test_no_override_is_auto_and_keeps_priority_pick(monkeypatch):
|
||||
monkeypatch.delenv("OMNIVOICE_DEVICE", raising=False)
|
||||
monkeypatch.setattr("core.prefs.resolve", lambda key, **kw: kw.get("default"))
|
||||
try:
|
||||
caps = _probe_with({"torch": _torch_mock(cuda_available=True, mps_available=True)})
|
||||
assert caps.family == "cuda"
|
||||
assert caps.requested_family == "auto"
|
||||
finally:
|
||||
_cleanup()
|
||||
|
||||
|
||||
def test_cpu_override_forces_cpu_on_an_accelerated_host(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_DEVICE", "cpu")
|
||||
try:
|
||||
caps = _probe_with({"torch": _torch_mock(cuda_available=True)})
|
||||
assert caps.family == "cpu"
|
||||
assert caps.requested_family == "cpu"
|
||||
# The pin is explained, not silent — a CUDA host showing CPU chips
|
||||
# without a note reads as a broken install.
|
||||
assert any("pinned" in n for n in caps.notes)
|
||||
finally:
|
||||
_cleanup()
|
||||
|
||||
|
||||
def test_override_for_a_missing_family_is_noted_and_ignored(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_DEVICE", "cuda")
|
||||
try:
|
||||
caps = _probe_with({"torch": _torch_mock(mps_available=True)})
|
||||
assert caps.family == "mps" # auto pick survives
|
||||
assert caps.requested_family == "cuda"
|
||||
assert any("not available" in n for n in caps.notes)
|
||||
finally:
|
||||
_cleanup()
|
||||
|
||||
|
||||
def test_override_matching_the_auto_pick_adds_no_note(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_DEVICE", "cuda")
|
||||
try:
|
||||
caps = _probe_with({"torch": _torch_mock(cuda_available=True)})
|
||||
assert caps.family == "cuda"
|
||||
assert not any("pinned" in n for n in caps.notes)
|
||||
finally:
|
||||
_cleanup()
|
||||
|
||||
|
||||
def test_env_beats_the_persisted_settings_pick(monkeypatch, tmp_path):
|
||||
# Same resolution order as engine selection (#981): a power-user's env
|
||||
# pin must not be silently undone by the UI's stored choice.
|
||||
from core import prefs
|
||||
|
||||
monkeypatch.setattr(prefs, "_PREFS_PATH", tmp_path / "prefs.json")
|
||||
prefs.set_("compute_device", "cuda")
|
||||
try:
|
||||
monkeypatch.setenv("OMNIVOICE_DEVICE", "cpu")
|
||||
assert device_caps.requested_device_override() == "cpu"
|
||||
monkeypatch.delenv("OMNIVOICE_DEVICE")
|
||||
assert device_caps.requested_device_override() == "cuda"
|
||||
finally:
|
||||
_cleanup()
|
||||
|
||||
|
||||
def test_unknown_values_normalize_to_auto(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_DEVICE", "quantum")
|
||||
try:
|
||||
assert device_caps.requested_device_override() == "auto"
|
||||
finally:
|
||||
_cleanup()
|
||||
|
||||
|
||||
def test_torch_unimportable_still_reports_the_request(monkeypatch):
|
||||
# Even a degraded CPU-only probe carries the requested family so the
|
||||
# Settings panel renders the user's pick instead of resetting to auto.
|
||||
monkeypatch.setenv("OMNIVOICE_DEVICE", "cpu")
|
||||
real_import = __import__
|
||||
|
||||
def _no_torch(name, *a, **kw):
|
||||
if name == "torch":
|
||||
raise ImportError("no torch here")
|
||||
return real_import(name, *a, **kw)
|
||||
|
||||
try:
|
||||
with patch.dict("sys.modules"):
|
||||
import sys
|
||||
|
||||
sys.modules.pop("torch", None)
|
||||
with patch("builtins.__import__", side_effect=_no_torch):
|
||||
caps = device_caps.refresh()
|
||||
assert caps.probe_ok is False
|
||||
assert caps.requested_family == "cpu"
|
||||
finally:
|
||||
_cleanup()
|
||||
@@ -52,6 +52,41 @@ def test_resolve_within_accepts_relative_and_existing_absolute_paths(tmp_path):
|
||||
assert resolve_within(root, item) == item
|
||||
|
||||
|
||||
def test_stored_subpaths_split_on_both_separator_families():
|
||||
"""The component split is host-independent.
|
||||
|
||||
Asserted on the splitter itself, not through ``resolve_within``: the
|
||||
Python suite runs on Linux only, where ``os.sep`` splitting already
|
||||
handled ``/``. A behavioural test would pass here whether or not the
|
||||
Windows path is fixed, so it would not guard the regression.
|
||||
"""
|
||||
from core.path_security import _PATH_SEPARATORS
|
||||
assert _PATH_SEPARATORS.split("sub/voice.wav") == ["sub", "voice.wav"]
|
||||
assert _PATH_SEPARATORS.split(r"sub\voice.wav") == ["sub", "voice.wav"]
|
||||
|
||||
|
||||
@pytest.mark.parametrize("stored_path", ["sub/voice.wav", r"sub\voice.wav"])
|
||||
def test_resolve_within_reads_a_stored_subpath(tmp_path, stored_path):
|
||||
"""A persisted sub-path resolves to the same file on Windows and POSIX.
|
||||
|
||||
Rows written on Windows, POSIX, or Docker must resolve identically after
|
||||
the same data directory is opened on another supported host.
|
||||
"""
|
||||
from core.path_security import resolve_within
|
||||
root = tmp_path / "root"
|
||||
(root / "sub").mkdir(parents=True)
|
||||
assert resolve_within(root, stored_path) == root / "sub" / "voice.wav"
|
||||
|
||||
|
||||
def test_resolve_within_rejects_traversal_through_either_separator(tmp_path):
|
||||
"""Splitting on both separators must not open a traversal path."""
|
||||
from core.path_security import UnsafePath, resolve_within
|
||||
root = tmp_path / "root"
|
||||
(root / "sub").mkdir(parents=True)
|
||||
with pytest.raises(UnsafePath):
|
||||
resolve_within(root, "sub/../../secret.wav")
|
||||
|
||||
|
||||
def test_resolve_within_rejects_parent_and_absolute_escape(tmp_path):
|
||||
from core.path_security import UnsafePath, resolve_within
|
||||
root = tmp_path / "root"
|
||||
@@ -76,7 +111,10 @@ def test_resolve_within_rejects_symlink_escape(tmp_path):
|
||||
(root / "link").symlink_to(outside, target_is_directory=True)
|
||||
except OSError:
|
||||
pytest.skip("symlink creation is unavailable on this host")
|
||||
with pytest.raises(UnsafePath):
|
||||
# Match the reason, not just the type: when ``/`` was not treated as a
|
||||
# separator on Windows this call failed at component validation instead,
|
||||
# so the containment check below it was never exercised there.
|
||||
with pytest.raises(UnsafePath, match="escapes its allowed root"):
|
||||
resolve_within(root, "link/secret.wav")
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,214 @@
|
||||
"""The FlashInfer opt-in (OMNIVOICE_FLASHINFER, upstream k2-fsa port).
|
||||
|
||||
An optimization must never be a point of failure (#278 contract, same as
|
||||
torch.compile): the env knob is CUDA-only, off by default, refuses with a
|
||||
named reason when the host can't honor it, latches off for the session after
|
||||
a runtime failure, and a mid-generation FlashInfer error unapplies the patch
|
||||
and retries the standard path once.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import pytest
|
||||
|
||||
torch = pytest.importorskip("torch")
|
||||
|
||||
|
||||
def _ee():
|
||||
import services.engine_env as m
|
||||
return m
|
||||
|
||||
|
||||
def _mm():
|
||||
import services.model_manager as m
|
||||
return m
|
||||
|
||||
|
||||
@pytest.fixture(autouse=True)
|
||||
def _reset_latch(monkeypatch):
|
||||
monkeypatch.setattr(_ee(), "_flashinfer_runtime_failure", None)
|
||||
monkeypatch.delenv("OMNIVOICE_FLASHINFER", raising=False)
|
||||
|
||||
|
||||
# ── the env knob ────────────────────────────────────────────────────────────
|
||||
|
||||
|
||||
@pytest.mark.parametrize(
|
||||
"value,expected",
|
||||
[
|
||||
("", "off"), ("0", "off"), ("false", "off"), ("off", "off"),
|
||||
("1", "on"), ("true", "on"), ("ON", "on"),
|
||||
("graph", "graph"), ("GRAPH", "graph"),
|
||||
("banana", "off"), # typo → default path, not a crash
|
||||
],
|
||||
)
|
||||
def test_flashinfer_mode_parsing(monkeypatch, value, expected):
|
||||
if value:
|
||||
monkeypatch.setenv("OMNIVOICE_FLASHINFER", value)
|
||||
assert _ee().flashinfer_mode() == expected
|
||||
|
||||
|
||||
def test_should_flashinfer_refuses_non_cuda(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_FLASHINFER", "1")
|
||||
assert _ee().should_flashinfer("cpu") == "off"
|
||||
assert _ee().should_flashinfer("mps") == "off"
|
||||
|
||||
|
||||
def test_should_flashinfer_refuses_without_the_package(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_FLASHINFER", "1")
|
||||
ee = _ee()
|
||||
monkeypatch.setattr(ee.importlib.util, "find_spec", lambda name: None)
|
||||
assert ee.should_flashinfer("cuda") == "off"
|
||||
|
||||
|
||||
def test_latched_reason_is_sanitized(monkeypatch):
|
||||
# Wheel import errors embed the user's home path — the latch must store
|
||||
# the redacted form (core.failure.sanitize maps $HOME → "~").
|
||||
import os
|
||||
|
||||
home = os.path.expanduser("~")
|
||||
_ee().mark_flashinfer_runtime_failure(
|
||||
f"ImportError: {home}/.venv/lib/flashinfer/_kernels.so: bad ELF"
|
||||
)
|
||||
latched = _ee()._flashinfer_runtime_failure
|
||||
assert home not in latched
|
||||
assert "ImportError" in latched
|
||||
|
||||
|
||||
def test_sanitizer_failure_never_latches_the_raw_reason(monkeypatch):
|
||||
# Fail closed: a broken redactor must not leak the original message.
|
||||
import core.failure
|
||||
|
||||
def _boom(_):
|
||||
raise RuntimeError("sanitizer exploded (test)")
|
||||
|
||||
monkeypatch.setattr(core.failure, "sanitize", _boom)
|
||||
_ee().mark_flashinfer_runtime_failure(
|
||||
"ImportError: /home/someone/secret-project/creds.so missing"
|
||||
)
|
||||
latched = _ee()._flashinfer_runtime_failure
|
||||
assert "secret-project" not in latched and "/home/" not in latched
|
||||
assert latched.startswith("ImportError")
|
||||
assert "redacted" in latched
|
||||
|
||||
|
||||
def test_runtime_failure_latches_the_session_off(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_FLASHINFER", "graph")
|
||||
ee = _ee()
|
||||
monkeypatch.setattr(ee.importlib.util, "find_spec", lambda name: object())
|
||||
assert ee.should_flashinfer("cuda") == "graph"
|
||||
ee.mark_flashinfer_runtime_failure("boom")
|
||||
assert ee.should_flashinfer("cuda") == "off"
|
||||
|
||||
|
||||
# ── failure classification ──────────────────────────────────────────────────
|
||||
|
||||
|
||||
def test_classifier_matches_flashinfer_markers():
|
||||
mm = _mm()
|
||||
assert mm._is_flashinfer_runtime_failure(RuntimeError("flashinfer plan failed"))
|
||||
assert mm._is_flashinfer_runtime_failure(RuntimeError("CUDA graph capture aborted"))
|
||||
assert not mm._is_flashinfer_runtime_failure(ValueError("Unsupported instruct items"))
|
||||
assert not mm._is_flashinfer_runtime_failure(RuntimeError("CUDA out of memory"))
|
||||
|
||||
|
||||
def test_classifier_walks_the_cause_chain():
|
||||
mm = _mm()
|
||||
inner = RuntimeError("flashinfer workspace too small")
|
||||
outer = RuntimeError("generation failed")
|
||||
outer.__cause__ = inner
|
||||
assert mm._is_flashinfer_runtime_failure(outer)
|
||||
# `raise ... from None` severs the chain — a genuine error must not be
|
||||
# re-classified via a suppressed FlashInfer context.
|
||||
severed = RuntimeError("generation failed")
|
||||
severed.__context__ = inner
|
||||
severed.__suppress_context__ = True
|
||||
assert not mm._is_flashinfer_runtime_failure(severed)
|
||||
|
||||
|
||||
# ── unapply restores the class implementations ──────────────────────────────
|
||||
|
||||
|
||||
class _MiniModel:
|
||||
class _Llm(torch.nn.Module):
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.lin = torch.nn.Linear(2, 2)
|
||||
self.config = type("C", (), {"use_cache": False})()
|
||||
self.attn_impl = None
|
||||
|
||||
def set_attn_implementation(self, name):
|
||||
self.attn_impl = name
|
||||
|
||||
def __init__(self):
|
||||
self.llm = self._Llm()
|
||||
|
||||
def _generate_iterative(self, *a):
|
||||
return "class-impl"
|
||||
|
||||
|
||||
def test_unapply_flashinfer_restores_instance_state():
|
||||
from types import MethodType
|
||||
|
||||
m = _MiniModel()
|
||||
# Simulate apply_flashinfer's instance-level patching.
|
||||
m.llm.lin.forward = MethodType(lambda self, x: "patched", m.llm.lin)
|
||||
m.llm.lin._fi_w_qkv = torch.zeros(1)
|
||||
m._generate_iterative = MethodType(lambda self, *a: "patched", m)
|
||||
m._fi_runner = object()
|
||||
m._fi_graph_cache = {}
|
||||
m._fi_enable_cuda_graph = True
|
||||
|
||||
_mm()._unapply_flashinfer(m)
|
||||
|
||||
assert "forward" not in vars(m.llm.lin), "instance forward override must go"
|
||||
assert not hasattr(m.llm.lin, "_fi_w_qkv")
|
||||
assert m._generate_iterative() == "class-impl"
|
||||
assert not hasattr(m, "_fi_runner")
|
||||
assert m.llm.attn_impl == "sdpa"
|
||||
assert m.llm.config.use_cache is True
|
||||
|
||||
|
||||
def test_unapply_restores_the_captured_attention_impl():
|
||||
# The pre-apply impl may be flash_attention_2, not sdpa — unapply must
|
||||
# put back what was actually there (CodeRabbit/Greptile, #1565).
|
||||
m = _MiniModel()
|
||||
m._fi_orig_attn_impl = "flash_attention_2"
|
||||
_mm()._unapply_flashinfer(m)
|
||||
assert m.llm.attn_impl == "flash_attention_2"
|
||||
assert not hasattr(m, "_fi_orig_attn_impl")
|
||||
|
||||
|
||||
# ── generate-time fallback ──────────────────────────────────────────────────
|
||||
|
||||
|
||||
def test_generate_fallback_unapplies_and_retries_once():
|
||||
mm = _mm()
|
||||
calls = {"n": 0}
|
||||
|
||||
class _Model(_MiniModel):
|
||||
def generate(self, **kw):
|
||||
calls["n"] += 1
|
||||
if calls["n"] == 1:
|
||||
raise RuntimeError("flashinfer ragged attention failed")
|
||||
return ["ok"]
|
||||
|
||||
m = _Model()
|
||||
m._fi_runner = object()
|
||||
mm._install_flashinfer_fallback(m)
|
||||
assert m.generate() == ["ok"]
|
||||
assert calls["n"] == 2
|
||||
assert not hasattr(m, "_fi_runner"), "fallback must unapply the patch"
|
||||
assert _ee()._flashinfer_runtime_failure is not None
|
||||
|
||||
|
||||
def test_generate_fallback_leaves_real_errors_alone():
|
||||
mm = _mm()
|
||||
|
||||
class _Model(_MiniModel):
|
||||
def generate(self, **kw):
|
||||
raise ValueError("Unsupported instruct items")
|
||||
|
||||
m = _Model()
|
||||
mm._install_flashinfer_fallback(m)
|
||||
with pytest.raises(ValueError):
|
||||
m.generate()
|
||||
@@ -17,6 +17,7 @@ EXPECTED_EXACT_REGEXES = {
|
||||
"^hf_abcdefghijklmnopqrstuvwxyz0123456789ABCDEF$",
|
||||
"^hf_QWERTYUIOPasdfghjklZXCVBNM0123456789xyzAB$",
|
||||
"^max_length=400$",
|
||||
"^Ed25519PrivateKey$",
|
||||
}
|
||||
|
||||
|
||||
|
||||
@@ -253,6 +253,89 @@ def test_side_effectful_get_rejects_remote_api_key_outside_server_mode(monkeypat
|
||||
assert exc.value.status_code == 403
|
||||
|
||||
|
||||
# Mode-distinct admin-gate detail: the 403 message must state what would
|
||||
# ACTUALLY satisfy the gate. The bundled UI routes any 403 whose detail
|
||||
# mentions "admin api key" to the API-key login form (frontend client.ts;
|
||||
# the literal contract is locked by tests/test_auth_gate_detail_lockstep.py).
|
||||
# Server mode accepts the key, so naming it is right. Desktop mode rejects
|
||||
# every non-loopback client regardless of credentials — the checks above only
|
||||
# run under server mode — so it must keep the plain loopback detail: naming
|
||||
# the key there invites a login form that can never succeed (a desktop
|
||||
# LAN-share guest would lose the whole consumption UI to it, #1213).
|
||||
|
||||
|
||||
def test_require_admin_desktop_detail_is_plain_loopback(monkeypatch):
|
||||
"""Desktop build: no presented key can satisfy the gate."""
|
||||
monkeypatch.delenv("OMNIVOICE_SERVER_MODE", raising=False)
|
||||
monkeypatch.setenv("OMNIVOICE_API_KEY", "s3cret") # a valid key can't help here
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin(
|
||||
_req_full("10.0.0.5", headers={"authorization": "Bearer s3cret"})
|
||||
)
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin required"
|
||||
|
||||
|
||||
def test_require_admin_server_mode_detail_names_the_key(monkeypatch):
|
||||
"""Server mode with an API key configured: the 403 names the key."""
|
||||
monkeypatch.setenv("OMNIVOICE_SERVER_MODE", "1")
|
||||
monkeypatch.setenv("OMNIVOICE_API_KEY", "s3cret")
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin(_req_full("172.17.0.1")) # credential configured, none presented
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin or admin API key required"
|
||||
|
||||
|
||||
def test_require_admin_pin_only_server_mode_detail_is_plain_loopback(monkeypatch):
|
||||
"""Server mode with ONLY a share PIN (Greptile P1, PR #1569): the PIN
|
||||
closes read-only bootstrap but no API key exists to present, so naming
|
||||
the key would send the browser to a login form that can never succeed.
|
||||
Only loopback can use admin here — the plain detail says so, and the
|
||||
SPA leaves it a plain error instead of gating the whole UI."""
|
||||
monkeypatch.setenv("OMNIVOICE_SERVER_MODE", "1")
|
||||
monkeypatch.delenv("OMNIVOICE_API_KEY", raising=False)
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin(_req_full("172.17.0.1", pin="424242")) # PIN ≠ admin credential
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin required"
|
||||
|
||||
|
||||
def test_require_admin_action_desktop_detail_is_plain_loopback(monkeypatch):
|
||||
"""Desktop build, side-effectful GET: plain loopback detail."""
|
||||
monkeypatch.delenv("OMNIVOICE_SERVER_MODE", raising=False)
|
||||
monkeypatch.setenv("OMNIVOICE_API_KEY", "s3cret")
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin_action(
|
||||
_req_full(
|
||||
"10.0.0.5",
|
||||
method="GET",
|
||||
headers={"authorization": "Bearer s3cret"},
|
||||
)
|
||||
)
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin required"
|
||||
|
||||
|
||||
def test_require_admin_action_server_mode_detail_names_the_key(monkeypatch):
|
||||
"""Server mode + key configured, side-effectful GET: names the key."""
|
||||
monkeypatch.setenv("OMNIVOICE_SERVER_MODE", "1")
|
||||
monkeypatch.setenv("OMNIVOICE_API_KEY", "s3cret")
|
||||
|
||||
with pytest.raises(HTTPException) as exc:
|
||||
require_admin_action(_req_full("172.17.0.1", method="GET"))
|
||||
|
||||
assert exc.value.status_code == 403
|
||||
assert exc.value.detail == "loopback origin or admin API key required"
|
||||
|
||||
|
||||
def test_side_effectful_get_rejects_pin_and_trusted_network(monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_SERVER_MODE", "1")
|
||||
monkeypatch.setenv("OMNIVOICE_TRUSTED_NETWORKS", "10.0.0.0/8")
|
||||
|
||||
@@ -50,6 +50,7 @@ _ALLOWED_FILES = {
|
||||
"README_CN.md", # Chinese README (a translation)
|
||||
"docs/data_preparation.md", # multilingual example payloads
|
||||
"docs/voice-design.md", # EN/CJK attribute mapping table
|
||||
"docs/engines/omnivoice.md", # pinyin pronunciation-control example (functional CJK)
|
||||
"docs/superpowers/specs/2026-05-31-voice-gallery-design.md", # Chinese-dialect taxonomy reference table
|
||||
"examples/README.md", # multilingual example payloads
|
||||
# Text-processing (CJK punctuation inside sentence/clause-splitting regexes)
|
||||
|
||||
@@ -0,0 +1,20 @@
|
||||
"""Packaged desktop builds must carry the SPA used by Network Sharing."""
|
||||
|
||||
from __future__ import annotations
|
||||
|
||||
import json
|
||||
from pathlib import Path
|
||||
|
||||
|
||||
ROOT = Path(__file__).resolve().parents[1]
|
||||
|
||||
|
||||
def test_desktop_bundle_carries_the_lan_frontend() -> None:
|
||||
"""The backend cannot serve LAN clients from Tauri's embedded WebView assets."""
|
||||
config = json.loads((ROOT / "frontend/src-tauri/tauri.conf.json").read_text())
|
||||
resources = config["bundle"]["resources"]
|
||||
|
||||
assert "../../frontend/dist" in resources, (
|
||||
"frontend/dist must be a filesystem bundle resource so the packaged "
|
||||
"Python backend can serve Network Sharing clients"
|
||||
)
|
||||
@@ -0,0 +1,223 @@
|
||||
"""Voice-clone prompts persist across restarts (upstream VoiceClonePrompt port).
|
||||
|
||||
The in-memory prompt cache (#427/#473) dies with the process, so the first
|
||||
generation of every session re-encoded each voice — and re-ran ASR when the
|
||||
profile had no stored transcript. Upstream k2-fsa added
|
||||
``VoiceClonePrompt.save()/.load()`` for exactly this; we port the format
|
||||
(version-tagged dict, ``torch.load(weights_only=True)``-safe) and put a disk
|
||||
layer under the memory LRU, keyed identically (ref path + mtime + ref_text +
|
||||
preprocess flag). Restart is simulated here by clearing the memory cache: a
|
||||
second lookup must come from disk, not a re-encode.
|
||||
|
||||
The layer is best-effort by contract: disabled (env), unwritable, or corrupt
|
||||
disk state must never fail a generation — worst case is the old re-encode.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import pytest
|
||||
|
||||
torch = pytest.importorskip("torch")
|
||||
|
||||
|
||||
def _tb():
|
||||
"""The *live* services.tts_backend (same rationale as
|
||||
test_clone_prompt_wiring._tb: other suites purge services.* modules)."""
|
||||
import services.tts_backend as m
|
||||
return m
|
||||
|
||||
|
||||
def _VoiceClonePrompt():
|
||||
"""Resolved at call time — a module-level binding could go stale when
|
||||
another suite purges omnivoice.* from sys.modules (CodeRabbit, #1565)."""
|
||||
from omnivoice.models.omnivoice import VoiceClonePrompt
|
||||
return VoiceClonePrompt
|
||||
|
||||
|
||||
def _prompt():
|
||||
return _VoiceClonePrompt()(
|
||||
ref_audio_tokens=torch.arange(24, dtype=torch.long).reshape(8, 3),
|
||||
ref_text="Nice to meet you.",
|
||||
ref_rms=0.123,
|
||||
)
|
||||
|
||||
|
||||
class _StubModel:
|
||||
def __init__(self):
|
||||
self.encodes = 0
|
||||
|
||||
def create_voice_clone_prompt(self, ref_audio, ref_text=None, preprocess_prompt=True):
|
||||
self.encodes += 1
|
||||
return _prompt()
|
||||
|
||||
|
||||
@pytest.fixture(autouse=True)
|
||||
def _isolated(tmp_path, monkeypatch):
|
||||
"""Point the disk layer at a per-test dir and start with empty caches."""
|
||||
monkeypatch.setattr("core.config.DATA_DIR", tmp_path / "data")
|
||||
monkeypatch.delenv("OMNIVOICE_PROMPT_DISK_CACHE", raising=False)
|
||||
_tb().clear_clone_prompt_cache()
|
||||
yield
|
||||
_tb().clear_clone_prompt_cache()
|
||||
|
||||
|
||||
@pytest.fixture()
|
||||
def ref_wav(tmp_path):
|
||||
p = tmp_path / "ref.wav"
|
||||
p.write_bytes(b"\x00" * 256)
|
||||
return str(p)
|
||||
|
||||
|
||||
def _disk_files(tmp_path):
|
||||
d = tmp_path / "data" / "prompt_cache"
|
||||
return sorted(d.glob("*.pt")) if d.is_dir() else []
|
||||
|
||||
|
||||
# ── the ported save/load format ─────────────────────────────────────────────
|
||||
|
||||
|
||||
def test_prompt_save_load_roundtrip(tmp_path):
|
||||
p = _prompt()
|
||||
path = str(tmp_path / "voice.pt")
|
||||
p.save(path)
|
||||
loaded = _VoiceClonePrompt().load(path)
|
||||
assert torch.equal(loaded.ref_audio_tokens, p.ref_audio_tokens)
|
||||
assert loaded.ref_text == p.ref_text
|
||||
assert loaded.ref_rms == pytest.approx(p.ref_rms)
|
||||
# The file must stay loadable under torch's safe default (weights_only=True
|
||||
# since 2.6) — a pickled dataclass would not be.
|
||||
raw = torch.load(path, weights_only=True)
|
||||
assert raw["format_version"] == 1
|
||||
|
||||
|
||||
def test_prompt_load_rejects_unknown_format_version(tmp_path):
|
||||
path = str(tmp_path / "future.pt")
|
||||
torch.save({"format_version": 999}, path)
|
||||
with pytest.raises(ValueError, match="format version"):
|
||||
_VoiceClonePrompt().load(path)
|
||||
|
||||
|
||||
def test_saved_tokens_are_cpu_even_from_dataclass_on_another_device(tmp_path):
|
||||
# save() must detach+CPU the tokens so the file is portable. On CUDA hosts
|
||||
# this exercises the real device move; CI (CPU-only) still verifies the
|
||||
# detach and that the persisted payload is CPU-resident.
|
||||
device = "cuda" if torch.cuda.is_available() else "cpu"
|
||||
p = _VoiceClonePrompt()(
|
||||
ref_audio_tokens=torch.zeros(8, 3, requires_grad=True).to(device),
|
||||
ref_text="x",
|
||||
ref_rms=0.5,
|
||||
)
|
||||
path = str(tmp_path / "v.pt")
|
||||
p.save(path)
|
||||
loaded = _VoiceClonePrompt().load(path)
|
||||
assert not loaded.ref_audio_tokens.requires_grad
|
||||
assert loaded.ref_audio_tokens.device.type == "cpu"
|
||||
# The device move must happen at SAVE time (portability of the file
|
||||
# itself), not merely at load: the raw payload carries CPU tensors.
|
||||
assert torch.load(path, weights_only=True)["ref_audio_tokens"].device.type == "cpu"
|
||||
|
||||
|
||||
# ── the disk layer under the memory cache ───────────────────────────────────
|
||||
|
||||
|
||||
def test_disk_hit_survives_restart(tmp_path, ref_wav):
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
|
||||
first = tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert model.encodes == 1
|
||||
assert len(_disk_files(tmp_path)) == 1
|
||||
|
||||
tb.clear_clone_prompt_cache() # "restart": memory gone, disk remains
|
||||
second = tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert model.encodes == 1, "restart re-encoded despite a persisted prompt"
|
||||
assert torch.equal(second.ref_audio_tokens, first.ref_audio_tokens)
|
||||
assert second.ref_text == first.ref_text
|
||||
|
||||
|
||||
def test_edited_reference_is_not_served_a_stale_prompt(tmp_path, ref_wav):
|
||||
import os
|
||||
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
tb.clear_clone_prompt_cache()
|
||||
|
||||
# Same path, new content+mtime → new key → the old file must not match.
|
||||
with open(ref_wav, "wb") as f:
|
||||
f.write(b"\x01" * 512)
|
||||
os.utime(ref_wav, (1, 1))
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert model.encodes == 2
|
||||
|
||||
|
||||
def test_single_use_refs_never_touch_disk(tmp_path, ref_wav):
|
||||
tb = _tb()
|
||||
tb._get_clone_prompt(_StubModel(), ref_wav, "hello", True, store=False)
|
||||
assert _disk_files(tmp_path) == [], (
|
||||
"store=False (dub per-segment clips) must not spray single-use "
|
||||
"prompts onto disk — same scan-resistance as the memory LRU"
|
||||
)
|
||||
|
||||
|
||||
def test_env_kill_switch_disables_the_layer(tmp_path, ref_wav, monkeypatch):
|
||||
monkeypatch.setenv("OMNIVOICE_PROMPT_DISK_CACHE", "0")
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert _disk_files(tmp_path) == []
|
||||
tb.clear_clone_prompt_cache()
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert model.encodes == 2 # no disk → honest re-encode
|
||||
|
||||
|
||||
def test_corrupt_disk_entry_is_dropped_and_reencoded(tmp_path, ref_wav):
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
tb.clear_clone_prompt_cache()
|
||||
|
||||
disk = _disk_files(tmp_path)
|
||||
assert len(disk) == 1
|
||||
disk[0].write_bytes(b"not a torch file")
|
||||
|
||||
prompt = tb._get_clone_prompt(model, ref_wav, "hello", True)
|
||||
assert prompt is not None
|
||||
assert model.encodes == 2, "corrupt file must fall back to encoding"
|
||||
# ...and the corrupt file was removed, then replaced by the fresh save.
|
||||
fresh = _disk_files(tmp_path)
|
||||
assert len(fresh) == 1
|
||||
assert torch.load(str(fresh[0]), weights_only=True)["format_version"] == 1
|
||||
|
||||
|
||||
def test_prune_keeps_only_the_newest(tmp_path, monkeypatch):
|
||||
import os
|
||||
import time
|
||||
|
||||
tb = _tb()
|
||||
monkeypatch.setattr(tb, "_PROMPT_DISK_CACHE_MAX", 3)
|
||||
model = _StubModel()
|
||||
refs = []
|
||||
for i in range(5):
|
||||
p = tmp_path / f"ref{i}.wav"
|
||||
p.write_bytes(bytes([i]) * 64)
|
||||
os.utime(p, (i + 1, i + 1))
|
||||
refs.append(str(p))
|
||||
for i, r in enumerate(refs):
|
||||
tb._get_clone_prompt(model, r, f"text {i}", True)
|
||||
# mtime is the prune order; keep saves strictly ordered even on
|
||||
# filesystems with coarse timestamps.
|
||||
files = _disk_files(tmp_path)
|
||||
newest = max(files, key=lambda f: f.stat().st_mtime)
|
||||
os.utime(newest, (1000 + i, 1000 + i))
|
||||
assert len(_disk_files(tmp_path)) == 3
|
||||
|
||||
|
||||
def test_unwritable_cache_dir_never_breaks_prompt_building(ref_wav, monkeypatch):
|
||||
# Simulate an unwritable data dir: the layer must vanish, not raise.
|
||||
monkeypatch.setattr(
|
||||
"core.config.DATA_DIR", "/proc/omnivoice-definitely-not-writable"
|
||||
)
|
||||
tb = _tb()
|
||||
model = _StubModel()
|
||||
assert tb._get_clone_prompt(model, ref_wav, "hello", True) is not None
|
||||
assert model.encodes == 1
|
||||
@@ -21,7 +21,9 @@ tests/test_synthetic_audio_watermark_1169.py.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
import io
|
||||
import re
|
||||
import tokenize
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
@@ -75,6 +77,46 @@ _PRODUCERS = [
|
||||
]
|
||||
|
||||
|
||||
def _code_only(src: str) -> str:
|
||||
"""``src`` with comments and string literals blanked to spaces.
|
||||
|
||||
ee35d238 made a module a "producer" by *mentioning* ``backend.generate()``
|
||||
in a comment — prose can't synthesize audio. Only real call sites may
|
||||
match ``_SYNTH_CALL``, so blank every COMMENT/STRING token span (spaces,
|
||||
not deletion, to keep the layout the regexes were written against).
|
||||
Unparseable source falls back to the raw text — fail closed, a module we
|
||||
can't tokenize still gets scanned.
|
||||
|
||||
f-strings stay conservative (Greptile P1 on #1564): on Python ≤3.11 the
|
||||
whole f-string — replacement expressions included — is ONE STRING token,
|
||||
so blanking it would let ``f"{backend.generate(t)}"`` evade the guard.
|
||||
f-prefixed strings are therefore kept raw there (a literal f-string
|
||||
*mentioning* a primitive false-positives toward the allowlist — fail
|
||||
closed). On 3.12+ (PEP 701) replacement code arrives as ordinary tokens
|
||||
and only the literal FSTRING_MIDDLE text is blanked.
|
||||
"""
|
||||
fstring_middle = getattr(tokenize, "FSTRING_MIDDLE", None)
|
||||
lines = src.splitlines(keepends=True)
|
||||
try:
|
||||
tokens = list(tokenize.generate_tokens(io.StringIO(src).readline))
|
||||
except (tokenize.TokenError, IndentationError, SyntaxError):
|
||||
return src
|
||||
for tok in tokens:
|
||||
if tok.type == tokenize.STRING:
|
||||
prefix = tok.string.split(tok.string[-1], 1)[0].rstrip("\"'")
|
||||
if "f" in prefix.lower():
|
||||
continue # pre-3.12 f-string: may contain executable code
|
||||
elif tok.type not in (tokenize.COMMENT, fstring_middle):
|
||||
continue
|
||||
(srow, scol), (erow, ecol) = tok.start, tok.end
|
||||
for row in range(srow - 1, erow):
|
||||
line = lines[row]
|
||||
lo = scol if row == srow - 1 else 0
|
||||
hi = ecol if row == erow - 1 else len(line.rstrip("\r\n"))
|
||||
lines[row] = line[:lo] + " " * (hi - lo) + line[hi:]
|
||||
return "".join(lines)
|
||||
|
||||
|
||||
def _py_files():
|
||||
for sub in ("api", "services", "worker"):
|
||||
for p in sorted((_BACKEND / sub).rglob("*.py")):
|
||||
@@ -84,9 +126,11 @@ def _py_files():
|
||||
def test_every_synthesis_module_routes_through_mark_synthetic():
|
||||
offenders = []
|
||||
for rel, src in _py_files():
|
||||
if not _SYNTH_CALL.search(src):
|
||||
if not _SYNTH_CALL.search(_code_only(src)):
|
||||
continue
|
||||
if rel in _ALLOWED or "mark_synthetic" in src:
|
||||
# The satisfying reference must be code too — a comment saying
|
||||
# "mark_synthetic" must not certify a module (CodeRabbit, #1564).
|
||||
if rel in _ALLOWED or "mark_synthetic" in _code_only(src):
|
||||
continue
|
||||
offenders.append(rel)
|
||||
assert not offenders, (
|
||||
@@ -100,7 +144,7 @@ def test_every_synthesis_module_routes_through_mark_synthetic():
|
||||
@pytest.mark.parametrize("rel", _PRODUCERS)
|
||||
def test_known_producer_still_marks(rel):
|
||||
src = (_BACKEND / rel).read_text(encoding="utf-8")
|
||||
assert "mark_synthetic" in src, (
|
||||
assert "mark_synthetic" in _code_only(src), (
|
||||
f"{rel} lost its mark_synthetic call — its synthetic audio would ship "
|
||||
"without the Art. 50(2) provenance mark (#1169)."
|
||||
)
|
||||
@@ -127,12 +171,34 @@ def test_allowlist_is_not_stale():
|
||||
p = _BACKEND / rel
|
||||
assert p.is_file(), f"watermark-coverage list names a missing file: {rel}"
|
||||
for rel in _ALLOWED:
|
||||
assert _SYNTH_CALL.search((_BACKEND / rel).read_text(encoding="utf-8")), (
|
||||
assert _SYNTH_CALL.search(_code_only((_BACKEND / rel).read_text(encoding="utf-8"))), (
|
||||
f"{rel} no longer matches a synthesis primitive — remove it from "
|
||||
"tests/test_watermark_route_coverage.py so the guard stays sharp."
|
||||
)
|
||||
|
||||
|
||||
def test_prose_mentions_are_not_producers():
|
||||
"""The ee35d238 regression: a comment (or log string / docstring) naming a
|
||||
synthesis primitive must not make a module a producer — only a call can."""
|
||||
prose = (
|
||||
"# A generic backend.generate() call accepts the same wire shape\n"
|
||||
'MSG = "route through generate_with_cached_ref(model) instead"\n'
|
||||
"def f():\n"
|
||||
' """Docs may mention _run_inference( freely."""\n'
|
||||
" return 1\n"
|
||||
)
|
||||
assert not _SYNTH_CALL.search(_code_only(prose))
|
||||
real = "def f(backend):\n return backend.generate(text='hi')\n"
|
||||
assert _SYNTH_CALL.search(_code_only(real))
|
||||
# Greptile P1: a call inside an f-string replacement field is code and
|
||||
# must still be caught, on every supported Python (≤3.11 tokenizes the
|
||||
# whole f-string as one STRING; 3.12+ splits out the expression tokens).
|
||||
fstring_call = 'def f(backend):\n return f"{backend.generate(text=\'hi\')}"\n'
|
||||
assert _SYNTH_CALL.search(_code_only(fstring_call))
|
||||
# ...and a comment claiming mark_synthetic must not certify a producer.
|
||||
assert "mark_synthetic" not in _code_only("# routes via mark_synthetic\nx = 1\n")
|
||||
|
||||
|
||||
# ── mark_synthetic unit contract (delegation, not new policy) ────────────────
|
||||
|
||||
|
||||
|
||||
@@ -78,7 +78,7 @@ def test_registration_declares_semantic_features(proto):
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_old_worker_is_visibly_refused_before_running_wrong_audio():
|
||||
"""An old peer can share v1's protobuf shape while missing inputs/progress.
|
||||
"""An old peer can share v1's protobuf shape while missing render parity.
|
||||
|
||||
Registration must fail by name, before authentication or task dispatch,
|
||||
instead of allowing a clone with no reference audio to report SUCCESS.
|
||||
@@ -95,6 +95,11 @@ async def test_old_worker_is_visibly_refused_before_running_wrong_audio():
|
||||
assert REQUIRED_FEATURES
|
||||
|
||||
|
||||
def test_remote_tts_render_parity_is_a_required_worker_feature():
|
||||
"""Do not let an old worker silently bypass the canonical TTS pipeline."""
|
||||
assert "remote_tts_render_v1" in REQUIRED_FEATURES
|
||||
|
||||
|
||||
# ── Control / data plane separation ────────────────────────────────────────
|
||||
|
||||
|
||||
|
||||
@@ -0,0 +1,93 @@
|
||||
"""Worker TTS must preserve the same rendering contract as local `/generate`.
|
||||
|
||||
The control plane already sends the profile reference, pinned seed and every
|
||||
quality control to a remote worker. This test protects the other half of that
|
||||
contract: the worker must call the canonical render helpers rather than a bare
|
||||
``backend.generate()`` call that silently discards the controls.
|
||||
"""
|
||||
from __future__ import annotations
|
||||
|
||||
from contextlib import nullcontext
|
||||
|
||||
|
||||
def _gallery_params():
|
||||
return {
|
||||
"ref_audio": "/worker-inputs/whisper-gallery.wav",
|
||||
"ref_text": "The gallery sample transcript.",
|
||||
"instruct": "female, whispering, warm",
|
||||
"language": "English",
|
||||
"duration": 3.5,
|
||||
"speed": 0.9,
|
||||
"num_step": 32,
|
||||
"guidance_scale": 2.0,
|
||||
"denoise": True,
|
||||
"postprocess_output": True,
|
||||
"t_shift": 0.4,
|
||||
"layer_penalty_factor": 1.1,
|
||||
"position_temperature": 0.7,
|
||||
"class_temperature": 0.8,
|
||||
"seed": 42,
|
||||
"max_chunk_chars": 180,
|
||||
"crossfade_ms": 55,
|
||||
"effect_preset": "broadcast",
|
||||
}
|
||||
|
||||
|
||||
def test_worker_omnivoice_preserves_gallery_identity_contract(monkeypatch):
|
||||
"""A selected Whisper archetype must reach native render unchanged."""
|
||||
from services import tts_backend
|
||||
from worker.executor import TaskExecutor
|
||||
import api.routers.generation as generation
|
||||
|
||||
model = object()
|
||||
backend = tts_backend.OmniVoiceBackend(model=model)
|
||||
captured = {}
|
||||
|
||||
monkeypatch.setattr(tts_backend, "engine_in_use", lambda _backend: nullcontext())
|
||||
monkeypatch.setattr(
|
||||
generation,
|
||||
"_run_inference",
|
||||
lambda *args, **kwargs: captured.update(args=args, kwargs=kwargs) or "audio",
|
||||
)
|
||||
|
||||
assert TaskExecutor._synthesize(backend, "Whispered test line.", _gallery_params()) == "audio"
|
||||
|
||||
args = captured["args"]
|
||||
assert args[0] is model
|
||||
assert args[1] == "Whispered test line."
|
||||
assert args[3] == "/worker-inputs/whisper-gallery.wav"
|
||||
assert args[4] == "The gallery sample transcript."
|
||||
assert args[5] == "female, whispering, warm"
|
||||
assert args[7:11] == (32, 2.0, 0.9, 0.4)
|
||||
assert args[13:17] == (1.1, 0.7, 0.8, 42)
|
||||
assert args[17:20] == ("broadcast", 180, 55)
|
||||
|
||||
|
||||
def test_worker_generic_engine_preserves_seeded_render_controls(monkeypatch):
|
||||
"""Non-native engines use the generic canonical helper with the same knobs."""
|
||||
from services import tts_backend
|
||||
from worker.executor import TaskExecutor
|
||||
import api.routers.generation as generation
|
||||
|
||||
class Backend:
|
||||
applies_own_mastering = False
|
||||
|
||||
backend = Backend()
|
||||
captured = {}
|
||||
monkeypatch.setattr(tts_backend, "engine_in_use", lambda _backend: nullcontext())
|
||||
monkeypatch.setattr(
|
||||
generation,
|
||||
"_run_backend_inference",
|
||||
lambda *args, **kwargs: captured.update(args=args, kwargs=kwargs) or "audio",
|
||||
)
|
||||
|
||||
assert TaskExecutor._synthesize(backend, "Whispered test line.", _gallery_params()) == "audio"
|
||||
|
||||
args = captured["args"]
|
||||
assert args[0] is backend
|
||||
assert args[1] == "Whispered test line."
|
||||
assert args[3] == "/worker-inputs/whisper-gallery.wav"
|
||||
assert args[4] == "The gallery sample transcript."
|
||||
assert args[5] == "female, whispering, warm"
|
||||
assert args[7:10] == (32, 2.0, 0.9)
|
||||
assert args[12:16] == (42, "broadcast", 180, 55)
|
||||
Reference in New Issue
Block a user